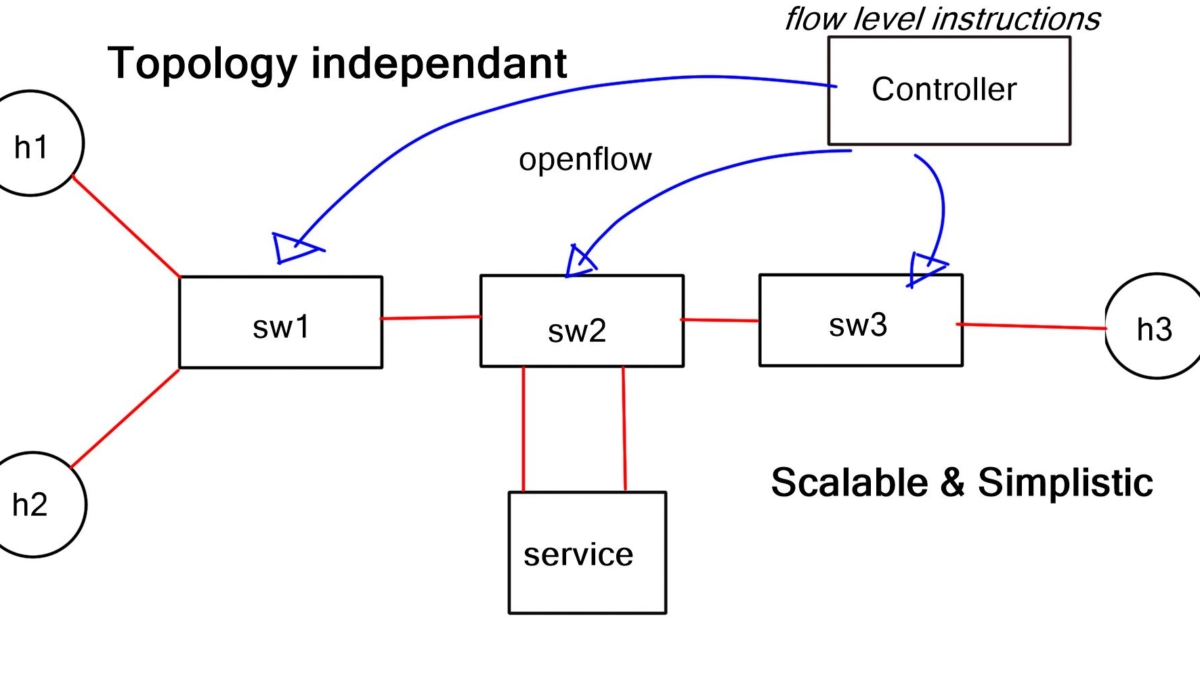
What does SDN mean

BGP has a new friend – BGP-Based SDN

BGP-Based SDN

The world of networking continues to evolve rapidly, with new technologies and approaches emerging to meet the growing demands of modern communication. Two such technologies, BGP (Border Gateway Protocol) and SDN (Software-Defined Networking), have gained significant attention for their impact on network flexibility and management. In this blog post, we will delve into the fascinating intersection of BGP and SDN, exploring how they work together to empower network administrators and optimize network operations.

Border Gateway Protocol (BGP) serves as the backbone of the internet, facilitating the exchange of routing information between networks. BGP enables dynamic routing, allowing routers to determine the best paths for data transmission based on various factors such as network policies, path preferences, and traffic conditions. It plays a crucial role in inter-domain routing, where multiple networks connect and exchange data.

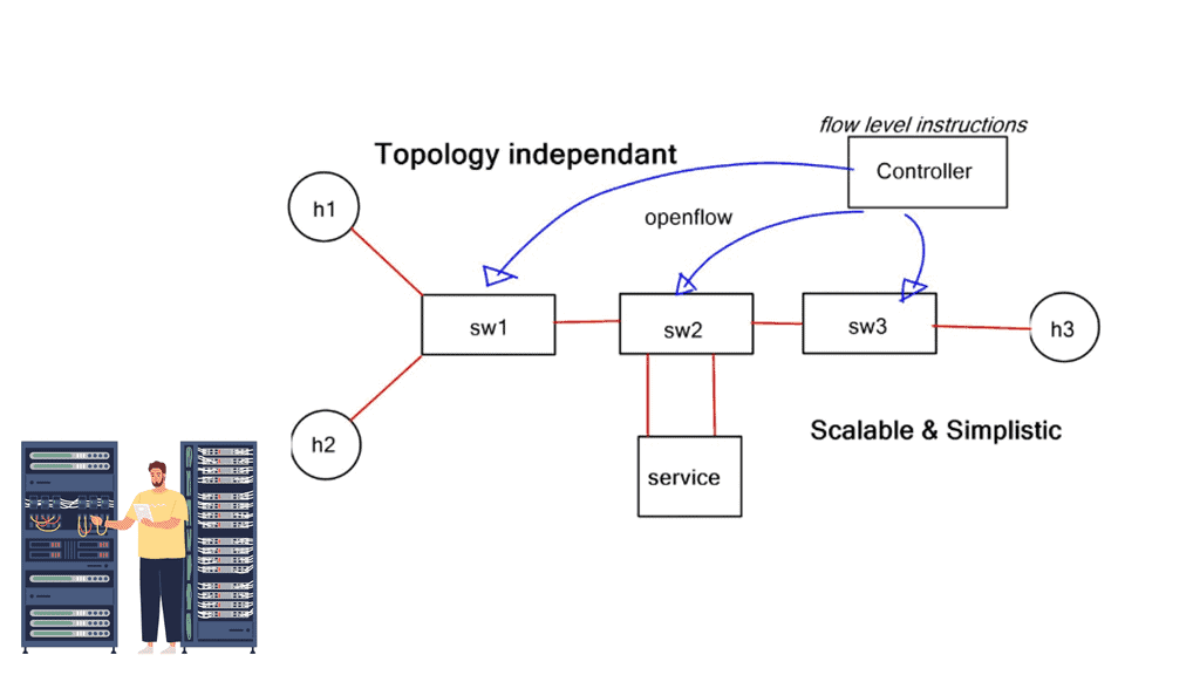
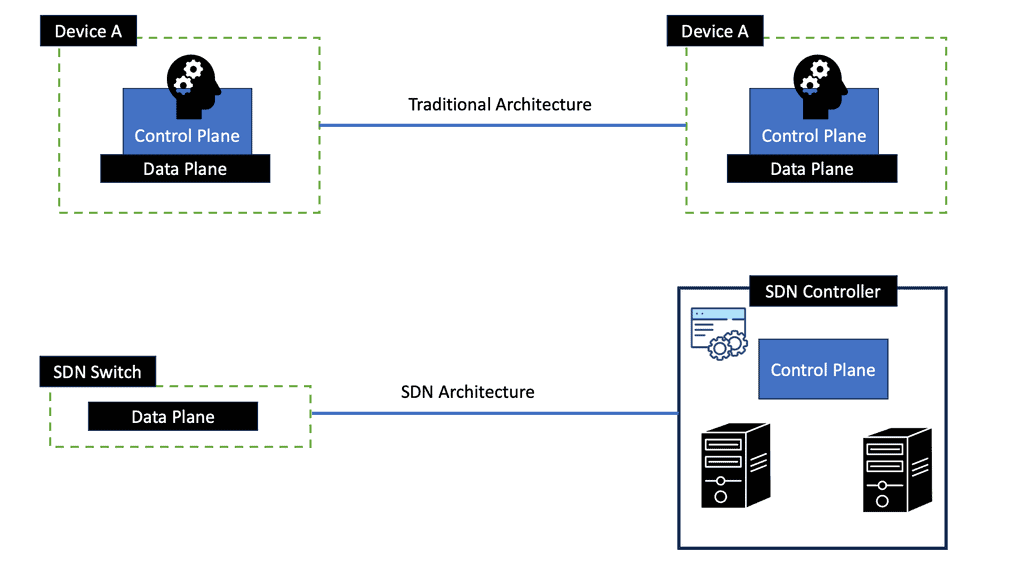
Software-Defined Networking (SDN) introduces a paradigm shift in network management by decoupling the control plane from the data plane. In traditional networks, network devices such as switches and routers possess both control and data plane functionalities. SDN separates these functions, with a centralized controller managing the network's behavior and forwarding decisions. The data plane, consisting of switches and routers, simply follows the instructions provided by the controller.

When BGP and SDN converge, we unlock a new realm of network possibilities. SDN's centralized control and programmability complement BGP's routing capabilities, offering enhanced flexibility and control over network operations. By leveraging SDN controllers, network administrators can dynamically adjust BGP routing policies, optimize traffic flows, and respond to changing network conditions in real-time. This dynamic interaction between BGP and SDN empowers organizations to adapt their networks to ever-evolving requirements efficiently.

The combination of BGP and SDN brings forth several advantages and opens up exciting use cases. Network operators can implement traffic engineering techniques to optimize network paths, improve performance, and minimize congestion. They can also utilize SDN's programmability to automate BGP configuration and provisioning, reducing human errors and accelerating network deployment. Additionally, BGP-SDN integration facilitates the implementation of policies for traffic prioritization, security, and load balancing.

The convergence of BGP and SDN represents a powerful synergy that empowers network administrators to achieve unprecedented levels of flexibility, control, and efficiency. By combining BGP's robust routing capabilities with SDN's programmability and centralized management, organizations can adapt their networks swiftly to meet evolving demands. As the networking landscape continues to evolve, the BGP-SDN combination will undoubtedly play a pivotal role in shaping the future of network architecture.

Highlights: BGP-Based SDN

Understanding BGP and SDN

1- BGP (Border Gateway Protocol) is a routing protocol used to exchange routing information between different networks on the internet. On the other hand, SDN is an architectural approach that separates the control plane from the data plane, allowing network administrators to centrally manage and configure networks through software.

2- BGP-based SDN combines the power of BGP routing with the flexibility and programmability of SDN. Network operators gain enhanced control, scalability, and agility in managing their networks by leveraging BGP as the control plane protocol in an SDN architecture. This marriage of BGP and SDN opens up new possibilities for network automation, policy-driven routing, and dynamic traffic engineering.

3- One critical advantage of BGP-based SDN is its ability to simplify network management. With centralized control and programmability, network operators can define policies and rules that govern their networks’ behavior.

4- This paves the way for efficient traffic engineering and the ability to respond dynamically to changing network conditions. Additionally, BGP-based SDN provides better scalability, allowing for the distribution of control plane functions across multiple controllers.

Knowledge Check: Prefer EBGP over iBGP

### What is eBGP?

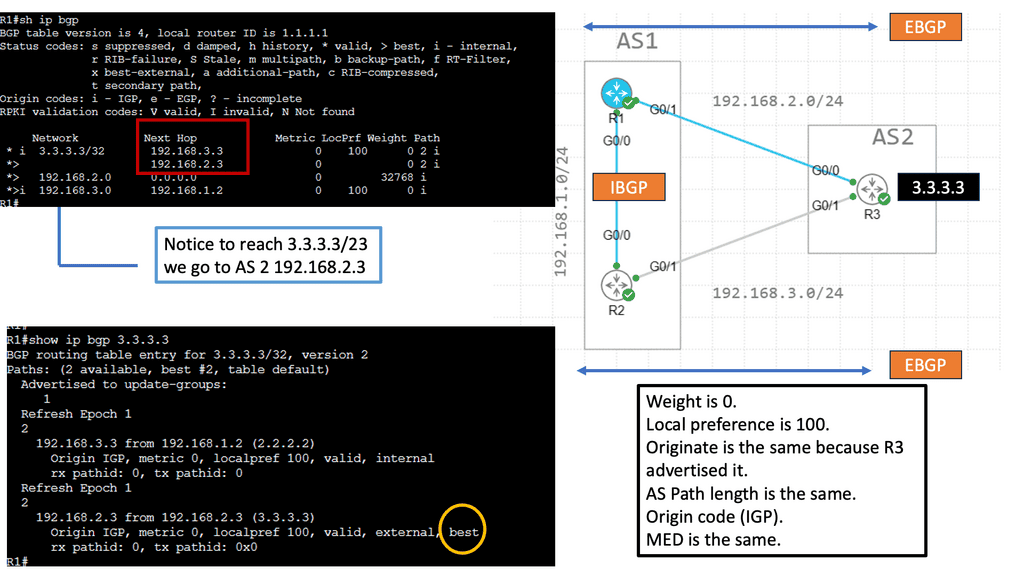
eBGP, or External BGP, is used for routing between different autonomous systems (AS). An autonomous system is essentially a collection of IP networks and routers under the control of a single organization. eBGP is employed when these networks communicate with each other. Its primary purpose is to exchange routing information between these independent systems, ensuring data can travel from one network to another across the globe.

eBGP is characterized by its scalability and efficiency in handling large amounts of routing information. It operates by sending updates about network reachability, allowing each AS to determine the best path for data transmission. This makes it an indispensable tool for ISPs and large enterprises managing extensive network infrastructures.

### Understanding iBGP

On the other hand, iBGP, or Internal BGP, operates within a single autonomous system. Its purpose is to distribute routing information obtained from eBGP to all routers within the same AS. Unlike eBGP, which is concerned with external communication, iBGP ensures that all routers within the AS have a consistent view of the network topology.

iBGP is crucial for maintaining the integrity and efficiency of a network’s internal routing. It prevents routing loops and ensures that data packets find the most optimal path within the AS. Additionally, it works seamlessly with other interior gateway protocols like OSPF and IS-IS to enhance network performance.

### Key Differences Between eBGP and iBGP

While both eBGP and iBGP are integral parts of the BGP protocol, they serve distinct purposes and operate under different conditions. Here are some key differences:

1. **Operational Scope**: eBGP is used between different AS, whereas iBGP operates within a single AS.

2. **Path Selection**: eBGP selects routes based on the AS path, preferring shorter paths, while iBGP relies on the IGP metrics to determine the best route within the AS.

3. **Hop Count**: eBGP sessions are typically limited to a single hop, although multi-hop configurations are possible. iBGP sessions, however, can span multiple hops within the AS.

4. **Route Propagation**: eBGP routes are advertised to iBGP peers, but iBGP routes are not automatically advertised to other iBGP peers, requiring additional configuration to propagate routes.

### Practical Applications and Considerations

Network administrators must carefully consider their use of eBGP and iBGP when designing and managing network infrastructures. eBGP is essential for connecting to external networks and the internet, while iBGP ensures efficient internal routing. Balancing both is key to achieving optimal network performance and reliability.

When configuring BGP, it is also important to implement security measures to prevent attacks such as route hijacking. This includes using route filtering, authentication, and monitoring tools to safeguard network operations.
## The Role of BGP in Traditional Networking ##

BGP has long been the backbone of internet routing, enabling data to traverse global networks efficiently. Its robust, policy-driven approach allows for complex routing decisions based on a variety of factors like path attributes and network policies. However, traditional BGP setups can be rigid, often requiring manual configurations that are time-consuming and error-prone. This is where SDN comes into play, offering a more dynamic and programmable approach to network management.

## Integrating BGP with SDN: A New Era

The integration of BGP with SDN is not just about replacing old systems but augmenting them. By leveraging SDN’s centralized control and programmability, BGP-based SDN allows for automated policy changes and real-time network optimization. This results in a more agile network that can adapt to changing demands and conditions. The centralized SDN controller can dynamically manage BGP routes, reducing the complexity and improving the responsiveness of the network.

## BGP SDN Challenges 

Despite its advantages, implementing BGP-based SDN is not without its challenges. Integrating SDN with existing BGP infrastructures can be complex and requires careful planning and execution. There is also the need for network professionals to acquire new skills and knowledge to effectively manage these advanced systems. Furthermore, ensuring compatibility between different SDN solutions and traditional network devices remains a critical consideration.

## Note: New Attack Surface 

While BGP-based SDN holds immense potential, it also poses certain challenges. One of the primary concerns is the complexity of implementation and migration. Integrating BGP with SDN requires careful planning and coordination to ensure a smooth transition. Moreover, security and privacy considerations must be considered when deploying BGP-based SDN, as centralized control introduces new attack vectors that must be mitigated.

Critical Components of BGP SDN:

a. BGP Routing: BGP SDN leverages the BGP protocol to manage the routing decisions between different networks. This enables efficient and optimized routing and seamless communication across various domains.

b. SDN Controller: The SDN controller acts as the centralized brain of the network, providing a single point of control and management. It enables network administrators to define and enforce network policies, configure routing paths, and allocate network resources dynamically.

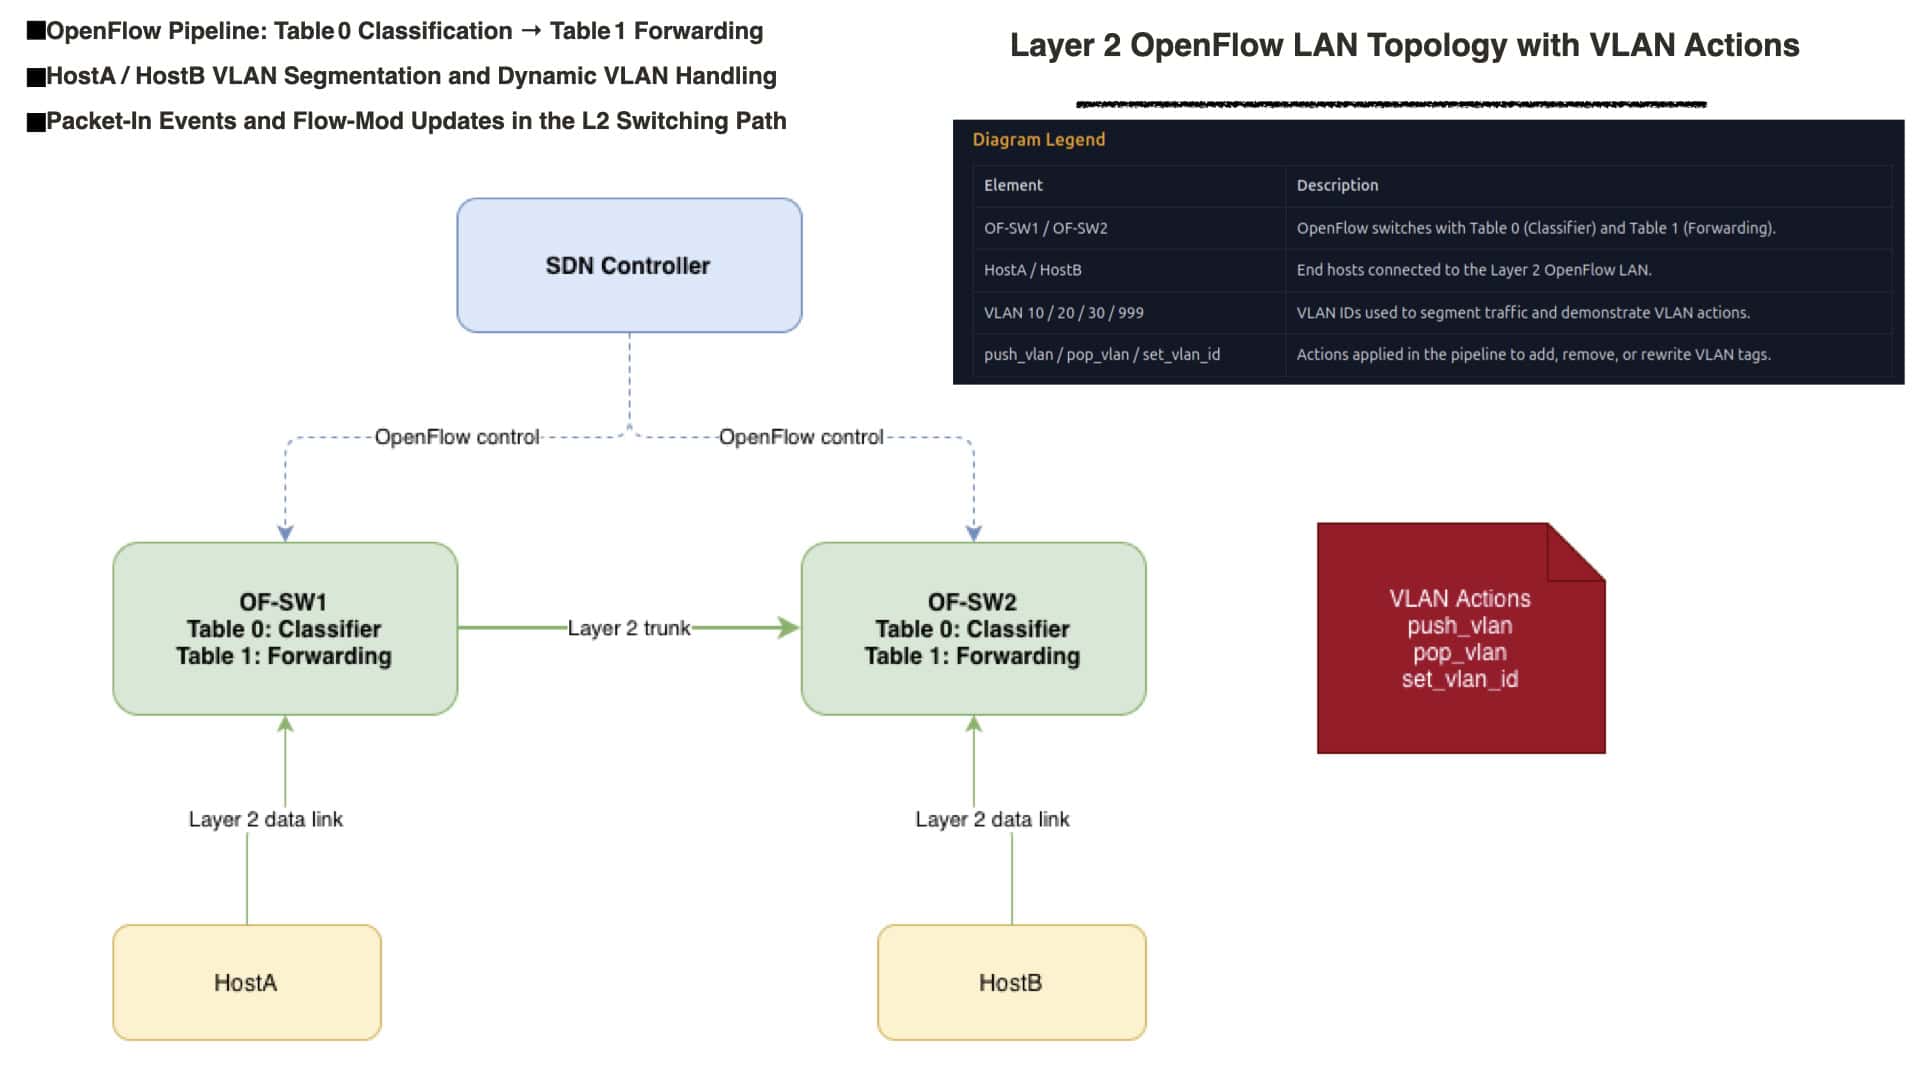
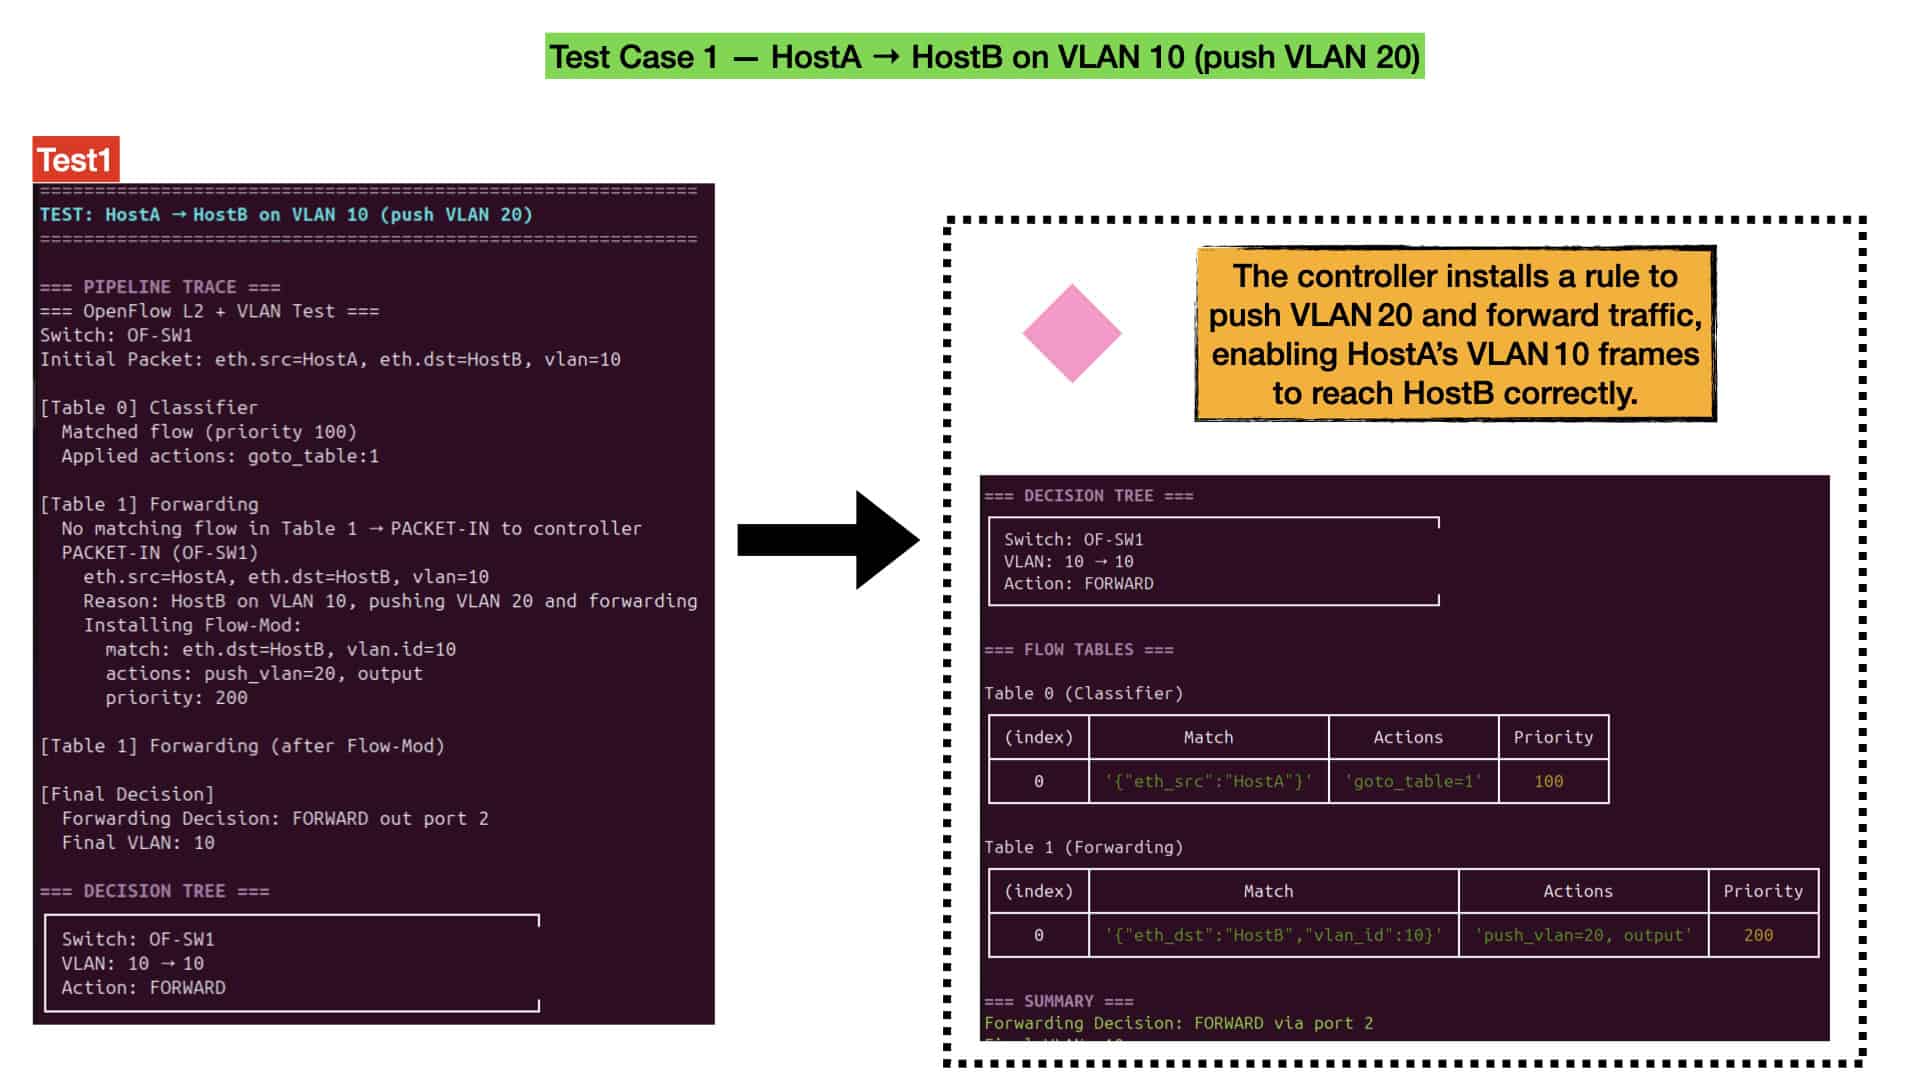
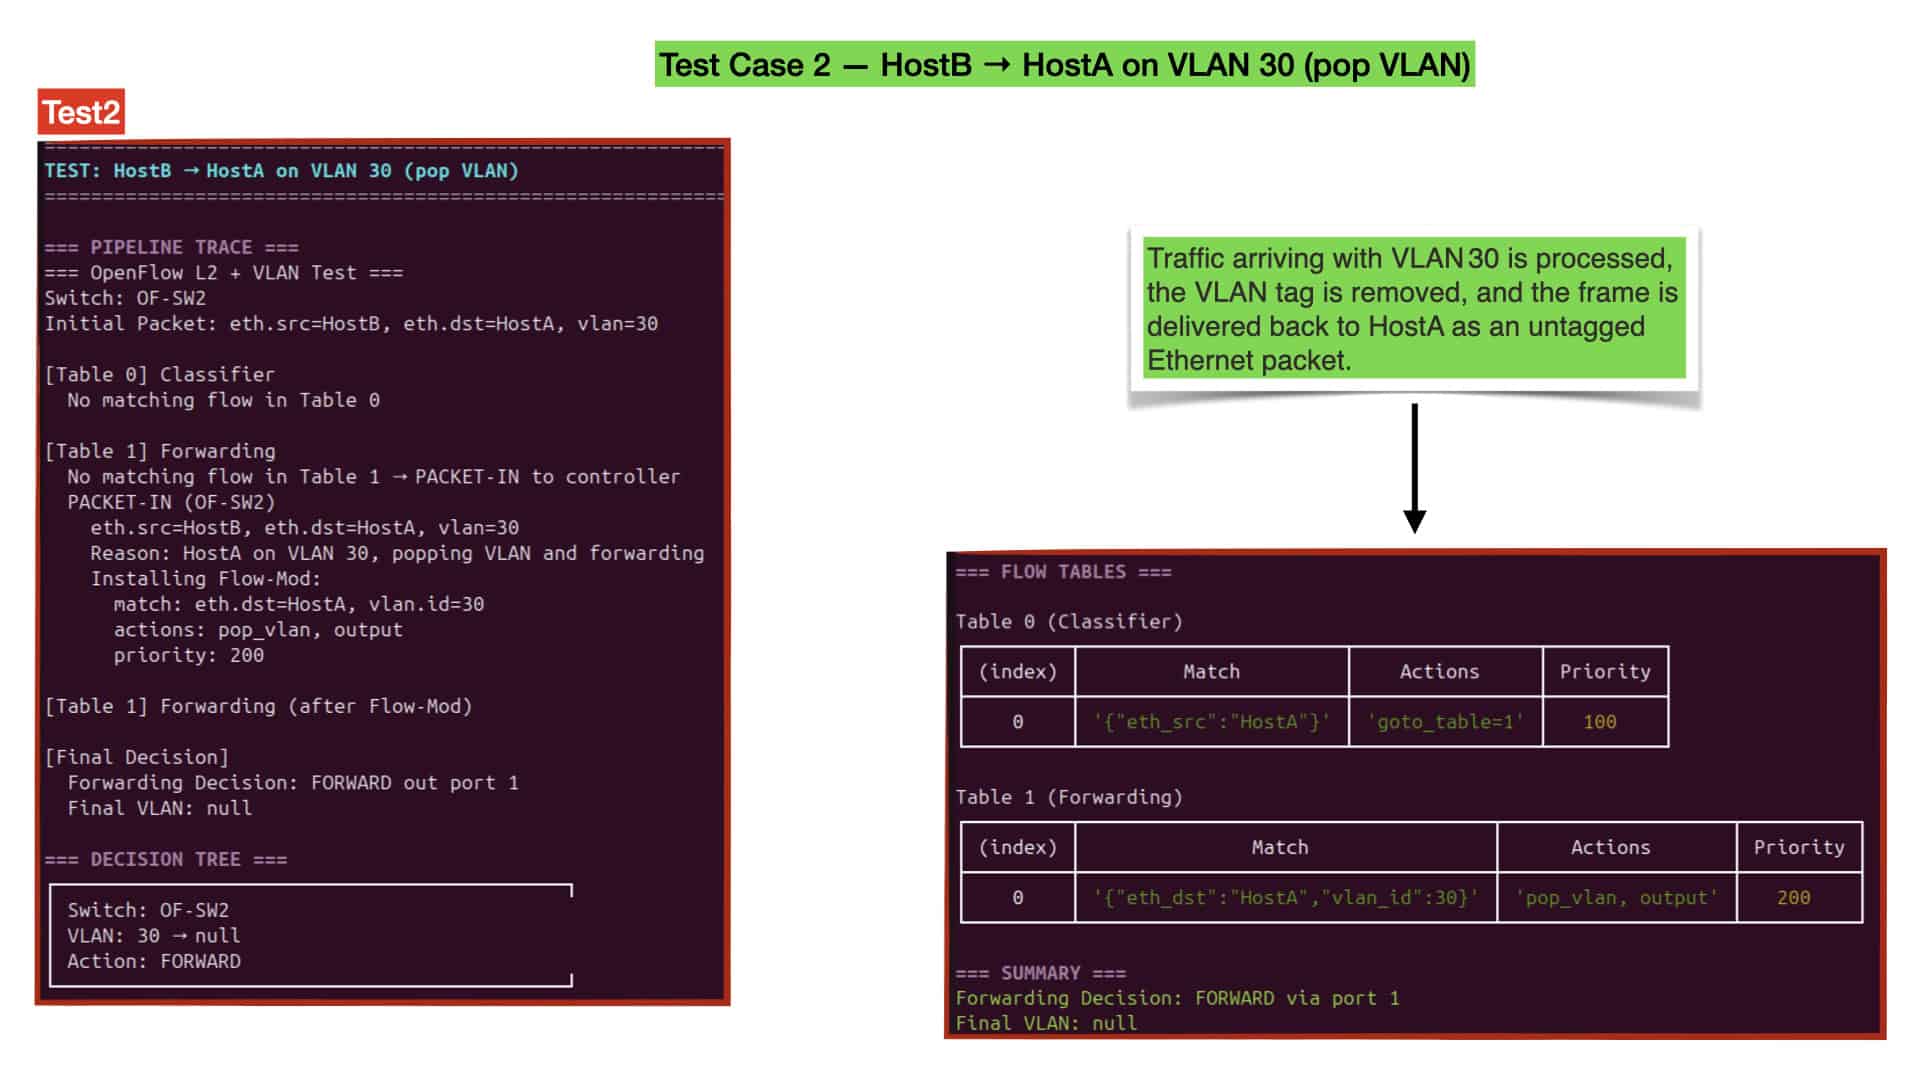
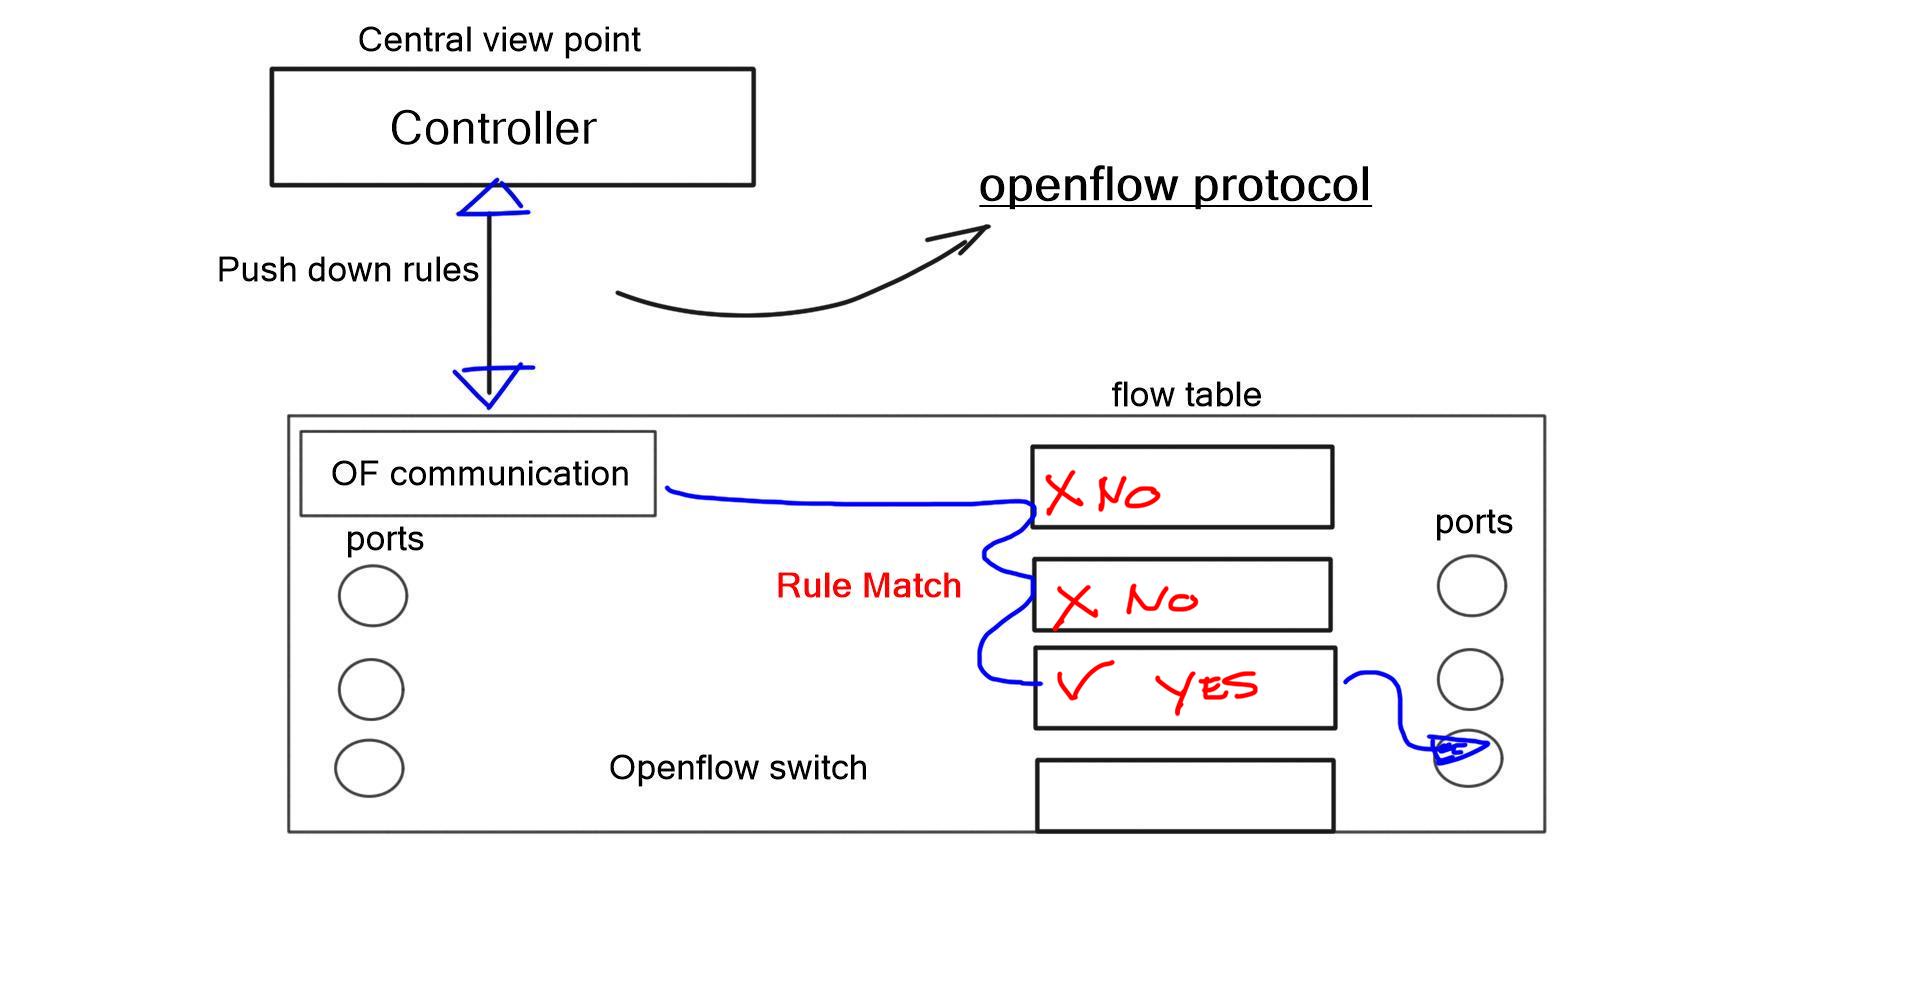
c. OpenFlow Protocol: BGP SDN uses the OpenFlow protocol to communicate between the SDN controller and the network switches. OpenFlow enables the controller to programmatically control the forwarding behavior of switches, resulting in greater flexibility and agility.

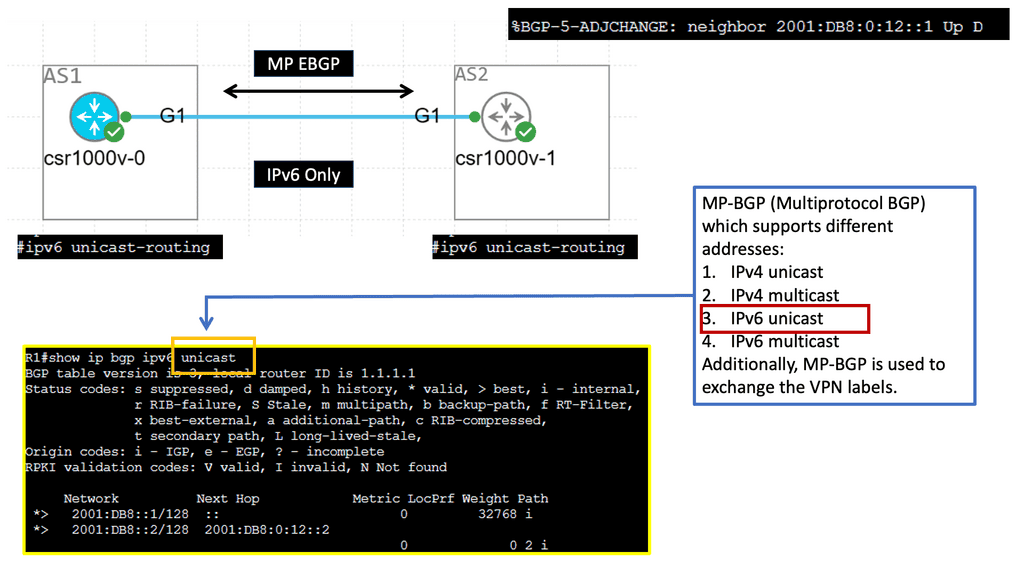
Example BGP Technology: IPv6 BGP

### IPv6 and BGP: A Synergistic Relationship

Transitioning to IPv6 doesn’t just mean more addresses; it means enhancing the operational capacity of BGP. IPv6 introduces features like simplified header formats and improved multicast routing, which can streamline the BGP process. This section will explore how IPv6 enhances BGP operations, offering benefits such as reduced latency, improved security, and better support for mobile networks.

### Challenges and Considerations in IPv6 BGP Deployment

Despite its advantages, the deployment of IPv6 within BGP is not without challenges. Network engineers face hurdles such as compatibility with existing IPv4 infrastructure, the complexity of dual-stack configurations, and the need for updated hardware and software. We’ll examine these challenges and provide insights into how organizations can navigate them to successfully implement IPv6 in their BGP configurations.
Benefits of BGP SDN:

a. Enhanced Flexibility: BGP SDN allows network administrators to tailor their network infrastructure to meet specific requirements. With centralized control, network policies can be easily modified or updated, enabling rapid adaptation to changing business needs.

b. Improved Scalability: Traditional network architectures often struggle to handle the growing demands of modern applications. BGP SDN provides a scalable solution by enabling dynamic allocation of network resources, optimizing traffic flow, and ensuring efficient bandwidth utilization.

c. Simplified Network Management: BGP SDN’s centralized management simplifies network operations. Network administrators can configure, monitor, and manage the entire network from a single interface, reducing complexity and improving overall efficiency.

Use Cases for BGP SDN:

a. Data Centers: BGP SDN is well-suited for data center environments, where rapid provisioning, scalability, and efficient workload distribution are critical. By leveraging BGP SDN, data centers can seamlessly integrate physical and virtual networks, enabling efficient resource allocation and workload migration.

b. Service Providers: BGP SDN allows service providers to offer their customers flexible and customizable network services. It enables the creation of virtual private networks, traffic engineering, and service chaining, resulting in improved service delivery and customer satisfaction.

BGP Technologies in BGP SDN

Understanding BGP Route Reflection

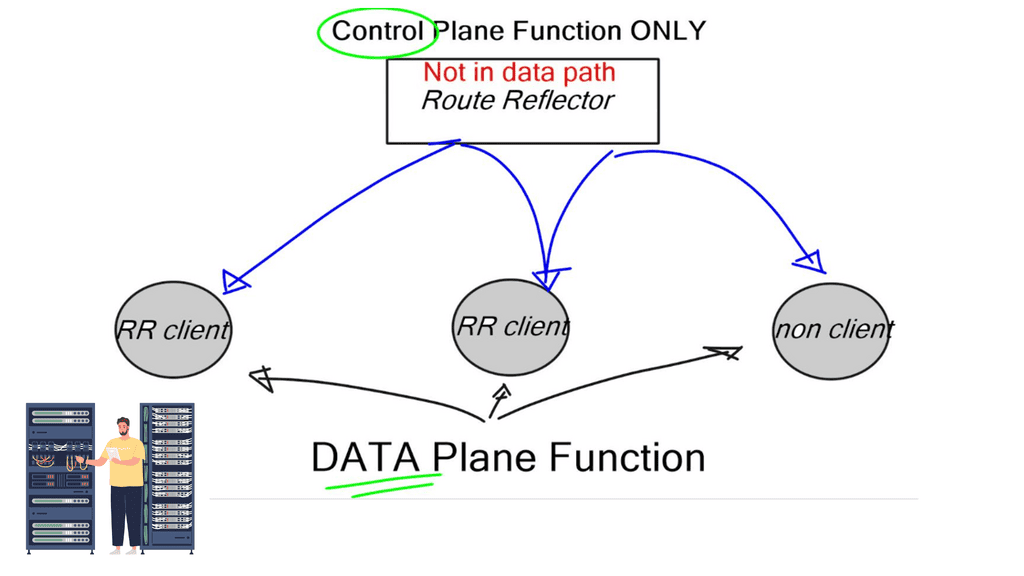
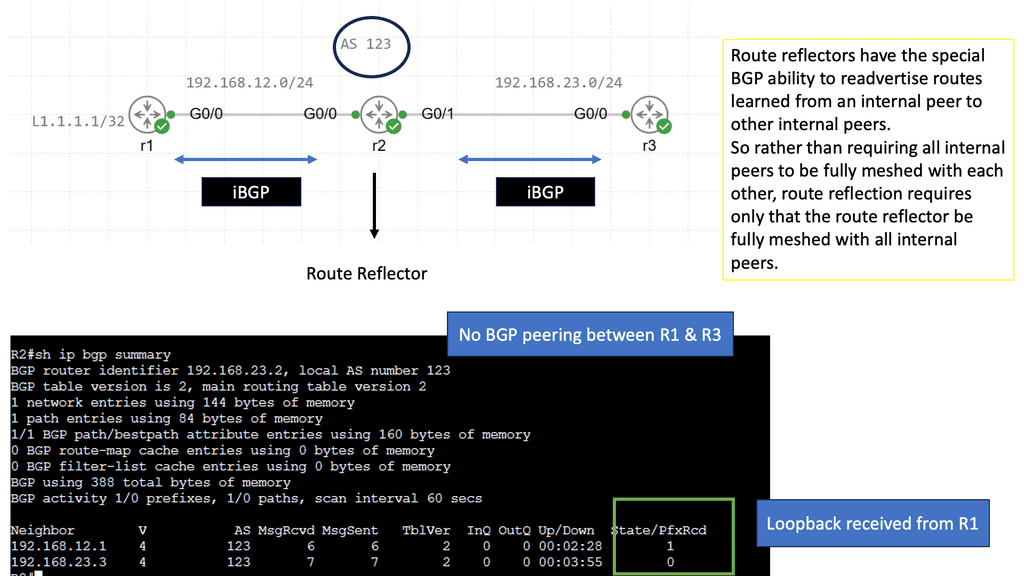
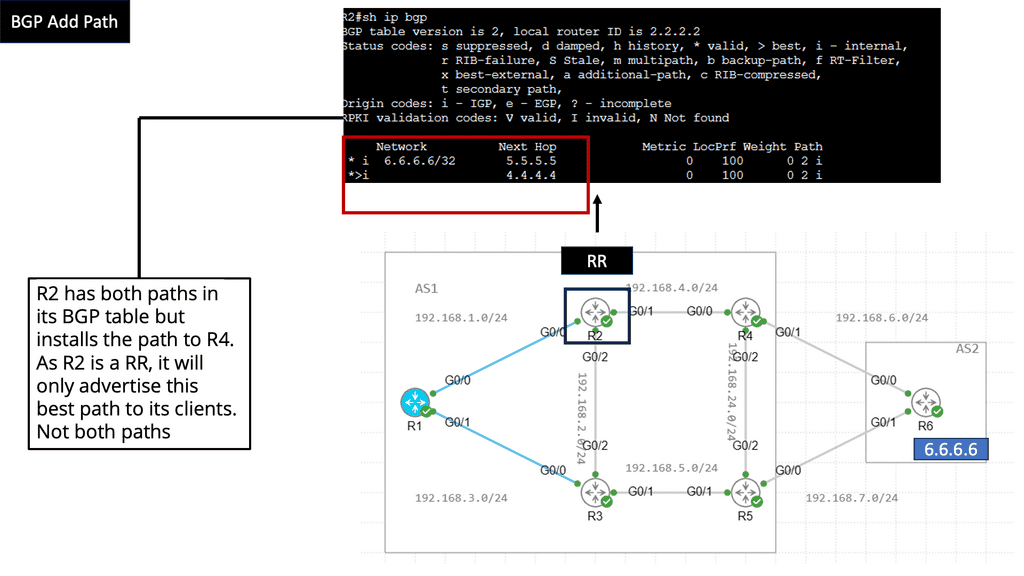
A – 🙂 BGP route reflection is a technique used to alleviate the burden of full-mesh connectivity in BGP networks. Traditionally, in a fully meshed BGP configuration, all routers must establish a direct peer-to-peer connection with every other router, resulting in complex and resource-intensive setups. Route reflection introduces a hierarchical approach that reduces the number of required connections, providing a more scalable alternative.

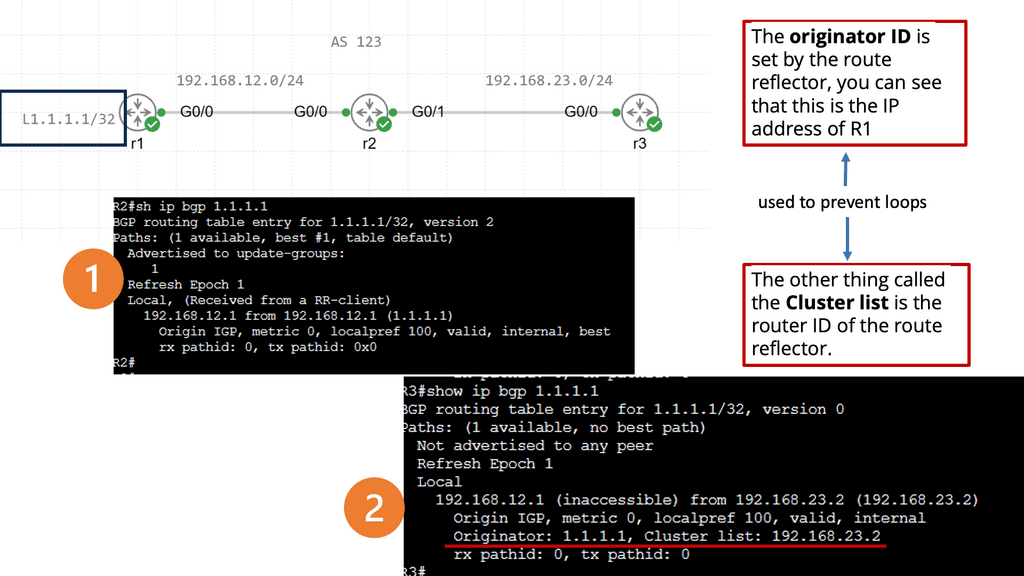
B – 🙂 Route reflectors act as centralized points within a BGP network and reflect and propagate routing information to other routers. They collect BGP updates from their clients and reflect them to other clients, ensuring a simplified and efficient distribution of routing information. Route reflectors maintain the overall consistency of the BGP network while reducing the number of required peer connections.

C- 🙂 To implement BGP route reflection, one or more routers within the network need to be configured as route reflectors. These route reflectors should be strategically placed to ensure efficient routing information dissemination. Clients, also known as non-route reflectors, establish peering sessions with the route reflectors and send their BGP updates to be reflected. Route reflector clusters can also be formed to provide redundancy and load balancing.
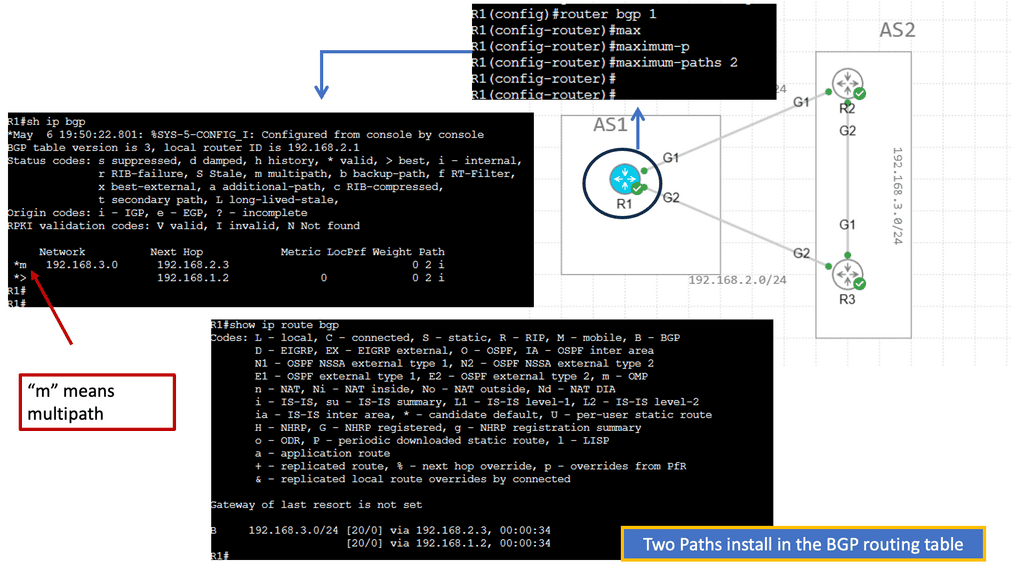
Understanding BGP Multipath

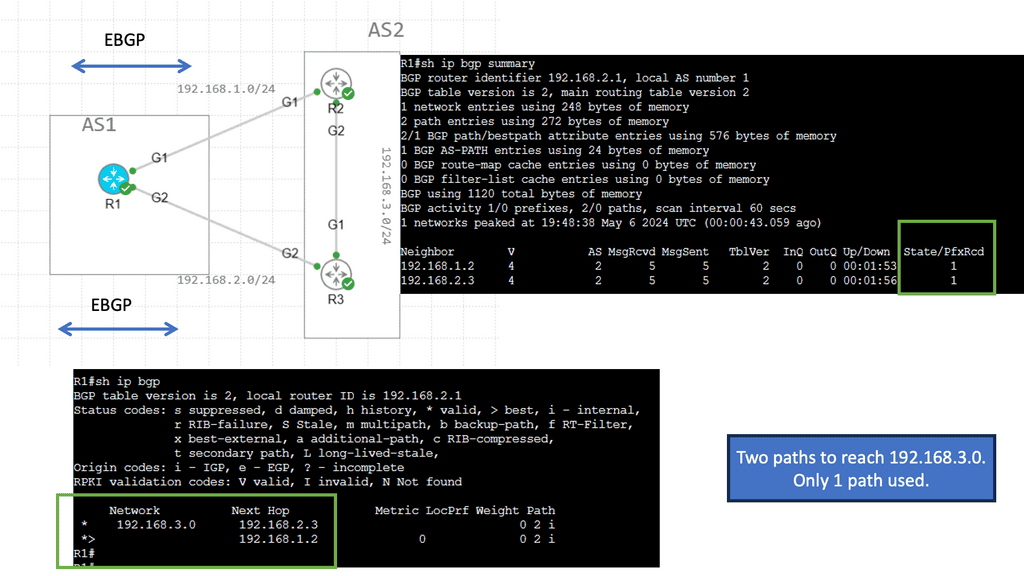
BGP multipath, short for Border Gateway Protocol multipath, is a feature that enables the use of multiple paths for traffic forwarding in a network. Traditionally, BGP selects a single best path based on attributes like AS path length, origin type, and MED (Multi-Exit Discriminator) value. However, with BGP multipath, multiple paths can be utilized simultaneously, distributing traffic across multiple links.

Enhanced Network Performance: BGP multipath optimizes network performance by load-balancing traffic using multiple paths. This helps avoid congestion on specific links and ensures efficient utilization of available bandwidth, resulting in faster and more reliable data transmission.

Improved Resilience: BGP multipath enhances network resilience by providing redundancy. In case of link failures or congestion, traffic can be automatically rerouted through alternative paths, minimizing downtime and ensuring continuous connectivity. This dramatically improves the overall reliability of the network infrastructure.
SDN and BGP

BGP SDN, or Border Gateway Protocol Software-Defined Networking, combines two powerful technologies: the Border Gateway Protocol (BGP) and Software-Defined Networking (SDN). BGP, a routing protocol, facilitates inter-domain routing, while SDN provides centralized control and programmability of the network. Together, they offer a dynamic and adaptable networking environment.

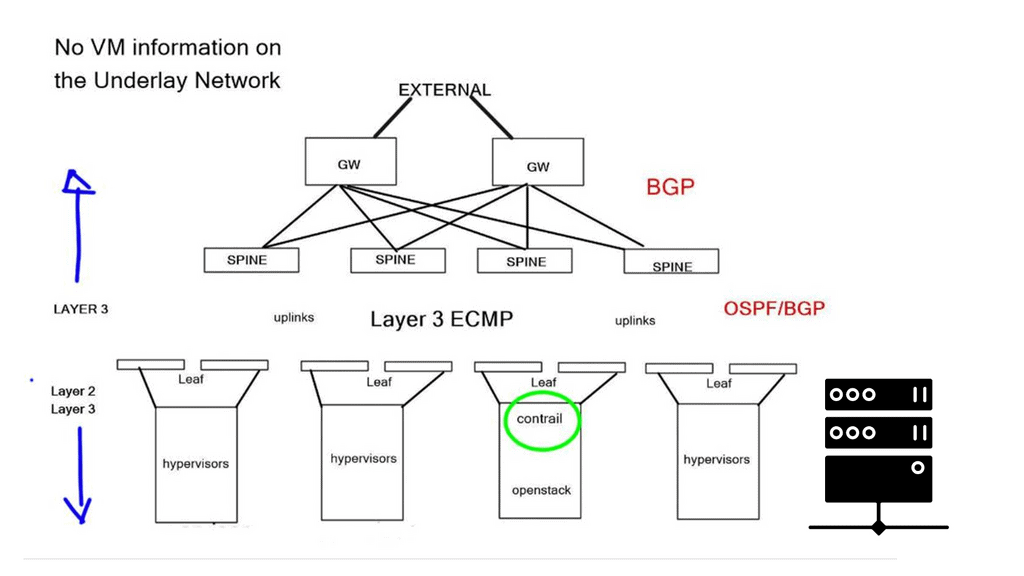
While Border Gateway Protocol (BGP) was initially designed to connect networks operated by different companies, such as transit service providers, providers of large-scale data centers discovered that it could be used for spine and leaf fabrics.

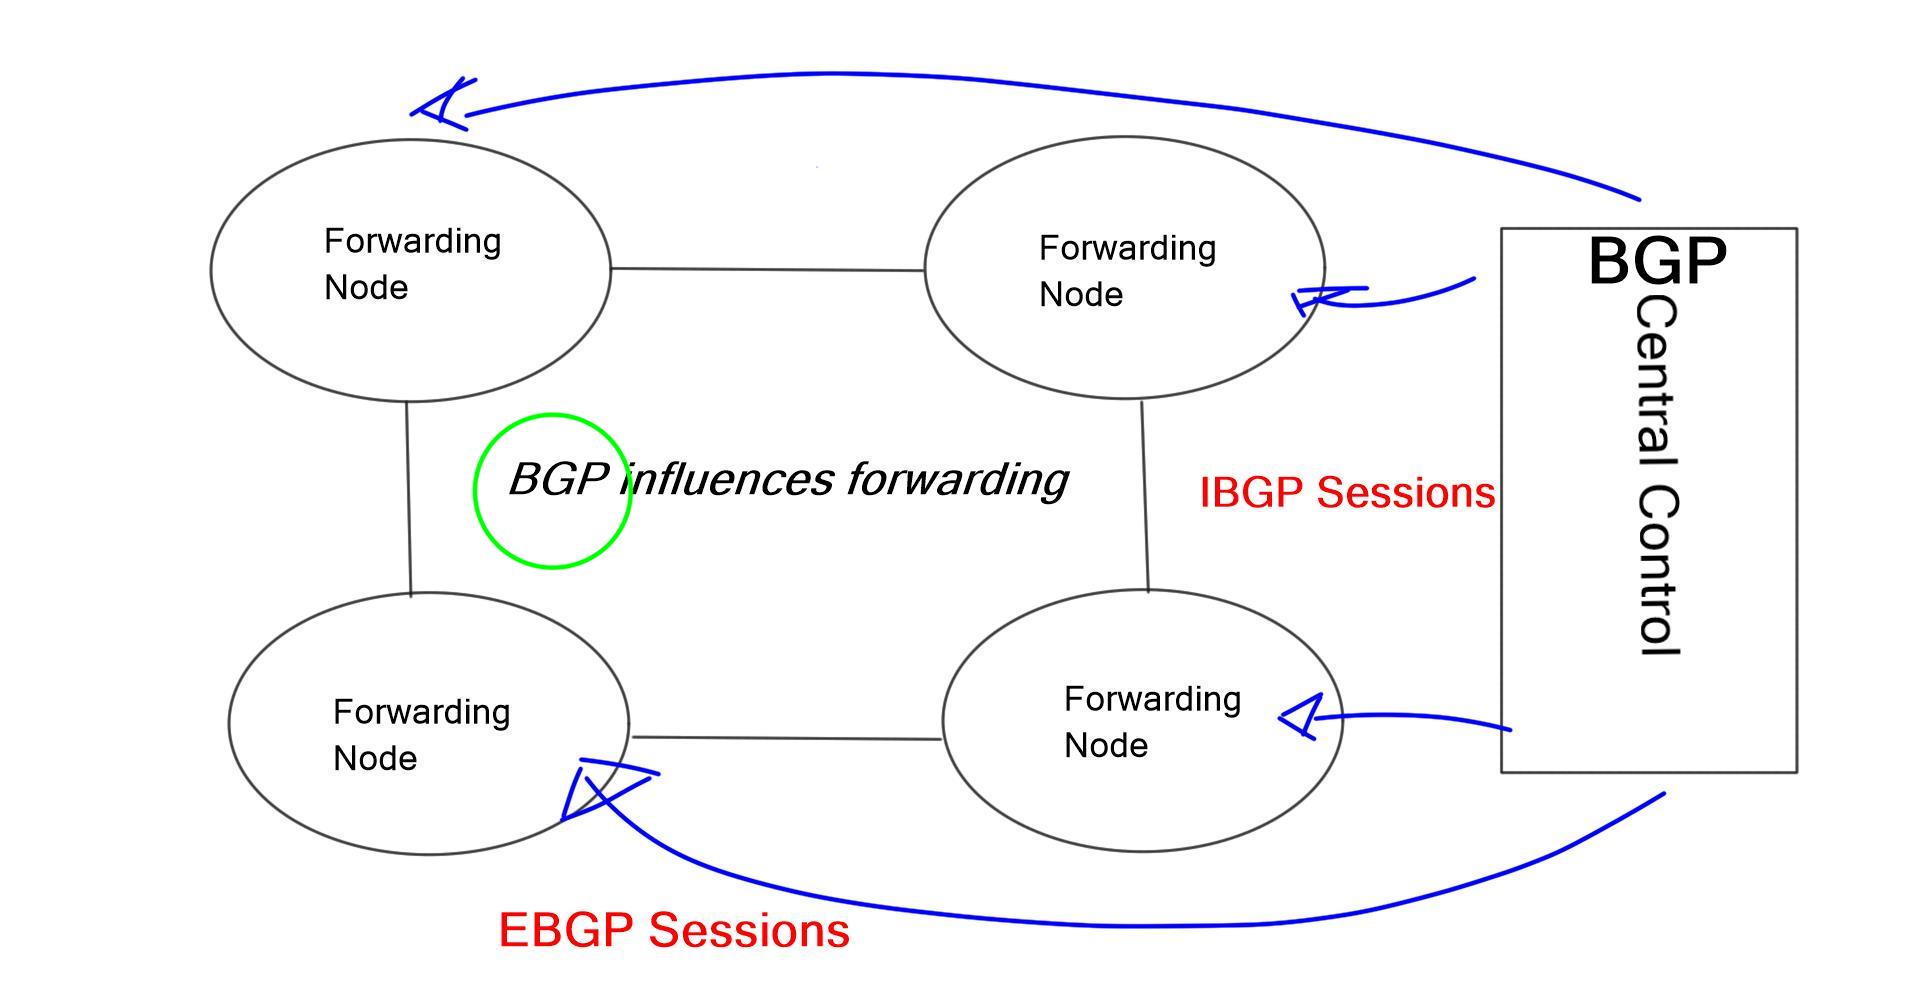
BGP can also be used as an SDN because it already runs on all routers. According to the diagram below, each router in the fabric is connected to an iBGP controller.

Augmented Model

After the iBGP sessions are established, the controller can read the entire topology to determine which path the flow should be pinned to and which flows should avoid the path over which the flow is passing.

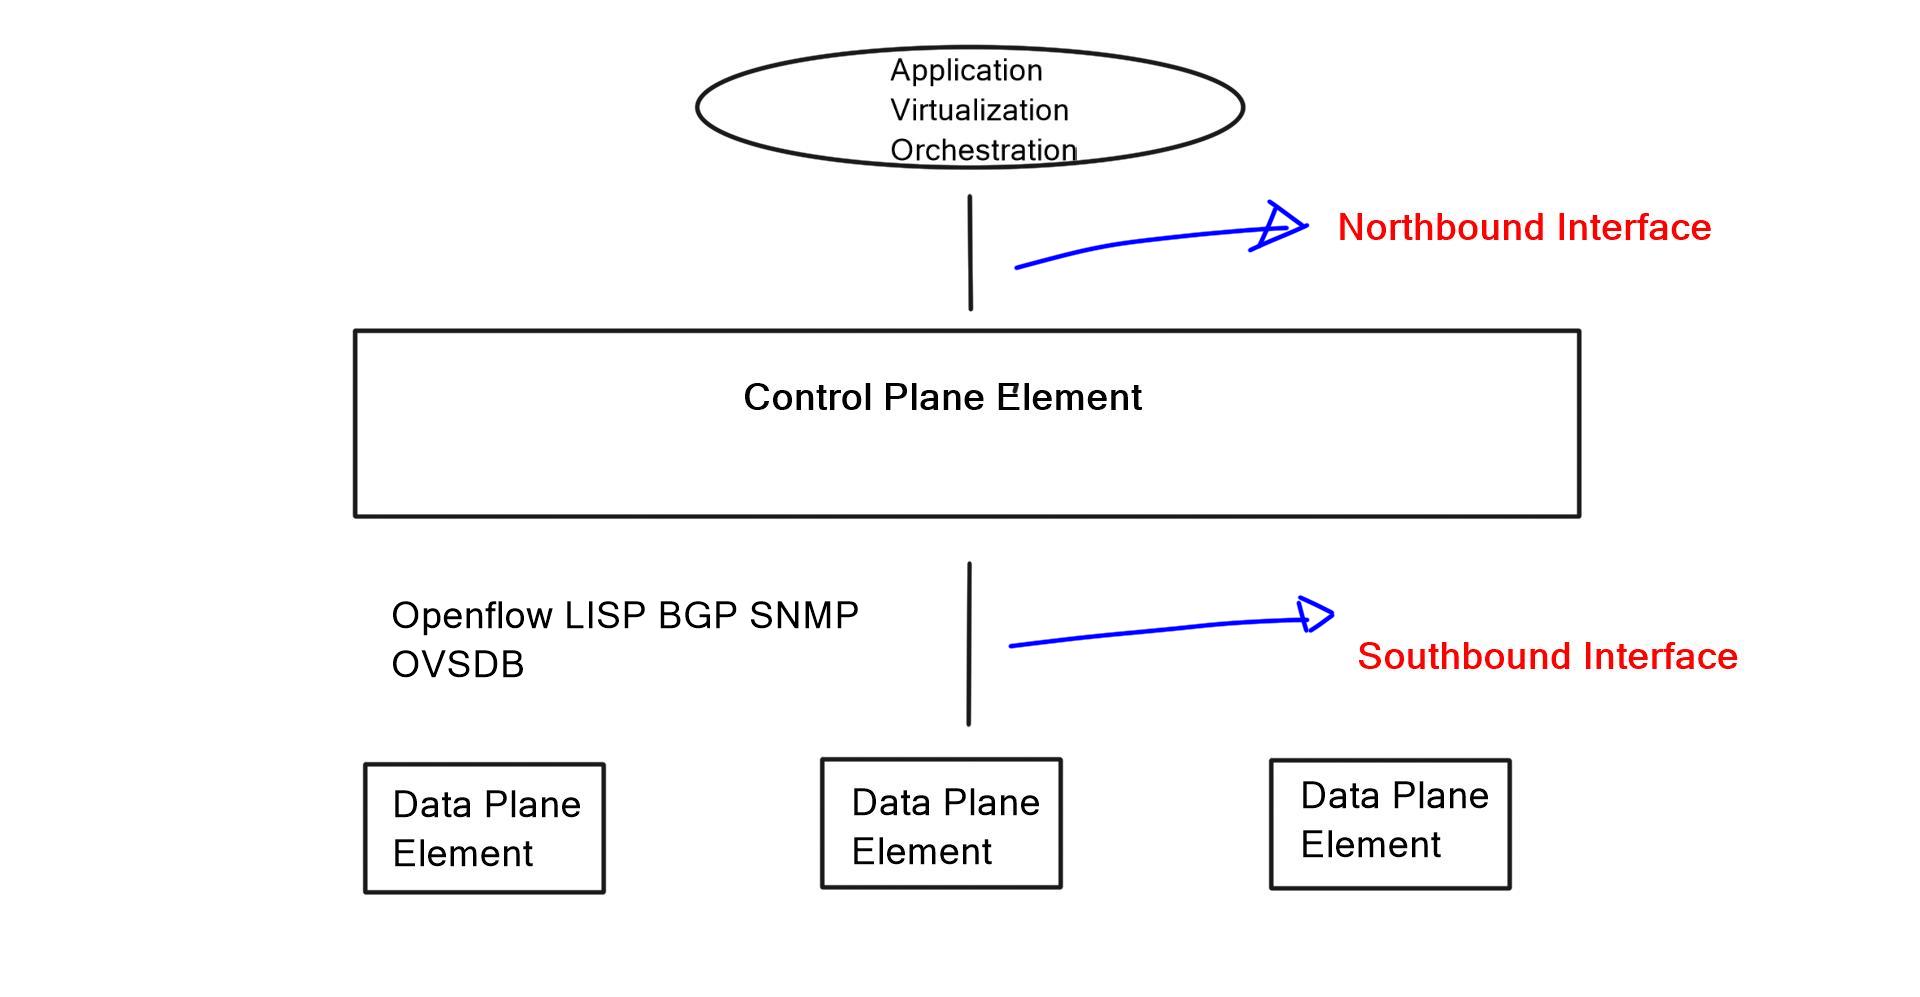
An augmented model uses a centralized control plane that interacts directly with a distributed control plane (eBGP). Interestingly, the same protocol used to push policy (the southbound interface) is also used to discover and distribute topology and reachability information in this hybrid model implementation.

The Role of SDN

Before we start our journey on BGP SDN, let us first address what SDN means. The Software-Defined Networking (SDN) framework has a large and varied context. Multiple components, including the OpenFlow protocol, may or may not be used. Some evolving SDN use cases leverage the capabilities of the OpenFlow protocol, while others do not require it.

OpenFlow is only one of those protocols within the SDN architecture. This post addresses using the Border Gateway Protocol (BGP) as the transfer protocol between the SDN controller and forwarding devices, enabling BGP-based SDN, also known as BGP SDN.

BGP and OpenFlow

– BGP and OpenFlow are monolithic, meaning they are not used simultaneously. Integrating BGP to SDN offers several use cases, such as DDoS mitigation, exception routing, forwarding optimizations, graceful shutdown, and integration with legacy networks.

– Some of these use cases are available using OpenFlow Traffic Engineering; others, like graceful shutdown and integration with the legacy network, are easier to accomplish with BGP SDN. 

– When BGP and OpenFlow are combined, they create a powerful synergy that enhances network control and performance. BGP provides the foundation for inter-domain routing and connectivity, while OpenFlow facilitates granular traffic engineering within a domain.

– Together, they enable network administrators to fine-tune routing decisions, balance traffic across multiple paths, and enforce quality of service (QoS) policies.

BGP Add Path Feature

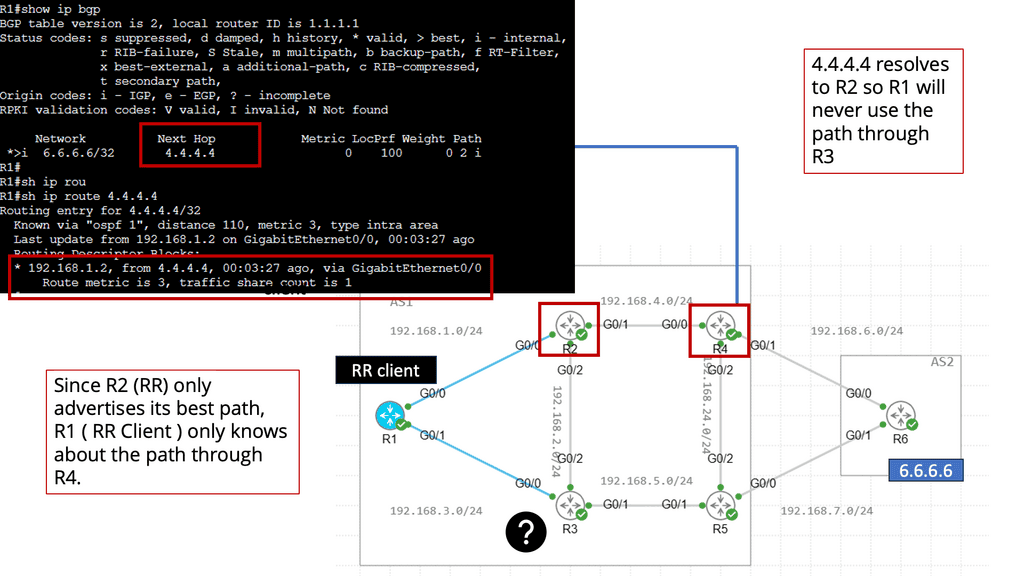
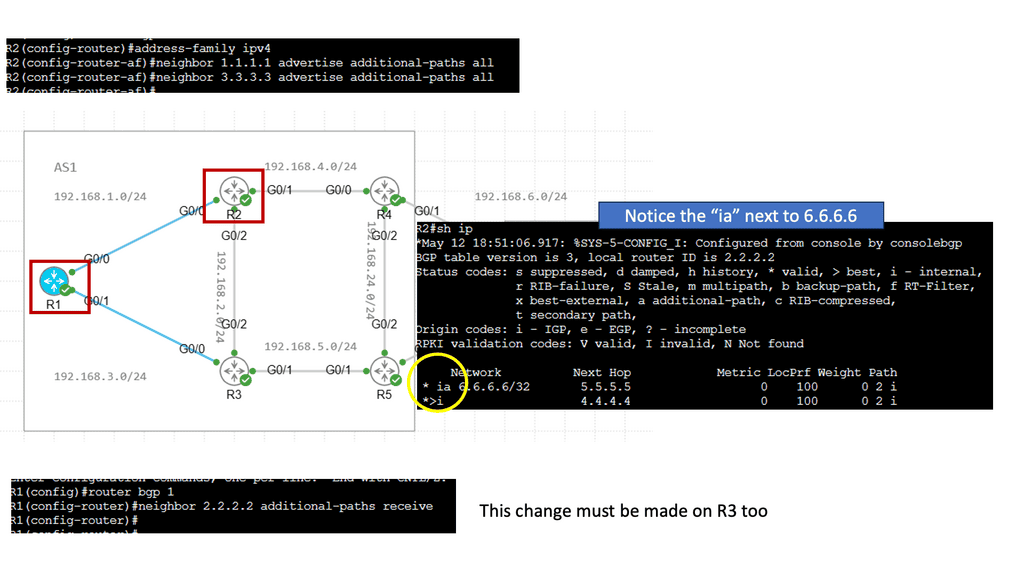
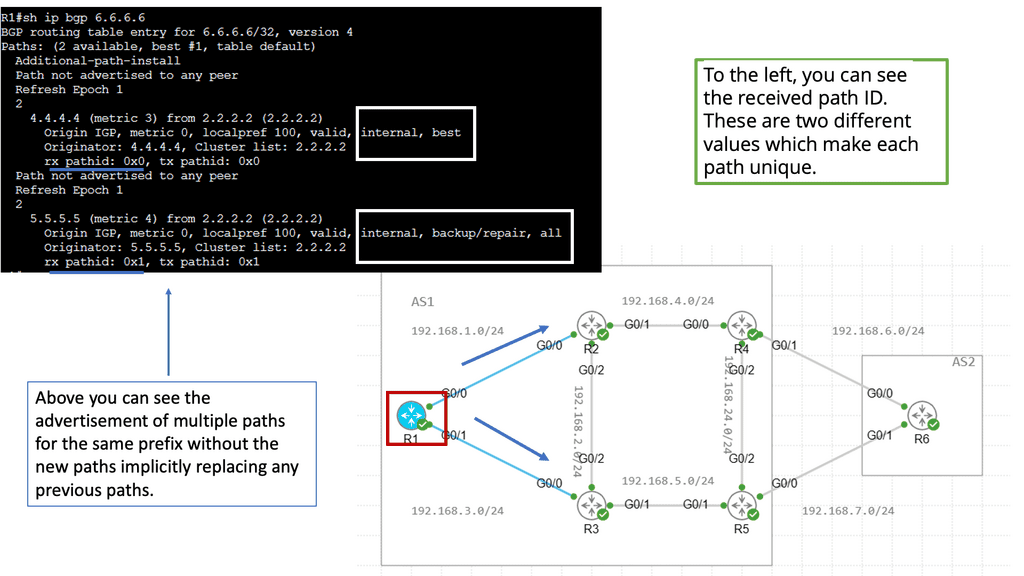
The BGP Add Path feature is designed to address the limitations of traditional BGP routing, where only the best path to a destination is advertised. With Add Path, BGP routers can advertise multiple paths to a destination network, providing increased routing options and allowing for more efficient traffic engineering. 

Introducing the Add Path feature brings several benefits to network administrators and service providers. Firstly, it enables better load balancing and traffic distribution across multiple paths, leading to optimized network utilization. Additionally, it enhances network resiliency by providing alternative paths in case of link failures or congestion. 
Before you proceed, you may find the following post helpful:

  1. BGP Explained
  2. Transport SDN
  3. What is OpenFlow
  4. Software Defined Perimeter Solutions
  5. WAN SDN
  6. OpenFlow And SDN Adoption
  7. HP SDN Controller

BGP-Based SDN

What is BGP?

What is the BGP protocol in networking? Border Gateway Protocol (BGP) is the routing protocol under the Exterior Gateway Protocol (EGP) category. In addition, we have separate protocols, which are Interior Gateway Protocols (IGPs). However, IGP can have some disadvantages.

Firstly, policies are challenging to implement with an IGP because of the need for more flexibility. Usually, a tag is the only tool available that can be problematic to manage and execute on a large-scale basis. In the age of increasingly complex networks in both architecture and services, BGP presents a comprehensive suite of knobs to deal with complex policies, such as the following:

• Communities

• AS_PATH filters

• Local preference

• Multiple exit discriminator (MED

Highlighting BGP-based SDN 

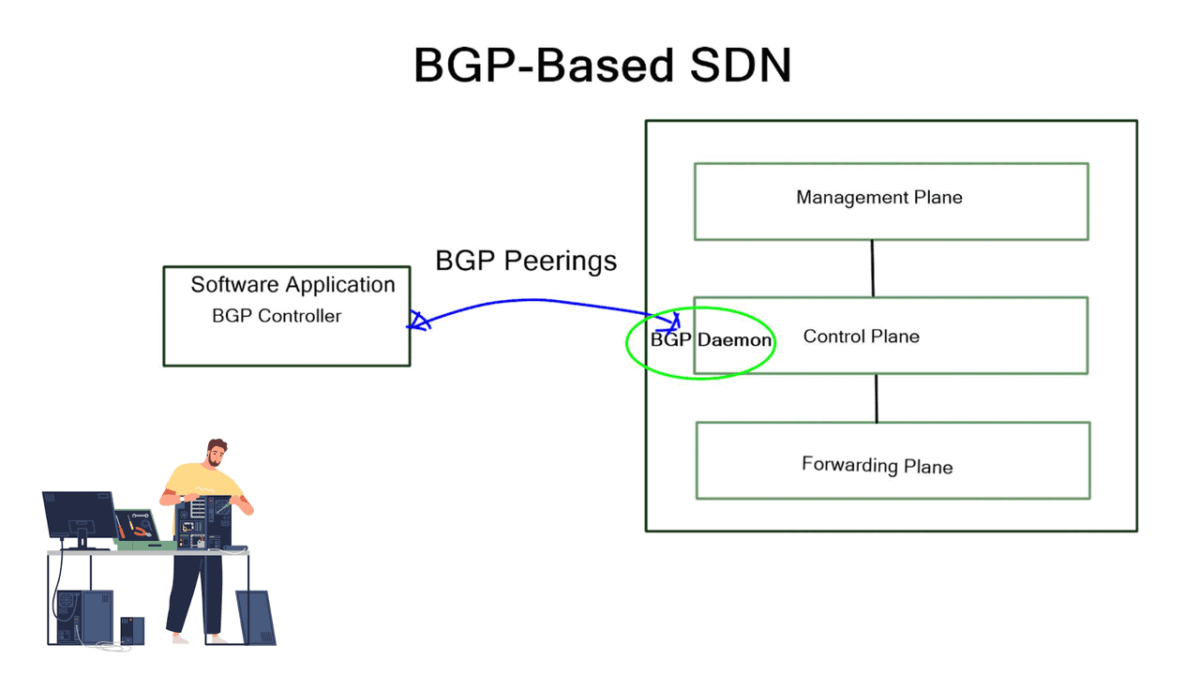
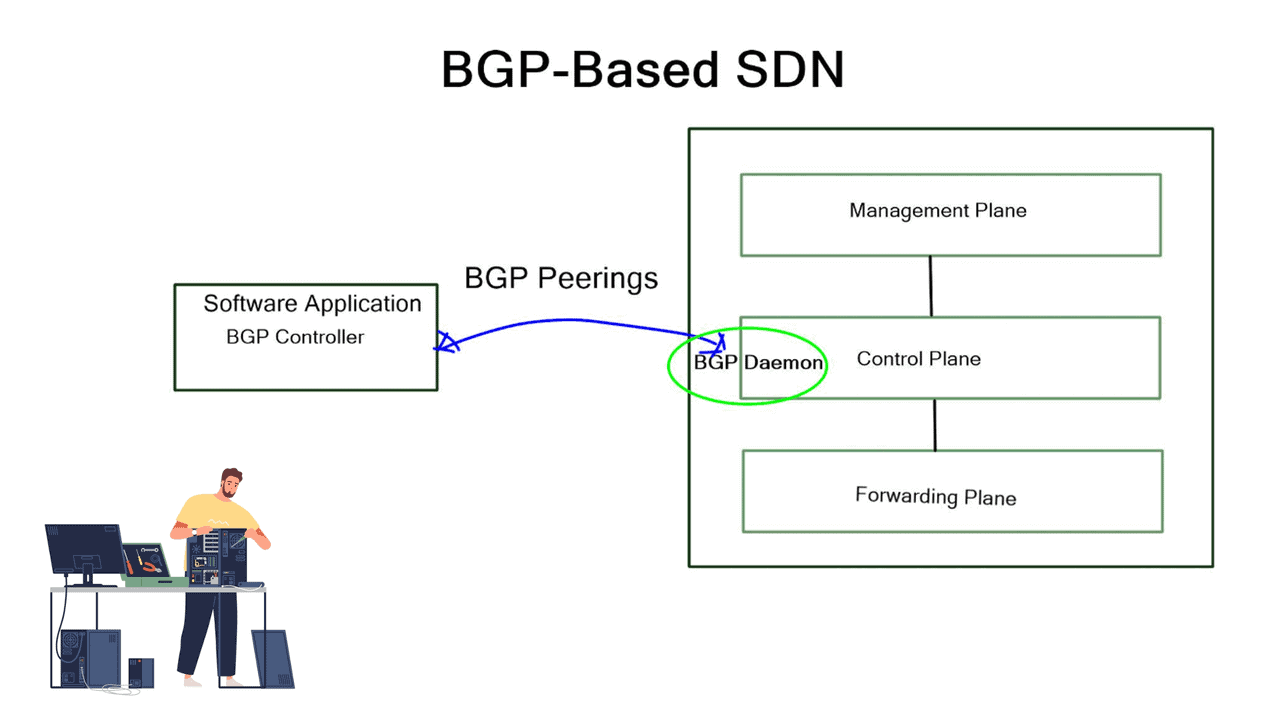
BGP-based SDN involves two main solution components that may be integrated into several existing BGP technologies. First, we have an SDN controller component that speaks BGP and decides what needs to be done. Second, we have a BGP originator component that sends BGP updates to the SDN controller and other BGP peers. For example, the controller could be a BGP software package running on Open Daylight. BGP originators are Linux daemons or traditional proprietary vendor devices running the BGP stack.
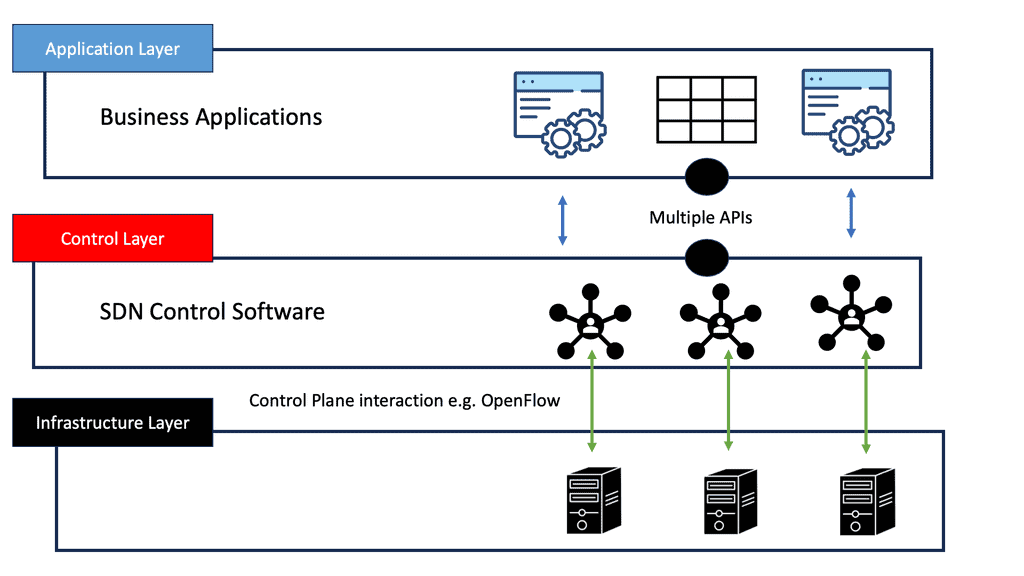
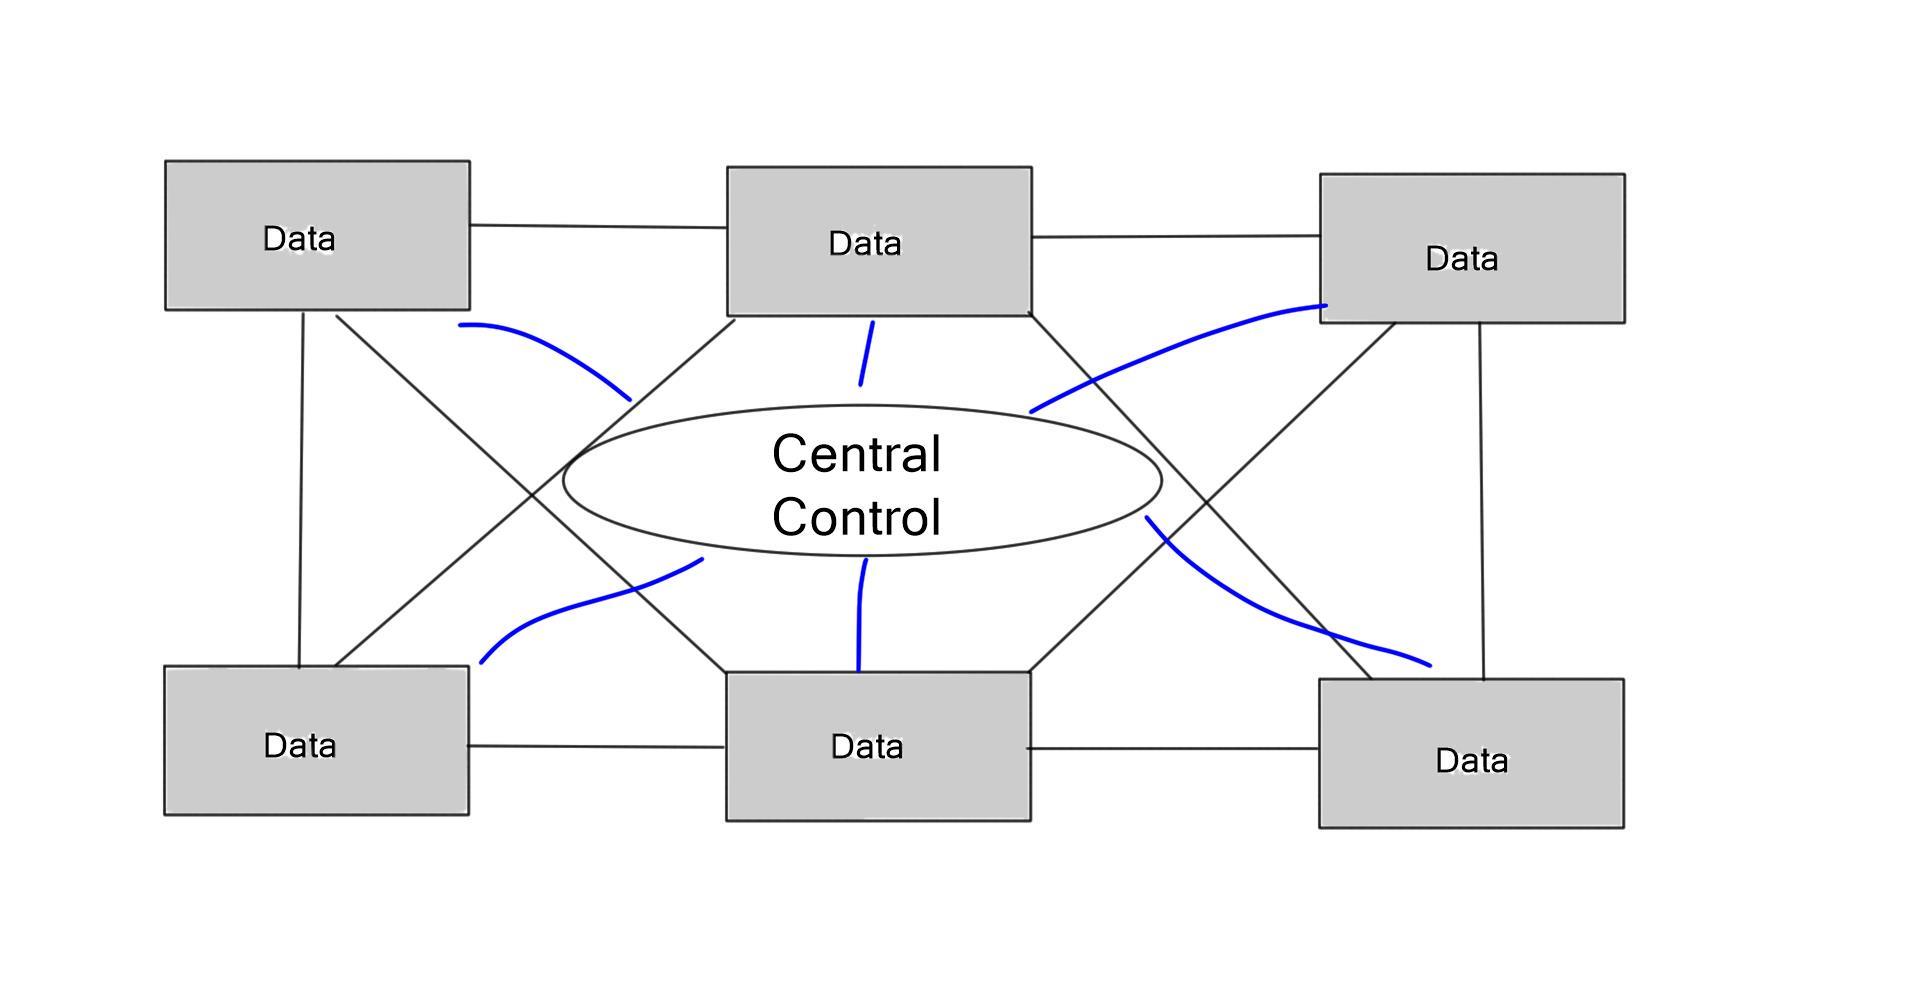
What does SDN mean
Diagram: What does SDN mean with BGP SDN?

Creating an SDN architecture

To create the SDN architecture, these components are integrated with existing BGP technologies, such as BGP FlowSpec (RFC 5575), L3VPN (RFC4364), EVPN (RFC 7432), and BGP-LS. BGP FlowSpec distributes forwarding entries, such as ACL and PBR, to devices’ TCAMs. L3VPN and EVPN offer the mechanism to integrate with legacy networks and service insertion. BGP-LS extracts IGP network topology information and passes it to the SDN controller via BGP updates.

**Central policy, visibility, and control**

Introducing BGP into the SDN framework does not mean a centralized control plane. We still have a central policy, visibility, and control, but this is not a centralized control plane. A centralized control plane would involve local control plane protocols establishing adjacencies or other ties to the controller. In this case, the forwarding devices outright require the controller to forward packets; forwarding functionality is limited when the controller is down.

If the BGP SDN controller acts as a BGP route reflector, all announcements go to the controller, but the network runs fine without it. The controller is just adding value to the usual forwarding process. BGP-based SDN architecture augments the network; it does not replace it.

Decentralizing the control plane is the only way; look at Big Switch and NEC’s SDN design changes over the last few years. Centralized control planes cannot scale.

Why use BGP?

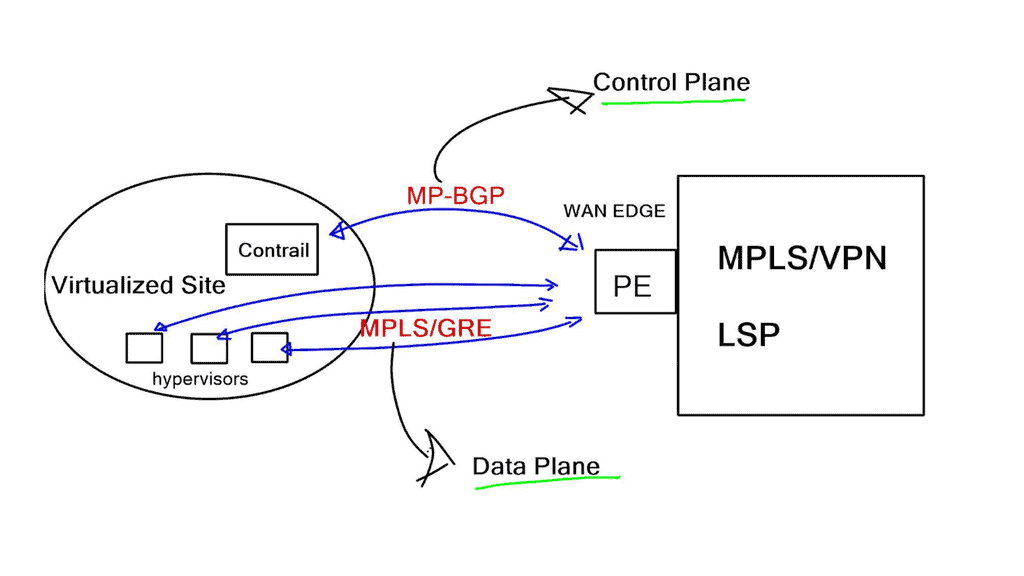
BGP is well-understood and field-tested. It has been extended on many occasions to carry additional types of information, such as MAC addresses and labels. Technically, BGP can be used as a replacement for Label Distribution Protocol (LDP) in an MPLS core. Labels can be assigned to IPv6 prefixes (6PE) and labeled switched across an IPv4-only MPLS core.

BGP is very extensible. It started with IPv4 forwarding, and address families were added for multicast and VPN traffic. Using multiple addresses inside a single BGP process was widely accepted and implemented as a core technology. The entire Internet is made up of BGP, and it carries over 500,000 prefixes. It’s very scalable and robust. Some MPLS service providers are carrying over 1 million customer routes.

The use of open-source BGP daemons

There are many high-quality open-source BGP daemons available. Quagga is one of the most popular, and its quality has improved since it adopted Cumulus and Google. Quagga is a routing suite that provides IGP support for IS-IS and OSPF. Also, a BIRD daemon is available. The implementation is based around Internet exchange points as the route server element. BIRD is currently carrying over 100,000 prefixes.

Using BGP-based SDN on an SDN controller integrates easily with your existing network. You don’t have to replace any existing equipment, deploy the controller, and implement the add-on functionality that BGP SDN offers. It enables a preferred step-by-step migration approach, not a risky big bang OpenFlow deployment.

IGP to the controller?

Why not run OSPF or ISIS to the controller? IS-IS is extendable with TLVs and, too, can carry a variety of information. The real problem is not extensibility but the lack of trust and policy control. IGP extension to the SDN controller with few controls could present a problem. OSPF sends LSA packets; there is no input filter. BGP is designed with policy control in mind and acts as a filter by implementing controls on individual BGP sessions.

BGP offers control on the network side and predicts what the controller can do. For example, the blast radius is restricted if the controller encounters a bug or is compromised. BGP also provides excellent policy mechanisms between the SDN controller and physical infrastructure. 

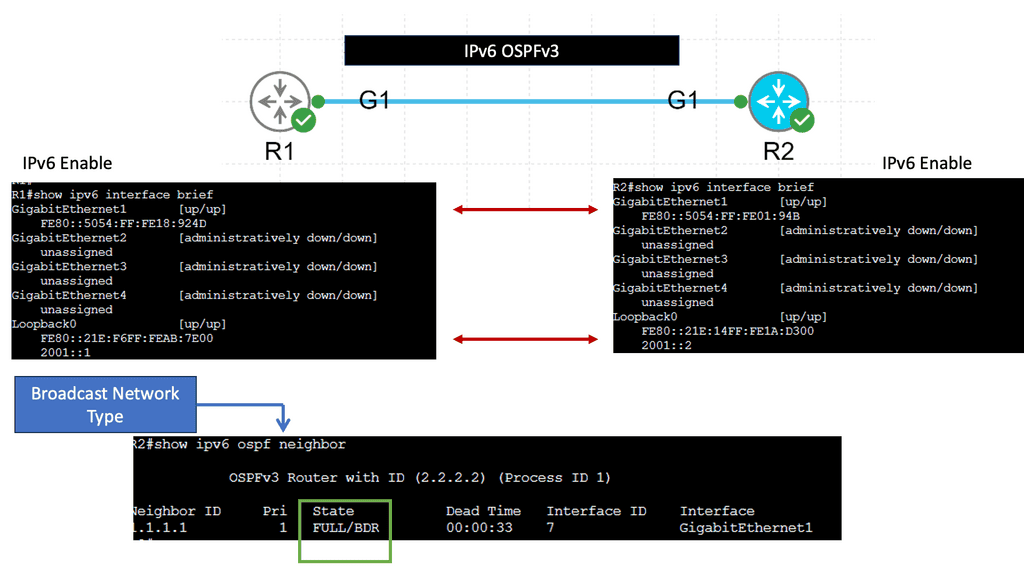
Example IGP Technology: IPv6 OSPFv3 

**The Evolution from OSPFv2 to OSPFv3**

OSPFv2, originally developed for IPv4, has been a reliable protocol for decades. However, with the transition to IPv6, a more robust solution was needed to handle the complexities of the new addressing scheme. Enter OSPFv3. This updated version retains the core principles of OSPFv2, such as using link-state routing and the Dijkstra algorithm, but introduces significant improvements. OSPFv3 supports larger address spaces, offers better security options, and is more flexible in its deployment, making it a natural choice for IPv6 networks.

**Key Features of OSPFv3**

One of the standout features of OSPFv3 is its address family support, which allows for the simultaneous routing of both IPv4 and IPv6. This dual capability is essential for networks transitioning between the two protocols. Additionally, OSPFv3 enhances security through the use of IPsec for authentication and confidentiality, addressing the vulnerabilities present in OSPFv2. The protocol also introduces a simplified packet structure, reducing overhead and increasing efficiency in data transmission.

**Implementing OSPFv3 in Your Network**

For network administrators, implementing OSPFv3 can seem daunting, but the benefits far outweigh the challenges. The protocol’s compatibility with both IPv4 and IPv6 means that it can be integrated into existing infrastructure with minimal disruption. When setting up OSPFv3, it’s crucial to ensure that all routers in the network are configured correctly to prevent routing loops and ensure seamless data flow. Regularly updating network configurations and monitoring performance can help maintain optimal operation.
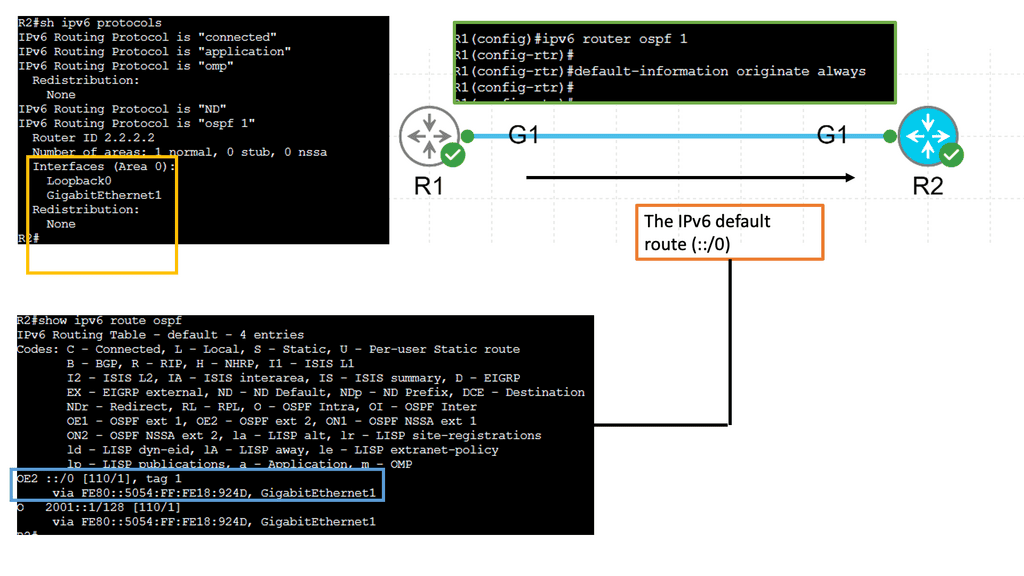
 

Introducing BGP-LS

SDN requires complete topology visibility. The picture is incomplete if some topology information is hidden in IGP and other NLRIs in BGP. If you have an existing IGP, how do you propagate this information to the BGP controller? Border Gateway Protocol Link-State (BGP-LS) is cleaner than establishing an IGP peering relationship with the SDN controller. 

BGP-LS extracts network topology information and updates it to the BGP controller. Once again, BGPv4 is extended to provide the capability to include the new Network Layer Reachability Information (NLRI) encoding format. It sends information from IS-IS or OSPF topology database through BGP updates to the SDN controller. BGP-LS can configure the session to be unidirectional and stop incoming updates to enhance security between the physical and SDN worlds.

SDN controller cannot leak information back

As a result, the SDN controller cannot leak information back into the running network. BGP-LS is a relatively new concept. It focuses on the mechanism to export IGP information and does not describe how the SDN controller can use it. Once the controller has the complete topology information, it may be integrated with traffic engineers and external path computing solutions to interact with information usually only carried by an IGP database.

For example, the Traffic Engineering Database (TED), built by ISIS and OSPF-TE extensions, is typically distributed by IGPs within the network. Previously, each node maintained its own TED, but now, this can be exported to a BGP RR SDN application for better visibility.

BGP scale-out architectures

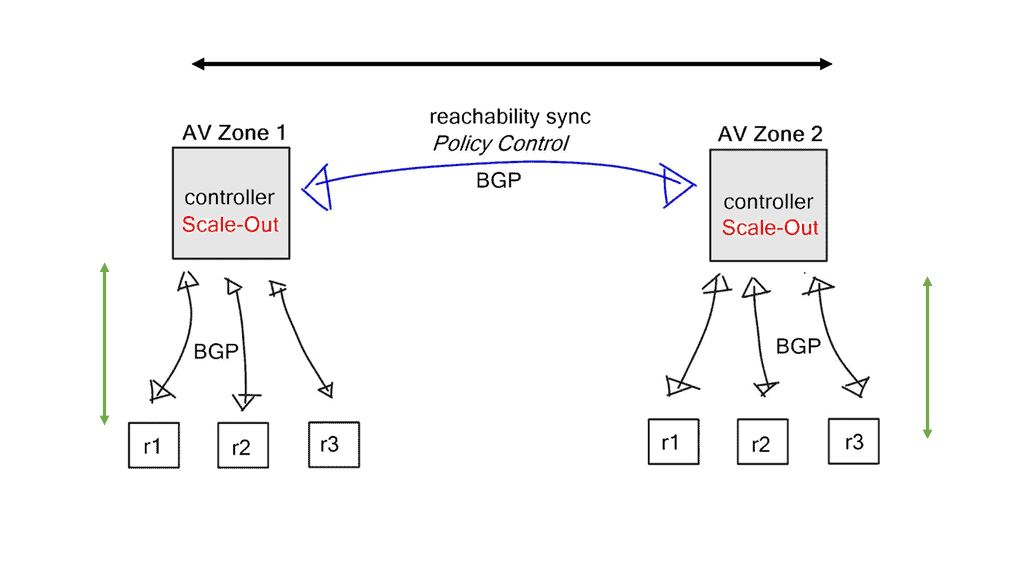
SDN controller will always become the scalability bottleneck. It can scale better when it’s not participating in data plane activity, but eventually, it will reach its limits. Every controller implementation eventually hits this point. The only way to grow is to scale out. 

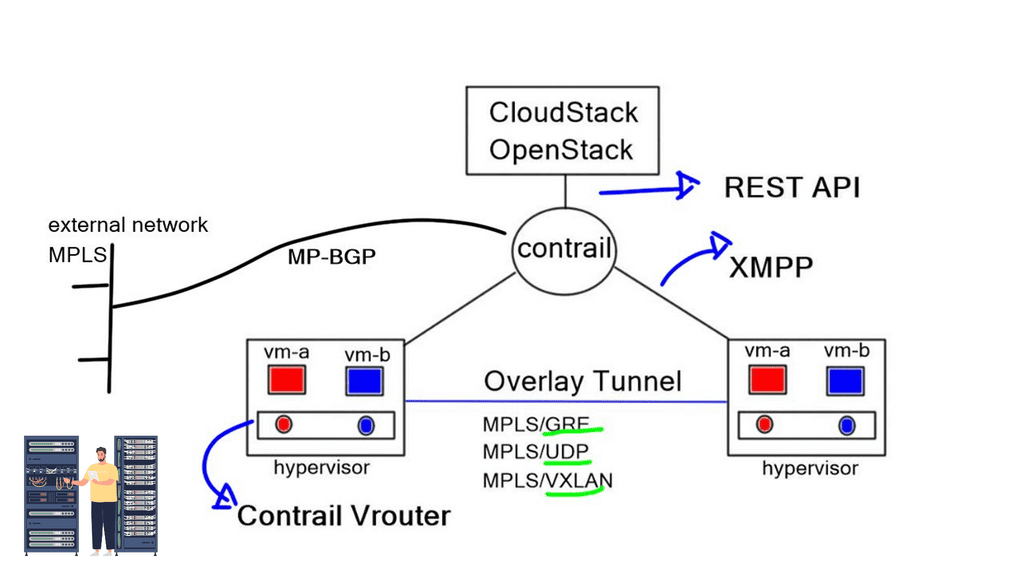
Reachability and policy information is synchronized between individual controllers. For example, reachability information can be transferred and synchronized with MP-BGP, L3VPN for IP routing, or EVPN for layer-2 forwarding.
BGP SDN

Utilizing BGP between controllers offers additional benefits. Each controller can be placed in a separate availability zone, and tight BGP policy controls are implemented on BGP sessions connecting those domains, offering a clean failure domain separation.

An error in one available zone is not propagated to the next available zone. BGP is a very scalable protocol, and the failure domains can be as large as you want, but the more significant the domain, the longer the convergence times. Adjust the size of failure domains to meet scalability and convergence requirements. 

Final Points: BGP-Based SDN

To appreciate the value of BGP-based SDN, it is essential to understand its components. BGP, the protocol that powers the internet by determining the best paths for data transmission, offers unparalleled scalability and stability. On the other hand, SDN introduces a dynamic and flexible approach to network management by decoupling the control plane from the data plane. When combined, BGP’s robust path selection and SDN’s centralized control create a network environment that is both resilient and adaptive to changing demands.

One of the primary advantages of integrating BGP with SDN is its ability to enhance network visibility and control. With centralized management, network administrators can implement comprehensive policies that optimize traffic flow, reduce latency, and improve security. Additionally, BGP-based SDN facilitates rapid deployment of new services and applications, enabling businesses to respond swiftly to market changes. This synergy also simplifies network troubleshooting and maintenance, leading to reduced operational costs and increased uptime.

BGP-based SDN is not just a theoretical concept; it is being actively implemented across various sectors. In data centers, it enables efficient resource utilization and supports the seamless scaling of services. Telecommunications companies leverage BGP-based SDN for efficient routing and traffic engineering, ensuring optimal performance and reliability. Furthermore, enterprises adopting hybrid cloud environments benefit from the enhanced connectivity and simplified management that this approach offers, allowing them to maintain competitive advantage in a digital-first world.
 

Summary: BGP-Based SDN

In today’s rapidly evolving technological landscape, software-defined networking (SDN) has emerged as a groundbreaking approach to network management. One of the key components within the realm of SDN is the Border Gateway Protocol (BGP). In this blog post, we delved into the world of BGP SDN, exploring its significance, functionality, and how it transforms traditional networking architectures.

Understanding BGP

BGP, or Border Gateway Protocol, is a routing protocol that facilitates the exchange of routing information between different autonomous systems (AS). It plays a crucial role in determining the optimal path for data packets to traverse across the internet. Unlike other routing protocols, BGP operates on a policy-based routing model, allowing network administrators to have granular control over traffic flow and network policies.

The Evolution of SDN

To comprehend the importance of BGP SDN, it is essential to understand the evolution of software-defined networking. SDN revolutionizes traditional network architectures by decoupling the control plane from the underlying physical infrastructure. This separation enables centralized network control, programmability, and dynamic configuration, enhancing flexibility and scalability.

BGP in the SDN Paradigm

Within the SDN framework, BGP plays a pivotal role in interconnecting different SDN domains, providing a scalable and flexible solution for routing between virtual networks. By incorporating BGP into the SDN architecture, organizations can achieve dynamic network provisioning, traffic engineering, and efficient handling of network policy changes.

Benefits of BGP SDN

The integration of BGP within the SDN paradigm brings forth numerous benefits. Firstly, it enables seamless interoperability between SDN and traditional networking environments, ensuring a smooth transition towards software-defined infrastructures. Additionally, BGP SDN empowers network administrators with enhanced control and visibility, simplifying the management of complex network topologies and policies.

Conclusion:

In conclusion, BGP SDN represents a significant milestone in the networking industry. Its ability to merge the power of BGP with the flexibility of software-defined networking opens new horizons for network management. By embracing BGP SDN, organizations can achieve greater agility, scalability, and control over their networks, ultimately leading to more efficient and adaptable infrastructures.

IT engineers team workers character and data center concept. Vector flat graphic design isolated illustration

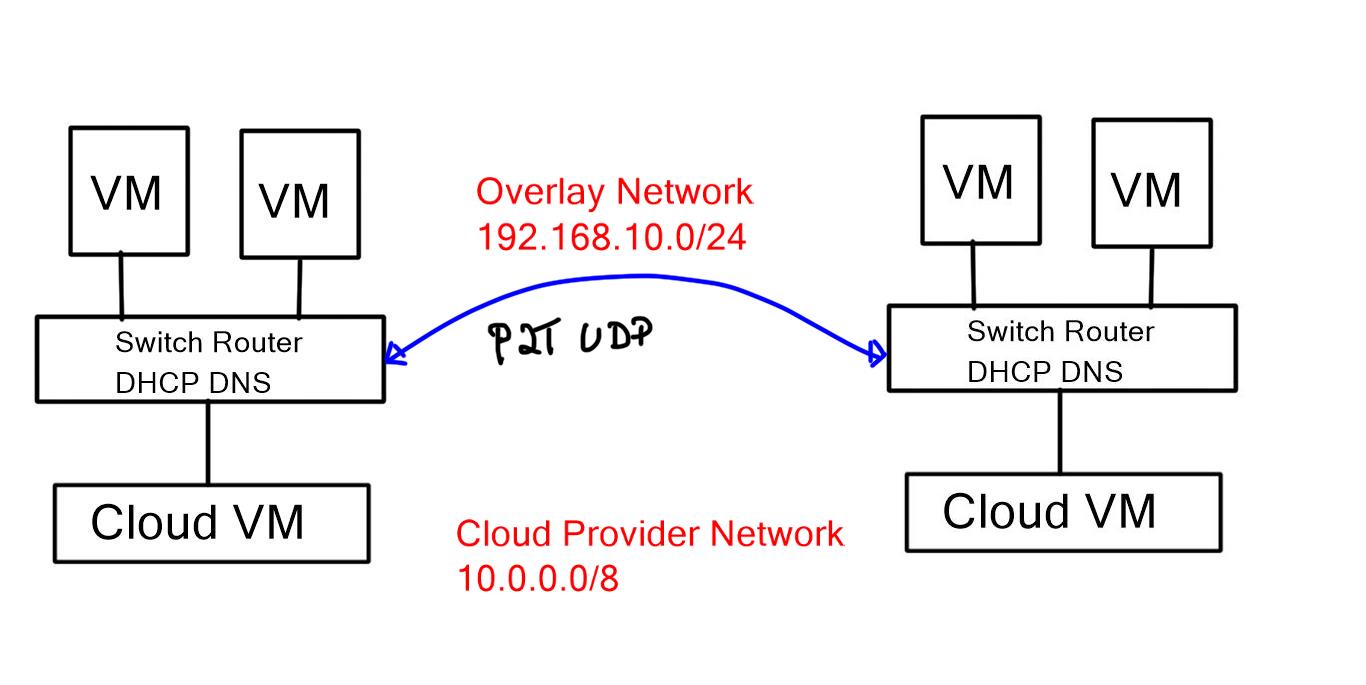
Neutron Networks

Neutron Networks

In today's digital age, connectivity has become essential to our personal and professional lives. As the demand for seamless and reliable network connections grows, businesses seek innovative solutions to meet their networking needs. One such solution that has gained significant attention is Neutron Networks. In this blog post, we will delve into Neutron Networks, exploring its features, benefits, and how it is revolutionizing connectivity.

Neutron Networks is an open-source networking project within the OpenStack platform. It acts as a networking-as-a-service (NaaS) solution, providing a programmable interface for creating and managing network resources. Unlike traditional networking methods, Neutron Networks offers a flexible framework that allows users to define and control their network topology, enabling greater customization and scalability.

Neutron networks serve as the backbone of OpenStack's networking service, providing a way to create and manage virtual networks for cloud instances. By abstracting the complexities of network configuration and provisioning, neutron networks offer a flexible and scalable solution for cloud deployments.

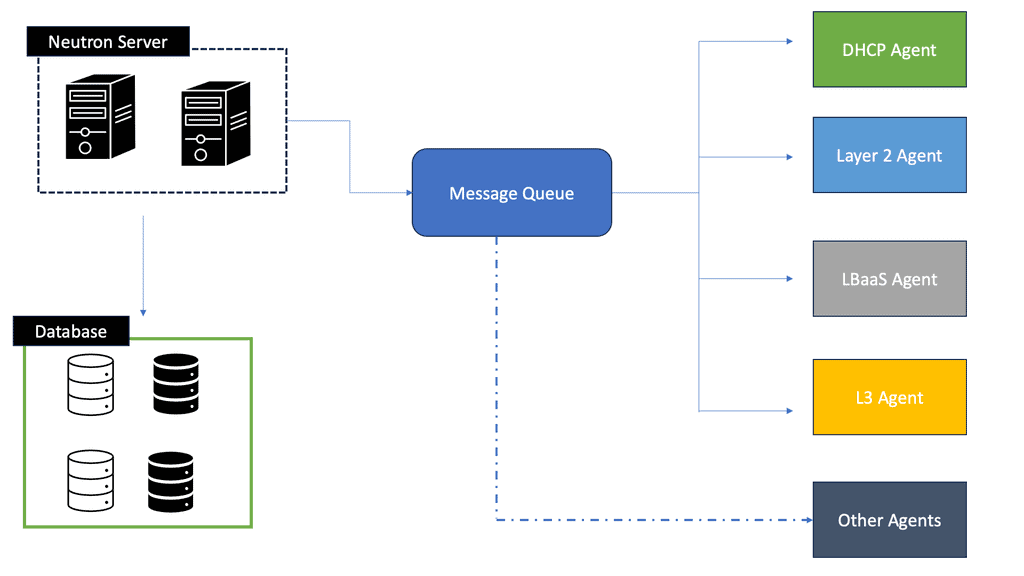
The architecture of neutron networks consists of various components working together to enable network connectivity. These include the neutron server, neutron agents, and the neutron plugin. The server acts as the central control point, while agents handle network operations on compute nodes. The plugin interfaces with underlying networking technologies, such as VLAN, VXLAN, or SDN controllers, allowing for diverse network configurations.

Neutron networks comprise several key components that contribute to their functionality. These include subnets, routers, security groups, and ports. Subnets define IP address ranges, routers enable inter-subnet communication, security groups provide firewall rules, and ports connect instances to the networks.

Neutron networks bring numerous advantages to cloud computing environments. Firstly, they offer network isolation, allowing different projects or tenants to have their own virtual networks. Additionally, neutron networks enable dynamic scaling and seamless migration of instances between hosts. They also support advanced networking features like load balancing and virtual private networks (VPNs), enhancing the capabilities of cloud deployments.

Neutron networks are a vital component of OpenStack, providing a robust and flexible solution for network management in cloud environments. Understanding their architecture and key components empowers cloud administrators to create and manage virtual networks effectively. With their ability to abstract the complexities of networking, neutron networks contribute to the scalability, security, and overall performance of cloud computing.

Highlights: Neutron Networks

### Understanding Neutron’s Architecture

Neutron’s architecture is designed to be modular and extensible, allowing it to support a variety of network topologies and technologies. At its core, Neutron consists of several key components, such as the Neutron server, plugins, and agents. The Neutron server acts as the central hub, handling API requests and managing network state. Plugins provide the actual network functionality, interfacing with different technologies like VLANs, VXLANs, and GRE tunnels. Agents, on the other hand, run on each compute node, facilitating network operations and enforcing network configurations.

### Key Features and Capabilities

Neutron offers a rich set of features that cater to diverse networking needs. It supports advanced networking functionalities such as IP address management, floating IPs, and security groups. With Neutron, users can create complex network topologies, including private networks, routers, and load balancers. Moreover, Neutron’s support for Software-Defined Networking (SDN) enables seamless integration with third-party networking solutions, providing enhanced flexibility and scalability.

### Neutron and OpenStack Integration

The integration of Neutron within the OpenStack ecosystem is seamless, offering users a comprehensive platform for managing both compute and network resources. Neutron’s APIs provide a consistent interface for interacting with network services, allowing developers to automate network provisioning and management. This integration ensures that network resources can be dynamically allocated and managed alongside compute instances, optimizing resource utilization and efficiency.

### Challenges and Considerations

While Neutron Networks offer significant advantages, there are challenges to consider when deploying them in OpenStack environments. Network latency and performance can be impacted by the complexity of the network topology and the underlying infrastructure. Additionally, security and compliance are critical considerations, as network configurations must be carefully managed to prevent vulnerabilities.

Neutron Networking

A– As part of OpenStack, Neutron networking is a software-defined networking (SDN) solution that enables virtual networks and connectivity in cloud environments. It acts as a networking-as-a-service (NaaS) component, providing a flexible and scalable approach to network management.

B– Within the Neutron framework, several essential components facilitate network connectivity. These include the neutron server, agents, plugins, and drivers. Each component ensures seamless communication between virtual machines (VMs) and the physical network infrastructure.

C– Neutron is composed of several key components that work in tandem to deliver a comprehensive networking solution. The Neutron server, for instance, acts as the central hub that orchestrates all networking requests and communicates with various agents deployed across the cloud infrastructure.

D– These agents, like the L3 agent and DHCP agent, are responsible for routing and addressing, ensuring that each instance within the cloud has the necessary network configuration. Additionally, Neutron utilizes plugins to support different networking technologies, offering flexibility and adaptability to its users.

**Various Networking Models**

Neutron supports various networking models, including flat networking, VLAN segmentation, and overlay networks. Each model offers distinct advantages and caters to different use cases. Understanding these models and their benefits is essential for network administrators and architects.

**Neutron Advanced Features**

Neutron networking offers advanced features such as security groups, load balancing, and virtual private networks (VPNs). These features enhance network security, performance, and isolation, enabling efficient and reliable communication across virtual machines.

Key Features and Functionality

Neutron Network offers a wide range of features that empower users to have fine-grained control over their network infrastructure. Some of its notable features include:

1. Network Abstraction: Neutron Network provides a high-level abstraction layer that simplifies the management of complex network topologies. It enables users to create and manage networks, subnets, and ports effortlessly.

2. Virtual Router: With Neutron Network, users can create virtual routers that can connect multiple networks, providing seamless connectivity and routing capabilities.

3. Security Groups: Neutron Network allows the creation of security groups to enforce network traffic filtering and access control policies. This enhances the overall security posture of the network infrastructure.

OpenStack Networking

A – ) An OpenStack-based cloud can manage networks and IP addresses with OpenStack Networking, a pluggable, scalable, API-driven system. Administrators and users can use the OpenStack Networking component to maximize the value and utilization of existing data center resources.

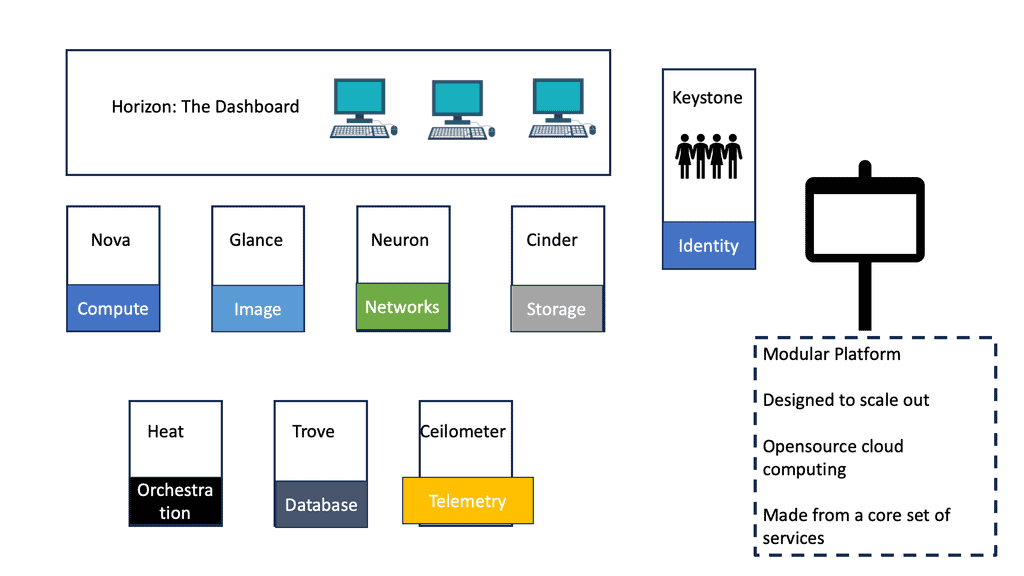
B – ) In addition to Nova’s compute service and Glance’s image service, Keystone’s identity service, Cinder’s block storage, and Horizon’s dashboard, Neutron’s networking service can be installed independently of other OpenStack services. Multiple hosts can provide resiliency and redundancy, or a single host can be configured to provide the networking services.

C – ) In OpenStack Networking, users can access a programmable interface, or API, that passes requests to the configured network plugins for further processing. Cloud operators can leverage different networking technologies to enhance and power cloud connectivity.

OpenStack Networking

Through IP forwarding, iptables, and network namespaces, OpenStack Networking provides routing and NAT capabilities. Network namespaces contain sockets, bound ports, and interfaces. Iptables processes and routing tables are separate components of each network namespace responsible for filtering and translating network addresses.

Using network namespaces to separate networks eliminates the risk of overlapping subnets between tenants’ networks. By configuring a router in Neutron, instances can communicate with outside networks. As well as Firewall as a Service and Virtual Private Network as a Service, router namespaces are also used by advanced networking services.

Data Center Expansion

Data centers today have more devices than ever before. Virtual machines and virtual network appliances have replaced Servers, routers, storage systems, and security appliances that once occupied rows of data center space. These devices place a great deal of strain on traditional network management systems due to their scalability and automation requirements. Infrastructure provisioning will be faster and more flexible with OpenStack.

An OpenStack-based cloud can manage its networks with OpenStack Networking, which is pluggable, scaleable, and API-driven. As with other core OpenStack components, administrators and users can use OpenStack Networking to maximize data center utilization.

It combines Compute (Nova), Image (Glance), Identity (Keystone), Block (Cinder), Object (Swift), and Dashboard (Horizon) into a complete cloud solution.

Openstack services

OpenStack Networking API

– Users can access OpenStack Networking’s API by requesting additional processing from configured network plugins. By defining network connectivity, cloud operators can enhance and power their clouds.

– It is possible to deploy OpenStack Networking services across multiple hosts or on a single node to provide resiliency and redundancy. Like many other OpenStack services, Neutron requires access to a database to store network configurations.

– A database containing the logical network configuration is connected to the Neutron server. Neutron servers receive API requests from users and services, and agents respond via message queues. Most network agents are dispersed across controllers and compute nodes and perform their duties there.

Neutron Server

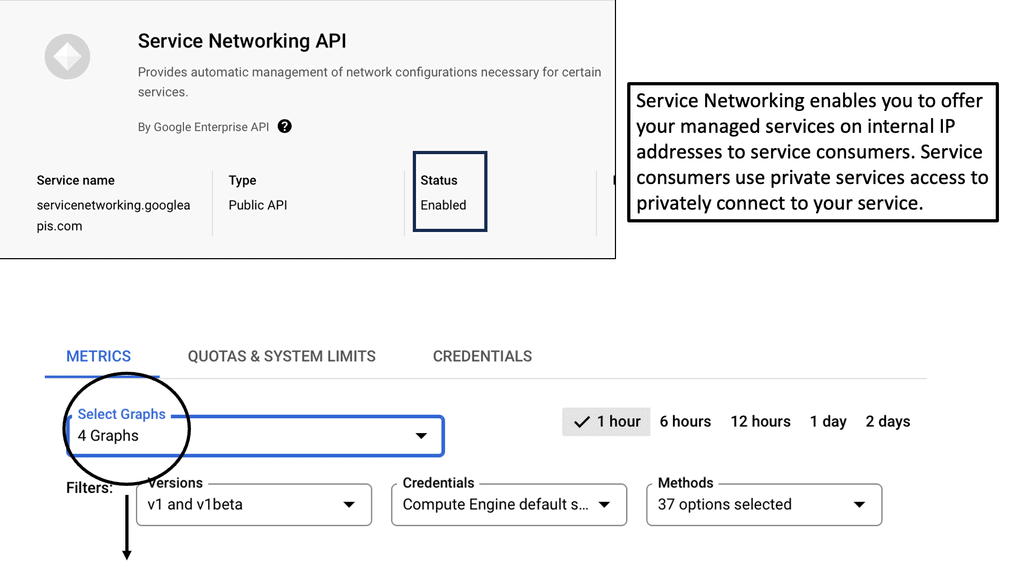
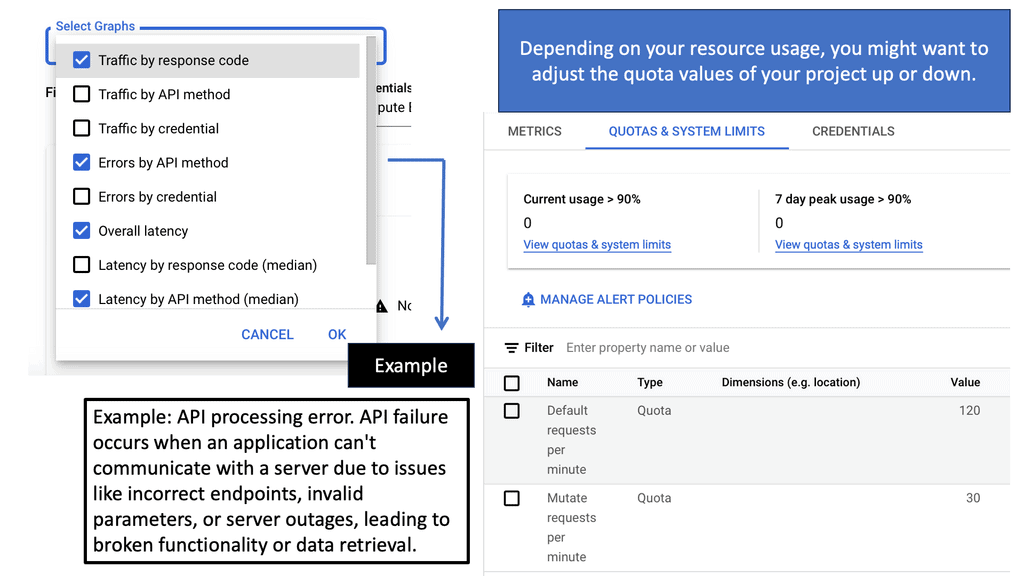
Example API Technology: Service Networking API

**Understanding the Architecture**

Service networking APIs typically follow a client-server model, where the client sends requests and the server responds with the necessary data or services. This architecture allows for modular, scalable, and maintainable systems. By abstracting the complexities of direct database access, APIs offer a standardized way to interact with application services, thus reducing development time and minimizing the potential for errors.

**Key Benefits of Using Service Networking APIs**

1. **Interoperability**: One of the primary advantages is the ability to connect disparate systems, allowing them to work together seamlessly. This is particularly valuable in organizations with diverse IT ecosystems.

2. **Scalability**: APIs provide a scalable solution to meet growing business demands. As your needs evolve, APIs can handle increasing loads without major changes to the underlying infrastructure.

3. **Security**: By acting as an intermediary between external requests and your services, APIs can enforce security protocols such as authentication and encryption, safeguarding sensitive data.

**Implementing Service Networking APIs**

To implement an effective service networking API, developers must focus on robust design principles. This includes creating clear documentation, ensuring consistent and predictable behavior, and utilizing RESTful or GraphQL frameworks for efficient data handling. Testing is also critical, as it helps identify potential issues before they impact end-users.

**Best Practices for API Management**

Effective API management involves monitoring, versioning, and documenting your APIs. Monitoring tools help track API performance and usage, while versioning ensures backward compatibility as your API evolves. Comprehensive documentation empowers developers to integrate your API quickly and efficiently, reducing the learning curve and fostering a community around your service.

Service Networking API


The Role of OpenStack Networking

OpenStack and neutron networks offer virtual networking services and connectivity to and from Instances. They play a significant role in the adoption of OpenFlow and SDN. The Neutron API manages the configuration of individual networks, subnets, and ports. It enhanced the original Nova network implementation and introduced support for third-party plugins, such as Open vSwitch (OVS) and Linux bridge.

OVS and LinuxBridge provide Layer 2 connectivity with VLANs or Overlay encapsulation technologies, such as GRE or VXLAN. Neutrons are pretty basic, but their capability is gaining momentum with each distribution release with the ability to include an OpenStack neutron load balancer.

Use Cases and Benefits:

Neutron Network finds applications in various scenarios, making it a versatile networking solution. Here are a few notable use cases:

1. Multi-Tenant Environments: Neutron Network enables service providers to offer segregated network environments to different tenants, ensuring isolation and security between them.

2. Software-Defined Networking (SDN): Neutron Network plays a crucial role in implementing SDN concepts by providing programmable and flexible network infrastructure.

3. Hybrid Cloud Deployments: With Neutron Network, organizations can seamlessly integrate public and private cloud environments, enabling hybrid cloud deployments with ease.

You may find the following helpful post for pre-information:

  1. OpenStack Neutron Security Groups
  2. Neutron Network
  3. OpenStack Architecture

Neutron Networks

OpenStack Networking

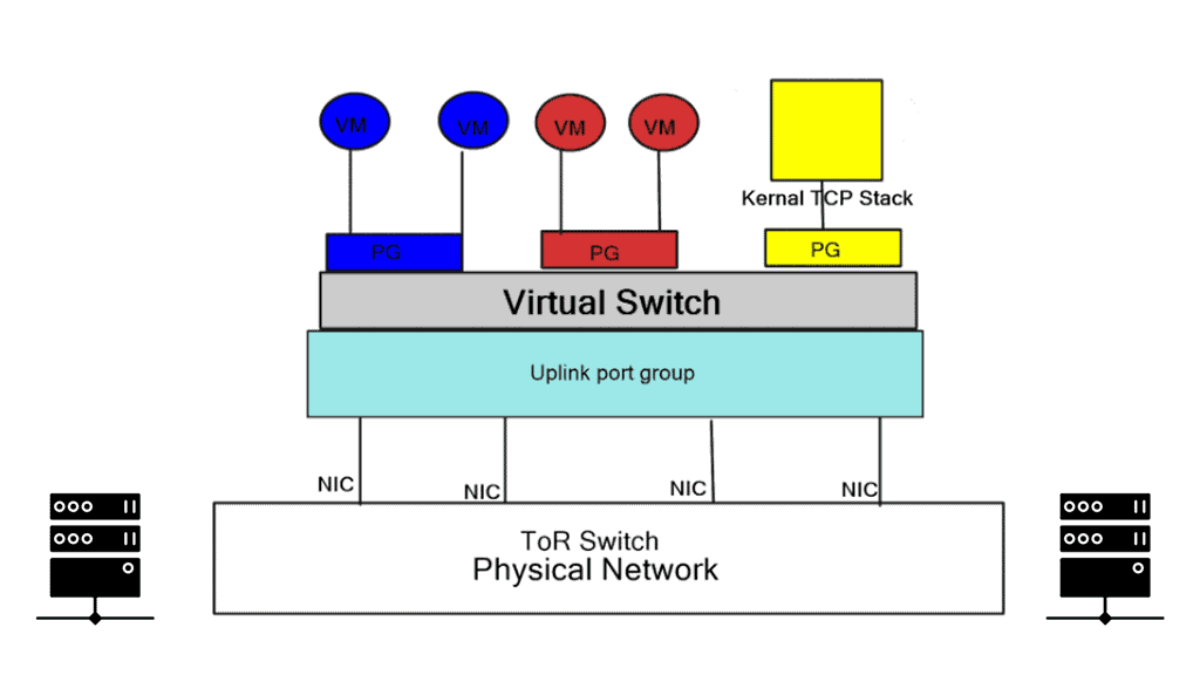
OpenStack Networking is a pluggable, API-driven approach to control networks in OpenStack. OpenStack Networking exposes a programmable application interface (API) to users and passes requests to the configured network plugins for additional processing. A virtual switch is a software application that connects virtual machines to virtual networks. The virtual switch operated at the data link layer of the OSI model, Layer 2. A considerable benefit to Neutron is that it supports multiple virtual switching platforms, including Linux bridges provided by the bridge kernel module and Open vSwitch.

  • A key point: Ansible and OpenStack

Ansible architecture offers excellent flexibility and can be used ways to leverage Ansible modules and playbook structures to automate frequent operations with OpenStack. With Ansible, you have a module to manage every layer of the OpenStack architecture. At the time of this writing, Ansible 2.2 includes modules to call the following APIs

  • Keystone: users, groups, roles, projects
  • Nova: servers, keypairs, security groups, flavors
  • Neutron: ports, network, subnets, routers, floating IPs
  • Ironic: nodes, introspection
  • Swift Objects
  • Cinder volumes
  • Glance images

Neutron Networks

Neutron networks support a wide range of networks. Including Flat, Local, VLAN, and VXLAN/GRE-based networks. Local networks are isolated and local to the Compute node. In a FLat network, there is no VLAN tagging. VLAN-capable networks implement 802.1Q tagging; segmentation is based on VLAN tags. Similar to the physical world, hosts in VLANs are considered to be in the same broadcast domain, and inter-VLAN communication must pass a Layer 3 device.

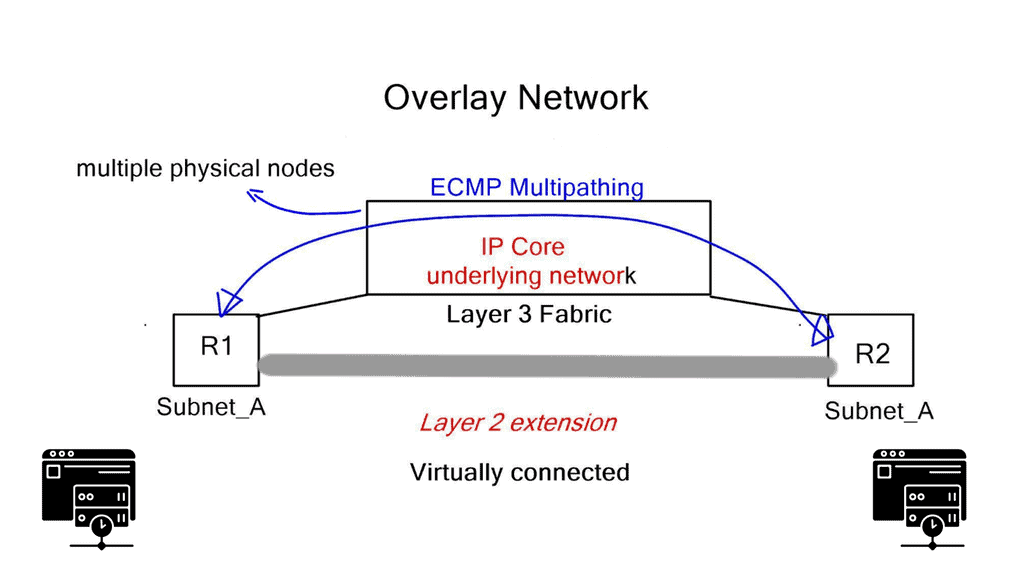
GRE and VXLAN encapsulation technologies create the concept known as overlay networking. Network Overlays interconnect layer 2 segments over an Underlay network, commonly an IP fabric but could also be represented as a Layer 2 fabric. Their use case derives from multi-tenancy requirements and the scale limitations of VLAN-based networks.

The virtual switches

Open vSwitch and Linux Bridge

Open vSwitch and Linux Bridge plugins are monolithic and cannot be used simultaneously. A new plugin, introduced in Havana, called Modular Layer 2 ( ML2 ), allows the use of multiple Layer 2 plugins simultaneously. It works with existing OVS and LinuxBridge agents and is intended to replace the associated plugins.

OpenStack foundations are pretty flexible. OVS and other vendor appliances could be used parallel to manage virtual networks in an OpenStack Neutron deployment. Plugins can replace OVS with a physically managed switch to handle the virtual networks. 

Open vSwitch

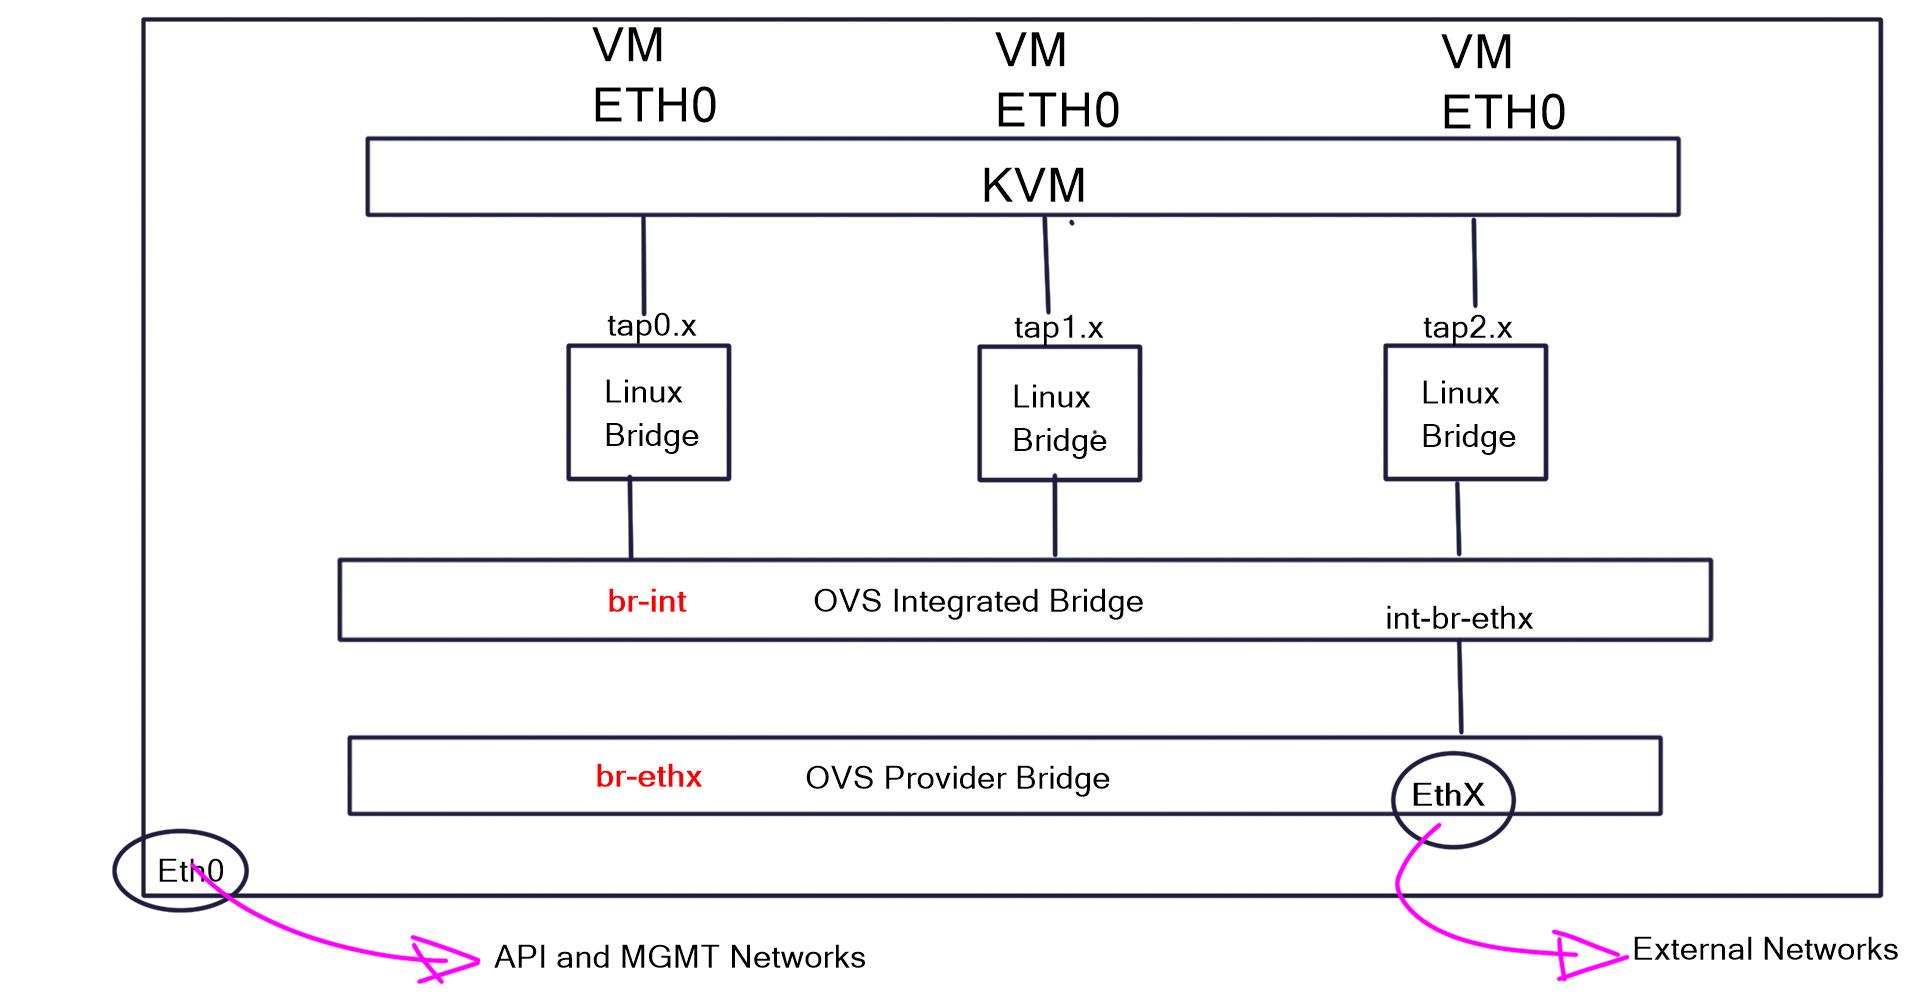
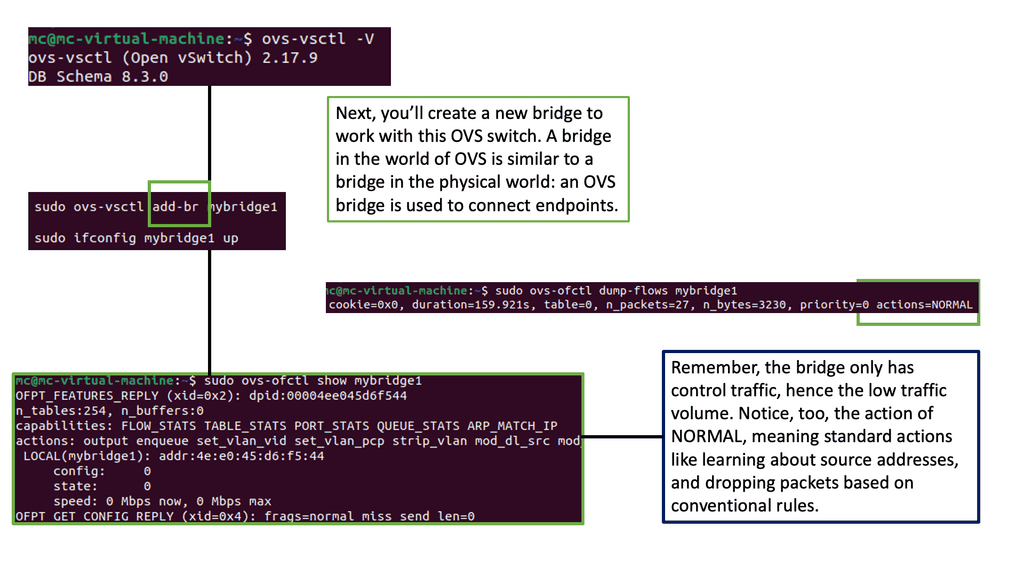
The OVS bridge is a popular software-based switch orchestrating the underlying virtualized networking infrastructure. It comprises a kernel module, a vSwitch daemon, and a database server. The kernel module is the data plane, similar to an ASIC on a physical switch. The vSwitch daemon is a Linux process creating controls so the kernel can forward traffic.

The database server is the Open vSwitch Database Server ( OVSDB) and is local on every host. OVS consists of 4 distinct elements, – Tap devices, Linux bridges, Virtual Ethernet cables, OVS bridges, and OVS patch ports. Virtual Ethernet cables, known as veth mimic network patch cords.

They connect to other bridges and namespaces (namespaces discussed later). An OVS bridge is a virtualized switch. It behaves similarly to a physical switch and maintains MAC addresses.

openstack networking

**OpenStack networking deployment details**

A few OpenStack deployment methods exist, such as Maas, Mirantis Fuel, Kickstack, and Packstack. They all have their advantages and disadvantages. Packstack suits small deployments, Proof of Concepts, and other test environments. It’s a simple Puppet-based installer. It uses SSH to connect to the nodes and invokes a puppet run to install OpenStack.

Additional configurations can be passed to Packstack via an answer file. As part of the Packstack run, a file called keystonerc_admin is created. Keystone is the identity management component of OpenStack. Each element in OpenStack registers with Keystone. It’s easier to source the file than those values in the source file, which are automatically placed in the shell environment.

Cat this file to see its content and get the login credentials. You will need this information to authenticate and interact with OpenStack.

openstack neutron load balancer

OpenStack lbaas Architecture

Neutron networks 

OpenStack is a multi-tenant platform; each tenant can have multiple private networks and network services isolated through network namespaces. Network namespaces allow tenants to have overlapping networks with other tenants. Consider a namespace for an enhanced VRF instance connected to one or more virtual switches. Neutron uses a “qrouter,” “glbaas,” and “qdhcp” namespaces.

Regardless of the network plugins installed, you need to install the neutron-server service at minimum. This service will expose the Neutron API for external administration. By default, it is configured to listen to API calls on ALL addresses. You can change this in the Neutron.conf file by editing the bind_host—0.0.0.0.

  • “Neutron configuration file is found at /etc/neutron/neutron.conf”

OpenStack networking provides extensions that allow the creation of virtual routers and virtual load balancers with an OpenStack neutron load balancer. Virtual routers are created with the neutron-l3-agent. They perform Layer 3 forwarding and NAT.

A router default performs Source NAT on traffic from an instance destined to an external service. Source NAT modifies the packet source appearing to upstream devices as if it came from the router’s external interface. When users want direct inbound access to an instance, Neutron uses what is known as a Floating IP address. It is similar to the analogy of Static NAT; one-to-one mapping of an external to an internal address. 

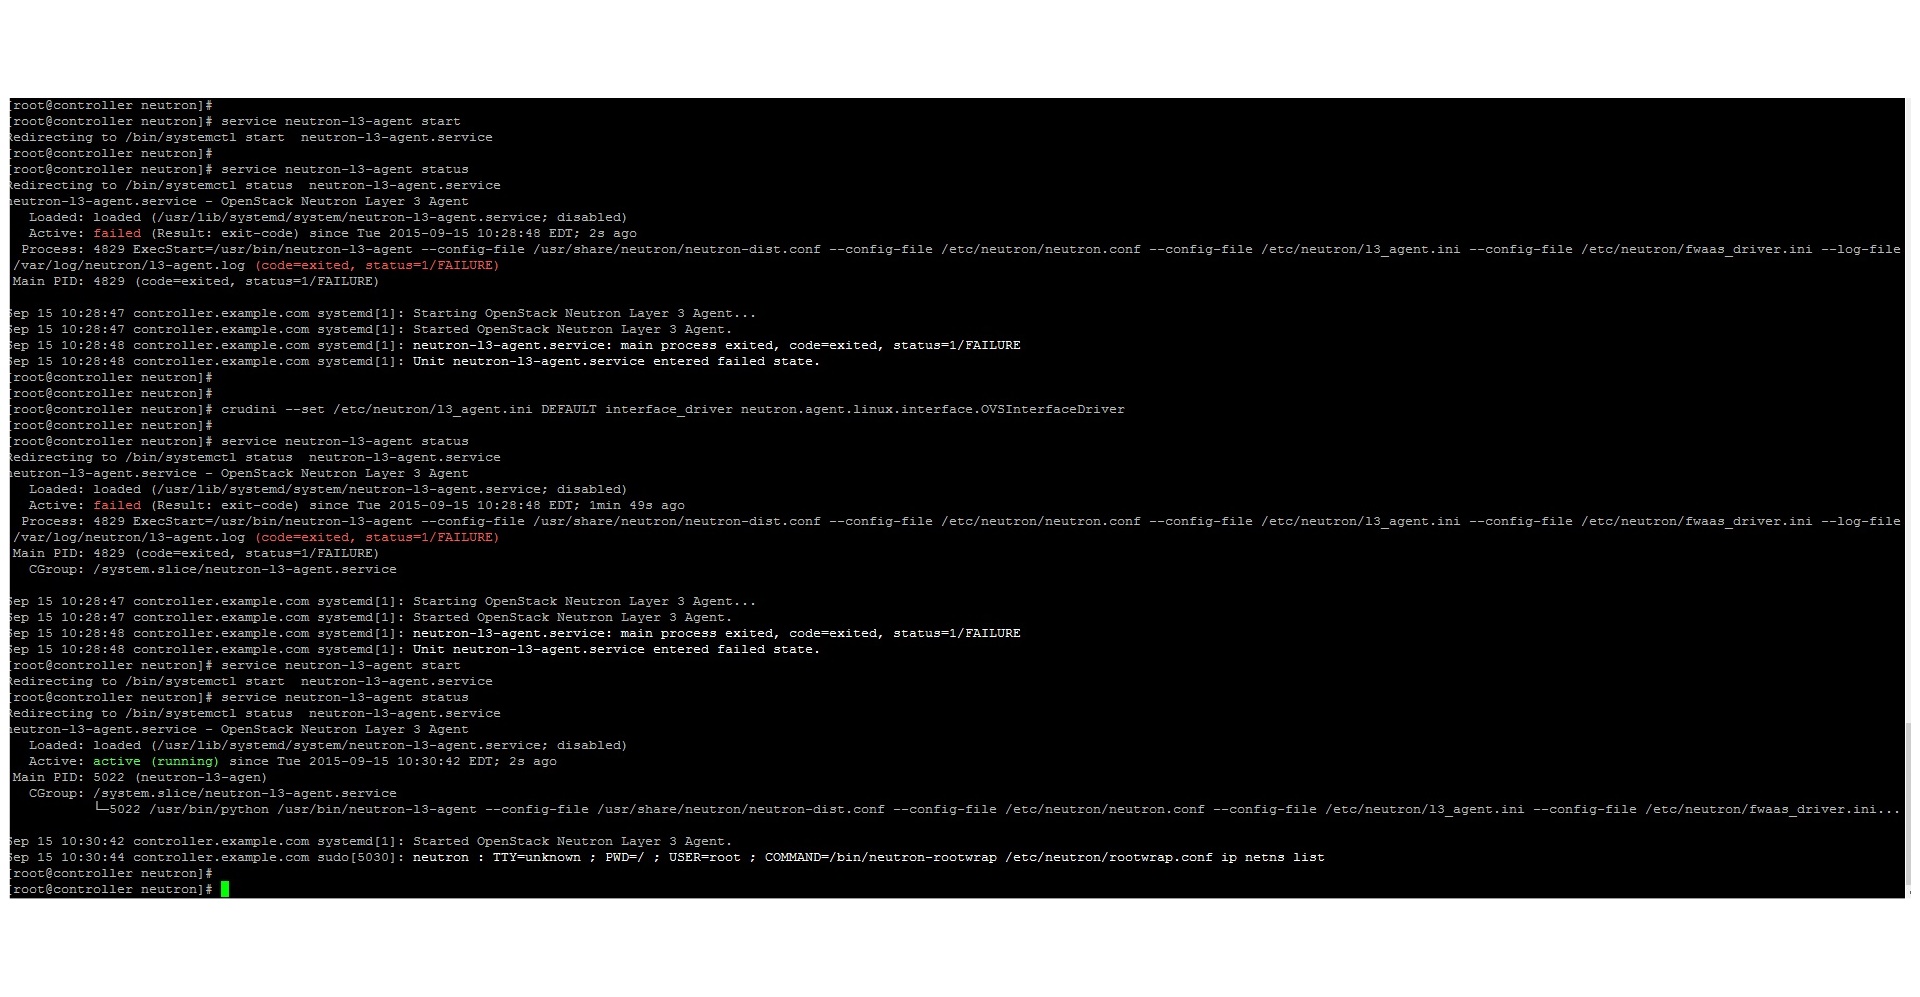
  • “Neutron stores its L3 configuration in the l3_agent.ini files.”

The following screenshot displays that the L3 agent must first be associated with an interface driver before you can start it. The interface driver must correspond to the chosen network plugin, for example, LinuxBridge or OVS. The “crudini“ commands set this.openstack lbaas architecture

OpenStack neutron load balancer

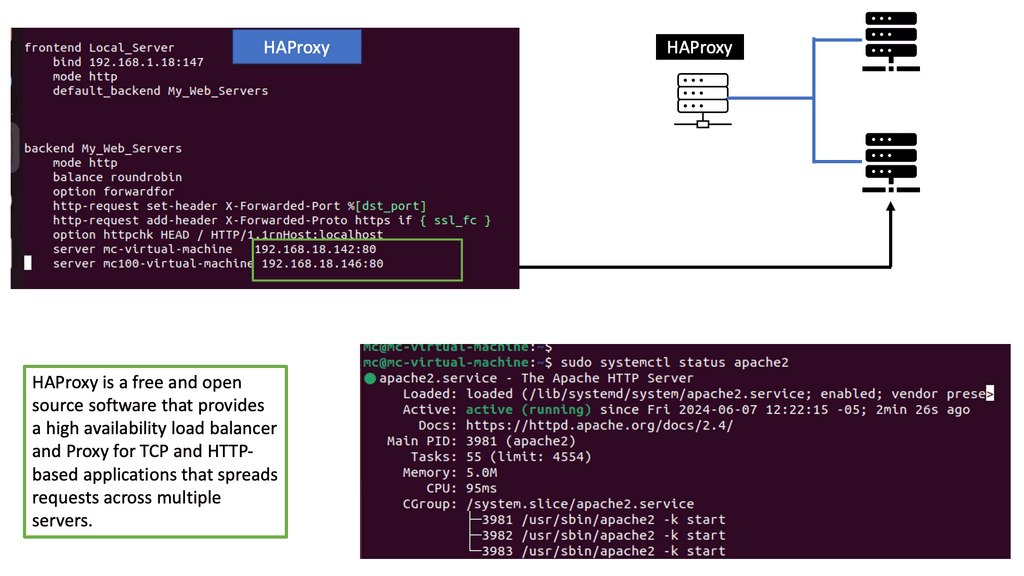
The OpenStack LBaaS architecture consists of the neutron-lbaas-agent and leverages the open-source HAProxy to load balance traffic destined to VIPs. HAProxy is a free, open-source load balancer. LBaaS supports third-party drivers, which will be discussed in later posts.

Load Balancing as a service enables tenants to scale their applications programmatically through Neutron API. It supports basic load-balancing algorithms and monitoring capabilities.

The OpenStack lbaas architecture load balancing algorithms are restricted to round-robin, least connections, and source IP. It can do basic TCP connect tests for monitoring and complete Layer 7 tests that support HTTP status codes.

HAProxy installation

As far as I’m aware, it doesn’t support SSL offloading. The HAProxy driver is installed in one ARM mode, which uses the same interface for ingress and egress traffic. It is not the default gateway for instances, so it relies on Source NAT for proper return traffic forwarding. Neutron stores its configuration in the lbaas_agent.ini files.

Like the l3 agent, it must associate with an interface driver before starting it – “crudini –set /etc/neutron/lbaas_agent.ini DEFAULT interface_driver neutron.agent.linux.interface.OVSInterfaceDriver”. Both agents use network namespaces for isolated forwarding and load-balancing contexts.

Example HA Proxy Technology:

### Understanding Load Balancing with HAProxy

Load balancing is a crucial aspect of maintaining a reliable and scalable system. HAProxy excels in this domain by efficiently distributing incoming network traffic across multiple servers. This not only ensures high availability but also enhances performance. By preventing any single server from being overwhelmed, HAProxy helps maintain a seamless user experience, even during traffic spikes. We’ll delve into how HAProxy achieves this and why it’s a preferred choice for Linux-based environments.

### Setting Up HAProxy on Linux

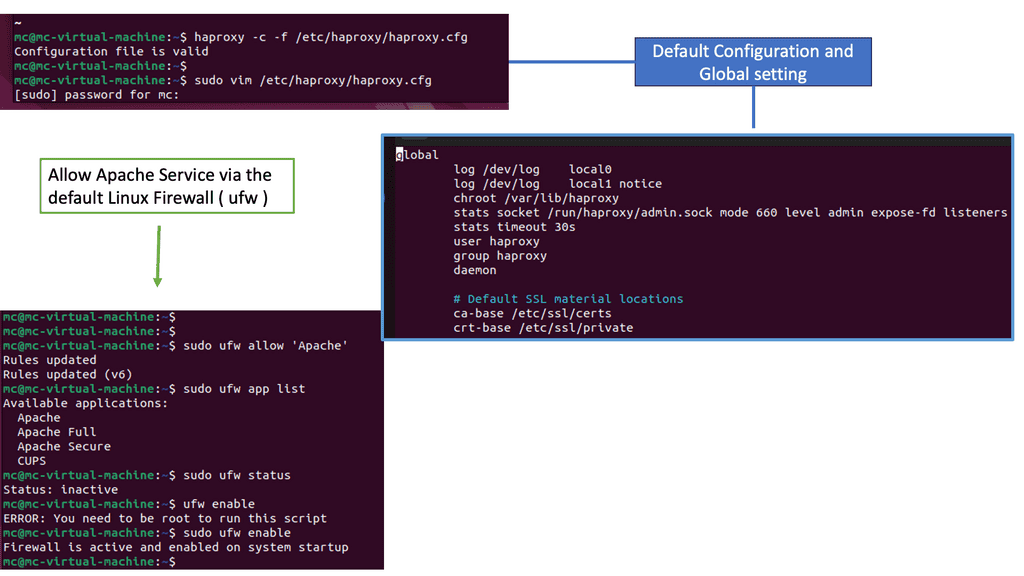
Setting up HAProxy on a Linux system is a straightforward process, even for those new to network management. We’ll provide a step-by-step guide to installing HAProxy on a Linux distribution, configuring basic settings, and ensuring your setup is secure and efficient. From initial installation to advanced configuration, you’ll learn how to get HAProxy up and running in no time.

—

### Advanced Configuration Tips

Once you have HAProxy installed, the real power lies in its configuration options. We’ll explore some advanced tips and tricks to optimize your HAProxy setup. This includes setting up SSL termination, configuring sticky sessions, and using ACLs (Access Control Lists) to manage traffic more precisely. These tips will help you tailor HAProxy to meet your specific needs and leverage its full potential.

### Monitoring and Maintenance

To ensure HAProxy continues to run smoothly, regular monitoring and maintenance are essential. We’ll discuss some of the best practices for keeping an eye on your HAProxy performance, including logging, health checks, and using third-party tools for enhanced visibility. By staying proactive, you can quickly identify and resolve potential issues before they impact your system’s availability.

Closing Points on Neutron Networks

In the realm of OpenStack, Neutron is the networking component that provides “networking as a service” between interface devices managed by other OpenStack services. Neutron’s role is crucial, as it enables users to create their own networks and assign IP addresses to them, creating a flexible and customizable cloud environment. Understanding Neutron is essential for anyone looking to leverage the full capabilities of OpenStack.

At its core, Neutron operates through a modular architecture that consists of a series of plugins and agents. This architecture allows it to support a variety of network technologies and configurations. Neutron’s main components include the Neutron server, which handles API requests, and various plugins, which serve as drivers for different network types. Agents installed on each compute node manage local networking, ensuring that the system runs smoothly and efficiently.

Neutron offers a plethora of features designed to enhance the networking experience. These include Layer 2 networking, which allows for the creation of isolated networks, and Layer 3 networking, which supports routing between different networks. Neutron also provides support for floating IPs, security groups, and VPN services, each of which adds an extra layer of functionality and security to your cloud environment.

Integrating Neutron into your OpenStack environment can seem daunting, but with a structured approach, it becomes manageable. Start by installing the Neutron service on your controller node and configure it to interact with the Identity service. Choose the appropriate plugin for your network setup, whether it’s the Modular Layer 2 plugin (ML2) for standard configurations or another option for more specific needs. Finally, ensure that Neutron agents are correctly installed and configured on each compute node to facilitate seamless networking.

—

**Common Challenges and Solutions**

While Neutron is a robust tool, users may encounter challenges during setup and maintenance. One common issue is network isolation, where instances cannot communicate over the intended network. This is often resolved by checking security group settings and ensuring proper router configuration. Another challenge is performance bottlenecks, which can be addressed by optimizing the placement of networking components and ensuring sufficient resources are allocated to the Neutron server.


Summary: Neutron Networks

In today’s interconnected world, seamless and reliable network connectivity is necessary. Behind the scenes, a fascinating technology known as neutron networks forms the backbone of this connectivity. In this blog post, we delved into the intricacies of neutron networks, uncovering their inner workings and understanding their critical role in modern communication systems.

Understanding Neutron Networks

Neutron networks, a core component of OpenStack, manage and orchestrate network connectivity within cloud infrastructures. They provide a virtual networking service, allowing users to create and manage networks, routers, subnets, and more. By abstracting the complexity of physical network infrastructure, neutron networks offer flexibility and scalability, enabling efficient communication between virtual machines and external networks.

Components of Neutron Networks

To grasp the functioning of neutron networks, we must familiarize ourselves with their key components. These include:

1. Network: The fundamental building block of neutron networks, a network represents a virtual isolated layer 2 broadcast domain. It provides connectivity between instances and allows traffic flow within a defined scope.

2. Subnet: A subnet defines a network’s IP address range and associated configuration parameters. It plays a crucial role in assigning addresses to instances and facilitating communication.

3. Router: Routers connect different networks, enabling traffic flow. They serve as gateways, directing packets to their destinations while enforcing security policies.

Neutron Networking Models

Neutron networks offer various networking models to accommodate diverse requirements. Two popular models include:

1. Provider Network: In this model, neutron networks leverage existing physical network infrastructure. It allows users to connect virtual machines to external networks and integrate with external services seamlessly.

2. Self-Service Network: This model empowers users to create and manage their own networks within the cloud infrastructure. It provides isolation and control, making it ideal for multi-tenant environments.

Advanced Features and Capabilities

Beyond the basics, neutron networks offer a range of advanced features and capabilities that enhance network management. Some notable examples include:

1. Load Balancing: Neutron networks provide load balancing services, distributing traffic across multiple instances to optimize performance and availability.

2. Virtual Private Network (VPN): By leveraging VPN services, neutron networks enable secure and encrypted communication between networks or remote users.

Conclusion:

In conclusion, neutron networks are the invisible force behind modern connectivity, enabling seamless communication within cloud infrastructures. By abstracting the complexities of network management, they empower users to create, manage, and scale networks effortlessly. Whether connecting virtual machines or integrating with external services, neutron networks are pivotal in shaping the digital landscape. So, next time you enjoy uninterrupted online experiences, remember the underlying power of neutron networks.

network traffic engineering

Network Traffic Engineering

Network Insight · Engineering Guide

Network Traffic Engineering: Optimising Paths, Performance and Capacity

Network traffic engineering is the practice of analysing, influencing and controlling how traffic moves through a network to meet defined performance, capacity, availability and policy objectives. Rather than relying exclusively on the paths selected by conventional routing, engineers can introduce additional controls to make better use of available network resources.

A routing table may identify a valid path to a destination, but that path is not necessarily the best choice for every traffic flow. A heavily utilised link, increasing latency, packet loss or an application with strict service requirements can make an alternative path more appropriate. Traffic engineering provides the methods to understand these conditions and influence forwarding decisions where the network design permits.

The central engineering question

How can we move the right traffic across the right path, at the right time, while respecting routing policy, available capacity, resilience and security requirements?

01

Measure the network

Monitor bandwidth utilisation, latency, jitter, packet loss and link health to identify congestion, performance changes and unused capacity.

02

Control traffic behaviour

Apply routing metrics, QoS policies, load balancing or explicit paths to influence how different traffic classes use network resources.

03

Choose suitable paths

Use the capabilities of technologies such as OSPF, IS-IS, BGP, MPLS Traffic Engineering and SDN to meet defined forwarding objectives.

04

Validate the outcome

Confirm that the selected path improves the intended metric without creating new bottlenecks or undermining redundancy and policy.

These techniques operate at different layers and solve different problems. QoS manages the treatment of traffic; routing protocols determine reachability and route preference; MPLS Traffic Engineering can establish constrained label-switched paths; and SDN can provide centralised visibility and programmable forwarding. Effective designs combine these capabilities where they add measurable value.

Topics explored in this guide
Congestion Management QoS and Bandwidth OSPF and IS-IS BGP Traffic Engineering MPLS RSVP-TE SDN and OpenFlow Cloud Networking WAN Optimisation
Network Insight · Traffic Engineering Guide

Network Traffic Engineering: Optimising Paths, Performance and Capacity

Network traffic engineering is the practice of measuring network behaviour and influencing how traffic uses available paths, links and services. It helps network engineers address congestion, make better use of capacity, improve application performance and design for failure.

From QoS and routing policy to MPLS traffic engineering, SDN, cloud networking and resilient WANs, this guide explores the mechanisms that shape traffic flow—and the important differences between selecting a route, managing a queue and measuring real application performance.

Traffic Measurement Routing & ECMP MPLS & SDN Cloud Networking WAN Resilience Interactive Lab
Section 01 · Observe Before Optimising

Traffic Measurement, Congestion and Quality of Service

Effective traffic engineering starts with evidence. Before changing routing policies, adjusting link costs or introducing explicit paths, engineers need to understand how traffic behaves, where congestion develops and which applications are affected. Measurement provides the foundation for making informed decisions rather than simply moving traffic from one link to another.

A network can have complete reachability and still deliver poor application performance. Routing protocols may select valid paths while a critical interface is saturated, queues are filling, packets are being discarded or delay-sensitive traffic is competing with large data transfers. Traffic engineering connects operational measurements with decisions about capacity, forwarding and traffic treatment.

1.1 The measurements that matter

No single metric explains every performance problem. Engineers combine interface statistics, active probes, flow records, queue counters and application telemetry to establish a more complete picture of network behaviour.

Bandwidth utilisation Shows how much of a link's available capacity is being consumed. Sustained high utilisation can indicate a bottleneck.
Latency Measures how long traffic takes to travel between measurement points. High delay can affect interactive applications.
Jitter Describes variation in packet delay. It matters particularly to real-time voice, video and other timing-sensitive traffic.
Packet loss Identifies packets that fail to reach the observation point. Congestion is one possible cause, but not the only one.
Queue behaviour Queue depth, drops and scheduling statistics help reveal contention at network interfaces.
Flow distribution Shows which conversations, applications or traffic classes consume capacity and how flows are distributed across paths.
Engineering principle: measure the path, not just the interface

A link may show acceptable average utilisation while users experience intermittent delay or loss. Correlate interface counters with end-to-end measurements, queue statistics and application symptoms before deciding where to intervene.

1.2 How congestion develops

Congestion occurs when traffic demands exceed the capacity available at a particular point, either temporarily or for a sustained period. Packets may accumulate in queues, increasing delay. When buffers fill, packets are dropped. Transport protocols may then retransmit data or reduce their sending rate, potentially reducing useful throughput further.

Congestion is not always caused by insufficient total network capacity. Traffic may be unevenly distributed, a preferred route may become overloaded, or several high-volume flows may converge on the same interface. A redundant path can remain underused even while another path is congested.

Observed symptom Possible explanation Useful investigation
High utilisation over time Demand is approaching or exceeding available capacity. Review interface rates, traffic trends and capacity forecasts.
Latency rises during busy periods Packets may be waiting in queues along the path. Compare latency with utilisation and queue statistics.
Loss on a particular interface Queue drops, physical errors, policing or another forwarding issue. Inspect drop counters, error counters and policy statistics.
One path is busy while another is idle Routing policy or flow-hashing behaviour may limit distribution. Check route selection, ECMP eligibility and per-flow traffic patterns.

1.3 Quality of Service: managing competing traffic

Quality of Service (QoS) provides mechanisms for classifying traffic and applying different forwarding treatments. It does not create additional bandwidth. Instead, it helps determine how available resources are shared when traffic competes for them.

A typical QoS design classifies packets into traffic classes, marks them where appropriate, and applies queuing, scheduling, shaping or policing policies at relevant points in the network. The design must be consistent across the intended path if the required treatment is to be maintained end to end.

Classify Identify traffic using defined rules.
Mark Apply an agreed traffic-class marking.
Queue and schedule Allocate transmission opportunities.
Verify Measure drops, delay and outcomes.

Several mechanisms are frequently used together, but they serve different purposes:

  • Classification and marking: identify traffic and communicate its intended treatment, commonly using fields such as DSCP.
  • Queuing and scheduling: control how packets from different classes share an interface during contention.
  • Traffic shaping: smooths or buffers traffic to enforce a configured transmission rate over time.
  • Policing: checks traffic against a rate or burst profile and may drop or remark packets that exceed it.
  • Admission and capacity control: helps prevent the network from accepting more traffic than the intended service can support.

For example, a voice class may receive low-latency treatment while bulk file transfers use remaining capacity. The voice queue still needs appropriate rate limits and capacity planning: an incorrectly configured priority queue can starve other traffic, and QoS cannot overcome a sustained shortage of physical bandwidth.

1.4 From monitoring to traffic engineering

Measurement and QoS are closely related to traffic engineering, but they are not the same thing. QoS primarily controls how packets are treated at forwarding points. Traffic engineering can go further by influencing which paths traffic uses, how demand is distributed across the topology, and whether additional capacity or protection paths are required.

If monitoring identifies a congested link, the appropriate response depends on the cause. Engineers might tune routing metrics, adjust traffic distribution, use policy-based routing, establish an MPLS Traffic Engineering path, or apply SDN-based control. If the problem is a physical fault or a queue configuration error, changing the route alone may not solve it.

Section takeaway

Reliable traffic engineering follows a measurement-led cycle: observe performance, identify the bottleneck, choose an intervention that matches the problem, and verify the result. These measurements become the evidence base for the routing and path-selection techniques explored in the next section.

Interactive lab · 01

Traffic Measurement & QoS Workbench

Change offered traffic, available capacity and queueing policy. Run the simulation to compare a simplified traffic-engineering outcome.

1. Traffic and capacity

120 Mbps
Total traffic arriving at the link.
100 Mbps
Maximum modelled service rate.
30%
Traffic marked as critical for this illustrative model.

2. Select a QoS policy

FIFO serves packets in arrival order. It does not prioritise critical traffic.
Ready. Adjust the inputs, then run the simulation.

Simulation results

Within capacity
Link utilisation
120%
Delivered throughput
100 Mbps
Modelled delay
— ms
Estimated loss / excess
16.7%
Offered load vs link capacity 120 / 100 Mbps
Offered traffic exceeds the configured link capacity.
1. ClassifyIdentify critical traffic
2. QueueApply selected policy
3. ScheduleAllocate service capacity
4. ForwardDeliver within capacity
The offered load exceeds link capacity. QoS can influence which traffic is served first, but it cannot create additional bandwidth.
Educational model only. Delay and loss are illustrative estimates, not measurements or predictions for a real network. Actual QoS behaviour depends on the device, queue configuration, traffic mix and congestion-management implementation.
Section 02 · Influence the Route

Routing-Based Traffic Engineering: OSPF, IS-IS, BGP and ECMP

Routing-based traffic engineering uses the control plane to influence where packets travel through a network. Rather than treating the routing table as a fixed result, engineers examine path costs, available alternatives, traffic distribution and routing policy to determine whether traffic is using the topology effectively.

Traditional routing protocols are designed primarily to establish reachability and select routes according to their defined decision processes. Traffic engineering builds on those mechanisms by adjusting metrics, using multiple eligible paths, applying routing policy or introducing tools that make path selection more deliberate.

Important distinction: a valid route is not necessarily the best-performing path

A routing protocol may select a path because it has the lowest configured cost or wins a policy decision. That does not automatically mean the path has the lowest real-time latency, the most spare bandwidth or the least packet loss.

2.1 Interior routing: OSPF and IS-IS

Open Shortest Path First (OSPF) and Intermediate System to Intermediate System (IS-IS) are link-state routing protocols commonly used within an autonomous system. Routers distribute topology information, calculate paths and install eligible routes according to the protocol's rules and the configured metrics.

OSPF Cost-based path selection

OSPF calculates shortest paths using configured interface costs. Engineers can tune costs to influence path preference, provided the change is consistent with the wider design and does not create unintended traffic shifts.

IS-IS Scalable link-state routing

IS-IS distributes link-state information and calculates routes using metrics. It is widely used in service-provider and large routed networks, including as an underlay for MPLS and Segment Routing designs.

Metric tuning is useful, but it is not a complete traffic-engineering system by itself. Changing a link cost can redirect many prefixes at once, potentially moving congestion elsewhere. The effect should be assessed across the topology, not just on the router where the change is made.

2.2 Equal-Cost Multipath: using multiple eligible routes

Equal-Cost Multipath (ECMP) allows a router to install multiple next hops for a destination when the routing system considers those paths equal under the applicable selection rules. Forwarding hardware or software then distributes traffic across the eligible next hops, often using a hash based on flow attributes.

Traffic arrives Packets belong to different flows.
ECMP next hops Several eligible routes are installed.
Flow hashing Flows are assigned to available paths.

ECMP can improve link utilisation and provide path redundancy, but it does not guarantee an even split of bytes or packets. A small number of large flows, unequal link capacities, hash collisions or different traffic patterns can leave one path busier than another. A change in the next-hop set may also remap flows, depending on the implementation.

Engineering consideration

Verify the actual distribution with per-interface counters or flow telemetry. Seeing two next hops in a routing table confirms multipath eligibility; it does not prove that traffic is balanced evenly across both links.

2.3 BGP traffic engineering: influence inter-domain traffic

Border Gateway Protocol (BGP) exchanges reachability information between autonomous systems and can also support routing policy within a network. BGP traffic engineering generally involves influencing which routes are selected or how traffic enters and leaves a network, rather than directly measuring every path's live performance.

Technique Typical purpose Key limitation
Local preference Influence outbound route selection within an AS. Applies to the local routing policy domain; it does not directly command remote networks.
AS-path prepending Make an advertised route appear less attractive to some remote networks. Remote networks apply their own policies, so the result is not guaranteed.
Selective prefix advertisement Influence which destinations are reachable through particular upstreams. Requires careful prefix, policy and reachability planning.
Communities Signal policy requests to a provider or other BGP neighbour. The receiving network determines which communities it supports and honours.

BGP policy can influence traffic direction, but it should not be confused with a mechanism that automatically picks the lowest-latency path. Even when two providers offer different performance, the resulting route depends on BGP attributes, import and export policies, route availability and the decisions of other networks.

2.4 Policy-Based Routing: steer traffic by policy

Policy-Based Routing (PBR) allows forwarding decisions to be influenced by criteria beyond the destination-based routing lookup alone. Depending on the platform, a policy may match source addresses, protocol, ports, ingress interface or other packet attributes and then select a configured next hop or forwarding action.

  • Application-aware separation: send a defined class of traffic through a designated gateway or service path.
  • WAN selection: steer selected traffic toward a preferred circuit, subject to the platform's policy and tracking capabilities.
  • Service insertion: direct matching traffic through a firewall, inspection device or other network service.
  • Operational safeguards: account for unavailable next hops, asymmetric routing, return-path requirements and policy interactions.

PBR is powerful because it can provide fine-grained control, but overly broad rules can bypass intended routing behaviour or create asymmetric paths. Policies should be narrowly scoped, observable and tested against failure conditions.

2.5 Performance-based optimisation and PfR

Some network designs add a monitoring and policy layer that evaluates WAN-path performance and influences how traffic is distributed. Cisco Performance Routing (PfR), also known in later product generations as part of the Intelligent WAN family, is one example of this approach. Depending on platform and configuration, such systems can use traffic classes, reachability, delay, loss or utilisation-related information to guide path selection.

The key idea is to connect measurements to a controlled routing decision. Instead of assuming that a statically preferred path is always suitable, the system can evaluate whether traffic meets defined performance objectives and apply an allowed alternative when policy conditions are met.

Approach Primary control Best understood as
OSPF / IS-IS metric tuning Interior path cost Influencing shortest-path calculations.
ECMP Multiple equal-cost next hops Sharing eligible flows across paths.
BGP policy Route preference and advertisement Influencing route selection and traffic direction.
PBR Packet-matching rules Steering selected traffic using policy.
Performance-based WAN control Measured conditions plus policy Adapting path choice to defined objectives where supported.

2.6 A practical routing-engineering workflow

Routing changes should be treated as controlled engineering interventions. Establish a baseline, define the desired outcome and check how the change affects both the intended traffic and other traffic sharing the same infrastructure.

  • Identify the affected prefixes, applications, ingress points and egress links.
  • Determine whether the problem is route selection, flow distribution, congestion, QoS treatment or a physical fault.
  • Select the narrowest suitable mechanism: metric tuning, ECMP, BGP policy, PBR or a performance-aware control system.
  • Check convergence, redundancy, route-policy interactions and possible asymmetric forwarding.
  • Measure the outcome and retain a rollback plan if performance or reachability degrades.
Section takeaway

Routing-based traffic engineering offers several levels of control, from adjusting link-state metrics to distributing flows with ECMP, influencing BGP route policy and steering selected packets with PBR. The correct choice depends on what needs to be controlled. When traffic requires a deliberately constrained path rather than ordinary route preference, MPLS Traffic Engineering introduces another set of tools.

Interactive lab · 02

Routing-Based Traffic Engineering Lab

Explore how routing metrics, BGP policy, equal-cost paths and traffic classification can influence packet forwarding.

1. Configure the routing scenario

PBR can steer selected traffic using configured match rules. Other traffic may follow the normal routing table.
Ready to simulate.

2. Selected forwarding path

Illustrative network: R1 forwards traffic towards destination R4 over one of two paths.

R1 R2 R3 R4 Cost 10 Cost 10 Cost 20 Cost 20
Selected path Available alternative Unavailable link
Chosen path
R1–R2–R4
Path cost
20
Active paths
1
The upper path has the lower illustrative metric, so the metric-based strategy selects it.
Learning model, not a router emulator. The example metrics and BGP policy preferences are illustrative. Real BGP best-path selection follows implementation-specific rules and configured attributes; BGP does not inherently select the lowest-latency route from live performance measurements. ECMP requires eligible equal-cost routes and compatible forwarding configuration.
Section 03 · Engineer the Path

MPLS Traffic Engineering: RSVP-TE, Explicit Paths and Fast Reroute

Multiprotocol Label Switching (MPLS) Traffic Engineering gives network operators greater control over how selected traffic crosses a routed core. Instead of relying exclusively on each router's ordinary shortest-path forwarding decision, an engineered path can be established to follow a planned route and, where supported, meet configured resource constraints.

This is particularly useful in service-provider networks, enterprise WANs and large IP backbones where several links may be available between the same endpoints. A shortest path can be perfectly valid yet concentrate traffic on a small number of links, leaving other capacity underused. Traffic engineering provides tools for controlling that distribution.

Core concept: reachability and path engineering are different tasks

An IGP such as OSPF or IS-IS supplies topology and reachability information. MPLS Traffic Engineering can use that information, together with engineering constraints and signalling, to establish a specific label-switched path through the network.

3.1 Understanding the MPLS forwarding model

In an MPLS network, packets are forwarded using labels attached to packets or frames. A Label Edge Router (LER) commonly classifies incoming traffic and pushes an MPLS label at the ingress edge. Intermediate Label Switch Routers (LSRs) forward traffic by swapping labels. At or near the egress, the label is removed and the packet continues toward its destination.

Ingress Classify and label

The ingress router identifies the traffic or forwarding equivalence class and applies the appropriate label stack for the selected forwarding path.

Core Switch labels

Core routers use label-forwarding entries to send traffic toward the next hop without requiring a full IP route lookup for every transit packet.

Egress Remove or process labels

The egress side processes the label stack and forwards the traffic toward its destination according to the service design.

Control plane Establish forwarding state

Routing and label-distribution mechanisms provide the information needed to build the forwarding entries used by the data plane.

MPLS forwarding alone does not guarantee that traffic follows an optimised path. Conventional MPLS label-switched paths may follow the IGP's shortest-path calculations. MPLS Traffic Engineering adds mechanisms for selecting and signalling paths that may differ from that default.

3.2 What is an MPLS Traffic Engineering tunnel?

An MPLS-TE tunnel represents a logical forwarding path from an ingress router toward an egress router. The tunnel can be associated with a planned route, resource requirements and protection behaviour. Traffic is then mapped onto the tunnel using the routing and forwarding mechanisms supported by the implementation.

The physical topology remains unchanged. What changes is the selected route through that topology and the forwarding state used to carry the traffic. Multiple tunnels can be engineered for different destinations, traffic classes or operational requirements.

Define Specify endpoints and path constraints.
Signal Request path establishment and resources.
Forward Carry traffic over the established LSP.
Monitor Check path health and resource usage.

3.3 RSVP-TE and constrained path selection

Resource Reservation Protocol Traffic Engineering (RSVP-TE) is a signalling mechanism historically used to establish MPLS traffic-engineered label-switched paths. The ingress router determines a candidate path using available topology and constraint information, then uses RSVP signalling to request establishment along that path.

Intermediate routers participate in signalling and maintain the required path state. Depending on the configuration and network capabilities, a path may include explicit hops, bandwidth requirements, administrative constraints and protection preferences.

Engineering input What it helps control Design consideration
Explicit route Constrains the path to specified hops or route segments. Explicit hops must remain reachable and compatible with the intended design.
Bandwidth requirement Requests that the path satisfy supported reservation constraints. Reservations depend on configured link attributes and admission-control state; they do not create physical capacity.
Administrative constraints Include or exclude links based on configured attributes. Link attributes must be maintained accurately and consistently.
Path optimisation Select a feasible candidate according to the configured objective. A path that is optimal under configured metrics may not be optimal for every real-time application metric.

RSVP-TE can reserve resources according to the network's configured reservation model. This is different from simply assigning a high QoS priority to packets. A reservation does not automatically guarantee application performance under every failure or congestion condition, and its effectiveness depends on correct capacity planning and operational configuration.

3.4 Why engineered paths can improve utilisation

Imagine a core network with two possible routes between an ingress and an egress router. The IGP's preferred route crosses a heavily used link, while an alternative route has spare capacity but more hops. A traffic-engineered tunnel can be configured to use the alternative when the path satisfies the intended constraints.

The objective is not always to choose the path with the fewest hops. Depending on the service, the objective might be to avoid a constrained link, satisfy a bandwidth requirement, keep traffic away from a particular administrative domain or provide a path that is independent of the primary route.

Do not confuse path length with path quality

A longer route can sometimes provide better capacity distribution or resilience. However, additional hops can also add delay and operational complexity. Compare the candidate paths against the actual engineering objectives instead of assuming that either the shortest or longest path is inherently better.

3.5 Fast Reroute: protecting traffic against failure

Traffic engineering also addresses what happens when a link or router fails. Without a pre-established protection mechanism, traffic may depend on routing convergence before it can use a new path. Fast Reroute (FRR) mechanisms can provide a locally available backup forwarding action intended to protect traffic while broader recovery takes place.

  • Link protection: aims to keep traffic moving when a particular link fails, using an eligible alternate path.
  • Node protection: aims to protect against failure of a downstream router where a suitable bypass is available.
  • Backup path design: requires an alternate that is genuinely independent of the protected resource where possible.
  • Post-failure capacity: the backup must be able to carry the redirected load without creating a new unacceptable bottleneck.

Protection is not the same as eliminating failure. A backup may be unavailable, share a common risk with the primary path or become congested when traffic shifts. Engineers should test failure scenarios and verify both the switchover behaviour and the resulting forwarding path.

3.6 MPLS-TE in modern network design

RSVP-TE remains important in many established networks, but it is not the only approach to traffic-engineered paths. Segment Routing can encode a path using a sequence of segments and may reduce the need to maintain per-tunnel signalling state at every transit router, depending on the architecture. The best choice depends on existing infrastructure, operational skills, interoperability and service requirements.

Whichever technology is used, the engineering process remains similar: define the objective, understand the topology, calculate a feasible path, install forwarding state, monitor performance and plan for failures. Traffic engineering is effective when the control-plane design is supported by accurate telemetry and disciplined operational practice.

Section takeaway

MPLS Traffic Engineering extends ordinary routing by allowing selected traffic to use engineered label-switched paths. RSVP-TE can signal explicit or constrained paths and support reservation and protection mechanisms. The next section moves from distributed routing and signalling toward SDN and OpenFlow, where a controller can coordinate forwarding decisions across multiple devices.

Interactive lab · 03

MPLS Traffic Engineering Workbench

Build a constrained path, inspect illustrative MPLS labels, and test what happens when a link fails with or without a pre-planned Fast Reroute backup.

1. Configure the LSP

40 Mbps
Each link advertises an illustrative available bandwidth value.
FRR can switch traffic to a pre-established local repair path when the protected failure is detected and the backup is usable.
Ready to simulate.

2. Inspect the selected path

Cost 10 Cost 10 Cost 15 Cost 15 Cost 5 R1 R2 R3 R4 Ingress Egress
Active LSPFRR repair pathFailed link
Selected route
R1–R2–R4
Path cost
20
Bandwidth fit
Pass
Illustrative label at R1Push 16001
Transit actionSwap 16002
Egress actionPop label
The explicit LSP follows R1–R2–R4. Label operations and path feasibility are illustrative.
Educational model only. Label values are fictional examples, not live router state. The simulation approximates path constraints using link bandwidth and illustrative costs. RSVP-TE signalling, admission control, label distribution, CSPF, failure detection and FRR behaviour depend on the real network's configuration and platform.
Section 04 · Centralised Control

SDN, OpenFlow and Centralised Traffic Engineering

Software-Defined Networking (SDN) introduces a programmable approach to network control. Rather than relying exclusively on independent configuration and distributed routing decisions at each device, an SDN architecture can give a controller a broader view of network topology, policy and observed conditions. The controller can use that view to calculate forwarding decisions and coordinate changes across supported devices.

This is valuable for traffic engineering because congestion and inefficient path selection are often network-wide problems. A link may look attractive from the perspective of one router while using it could overload a shared resource elsewhere. A controller with sufficiently current topology and telemetry can evaluate a wider set of alternatives before deploying a policy.

SDN is an architecture, not a single protocol

A controller-based design may use OpenFlow, NETCONF, gNMI, APIs or vendor-specific interfaces, depending on the devices and architecture. OpenFlow is one protocol associated with SDN; not every SDN system uses it.

4.1 The main components of an SDN design

Application layer Express the objective

Applications describe the intended policy, such as prioritising a traffic class, selecting a path or avoiding a constrained link.

Control layer Analyse and decide

The controller evaluates available topology, policy, device capabilities and telemetry to calculate an appropriate forwarding strategy.

Infrastructure layer Forward the traffic

Switches and routers apply supported forwarding rules or configuration changes to implement the selected behaviour.

Feedback Observe the outcome

Counters, events and measurements help the system assess whether the policy is working and whether another action is required.

4.2 How OpenFlow can influence forwarding

OpenFlow defines a protocol through which a controller can communicate with compatible forwarding devices. In an OpenFlow-capable switch, flow tables contain entries that match packet fields and specify actions, such as forwarding a packet to a port, modifying supported fields or sending selected traffic to the controller.

The controller can install, modify or remove flow entries according to its application logic and the capabilities of the switch. This enables explicit control over matching traffic, although the exact match fields, actions, table pipeline and hardware support depend on the OpenFlow version and implementation.

Collect Read topology and device information.
Calculate Evaluate paths and policy constraints.
Install Apply compatible forwarding rules.
Verify Observe counters and traffic outcomes.

A controller does not magically gain control over every device in the network. Devices must expose a compatible interface, the controller must understand their capabilities, and the design must account for existing forwarding state and other control-plane systems.

4.3 Centralised path selection using network metrics

A traffic-engineering controller can score candidate paths against defined objectives. For example, a policy might reject paths that fail a bandwidth requirement, penalise paths with high observed delay, avoid links with excessive loss, and prefer a suitable path with more available capacity.

A simplified illustrative scoring model could combine normalised measurements:

Illustrative path score

Path score = (latency weight × latency score) + (loss weight × loss score) + (jitter weight × jitter score) + (utilisation weight × utilisation score).
In this example, lower scores are preferred. Real systems must define normalisation, units, thresholds, missing-data handling and hard constraints carefully.

This model is a conceptual example, not a standard OpenFlow algorithm. A production controller may use graph algorithms, constraint-based path computation, optimisation solvers or simpler policy rules. Measurements can also be stale or noisy, so a robust system avoids changing paths in response to every small fluctuation.

4.4 Example: selecting a path through a diamond topology

Consider a source router connected to two intermediate routers, both of which can reach the same destination. One candidate path has lower latency but is approaching its capacity limit. The other has slightly higher latency but more spare bandwidth. A controller can evaluate both against the application's policy and select a path that meets the required performance and capacity objectives.

Candidate path Observed condition Possible policy result
Path A Low latency, but high utilisation. Prefer it for delay-sensitive traffic only if capacity constraints remain satisfied.
Path B Moderate latency, more spare capacity. Prefer it for a high-volume flow if it meets the application's delay limit.
Backup path Available alternative with acceptable failure-domain separation. Retain as a recovery option if the primary path becomes unavailable.

The right answer depends on the service objective. A video-conferencing flow may be sensitive to delay and jitter, while a large replication flow may place greater emphasis on sustained throughput. The controller should evaluate traffic against explicit requirements rather than applying one universal ranking to every application.

4.5 Centralised control versus distributed routing

Centralised and distributed control are not mutually exclusive. Many networks use a distributed IGP or BGP for basic reachability while a controller provides additional policy, automation or traffic-engineering decisions. This combination can preserve the strengths of established routing while introducing more coordinated control.

Consideration Distributed routing Controller-based control
Decision scope Routers make decisions using their protocol state and configured policies. A controller can evaluate a broader topology view, subject to the data it receives.
Convergence and updates Protocols exchange updates and recalculate routes as network state changes. Changes depend on controller logic, telemetry, device interfaces and deployment behaviour.
Programmability Typically configured through routing policies and device features. Can support policy automation and coordinated changes through software.
Failure considerations Distributed protocols can continue operating according to their local state and design. Requires controller availability, secure communication and a strategy for stale or lost control connectivity.
Operational complexity Familiar protocols, but potentially many separate device configurations. Centralised automation can simplify operations, but introduces software, integration and policy-validation requirements.

4.6 Stability, security and safe deployment

A centralised view can improve coordination, but poorly designed control loops can cause traffic to oscillate between paths. If several flows are moved at once, the new path may become congested, triggering another round of changes. Telemetry delay can make the controller react to conditions that no longer exist.

  • Use guardrails: define capacity limits, acceptable performance ranges and policy constraints before deploying changes.
  • Reduce oscillation: use thresholds, hold-down periods or hysteresis where appropriate to avoid unnecessary path changes.
  • Validate first: test controller decisions and device compatibility in a lab or limited deployment.
  • Secure the control channel: restrict access, authenticate components and protect controller APIs and management interfaces.
  • Plan for controller failure: define what devices should do when controller connectivity is lost or policy information becomes stale.
  • Keep a rollback path: record previous configuration and provide a tested recovery procedure.
Visibility must lead to verified action

A controller may calculate an excellent theoretical path, but success depends on whether the forwarding devices can implement it, whether the route remains available, and whether measured application performance improves after deployment.

4.7 Where SDN fits in the traffic-engineering toolkit

SDN is most useful when policy and forwarding decisions benefit from coordination across devices or when repetitive changes can be automated safely. It can complement IGP metrics, BGP policy, ECMP, MPLS-TE and QoS rather than replacing every existing mechanism.

The practical goal is to connect network-wide intent with measurable outcomes. A controller should understand what the network is trying to achieve, choose a feasible action, deploy that action through supported interfaces, and verify that the result matches the objective.

Section takeaway

SDN enables programmable, coordinated traffic control, while OpenFlow is one possible interface for managing forwarding rules on compatible devices. Centralised visibility can support more deliberate path selection, but dependable traffic engineering still requires accurate telemetry, stable control logic, secure interfaces and a tested failure strategy. The next section examines how these principles apply to cloud networking, load balancing and Kubernetes.

Interactive lab · 04

SDN Controller & Traffic Engineering Lab

Compare distributed shortest-path routing with controller-selected paths. Change link utilisation, simulate a failure, and inspect the illustrative forwarding decision.

1. Configure the network

85%
Illustrative utilisation for the R1–R2–R4 path.
35%
Illustrative utilisation for the R1–R3–R4 path.
Uncheck this to model a controller-dependent decision that cannot be updated. Existing forwarding may persist, but adaptation is not assumed.
Ready to simulate.

2. View the forwarding decision

SDN Controller Upper path Utilisation Lower path Utilisation R1 R2 R3 R4 Ingress → selected path → egress
Selected forwarding pathUnavailable path
Selected path
R1–R3–R4
Modelled utilisation
35%
Decision state
Installed
The controller selects the less-utilised path in this illustrative model. Real SDN decisions depend on telemetry, policy, controller logic and the capabilities of the forwarding devices.
Educational model only. The utilisation values are illustrative inputs, not measured network telemetry. OpenFlow is one protocol that can be used between a controller and compatible switches; SDN can also use other southbound interfaces. A controller does not automatically provide global optimisation unless its data, policies and control logic support it.
Section 05 · From Network to Application

Cloud, Kubernetes and Application Traffic Engineering

Traffic engineering extends beyond traditional routers and WAN circuits. In cloud and container environments, performance depends on how virtual networks route packets, how load balancers distribute requests, how applications are deployed across regions, and which services are permitted to communicate. These mechanisms operate at different layers, but they all influence the path or destination that traffic takes.

A useful design begins by distinguishing network routing from request distribution and security policy. A virtual network route determines where packets are forwarded next. A load balancer chooses a backend or service endpoint for a connection or request. A Kubernetes NetworkPolicy defines permitted communication between selected workloads, subject to the network plugin's implementation. These controls complement one another rather than replacing one another.

Three different control problems

Routing answers, “Where should packets go next?” Load balancing answers, “Which eligible backend should handle this traffic?” Network policy answers, “Which communications are allowed?” Confusing these responsibilities can lead to ineffective optimisation or security gaps.

5.1 Cloud virtual networks and route selection

Cloud platforms provide virtual networking constructs such as virtual private clouds, subnets, route tables, gateways, peering connections and private connectivity services. Together, these determine how traffic moves between workloads, services and external networks.

In Google Cloud, for example, Virtual Private Cloud (VPC) routes participate in forwarding decisions within the supported network environment. Route destinations, next-hop types, route priority and other platform-specific rules affect which route is selected. VPC peering can provide private connectivity between eligible networks, but it does not automatically make every route transitive across a chain of peerings.

Route tables Control packet forwarding

Routes associate destination ranges with next hops. Engineers should check route priority, destination specificity, reachability and the supported next-hop type.

Network connectivity Connect workloads and networks

Peering, VPNs, dedicated connectivity and gateways provide different connectivity models, each with its own routing and reachability constraints.

Observability Trace actual traffic behaviour

Flow logs, route inspection, health information and application telemetry help identify where traffic is delayed, dropped or sent along an unexpected path.

Capacity planning Match demand to resources

Regional capacity, service quotas, network limits and workload placement can constrain the available options even when a route exists.

Cloud routing is not identical to physical-router routing. Providers implement their own control planes and forwarding rules, and some behaviour is managed by the platform rather than exposed as a customer-configurable protocol. Engineers should use the provider's documented route-selection and connectivity model when diagnosing a cloud traffic path.

5.2 Load balancing: distributing connections and requests

Load balancing distributes eligible traffic across a set of backend services or endpoints. Depending on the product, a load balancer may operate at Layer 4, making decisions using transport-layer information, or at Layer 7, where HTTP attributes and application-level information can influence routing.

Client Sends a connection or request.
Load balancer Evaluates policy and backend health.
Backend pool Receives traffic on selected endpoints.

Backend selection may consider health checks, configured balancing policies, locality, connection persistence, capacity or other product-specific criteria. The exact behaviour varies by load balancer type, so engineers should not assume that every service chooses the backend with the lowest live latency.

Mechanism Primary responsibility Example use
Network routing Forwards packets toward a destination or next hop. Reach a workload subnet through a valid virtual route.
Layer 4 load balancing Distributes transport connections or flows. Spread TCP or UDP traffic across eligible backends.
Layer 7 load balancing Routes application requests using supported application attributes. Send requests to different services based on host or URL rules.
Health checks Determine whether a backend is eligible to receive traffic. Stop sending new traffic to an unhealthy service endpoint.

5.3 Cross-region traffic engineering

Applications deployed in multiple regions can improve availability and serve users from geographically distributed locations. However, distributing traffic across regions introduces decisions about latency, regional capacity, data locality, cost, service dependencies and disaster recovery.

Global or cross-region load balancing can direct traffic to eligible backends in different locations according to the service's supported selection model. A well-designed policy considers backend health and regional availability while avoiding a configuration in which one region becomes overloaded during a surge or a regional failure.

  • Latency and proximity: consider where users are located and how application response time varies by region.
  • Regional capacity: ensure each region can support its expected demand and any planned failover load.
  • Health and readiness: verify that the service can safely receive requests before sending traffic to it.
  • Data dependencies: account for replication delay, state consistency and services that are available in only one region.
  • Cost and egress: evaluate the financial impact of cross-region traffic and data transfer.
  • Failure testing: verify how traffic is redistributed when a region or backend pool becomes unavailable.
Failover must be capacity-aware

A second region is not a complete resilience strategy if it cannot handle the workload displaced by a failure. Test realistic traffic volumes and dependencies, not just whether a health check causes traffic to move.

5.4 Kubernetes networking and NetworkPolicy

Kubernetes introduces additional networking layers because applications run in pods that can be created, moved, scaled or replaced dynamically. Services provide stable ways to reach groups of pods, while ingress controllers, gateways or service meshes can provide further traffic-management capabilities depending on the cluster architecture.

Kubernetes NetworkPolicy is primarily a traffic-permission mechanism. It specifies which connections are allowed to or from selected pods, based on supported selectors and rules. It does not, by itself, choose the lowest-latency route, distribute traffic evenly between pods or guarantee that a particular path will be used. Enforcement requires a network implementation that supports NetworkPolicy.

Service Provide stable service access

A Kubernetes Service provides a stable abstraction for reaching a group of eligible endpoints, while the cluster's data plane handles traffic forwarding.

Ingress or gateway Control external application entry

Supported ingress or gateway implementations can route application traffic toward services using their configured rules and capabilities.

NetworkPolicy Restrict permitted connections

Policy rules can limit communication between workloads and other permitted peers, reducing unnecessary network exposure.

Telemetry Observe workload performance

Application metrics, service-level indicators, flow data and cluster events help distinguish network problems from application or resource bottlenecks.

5.5 Application-aware traffic steering

Application-aware steering makes forwarding or backend decisions using information about the service, request or traffic class. Depending on the architecture, this may be implemented by an application load balancer, API gateway, service mesh, SDN controller or a policy-aware WAN platform.

Consider a service that has both a current application version and a legacy version. A request can be directed according to a validated application-version header, authenticated identity, hostname or route rule. Such decisions should be made at the appropriate application-aware layer rather than assuming that ordinary IP routing understands application identity.

Steering input Possible decision Safeguard
Host or URL path Send a request to a matching application service. Validate routing rules and avoid exposing unintended endpoints.
Authenticated identity Apply access or service-routing policy for an authorised user or client. Verify identity tokens and enforce authorisation server-side.
Application version Direct eligible requests to a new or legacy service. Validate the version value and do not trust a client-supplied header on its own.
Backend health Remove unhealthy endpoints from new traffic selection. Use meaningful health checks and test recovery behaviour.

Headers such as X-App-Version are ordinary request metadata, not proof of identity or permission. A client may be able to alter them. If a decision affects access or sensitive operations, validate the request against trusted authentication and authorisation information, and enforce the rule at a trusted gateway or service boundary.

5.6 Combining the controls into one design

Consider an application deployed across two cloud regions, with several Kubernetes services behind regional load balancers. The network route table provides connectivity between the relevant components. Regional load balancers select healthy backends. Kubernetes Services provide stable access to pods, while NetworkPolicy restricts permitted workload communication. Application-level rules may then steer requests based on service paths or validated identity.

If users experience slow responses, engineers should investigate each layer independently before changing the design. The problem might be a route issue, overloaded backend, unhealthy pod, cross-region dependency, restrictive network policy or slow application query. A change at the wrong layer can hide the symptom without correcting its cause.

  • Trace the request path from the client through the load balancer, network and application service.
  • Check route selection and connectivity between the relevant networks and subnets.
  • Review backend health, endpoint availability and regional utilisation.
  • Verify that NetworkPolicy permits the required communication without granting unnecessary access.
  • Correlate network measurements with application latency, errors and resource metrics.
  • Test scaling, backend loss and regional failover under representative demand.
Section takeaway

Cloud and application traffic engineering combines several distinct controls: virtual routes determine packet forwarding, load balancers distribute connections or requests, Kubernetes networking connects workloads, and NetworkPolicy restricts permitted communication. The strongest designs coordinate these layers while measuring the actual outcome. The next section moves back toward WAN engineering, including DMVPN, NHRP and IPv6 path behaviour.

Interactive lab · 05

Cloud & Kubernetes Traffic Engineering Lab

Choose a traffic-steering layer, vary application demand, and simulate an unhealthy backend. See how cloud routing, load balancing and Kubernetes service selection solve different problems.

1. Configure traffic delivery

120 req/s
Illustrative requests per second reaching the service.
If disabled, this simplified model may send traffic to an unhealthy backend, illustrating the importance of health-aware selection.
Ready to simulate.

2. Inspect the delivery path

Incoming requests Cloud routing layer Backend A Backend B Backend C 40 req/s 40 req/s 40 req/s Illustrative backend distribution
Selected delivery pathUnused or unavailable path
Traffic delivered
120 req/s
Active backends
3 of 3
Unserved demand
0 req/s
Network layerRoute selection
Service layerBackend selection
App layerRequest policy
A cloud network route determines where packets are forwarded. A load balancer or service proxy selects a backend; these functions are related but not interchangeable.
Educational model only. Requests are divided evenly or by a simplified policy; no real cloud account, Kubernetes cluster, health probe, or application header is accessed. Kubernetes Services distribute traffic according to the cluster's networking implementation and endpoint state. Application-provided headers are not trusted identity unless validated by a trusted component.
Section 06 · Engineer the WAN

WAN Traffic Engineering: DMVPN, NHRP and IPv6

Wide Area Network (WAN) traffic engineering must account for more than the route selected by a routing protocol. Enterprise WANs often combine hub-and-spoke connectivity, encrypted tunnels, multiple transport circuits and remote branches with different bandwidth and latency characteristics. The engineering challenge is to direct traffic appropriately, make efficient use of available paths and preserve connectivity when links or tunnels fail.

Dynamic Multipoint VPN (DMVPN), the Next Hop Resolution Protocol (NHRP), routing policy and IPv6 neighbour and router-discovery mechanisms solve different problems within this environment. Understanding their roles helps engineers distinguish tunnel establishment and address resolution from route selection and traffic optimisation.

Keep the functions separate

DMVPN provides a framework for dynamic multipoint tunnel connectivity. NHRP helps spokes discover the tunnel endpoint information needed for direct communication. Routing protocols determine network reachability, while routing policy and supported path-selection features influence which available route traffic uses.

6.1 DMVPN: flexible hub-and-spoke connectivity

DMVPN is a Cisco networking architecture commonly built from multipoint GRE (mGRE), NHRP and IPsec. It enables a hub-and-spoke VPN design in which remote sites can use a shared multipoint tunnel interface rather than requiring a separately configured static GRE tunnel for every possible spoke-to-spoke connection.

Multipoint GRE Provide tunnel encapsulation

mGRE supports multiple tunnel destinations through a multipoint interface, allowing the architecture to scale more flexibly than a collection of individually configured point-to-point GRE tunnels.

NHRP Resolve remote tunnel endpoints

NHRP allows a spoke to register its tunnel information with a hub and discover the mapping needed to communicate directly with another spoke when the design supports it.

IPsec Protect tunnel traffic

IPsec can provide confidentiality, integrity and peer authentication according to the configured security policy and negotiated parameters.

Routing protocol Exchange reachability

A supported routing protocol can advertise branch prefixes and provide the route information needed to send traffic through the overlay.

6.2 DMVPN phases and direct spoke-to-spoke traffic

DMVPN designs are commonly described in phases. The phase influences how routing information and next-hop behaviour interact with NHRP and whether direct spoke-to-spoke forwarding can be established.

DMVPN phase Typical behaviour Traffic-engineering consideration
Phase 1 Spoke-to-spoke traffic typically traverses the hub. Simple centralised forwarding, but the hub can become a bandwidth or latency bottleneck.
Phase 2 Direct spoke-to-spoke tunnels can be established, with routing and next-hop requirements that preserve the remote spoke as the next hop. Can reduce hub transit, but route summarisation and next-hop handling require careful design.
Phase 3 NHRP redirect and shortcut mechanisms can help spokes discover and establish direct paths while allowing more scalable hub-oriented routing designs. Can improve direct-path efficiency, but depends on compatible configuration and correct operation of the redirect and shortcut process.

Exact configuration requirements vary by platform and software version. The phase label alone does not guarantee a particular path: verify the installed route, next-hop resolution, NHRP state and actual forwarding behaviour.

6.3 How NHRP shortcuts change the traffic path

In a hub-and-spoke overlay, the hub may initially provide reachability between two spokes. When a spoke sends traffic toward a remote branch, the hub can identify an opportunity for direct communication and send an NHRP redirect in a supported Phase 3 design. The source spoke can then use NHRP to resolve the remote spoke's tunnel endpoint and establish a shortcut path.

Initial traffic Spoke A forwards toward Spoke B through the hub.
Redirect The hub indicates that a shortcut may be appropriate.
NHRP resolution Spoke A discovers the remote tunnel endpoint.
Direct path Eligible traffic can travel between the spokes.

A shortcut can reduce unnecessary hub transit and may improve latency or relieve hub capacity. However, a direct tunnel is not automatically the fastest or most resilient path. The underlay Internet or private WAN path between spokes may have different delay, loss and capacity characteristics, and the tunnel still depends on valid routing and security state.

Measure the overlay and the underlay

If a DMVPN application performs poorly, inspect both the logical overlay route and the physical or provider path carrying the tunnel. Tunnel state alone does not prove that the underlying transport is healthy or that the selected route meets the application's needs.

6.4 Routing policy across multiple WAN paths

Many enterprise WANs have more than one available transport, such as broadband Internet, private WAN connectivity or cellular backup. Routing metrics and policy can influence which path is preferred, while platform-specific tracking or performance-based WAN features may respond to reachability or measured conditions.

  • Primary and backup paths: define a preferred route and verify that an alternate becomes usable when the primary fails.
  • Traffic separation: use supported routing policy or PBR to direct selected traffic through an appropriate WAN service.
  • Dynamic tunnel selection: consider which peers and tunnel endpoints remain reachable after an underlay change.
  • Capacity and cost: account for circuit bandwidth, data-transfer costs and the demand expected during failover.
  • Asymmetric forwarding: check whether outbound and return traffic follow compatible paths, particularly when stateful firewalls or NAT are involved.

Basic route preference does not inherently measure real-time latency or loss. Where a design requires application-specific performance objectives, use an appropriate performance-monitoring and path-selection capability rather than assuming that a lower routing metric always identifies the best-performing circuit.

6.5 IPv6 Router Advertisements and path preference

IPv6 introduces its own mechanisms for discovering routers and learning default-router information. Hosts can receive Router Advertisements (RAs) through Neighbor Discovery, with information such as router preference helping a host distinguish between advertised default routers when the relevant conditions and implementations support that behaviour.

Router preference is not a general-purpose traffic-engineering metric. It does not directly measure bandwidth, application latency or packet loss. It helps influence a host's choice among eligible default routers, while broader IPv6 route selection also depends on the destination, routing table and other applicable rules.

IPv6 mechanism Purpose What it does not guarantee
Router Advertisement Advertises router and network information to IPv6 hosts. Does not automatically identify the lowest-latency upstream path.
Default-router preference Helps distinguish advertised default routers according to supported preference rules. Does not guarantee that the preferred router has more capacity or better performance.
IPv6 routing protocol Provides routes and reachability within the relevant routing domain. Does not automatically optimise every application flow using real-time metrics.
Policy and monitoring Can guide path choice based on defined operational objectives. Cannot compensate for missing telemetry, incorrect policy or unavailable connectivity.

6.6 WAN failure handling and validation

A resilient WAN design must be tested under failure, not just during normal operation. A tunnel can remain configured while its underlying path has degraded, and a routing change can restore reachability without restoring acceptable application performance.

  • Confirm that the expected routes are installed and that next hops resolve correctly.
  • Inspect tunnel state, NHRP mappings and shortcut behaviour where applicable.
  • Measure delay, jitter, loss and throughput over the actual traffic path.
  • Simulate loss of a circuit, hub or remote endpoint and verify recovery behaviour.
  • Check firewall, NAT and security-association behaviour when traffic moves between paths.
  • Confirm that backup capacity is sufficient for the traffic redirected during failure.
  • Review IPv6 Router Advertisements and default-router behaviour separately from IPv4 routing.
Section takeaway

WAN traffic engineering combines routing policy, tunnel architecture, endpoint discovery and failure planning. DMVPN and NHRP can support dynamic branch connectivity and direct spoke-to-spoke paths, while IPv6 Router Advertisements influence host-side router discovery. None of these mechanisms alone guarantees optimal performance: validate the installed routes, tunnel state, underlying transport and measured application outcomes. The next section brings these principles together in an interactive traffic-engineering lab.

Interactive lab · 06

WAN Traffic Engineering Workbench

Explore DMVPN phases, NHRP shortcut behaviour, WAN link failures, and IPv6 default-router preference in one illustrative topology.

1. Configure the WAN

80 ms
Illustrative one-way delay estimate for the hub-mediated path.
30 ms
Illustrative one-way delay estimate for a direct spoke-to-spoke path.
This illustrates RFC 4191 router preference, not latency measurement.
Ready to simulate.

2. Inspect the WAN path

A–Hub Hub–B Spoke shortcut HUB A B WAN overlay
Selected pathNHRP shortcutUnavailable tunnel
Forwarding path
A → B direct
Modelled delay
30 ms
Shortcut state
Formed
IPv6 default-router selection example
Router A preferenceMedium
Router B preferenceHigh
Illustrative preference outcomeRouter B preferred
In Phase 3, NHRP can help spokes discover a direct shortcut after traffic initially traverses the hub. Exact behaviour depends on platform, configuration, routing and tunnel state.
Educational model only. Delay values are user-entered illustrations, not live measurements. DMVPN phase behaviour depends on implementation and configuration. NHRP resolves protocol next-hop information and can support shortcut formation; it does not guarantee a faster path. IPv6 Router Advertisement default-router preference expresses High, Medium or Low preference and is not a live latency or performance metric.
Section 07 · Interactive lab

Interactive Traffic Engineering Lab: Compare Paths, Manage Congestion and Protect Resilience

Traffic engineering turns network measurement into a forwarding decision. In this simplified lab, you will compare two paths across a small WAN, inspect latency and utilisation, and see how a failed link can change the preferred route.

The topology and metrics are illustrative, not live measurements. They represent a network in which a traffic engineer must balance delay, link utilisation and resilience rather than choosing a route based on hop count alone.

Lab objective

Choose a routing strategy, adjust the demand placed on the network and simulate a link failure. Observe how the selected path changes, then consider whether the lowest-latency path is also the best operational choice.

Path Selection Workbench Source: Edge A · Destination: Edge D · Two candidate routes through a diamond-shaped WAN.
Selected path A–C–D
Estimated latency 28 ms
Peak link utilisation 55%
Path status Available
Interactive diamond WAN topology Edge A connects to routers B and C, which each connect to destination D. The highlighted route indicates the currently selected path. 40 ms · 70% 35 ms · 65% 15 ms · 45% 13 ms · 55% A B C D Source Destination Illustrative WAN · Values are simulated
Selected route Available alternative Failed link
ROUTE SELECTED Balanced path selected

The lower path offers a lower estimated latency in this example. The selected strategy also considers utilisation when comparing candidate routes.

7.1 Understand the simulated network

The WAN uses four routers and two end-to-end candidate paths. The upper route passes through B, while the lower route passes through C. Each link has a baseline latency and utilisation value. The simulation distributes the additional offered load across the links of the selected path and estimates a congestion-related delay penalty as utilisation rises.

Candidate path Baseline latency Initial peak utilisation Engineering consideration
A–B–D 75 ms 70% Higher baseline delay and less headroom on its most utilised link.
A–C–D 28 ms 55% Lower baseline delay and more headroom in the initial example.

7.2 Experiment with the routing strategy

  • Lowest estimated latency: selects the available path with the lowest modelled delay, including the simulation's congestion penalty.
  • Balanced latency and utilisation: scores candidate paths using both estimated delay and peak link utilisation.
  • Prefer lower utilisation: favours the route with more remaining headroom, while still considering estimated delay.
  • Manual selection: lets you choose a path directly and compare it with the automatic strategies.

These are teaching strategies, not exact implementations of OSPF, IS-IS, BGP, RSVP-TE or a commercial SD-WAN controller. Real networks use protocol-specific metrics, policies and constraints. A routing protocol does not automatically use live latency and utilisation simply because those measurements are available elsewhere.

7.3 Simulate congestion and link failure

Increase the offered load to see how the selected route's modelled utilisation and delay change. Then select Simulate upper-link failure. The upper route becomes unavailable, and the automatic strategies must use the remaining path. If the manually selected route is no longer available, the lab reports that condition rather than silently claiming that the manual choice succeeded.

What this demonstrates

A path that looks attractive under normal conditions may lose its advantage when demand increases or a link fails. Traffic engineering should consider performance, capacity, policy and resilience together, and should be validated with actual telemetry and failure testing before being deployed.

7.4 Engineering review checklist

  • Are latency, loss and utilisation measured on the same traffic path and over a suitable time window?
  • Does the selected route have sufficient capacity for expected demand and failover traffic?
  • Are primary and backup paths genuinely independent, or do they share a circuit, provider or physical conduit?
  • Can routing policy and security controls accommodate a path change?
  • Does the recovery process restore acceptable application performance, not merely basic reachability?
  • Are the path-selection decisions observable, explainable and reversible?
Section takeaway

Traffic engineering is a continuous process of measurement, path selection, validation and adjustment. Use the lab to explore trade-offs, then apply the same reasoning to routing policy, MPLS traffic engineering, SDN controllers and WAN designs. In production, base decisions on trustworthy telemetry, documented objectives and repeatable tests—not on an illustrative score alone.

Network Insight · Interactive Lab 07

Traffic Engineering Scenario Challenge

Can you deliver the traffic without overloading a link? Choose a strategy, change demand and capacity, then introduce a failure to test the outcome.

1. Configure the network
Traffic demand 120 Mbps
R1 → R2 → R4 100 Mbps
R1 → R3 → R4 80 Mbps
Scenario objective

Maximise delivered traffic, avoid exceeding available path capacity, and maintain a usable route after a failure. The best strategy depends on the demand and network conditions.

R1 Ingress R2 Upper R5 Upper R3 Lower R6 Lower R4 Destination UPPER PATH · illustrative delay 18 ms LOWER PATH · illustrative delay 32 ms
Upper path Lower path Unavailable or unused
Delivered traffic
120 Mbps
Unserved traffic
0 Mbps
Estimated path delay
18 ms
Traffic delivered
100%
2. Scenario result
Scenario ready

Run the scenario to evaluate the selected strategy against available path capacity.

Demand successfully delivered 100%
Upper: idle Lower: idle No failure
Engineering takeaway

Path choice is only one part of traffic engineering. Capacity, demand, failures and policy all influence the result.

Educational model only. Delay values are illustrative; this lab does not implement live routing, QoS queues, BGP, RSVP-TE or a production traffic controller.

Network Insight · Engineering Summary

Network Traffic Engineering: Key Takeaways

Network traffic engineering is the practice of directing, distributing and managing traffic to make effective use of network resources. It connects routing policy, link capacity, Quality of Service (QoS), traffic measurement and application requirements to improve performance, resilience and operational control.

The central challenge is not simply to find a path between two endpoints. Engineers must understand how traffic behaves under normal conditions, where congestion develops, what happens when links fail, and whether the chosen policy can deliver the required service.

What you should understand

01 · MEASURE
Traffic, congestion and QoS

Use throughput, utilisation, loss, latency and jitter to understand network conditions. QoS controls how traffic is classified, queued and treated; it does not automatically select a different route.

02 · STEER
Routing-based engineering

OSPF and IS-IS metrics, BGP policy, ECMP, policy-based routing and performance-aware routing mechanisms influence how traffic reaches its destination. Each operates within its own capabilities and constraints.

03 · CONSTRAIN
MPLS Traffic Engineering

Explicit paths, bandwidth constraints, RSVP-TE and fast reroute can provide more deliberate path control and protection than ordinary shortest-path forwarding alone.

04 · CONTROL
SDN and centralised decisions

Software-defined networking can use controller policies and network telemetry to coordinate forwarding decisions. OpenFlow is one possible southbound protocol, not a synonym for SDN itself.

05 · INTEGRATE
Cloud and application traffic

Cloud routing, load balancing, Kubernetes service selection and application-aware steering solve different problems. Good designs make their boundaries and health-check behaviour explicit.

06 · RESILIENCE
WANs, DMVPN and IPv6

WAN path selection, NHRP-supported shortcuts, failover design and IPv6 router preferences must be evaluated against actual topology, platform behaviour and operational requirements.

The engineering principle: the shortest path, the lowest-delay path and the least-congested path are not necessarily the same. Effective traffic engineering balances policy, available capacity, measured conditions and failure recovery.

A practical workflow for engineers

  1. Establish a baseline. Measure offered load, throughput, link utilisation, loss and latency.
  2. Identify the constraint. Determine whether the problem is congestion, path selection, capacity, QoS treatment or application behaviour.
  3. Choose the appropriate mechanism. Apply routing policy, constrained path engineering, load distribution, QoS or application-level controls where suitable.
  4. Test failure conditions. Simulate link loss, reduced capacity and traffic surges; verify that alternate paths can carry the required demand.
  5. Validate the outcome. Compare the result against measurable service objectives and confirm that the change has not created a new bottleneck.

Put the concepts into practice

Use the interactive Traffic Engineering Lab in this article to experiment with traffic demand, path capacity, routing strategies and link failures. Observe how the selected policy affects delivered traffic and where a capacity shortfall occurs.

Treat the lab as a learning model rather than a prediction of live network behaviour. Real deployments require platform-specific configuration, reliable telemetry, testing and operational safeguards.

Network Insight · Understand the traffic. Evaluate the paths. Validate the outcome.
```
☕
Support Network Insight
Help support independent engineering guides, interactive networking tools, and future learning labs.
Support Network Insight ```
application traffic steering

Application Traffic Steering

NETWORK ENGINEERING · APPLICATION AWARENESS

Application Traffic Steering: From Flow Awareness to Intelligent Path Selection

Modern networks must do more than discover a destination and forward packets toward it. They must support applications with different performance requirements, direct traffic across available paths, preserve security policy and respond when network conditions change. Application traffic steering brings these decisions together by matching traffic flows with the paths and services best suited to their requirements.

Voice traffic may require low latency and jitter. Video applications need sufficient bandwidth and stable delivery, while transactional services may depend on predictable response times and secure access. Sending every flow along the same path without considering these differences can waste capacity or degrade the user experience.

Traffic steering introduces an additional layer of decision-making. Depending on the architecture, the network can classify applications, evaluate path performance, apply routing policies, distribute requests across servers or direct selected flows through security services. The mechanisms differ, but the engineering objective is consistent: make forwarding and delivery decisions that align with application needs.

From application requirements to a steering decision

01 · CLASSIFY Identify the flow Determine the application, endpoints, protocol and relevant identity or policy context.
02 · EVALUATE Assess conditions Compare available paths, performance metrics, service health and policy requirements.
03 · SELECT Choose an action Apply the relevant routing, load-balancing or service-steering mechanism.
04 · VERIFY Check the outcome Confirm forwarding, service availability and observed application performance.
Conceptual application traffic steering model
Application Flow
→
Classification
→
Policy
→
Path / Service
→
Forwarding

Why traditional routing is not the whole answer

Traditional IP routing primarily selects a forwarding next hop using destination prefixes and the routing information available to the router. Routing protocols can respond to topology changes and select among alternative routes, but ordinary destination-based forwarding does not automatically distinguish every application sharing the same destination.

Application traffic steering can introduce additional classification, policy and performance inputs. SD-WAN systems may select between WAN paths using measured latency, jitter or loss. Load balancers distribute requests among backend servers. Policy-Based Routing can override normal routing decisions for matching traffic, while programmable SDN architectures can install more granular forwarding rules.

These approaches are related, but they are not interchangeable. A steering design must identify which device makes the decision, which information it can observe and which forwarding actions its platform supports.

BGP Application Traffic Steering

Border Gateway Protocol (BGP) provides an important foundation for traffic engineering between autonomous systems and across interconnected networks. By exchanging reachability information and applying routing policy, BGP allows network engineers to influence which advertised route is selected and how traffic enters or leaves a network.

BGP-based steering is not the same as an application-aware SD-WAN engine. BGP generally operates on network-layer reachability and path attributes, rather than independently measuring every application's real-time experience. However, carefully designed BGP policies can support application delivery objectives when traffic is separated into suitable prefixes or routing domains, or when BGP works alongside more granular steering mechanisms.

Dedicated BGP Learning Section
How BGP Influences Traffic Paths

Consider an enterprise network connected to two upstream providers. Both providers advertise reachability to a destination prefix. The enterprise can apply supported BGP policy to influence its preferred outbound route, while appropriately configured announcements and attributes can influence how remote networks select paths toward it.

Enterprise
→
Provider A
or
Provider B
→
Destination

The preferred path depends on routing policy, BGP attributes, reachability and the decision process at the relevant routers. Local preference can influence outbound path selection within an autonomous system; AS-path prepending may influence some remote networks' inbound route choices, but it is not a guarantee. BGP does not automatically select the lowest-latency application path.

BGP techniques explored in this article
Local preference Influence which eligible BGP route is preferred for outbound traffic within an autonomous system.
AS-path prepending Influence some remote networks' inbound route choices by advertising a longer AS path, subject to their policies.
More-specific prefixes Understand how prefix advertisements and longest-prefix matching can affect traffic destinations, within routing and operational constraints.
BGP Flow Specification Explore distribution of traffic-matching rules and supported actions for filtering or rate-limiting flows, subject to implementation and policy.

Performance and security must work together

A path that appears optimal from a latency or bandwidth perspective may still be unsuitable if it violates a security policy, traverses an unavailable service or fails a forwarding check. Effective steering therefore combines performance objectives with reachability, security controls and operational constraints.

This is especially important when BGP is part of the solution. A route can be valid and selected by BGP without guaranteeing that the application will achieve its required response time. Engineers must distinguish routing reachability from end-to-end application health.

Engineering principle

A routing decision determines where traffic can be forwarded. An application steering strategy determines which available path or service best satisfies the application's requirements, within the capabilities of the network and its configured policies.

What this learning journey covers

Path selection Understand application classification, path metrics, routing policies and steering decisions.
Load balancing Explore server selection, health checks and request distribution.
BGP traffic engineering Understand local preference, AS-path prepending, prefix selection and the limits of routing-based control.
Flow-level control Explore SDN, BGP Flow Specification, service insertion and policy-driven forwarding.
Interactive Learning · Application Traffic Steering
From Routing Policy to Steering Outcome

Continue through the article to examine how traffic is classified, how available paths are compared, how BGP policies influence route selection and how a steering decision can be tested against real forwarding and security constraints.

01 / Foundations

How Application Traffic Steering Works

Application traffic steering is the process of identifying a flow, evaluating its requirements and choosing an appropriate forwarding or application-handling decision. It brings policy into the path a request takes, rather than treating every flow as an identical destination lookup.

Start with the core model: classify traffic, evaluate policy, select an eligible path and verify the outcome. This foundation helps distinguish ordinary routing from policy-based routing, SD-WAN, load balancing and application-aware controls.

ClassifyEvaluateSelectVerify
Section 01 · Core Concepts

How Application Traffic Steering Works

Application traffic steering is the process of directing network traffic according to application requirements, network conditions and configured policy. Rather than treating every packet or connection identically, a steering system can identify relevant traffic, evaluate the available forwarding choices and apply an appropriate action.

The decision may happen at different points in the network. An edge router can apply Policy-Based Routing (PBR), an SD-WAN appliance can select a WAN path, a load balancer can choose a backend server, or a programmable network controller can install flow-specific forwarding rules. The mechanism depends on the problem being solved and the capabilities of the infrastructure.

The four stages of a steering decision

STAGE 01 Classify Identify the traffic using available information such as addresses, protocol, ports, application identity or policy tags.
→
STAGE 02 Evaluate Consider route availability, policy, link performance, destination health and service requirements.
→
STAGE 03 Select Choose an eligible next hop, WAN path, server or service chain according to the applicable rules.
→
STAGE 04 Forward and verify Apply the decision, then verify connectivity, service health and application performance.

What information can influence the decision?

Steering decisions are only as good as the information available to the component making them. Some mechanisms rely primarily on packet headers and routing policy. Others incorporate application recognition, active probes, telemetry, user identity or the health of destination services.

Traffic and policy context

Source and destination prefixes, transport protocol, ports, routing attributes, access rules and application classification can determine which policy applies to a flow.

Path and service conditions

Depending on the platform, measured latency, jitter, packet loss, bandwidth, link state and backend health can help determine which available path or service is suitable.

Important distinction: routing versus steering

Routing establishes reachability and selects routes according to the routing information and decision rules in use. Application traffic steering adds classification or policy objectives that influence how selected traffic is handled. A routing protocol does not automatically provide application awareness or real-time performance measurement.

Three common steering approaches

  • Policy-Based Routing: Matches defined traffic criteria and directs matching packets through a configured next hop or forwarding action, where supported.
  • SD-WAN path selection: Can use link measurements and application policies to choose between available WAN transports.
  • Load balancing: Distributes connections or requests across eligible servers or service endpoints, often using health checks and a configured selection algorithm.

BGP can also influence traffic paths by exchanging reachability and applying attributes and routing policy. For example, local preference can influence outbound route selection within an autonomous system, while AS-path prepending may affect some remote networks' inbound choices. These techniques operate at the routing-policy level and do not, by themselves, guarantee the lowest-latency path for a particular application.

Example: steering traffic away from a degraded link

Imagine a branch office with two WAN connections. Both links are available, but the primary connection begins experiencing increased packet loss. A steering system with suitable measurement and policy capabilities may direct eligible application traffic to the secondary connection. When the primary link meets the configured recovery conditions, the system may return traffic to it.

Illustrative decision sequence

Observe: The primary link's measured loss exceeds the configured threshold.
Evaluate: The secondary link is available and satisfies the applicable policy.
Steer: Eligible traffic is directed through the secondary link.
Verify: Monitoring confirms the forwarding change and checks whether application performance improves.

This is a conceptual example. Actual detection intervals, thresholds, failover behaviour and recovery rules depend on the implementation.

Design considerations

  • Define the objective. Decide whether the priority is availability, latency, loss, cost, security or a combination of factors.
  • Understand the control point. Identify which router, SD-WAN appliance, controller or load balancer can enforce the decision.
  • Check the return path. Asymmetric routing, stateful firewalls and session persistence can affect whether a change works correctly.
  • Validate the outcome. A selected route or link is not proof that application performance has improved; measure the result.
Key takeaway

Application traffic steering connects traffic classification, policy, path selection and verification. Understanding where each decision is made is the first step toward choosing the right mechanism, whether that is PBR, SD-WAN, load balancing, BGP policy or programmable flow-level control.

Network Insight / Application Traffic Steering Lab 01

Classify. Decide. Steer. Verify.

Follow an application flow through a simplified steering system. Change the policy to see how traffic classification, path selection and health checks influence the illustrative forwarding decision.
Ready
Traffic Decision Path
0 / 6
◉
APPLICATION
10.10.10.25
HTTPS request
◈
STEERING ENGINE
Classify + evaluate
⇢
PATH A
Preferred route
Awaiting traffic
Start the simulation to inspect the application flow.
Flow Classification
Illustrative metadata
Source10.10.10.25
Destination203.0.113.40
ApplicationHTTPS / Business
PriorityHigh
Decision stateNot evaluated
Available Paths
Sample telemetry
A
Path A · Premium WAN
Latency 24 ms · Cost high · Healthy
B
Path B · Broadband
Latency 38 ms · Cost low · Healthy
C
Path C · Backup link
Latency 71 ms · Cost medium · Healthy
Steering Timeline
Six decision stages
01
Ingress
The application flow enters the network.
02
Classify
The system identifies the flow using available metadata and policy.
03
Evaluate
The selected policy compares eligible paths and their relevant metrics.
04
Select
A path is chosen according to the current steering policy.
05
Forward
The flow is forwarded through the selected path.
06
Verify
The system checks the outcome and can reconsider the path if conditions change.
Decision Telemetry
Live interpretation
Current Event
Press Step Forward to begin
Observe how the steering process moves from classification to forwarding.
Simulation Progress
Engineering takeaway: traffic steering is a policy decision process. The best path depends on the application requirements, available measurements and configured rules.
02 / Policy and Classification

Policy-Based Routing: Classifying Traffic and Choosing a Path

Policy-Based Routing (PBR) allows selected traffic to follow a policy-defined forwarding decision rather than relying exclusively on the normal destination-based route lookup. Rules may match supported attributes such as source address, destination address, protocol or transport ports.

PBR is useful when different traffic classes need different next hops or handling. Its effectiveness depends on correct match conditions, reachable next hops, suitable fallback behaviour and careful validation of both forward and return traffic.

Match conditionsPolicy rulesNext-hop choiceFallback behaviour
Section 02 · Traffic Policy

Policy-Based Routing: Classifying Traffic and Choosing a Path

Policy-Based Routing (PBR) allows a network device to make forwarding decisions using configured traffic-matching rules rather than relying exclusively on the destination-based route lookup. It can direct selected traffic toward a particular next hop or interface when the platform, policy and forwarding design support that action.

PBR is useful when different traffic classes need different treatment. For example, an organisation might direct traffic from a particular department through a security appliance, send selected application traffic over a dedicated WAN connection, or route traffic from a specific subnet toward a service network.

How a PBR decision is made

01 · MATCH Identify traffic Compare packet attributes against configured match criteria.
→
02 · APPLY Evaluate policy Determine whether a routing policy applies to the packet.
→
03 · SELECT Choose forwarding Use the configured next hop, interface or supported action.
→
04 · CHECK Verify delivery Confirm reachability and check that the chosen path works as intended.

What can a policy match?

The exact matching options depend on the vendor and platform. Common implementations use access control lists or equivalent classifiers to identify traffic using network and transport-layer fields.

Network layer
Source and destination

Match source or destination IP prefixes to apply different forwarding policies to users, subnets or destination networks.

Transport layer
Protocol and ports

Where supported, distinguish traffic by protocol and port, such as selected TCP or UDP flows.

Policy context
Traffic classes

Use configured classifiers, markings or other supported criteria to associate traffic with a forwarding policy.

Operational context
Next-hop availability

Use platform-supported tracking or failover mechanisms where available so a policy does not blindly depend on an unusable next hop.

Example: sending selected traffic through a preferred path

Consider a branch router connected to two upstream paths. A defined traffic class should use the preferred path, while other traffic continues to use the normal routing table. PBR can implement this separation when the router supports the required matching and forwarding actions.

Illustrative forwarding policy
Traffic received by branch router | v Match configured source / destination / protocol criteria | +-- Match --> Apply policy-selected next hop | +-- No match --> Use normal destination-based routing

This is a conceptual flow, not vendor-specific configuration. The actual processing order, supported actions and fallback behaviour must be confirmed for the router and software release in use.

PBR versus ordinary destination-based routing

Destination-based routing

The device normally consults its forwarding information to select the best matching destination prefix and corresponding next hop. The result is primarily determined by destination reachability and the routing information installed in the forwarding table.

Policy-Based Routing

Matching traffic can receive a policy-defined forwarding treatment that differs from the normal destination-based choice. Traffic that does not match the policy generally follows the platform's configured normal routing behaviour.

Important operational distinction

PBR does not automatically discover the best-performing path. A configured policy may select a next hop even when that path is congested or unavailable unless suitable tracking, failover and verification mechanisms are configured.

Where PBR fits in application traffic steering

PBR is particularly useful when the steering requirement can be expressed as a clear rule and enforced at a suitable network device. It can provide deterministic traffic handling, but it is not inherently equivalent to deep application recognition or continuous performance-aware path selection.

  • Use PBR when defined traffic matches must use a particular supported forwarding path.
  • Consider SD-WAN when path decisions need to incorporate measured WAN performance and application policies.
  • Consider load balancing when the decision is which backend server or service endpoint should receive a request.
  • Consider BGP policy when the objective is to influence route selection and reachability across BGP-controlled networks.
Key takeaway

PBR turns a traffic-matching rule into a forwarding decision. Successful deployment requires precise match criteria, a valid next hop, a defined fallback strategy and operational checks that confirm traffic reaches its intended destination.

Network Insight / Application Traffic Steering Lab 02

Policy-Based Routing: Match the Flow, Choose the Path

Explore how a router can use configured policy to steer selected traffic toward a particular next hop instead of relying solely on the ordinary destination-based routing decision.
Ready
Policy Decision Topology
0 / 6
◉
BUSINESS LAN
10.10.10.0/24
◇
EDGE ROUTER
PBR policy
⇢
WAN A
192.0.2.1
WAN A · Primary
Next hop 192.0.2.1
Preferred for selected classes
WAN B · Alternate
Next hop 198.51.100.1
Alternate policy path
Key concept: PBR matches traffic against configured criteria and applies a policy action, such as setting a next hop. Exact match fields and actions depend on the router platform and configuration.
Matched Traffic
Example packet
Source subnet10.10.10.0/24
Destination203.0.113.80
Traffic classBusiness
Policy matchAwaiting inspection
Policy actionNot applied
Selected next hopNot selected
Illustrative Policy Rules
First matching rule
Rule 10 · Real-time
HIGH PRIORITY
Voice traffic → WAN A, when the policy match succeeds.
Rule 20 · Business
BUSINESS
Business application traffic → WAN A.
Rule 30 · Bulk
COST AWARE
Bulk transfer traffic → WAN B.
Default
FALLBACK
Unmatched traffic follows the ordinary routing decision in this model.
Packet Processing Timeline
Match → action → forwarding
01
Ingress
A packet arrives at the router from the selected source network.
02
Classify
The packet is checked against the configured policy match criteria.
03
Match
A rule matches the illustrative traffic class, or the packet uses the fallback behaviour.
04
Action
The policy selects a next hop for traffic matching the rule.
05
Forward
The router forwards the packet toward the selected next hop, if the action can be applied.
06
Verify
The outcome is checked conceptually; real forwarding and failover depend on platform behaviour and configuration.
PBR Lab Telemetry
Live interpretation
Current Event
Press Step Forward to begin
Select a traffic class and step through the policy decision.
Simulation Progress
Policy Result
No decision yet
The selected rule and next hop will appear as the simulation advances.
03 / Performance and Path Quality

SD-WAN and Performance-Based Path Selection

SD-WAN can combine centralised policy with measurements from available network paths. Depending on the platform, information such as latency, jitter, packet loss and link health can help determine whether a path is suitable for a particular application or traffic class.

The key difference from conventional routing is the use of application requirements and path-quality information in steering decisions. Performance-based steering still needs thresholds, failover rules and recovery logic to avoid unstable path changes.

LatencyJitterPacket lossFailover and recovery
Section 03 · Performance-Aware Networking

SD-WAN and Performance-Based Path Selection

Software-Defined Wide Area Networking (SD-WAN) can extend traffic steering beyond static path preferences by combining application policies with information about available WAN connections. Depending on the implementation, an SD-WAN edge can evaluate link measurements, identify application traffic and select an eligible path according to configured service requirements.

A branch office might have broadband, business fibre and an MPLS connection. These links can differ in cost, capacity, latency and reliability. Instead of treating one connection as universally best, an SD-WAN policy can determine which transport is suitable for each traffic class and respond when conditions change.

Which measurements matter?

Responsiveness
Latency

Measures the time taken for traffic to travel between measurement points. Lower latency can benefit interactive applications such as voice, remote desktops and transactional systems.

Consistency
Jitter

Describes variation in packet delay. Unstable delay can affect real-time audio and video even when average latency appears acceptable.

Reliability
Packet loss

Indicates packets that fail to reach the measurement destination. Loss can degrade voice and video and trigger retransmissions for applications using reliable transport protocols.

Capacity
Available bandwidth

Helps determine whether a path can support the expected traffic demand. Capacity estimates must be interpreted alongside congestion, shaping and competing traffic.

From telemetry to a forwarding action

01 · MEASURE Monitor links Collect supported path metrics using probes or other telemetry.
→
02 · CLASSIFY Identify traffic Associate traffic with an application or configured policy class.
→
03 · COMPARE Check requirements Compare eligible paths against policy thresholds and preferences.
→
04 · STEER Select a path Apply the configured path choice and continue monitoring conditions.

Example: choosing between two WAN paths

Imagine that a branch uses two WAN transports. The primary link normally carries voice and business application traffic, but its measured loss increases. The secondary link remains within the policy's acceptable performance limits. An SD-WAN implementation may steer the affected application traffic to the secondary path, provided the configured policy and platform support that behaviour.

Illustrative path comparison
WAN Path A · Primary
Loss above policy threshold

The connection is still reachable, but its measured quality no longer satisfies the application's configured requirements.

WAN Path B · Alternative
Within policy limits

The alternative connection is eligible for the affected traffic, so the steering policy may prefer it until conditions change.

The key point is that link availability and link suitability are different questions. A link can remain operational while its measured performance falls outside the requirements of a particular application.

No specific latency, jitter or loss values are assumed here. Thresholds and failover behaviour are implementation- and policy-dependent.

Different applications need different policies

Voice and real-time collaboration

Prioritise acceptable latency, jitter and loss. A high-capacity path may still be unsuitable if delay variation is excessive.

Bulk transfers and backups

Consider available capacity, transfer duration and cost. These applications may tolerate more delay than interactive services.

Business-critical applications

Define acceptable performance and availability requirements, with clear rules for alternate paths and recovery.

Guest and general internet traffic

Apply appropriate access, capacity and cost policies without automatically giving every flow the same path preference.

Failover is only part of the design

Steering traffic away from a degraded connection is useful, but the policy must also define what happens when the preferred path recovers. Without suitable thresholds, hold-down periods or other stability controls, repeated changes can cause unnecessary path switching. The precise controls available depend on the platform.

  • Define thresholds: Specify which measured conditions make a path acceptable or unsuitable.
  • Plan recovery: Determine when traffic should return to the preferred path after performance improves.
  • Check capacity: Ensure the alternate path can handle the traffic it may receive during degradation or failure.
  • Verify application health: Confirm that the path change actually improves the user experience.
SD-WAN and BGP solve different parts of the problem

SD-WAN can make policy-driven path choices using application classification and measured transport performance. BGP exchanges reachability and applies routing policy to select routes. They can complement each other, but BGP alone does not provide the same application-level measurement and steering behaviour as a performance-aware SD-WAN system.

Key takeaway

Performance-based steering connects path measurement to application policy. It can help networks respond to changing WAN conditions, but effective deployment requires realistic thresholds, stable failover behaviour, sufficient backup capacity and end-to-end verification.

Network Insight · Interactive Lab 03

SD-WAN Performance-Based Path Selection

Watch an application flow get matched to a policy, evaluated against live link conditions, and forwarded over a selected WAN path.

Ready to evaluate
01 / Overlay and underlay view
Phase 0 of 5
▦
Branch LAN Application flow
→
◇
SD-WAN Edge Policy engine
→
◎
Cloud / DC Destination
Logical overlay: the edge selects an eligible transport path based on policy and measured conditions.
02 / WAN underlay telemetry
Illustrative measurements
Awaiting traffic classification

Choose an application profile, then step through the path-selection process.

04 / Decision sequence
Step-by-step
1
Classify the applicationIdentify the traffic profile and its requirements.
2
Measure link conditionsCompare latency, loss, jitter and availability.
3
Evaluate policy and SLACheck which paths satisfy the selected policy.
4
Select the transportChoose the best eligible WAN path.
5
Forward and verifyShow the chosen path and simulated outcome.
05 / Event timeline
0 events
Lab initialized
Select an application and step forward to begin.
Engineering note: This is an illustrative policy model, not a live SD-WAN controller. Real products differ in their SLA probes, thresholds, path scoring, failover timers, hysteresis and load-sharing behaviour. A policy may prefer a path only while that path remains eligible; if no path satisfies the policy, the result depends on the configured fallback behaviour.
04 / Application Delivery

Load Balancing: Steering Requests to Healthy Services

Load balancing distributes incoming requests or connections across a group of service instances. Instead of sending every request to one endpoint, a load balancer can select a backend according to its configured algorithm, health status and other supported criteria.

Layer 4 load balancing generally uses transport-level connection information, while Layer 7 balancing can make decisions using application protocol details. Both can improve availability and resource utilisation, but neither removes the need for health checks, capacity planning and session-handling decisions.

Backend selection Health checks Layer 4 and Layer 7 Session persistence
Section 04 · Application Delivery

Load Balancing: Steering Requests to Healthy Services

Load balancing distributes client connections or application requests across multiple servers or service endpoints. Rather than allowing every request to depend on a single backend, a load balancer selects an eligible destination according to its configured algorithm, health information and any applicable session or routing policy.

This is a different steering problem from selecting a WAN path or choosing a BGP route. Load balancing focuses on where a request or connection should be delivered within an application service. It can improve capacity utilisation and availability, but the result depends on how backend health, session state and application behaviour are handled.

A typical application delivery architecture

Client-to-service request flow
Client / Application User
↓
Load Balancer · Selects an Eligible Backend
↓
Application Server A Backend endpoint
Application Server B Backend endpoint
Application Server C Backend endpoint

The load balancer receives a request or connection, applies its selection logic and directs it to a backend that is eligible to serve the traffic. The exact forwarding model depends on whether the implementation operates at Layer 4, Layer 7 or another supported service-delivery layer.

Layer 4 and Layer 7 load balancing

Transport-aware
Layer 4 load balancing

Uses transport and network connection information, commonly including IP addresses, protocol and TCP or UDP ports. It can distribute connections without needing to interpret the full application request.

Application-aware
Layer 7 load balancing

Can make decisions using application-layer information such as HTTP hostnames, URL paths, headers or other supported request attributes. This enables more granular application delivery policies.

Layer 7 visibility can support more detailed routing decisions, but it introduces additional considerations, including TLS termination, certificate handling, request parsing and the privacy of application data. The chosen design should match the requirements of the service.

Common backend selection methods

Round robin

Distributes new selections sequentially across eligible backend servers. It is simple, but does not inherently account for different server capacities or current workloads.

Weighted distribution

Assigns different selection weights to backends. A server with a higher configured weight can receive a larger share of selections, depending on the algorithm.

Least connections

Selects a backend based on its active connection count, where supported. This can help distribute connection load but may not accurately represent the processing cost of every request.

Hash-based selection

Uses a key such as a client address or request attribute to select a backend. Depending on the method, this can help maintain consistency for related requests.

Health checks: avoid sending traffic to failed backends

A backend can remain reachable at the IP layer while its application is unable to serve requests correctly. Load balancers therefore commonly use health checks to determine whether a destination should remain in the eligible backend pool.

  • Connectivity checks: Verify that a supported network or transport endpoint responds.
  • Application checks: Request a health endpoint or test a service-specific condition when configured.
  • Pool membership: Remove unhealthy destinations from new selections and restore them according to the configured recovery rules.
  • Capacity awareness: Consider whether the remaining healthy servers can handle the additional traffic.
Health does not always mean application success

A successful health check confirms only the conditions that it actually tests. A basic TCP check may pass while a database dependency, login workflow or critical application function is failing. Health checks should be designed to reflect the service's real operational needs.

Session persistence and state

Some applications store session state locally on a particular server. If successive requests from the same user are sent to different backends, the application may lose access to that state unless the architecture supports shared sessions or another state-management mechanism.

Session persistence, sometimes called stickiness, can help keep related requests associated with a backend. However, it can also create uneven load distribution or reduce flexibility during a failure. Shared session storage and stateless application design can reduce dependence on persistent backend selection.

Load balancing versus network traffic steering

Network path steering

Chooses how traffic traverses the network, for example by selecting a WAN transport, applying PBR or influencing route selection through BGP policy.

Application load balancing

Chooses which eligible server or service endpoint receives a request or connection. It operates at the application delivery layer rather than simply selecting an IP route.

These mechanisms can work together. Routing and SD-WAN determine how traffic reaches the application delivery infrastructure, while the load balancer selects a backend. A successful end-to-end design needs both layers to be reachable and correctly configured.

Design checks before deployment

  • Capacity: Confirm that the load balancer and healthy backends can support expected traffic and failure scenarios.
  • Protocol behaviour: Check TLS termination, connection reuse, timeouts and supported application protocols.
  • Failure handling: Define how unhealthy backends are detected, excluded and returned to service.
  • Observability: Monitor backend health, request errors, response times and distribution across the server pool.
Key takeaway

Load balancing steers requests or connections across eligible application backends. Effective application delivery combines an appropriate selection algorithm, meaningful health checks, session-state planning and monitoring. It complements network-level steering but solves a different part of the delivery problem.

Network Insight · Interactive Lab 04

Load Balancing and Application Delivery

Send application requests through a load balancer, observe server selection, and test how health checks change traffic distribution.

Ready for requests
01 / Application delivery path
0 requests processed
▦
Clients HTTPS requests
→
⇄
Load Balancer Round robin
→
▣
Application Server pool
APP-01HEALTHY
Load0%
Requests0
APP-02HEALTHY
Load0%
Requests0
APP-03HEALTHY
Load0%
Requests0
Green border = server selected for the latest request. Red status = unavailable and excluded from new selections.
02 / Pool statistics
Current simulation
Total requests0
Successful0
Failed / rejected0
Awaiting first request

Select a balancing algorithm, then send a request to see which healthy server receives it.

04 / Request processing
Illustrative sequence
1
Receive requestA client sends an application request to the service endpoint.
2
Check server healthOnly eligible pool members can receive new traffic.
3
Apply balancing policyThe configured algorithm selects a server.
4
Forward requestThe load balancer sends the request to the selected server.
5
Record outcomeThe simulation updates request counts and pool load.
05 / Event timeline
0 events
Lab initialized
Ready to simulate application requests.
Engineering note: This is a simplified application-delivery model. Real load balancers may use connection counts, response times, weights, cookies, source affinity, consistent hashing, health-check thresholds and draining behaviour. A health check does not guarantee that every application transaction will succeed, and persistence rules can affect distribution even when multiple servers are healthy.
05 / Programmable Networking

SDN, OpenFlow and Flow-Level Traffic Steering

Software-Defined Networking introduces programmable approaches to network control. In compatible architectures, a controller can coordinate forwarding policies and install rules that classify selected packets and specify how those packets should be processed.

OpenFlow is one example of a protocol used to manage flow-table entries on supported switches. This section explores match/action logic, rule priorities and installation strategies, along with the operational checks needed to ensure that programmed forwarding matches the intended policy.

Control plane Flow tables Match/action rules Programmable paths
Section 05 · Programmable Networking

SDN, OpenFlow and Flow-Level Traffic Steering

Software-Defined Networking (SDN) introduces a programmable approach to network control. Instead of configuring every forwarding decision only through individual device interfaces, an SDN architecture can use a controller or network application to define policies and coordinate forwarding behaviour across supported network devices.

This approach can support more granular steering than conventional destination-based routing alone. Depending on the platform and forwarding technology, traffic can be classified using fields such as source and destination addresses, protocol and transport ports, then handled using rules that specify the permitted forwarding actions.

Separating network control from packet forwarding

Control plane
Controller and policy logic

Computes or coordinates forwarding policies, maintains a view of relevant network state and communicates supported rules to network devices through the applicable control interface.

Data plane
Switches and forwarding devices

Processes packets using installed forwarding entries, match criteria and supported actions. The device performs the actual packet handling at forwarding time.

The separation is conceptual rather than absolute. Real networks still require mechanisms for topology discovery, reachability, failure handling, rule installation and coordination between control and forwarding components. SDN platforms differ in how they implement these functions.

How a programmable steering rule is applied

01 · IDENTIFY Classify the flow Determine which packet fields or traffic conditions match the policy.
→
02 · COMPUTE Determine the action Apply controller logic, topology information and policy constraints.
→
03 · INSTALL Program forwarding Install or update a supported rule on the relevant forwarding device.
→
04 · PROCESS Handle packets Match packets against the installed rules and execute the configured action.

OpenFlow and match/action forwarding

OpenFlow is a protocol historically associated with SDN that allows a controller to communicate with compatible switches and manage supported flow-table entries. An entry can contain match fields, priority, counters and instructions or actions that determine how matching packets are processed.

Depending on the OpenFlow version and switch capabilities, actions may include forwarding to a port, dropping a packet, modifying supported header fields or directing processing to another table. The precise capabilities are version- and implementation-dependent.

Conceptual flow-table entry
MATCH Source: 10.10.10.0/24 Destination: 198.51.100.20 Protocol: TCP Port: 443 ACTION Forward using the configured permitted output path

This is an illustrative rule, not executable OpenFlow syntax. It shows how selected traffic can be distinguished from other packets and associated with a forwarding action supported by the device.

The example assumes the platform supports the specified match fields and a valid forwarding action. A production rule also needs suitable priority, table behaviour and lifecycle management.

Why rule priority and table processing matter

A programmable switch may contain many flow entries. Multiple entries can potentially match the same packet, so priority and table-processing rules determine which entry applies and how processing continues. Broad rules can unintentionally override more specific policies if they are installed with inappropriate priorities or instructions.

  • Specificity: Ensure that intended traffic matches the correct entry rather than an unrelated broad rule.
  • Priority: Use a deliberate priority strategy for overlapping match conditions.
  • Fallback: Define the intended behaviour when no specific entry matches.
  • Lifecycle: Consider timeouts, stale entries, updates and cleanup when policies change.

Reactive and proactive rule installation

Reactive approach

A device or controller interaction triggered by traffic can lead to a rule being installed after the relevant flow is first encountered. This can provide flexibility but may introduce initial setup delay and control-plane workload.

Proactive approach

Rules are installed before the associated traffic arrives. This can reduce first-packet setup delays, provided the required policies, topology information and forwarding entries are already available.

Where programmable flow steering is useful

Traffic isolation

Apply distinct forwarding policies to selected traffic classes or network segments, subject to the platform's match and action support.

Service insertion

Direct eligible traffic through a firewall, inspection system or other service before it reaches its destination.

Path engineering

Select a supported forwarding path based on controller policy and network state, rather than relying solely on the normal forwarding choice for the destination.

Policy experimentation

Test traffic classification and forwarding changes in a controlled lab before considering a production deployment.

Programmability does not remove operational constraints

A controller can only install actions supported by the target devices, and the resulting path must still be valid. Rule conflicts, stale state, control-channel failures and incomplete topology information can affect traffic delivery. Validate both the controller's policy and the forwarding behaviour of the devices.

SDN flow rules versus BGP policy

BGP primarily exchanges reachability information and applies routing attributes and policy to select routes. Programmable flow steering can operate at a finer granularity when the forwarding platform supports the required packet matches and actions.

The two approaches can coexist. BGP can provide reachability between routing domains, while an SDN-controlled data plane applies more specific forwarding rules within a network. Their responsibilities should be clearly separated to avoid conflicting decisions or unexpected forwarding behaviour.

Engineering checks

  • Device compatibility: Confirm supported protocols, match fields, actions, table capacity and controller integration.
  • Failure behaviour: Decide what happens when the controller or its communication channel becomes unavailable.
  • Rule consistency: Validate policy updates and ensure that partially installed rules do not create unintended traffic paths.
  • Security: Restrict controller access and protect the interfaces used to program forwarding behaviour.
  • Observability: Inspect flow counters, device state, packet paths and application outcomes.
Key takeaway

SDN and OpenFlow illustrate how programmable forwarding can turn centrally defined policy into flow-level actions. The benefits depend on device support, sound rule design, reliable control mechanisms and verification that the installed forwarding behaviour matches the intended policy.

Network Insight · Interactive Lab 05

SDN, OpenFlow and Flow-Level Steering

Install a flow rule, send a packet through a programmable switch, and inspect how match fields determine the forwarding action.

Controller ready
01 / SDN forwarding topology
0 packets processed
▦
Traffic Source Packet ingress
→
▤
SDN Switch Flow table lookup
→
◎
Destination Output port
Port 1 · Web Web application service READY
Port 2 · Voice Real-time traffic service READY
Port 3 · Default General forwarding path READY
02 / Installed flow table
2 rules installed
PriorityMatch fieldsActionPacketsState
200UDP · DSCP EFOutput: Port 20Installed
100TCP · Destination 443Output: Port 10Installed
Ready for packet inspection

Choose a packet profile and send a test packet. The switch checks installed rules in priority order.

04 / Packet processing sequence
Waiting for packet
1
Receive packetThe switch receives a packet on an ingress port.
2
Inspect match fieldsCompare protocol, destination port and DSCP against flow entries.
3
Choose highest-priority matchWhen multiple entries match, priority determines the selected entry.
4
Execute actionForward to an output port or drop the packet.
5
Update flow statisticsRecord the outcome in the simulated flow table.
05 / Controller and switch events
0 events
Controller initialized
Default demonstration rules are available.
Engineering note: This is a conceptual OpenFlow-style flow-table model, not a live SDN controller or protocol implementation. Real flow entries may match additional fields, include cookies and timeouts, use groups or meters, and trigger controller processing on a table miss. This lab represents a table miss as a drop unless a matching default rule is installed.
06 / Service-Aware Networking

Service Insertion and Service Function Chaining

Some application flows need to pass through security or inspection functions before reaching their destination. Service insertion directs selected traffic through a required service, while Service Function Chaining defines a logical sequence of functions for a particular traffic class or service.

Building a reliable chain involves more than drawing a path through appliances. Engineers must consider service health, return-path behaviour, capacity, latency, failure handling and the policy requirements that determine which traffic must traverse each function.

Firewall Inspection Service sequence Failure handling
Section 06 · Service-Aware Networking

Service Insertion and Service Function Chaining

Application traffic does not always travel directly from source to destination. Some flows must pass through security, inspection or optimisation services before they reach their target. Service insertion steers selected traffic through these functions, while Service Function Chaining (SFC) defines an intended sequence of functions for a traffic class or service.

For example, traffic entering an enterprise application may need to pass through a firewall, an intrusion prevention system and a traffic monitor. The steering system must identify the relevant traffic, select the required service path and preserve the intended forwarding behaviour throughout the chain.

What is a service function chain?

Client Application request
→
Firewall Enforce security policy
→
Inspection Inspect eligible traffic
→
Monitor Observe traffic behaviour
→
Application Receive the request

This diagram illustrates one possible chain. A real deployment may use different functions, may bypass selected services for certain traffic classes, and must account for return traffic and the capabilities of the services and forwarding infrastructure.

Common service functions

Security
Firewall

Applies access-control policy to permit or deny traffic according to defined rules and connection state.

Threat detection
Intrusion prevention

Examines eligible traffic for suspicious patterns or known threats and applies configured prevention actions.

Application delivery
Proxy or gateway

Mediates selected application connections, potentially enforcing application policy or providing protocol-aware processing.

Visibility
Traffic monitoring

Collects or analyses traffic information for troubleshooting, performance measurement and operational visibility.

How service-aware steering works

From application policy to forwarding path
1. CLASSIFY Identify the traffic class and applicable policy. 2. SELECT Determine which service functions are required. 3. STEER Direct traffic to the selected service path. 4. PROCESS Allow each service to perform its intended function. 5. FORWARD Continue toward the destination after the required processing. 6. VERIFY Confirm delivery, service health and expected policy behaviour.

This is a conceptual workflow rather than a protocol-specific implementation. The exact sequence depends on the network architecture, steering mechanism and service-chain design.

Policy-based service selection

Not every application flow needs the same treatment. A steering policy can associate traffic classes with different service requirements. The classification method may use network-layer fields, transport-layer information, application identity or metadata supplied by a trusted policy system, depending on the platform.

Corporate application traffic

Send eligible traffic through firewall inspection before forwarding it to an internal application.

Guest network traffic

Apply a separate access policy and direct traffic through the appropriate security controls.

Sensitive data flows

Require additional inspection or monitoring where the policy and applicable privacy requirements permit it.

Low-risk internal flows

Use a shorter approved path when policy allows, avoiding unnecessary service processing and additional latency.

A shorter path is not automatically a better path

Bypassing a service can reduce latency and processing overhead, but it may also remove a required security or compliance control. Steering decisions must respect the intended service policy, not simply choose the route with the fewest hops.

Ways to implement service insertion

Network policy
Policy-based routing

Match selected traffic and direct it toward a service next hop or inspection path. The design must account for routing reachability, next-hop availability and return traffic.

Programmable forwarding
SDN and flow rules

Use controller-managed forwarding rules to steer supported traffic through selected service points, subject to device capabilities.

Service-chain architecture
Service Function Chaining

Define a logical sequence of service functions and use a compatible forwarding architecture to guide traffic through that sequence.

Application delivery
Proxy or load balancer

Insert an application-aware intermediary that can enforce policy, inspect supported protocols or select an appropriate backend.

Operational challenges to design for

  • Service availability: Define what happens if a required firewall or inspection service becomes unavailable. Fail-open and fail-closed behaviour have different security and availability consequences.
  • Return-path symmetry: Stateful services may require both directions of a connection to traverse the same service instance or a coordinated cluster.
  • Capacity and latency: Each service adds processing overhead and may become a bottleneck. Estimate aggregate throughput, connection scale and expected delay.
  • Loop prevention: Ensure that traffic cannot repeatedly re-enter the same service chain because of incorrect forwarding rules.
  • Encapsulation and MTU: If the architecture adds encapsulation, validate path MTU and account for the extra headers.
  • Policy consistency: Make sure changes to classification or chain definitions are reflected safely across the relevant devices.

Example: investigating an application delay

Scenario

Users report that an internal application has become slow. The network path includes a firewall, an inspection service and the application gateway.

Observed: Client → Firewall → Inspection → Gateway → Application Investigate: 1. Compare latency before and after each service. 2. Check service health, CPU and connection capacity. 3. Confirm that the flow matches the intended policy. 4. Verify forward and return paths. 5. Test any approved policy change in a controlled scope.

The aim is to identify which part of the chain contributes to the delay. Removing a service without confirming its security role is not a sound troubleshooting shortcut.

Service chaining versus ordinary routing

Ordinary routing generally selects a next hop toward a destination according to the routing table and associated policy. Service chaining adds another requirement: eligible traffic must visit specified functions before continuing toward its destination.

BGP can provide reachability to service networks or destinations, but BGP alone does not define a complete application service chain. Additional policy, forwarding rules or service-chain mechanisms are needed to enforce the required sequence.

Key takeaway

Service insertion makes traffic steering aware of the network services a flow must traverse. A successful design combines correct classification, a deliberate service sequence, reliable forwarding, health handling and verification that security and application requirements remain satisfied.

Network Insight · Interactive Lab 06

Service Insertion and Service Function Chaining

Steer application traffic through a defined sequence of security and visibility services before it reaches the destination.

Chain ready
01 / Service function chain
Stage 0 of 5
▦
Application Incoming traffic
→
⬡
Firewall Policy inspection
→
⌕
IPS Threat inspection
→
◉
Monitor Visibility / telemetry
→
◎
Destination Application service
Illustrative chain: application traffic is directed through selected service functions in sequence. A failed mandatory service can stop the flow.
02 / Chain telemetry
Current simulated flow
Stages completed0 / 5
Added delay0 ms
Flow outcomePending
Awaiting traffic

Select a chain profile and process the flow one stage at a time, or run the complete chain.

04 / Processing sequence
Waiting for flow
1
Classify trafficIdentify the application and applicable chain policy.
2
Insert service pathDetermine the required service functions and order.
3
Inspect at each serviceApply firewall, IPS and visibility processing.
4
Handle failure or threatContinue, bypass or stop according to the demonstration policy.
5
Deliver or blockRecord the final outcome for the application flow.
05 / Service event timeline
0 events
Chain initialized
Ready to process an application flow.
Engineering note: This is a conceptual service-function-chaining model. Real deployments can use service-function forwarders, overlays, metadata, policy classifiers and platform-specific steering mechanisms. Bypass, fail-open and fail-closed behaviour depends on service criticality and the configured operational policy; this lab uses a simplified mandatory-versus-optional control.
07 / Identity and Application Policy

Identity-Aware Traffic Steering

Traffic decisions can use more than IP addresses and ports. An application may also evaluate authenticated user identity, workload identity, roles and trusted policy signals to determine which resources or services a request is permitted to access.

This section connects application-level policy to traffic handling through a Node.js example. It also explains the boundary between choosing an application backend and changing the network forwarding path, plus the validation and enforcement needed to make identity-aware decisions secure.

Authentication Authorisation Node.js example Policy enforcement
Section 07 · Identity and Application Policy

Identity-Aware Traffic Steering

Traditional network policies commonly classify traffic using addresses, protocols, ports and other packet attributes. Modern application architectures can add another dimension: identity. An application may use authenticated user identity, workload identity or a trusted policy decision to determine which service, resource or application path a request is allowed to access.

Identity-aware steering connects application context to policy enforcement. For example, a request from an authorised employee might be directed to an internal application service, while a request without the required permissions is denied or sent through an additional verification step.

An important distinction

Identity-aware application routing is not automatically the same as network-layer path selection. An application gateway may choose a backend or reject a request without changing the underlying IP route. Network forwarding changes require a compatible network policy or steering mechanism.

From identity to an application decision

01 · AUTHENTICATE Establish identity Verify the user, workload or client through an appropriate identity system.
→
02 · AUTHORISE Evaluate permissions Check roles, claims and access policy for the requested resource.
→
03 · SELECT Choose the outcome Permit, deny, require another check or select an approved application service.
→
04 · VERIFY Enforce and log Apply the decision and record the outcome without exposing sensitive data.

What information can inform steering?

User context
Authenticated identity

A verified user identity or group membership can help determine whether a request is permitted to access a protected application.

Workload context
Service identity

A service-to-service request can be evaluated using the identity of the calling workload, rather than trusting its IP address alone.

Request context
Resource and operation

The requested resource and operation can determine which application handler, backend or access policy should apply.

Risk and policy
Trusted policy signals

A trusted access system may provide policy outcomes based on approved context, subject to the organisation's security design.

Example: a Node.js application gateway

Consider a Node.js service that receives an authenticated request and determines which application endpoint the caller may use. The application should verify the authentication evidence and then make an explicit authorisation decision. It should not treat a client-supplied role, username or HTTP header as proof of identity.

Illustrative policy logic
Incoming request | v Verify authentication token | v Check token issuer, audience, expiry and signature | v Evaluate required permission | +---- Not authorised ----> Reject request | +---- Authorised --------> Select permitted service | v Log outcome

The diagram describes a control flow rather than a complete, production-ready authentication implementation. Token verification must use a trusted identity configuration and suitable libraries.

Illustrative Node.js decision function

The following small example demonstrates the policy decision after authentication has already been performed by a trusted middleware or identity integration. It is not a substitute for verifying credentials.

function selectApplicationService(principal) { if (!principal || !Array.isArray(principal.roles)) { return { allowed: false, reason: "missing_identity" }; } if (principal.roles.includes("operations")) { return { allowed: true, service: "operations-api" }; } if (principal.roles.includes("employee")) { return { allowed: true, service: "employee-portal" }; } return { allowed: false, reason: "insufficient_permission" }; }

In this example, the function receives a principal object created by trusted authentication middleware. It checks an allowlisted set of roles and returns a service selection or denial. A real application must also enforce the returned decision, validate the principal's provenance and apply resource-specific authorisation.

Do not confuse selection with enforcement

Returning a service name does not itself secure a request. The application must ensure that the selected service is actually used, that unauthorised callers cannot bypass the gateway and that each downstream service applies its own required access controls.

Application steering versus network steering

Application layer
Select a backend or endpoint

A gateway or application can direct a permitted request to a service, API version or backend pool. The underlying network still forwards packets according to its own routing and forwarding rules.

Network layer
Select a forwarding path

A network policy, SDN controller or compatible forwarding system changes how eligible packets traverse the network. It needs an appropriate way to map trusted identity or policy context to traffic.

How identity can connect to network policy

In a larger architecture, an identity-aware application or policy service may communicate a decision to an enforcement point. Depending on the environment, enforcement could occur at an API gateway, service mesh proxy, firewall, network access control system or programmable network controller.

  • Establish a trusted mapping: Define how an authenticated identity or workload maps to a policy and the traffic it governs.
  • Use an appropriate enforcement point: Apply the decision where the relevant request or traffic can actually be controlled.
  • Limit policy scope: Avoid broad network changes when an application-level allow or deny decision is sufficient.
  • Handle policy changes: Consider token expiry, revoked permissions, stale rules and the time needed to distribute updates.
  • Maintain observability: Correlate application decisions with network events using suitable identifiers while minimising sensitive information in logs.

Security and operational considerations

Token validation

Validate signature, issuer, audience, expiry and other required claims. Never trust decoded token contents without verifying the token.

Least privilege

Grant only the permissions required for the specific resource and operation. A general role should not automatically imply unrestricted access.

Trusted headers

Remove or overwrite externally supplied identity headers at a trusted gateway before passing identity context to downstream services.

Fail-safe behaviour

Define what happens when the identity provider or policy service is unavailable. Avoid silently treating an unknown identity as authorised.

When is identity-aware steering useful?

  • Multi-tenant platforms: Direct authorised requests to the correct tenant service while preventing cross-tenant access.
  • Internal APIs: Apply different permissions to operations, users and service identities.
  • Zero-trust architectures: Make access decisions based on verified identity and policy rather than relying on network location as the sole trust signal.
  • Controlled application migration: Direct eligible requests to an approved service version or backend after authorisation.
Key takeaway

Identity-aware traffic steering brings authenticated identity and application policy into request handling. Node.js can demonstrate application-level service selection, while broader network steering requires a trusted integration between identity, policy and the appropriate forwarding enforcement point.

Network Insight · Interactive Lab 07

Identity-Aware Traffic Steering

Use identity, device posture and application context to determine which services a user can reach and how their traffic is handled.

Policy ready
01 / Identity-to-application path
Stage 0 of 5
♙
Employee · Standard access Identity awaiting evaluation
ROLE: EMPLOYEE DEVICE: TRUSTED
♙
User / Identity Role and group
→
◇
Access policy Identity + context
→
⇢
Traffic steering Choose permitted path
→
▦
Application Allow or deny access
Illustrative access path. Identity-aware systems can enforce policy at gateways, proxies, application access brokers or other enforcement points.
Checks completed0 / 5
Policy outcomePending
Selected route—
Awaiting access request

Choose an identity, application and device posture. Then evaluate the request to see how policy changes the traffic path.

03 / Decision sequence
Waiting for request
1
Identify the userResolve the identity and associated role or group.
2
Evaluate device and contextCheck device trust, MFA, network and sign-in risk.
3
Match application policyCompare the requested application with role permissions.
4
Select enforcement pathChoose a permitted route, step-up action or denial.
5
Enforce and recordAllow or deny the request and record the decision.
04 / Policy event log
0 events
Policy engine ready
Waiting for an access request.
Engineering note: This is a teaching simulation, not a production identity provider or security policy engine. The role permissions and access outcomes are illustrative. Real deployments require explicit authorization rules, strong identity verification, device posture signals, least-privilege design, and carefully defined handling of risk and authentication failures.
Network Insight · Key Takeaways

Conclusion: From Traffic Forwarding to Intent-Based Steering

Application traffic steering is about more than finding a route from one network to another. It is about making an informed forwarding decision based on the application, the user, the current network conditions, security requirements and the destination service.

Traditional routing provides the underlying reachability, while technologies such as policy-based routing, SD-WAN, load balancing, software-defined networking and service function chaining add different ways to influence how traffic travels. Identity-aware policies extend this approach by considering who is requesting access, whether the device is trusted and which application the user is permitted to reach.

The central engineering principle

Classify the traffic, evaluate the relevant policy, select an appropriate path, and verify the outcome. Effective steering must balance application performance, availability, security and operational simplicity rather than optimise one factor in isolation.

01
Classify Identify the application, traffic flow, user or device context.
02
Evaluate Apply routing policy, access rules, service requirements and performance signals.
03
Steer Choose an eligible route, network path, service chain or application endpoint.
04
Verify Check reachability, application health, policy enforcement and observed performance.
Connect the concepts · BGP

Where does BGP fit into application traffic steering?

Border Gateway Protocol (BGP) supplies routing information and path-selection mechanisms that can support traffic-engineering objectives. Local preference can influence outbound path selection within an autonomous system, AS-path prepending can influence how some external networks compare routes, and carefully designed more-specific advertisements can affect inbound traffic patterns. These mechanisms have different scopes and limitations: they do not replace application-aware policy, and their effect depends on routing configuration and the behaviour of other networks.

BGP Best-Path Selection Local Preference AS-Path Prepending Route Advertisement Traffic Engineering

In a real deployment, the best design is rarely a single technology. Routing, application delivery, security controls and identity policy often work together. The challenge is to define clear responsibilities between these layers, avoid conflicting policies, and ensure that a steering decision remains observable and supportable when conditions change.

Final takeaway: Good traffic steering is deliberate, measurable and policy-driven. The goal is not simply to move packets along a different path; it is to deliver the required application experience through a path that meets the organisation's performance, availability and security objectives.

```
☕
Support Network Insight
Help support independent engineering guides, interactive networking tools, and future learning labs.
Support Network Insight ```
NFV

NFV Use Cases

NFV Use Cases

Network Function Virtualization (NFV) has emerged as a transformative technology in networking. By decoupling network functions from dedicated hardware and implementing them in software, NFV offers remarkable flexibility, scalability, and cost-efficiency. This blog post will explore the diverse range of NFV use cases and how this technology is revolutionizing various industries.

NFV allows the virtualization of various network appliances such as firewalls, load balancers, and routers. This consolidation of functions into software-based instances simplifies network management, reduces hardware complexity, and enables efficient resource allocation.

NFV in Telecommunications: With the rapid expansion of mobile networks and the increasing demand for bandwidth, telecommunications companies are embracing NFV to enhance their infrastructure. By virtualizing network functions such as firewalls, load balancers, and session border controllers, telecom operators can achieve cost savings, simplified management, and faster service deployment. NFV also enables dynamic scaling of resources, ensuring optimal network performance even during peak usage periods.

NFV in Cloud Computing: Cloud service providers leverage NFV to deliver scalable and on-demand network services to their customers. By virtualizing functions like virtual routing, switching, and firewalls, cloud providers can offer flexible and customizable network configurations to meet diverse client requirements. NFV also enables rapid service chaining, allowing for the seamless integration of different network functions to create complex service offerings.

NFV in the Internet of Things (IoT): The proliferation of IoT devices brings forth new challenges in terms of managing and securing the massive amounts of data generated. NFV plays a crucial role in IoT deployments by providing virtualized security services that can be dynamically allocated based on the changing demands of IoT networks. Additionally, NFV enables efficient data processing and analysis at the edge, reducing latency and improving overall system performance.

NFV in the Healthcare Industry: The healthcare sector is embracing NFV to enhance patient care, optimize resource utilization, and improve operational efficiency. By virtualizing functions like patient monitoring systems, electronic health records, and secure communications, healthcare providers can streamline workflows, reduce costs, and ensure data privacy. NFV also enables telemedicine services, facilitating remote consultations and enhancing access to healthcare in underserved areas.

The use cases of NFV span across various industries, showcasing its versatility and transformative potential. From telecommunications to cloud computing, IoT, and healthcare, NFV's ability to virtualize network functions offers numerous benefits such as cost savings, flexibility, and scalability. As technology continues to evolve, NFV will undoubtedly play a pivotal role in shaping the future of networking, enabling innovative solutions to meet the ever-growing demands of the digital era.

NFV Use Case

**Introduction to Network Function Virtualization (NFV)**

In the ever-evolving landscape of technology, Network Function Virtualization (NFV) has emerged as a groundbreaking innovation. This transformative approach to network architecture promises to revolutionize how service providers create and deliver network services. By decoupling network functions from proprietary hardware appliances, NFV offers unprecedented flexibility and scalability. But what exactly is NFV, and why does it hold such promise for the future of networking?

**The Architecture Behind NFV**

At its core, NFV is about transforming network functions into software applications that can run on standard servers. This shift allows for the virtualization of functions such as firewalls, load balancers, and routers, which were traditionally tied to specific hardware. The architecture relies on a combination of virtual machines, hypervisors, and cloud computing to create a dynamic and efficient network environment. By using commercial off-the-shelf hardware, service providers can reduce costs and increase agility in deploying new services.

**Benefits of Adopting NFV**

The adoption of NFV brings a myriad of benefits to both service providers and end-users. For providers, it means a significant reduction in capital and operational expenditures. The flexibility to deploy network functions as software applications enables faster service innovation and deployment. For end-users, NFV translates to improved service delivery, with enhanced reliability and performance. Moreover, the scalability of NFV allows for better management of network resources, adapting quickly to varying demands.

**Challenges in Implementing NFV**

Despite its advantages, implementing NFV is not without challenges. One of the primary concerns is the integration of NFV with existing network infrastructures. As providers transition from hardware-based solutions to virtualized environments, they must ensure compatibility and interoperability. Additionally, security remains a critical issue, as virtualization introduces new vulnerabilities. Addressing these challenges requires a robust strategy and collaboration between industry players to establish standards and best practices.

**The Future of NFV**

Looking ahead, NFV is poised to play a crucial role in the advancement of 5G networks and the Internet of Things (IoT). As the demand for high-speed, low-latency services grows, NFV’s ability to deliver flexible, scalable solutions will be invaluable. The technology’s potential to support innovative services, such as network slicing and edge computing, positions it as a key driver of future network evolution. As NFV matures, we can expect to see even greater integration with emerging technologies, further reshaping the networking landscape.

Network Function Virtualisation (NFV)

At its core, NFV decouples network functions such as firewalls, load balancers, and routers from proprietary hardware appliances, allowing them to run as software on a range of hardware. This shift not only reduces the reliance on specialized hardware but also enhances the flexibility and scalability of networks. By leveraging standard IT virtualization technology, NFV enables network operators to deploy new services with greater speed and efficiency.

It could be argued that Network Function Virtualization (NFV) builds on some of the basic and now salient concepts of Software Defined Networking (SDN). Separation of control and data planes, logical centralization, controllers, network virtualization (logical overlays), application awareness, and application intent control are all trending toward running on commodity (Commercial Off-The-Shelf (COTS)) hardware platforms.

With NFV, these concepts are expanded with new methods supporting service element interconnection, such as Service Function Chaining (SFC), and new management techniques for coping with its dynamic, elastic capabilities.

**Network Service and Service Function**

A: – The concept of a network service refers to any computational service that possesses a network component. Some functions can discriminate between individual network flows or manipulate them in other ways. According to the IETF SFC Architecture document, an operator’s offering is delivered using one or more service functions.

B: – The IETF document defines a service function as a function responsible for treating received packets in a specific manner: “A function responsible for treating received packets in a particular manner.” A network element that provides a service function, whether virtual or traditional, highly integrated, may also offer multiple service functions, so we would refer to it as a “composite.”

NFV is not complicated

C: – Network functions virtualization (NFV) is not a complicated concept. The term refers to deploying hardware functions as software instead of hardware. Most commonly, virtual machines (VMs) serve as routers, firewalls, load balancers, intrusion detection and prevention systems (IDS/IPS), virtual private networks (VPNs), application firewalls, and other functions.

D: – A monolithic piece of hardware may cost tens of thousands of dollars and may have thousands of lines of code, and with NFV, it can be broken down into N pieces of software- namely, virtual appliances. A smaller device makes it easier to manage from the perspective of a single device.

A Key Point: Network Virtualization:

In network virtualization, endpoints are grouped logically on a network. As a result of this abstraction, VMs (and other assets) appear, behave, and can be managed as if they were all located on the same physical segment of the network. Even though it is an old technology, it is essential in virtual environments, where assets are created and moved without much regard for location. Automation and management tools have been designed specifically for scalable and elastic virtualized data centers and clouds.

NFV Use Cases

1. Telecommunications:

NFV has revolutionized the telecommunications sector by enabling the virtualization of crucial network functions. Service providers can now deploy virtualized network functions (VNFs) such as routers, firewalls, and load balancers, reducing the reliance on dedicated hardware. This allows for dynamic scaling, faster service deployment, and increased operational efficiency.

2. Cloud Computing:

NFV is playing a pivotal role in the evolution of cloud computing. By virtualizing network functions, NFV enables the creation of software-defined networking (SDN) architectures, which offer greater agility and flexibility in managing network resources. This allows cloud service providers to quickly adapt to changing demands, optimize resource allocation, and deliver services with enhanced performance and reliability.

3. Internet of Things (IoT):

The proliferation of IoT devices has created new challenges for network infrastructure. NFV has emerged as a solution to meet the dynamic demands of IoT deployments. By virtualizing network functions, NFV enables the efficient management and orchestration of network resources to support the massive scale and diverse requirements of IoT applications. This ensures seamless connectivity, efficient data processing, and improved overall performance.

4. Enterprise Networking:

NFV significantly benefits enterprise networking by simplifying network management and reducing costs. With NFV, enterprises can deploy virtualized network functions to replace traditional hardware appliances, reducing hardware and maintenance costs. This enables enterprises to rapidly deploy new services, scale their networks as per demand, and improve overall network performance and security.

5. Service Chaining:

NFV enables service chaining, which refers to the sequential routing of network traffic through a series of virtualized network functions. Service chaining allows for the creation of complex network service workflows, enabling the delivery of advanced services such as network security, traffic optimization, and deep packet inspection. NFV’s ability to dynamically chain and orchestrate virtualized network functions opens up new possibilities for service providers to deliver innovative and personalized services to their customers.

Network Functions Virtualization

Within NFV, Layer 4 through 7 services such as load balancing and firewalling are virtualized. Virtualization enables certain types of network appliances to be easily deployed wherever needed by converting them into virtual machines. Inefficiencies caused by virtualization led to the creation of NFV. Virtualization has been discussed primarily for its benefits but has also caused many problems.

Data center traffic was routed to and from network appliances at the network’s edge. There is a problem for fixed appliances since VMs are springing up and moving around. Virtualizing functions like firewalls can be easily “spun up” and placed where needed, just like virtual machines.

Virtual Networks with VXLAN:

Virtual machines supporting applications or services require physical switching and routing to connect to the data center or cloud and clients over a WAN link or the Internet. Data center networks must be secure in addition to load balancing and security. As traffic leaves the VM, it encounters a virtual switch (hypervisor), and then a physical switch at the top or end of the rack. The physical network cannot cope with the rapidly shifting state of virtual machines once traffic leaves the hypervisor.

VXLAN multicast mode
Diagram: VXLAN multicast mode

The issue can be circumvented by creating a logical network of VMs that spans the physical networks. Encapsulation is used in VXLAN, as in most other network virtualization forms. In contrast to simple VLANs, which can create only 4096 logical networks per physical network, VXLAN can create about 16 million logical networks per physical network. That scale is necessary for a large data center or cloud.

A shift from hardware-centric:

NFV, at its core, is the virtualization of network functions traditionally performed by dedicated hardware appliances. It enables the decoupling of network functions from specialized hardware, allowing them to be run as software on general-purpose servers. This shift from hardware-centric to software-centric network infrastructure brings immense flexibility, agility, and resource optimization advantages.

SDN and NFV

While Software Defined Networking (SDN) and Network Function Virtualization (NFV) are used in the same context, they satisfy separate functions in the network. NFV is used to program network functions, like network overlays, QoS, VPNs, etc., enabling a series of SDN NFV use cases. SDN is used to program the network flows. They have entirely different heritages. SDN was born in academic labs and found roots in the significant hyper-scale data center topologies of Google, Amazon, and Microsoft.

Its use case moves from the internal data center to the service provider and mobile networks. NFV, on the other hand, was pushed by service providers in 20012-2013, and work is driven out of the European Telecommunications Standard Institute (ETSI) working group. The ETSI has proposed an NFV reference architecture, several white papers, and technology leaflets. 

You may find the following valuable post for pre-information:

  1. Ansible Tower
  2. What is OpenFlow
  3. LISP Protocol
  4. Open Networking
  5. OpenFlow Protocol
  6. What is BGP protocol in Networking
  7. Removing State From Network Functions

NFV Use Cases

Over the past few years, it has become increasingly popular for companies operating within different industrial and commercial sectors to use network function virtualization (NFV) to solve multiple networking challenges. With the expansion of the Internet of Things (IoT) and advances in network communications technologies, along with the growing demand for ever more advanced services, network function virtualization is allowing enterprises to design, provide, and ease into much more advanced services and operations as well as reduce outgoings through cost savings.

Highlighting NFV

Network Function Virtualization (NFV) is a network architecture concept that uses software-defined networking (SDN) principles to virtualize entire classes of network node functions into building blocks that can be connected, composed, and reconfigured to create communication services. This virtualization approach to developing a programmable network layer is essential to realizing a Software Defined Network (SDN).

NFV enables the network administrator to rapidly create, deploy, and configure network services across data centers and remote locations, eliminating the need to deploy and maintain dedicated hardware for each service. In addition, by virtualizing the network functions, the network administrator can use a single instance of the service across the entire network, reducing complexity and management overhead.

NFV Benefits

The main benefit of NFV is that it simplifies network management, allowing the network administrator to create, deploy, and configure services as needed quickly.  It also reduces costs associated with managing multiple instances of the same service. Additionally, NFV enables the network administrator to quickly deploy new services, allowing for rapid deployment and testing of new network services.

In addition to these benefits, NFV also provides flexibility and scalability. By leveraging virtualization, the network administrator can quickly scale the network up or down as needed without purchasing additional hardware. Additionally, NFV allows for more efficient use of resources, eliminating the need to buy dedicated hardware for each service.

NFV use cases
Diagram: NFV. The source is AVI.

NFV Advanced

Network function virtualization (NFV) denotes a significant transformation for telecommunications/service provider networks, pushed by reducing cost, increasing flexibility, and providing personalized services. NFV leverages cloud computing principles to change how NFs such as gateways and middleboxes are offered. Unlike today’s tight coupling between the NF software and dedicated hardware, the loosely coupled software and hardware in NFV can relieve the upgrade cost and increase innovation flexibility.

**SDN NFV Use Cases: ASIC and Intel x86 Processor**

To understand network function virtualization, consider the inside of proprietary network devices and standard servers. The inside of a network device looks similar to that of a standard server. They have several components, including Flash, PCI bus, RAM, etc. Apart from the number of physical ports, the architecture is very similar. The ASIC (application-specific integrated circuit) is not as important as vendors would like you to believe.

When buying a networking device, you are not paying for the hardware—the hardware is cheap—but for the software and maintenance costs. Hardware is a minor component of the total price. Why can’t you run network services on Intel x86? Why is there a need to run these services on vendor-proprietary software? x86 general-purpose OSs can perform just as well as some routers with dedicated silicon.

SDN NFV use cases
Diagram: SDN NFV use cases

Network Function Virtualization Architecture

The concept of NFV is simple: Let’s deploy network services in VM format on generic, non-proprietary hardware. NFV increases network agility by deploying services in seconds, not weeks. The time-to-deployment is quicker, enabling the introduction of new concepts and products in line with the business deployment speeds needed for today’s networks.

In addition, NFV reduces the number of redundant devices. For example, why have two firewall devices on active / standby when you can insert or replace a failed firewall in seconds with NFV?  It also simplifies the network and reduces the shared state in network components.

A shared state is always bad for a network, and too much device complexity leads to “holy cows.” A holy cow is a network device ingrained so much in the network with obsolete and old configurations it cannot be moved quickly or cheaply (everything can be moved at a cost).

NFV use cases

However, not everything can be expressed in software. You can’t replace a Terabit switch with an Intel CPU. Replacing a top-end Cisco GSR or CSR with an Intel x86 server may be cheaper, but it is far from practical functionally. There will always be a requirement for hardware-based forwarding, which will likely never change. But if your existing hardware uses Intel’s x86 forwarding, there is no reason it can’t run on generic hardware.

Possible SDN NFV use cases with network function for NFV include Firewalls with stateful inspection firewall capabilities, Deep Packet Inspection (DPI) devices, Intrusion Detection Systems, SP CE and PE devices, and Server Load Balancers. DPI is never usually done in hardware, so why can’t we put it on an x86 server?

Load balancing can be scaled out among many virtual devices in a pay-as-you-grow model, making it an accepted NFV candidate. There is no need to put 20 IP addresses on a load balancer when you can quickly scale 20 independent load balancing instances in NFV format.

Network Function Virtualization Architecture
Diagram: Network Function Virtualization Architecture

 Control plane functionality

While the relevant use cases of NFV continue to evolve, an immediate and widely accepted use case would be with control plane functionality. Control plane functions don’t require intensive hardware-based forwarding functions. Instead, they provide reachability and control information for end-to-end communication.

Example Technology: BGP Route Reflection

**What is BGP Route Reflection?**

At its core, BGP route reflection is a method used to optimize the dissemination of routing information within a network. Traditionally, BGP required a full mesh of internal BGP (iBGP) peers, which could become unwieldy as networks grew. Route reflection provides a solution to this scalability issue by allowing a BGP router, known as a route reflector, to propagate routes to other BGP routers without needing a direct link.

**How Route Reflection Works**

Route reflection simplifies network architecture by introducing route reflectors and clients. The route reflector acts as a central point that receives routing updates and then reflects, or disseminates, these updates to its clients. This structure reduces the number of connections required, improving network efficiency and manageability. By implementing route reflection, network operators can maintain fewer connections and still ensure optimal route dissemination, making it a popular choice in large-scale network environments.

**The Advantages of Route Reflection**

There are several key advantages to using route reflection in BGP. First and foremost, it significantly reduces the complexity of managing network connections. By minimizing the number of iBGP peering sessions, route reflection alleviates the administrative burden and lowers the potential for configuration errors. Additionally, route reflection can lead to improved network performance by streamlining the path selection process, ensuring that data takes the most efficient route possible.

**Challenges and Considerations**

While route reflection offers many benefits, it is not without its challenges. One of the primary concerns is the potential for suboptimal routing. Because route reflectors may not have a complete view of the network, there is a risk that the path chosen might not be the most efficient. Network operators need to carefully design their route reflection topology and consider redundancy to mitigate these risks. Additionally, understanding the underlying BGP policies and configurations is crucial to avoid unforeseen routing issues.


BGP RR and LISP Mapping Database

For example, take the case of a BGP Route-Reflector (RR) or LISP Mapping Database. An RR does not participate in data plane forwarding. It is usually designed in a redundant route reflector cluster for control plane services, reflecting routes from one node to another. It is not in the data transit path.

We have used proprietary vendor hardware as route reflectors for ages as they had the best BGP stack. But buying a high-end Cisco or Juniper device just to run RR control plane services wastes money and hardware resources. Why buy a router with suitable forwarding hardware when you only need the control plane software element? 

LISP mapping databases

LISP Mapping Databases are commonly deployed on x86, not a dedicated routing appliance. This is how the lispers.net open ecosystem mapping server is deployed. All routers needed for control plane services can be put in a VM. Control plane functionality is not the only one for NFV use cases. Service providers are also implementing NFV for virtual PE and virtual CE devices.

They offer per-customer use cases by building a unique service chain for each customer. Some providers want to allow customers to build their own service chains. This allows you to quickly create new services and test service adoption rates to determine if anyone is buying the product—a great way to test new services.

LISP networking
Diagram: LISP Networking. Source is Cisco

Network Function Virtualization performance

There are three elements relating to performance – management, control, and data plane. Management and control plane performance is not as critical as the data plane. As long as you get decent protocol convergence timers, it should be good enough. But generally speaking, they are not as crucial as data plane forwarding, which is critical for performance.

The performance you get out of the box with an x86 device isn’t outstanding; maybe 1 or 2 GiG of forwarding performance. If you do something simple like switching Layer 2 packets, the performance will increase to 2 or 3 gigs per core. Unfortunately, this is considerably less than what the actual hardware can do. The hardware can push 50 to 100GiG through a mid-range server. Why is out-of-the-box performance so bad?

TCP stack and Linux kernel

The problem lies with the TCP stack and Linux Kernel. The Linux Kernel was never designed for high-speed packet forwarding. It could offer a better data plane but an excellent control plane function. To improve performance, you may need multi-core processing. Sometimes, the forwarding path taken by the virtual switch is so long that it kills performance.

Significantly, when the encapsulation and decapsulation process of tunneling is involved, in the past, when you started to use Open vswitch (OVS) ( what is OVS ) with GRE tunneling – VPNoverview performance fell drastically.

They never had this problem with VLANS because they used a different code path. With the latest version of OVS, performance is not an issue. On the contrary, it’s faster than most of its alternatives, such as the Linux Bridge.

The performance has increased due to the changes in architecture for multithreading, megaflows, and additional classification improvements. It can be optimized further with Intel DPDK. DPDK is a set of enhanced libraries and drivers that enable kernel bypass, gaining impressive performance. Performance may also be achieved by moving the hypervisor out of the picture with SR-IOV.

SR-IOV slices a single physical NIC into multiple virtual NICs, and then you connect the VM to one of the virtual NICs. You are allowing the VM to work with the hardware directly.

Summary: NFV Use Cases

Section 1: NFV in Telecommunications

NFV has significantly impacted the telecommunications industry by enabling service providers to virtualize network functions, such as routing, firewalls, and load balancing. This virtualization allows for increased flexibility, scalability, and cost-effectiveness in managing network infrastructure.

Section 2: NFV in Healthcare

The healthcare sector has seen the integration of NFV to optimize network performance and security. By virtualizing functions like data storage, security protocols, and patient monitoring systems, healthcare providers can streamline operations, improve patient care, and enhance data privacy.

Section 3: NFV in Banking and Finance

In the banking and finance industry, NFV offers many benefits, including enhanced network security, improved transaction speeds, and efficient data management. Virtualizing functions like fraud detection, virtual private networks (VPNs), and disaster recovery systems enable financial institutions to stay competitive in a rapidly evolving digital landscape.

Section 4: NFV in the Internet of Things (IoT)

The proliferation of IoT devices necessitates robust network infrastructure to handle the massive influx of data. NFV optimizes IoT networks by providing virtualized functions like data analytics, security, and edge computing. This enables efficient data processing, reduced latency, and improved scalability in IoT deployments.

Virtual Switch

Virtual Switch

Virtual Switch

In today's digital age, where connectivity is paramount, network administrators constantly seek ways to optimize network performance and streamline management processes. The virtual switch is a crucial component that plays a significant role in achieving these goals. In this blog post, we will delve into virtual switches, exploring their benefits, features, and how they contribute to creating efficient and robust network infrastructures.

A virtual switch, also known as a vSwitch, is a software-based network switch that operates within a virtualized environment. It bridges virtual machines (VMs) and physical network interfaces, enabling communication. Like a physical switch, a virtual switch facilitates data transmission, ensuring seamless connectivity throughout the network.

Virtual switches are software-based networking components that operate within virtualized environments. They play a crucial role in directing network traffic between virtual machines (VMs) and physical networks. By emulating the functionalities of traditional physical switches, virtual switches enable efficient and flexible network management in virtualized environments.

Enhanced Network Virtualization: Virtual switches provide the foundation for network virtualization, allowing organizations to create multiple virtual networks within a single physical network infrastructure. This enables better resource utilization, improved security, and simplified network management.

Simplified Network Configuration: Unlike physical switches that require manual configuration, virtual switches can be easily managed and configured through software interfaces. This flexibility allows for dynamic allocation of network resources, making it easier to adapt to changing network requirements.

Improved Network Security: Virtual switches offer advanced security features, such as virtual LAN (VLAN) segmentation and access control lists (ACLs). These features help isolate and secure network traffic, reducing the risk of unauthorized access and potential security breaches.

Scalability and Flexibility: Virtual switches provide greater scalability and flexibility compared to their physical counterparts. With virtual switches, organizations can quickly add or remove virtual ports, adapt to changing network demands, and dynamically allocate network resources as needed.

Cost Efficiency: Virtual switches eliminate the need for additional hardware, resulting in cost savings for organizations. By leveraging existing server infrastructure, virtual switches reduce both capital and operational expenses associated with physical switches.

The virtual switch has emerged as a game-changer in the world of connectivity. Its ability to enhance network virtualization, simplify network configuration, and improve security makes it a valuable tool for organizations across various industries. As our reliance on virtualized environments continues to grow, the virtual switch will undoubtedly play a pivotal role in shaping the future of connectivity.

Highlights: Virtual Switch

### What is a Virtual Switch?

A virtual switch, often referred to as a vSwitch, is a software-based switch that enables the connection of virtual machines (VMs) to a network within a virtualized host environment. Unlike a physical switch, which requires hardware, a virtual switch functions entirely within the software layer, allowing seamless communication between VMs and external networks. It acts as a bridge, directing the network traffic between connected virtualized devices, thereby facilitating efficient data flow and resource utilization.

### How Virtual Switches Work

At its core, a virtual switch operates similarly to a physical switch, with the ability to forward data packets based on MAC addresses. It connects virtual network interface cards (vNICs) of VMs to each other and to the physical network. By maintaining a MAC address table, the virtual switch learns and stores the network locations of devices, ensuring that data packets are correctly forwarded to their intended destinations. This functionality allows for robust network segmentation and enhanced security measures within a virtualized environment.

### Benefits of Implementing Virtual Switches

Virtual switches offer numerous advantages that make them indispensable in modern networking. First and foremost, they provide scalability, allowing network administrators to easily add or remove VMs without the need for additional hardware. This flexibility results in significant cost savings and reduced operational complexity. Additionally, virtual switches enhance network security through features like port isolation and VLAN tagging, ensuring that sensitive data remains protected. Their ability to integrate with software-defined networking (SDN) solutions further amplifies their efficiency, enabling centralized network management and automation.

### Challenges and Considerations

While virtual switches offer compelling benefits, they also present certain challenges. Performance can be a concern, especially in environments with high levels of network traffic. Additionally, the complexity of managing virtual networks requires skilled personnel and robust monitoring tools to ensure optimal performance. Network administrators must also consider compatibility issues, as different virtualization platforms may have varying virtual switch implementations.

Understanding Virtual Switching

Virtual switching is a fundamental component of SDN, enabling the creation and management of virtual networks within a physical network infrastructure. Unlike traditional switches that rely on dedicated hardware, virtual switches operate in software, providing a flexible and programmable approach to network connectivity. By decoupling the control plane from the data plane, virtual switching allows for centralized management and dynamic allocation of network resources.

One of virtual switching’s key advantages is its ability to improve network agility. With virtual switches, network administrators can easily create, modify, and scale virtual networks to meet the changing demands of modern applications. 

**Isolation Between Virtual Networks**

Virtual switching also enhances network security by providing isolation between virtual networks, preventing unauthorized access, and minimizing the impact of potential breaches. Additionally, virtual switches enable advanced network services such as load balancing, traffic shaping, and firewalling, enhancing overall network performance and efficiency.

Deploying virtual switching requires compatible network hardware and the appropriate software-defined networking infrastructure. Virtual switches are typically integrated into hypervisors or operating systems, allowing seamless integration with virtual machines and containers. 

**Centralized Management**

Network administrators can configure virtual switches through a centralized management console, simplifying network provisioning and reducing operational costs. Moreover, virtual switching supports interoperability with traditional physical switches, enabling a gradual transition towards a fully virtualized network environment.

Use Cases and Applications:

Virtual switches are extensively used in various scenarios across industries. Here are a few prominent examples:

1. Data Centers: In large-scale data centers, virtual switches are critical in connecting VMs and containers to the underlying physical infrastructure. They provide agility and scalability, allowing seamless workload migration and resource allocation.

2. Network Function Virtualization (NFV): Virtual switches are vital in NFV deployments, where traditional network functions are virtualized. They enable the creation of virtual network functions (VNFs) and facilitate chaining these functions to build complex network services.

3. Software-defined networking (SDN): In SDN architectures, virtual switches are integral to the network fabric. They provide programmability and flexibility, allowing centralized network control and automated provisioning.

A virtual switch is a software-based network switch that operates within a hypervisor, facilitating network traffic between VMs and the external network. It behaves similarly to a physical switch, providing connectivity, VLAN segmentation, and traffic management capabilities.

Types: Virtual Switches

1: Standard Virtual Switches

Standard virtual switches are the most basic type, typically provided by the hypervisor. They offer essential network functions such as MAC address learning, port grouping, and basic VLAN support. Standard virtual switches are suitable for small-scale virtualization deployments with straightforward networking requirements.

2: Distributed Virtual Switches

Distributed virtual switches (DVS) take virtual networking to the next level by extending network management capabilities across multiple hypervisor hosts. DVS centralizes the configuration and monitoring of virtual switches, enabling consistent policies and simplifying network administration. It is ideal for large-scale deployments with high availability and load balancing requirements.

**Open Virtual Switches**

Open virtual switches (OVS) are an open-source alternative that provides enhanced flexibility and extensibility. OVS supports advanced features like network overlays, tunneling protocols, and fine-grained traffic control. It has gained popularity in software-defined networking (SDN) and cloud environments, allowing seamless integration with orchestration platforms and network virtualization technologies.

Virtual switches find applications across various scenarios. They are indispensable in virtualization platforms, enabling VM-to-VM communication, connectivity to physical networks, and network isolation. Virtual switches also play a vital role in SDN deployments, facilitating traffic steering, network programmability, and dynamic policy enforcement.

– Linux Bridge: OVS leverages the Linux bridge as its foundation, allowing for seamless integration with existing network infrastructures. This compatibility ensures easy adoption and migration for users already familiar with Linux networking.

– Open vSwitch: OVS extends beyond the capabilities of a traditional Linux bridge by offering advanced features like multi-layer switching, support for different tunneling protocols, and the ability to handle complex network flows efficiently.

Software-based switching

A: ) Several types of virtual switches are available on the market, including VMware vSwitch, Microsoft Hyper-V Virtual Switch, Linux bridges, and Open vSwitch (OVS). Switches like these are sometimes referred to as SDN switches. Still, they are software-based switches that reside in the kernel of the hypervisor and provide network connectivity between VMs/containers and the node itself.

B: ) Like their physical switch counterparts, they provide features like MAC learning, link aggregation, SPAN, and sFlow. These virtual switches run in software as part of a more comprehensive SDN and network virtualization solution.

C: ) Even though virtual switches aren’t a solution in and of themselves, they are essential to the development of the industry as a whole. In the data center, they have added a new edge or access layer. Feature/function development is no longer limited to physical tor switches that are hardware-defined and hardware-defined.

D:)  The new edge’s software-based nature allows the rapid creation of new network functions in software, making it easier to distribute policies throughout the network, thanks to virtual switches. An example is deploying the security policy nearest to the endpoint, a VM or container, to enhance network security.

Example: OpenvSwitch

Section 1: Understanding OpenvSwitch

OpenvSwitch is an open-source, multi-layer software switch that enables network automation and virtualization. It operates at the data link layer of the networking stack and provides a flexible and programmable interface for managing virtual and physical network devices. With support for numerous protocols and technologies, OpenvSwitch offers a robust foundation for building virtualized network infrastructures.

Section 2: Features OpenvSwitch

One of OpenvSwitch’s standout features is its support for both traditional and software-defined networking (SDN) environments. It seamlessly integrates with popular SDN controllers, allowing administrators to centrally manage and control network traffic. Additionally, OpenvSwitch supports various tunneling protocols, such as VXLAN and GRE, enabling the creation of virtual networks across the physical infrastructure.

Section 3: Scenarios OpenvSwitch

OpenvSwitch is helpful in a wide range of scenarios. It plays a crucial role in creating and managing virtual networks in cloud computing environments, ensuring efficient communication between virtual machines. Moreover, OpenvSwitch is highly extensible, allowing for the integration of custom modules and extensions to meet specific networking requirements. Its ability to handle high data rates and perform packet switching at wire speed makes it an ideal choice for demanding network environments.

Virtual Network and Container Networking  

Container networking operates by connecting multiple containers and enabling them to communicate with each other and the outside world. To grasp its fundamentals, it is essential to comprehend concepts like container network models, network namespaces, and container network interfaces (CNIs). We will explore these concepts in detail, shedding light on how they contribute to efficient container networking.
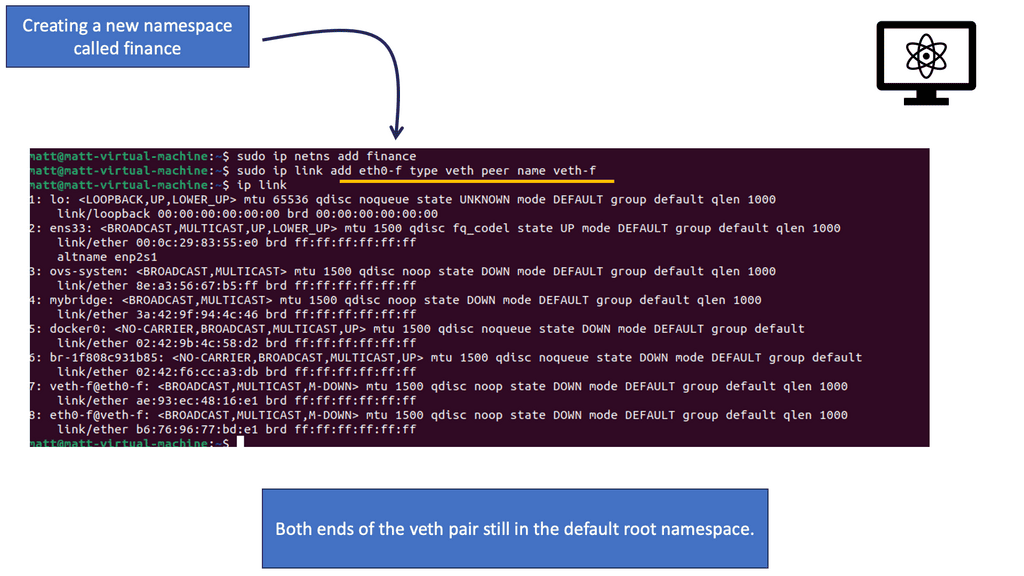
Container networking offers many benefits that enhance the performance and scalability of containerized applications. By leveraging container networking, developers can achieve improved service discovery, load balancing, and network security. We will discuss these advantages, showcasing how container networking can enhance application deployment and management.

Docker Default Networking

Docker default networking is the built-in networking solution that allows containers to communicate with each other and the outside world. By default, Docker creates a bridge network that acts as a virtual switch connecting all containers on the host. This bridge network assigns IP addresses to containers and provides them with a unique network identity.
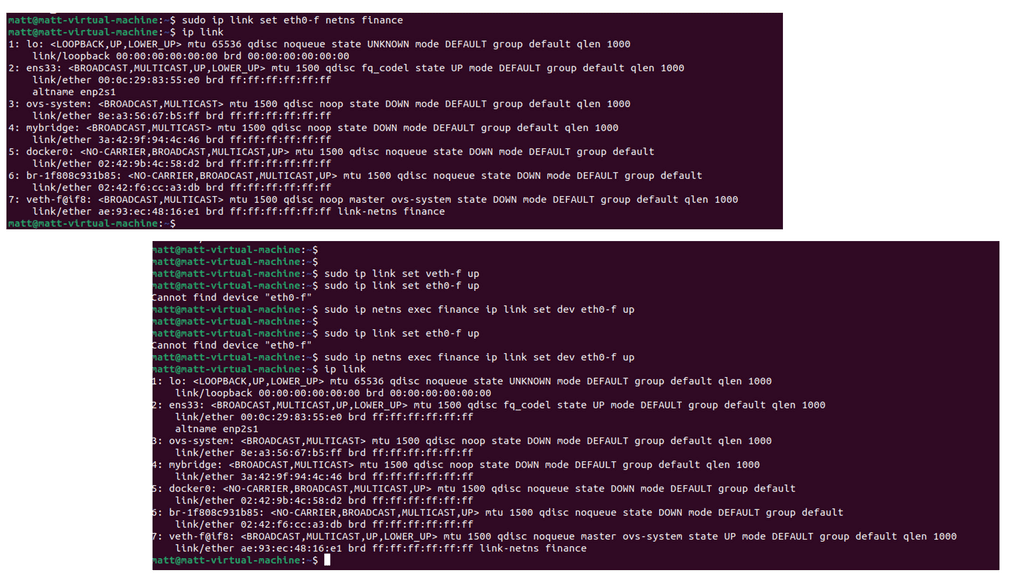
One of the primary benefits of Docker default networking is the ease of container-to-container communication. Containers within the same bridge network can communicate with each other using container names as DNS entries. This convenient feature eliminates complex IP address management and enables seamless integration between related containers.

** Container to Container Networking **

While Docker default networking offers excellent flexibility, there are scenarios where direct access to the host network is required. By leveraging the host network mode, containers can share the same networking stack as the host, bypassing the Docker bridge network altogether. This mode is handy for scenarios where containers must bind to specific host ports or require low-level network access.

Docker default networking incorporates a built-in DNS resolver that simplifies service discovery within containerized environments. Containers can resolve each other’s names using the embedded DNS server, making it easier to establish connections without remembering IP addresses. This feature becomes crucial in dynamic container orchestration scenarios where containers come and go frequently.

The Role of Virtual Switching

Virtual Switching functionality is not carried out with a standard switch, and we will have a distributed virtual switch located closer to the workloads that will connect to a ToR switch. The ToR switch is the first hop device from the virtual switch.  In a VMware virtualized environment, a single host runs multiple virtual machines (VM) through the VMkernel hypervisor.

The physical host does not have enough network cards to allocate a physical NIC to every VM, and there are exceptions, such as Cisco VM-FEX. Still, we generally have more virtual machines than physical network cards. We need a network to support communication flows so that VMs can communicate with each other internally or even via uplink.

**Traffic Boundaries**

Implementing a Layer 2 switch within the ESXi hosts allows traffic flowing from VMs within the same VLAN to be locally switched. Traffic across VLAN boundaries is passed to a security or routing device northbound to the switch.

There are possibilities for micro-segmentation, VM NIC firewalls, and stateful inspection firewalls, but let’s deal with them later in an article. Essentially, the virtual switch aggregates multiple VM traffic across a set of links and provides frame delivery between VMs based on Media Access Control (MAC) address, all of which fall under the umbrella of virtual switching with a distributed virtual switch.

Example Traffic Boundary:  

Understanding Zone-Based Firewalls

– Zone-based firewalls provide a robust means of controlling network traffic by dividing the network into security zones. Each zone represents a group of network devices with similar security requirements. By creating logical zones and enhancing network protection, administrators can apply different security policies and access rules tailored to specific zones.

– Zone-based firewalls offer several advantages over traditional firewall architectures. Firstly, they provide granular control over network traffic by allowing administrators to define policies based on source and destination zones. This helps prevent unauthorized access and restricts lateral movement within the network. Secondly, zone-based firewalls simplify firewall management by reducing the number of access control lists (ACLs) required, resulting in improved performance and more straightforward configuration.

Enter the Hypervisor

Servers use hypervisors to divide specialized hardware resources from the operating system. With a hypervisor, server drivers and resources are connected through the hypervisor, not the OS.

Adding a layer may increase efficiency, so what can they do to make it more efficient? I think that’s a good question.

In short, a hypervisor provides a virtual connection to a server’s resources for a virtual machine’s operating system. The significant part is that it can do this for many VMs running on the same server, regardless of whether they use different operating systems or applications.

**Virtual Machine Consolidation**

Virtual machines and hypervisors allow us to consolidate servers at a huge scale. The majority of servers can only run at a capacity of 5% to 10%. A company may save 6x to 15x in physical server costs if multiple applications are combined onto one server and CPU usage is less than 80%. In addition, there are other efficiencies. Cooling and power costs can be dramatically reduced with a 10x reduction in server numbers.

Another significant benefit of virtualization is the ability to migrate servers within a data center in a few hours without disrupting service. If a data center were moved without virtualization, it would almost certainly cause widespread service disruption over weeks or months. Furthermore, virtualization improves disaster recovery capabilities and reduces provisioning times for new applications.

Virtualization

Virtualizing the network

VMs supporting applications or services need physical switching and routing to communicate with data center clients over a WAN link or the Internet. Data centers also require security and load balancing. Virtual switches (hypervisors) are the first switches traffic leaves a VM, followed by physical switches (TORs or EORs). When traffic leaves the hypervisor, it enters the physical network, which cannot handle the rapid changes in the state of the VMs connected to it.

We can solve this problem using a logical network of virtual machines. As with most network virtualization, VXLAN does this through encapsulation. Unlike VLANs, which can only create 4096 logical networks on any given physical network, VXLAN can create around 16 million logical networks. This scale makes it essential to have a large data center or cloud.

Network Virtualization

Software-defined networking has become synonymous with network virtualization. This section uses network virtualization to refer to a software-only overlay solution. Some solutions in this category include VMware NSX, Nokia Nuage Networks Virtualized Services Platform (VSP), and Juniper’s Contrail.

VXLAN is an overlay protocol used to connect hypervisor-based virtual switches. Adjacencies are established between VMs residing on different physical hosts, independent of the physical network, which may be Layer 2, Layer 3, or a combination of both. The physical network is decoupled into a virtual one, allowing flexibility and choice.

Virtual switches are just one aspect of overlays, part of network virtualization solutions. These solutions can offer security, load balancing, and backward integration into the physical network with a single management point (the controller). Often, network virtualization solutions integrate with best-of-breed Layer 4-7 service providers, allowing users to choose the technology they want to use.

A centralized control plane maps overlay and underlay networks. Despite its scalability, flexibility, and interoperability, this centralized approach has limitations. Alternative protocols exist, such as Ethernet VPN (EVPN). Through BGP, each network device distributes mapping information to the rest of the network to establish VXLAN tunnels in EVPN. Controllerless solutions are VXLAN solutions without controllers.

Use Case: VXLAN – Flood and Learn

Understanding VXLAN

VXLAN, which stands for Virtual Extensible LAN, is a network virtualization technology that allows for the creation of scalable and flexible overlay networks. It enables the encapsulation of Layer 2 Ethernet frames within Layer 3 UDP packets, making extending Layer 2 connectivity across different Layer 3 networks possible. Before diving into flood and learning, let’s briefly grasp the basics of VXLAN.

Flood and learn is a mechanism VXLAN uses to ensure that multicast, broadcast and unknown unicast traffic is handled correctly within the overlay network. When a VXLAN tunnel endpoint (VTEP) receives such traffic, it floods the packets to all other VTEPs within the same VXLAN segment. Each VTEP then learns the necessary forwarding information by examining the inner Ethernet frame. This process allows for efficient and dynamic traffic forwarding across the VXLAN network.

Related: You may find the following helpful post for pre-information:

  1. Distributed Firewalls
  2. VMware NSX Security
  3. Nest Hypervisors
  4. Layer-3 Data Center
  5. Overlay Virtual Networks
  6. WAN SDN
  7. Hyperscale Networking

Virtual Switch

VMware Virtual Switch

The virtual network delivers networking for virtual machines, such as ESXi hosts in the VMware world. Like physical switches in our physical network, the essential component in a virtual network is a virtual switch. A virtual switch is a software-based switch built inside the ESXi kernel (VMkernel), used to deliver networking for the virtual environment.
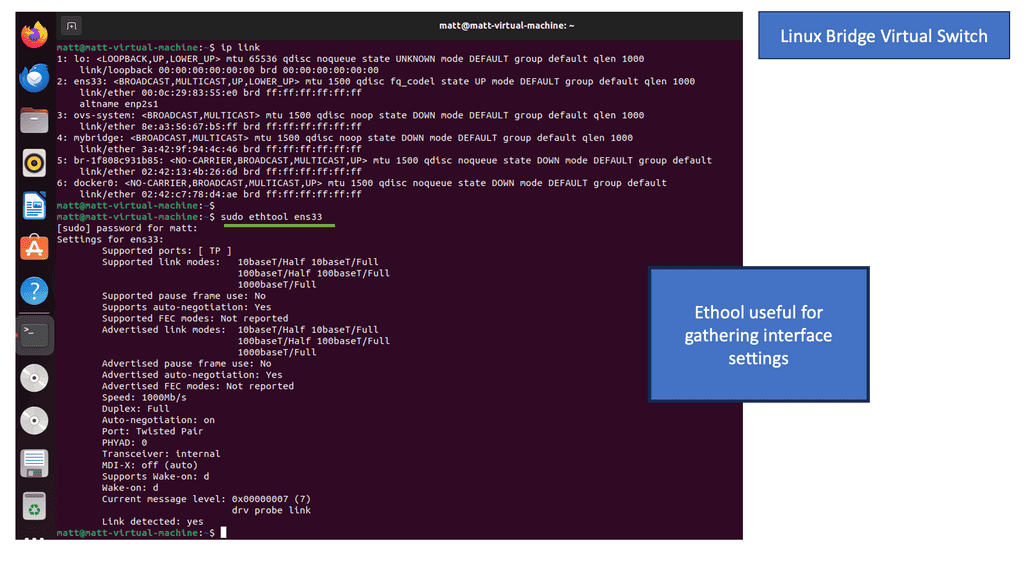
For example, traffic that flows from/to virtual machines is passed through one of the virtual switches in VMkernel. The virtual switch provides the connection for virtual machines to communicate with each other, whether operating on the same host or different hosts. A virtual switch works at Layer 2 of the OSI model.

Features of Virtual Switches:

1. VLAN Support: Virtual switches support VLANs, allowing administrators to logically divide a physical network into multiple virtual networks. This enables better network segmentation, improved security, and more efficient use of network resources.

2. Quality of Service (QoS): Virtual switches provide QoS capabilities, allowing administrators to prioritize specific types of network traffic. They ensure optimal performance and minimal latency by assigning higher priority to critical applications such as VoIP (Voice over Internet Protocol) or video conferencing.

3. Traffic Monitoring and Analysis: Virtual switches offer built-in traffic monitoring and analysis tools. Administrators can monitor network traffic in real-time, identify bottlenecks, and gain valuable insights into network performance. This enables proactive troubleshooting and optimization of network resources.

Open vSwitch in Linux

This guide addresses virtual switching with the Open vSwitch (OVS). The OVS is a multi-layer virtual switch that can perform basic Layer 3 and Layer 3 functionality. I have OVS running on a Ubuntu host.  Let’s first have a look at the setup and network configuration. I’m in a virtualized environment, and we have an online interface ens33 to the outside world. You can also see that we have OVS already installed with a bridge called my bridge setup. 
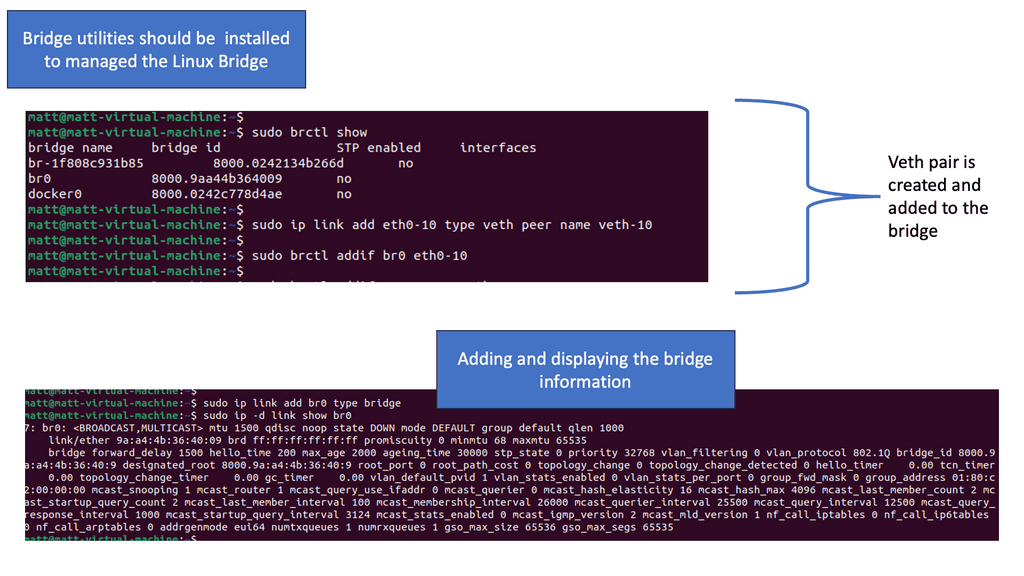
Note:

The OVS acts like a standard switch and carries out the same switching logic you would find with, for example, a physical catalyst switch. LAN switches receive Ethernet frames and then make a switching decision: either forward the frame to some other ports or ignore the frame. To accomplish this primary mission, switches perform three actions:

  1. Based on the destination MAC address, decide whether to forward a frame or filter (not forward) it.
  2. Preparing to forward frames by learning MAC addresses by examining the source MAC address of each frame received by the switch
  3. Preparing to forward only one copy of the frame to the destination by creating a (Layer 2) loop-free environment with other switches by using Spanning Tree Protocol (STP)

Linux works with namespaces, which form the underlying technology of containers. See how we added a new namespace called finance. We will also create a new veth pair. A veth pair is like a virtual cable. What goes in one end must come out the other end. Consider a veth pair linked to a standard physical cable but in virtual work.

Remember, when we discuss a new namespace, we need to move the links around of the veth pair to the corresponding namespace. In this setup, we have configured only one namespace, finance, but we also have the default namespace of root. The OVS switch, by default, is in the root namespace and can be used to connect disparate namespaces. The OVS also uses VXLAN to extend Layer 2 over IP. 

Virtual Switch: Three Distinct Types

To enable virtual switching, there are three virtual switches in a VMware environment: a) a standalone virtual switch, b) distributed virtual switch, and c) 3rd party distributed switch, such as the Cisco Nexus 1000v. These virtual switches have ports, and the hypervisor presents what looks like an NIC to every VM. The VMs are now isolated, thinking they have a virtual Ethernet adapter. Even if you change the physical cards in the server, the VM does not care as it does not see the physical hardware.

The diagram displays a virtualized environment with two sets of VMs, blue and red, attached to corresponding Port Groups. Port Groups are nothing special, simply management groups based on configuration templates. You may freely have different VMs in Port Groups in the same VLAN communication. The virtual NIC is a software construct emulated by the hypervisor. 

Virtual switching and the virtual switch:

The standalone virtual switch lacks advanced features but gains in performance. It is not a feature-rich virtual switch and supports standard VLAN and control planes consisting of CDP. Each ESXi host has an independent switch comprised of its data and control planes. Every switch is a separate management entity.

The Distributed virtual switch (vDS) is purely a management entity and minimizes the configuration burden of the standalone switch. It’s a template you configure in vCenter, applied to individual hosts. It lets you view the entire network infrastructure as one object in the vCenter. The port and network statistics assigned to the VM move when the VM moves.

Virtual distributed switch:

The vDS is a simple management template. Each ESXi host has its control and data plane with unique MAC and forwarding rules. The local host proxy switch performs packet forwarding and runs control plane protocols. One major vDS drawback is that if vCenter drops, you cannot change anything on the local hosts.

As a best design practice, most engineers use the standard standalone switch for management traffic and vDS for VM traffic on the same host. Each virtual switch (vS and vDS) must have its uplinks. For redundancy, you need at least two uplinks for each switch; already, you need four uplinks, usually operating at 10Gbps.

  • VMware-based software switches don’t follow 802.1 forwardings or operate Spanning Tree Protocol (STP). Instead, they use special tricks to prevent forwarding loops, such as Reverse Path Forwarding (RPF) checking on the source MAC address.

Virtual Switch and the Linux Bridge

The Linux Bridge is a virtual device connecting multiple network interfaces, allowing them to operate as a single network segment. Similar to the Open vSwitch, the Linux bridge uses veth pairs.

Note:

– The Linux Bridge supports STP, which prevents network loops and ensures efficient packet forwarding.

– The Linux Bridge can handle Virtual LANs (VLANs) and allows for creating VLAN-aware bridges.

– Configuring VLANs with the Linux Bridge enables network segmentation and improved traffic management.

Linux Bridge Utilities:

Linux Bridge Utilities, or brctl, can create and manage software-based network bridges in Linux. These utilities connect multiple network interfaces at the data link layer, creating a virtual bridge that facilitates communication between network segments. 

Virtual Switches, like physical switches, run STP to prevent loops.

The Cisco Nexus 1000v

Third-party virtual switching may also be plugged in, and the Nexus 1000v is the most popular. It operates with a control plane, a Virtual Supervisor Module (VSM), distributed data plane objects, and a Virtual Ethernet Module (VEM). Cisco initially operated all control plane protocols on the VSM, including LACP and IGMP snooping. It severely inhibited scalability; now, control plane protocols are distributed locally to the VEMs.

It’s a feature-rich software switch and supports VXLAN. You may also use the TCP-established keyword unavailable in VMware versions. Some of these products are free; others require an enterprise plus license. If you want a free, feature-rich, standards-based switching product, use Open vSwitch, licensed under Apache 2.0.

virtual switching
Diagram: Virtual switching with Nexus 1000v

Open vSwitch

What is OVS? Open vSwitch is similar to VMware virtual switch and Cisco Nexus 1000v. It operates as a soft switch within the hypervisor or as the control stack for switching silicon. For example, you can flash your device with OpenWrt and install the Open vSwitch package from the OpenWrt repository. Both are standards-based.

The following displays the ports on an Open vSwitch; as you can see, several bridges are present. These bridges are used to forward packets between hosts. It has a great feature set for a complimentary switch, including VXLAN, STT, Layer 4 hashing, OpenFlow, etc.

**Virtual Switching: Integration with the ToR Switch**

The virtual switch needs to connect to a ToR switch. So, even though the connection is logical, there must be a physical connection between the virtual switch and the ToR switch. Preferably a redundant connection for high availability. However, what happens with the VM on the virtual switch that needs to move?

Challenges occur when VMs must move, resulting in an enormous VLAN sprawl. All VLANs configured on all uplinks to the ToR switch create one big switch. What can be done to reduce this requirement? The best case would be integrating a solution synchronizing the virtual and physical worlds. Any changes in the virtual world are automatically provisioned in the physical world.
Ideally, we would like the list of VLANs configured on the server-facing port adjusted dynamically as VMs are moved around the network. For example, if VM-A moves from location A, we want its VLAN removed from the previous location and added to the new location B. Automatic VLAN synchronization reduces the flooding of Broadcast to servers, lowering the CPU utilization on each physical node.

Virtual switch: The different vendors

Arista, Force 10, and Brocade have VMware networking solutions on their ToR switches. Arista’s solution is VMtracer, which is natively integrated with EOS and works across all their data center switches. VMtracer gives you better visibility and control over VMs. It sends and receives CCDP or LLDP packets to extract VM information, including VLAN numbering per server port.

When a VM moves, it can remove the old VLAN and add the new VLAN to the new ports. Juniper and NEC use their Network Management systems to keep track of VMs and update the list of VLANs accordingly.

Cisco utilizes VM-FEX and a new feature called VM tracker, which is available on NX-OS. Cisco’s VM tracker interacts with vCenter SOAP API. It works with vCenter to identify the VLAN requirements of each VM and track their movements from one ESXi host to another. It relies on Cisco Discovery Protocol (CDP) information and does not support Link Layer Discovery Protocol (LLDP).

Edge Virtual Bridging (EVB)

An IEEE standard way to solve this is called EVB, and Juniper supports it, as HP ToR switches. VMware virtual switches do not currently support it. To implement EVB in a VMware virtualized environment, you must change the VMware virtual switch to either HP or Juniper. EVB uses VLANs or Q-in-Q tagging between the hypervisor and the physical switch. They introduced a new protocol called VSI that uses VDP as its discovery protocol.

The protocol runs between the virtual switch in the hypervisor and the adjacent physical switch, enabling the hypervisor to request information (for example, upon VM move) from the physical switch. EVB follows two paths a) 802.1qbg and b) 802.1qbh. 802.1qbg is also called VEPA (Virtual Ethernet Port Aggregation), and 802.1qbh is also known as VN-Tag (Cisco products support VN-Tag). Both are running in parallel and attempt to provide consistent control for VMs.

Limit core flooding

To reduce flooding in the network core, you need a protocol between the switches that allows them to exchange information about which VLANs are in use. Cisco uses VTP and designs it carefully. There is a standard layer 2 messaging protocol called Multiple VLAN Registration Protocol (MVRP), but many vendors do not implement it.

It automates the creation and deactivation of VLANs by allowing switches to register and de-register VLAN identifiers. Unlike VTP, it does not use a “client” – “server” model. Instead, MVRP advertises VLAN information over 802.1q trunks to connected switches with MVRP enabled on the same interface. The neighboring switch receives the MVRP information and builds a dynamic VLAN table. MVRP is supported on Juniper Networks MX Series routers and EX Series switches.

Virtual switches have become indispensable components in modern network infrastructures. Their ability to enhance network performance, simplify management processes, and provide advanced security features make them essential for organizations of all sizes. By leveraging the benefits and features of virtual switches, network administrators can create robust and efficient networks, enabling seamless connectivity and optimizing overall network performance.

Closing Points on Virtual Switching

Virtual switching involves the emulation of a network switch within a software environment, allowing multiple virtual machines (VMs) to connect and communicate as if they were on a physical network. Unlike traditional hardware switches, virtual switches operate within the hypervisor layer, providing a bridge for data packets between VMs and the external network. This virtualization not only reduces the need for physical hardware but also streamlines the management of network resources.

One of the foremost advantages of virtual switching is its unparalleled scalability. Organizations can easily add or remove VMs without the constraints of physical infrastructure, adapting swiftly to changing demands. Moreover, virtual switches enhance network security by isolating traffic between VMs, reducing the risk of unauthorized access. The centralized management offered by virtual switching simplifies network configuration, monitoring, and troubleshooting, making it an indispensable tool for IT administrators.

As cloud computing becomes the norm, virtual switching plays a critical role in supporting cloud infrastructure. It enables the dynamic allocation of resources, ensuring optimal performance and reliability for cloud-based applications. By facilitating smooth data transfer between cloud instances, virtual switching enhances the agility and efficiency of cloud services, catering to the needs of businesses and users alike.

Despite its numerous benefits, virtual switching is not without challenges. Organizations must contend with issues related to network latency, packet loss, and compatibility with existing hardware and software. Additionally, the complexity of managing virtual networks requires skilled IT professionals to ensure optimal performance and security. Careful planning and implementation are essential to harness the full potential of virtual switching.

Summary: Virtual Switch

In today’s digital age, virtual switching has emerged as a transformative technology, revolutionizing how we connect and communicate. From data centers to networking infrastructure, virtual switching has paved the way for unprecedented flexibility and efficiency. This blog post delved into virtual switching, exploring its benefits, working principles, and potential applications.

Understanding Virtual Switching

Virtual switching is the process of emulating network switches using software. Unlike traditional physical switches, virtual switches exist purely in the virtual realm, allowing for dynamic configuration and management. By abstracting the hardware layer, virtual switching enables greater scalability, agility, and cost-effectiveness.

How Virtual Switching Works

Virtual switches operate within hypervisors or virtualization platforms, intermediaries between virtual machines (VMs) and the physical network infrastructure. They leverage software-defined networking (SDN) principles to facilitate network traffic flow, applying policies and routing packets between VMs or external networks. Through advanced algorithms and protocols, virtual switches ensure efficient data transmission and network security.

Benefits and Applications of Virtual Switching

Enhanced Flexibility: Virtual switching liberates organizations from the constraints of physical hardware. It allows for seamless migration of VMs across hosts, enabling load balancing, resource optimization, and high availability. This flexibility empowers businesses to adapt and scale their networks with ease.

Improved Efficiency: The dynamic nature of virtual switches streamlines network management and reduces operational complexity. Administrators can configure and provision virtual networks on demand, eliminating the need for manual hardware reconfiguration and resulting in significant time and cost savings.

Network Virtualization: Virtual switching forms the foundation of network virtualization, enabling the creation of virtual networks, overlays, and logical partitions. By abstracting the network layer, organizations can achieve multi-tenancy, isolate traffic, and enhance security. This technology has found applications in cloud computing, software-defined data centers, and network function virtualization.

Challenges and Considerations

While virtual switching offers numerous advantages, there are also some drawbacks. Factors such as network latency, scalability, and compatibility with existing infrastructure must be carefully evaluated. Additionally, security measures, such as implementing virtual firewalls and access controls, become crucial in protecting virtual networks from potential threats.
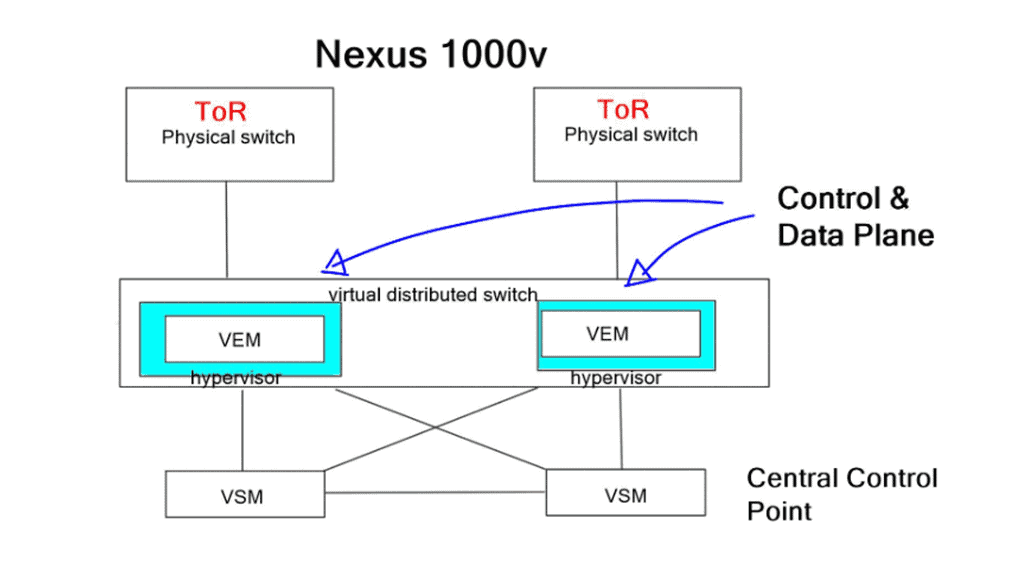
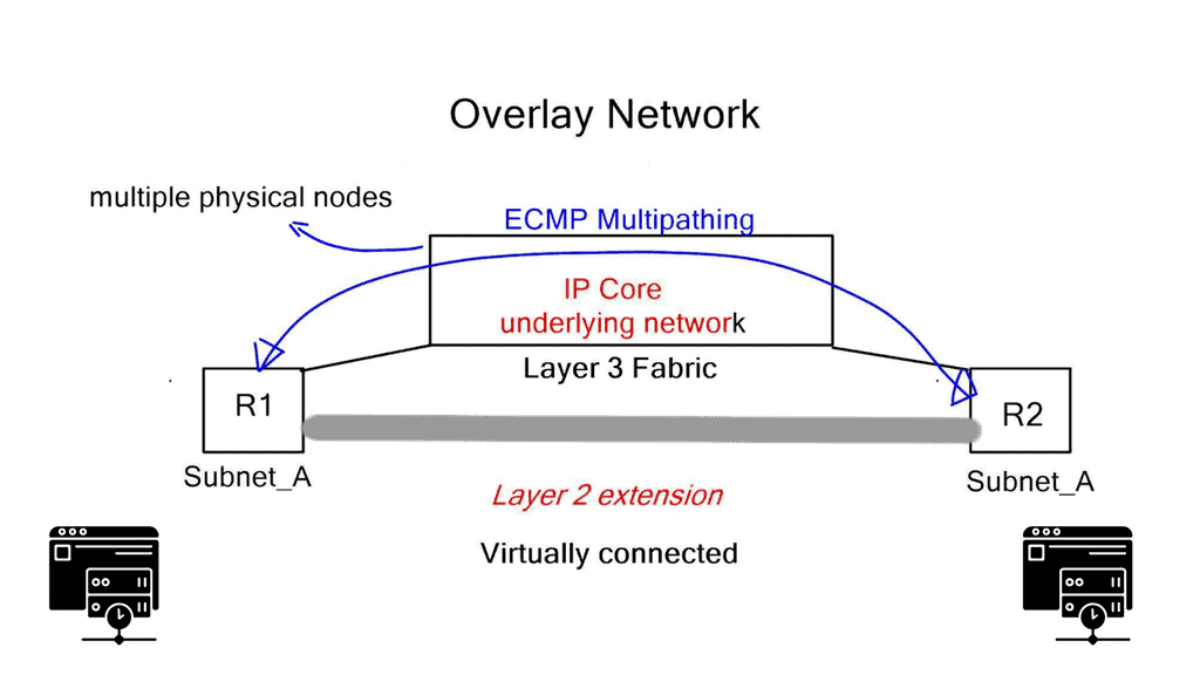
Conclusion

In conclusion, virtual switching has ushered in a new era of connectivity, transforming the networking landscape. Its ability to provide flexibility, efficiency, and network virtualization has made it a vital component of modern IT infrastructure. As technology continues to evolve, virtual switching will play a pivotal role in shaping the future of networking.

opencontrail

OpenContrail

OpenContrail

In today's fast-paced world, where cloud computing and virtualization have become the norm, the need for efficient and flexible networking solutions has never been greater. OpenContrail, an open-source software-defined networking (SDN) solution, has emerged as a powerful tool. This blog post explores the capabilities, benefits, and significance of OpenContrail in revolutionizing network management and delivering enhanced connectivity in the cloud era.

OpenContrail, initially developed by Juniper Networks, is an open-source SDN platform offering comprehensive network capabilities for cloud environments. It provides a scalable and flexible network infrastructure that enables automation, network virtualization, and secure multi-tenancy across distributed cloud deployments.

OpenContrail, an open-source network virtualization platform, is designed to simplify the management and orchestration of virtual networks. Built on well-established technologies such as OpenStack and SDN, it provides a comprehensive set of tools and APIs to create and manage virtualized network services. With OpenContrail, organizations can achieve greater scalability, security, and performance while reducing operational complexities.

Virtual Network Overlays: OpenContrail leverages virtual network overlays to create isolated and secure network segments, allowing for seamless multi-tenancy and network segmentation.

Network Policy and Security: It offers fine-grained network policies to control traffic flow, implement access control, and enforce security measures at the virtual network level.

Analytics and Monitoring: OpenContrail provides advanced analytics and monitoring capabilities, allowing administrators to gain insights into network performance, troubleshoot issues, and optimize resource allocation.

Cloud Service Providers: OpenContrail empowers cloud service providers to deliver scalable and secure network services to their customers. It enables seamless provisioning of virtual networks, ensuring high-performance connectivity and efficient resource utilization.

Enterprise Networks: Enterprises can leverage OpenContrail to build agile and flexible network infrastructures. It simplifies network management, enables seamless integration with existing infrastructure, and provides enhanced security measures.

Internet of Things (IoT): With the proliferation of IoT devices, OpenContrail offers a robust solution for managing and securing large-scale IoT deployments. It enables efficient communication between devices, ensures data privacy, and provides centralized control over IoT network resources.

OpenContrail proves to be a groundbreaking solution in the realm of network virtualization. Its feature-rich architecture, open-source nature, and diverse real-world applications make it an invaluable tool for organizations seeking to optimize network performance, enhance security, and embrace the future of virtualized networks.

Highlights: OpenContrail

Understanding OpenContrail

OpenContrail is an open-source software-defined networking (SDN) solution that enables the creation and management of virtual networks. It provides a scalable and flexible networking platform that simplifies network provisioning, enhances security, and optimizes network performance. By leveraging OpenContrail, organizations can effectively address the challenges posed by traditional networking approaches.

**Key Features and Benefits**

OpenContrail offers a wide range of powerful features that set it apart from traditional networking solutions. One of its key features is network virtualization, which allows the creation of isolated virtual networks within a physical network infrastructure.

This enables organizations to achieve greater agility and scalability, as well as efficient resource utilization. Additionally, OpenContrail provides advanced security measures, including micro-segmentation, that help protect sensitive data and prevent unauthorized access.

**Use Cases and Industry Applications**

OpenContrail is versatile and can be applied across various industries and use cases. In the telecommunications sector, it supports network slicing and virtual network functions (VNFs), crucial for deploying 5G networks. Enterprises use OpenContrail to create agile and scalable cloud environments, facilitating faster application deployment and improving overall operational efficiency.

Additionally, OpenContrail’s robust security features make it a preferred choice for sectors that require stringent data protection measures, such as finance and healthcare. By providing micro-segmentation and advanced threat detection, OpenContrail helps organizations safeguard their sensitive information.

Open-source network virtualization platform

OpenContrail is an open-source network virtualization platform that enables the creation of virtual networks overlaying physical infrastructure. It provides a scalable and flexible solution for managing network resources, improving security, and enhancing overall network performance. By decoupling the network control plane from the data plane, OpenContrail brings a new level of agility and efficiency to network operations.

1. Virtual Network Creation: OpenContrail allows the creation of virtual networks, each with its own isolated environment, policies, and routing tables. This enables organizations to achieve multi-tenancy and securely isolate their applications and workloads.

2. Network Automation and Orchestration: With OpenContrail, network provisioning and management become automated and orchestrated. This reduces manual configuration efforts and brings more consistency and reliability to network operations.

3. Enhanced Security: OpenContrail provides advanced security features such as micro-segmentation, distributed firewalling, and traffic isolation. These capabilities ensure that applications and data remain protected and isolated, even in complex and dynamic network environments.

Understanding OpenContrail components

Controller Node: At the heart of OpenContrail lies the Controller Node, which acts as the brain of the network. It is responsible for managing and orchestrating all the network services, including configuration, control, and analytics. Through its intuitive and user-friendly interface, network administrators can easily define and enforce policies, monitor network performance, and troubleshoot issues.

vRouter: The vRouter, short for virtual router, is a critical component of OpenContrail that ensures efficient packet forwarding within the network. By combining the power of virtualization and routing, the vRouter enables seamless communication between virtual machines and physical hosts. It provides advanced networking capabilities, such as firewalling, NAT, and VPN, while ensuring high performance and scalability.

Analytics Node: To gain valuable insights into network behavior and performance, OpenContrail incorporates an Analytics Node. This component collects and analyzes network data, generating comprehensive reports and metrics. Network operators can leverage this information to optimize network utilization, identify bottlenecks, and proactively address potential issues. The Analytics Node plays a crucial role in ensuring the reliability and efficiency of the entire network infrastructure.

Web User Interface: OpenContrail offers a user-friendly Web User Interface (UI) that simplifies network management and configuration. With its intuitive design and powerful functionalities, network administrators can easily define network topologies, set up policies, and monitor network performance in real time. The Web UI provides a centralized platform for managing the entire network infrastructure, making deploying, scaling, and maintaining OpenContrail deployments easier.

The traditional network vs. SDN network

In a traditional network, each switch/router must be programmed individually because applications are loaded. These applications could include a load balancer, intrusion detection, monitoring, or Voice over IP (VoIP). Based on local logic, each switch/router decides where to route packets as traffic flows through the network. Changing applications or flows in this network requires systematically programming each switch/router.

A traditional network includes both a control plane and a forwarding plane. There are also applications loaded on each device, which must be configured separately.

In an SDN network, a switch/router is not connected to any applications or intelligence. By centralized control of all devices, the network becomes programmable. A controller interfaces with applications, which are then executed across a network. Traffic flows are now supervised by a centralized controller that distributes and manages a flow table for each switch/router. Several factors can be used to define very flexible flow tables.

The flow table also collects statistics, which are fed up to the controller. This improves both visibility and control of the network because issues are immediately reported to the controller, which, in turn, can make immediate adjustments across the entire network.

The role of The VM

Virtual machines have been around for a long time, but we are beginning to spread our computing workloads in several ways. When you throw in docker containers and bare metal servers, networking becomes more interesting. Network challenges arise when all these components require communication within the same subnet, access to Internet gateways, and Layer 3 MPLS/VPNs.

As a result, data center networks are moving towards IP underlay fabrics and Layer 2 overlays. Layer 3 data plane forwarding utilizes efficient Equal-cost multi-path routing (ECMP), but we lack Layer 2 multipathing by default. Now, similar to an SD WAN overlay approach, we can connect dispersed layer 2 segments and leverage all the good features of the IP underlay. To provide Layer 2 overlays and network virtualization, Juniper has introduced an SDN platform called Junipers OpenContrail in direct competition with

Virtualization

For additional pre-information, you may find the following post of use.

  1. ACI Cisco
  2. Network Traffic Engineering
  3. Spine Leaf Architecture
  4. IP Forwarding
  5. SDN Data Center
  6. Network Overlays
  7. Application Traffic Steering
  8. What is BGP Protocol in Networking

Highlights: OpenContrail

Key Features and Benefits:

Network Virtualization:

OpenContrail leverages network virtualization techniques to provide isolated virtual networks within a shared physical infrastructure. It offers a logical abstraction layer, enabling the creation of virtual networks that operate independently, complete with their own routing, security, and quality of service policies. This approach allows for the efficient utilization of resources, simplified network management, and improved scalability.

Secure Multi-Tenancy:

OpenContrail’s security features ensure tenants’ data and applications remain isolated and protected from unauthorized access. It employs micro-segmentation to enforce strict access control policies at the virtual machine level, reducing the risk of lateral movement within the network. Additionally, OpenContrail integrates with existing security solutions, enabling the implementation of comprehensive security measures.

Intelligent Automation:

OpenContrail automates various network provisioning, configuration, and management tasks, reducing manual intervention and minimizing human errors. Its programmable API and centralized control plane simplify the deployment of complex network topologies, accelerate service delivery, and enhance overall operational efficiency.

Scalability and Flexibility:

OpenContrail’s architecture is designed to scale seamlessly, supporting distributed cloud deployments across multiple locations. It offers a highly flexible solution that can adapt to changing network requirements, allowing administrators to dynamically allocate resources, establish new connectivity, and respond to evolving business needs.

OpenContrail in Practice:

OpenContrail has gained significant traction among cloud providers, service providers, and enterprises seeking to build robust, scalable, and secure networks. Its open-source nature has facilitated its adoption, encouraging collaboration, innovation, and customization. OpenContrail’s community-driven development model ensures continuous improvement and the availability of new features and enhancements.

opencontrail
Diagram: OpenContrail.

Highlighting Junipers OpenContrail

OpenContrail is an open-source network virtualization platform. The commercial controller and open-source product are identical; they share the same checksum on the binary image. Maintenance and support are the only difference. Juniper decided to open source to fit into the open ecosystem, which wouldn’t have worked in a closed environment.

OpenContrail offers features similar to VMware NSX, can apply service chaining and high-level security policies, and provides connections to Layer 3 VPNs for WAN integration. OpenContrail works with any hardware, but integration with Juniper’s product sets offers additional rich analytics for the underlay network.

Underlay and overlay network visibility are essential for troubleshooting. You need to look further than the first header of the packet; you need to look deeper into the tunnel to understand what is happening entirely. 

Network virtualization – Isolated networks

With a cloud architecture, network virtualization gives the illusion that each tenant has a separate isolated network. Virtual networks are independent of physical network location or state, and nodes within the physical underlay can fail without disrupting the overlay tenant. A tenant may be a customer or department, depending if it’s a public or private cloud.

The virtual network sits on top of a physical network, the same way the compute virtual machines sit on top of a physical server. Virtual networks are not created with VLANs; Contrail uses a virtual overlay network system for multi-tenancy and cross-tenant communication. Many problems exist with large-scale VLAN deployments for multi-tenancy in today’s networks.

They introduce a lot of states in the physical network, and the Spanning Tree Protocol (STP) also introduces well-documented problems. There are technologies (THRILL, SPB) to overcome these challenges, but they add complexity to the design of the network.

Service Chaining

Customers require the ability to apply policy at virtual network boundaries. Policies may include ACL and stateless firewalls provided within the virtual switch. However, once you require complicated policy pieces between virtual networks, you need a more sophisticated version of policy control and orchestration called service chaining. Service chaining applies intelligent services between traffic from one tenant to another.

For example, if a customer requires content caching and stateful services, you must introduce additional service appliances and force next-hop traffic through these appliances. Once you deploy a virtual appliance, you need a scale-out architecture.

The ability to Scale-out

Scale-out is the ability to instantiate multiple physical and virtual machine instances and load balance traffic across them. Customers may also require the ability to connect with different tenants in dispersed geographic locations or to workloads in a remote private cloud or public cloud. Usually, people build a private cloud for the norm and then burst into a public cloud. 

Juniper has implemented a virtual networking architecture that meets these requirements. It is based on well-known technology, MPLS/layer 3 VPN. MPLS/layer 3 VPN is the base for Juniper designs.

MPLS Overlay

Virtual Network Implementation

A – MPLS Overlay

The SDN controller is responsible for the networking aspects of virtualization. When creating virtual networks, initiate the Northbound API and issue an instruction that attaches the VM to the VN. The network responsibilities are delegated from Cloudstack or OpenStack to Contrail. The Contrail SDN controller automatically creates the overlay tunnel between virtual machines. The overlay can be either an MPLS overlay style with MPLS-over-GRE, MPLS-over-UDP, or VXLAN. 

L3VPN for routed traffic and EVPN for bridged traffic

Juniper’s OpenContrail is still a pure MPLS overlay of MPLS/VPN, using L3VPN for routed traffic and EVPN for bridged traffic. Traffic forwarding between end nodes has one MPLS label (VPN label), but they use various encapsulation methods to carry labeled traffic across the IP fabric. As mentioned above, this includes MPLS-over-GRE – a traditional encapsulation mechanism, MPLS-over-UDP – a variation of MPLS-over-GRE that replaces the GRE headers with UDP headers. MPLS-over-VXLAN uses VXLAN packet format but stores the MPLS label in the Virtual Network Identifier (VNI) field.

B – The forwarding plane

The forwarding plane takes the packet from the VM and gives it to the “Vrouter,” which does a lookup and determines if the destination is a remote network. If it is, it encapsulates the packet and sends it across the tunnel. The underlay that sites between the workloads forward is based on tunnel source and destination only.

No state belongs to end hosts ‘VMs, MAC addresses, or IPs. This type of architecture gives the Core a cleaner and more precise role. Generally, as a best practice, keeping “state” in the Core is a lousy design principle.

C – Northbound and southbound interfaces

To implement policy and service chaining, use the Northbound Interface and express your policy at a high level. For example, you may require HTTP or NAT and force traffic via load balancers or virtual firewalls. Contrail does this automatically and issues instructions to the Vrouter, forcing traffic to the correct virtual appliance. In addition, it can create all the suitable routes and tunnels, causing traffic through the proper sequence of virtual machines.

Contrail achieves this automatically with southbound protocols, such as XMPP (Extensible Messaging and Presence Protocol) or BGP. XMPP is a communications protocol based on XML (Extensible Markup Language).

WAN Integration

Junipers OpenContrail can connect virtual networks to external Layer 3 MPLS VPN for WAN integration. In addition, they gave the controller the ability to peer BGP to gateway routers. For the data plane, they support MPLS-over-GRE, and for the control plane, they speak MP-BGP.

Contrail communicates directly with PE routers, exchanging VPNv4 routes with MP-BGP and using MPLS-over-GRE encapsulation to pass IP traffic between hypervisor hosts and PE routers. Using standards-based protocols lets you choose any hardware appliance as the gateway node.

mpls overaly

This data and control plane makes integration to an MPLS/VPN backbone a simple task. First, MP-BGP between the controllers and PE-routers should be established. Inter-AS Option B next hop self-approach should be used to demonstrate some demarcation points.

OpenContrail has emerged as a game-changer in software-defined networking, empowering organizations to build agile, secure, and scalable networks in the cloud era. With its advanced features, such as network virtualization, secure multi-tenancy, intelligent automation, and scalability, OpenContrail offers a comprehensive solution that addresses the complex networking challenges of modern cloud environments.

As the demand for efficient and flexible network management continues to rise, OpenContrail provides a compelling option for organizations looking to optimize their network infrastructure and unlock the full potential of the cloud.

Summary: OpenContrail

OpenContrail is a powerful open-source software-defined networking (SDN) solution revolutionizing network management and connectivity. In this blog post, we will explore its key features, benefits, and use cases and showcase how it empowers organizations to build robust and scalable networks.

Understanding OpenContrail

OpenContrail, developed by Juniper Networks, is an open-source SDN controller that provides network virtualization and automation capabilities. It is a single control point for managing and orchestrating network resources, enabling organizations to simplify network operations and enhance flexibility. By decoupling the network control plane from the underlying physical infrastructure, OpenContrail brings agility and scalability to modern networks.

Key Features of OpenContrail

OpenContrail offers a wide range of features, making it a preferred choice for network administrators. Some notable features include:

1. Virtual Network Overlay: OpenContrail creates virtual network overlays, allowing multiple virtual networks to coexist on a shared physical infrastructure. This isolation ensures enhanced security and enables efficient resource utilization.

2. Policy-Driven Automation: With policy-driven automation, network administrators can define and enforce network policies and access controls across the infrastructure. OpenContrail simplifies the management and enforcement of complex policies, reducing operational overhead.

3. Analytics and Monitoring: OpenContrail provides extensive analytics and monitoring capabilities, offering real-time insights into network traffic, performance, and security. These insights help administrators optimize network resources and troubleshoot issues effectively.

Use Cases of OpenContrail

OpenContrail finds applications in various use cases across industries. Some prominent use cases include:

1. Cloud Infrastructure: OpenContrail enables cloud service providers to build and manage scalable and secure cloud infrastructures. It facilitates seamless integration with popular cloud platforms and offers rich networking capabilities.

2. Data Centers: OpenContrail simplifies network management in data center environments. It provides dynamic workload placement, automated provisioning, and seamless connectivity between virtual machines and containers, ensuring efficient resource utilization.

3. Multi-Cloud Networking: OpenContrail supports multi-cloud networking, allowing organizations to connect and manage multiple cloud environments securely. It provides seamless connectivity, consistent policies, and centralized control across cloud providers.

Conclusion:

OpenContrail presents a game-changing solution for organizations seeking to enhance their networking capabilities. With its rich feature set, including virtual network overlays, policy-driven automation, and advanced analytics, OpenContrail empowers organizations to build scalable, secure, and agile networks. Whether it’s cloud infrastructure, data centers, or multi-cloud networking, OpenContrail is a reliable and versatile SDN solution.

OpenFlow Service Chaining

OpenFlow and SDN Adoption

OpenFlow and SDN Adoption

In the ever-evolving world of networking, new technologies and approaches continue to reshape the landscape. One such technology that has gained significant attention is OpenFlow, which forms the backbone of Software-Defined Networking (SDN). In this blog post, we will delve into the concept of OpenFlow and explore its growing adoption in the networking industry.

OpenFlow can be best described as a protocol that enables the separation of the control plane and the data plane in a network. Traditionally, network devices handled both the control and data forwarding aspects, leading to limited flexibility and scalability. With OpenFlow, the control plane is centralized in a controller, allowing for dynamic network management and programmability.

Benefits of OpenFlow: The adoption of OpenFlow brings forth a multitude of benefits. Firstly, it offers network administrators unprecedented control and visibility into the network, empowering them to efficiently manage traffic flows and implement changes on the fly. Additionally, OpenFlow promotes network programmability, enabling the development of innovative applications and services that can harness the full potential of the network infrastructure.

OpenFlow in Action: Numerous organizations and industries have recognized the potential of OpenFlow and have embraced it in their networks. For instance, data centers have leveraged OpenFlow to create virtual networks with enhanced security and improved resource allocation. Internet Service Providers (ISPs) have also adopted OpenFlow to optimize traffic routing and enhance network performance.

Challenges and Considerations: While OpenFlow holds great promise, it is not without its challenges. One of the primary concerns is ensuring interoperability across different vendors and devices, as OpenFlow relies on a standard set of protocols and features. Additionally, network security and policy enforcement must be carefully addressed to prevent unauthorized access and protect sensitive data.

OpenFlow and SDN adoption are revolutionizing the networking industry, offering unprecedented control, programmability, and scalability. As organizations continue to recognize the benefits of OpenFlow, we can expect to see further advancements and innovations in the realm of network management and infrastructure.

Highlights: OpenFlow and SDN Adoption

Understanding OpenFlow

OpenFlow is a communication protocol that enables the separation of the control plane and the data plane in network switches. By doing so, it allows for centralized control and programmability of network devices. This revolutionary approach replaces traditional, fixed-function network devices with programmable switches, enabling more flexibility and agility in network management.

SDN provides network administrators with a holistic view of the network, allowing them to monitor and manage network traffic with granular control. This increased visibility enables better troubleshooting, efficient resource allocation, and improved security measures.

**Simplified Network Management**

With SDN, network configurations can be abstracted and managed through software, eliminating the need for manual, device-by-device configuration changes. This simplification streamlines network management, reduces human errors, and accelerates network provisioning and deployment.

The programmability of SDN allows for dynamic network provisioning and scaling, making it easier to adapt to changing network demands. Whether it’s scaling up to accommodate increased traffic or reconfiguring network paths, SDN offers unparalleled flexibility, enabling networks to evolve and grow seamlessly.

**SDN & Virtualization**

SDN opens doors to network virtualization, where multiple virtual networks can coexist on a shared physical network infrastructure. This concept enables efficient resource utilization, isolation of traffic, and improved network efficiency.

By decoupling the control plane from the data plane, SDN fosters an environment for experimentation and innovation. Developers can create and deploy custom network applications, allowing for rapid prototyping and testing of new networking concepts without disrupting the underlying infrastructure.

 **Basics of Network Virtualization**

Network virtualization involves creating a virtual network that operates independently of the underlying physical hardware. This is achieved through software-defined networking (SDN) and network functions virtualization (NFV). SDN separates the network’s control plane from the data plane, allowing for centralized management and control of network traffic. NFV, on the other hand, replaces traditional network hardware functions with software-based solutions, enabling greater flexibility and scalability.

Use Cases and Real-World Applications

A: -) OpenFlow and SDN have been found to be extensively used in various domains and industries. From data centers and cloud computing environments to enterprise networks and even telecommunications, the versatility of OpenFlow and SDN is undeniable.

B: -) They enable dynamic traffic engineering, efficient load balancing, and improved network security. Furthermore, SDN has paved the way for network function virtualization (NFV), allowing the deployment of network services as software applications rather than dedicated hardware.

Background: OpenFlow L2 Switching & VLAN Handling

Layer 2 OpenFlow switching relies on a structured pipeline where packets enter Table 0 for initial classification and then move to Table 1 for forwarding. VLAN tags play a central role in segmenting traffic, and actions such as push_vlan, pop_vlan, and set_vlan_id allow the pipeline to add, remove, or rewrite VLAN identifiers as packets traverse the network. This lab demonstrates how VLAN-aware forwarding behaves inside an SDN-driven LAN.

When a packet arrives, the switch evaluates its fields—source MAC, destination MAC, and VLAN ID—against the flow entries in each table. If a match exists, the associated actions are applied, modifying the VLAN tag or directing the packet to the correct output port. If no match is found, the packet is surfaced for further processing, allowing new flow entries to be added dynamically. This mechanism ensures the pipeline adapts to traffic patterns and VLAN requirements.

The three test cases highlight different aspects of VLAN manipulation within the OpenFlow pipeline. Test 1 shows VLAN retagging, where traffic arriving on VLAN 10 is processed and forwarded using VLAN 20. Test 2 demonstrates VLAN removal, with VLAN 30 traffic being stripped and delivered as an untagged frame. Test 3 illustrates VLAN rewriting, where an unknown VLAN 999 is converted into VLAN 20 to maintain consistent segmentation across the forwarding path.

These tests collectively show how flexible VLAN handling enables predictable forwarding in SDN-based LANs. By retagging, removing, or rewriting VLANs, the pipeline ensures that hosts receive traffic in the correct segment regardless of how packets enter the network. This approach eliminates reliance on traditional MAC learning and provides deterministic, rule-driven forwarding that scales cleanly across multi-switch topologies.

Impact on the Networking Landscape

– At its core, OpenFlow is a communications protocol that enables the separation of the control plane and the data plane in networking devices. It allows for the programmability and centralized control of network switches and routers. With OpenFlow, network administrators can dynamically manage traffic, define routing paths, and apply policies, all through a centralized controller.

– SDN takes the concept of OpenFlow further by providing a framework for network management and configuration. It abstracts the underlying network infrastructure and allows for programmability and automation through a software-based controller. SDN architectures offer flexibility, scalability, and agility, making adapting to evolving network demands easier.

– The combination of OpenFlow and SDN brings numerous benefits to network operators, administrators, and end-users. Firstly, it simplifies network management by providing a centralized view and control of the entire network.

– This simplification leads to enhanced network visibility, easier troubleshooting, and faster deployment of new services. Additionally, OpenFlow and SDN enable network virtualization, allowing for the creation of logical networks decoupled from the physical infrastructure.

The SDN Layers

The Application Layer:

As its name suggests, this layer includes network applications. Examples of these applications include communication applications, such as VoIP prioritization, and security applications, such as firewalls. Also included in this layer are utilities and network services.

Switches and routers traditionally handled these applications. SDN simplifies their management by offloading them. In addition, companies can save a lot of money by stripping down the hardware.

The Control Layer:

Switches and routers are now controlled by a centralized control plane, which allows the network to be programmed. As an open-source network protocol, OpenFlow has become the industry standard despite Cisco’s OpenFlow variant.

The Infrastructure Layer:

This layer includes data, switches, and routers. Traffic is moved according to flow tables. SDN leaves this layer essentially unchanged since routers and switches still move packets. The main difference is the centralization of traffic flow rules. However, the intelligence of vendor devices is not stripped away.

The API provides centralized control of SDN for large network providers to protect their intellectual property. However, the cost of generic packet-forwarding devices is much lower than traditional networking equipment.

SDN and OpenFlow

A Programmable Network

Developers have made it possible for network administrators to create “slices” that allow generic networking hardware to support multiple configurations by adding a virtualization layer between the control system and the hardware layer. It resembles how a hypervisor can run a virtual machine (VM) on a single server. Using SDN, an administrator can create different rules and applications for various groups of users.

Because most applications are not installed on the devices, SDN enables the network to appear as one big switch/router. There could be three devices on the network or 30,000. They are all the same as centralized applications. (Some applications are just nodes on the network.) Therefore, upgrades, changes, additions, and configurations are much more accessible.

The role of OpenFlow

Firstly, the basis of the SDN adoption report is the OpenFlow protocol, an existing technology derived from academic labs. Its origins can be traced back to 2006 when Martin Casado, part of the “Clean Slate” program, developed Ethane. They were trying to figure out ways to manage the network states via a centrally managed global policy.

The idea that networks are dynamic and non-symmetrical poses challenges in keeping track of their state to enforce programmability. The program has stopped but produced several follow-up programs, including OpenFlow and SDN.

SDN OpenFlow is not revolutionary new. Similar ideas have been available, and previous projects have tried to solve the same problems OpenFlow is trying to solve today. Besides the central viewpoint use case, whatever you can do with OpenFlow today is possible with Policy-Based Routing (PBR) and ACL. The problem is that these tools are clumsy and do not scale well.

What is OpenFlow

You may find the following useful for pre-information:

  1. Virtual Overlay Network
  2. SDN Router
  3. What is OpenFlow
  4. BGP SDN
  5. SDN BGP
  6. Hyperscale Networking
  7. SDN Data Center

OpenFlow and SDN Adoption

What is OpenFlow?

OpenFlow is an open standard that enables the separation of the control plane and the data plane in network devices. It allows network administrators to centrally control and manage the behavior of network switches and routers, resulting in increased network programmability, flexibility, and scalability. OpenFlow provides a standardized protocol that facilitates communication between the control and data planes, enabling the network to be programmed and controlled through software.

Understanding SDN Adoption:

SDN is a paradigm shift in network architecture that leverages OpenFlow and other technologies to virtualize and abstract network resources. With SDN, the control plane is decoupled from the underlying physical infrastructure, allowing network administrators to configure and manage networks dynamically through a centralized controller. This centralized control simplifies network operations, enhances automation, and creates innovative network services.

The use of APIs:

Besides the network abstraction, the SDN architecture will deliver a set of APIs that streamline the implementation of standard network services. These network services include routing, security, access control, and traffic engineering. Consequently, we can achieve exceptional programmability, automation, and network control, enabling us to build highly scalable and flexible networks that readily adapt to changing business needs. Then, we have OpenFlow and the SDN story. OpenFlow is the first standard interface explicitly designed for SDN, providing high-performance and granular traffic control across multiple networking devices.

**Benefits of OpenFlow and SDN Adoption**

The adoption of OpenFlow and SDN comes with numerous benefits for organizations of all sizes:

1. Enhanced Network Programmability: OpenFlow and SDN enable network administrators to program and control networks through software, making implementing new network services and policies easier.

2. Increased Flexibility and Scalability: SDN allows for dynamic network reconfiguration and resource allocation, ensuring networks can adapt to changing requirements and scale efficiently.

3. Centralized Network Management: With SDN, network administrators can manage and configure multiple network devices from a centralized controller, simplifying network operations and reducing the complexity of managing traditional networks.

4. Improved Network Security: SDN facilitates the implementation of granular security policies, enabling network administrators to quickly detect and respond to security threats, enhancing overall network security.

**Challenges and Considerations**

While OpenFlow and SDN offer significant advantages, their adoption comes with a few challenges that organizations need to address:

1. Compatibility: Not all network devices and vendors fully support OpenFlow and SDN, requiring organizations to consider device compatibility carefully before implementation.

2. Skillset and Training: SDN introduces new concepts and requires network administrators to acquire skills and knowledge to deploy and manage SDN-based networks effectively.

3. Transition from Legacy Infrastructure: Migrating from traditional networking solutions to SDN-based architectures requires careful planning and a phased approach to minimize disruptions and ensure a smooth transition.

Starting Points for SDN Adoption

SDN Architectures and OpenFlow

SDN architectures and OpenFlow offer several advantages. You can influence traffic forwarding behavior at a more granular flow level. A holistic view instead of a partial view of distributed devices simplifies the network. Traffic engineering with SDN becomes easier to implement when you have a centralized view; this is how Google implemented SDN. Google has two network backbones: an Internet-facing backbone and a data center backbone. 

They noticed that the cost/bit was not decreasing as the network grew. It was doing the opposite. Their solution was to implement a centralized controller and manage the WAN as a fabric, not as a collection of individual nodes.

SDN adoption report: Virtual switching fabric

SDN architectures allow networks to move from loosely coupled systems to a virtual switching fabric. One extensive flat virtualized network that appears and can be managed as a single switch has many operational advantages. The switch fabric consists of multiple physical nodes but behaves like one big switch. For example, a port on any underlying switch fabric nodes or virtual switch appears as a port to the single switching fabric.

The entire data plane becomes an abstraction. By employing this architecture, we manage the data plane as a whole entity instead of a set of loosely coupled connected devices. If we study existing networks, the control and data planes are distributed to the same locations. No central point controls individual nodes, resulting in complex cross-network interactions.

sdn adoption

Open Shortest Path First (OSPF)

Open Shortest Path First (OSPF) calculates the shortest path tree from each node to every other node. Each OSPF neighbor must establish an adjacency and build and synchronize the link-state databases (LSB). The complexity can be reduced by designing OSPF areas with ABRs but by sacrificing some precision of route information. Imagine that every node reports and synchronizes its LSB to a central controller with an OSPF SDN application instead of individual nodes.

The controller can perform the Shortest Path First (SPF) calculation and directly update each node’s forwarding information base (FIB). The network now becomes programmable. While it does bring advantages, the laws of physics have not changed.

OpenFlow does not decrease latency or let you push more bits through a link. It does, however, let you better manage and control your network. It removes the box-by-box mentality and introduces automation and programmability.

SDN CONTROLLERExample Routing Technology with OSPF

#### Introduction to OSPFv3

In the realm of networking, efficient and reliable routing protocols are crucial for ensuring seamless data transmission. One such protocol that has gained prominence is OSPFv3 (Open Shortest Path First version 3). This blog post will delve into the intricacies of OSPFv3, exploring its features, benefits, and the role it plays in modern networks.

#### Understanding OSPFv3 Basics

OSPFv3 is an evolution of the OSPF protocol, specifically designed to support IPv6. While it retains the core functionalities of its predecessor, OSPFv2, OSPFv3 brings enhancements that make it more suitable for IPv6-based networks. Unlike OSPFv2, which operates at the network layer, OSPFv3 is designed to work with both IPv4 and IPv6, offering greater flexibility and future-proofing networks as organizations transition to IPv6.

#### Key Features of OSPFv3

One of the standout features of OSPFv3 is its capability to support multiple instances per link. This means that different OSPFv3 processes can operate over the same network link, providing advanced network segmentation and improved routing efficiency. Additionally, OSPFv3 introduces a simplified header format, reducing overhead and enhancing performance. The protocol also supports address families, allowing for more granular control over routing decisions.

#### OSPFv3 vs. OSPFv2: What’s the Difference?

While OSPFv2 and OSPFv3 share a common heritage, there are notable differences between them. OSPFv3’s support for IPv6 is the most significant distinction, but it also includes changes in LSA (Link State Advertisement) types and packet structures. Furthermore, OSPFv3 operates with a more modular approach, separating topology information from routing information, thereby improving scalability and efficiency in complex network environments.


Do you think OpenFlow will be derailed?

SDN OpenFlow has come up against some market adoption barriers, such as silicon challenges and numerous vendor-specific extensions. In addition, the lack of conformance tests has led to some inconsistencies. It depends on how you define it. To explain it, you need to know what it is not. It is not a controller or a forwarding switch but a communication between the two.

It has a distinct place in the SDN architecture and does not run anywhere except between the control (controller) and the data plane, such as the OVS bridge acting as the switch infrastructure. SDN OpenFlow is also not alone in this space; other technologies provide control and data plane communications, such as BGP, Open vSwitch Database Management Protocol (OVSDB), NETCONF, and Extensible Message and Presence Protocol (XMPP).

Juniper’s OpenContrail uses XMPP.

SDN ADOPTION

It is evolving, and emerging technologies are sometimes slow to adopt. For example, in the early days of Novell networks, there were 4-frame types. Likewise, OpenFlow is changing and adapting as time progresses. For example, the original version of OpenFlow did not have multiple flow tables; now, versions 1.3 and 1.4 have multiple tables with various actions and many additional features.

**Will it be used for program forwarding paths instead of BGP?** 

Probably not, but it will augment BGP and other traditional technologies. It is not strictly a YES or NO answer as the SDN adoption falls into two buckets: one with OpenFlow and one without. Take the IPv6 adaptations as the IPv4 “replacement.” There was a “D” day of IPv4 address exhaustion, but IPv4 is still widely used. New “transition” mechanisms such as 6to4 and NAT64 are still widely deployed. It is the same with SDN and OpenFlow.

Example IPv6 Technology: NAT64

**How NAT64 Works**

NAT64, short for Network Address Translation from IPv6 to IPv4, acts as a translator between IPv6 and IPv4. It allows IPv6 clients to access IPv4 services by translating IPv6 addresses into IPv4 addresses and vice versa. This is achieved through a NAT64 gateway, which facilitates the exchange of data between the two different protocols. The gateway assigns an IPv6 prefix for the IPv4 address pool, enabling seamless communication across the network. Understanding this process is vital for network administrators tasked with managing hybrid networks during the transition phase.

**Benefits of Implementing NAT64**

Implementing NAT64 offers numerous benefits for organizations and network administrators. Firstly, it aids in the gradual transition to IPv6 by allowing IPv6-only devices to access IPv4 content. This is particularly beneficial for mobile networks and new internet service providers aiming to future-proof their infrastructure. Additionally, NAT64 reduces the need for dual-stack configurations, which can be complex and resource-intensive. By simplifying network configurations, NAT64 helps cut operational costs and streamline network management.

There will be ways to make traditional networks communicate with SDN and OpenFlow. BGP was invented as an EBGP, but people use EBGP Internal in their network. BGP is also used as an SDN control plane. It will be the case that you have controllers that provide automation and a holistic view but can speak BGP or OSPF to program the forwarding devices. SDN migrations will come incrementally, similar to what we see with IPv4 and IPv6

The lack of clarity in the controller space has limited OpenFlow’s progress. However, the controller market is consolidating now, which gives users a clear path forward. This emergence is a good thing and will move OpenFlow forward. Maintaining SDN applications on different controllers is a dead end, but now that OpenDaylight is emerging, we have controller unity.

A market with numerous open-source controllers would make SDN application development difficult. There will always be business drivers for proprietary controllers serving a particular niche and corner case problems the open community did not invest in. Even today, specialized UNIX platforms exist when you look at open Linux. Similarly, this adoption of technology will be evident for OpenFlow controllers.

Example BGP Technology: EBGP and IBGP

### Understanding BGP: The Basics

Before diving into the preferences, it’s crucial to understand what BGP is. Border Gateway Protocol (BGP) is a standardized exterior gateway protocol designed to exchange routing and reachability information among autonomous systems (AS) on the internet. It is key to ensuring data finds the most efficient path across the complex web of networks.

– **eBGP vs. iBGP:** eBGP is used for communication between different autonomous systems, while iBGP is used within the same autonomous system. This distinction is fundamental in understanding their roles and why eBGP is often preferred.

### The Preference for eBGP: Key Reasons

1. **Policy Control and Flexibility:** eBGP allows for more granular policy control, enabling network administrators to implement routing policies that align with business objectives. This flexibility is less pronounced in iBGP, which is typically used to propagate routes within an AS.

2. **Route Propagation and Stability:** eBGP sessions are generally between routers in different administrative domains, which inherently adds a layer of stability and security in route propagation. eBGP routes are often considered more reliable due to the distinct boundaries they operate across.

3. **Loop Prevention Mechanics:** eBGP inherently prevents routing loops by default, due to its AS-path attribute which records the path that routing information has traversed. iBGP requires additional mechanisms, such as route reflectors or confederations, to handle loop prevention efficiently.

### Practical Implications for Network Administrators

Understanding the preference for eBGP over iBGP can significantly impact how network administrators design and manage networks. For instance, leveraging eBGP for inter-AS communication can lead to more robust and secure network architectures. Additionally, the ability to set preferences for route selection can optimize traffic flow and enhance network performance.

The Future of OpenFlow and SDN:

The adoption of OpenFlow and SDN has gained significant momentum in recent years, and the future looks promising for these technologies. With the increasing demand for flexible, scalable, and programmable networks, OpenFlow and SDN are vital in deploying 5G networks, Internet of Things (IoT) applications, and network virtualization.

OpenFlow and SDN adoption revolutionizes network infrastructure, offering increased programmability, flexibility, and centralized management. While challenges exist, the benefits of OpenFlow and SDN far outweigh the drawbacks.

As organizations continue to embrace digital transformation, OpenFlow and SDN will continue to shape the future of networking, enabling agile, scalable, and secure networks that can adapt to the evolving needs of modern businesses.

Closing Points on SDN and OpenFlow

In the realm of modern networking, OpenFlow and Software-Defined Networking (SDN) stand as pioneers of a transformative journey. Traditional networks, often rigid and complex, are evolving into more dynamic and programmable entities, thanks to these groundbreaking technologies. OpenFlow, a protocol that enables the separation of the control and data planes, is at the heart of this transformation. Combined with SDN, which offers centralized control over network devices, organizations can now manage their networks with unprecedented flexibility and efficiency.

Adopting OpenFlow and SDN brings a plethora of advantages. First and foremost, network administrators gain enhanced control and visibility over their entire network infrastructure. This centralized management simplifies the deployment of new services and reduces the time needed for troubleshooting. Additionally, the programmability of SDN allows for rapid adaptation to changing business needs, providing a competitive edge in today’s fast-paced digital landscape. Cost savings are another major benefit, as organizations can optimize resource usage and reduce hardware dependency.

While the benefits are clear, the road to adopting OpenFlow and SDN is not without its challenges. One of the primary obstacles is the need for a shift in mindset. Network engineers accustomed to traditional methods must embrace new skills and paradigms. There is also the challenge of interoperability, as integrating OpenFlow and SDN with existing systems can be complex. Security concerns, too, must be addressed, as the centralized nature of SDN can introduce new vulnerabilities if not properly managed.

Despite the challenges, many organizations have successfully adopted OpenFlow and SDN. For instance, large data centers and cloud service providers have leveraged these technologies to enhance scalability and performance. In the telecommunications sector, companies have implemented SDN to improve network traffic management and service delivery. These success stories illustrate the transformative potential of OpenFlow and SDN, providing a blueprint for others to follow.

Summary: OpenFlow and SDN Adoption

In today’s rapidly evolving technological landscape, Software-Defined Networking (SDN) and OpenFlow have emerged as game-changing innovations revolutionizing the world of networking. This blog post delves into the intricacies of SDN and OpenFlow, exploring their capabilities, benefits, and their potential to reshape the future of networking.

Understanding SDN

SDN, short for Software-Defined Networking, is a paradigm that separates the control plane from the data plane, enabling centralized network management. Unlike traditional networking approaches, SDN decouples network control, making it programmable and agile. It empowers network administrators with unprecedented flexibility and control over their infrastructure. 

Unveiling OpenFlow

At the core of SDN lies OpenFlow, a protocol that enables communication between the control and data planes. OpenFlow facilitates the flow of network packets, allowing administrators to define and manage network traffic dynamically. Providing a standardized interface promotes interoperability between different vendors’ networking equipment, fostering innovation and cost-effectiveness. 

Benefits of SDN and OpenFlow

Enhanced Network Flexibility and Scalability: SDN and OpenFlow enable network administrators to adjust network resources dynamically, optimize traffic flow, and respond to changing demands. This flexibility and scalability empower organizations to adapt swiftly to evolving network requirements, ensuring efficient resource utilization. 

Simplified Network Management: With SDN and OpenFlow, network administrators can centrally manage and orchestrate network devices, eliminating the need for manual configurations on individual devices. This centralized control simplifies network management, reduces human errors, and accelerates the deployment of new services. 

Improved Network Security: SDN’s centralized control allows for better security management. Administrators gain granular control over network access, threat detection, and response by implementing security policies and protocols at the controller level. This enhanced security posture helps safeguard critical assets and data. 

Data Center Networking: SDN and OpenFlow find extensive applications in data centers, where virtualization and cloud computing demand dynamic resource allocation and efficient traffic management. By abstracting network control, SDN facilitates seamless scalability, load balancing, and efficient utilization of data center resources.  

Campus and Enterprise Networks: In campus and enterprise networks, SDN and OpenFlow enable administrators to manage and optimize network traffic, prioritize critical applications, and quickly respond to changing user demands. These technologies also facilitate network slicing, allowing organizations to create virtual networks tailored to specific requirements. 

In conclusion, SDN and OpenFlow represent a paradigm shift in networking, offering immense potential for increased efficiency, scalability, and security. As organizations continue to embrace digital transformation, these technologies will play a pivotal role in shaping the future of networking. By decoupling network control and leveraging the power of programmability, SDN and OpenFlow empower administrators to build agile, intelligent, and future-ready networks.

OpenStack written on the keyboard button

Openstack Architecture in Cloud Computing

OpenStack Architecture in Cloud Computing

Cloud computing has revolutionized businesses' operations by providing flexible and scalable infrastructure for hosting applications and storing data. OpenStack, an open-source cloud computing platform, has gained significant popularity due to its robust architecture and comprehensive services.

In this blog post, we will explore the architecture of OpenStack and how it enables organizations to build and manage their own private or public clouds.

At its core, OpenStack comprises several interconnected components, each serving a specific purpose in the cloud infrastructure. The architecture follows a modular approach, allowing users to select and integrate the components that best fit their requirements.

OpenStack architecture is designed to be modular and scalable, allowing businesses to build and manage their own private or public clouds. At its core, OpenStack consists of several key components, including Nova, Neutron, Cinder, Glance, and Keystone. Each component serves a specific purpose, such as compute, networking, storage, image management, and identity management, respectively.

Highlights: OpenStack Architecture in Cloud Computing

Understanding OpenStack Architecture

OpenStack is an open-source cloud computing platform that allows users to build and manage cloud environments. At its core, OpenStack consists of several key components, including Nova, Neutron, Cinder, Glance, and Keystone. Each component plays a crucial role in the overall architecture, working together seamlessly to deliver a comprehensive cloud infrastructure solution.

**Core Components of OpenStack**

OpenStack is composed of several interrelated components, each serving a specific function to create a comprehensive cloud environment. At its heart lies the Nova service, which orchestrates the compute resources, allowing users to manage virtual machines and other instances.

Swift, another key component, provides scalable object storage, ensuring data is securely stored and easily accessible. Meanwhile, Neutron takes care of networking, offering a rich set of services to manage connectivity and security across the cloud infrastructure. Together, these components and others such as Cinder for block storage and Horizon for the dashboard interface, form a cohesive cloud ecosystem.

**The Benefits of OpenStack**

What makes OpenStack particularly appealing to organizations is its open-source nature, which translates to cost savings and flexibility. Without the constraints of vendor lock-in, businesses can tailor their cloud infrastructure to meet specific requirements, integrating a wide array of tools and services.

OpenStack also boasts a robust community of developers and users who contribute to its continual improvement, ensuring it remains at the forefront of cloud innovation. Its ability to scale effortlessly as an organization grows is another significant advantage, providing the agility needed in today’s fast-paced business environment.

**Why Businesses Choose OpenStack**

Businesses across various sectors are adopting OpenStack to leverage its versatility and power. Whether it’s a tech startup looking to rapidly scale operations or an established enterprise seeking to optimize its IT resources, OpenStack provides the infrastructure needed to support diverse workloads. Its compatibility with popular cloud-native technologies like Kubernetes further enhances its appeal, enabling seamless integration with modern development practices. By choosing OpenStack, organizations are equipped to tackle the challenges of digital transformation head-on.

1: – Nova – The Compute Service

Nova, the compute service in OpenStack, is responsible for managing and orchestrating virtual machines (VMs). It provides the necessary APIs and services to launch, schedule, and monitor instances. Nova ensures efficient resource allocation, enabling users to scale their compute resources as needed.

2: – Neutron – The Networking Service

Neutron is the networking service in OpenStack that handles network connectivity and addresses. It allows users to create and manage virtual networks, routers, and firewalls. Neutron’s flexibility and extensibility make it a crucial component for building complex network topologies within the OpenStack environment.

3: – Cinder – The Block Storage Service

Cinder provides block storage services in OpenStack, allowing users to attach and manage persistent storage volumes. It offers features like snapshots and cloning, enabling data consistency and efficient storage management. Cinder integrates with various storage technologies, providing flexibility and scalability in meeting different storage requirements.

4: – Glance – The Image Service

Glance acts as the image service in OpenStack, providing a repository for managing virtual machine images. It allows users to store, discover, and retrieve images, simplifying the process of deploying new instances. Glance supports multiple image formats and can integrate with various storage backends, offering versatility in image management.

Keystone – The Identity Service

Keystone serves as the identity service in OpenStack, handling user authentication and authorization. It provides a centralized authentication mechanism, enabling secure access to the OpenStack environment. Keystone integrates with existing identity providers, simplifying user management for administrators.

What is OpenStack?

OpenStack is a comprehensive cloud computing platform that enables the creation and management of private and public clouds. It provides interrelated services, including computing, storage, networking, and more. OpenStack’s open-source nature fosters collaboration and innovation within the cloud community.

Cloud computing platforms such as OpenStack are free and open standards. Both public and private clouds use infrastructure-as-a-service (IaaS) to provide users with virtual servers and other resources. In a data center, a software platform controls diverse, multi-vendor pools of processing, storage, and networking resources. In addition to web-based dashboards, command-line tools, and RESTful web services are available to manage them.

NASA and Rackspace Hosting began developing OpenStack in 2010. The OpenStack Foundation, a non-profit corporation established in September 2012[3] to promote OpenStack software and its community, managed the project as of 2012. In 2021, the foundation announced it would be renamed the Open Infrastructure Foundation. By 2018, more than 500 companies had joined the project.

**Key Features of OpenStack**

OpenStack offers a wide range of features, making it a powerful and flexible cloud solution. Some of its notable features include:

1. Scalability and Elasticity: OpenStack allows users to scale their infrastructure up or down based on demand, ensuring optimal resource utilization.

2. Multi-Tenancy: With OpenStack, multiple users or organizations can securely share the same cloud infrastructure while maintaining isolation and privacy.

3. Modular Architecture: OpenStack’s modular design allows users to choose and integrate specific components per their requirements, providing a highly customizable cloud environment.

OpenStack: The cloud operation system

– Cloud operating systems such as OpenStack are best viewed as public and private clouds, respectively. In this era of cloud computing, we are moving away from virtualization and software-defined networking (SDN). Any organization can build a cloud infrastructure using OpenStack without committing to a vendor.

– Despite being open source, OpenStack has the support of many heavyweights in the industry, such as Rackspace, Cisco, VMware, EMC, Dell, HP, Red Hat, and IBM. If a brand name acquires OpenStack, it won’t disappear overnight or lose its open-source status.

– OpenStack is also an application and toolset that provides identity management, orchestration, and metering. Despite supporting several hypervisors, such as VMware ESXi, KVM, Xen, and Hyper-V, OpenStack is not a hypervisor. Thus, OpenStack does not replace these hypervisors; it is not a virtualization platform but a cloud management platform.

– OpenStack is composed of many modular components, each of which is governed by a technical committee. OpenStack’s roadmap is determined by a board of directors driven by its community.

Openstack services

OpenStack Modularity

OpenStack is highly modular. Components provide specific services, such as instance management, image catalog management, network management, volume management, object storage, and identity management. A minimal OpenStack deployment can provision instances from images and connect them to networks. Identity management controls cloud access. Some clouds are only used for storage.

There is an object storage component and, again, an identity component. The OpenStack community does not refer to services by their functions, such as services, images, etc. Instead, these components are referred to by their nicknames. Server functions are officially called compute, but everyone calls them Nova. It’s pretty fitting since NASA co-founded OpenStack. Glance is the image service, Neutron is the network service, and Cinder is the volume service. Swift provides object storage, while Keystone includes identity management, which keeps everything together.

The Role of Decoupling

The key to cloud computing is decoupling virtual resources from physical ones. The ability to abstract processors, memory, etc., from the underlying hardware enables on-demand/elastic provisioning and increased efficiency. This abstraction process has driven the cloud and led to various popular cloud flavors such as IaaS – Infrastructure-as-as-Service, PaaS – Platform-as-as-Service, and SaaS – Software-as-as-Service, a base for OpenStack foundations.

The fundamentals have changed, and the emerging way of consuming I.T. ( compute, network, storage ) is the new “O.S.” for the data center in the cloud. The cloud cannot operate automatically and needs a management suite to control and deploy service-oriented infrastructures. Different companies deploy different teams that specialize only in managing cloud computing. Those without an in-house team get it outsourced by firms like Global Storage. 

SDN Abstraction

These platforms rely on a new networking architecture known as software-defined networking. Traditional networking relies on manual administration, and its culture is based on a manual approach. Networking gear is managed box by box, and administrators maintain singular physical network hardware and connectivity. SDN, on the other hand, abstracts the network.

The switching infrastructure may still contain physical switch components but is managed like one switch. The data plane is operated as an entire entity rather than a loosely coupled connected device. SDN approach is often regarded as a prerequisite and necessary foundation for scalable cloud computing.

SDN and OpenFlow

Related: You may find the following post of interest:

  1. OpenStack Neutron Security Groups
  2. OpenStack Neutron
  3. Network Security Components
  4. Hyperscale Networking

OpenStack Architecture in Cloud Computing

The adoption of cloud technology has transformed how companies run their IT services. By leveraging new strategies for resource use, several cloud solutions came into play with different categories: private, public, hybrid, and community. OpenStack falls into the private cloud category. However, deploying OpenStack is still tricky, requiring a good understanding of its beneficial returns to a given organization regarding automation, orchestration, and flexibility.

The New Data Center Paradigm

n cloud computing, infrastructure services such as Software as a Service (SaaS), Platform as a Service (PaaS), and Infrastructure as a Service (IaaS) are provided. Agility, speed, and self-service are the challenges the public cloud sets. Most companies have expensive IT systems, which they have developed and deployed over the years, but these systems are siloed and require human intervention.

As public cloud services become more agile and faster, IT systems struggle to keep up. Today’s agile service delivery environment may make the traditional data center model and siloed infrastructure unsustainable. To achieve next-generation data center efficiency, enterprise data centers must focus on speed, flexibility, and automation.

Fully Automated Infrastructure

Admins and operators can deploy fully automated infrastructures with a software infrastructure within a minute. Next-generation data centers reduce infrastructure to a single, significant, agile, scalable, and automated unit. The result is an infrastructure that is programmable, scalable, and multi-tenant-aware. In this regard, OpenStack stands out as the next generation of data center operating systems.

Several sizeable global cloud enterprises, such as VMware, Cisco, Juniper, IBM, Red Hat, Rackspace, PayPal, and eBay, have benefited from OpenStack. Many are running a private cloud based on OpenStack in their production environment. Your IT infrastructure should use OpenStack if you wish to be a part of an innovative, winning cloud company.

The main components of OpenStack are:

While different services cater to various needs, they follow a common theme in their design:

  • In OpenStack, Python is used to develop most services, making it easier for them to be developed rapidly.

  • REST APIs are available for all OpenStack services. The APIs are the primary communication interfaces for other services and end users.

  • Different components may be used to implement the OpenStack service. A message queue communicates between the service components and has several advantages, including queuing requests, loose coupling, and load distribution.

1. Nova: Nova is the compute service responsible for managing and provisioning virtual machines (VMs) and other instances. It provides an interface to control and automate the deployment of instances across multiple hypervisors.

2. Neutron: Neutron is a networking service that enables the creation and management of virtual networks within the cloud environment. It offers a range of networking options, including virtual routers, load balancers, and firewalls, allowing users to customize their network configurations.

3. Cinder: Cinder provides block storage to OpenStack instances. It allows users to create and manage persistent storage volumes, which can be attached to cases for data storage. Cinder supports various storage backends, including local disks and network-attached storage (NAS) devices.

4. Swift: Swift is an object storage service that provides scalable and durable storage for unstructured data. It enables users to store and retrieve large amounts of data, making it suitable for applications that require high scalability and fault tolerance.

5. Keystone: Keystone serves as the identity service for OpenStack, providing authentication and authorization mechanisms. It manages user credentials and assigns access rights to the various components and services within the cloud infrastructure.

6. Glance: Glance is an image service that enables users to discover, register, and retrieve virtual machine images. It provides a catalog of images that can be used to launch instances, making it easy to create and manage VM templates.

7. Horizon: Horizon is the web-based dashboard for OpenStack, providing a graphical user interface (GUI) for managing and monitoring the cloud infrastructure. It allows users to perform administrative tasks like launching instances, managing networks, and configuring security settings.

These components work together to provide a comprehensive cloud computing platform that offers scalability, high availability, and efficient resource management. OpenStack’s architecture is designed to be highly modular and extensible, allowing users to add or replace components per their specific requirements.

Keystone

Architecturally, Keystone is the most straightforward service in OpenStack. OpenStack’s core component provides an identity service that enables tenant authentication and authorization. By authorizing communication between OpenStack services, Keystone ensures that the correct user or service can access the requested OpenStack service.

Keystone integrates with numerous authentication mechanisms, including usernames, passwords, tokens, and authentication-based systems. It can also be integrated with existing backends like Lightweight Directory Access Protocol (LDAP) and Pluggable Authentication Module (PAM).

Swift

Swift is one of the storage services that OpenStack users can use. REST APIs provide access to its object-based storage service. Object storage differs from traditional storage solutions, such as file shares and block-based access, in that it treats data as objects that can be stored and retrieved. An overview of Object Storage can be summarized as follows. In the Object Store, data is split into smaller chunks and stored in separate containers. A cluster of storage nodes maintains redundant copies of these containers to provide high availability, auto-recovery, and horizontal scalability.

Cinder

Another way to provide storage to OpenStack users may be to use the Cinder service. This service manages persistent block storage, which provides block-level storage for virtual machines. Virtual machines can use Cinder raw volumes as hard drives.

Some of the features that Cinder offers are as follows:

  • Volume management: This allows the creation or deletion of a volume

  • Snapshot management: This allows the creation or deletion of a snapshot of volumes

  • Attaching or detaching volumes from instances

  • Cloning volumes

  • Creating volumes from snapshots 

  • Copy of images to volumes and vice versa

Like Keystone services, Cinder features can be delivered by orchestrating various backend volume providers, such as IBM, NetApp, Nexenta, and VMware storage products, through configurable drivers.

Manila

As well as the blocks and objects we discussed in the previous section, OpenStack has had a file-share-based storage service called Manila since the Juno release. Storage is provided as a remote file system. Unlike Cinder, it is similar to the Storage Area Network (SAN) service as opposed to the Network File System (NFS) we use on Linux. The Manila service supports NFS, SAMBA, and CIFS as backend drivers. The Manila service orchestrates shares on the share servers.

Glance

An OpenStack user can launch a virtual machine from the Glance service based on images and metadata. Depending on the hypervisor, various image formats are supported. With Glance, you can access images for KVM/Qemu, XEN, VMware, Docker, etc.

When you’re new to OpenStack, you might wonder, What’s the difference between Glance and Swift? Both handle storage. How do they differ? What is the need for such a solution?

Swift is a storage system, whereas Glance is an image registry. In contrast, Glance keeps track of virtual machine images and their associated metadata. Metadata can include kernels, disk images, disk formats, etc. Glance uses REST APIs to make this information available to OpenStack users. Images can be stored in Glance utilizing a variety of backends. Directories are the default approach, but other methods, such as NFS and Swift, can be used in massive production environments.

In contrast, Swift is a storage system. This solution allows you to store data such as virtual disks, images, backup archiving, and more.

As an image registry, Glance serves as a resource for users. Glance focuses on an architectural approach to storing and querying image information via the Image Service API. In contrast, storage systems typically offer highly scalable and redundant data stores, whereas Glance allows users (or external services) to register virtual disk images. You, as a technical operator, must find the right storage solution at this level that is cost-effective and performs well.

**OpenStack Features**

Scalability and Elasticity

OpenStack’s architecture enables seamless scalability and elasticity, allowing businesses to allocate and manage resources dynamically based on their needs. By scaling up or down on demand, organizations can efficiently handle periods of high traffic and optimize resource utilization.

Multi-Tenancy and Isolation

One of OpenStack’s standout features is its robust multi-tenancy support, which enables the creation of isolated environments for different users or projects within a single infrastructure. This ensures enhanced security, privacy, and efficient resource allocation across various departments or clients.

Flexible Deployment Models

OpenStack offers a variety of deployment options, including private, public, and hybrid clouds. This flexibility allows businesses to choose the most suitable model based on their specific requirements, whether maintaining complete control over their infrastructure or leveraging the benefits of public cloud providers.

Comprehensive Service Catalog

With an extensive service catalog, OpenStack provides a wide range of services such as compute, storage, networking, and more. Users can quickly provision and manage these services through a unified dashboard, simplifying the management and deployment of complex infrastructure components.

Open and Vendor-Agnostic

OpenStack’s open-source nature ensures vendor-agnosticism, allowing organizations to choose hardware, software, and services from various vendors. This eliminates the risk of vendor lock-in and fosters a competitive market, driving innovation and cost-effectiveness.

OpenStack Architecture in Cloud Computing

OpenStack Fundations and Origins

OpenStack Foundations is a software platform for orchestrating and automating data center environments. It provides APIs enabling users to create virtual machines, network topologies, and scale applications to business requirements. It does not just let you control your cloud; you may make it available to customers for unique self-service and management.

It’s a collection of projects (each with a specific mission) to create a shared cloud infrastructure maintained by a community. It enables any organization type to build its public or private cloud stack. A key differentiator from OpenStack and other platforms is that it’s open-source, run by an independent community continually updating and reviewing publicly accessible information. The key to its adoption is that customers do not fear vendor lock-in.

The pluggable framework is supported by multiple vendors, allowing customers to move away from the continuous path of yearly software license renewal costs. There is real momentum behind it. The lead-up to OpenStack and cloud computing started with Amazon Web Service (AWS) in 2006. They offered a public IaaS and virtual instances with an API. However, there was no SLA or data guarantee, so research academies mainly used it.

NASA and Rackspace

Historically, OpenStack was founded by NASA and Rackspace. NASA was creating a project called Nebula, which was used for computing. Rackspace was involved in a storage project ( object storage platform ) called Cloud Files. The two projects mentioned above led to a community of collaborating developers working on open projects and components.

There are plenty of vendors behind it and across the entire I.T. stack. For servers, we have Dell and H.P.; Storage consists of NetApp and SolidFire; Networking has Cisco and Software with VMware and IBM.

Initially, OpenStack foundations started with three primary services: NOVA computer service, SWIFT storage service, and GLANCE virtual disk image service. Soon after, many additional services, such as network connectivity, were added. The initial implementations were simple, providing only basic networking via Linux Layer 2 VLANs and IPtables.

Now, with the Neutron networks, you can achieve a variety of advanced topologies and rich network policies. Most networking is based on tunneling ( GRE or VXLAN ). Tunnels are used within the hypervisor, so it fits nicely with multi-tenancy. Tunnels are created between the host over the Layer 3 network within the hypervisor. As a result, tenancy V.M.s can spin up where they want and communicate over the tunnel.

What is an API?

The application programming interface ( API ) is the engine under the cloud hood. The messenger takes requests, tells the systems what you want to do, and then returns the response to you—ultimately creating connectivity.

openstack foundations

Each core project (compute, network, etc.) will expose one or more HTTP/RESTful interfaces for public or managed access. This is known as a Northbound REST API. Northbound API faces some programming interfaces. It conceptualizes lower-level detail functions. Southbound faces the forwarding plane and allows components to communicate with a lower-level part.

For example, a southbound protocol could be OpenFlow or NETCONF. Northbound and southbound are software directions from the reference point of the network operating systems. We now have an East-West interface. At the time of writing, this protocol is not fully standardized, but eventually, it will be used to communicate between federations of controllers for state synchronization and high availability.

Example API Technology: Service Networking API

**Understanding the Basics of Service Networking**

Service Networking APIs primarily serve as the bridge connecting disparate services, allowing them to communicate efficiently. They are designed to simplify the process of integrating services, reducing the complexity associated with managing network connections. On Google Cloud, Service Networking APIs facilitate a variety of use cases, including hybrid cloud setups, service mesh architectures, and microservices communication.

**Key Benefits of Service Networking APIs on Google Cloud**

Google Cloud’s Service Networking APIs offer a plethora of advantages. Firstly, they enhance scalability by allowing services to communicate seamlessly without manual network configurations. Secondly, they bolster security through integrated policies that help safeguard data in transit. Additionally, these APIs support automated service discovery, which significantly reduces the time and effort required for service integrations and deployments.

**Implementing Service Networking APIs**

Implementing Service Networking APIs on Google Cloud is a straightforward process, designed to cater to both novice and experienced developers. Google Cloud provides comprehensive documentation and support, streamlining the setup and configuration of these APIs. Moreover, with tools like Google Kubernetes Engine (GKE) and Anthos, developers can leverage Service Networking APIs to manage and deploy services across hybrid and multi-cloud environments effortlessly.

Service Networking API

OpenStack Architecture: The Foundations

  1. OpenStack Compute – Nova is comparable to AWS EC2. She is used to provisioning instances for applications.
  2. OpenStack Storage – Swift is comparable to AWS S3. Provides object storage functions for application objects.
  3. OpenStack Storage – Cinder is comparable to AWS Elastic Block Storage. Provides persistent block storage functions for stateless instances.
  4. OpenStack Orchestration – Heat is comparable to AWS Cloud formation. Orchestrates deployment of cloud services
  5. OpenStack Networking—Neutron Network is comparable to AWS VPC and ELB. It creates networks, topologies, ports, and routers.

There are others, such as Identity, Image Service, Trove, Ceilometer, and Sahara.

Each OpenStack foundation component has an API that can be called from either CURL, Python, or CLI. CURL is a command-line tool that lets you send HTTP requests and receive responses. Python is a widely used programming language within the OpenStack ecosystem. It automates scripts to create and manage resources in your OpenStack cloud. Finally, command-line interfaces (CLI) can access and send requests to APIs.

OpenStack Architecture & Deployment

OpenStack has a very modular design, and the diagram below displays key OpenStack components. Logically, it can be divided into three groups: a) Control, b) Network, and c) Compute. All of the features use a database or a message bus. The database can either be MySQL, MariaDB, or PostgreSQL. The message bus can be RabbitMQ, Qpid, and ActiveMQ.

The messaging and database could run on the same control node for small or DevOps deployments but could be separated for redundancy. The cloud controller on the left consists of numerous components, which are often disaggregated into separate nodes. It is the logical interface to the cloud and provides the API service.

Openstack Deployment

The network controller includes the networking service Neutron. It offers an API for orchestrating network connectivity. Extension plugins provide additional network services such as VPNs, NAT, security firewalls, and load balancing. Generally, it is separate from the cloud controller, as traffic may flow through it. The compute nodes are the instances. This is where the application instances are deployed. 

Leverage vagrant 

Vagrant is a valuable tool for setting up Dev OpenStack environments to automate and build virtual machines ( with OpenStack ). It’s a wrapper around a virtualization platform, so you are not running the virtualization in Vagrant. The Vagrant V.M. gives you a pure environment to work with as it isolates dependencies from other V.M. applications. Nothing can interfere with the V.M., offering a full testing scope. An excellent place to start is Devstack. It’s the best tool for setting up small single-node non-production/testing installs.

Closing Points: OpenStack Architecture in Cloud Computing 

OpenStack is composed of several core services, each responsible for specific functionalities within the cloud infrastructure. These services include:

– **Nova**: This is the compute service of OpenStack, responsible for managing virtual machines and instances. Nova acts as the brain of the OpenStack ecosystem, ensuring efficient allocation and management of resources.

– **Swift**: OpenStack’s object storage system, Swift, is designed to store and retrieve unstructured data at scale. It ensures data redundancy, scalability, and durability, making it suitable for applications requiring massive storage capabilities.

– **Cinder**: Cinder handles block storage needs, allowing users to manage persistent storage independently of compute instances. This flexibility is essential for applications requiring high-performance storage.

– **Neutron**: Neutron manages networking for OpenStack, providing a framework for users to create and manage networking services like routers, switches, and firewalls.

– **Keystone**: Serving as the identity service, Keystone authenticates and authorizes users and services in an OpenStack environment, ensuring secure access control.

– **Horizon**: This is the dashboard component, allowing users to interact with the OpenStack services through a web-based interface. Horizon offers an intuitive and user-friendly way to manage cloud resources.

One of the key advantages of OpenStack is its ability to scale efficiently. Organizations can start with a small cloud infrastructure and expand it effortlessly as their needs grow. OpenStack’s modular design allows new services to be added without disrupting existing ones, making it an ideal choice for businesses anticipating rapid growth or fluctuating workloads.

Security is paramount in cloud computing, and OpenStack addresses this with a variety of tools and practices. Keystone provides a solid foundation for identity management, while additional security measures are implemented through OpenStack’s extensive community of developers and contributors. Regular updates and compliance checks ensure that OpenStack remains at the forefront of cloud security standards.

Summary: OpenStack Architecture in Cloud Computing

In the fast-evolving world of cloud computing, OpenStack has emerged as a powerful open-source platform that enables efficient management and deployment of cloud infrastructure. Understanding the architecture of OpenStack is essential for developers, administrators, and cloud enthusiasts alike. This blog post delved into the various components and layers of OpenStack architecture, providing a comprehensive overview of its inner workings.

Section 1: OpenStack Components

OpenStack comprises several key components, each serving a specific purpose in the cloud infrastructure. These components include:

1. Nova (Compute Service): Nova is the heart of OpenStack, responsible for managing and provisioning virtual machines (VMs) and controlling compute resources.

2. Neutron (Networking Service): Neutron handles networking functionalities, providing virtual network services, routers, and load balancers.

3. Cinder (Block Storage Service): Cinder offers block storage capabilities, allowing users to attach and manage persistent storage volumes to their instances.

4. Swift (Object Storage Service): Swift provides scalable and durable object storage, ideal for storing large amounts of unstructured data.

Section 2: OpenStack Architecture Layers

The OpenStack architecture is structured into multiple layers, each playing a crucial role in the overall functioning of the platform. These layers include:

1. Infrastructure Layer: This layer comprises the physical hardware resources such as servers, storage devices, and switches that form the foundation of the cloud infrastructure.

2. Control Layer: The control layer comprises services that manage and orchestrate the infrastructure layer. It includes components like Nova, Neutron, and Cinder, which control and coordinate resource allocation and network connectivity.

3. Application Layer: At the topmost layer, the application layer consists of software applications and services that run on the OpenStack infrastructure. These can range from web applications to databases, all utilizing the underlying resources OpenStack provides.

Section 3: OpenStack Deployment Models

OpenStack offers various deployment models to cater to different needs and requirements. These models include:

1. Public Cloud: OpenStack is operated and managed by a third-party service provider in a public cloud deployment, offering cloud services to multiple organizations or individuals over the internet.

2. Private Cloud: A private cloud deployment involves setting up an OpenStack infrastructure exclusively for a single organization. It provides enhanced security and control over data and resources.

3. Hybrid Cloud: A hybrid cloud deployment combines both public and private clouds, allowing organizations to leverage the benefits of both models. This provides flexibility and scalability while ensuring data security and control.

Conclusion

OpenStack architecture is a complex yet robust framework that powers cloud computing environments. Understanding its components, layers, and deployment models is crucial for effectively utilizing and managing OpenStack infrastructure. Whether you are a developer, administrator, or simply curious about cloud computing, exploring OpenStack architecture opens up a world of possibilities for building scalable and efficient cloud environments.

sd-wan3

VIPTELA SD-WAN – WAN Segmentation


VIPTELA SD-WAN

Problem Statement

WAN edge networks sit too far from business logic and are built, and designed with limited application and business flexibility. On the other hand, applications sit closer to business logic. It’s time for networking to bridge this gap using policies and business logic-aware principles. For additional information on WAN, challenges proceed to this SD WAN tutorial.


Traditional Segmentation

Network segmentation is defined as a portion of the network that is separated from the rest. Segmentation can be physical or logical. Physical segmentation involves complete isolation at a device and link level. Some organizations require the physical division of individual business units for security, political, or other reasons. At a basic level, logical segmentation begins with VLAN boundaries at Layer 2. VLAN consists of a group of devices that communicate as if they were connected to the same wire. As VLANs are logical and not physical connections, they are flexible and can span multiple devices.

While VLANs provide logical separation at Layer 2, virtual routing and forwarding (VRF) instances provide separation at Layer 3. Layer 2 VLAN can now map to Layer 3 VRF instances. However, every VRF has a separate control plane and configuration completed on a hop-by-hop basis. Individual VRFs with separate control planes from individual routing protocol neighbor relationships, hamper router performance.

VIPTELA VRF
VRF Separation

MPLS/VPNs overcome hop-by-hop configurations to allow segmentation. This enables physically divided business units to be logically divided without the need for individual hop-by-hop VPN configurations throughout the network. Instead, only the PE edge routers carry VPN information. This supports a variety of topologies such as hub and spoke, partial mesh, or any to any connectivity. While MPLS/VPNs have their benefits, they also introduce a unique set of challenges.

MPLS Challenges

MPLS topologies, once provisioned, are difficult to modify. This is due to the fact that all the impacted PE routers have to be re-provisioned with each new policy change. In this way, MPLS topologies are similar to the brick foundation of a house. Once the foundation is laid, it’s hard to make changes to the original structure without starting over.

Most modifications to VPN site topologies must go through an additional design phase. If a Wide Area Network (WAN) is outsourced to a carrier, it would require service provider intervention with additional design & provisioning activities. A simple task such as mapping application subnets to new or existing RT may involve onsite consultants, new high-level design, and configuration templates which would have to be applied by provisioning teams. Service provider provisioning and design activities are not free and usually have long lead times.

Some flexible Edge MPLS designs do exist. For example, community tagging and matching. During the design phase, the customer and service provider agree on predefined communities. Once these are set by the customer (attached to a prefix) they are matched by the provider to perform a certain type of traffic engineering (TE).

While community tagging and matching do provide some degree of flexibility and are commonly used, it remains a fixed, predefined configuration. Any subsequent design changes may still require service provider intervention.

Applications Must Fit A Certain Topology

The model forces applications to fit into a network topology that is already built and designed. It lacks the flexibility for the network to keep up with changing business needs. What’s needed is a way to map application requirements to the network. Applications are exploding and each has a variety of operational and performance requirements, which should be met in isolation.

Viptela SD-WAN & Topologies Per Application

By moving from hardware and diverse control planes to software & unified control planes at the WAN edge, SD-WAN evolves the fixed network approach. It abstracts the details of WAN; allowing application-independent topologies. SD-WAN provides segmentation between traffic sets and could be a good way to help create on-demand applications. Essentially, creating multiple on-demand topologies per application or group of applications. Each application can have its own topology and dynamically changing policies which are managed by a central controller.

The application controls the network design.

SD-WAN - Application flows
SD-WAN – Application flows

In SD-WAN, the central controller is hosted and managed by the customer, not a service provider. This enables the WAN to be segmented for each application at the customer’s discretion. For example, PCI traffic can be transported using an overlay specifically designed for compliance via Provider A. Meanwhile, ATM traffic can travel over the same provider network but using an overlay specifically designed for ATM. Meanwhile, each overlay can have different performance characteristics for path failover so that if the network does not reach a certain round-trip time (RTT) metric, traffic can reroute over another path. The customer has complete control over what application goes where and has the power to change policies on the fly.

The SDN controller, which acts as the brain, can set different applications to run over different paths based on business requirements and performance SLAs, not on a fixed topology. Each topology is segmented from the others and applications can share or have independent on-demand topologies. SD-WAN dramatically accelerates the time it takes to adapt the network to changing business needs.

SD-WAN Topologies

The network topologies can be depicted either physically or logically. Common topologies such as Star, Mesh, Full, and Ring are categorized under a centralized or decentralized function. In a physical world, these topologies are fixed and cannot be automatically changed. Logical topologies may also be hindered by physical device footprints.

In contrast, SD-WAN fully supports the coexistence of multiple application topologies regardless of existing physical footprints. For example, Lync message and video subscriptions may require different path topologies with separate SLAs. Messages may travel over low-cost links while video requires lower latency transports.

SD-WAN can flexibly cater to the needs of any type of application. In retail environments, store-specific applications may require a hub and spoke topology for authentication or security requirements. Surveillance systems may require full mesh topology. Guest Wi-fi may require local Internal access compared to normal user traffic that is scrubbed via a hub site. This per-application topology gives designers better control over the network. Viptela SD-WAN endpoints support multiple logical segments (regardless of the existing physical network), each of which can use a unique topology (full mesh, hub and spoke, ring) and be managed via its own policy.

Viptela SD-WAN: Predictable Application Performance

Obtaining predictable services is achieved by understanding the per-application requirements and routing appropriately.

Traditional MPLS WANs, offer limited fabric visibility. For example, providers allow enterprises to perform traceroute and pings, but bits-per-second is a primitive and unreliable method for measuring end-to-end application performance. Instead, WANs should be monitored at multiple layers, not just at the packet layer.

If a service provider is multiple autonomous systems (AS) away and experiencing performance problems, these cannot be addressed and detected using traditional distance-vector methods. This makes it impossible to route around problems and detect transitory oscillations. If errors on a transit path exist, a way must exist to penalize those paths.

Currently, there’s no way to detect when a remote network on the Internet is experiencing brownouts. Since the routing protocol is still operating, the best path does not change as neighbors might still be up. Routing should exist at the transport and application layer, and monitor both application flows and transactions. SD-WAN provides this function and delivers visibility at the device, transport, and application layer for insight into how the network is performing at any given time. This makes it possible to react to transitory failures before they can impact users.

“This post is sponsored by Viptela, an SD-WAN company. All thoughts and opinions expressed are the authors”


network-automation3

Network Configuration Automation

Network Configuration Automation

In today's fast-paced digital landscape, efficient network configuration automation has become a cornerstone for organizations striving to enhance their operational productivity. Automating network configuration processes not only saves time and effort but also minimizes human error and ensures consistent network performance. In this blog post, we will explore the key benefits and considerations of network configuration automation, along with best practices to implement it effectively.

Network configuration automation refers to the practice of automating the deployment, management, and monitoring of network devices and related configurations. It streamlines the repetitive and time-consuming tasks involved in configuring network devices, such as routers, switches, and firewalls. By utilizing automation tools and frameworks, organizations can achieve greater agility, scalability, and accuracy in their network infrastructure.

Automating network configuration brings numerous advantages to organizations. Firstly, it significantly reduces the risk of human errors that can lead to network downtime or security vulnerabilities. Automation ensures consistency across network devices, eliminating configuration discrepancies.

Secondly, it enhances operational efficiency by reducing manual efforts and standardizing configuration processes, allowing IT teams to focus on more strategic initiatives. Lastly, network configuration automation facilitates faster troubleshooting and enables rapid changes to adapt to dynamic network requirements.

Comprehensive Network Inventory: Begin by creating a detailed inventory of network devices, including their models, firmware versions, and current configurations. This inventory will serve as a foundation for automation workflows.

Define Configuration Standards: Establish clear and standardized configuration templates that align with industry best practices. These templates should include essential parameters, such as IP addresses, routing protocols, and security policies.

Utilize Automation Tools: Choose a robust automation tool or framework that suits your organization's requirements. Evaluate features like device compatibility, scalability, and ease of integration with existing network management systems.

Test and Validate: Before deploying automated configurations in a production environment, thoroughly test and validate them in a controlled lab or staging environment. This step helps identify potential issues or conflicts.

While network configuration automation offers substantial benefits, it is essential to consider potential challenges. Organizations must ensure proper security measures are in place to protect automation tools and the integrity of network configurations. Additionally, regular monitoring and auditing of automated processes are crucial to detect any anomalies or unauthorized changes.

Network configuration automation serves as a catalyst for operational efficiency and reliability in modern network infrastructures. By embracing automation tools, defining robust processes, and adhering to best practices, organizations can streamline their network configuration workflows, reduce errors, and improve overall network performance.

With the right approach, network configuration automation becomes a strategic enabler for organizations seeking to stay competitive in today's digital landscape.

Highlights: Network Configuration Automation

**The Rise of Automation in Networking**

Automation in networking refers to the use of software and technologies to automate the configuration, management, testing, deployment, and operation of network devices. This approach is gaining traction as it addresses some of the most pressing challenges in networking today, such as the need for speed, accuracy, and scalability. By automating routine tasks, network administrators can focus on more strategic initiatives, resulting in more efficient and effective networks.

**Benefits of Networking Automation**

One of the most significant benefits of automation in networking is its ability to enhance efficiency. Automated systems can perform repetitive tasks quickly and accurately, reducing the likelihood of human error. This increased precision leads to improved network performance and reliability. Additionally, automation allows for faster deployment of network changes and updates, enabling organizations to respond swiftly to evolving business needs and technological advancements.

**Overcoming Challenges in Automation**

While the advantages of networking automation are clear, the journey to full automation is not without obstacles. One of the primary challenges is the complexity of integrating automation tools with existing network infrastructures. Organizations must also address potential security issues, as automated systems can be vulnerable to cyber threats if not properly managed. Moreover, there is a need for skilled personnel who can oversee and maintain these automated systems, highlighting the importance of ongoing training and development.

**The Future of Networking: What Lies Ahead?**

As automation continues to gain ground, the future of networking looks promising. Emerging technologies such as artificial intelligence and machine learning are expected to further enhance automation capabilities, leading to more intelligent and adaptive networks. These advancements will enable networks to self-optimize and self-heal, minimizing downtime and maximizing performance. As a result, businesses can expect to see increased efficiency, reduced operational costs, and improved customer satisfaction.

Introducing Network Configuration Automation

1: – In today’s fast-paced digital landscape, efficient network configuration management is crucial for businesses to thrive. Manual network configuration tasks can be time-consuming, error-prone, and hinder productivity. This is where network configuration automation comes into play, revolutionizing the way networks are managed and maintained.

2: – Network configuration automation refers to the use of tools and scripts to automatically configure network devices such as routers, switches, and firewalls. This process eliminates the need for manual configuration, which can be time-consuming and prone to human error. By automating repetitive tasks, organizations can ensure consistency and accuracy across their network infrastructure.

3: – Automating network configuration processes offers a plethora of advantages. Firstly, it significantly reduces human errors that often occur during manual configurations. With automation, consistency and accuracy are ensured, leading to enhanced network reliability. Additionally, network configuration automation saves time and resources, allowing IT teams to focus on more strategic tasks rather than mundane and repetitive configurations.

4: – Implementing network configuration automation involves selecting the right tools and technologies for your organization. Popular options include Ansible, Puppet, and Chef, each offering unique features and capabilities. It’s important to assess your specific needs and environment before choosing a solution. Once implemented, automation scripts can be created and customized to meet your organization’s unique requirements, ensuring seamless integration into existing workflows.

Note: – **Application Changes**

Applications are deployed differently today than they were 10-15 years ago. So much has changed with the app. The problem we are seeing today is that the network is not tightly coupled with these other developments. Providing various network policies and corresponding configurations is not tightly associated with the application.

They are usually loosely coupled and reactive. For example, analyzing firewall rules and providing a network assessment is nearly impossible with old security devices, driving the need for network configuration automation and the ability to automate network configuration.

Right Tools & Strategies 

– To successfully implement network configuration automation, businesses need to adopt the right tools and strategies. Robust automation platforms, such as Ansible or Puppet, can streamline the process by providing intuitive interfaces and extensive libraries of pre-built configurations. IT teams should also establish clear configuration standards and templates to ensure consistency across the network.

– While network configuration automation offers numerous benefits, it’s not without its challenges. One common obstacle is the initial investment required to implement automation tools and train IT staff. However, the long-term cost savings and increased efficiency outweigh the initial costs. Additionally, businesses must carefully plan and test automation workflows to avoid unintended consequences or disruptions to network operations.

Deterministic outcomes

An enterprise organization’s change review involves examining upcoming network changes, their impact on external systems, and their rollback plans. When humans use the CLI to make changes, typing the wrong command can have catastrophic results. Think about a team of three, four, five, or fifty engineers. Depending on the engineer, changes can be made in a variety of ways. In addition, even using a GUI or a CLI does not eliminate or reduce the chance of errors during change control.

The executive team has a better chance of achieving deterministic outcomes when they use proven and tested network automation to make changes. This increases their chances of achieving a successful project the first time around by achieving more predictable behavior than when making changes manually. This might happen when a new VLAN is added or a new customer is onboarded, requiring multiple network changes.

Furthermore, deterministic results result in lower operating expenses (OpEx), as network changes require less manual labor, resulting in a more efficient network operation (e.g., automating time-consuming tasks such as updating a network device’s operating system). Network engineers can focus on more strategic projects and improve processes with less operating time.

Device Provisioning

An easy and fast way to get started with network automation is to automate the creation and pushing of device configuration files. Two steps are involved in this process: creating the configuration file and pushing it to the device.

To automate configuration files (or configuration data in general), the input parameters (configuration parameters) must first be decoupled from the vendor-proprietary syntax (CLI). Separate files will be created for configuration templates, VLANs, domains, interfaces, routing, etc.

Data Collection and Enrichment

Through SNMP, monitoring tools typically poll management information bases (MIBs) for data. Data may be returned in excess or insufficient to meet your needs. What should be done when polling interface statistics? What if you only need interface resets, not CRC errors, jumbo frames, or output errors?

The command show interface may return every counter, but what if you only need interface resets? Moreover, what if you want to see interface resets correlated with Cisco Discovery Protocol (CDP) or LLDP neighbors now rather than in the future? In this context, what role does network automation play?

We focus on giving you more control so you can customize what you get when you get it, how it is formatted, and how it is used after it is collected. Automating the process can maximize your data.

Migrations

Migrating from one platform to another is never easy. There may be platforms from the same vendor or different vendors. In our example, you can create configuration templates for network devices and operating systems using various forms of automation. Vendors may provide a script or tool that helps with migrations. It would then be possible to generate a configuration file for every vendor using a defined and standard data set (common data model).

If you are using them, you must also consider vendor-proprietary extensions. It is fantastic that such a tool can be built independently rather than by a vendor. A vendor must account for all the device features, while an organization only needs a limited number. Vendors aren’t concerned about this; they are worried about their equipment not making it easier for you, the network operator, to manage multivendor environments.

Configuration Management

In configuration management, devices are deployed, pushed, and managed according to their configuration state. Everything from interface descriptions to configurations of ToR switches, firewalls, load balancers, and advanced security infrastructure is covered to deploy three-tier applications.

As you can see, with the read-only forms of automation, you don’t have to start by pushing configurations. This method may be worthwhile if you spend countless hours making the same change across many routers or switches.

Before you proceed, you may find the following articles of interest:

  1. Open Networking
  2. A10 Networks
  3. Brownfield Network Automation

Network Configuration Automation

One of the easiest and quickest ways to get started with network automation is to automate the creation of the device configuration files used for initial device provisioning and push them to network devices. You can also get a lot of information with automation. For example, network devices have enormous static and ephemeral data buried inside, and using open-source tools or building your own gets you access to this data.

Examples of this type of data include entries in the BGP table, OSPF adjacencies, active neighbors, interface statistics, specific counters and resets, and even counters from application-specific integrated circuits (ASICs) themselves on newer platforms.

Guide with Ansible Core

We have Ansible installed and a managed host already prepared in the following. The managed host needs to have SSH enabled and a user with admin privileges. Ansible finds managed hosts by looking at the inventory file. The inventory file is also a great place to pass variables that can be used to remove site-specific information; this is set under the host var section below.

Remember that Ansible requires Python, and below, we are running Python version 3.0.3 and Jinja version 3.0.3, which is used for templating. You can pass information to ansible managed hosts with playbooks and ad hoc commands. Below, I’m using an ad hoc command, calling the command module by default, and testing with a ping.

Ansible configuration
Diagram: Ansible Configuration

**Benefits of Network Configuration Automation**

1. Time and Resource Efficiency: Organizations can free up their IT staff to focus on more strategic initiatives by automating repetitive and time-consuming network configuration tasks. This results in increased productivity and efficiency across the organization.

2. Enhanced Accuracy and Consistency: Manual configuration processes are prone to human error, leading to misconfigurations and network downtime. Network configuration automation eliminates these risks by ensuring consistency and accuracy in network configurations, reducing the chances of costly errors.

3. Rapid Network Deployment: Network administrators can quickly deploy network configurations across multiple devices simultaneously with automation tools. This accelerates network deployment and enables organizations to respond faster to changing business needs.

4. Improved Security and Compliance: Network configuration automation enhances security by enforcing standardized configurations and ensuring compliance with industry regulations. Automated security protocols can be applied consistently across the network, reducing vulnerabilities and enhancing overall network protection.

5. Simplified Network Management: Automation tools provide a centralized platform for managing network configurations, making it easier to monitor, troubleshoot, and maintain network devices. This simplifies network management and reduces the complexity associated with manual configuration processes.

**Implementing Network Configuration Automation**

To implement network configuration automation, organizations need to consider the following steps:

1. Assess Network Requirements: Understand the specific network requirements, including device types, network protocols, and security policies.

2. Select an Automation Tool: Evaluate different automation tools available on the market and choose the one that best suits the organization’s needs and network infrastructure.

3. Create Configuration Templates: Develop standardized configuration templates that can be easily applied to network devices. These templates should include best practices, security policies, and network-specific configurations.

4. Test and Validate: Before deploying automated configurations, thoroughly test and validate them in a controlled environment to ensure their effectiveness and compatibility with the existing network infrastructure.

5. Monitor and Maintain: Regularly monitor and maintain the automated network configurations to identify and resolve any issues or security vulnerabilities that may arise.

The Need to Automate Network Configuration

There are always hundreds, if not thousands, of outdated rules even though the application service is not required. Another example is unused VLANs left configured on access ports, posing a security risk. The problem lies in the process: how we change and provision the network is not tied to the application. It is not automated. Inconsistent configurations tend to grow as human interaction is required to tidy things up. People move on and change roles.

You cannot guarantee the person creating a firewall rule will be the engineer deleting the rule once the corresponding applications are decommissioned or changed. And if you don’t have a rigorous change control process, deprecated configurations will be idle on active nodes.

A key point: The use of Ansible variables in an Ansible architecture.

For configuration management, you could opt for Red Hat Ansible. The Ansible architecture consists of modules with tasks on the target hosts listed in the inventory. Various plugins are available for additional context and Ansible variables for flexible playbook development. Ansible Core is the CLI-based version of automation, and Ansible Tower is the platform.

The recommended approach for enterprise-wide security would be a platform-based approach to the Ansible architecture. Using a platform approach using Ansible variables creates a very flexible automation journey where you can have one playbook with Ansible variables, removing any site-specific information running against several different inventories that could relate to your other functions, Dev, Staging, and Production.

Network Automation

The network is critical for business continuity, resulting in real uptime pressure. Operational uptime is directly tied to the success of the business. This results in a manual culture, which manifests as manual and slow. The actual bottleneck is our manual culture for network provision and operation. 

Virtualization – Beginning the change

Virtualization vendors are changing the manual approach. For example, if we look at essential MAC address learning and its process with traditional switches. The source MAC address of an incoming Ethernet frame is examined, and if the source MAC address is known, it doesn’t need to do anything, but if it’s not known, it will add that MAC to its table and make a note of the port the frame entered. The switch has a port for MAC mapping. The table is continually maintained, and MAC addresses are added and removed via timers and flushing.

The virtual switch

The virtual switch operates differently. Whenever a VM spins up and a VNIC attaches to the virtual switch, the Hypervisor programs everything it needs to know to forward that traffic into its process on the virtual switch. There is no MAC learning. When you spin down the VM, the hypervisor does not need to wait for a timer.

It knows the source is no longer there; as a result, it no longer needs to have that state. Less state in a network is a good thing. The critical point is that the provision of the application/ virtual machine is tightly coupled with the provisioning of network resources. Tightly coupling applications to network resources/provisioning offers less “Garbage Collection.”

Box mentality  

When the contents of HLD / LLD are completed and you are now moving to the configuration stage, the current implementation-specific details are done per box. The commands are defined on individual boxes and are vendor-specific. This works functionally, and it’s how the Internet was built, but it lacks agility and proper configuration management. Many repetitive tasks with a box mentality destroy your ability to scale.

Businesses are mainly concerned with agility and continuity, but you cannot have these two things with manual provisions. You must look at your network as a system, not individual boxes. When you look at applications and their scaling, the current network-style implementation method does not scale and keeps in line with the apps. The solution is to move to network configuration automation and automatic interaction.

Configuration management

Network Configuration Automation and Automate Network Configuration

We must move out of a manual approach and into an automated system. Focus initially on low-hanging fruit and easy wins. What takes engineers the longest to do? Do VLAN and Subnet allocation sheets ring a bell? We should size according to demand and not care about the type of VLAN or the Internal subnet allocation. Microsoft Azure cloud is a perfect example.

They do not care about the type of private address they assign to internal systems. They automate the IP allocation and gateway assignment so you can communicate locally. Designing optimum networks to last and scale is not good enough anymore. The network must evolve and be programmed to keep up with app placement. The configuration approach needs to change, and we should move to proper configuration management and automation.

Ansible is a widespread tool of choice. As previously mentioned, we have Ansible Tower as a platform, and for CLI-based devices, we have Ansible Core, which supports variable substitution with Ansible variables. 

SDN: A companion to network automation?

One benefit of Software-Defined Networking (SDN) is that it lets you view your network holistically, with a central viewpoint. Network configuration automation is not SDN, and SDN is not network automation. They work side by side and complement each other. SDN allows you to be abstract and prevents those who do not need to see the detail from not seeing it.

The application owners do not care about VLANs. Application designers should also not care about local IP allocations if they have designed the application correctly. Centralization is also a goal for SDN. Centralization with SDN is different from control-plane centralization. Central SDN controller devices should not fully control the control plane.

SDN companies have learned this and now allow network nodes to handle some or part control plane operations.  

Programming network: Automate network configuration

You don’t need to be a programmer, but you should start thinking like one. Learning to program will make you better equipped to deal with things. Programming networks is a diagonal step from what you are doing now, offering an environment to run code and ways to test code before you run it out.

The current CLI is the most dangerous approach to device configuration; you can even lock yourself out of a device. Programming adds a safety net. It’s more of a mental shift. Stop jumping to the CLI and THINK FIRST. Break the task down and create workflows. Workloads are then mapped to an automation platform.

A key point: TCL and EXPECT

TCL ( Tool Command Language ) is a scripting language created in 1988 at UC Berkeley. It aims to connect Shell scripts and Unix commands. EXPECT is a TCL extension written by Don Libes. It automates Telnet, SSH, and Serial sessions to perform many repetitive tasks.

EXPECT’s main drawback is that it is not secure and is synchronous only. If you log onto a device, you display login credentials in the EXPECT scripts and cannot encrypt that data in the code. In addition, it operates sequentially, meaning you send a command and wait for the output; it does not send send send and wait to receive; it’s a send and waits, sends and wait for mythology.

A key point: SNMP has failed | NETCONF begins

SNMP is used for fault handling, monitoring equipment, and retrieving performance data, but very few use SNMP to set configurations. More often, there is no 1:1 translation between a CLI configuration operation and an SNMP “SET.” It’s hard to get this 1-2-1 correlation. As a result, not many people use SNMP for device configuration and management of structures.

CLI scripting was the primary approach to automating network configuration changes before NETCONF. Unfortunately, CLI scripting has several limitations, including a lack of transaction management, no structured error management, and the ever-changing structure and syntax of commands, making scripts fragile and costly to maintain. Even the use of autocorrelation scripts won’t be able to fix it.

People make mistakes, and ultimately, people are bad at stuff. It’s the nature of the beast. Human error plays a significant role in network outages, and if a person is not logging in doing CLI, they are less likely to make a costly mistake. Human interaction with the network is a major cause of network outages.

NETCONF & Tail-F

NETCONF ( network control protocol ) is an XML-based data encoding for configuration and protocol messages. It offers secure transport and is Asynchronous, so it’s not sequential like TCL and EXPECT. Asynchronous makes NETCONF more efficient. It allows the separation of the configuration from the non-configuration items.

SNMP makes backup and restore complex, as you have no idea what fields are used to restore. Also, because of SNMP’s binary nature, it isn’t easy to compare configurations from one device to another. NETCONF is much better at this.

A final note: Transaction-based approach

It offers a transaction-based approach. A transaction is a set of configuration changes, not a sequence. SNMP for configuration requires everything to be in the correct sequence/order. But with a transaction, you throw in everything, and the device figures out how to roll it out.

What matters is that operators can write service-level applications that activate service-level changes and don’t have to make the application aware of all the sequence of changes that must be completed before the network can serve application responses and requests. Check out an exciting company called Tail-F (now part of Cisco), which offers a family of NETCONF-enabled products.

Closing Points on Network Configuration Automation

Automation in networking refers to the use of software and tools to execute network management tasks with minimal human intervention. This includes configuration, management, testing, deployment, and operation of physical and virtual devices within a network. The primary goal of automation is to improve efficiency, reduce human error, and enable network administrators to focus on strategic tasks rather than mundane, repetitive ones.

The integration of automation into networking brings numerous advantages. Firstly, it significantly enhances operational efficiency by automating routine tasks, allowing network teams to allocate their time and resources more effectively. Secondly, it reduces the risk of human errors, which are often the cause of network outages and security breaches. Thirdly, automation supports scalability, enabling networks to grow and adapt without the need for extensive manual configuration. Lastly, it provides real-time insights and analytics, empowering businesses to make data-driven decisions.

Despite its benefits, the implementation of automation in networking is not without challenges. One of the primary obstacles is the complexity of integrating automation tools with existing network infrastructure. Organizations may also face resistance from IT staff who are wary of changing established processes. Additionally, there is a need for ongoing training and upskilling to ensure that teams can effectively manage and optimize automated systems. Addressing these challenges requires careful planning, investment, and a commitment to change management.

As technology continues to evolve, the future of networking automation looks promising. Advances in artificial intelligence and machine learning are expected to further enhance automation capabilities, leading to smarter, more adaptive networks. The rise of the Internet of Things (IoT) and 5G technologies will also drive demand for automated solutions to manage the increased complexity and volume of network traffic. As businesses continue to embrace digital transformation, automation will become an indispensable component of modern networking strategies.

Summary: Network Configuration Automation

Network configuration is crucial in ensuring seamless connectivity and efficient data flow in today’s fast-paced technological landscape. However, the manual configuration of networks can be time-consuming, prone to errors, and hinder scalability. This is where network configuration automation comes into play, revolutionizing how networks are managed and optimized. In this blog post, we explored the benefits, implementation techniques, and best practices of network configuration automation.

Understanding Network Configuration Automation

Network configuration automation involves leveraging software and tools to automate configuring and managing network devices. Reducing human intervention eliminates manual errors, enhances agility, and enables effective network management at scale.

Benefits of Network Configuration Automation

Automating network configuration brings a plethora of advantages to organizations. Firstly, it significantly reduces human errors, ensuring accurate and consistent device configurations. Secondly, it enhances efficiency by saving time and effort spent on manual configurations. Additionally, automation allows for faster deployment of network changes, improving overall network agility and responsiveness.

Implementation Techniques for Network Configuration Automation

Implementing network configuration automation requires a structured approach. It involves:

1. Inventory and Device Discovery: Create an inventory of network devices and establish a comprehensive understanding of the existing network infrastructure.

2. Configuration Templates and Version Control: Develop standardized configuration templates that can be easily applied to multiple devices. Implement version control mechanisms to track and manage configuration changes effectively.

3. Orchestration and Automation Tools: Leverage network automation tools that provide scripting, scheduling, and deployment automation features. Tools like Ansible, Chef, and Puppet offer potent capabilities to streamline network configuration.

Best Practices for Network Configuration Automation

To ensure a successful implementation of network configuration automation, consider the following best practices:

1. Test and Verify: Before deployment, thoroughly test and verify automation scripts and templates to ensure they align with the desired network configuration and functionality.

2. Security and Compliance: Incorporate security measures and compliance standards into automation processes to protect network assets and ensure adherence to industry regulations.

3. Documentation and Change Management: Maintain detailed documentation of configurations and changes made through automation. Implement a change management process to track modifications and facilitate troubleshooting.

Conclusion

Network configuration automation is a game-changer in network management. By embracing automation, organizations can reduce errors, enhance efficiency, and improve overall network performance. Whether deploying standardized configurations or orchestrating complex network changes, automation streamlines processes, allowing IT teams to focus on strategic initiatives and innovation.