Software Defined Internet Exchange

Software Defined Internet Exchange

In today's digital era, where data is the lifeblood of every organization, the importance of a reliable and efficient internet connection cannot be overstated. As businesses increasingly rely on cloud-based applications and services, the demand for high-performance internet connectivity has skyrocketed. To meet this growing need, a revolutionary technology known as Software Defined Internet Exchange (SD-IX) has emerged as a game-changer in the networking world. In this blog post, we will delve into the concept of SD-IX, its benefits, and its potential to revolutionize how we connect to the internet.

Software Defined Internet Exchange, or SD-IX, allows organizations to dynamically connect to multiple Internet service providers (ISPs) through a centralized platform. Traditionally, internet traffic is exchanged through physical interconnections between ISPs, resulting in limited flexibility and control. SD-IX eliminates these limitations by virtualizing the interconnection process, enabling organizations to establish direct, secure, and scalable connections with multiple ISPs.

SD-IX Defined: Software Defined Internet Exchange, or SD-IX, is a cutting-edge technology that enables dynamic and automated interconnection between networks. Unlike traditional methods that rely on physical infrastructure, SD-IX leverages software-defined networking (SDN) principles to create virtualized interconnections, providing flexibility, scalability, and enhanced control.

Enhanced Performance: One of the prominent advantages of SD-IX is its ability to optimize network performance. By utilizing intelligent routing algorithms and traffic engineering techniques, SD-IX reduces latency, improves packet delivery, and enhances overall network efficiency. This translates into faster and more reliable connectivity for businesses and end-users alike.

Flexibility and Scalability: SD-IX offers unparalleled flexibility and scalability. With its virtualized nature, organizations can easily adjust their network connections, add or remove services, and scale their infrastructure as needed. This agility empowers businesses to adapt to changing demands, optimize their network resources, and accelerate their digital transformation initiatives.

Cost Efficiency: By leveraging SD-IX, organizations can significantly reduce their network costs. Traditional methods often require expensive physical interconnections and complex configurations. SD-IX eliminates the need for such costly infrastructure, replacing it with virtualized interconnections that can be provisioned and managed efficiently. This cost-saving aspect makes SD-IX an attractive option for businesses of all sizes.

Driving Innovation: SD-IX is poised to drive innovation in the networking landscape. Its ability to seamlessly connect disparate networks, whether cloud providers, content delivery networks, or internet service providers, opens up new possibilities for collaboration and integration. This interconnected ecosystem paves the way for novel services, improved user experiences, and accelerated digital innovation.

Enabling Edge Computing: As the demand for low-latency applications and services grows, SD-IX plays a crucial role in enabling edge computing. By bringing data centers closer to the edge, SD-IX reduces latency and enhances the performance of latency-sensitive applications. This empowers businesses to leverage emerging technologies like IoT, AI, and real-time analytics, unlocking new opportunities and use cases.

Software Defined Internet Exchange (SD-IX) represents a significant leap forward in the world of connectivity. With its virtualized interconnections, enhanced performance, flexibility, and cost efficiency, SD-IX is poised to reshape the networking landscape. As organizations strive to meet the ever-increasing demands of a digitally connected world, embracing SD-IX can unlock new realms of possibilities and propel them towards a future of seamless connectivity.

SD-IX / SDX · INTERACTIVE LAB 01

How Does a Software-Defined Internet Exchange Change the Path?

Compare a conventional IXP fabric with a software-defined exchange. Follow the separation between BGP route exchange, the switching fabric and programmable traffic policy.

Internet Exchange Fabric READY
AS
Network A Member AS
IX
Exchange Fabric Shared switching fabric with BGP route exchange
BGP / Routing Control
AS
Network B Member AS
The exchange currently uses destination-based routing as the primary forwarding model.
Control Plane BGP
Data Plane L2 Fabric
Policy Granularity Prefix
Steering Limited
Conceptual model. Modern IXPs can use a variety of architectures, route servers, routing policies and programmable platforms. SDX is presented here as an architectural pattern rather than a claim that every IXP uses one specific controller or forwarding technology.
Exchange Result
Configure the exchange model and trace the traffic path.
Control-Plane Console
[READY] Awaiting exchange-path trace...
Engineering Insight

Traditional BGP-based exchange routing is powerful and scalable, but its normal decision model is centred on destination prefixes. A programmable exchange can introduce additional policy layers closer to the forwarding plane.

Highlights: Software Defined Internet Exchange

Understanding Software-Defined Internet Exchange

a) SD-IX is a cutting-edge technology that enables dynamic and flexible interconnection between networks. Unlike traditional internet exchange points (IXPs), SD-IX leverages software-defined networking (SDN) principles to create virtualized exchange environments. By abstracting the physical infrastructure, SD-IX allows on-demand network connections, enhanced scalability, and simplified network management.

b) Internet exchanges are physical locations where multiple Internet service providers (ISPs), content delivery networks (CDNs), and network operators connect their networks to exchange Internet traffic. By establishing direct connections, IXPs enable efficient and cost-effective data transfer between various networks, enhancing internet performance and reducing latency.

**How Internet Exchanges Work**

Internet Exchanges typically consist of high-speed switches and routers deployed in data centers. These devices provide the necessary connectivity between participating networks, facilitating traffic exchange.

To join an Internet Exchange, networks must adhere to specific peering policies and agreements. These guidelines dictate the terms of traffic exchange, including technical requirements, traffic ratios, and network security measures.

**Internet Exchange Points Around the World**

1: – ) Numerous Internet Exchange Points (IXPs) are located worldwide, with some of the most prominent ones including DE-CIX in Frankfurt, AMS-IX in Amsterdam, and LINX in London. These IXPs are critical hubs for global internet connectivity, enabling networks from different regions to exchange traffic.

2: – ) major global IXPs, regional and national Internet Exchange Points cater to specific geographic areas. These local IXPs further improve network performance by facilitating regional traffic exchange and reducing the need for long-haul data transfer.

3: – ) the demand for high-performance and reliable internet connectivity continues to grow, SD-IX is poised to play a pivotal role in shaping the future of networking. By virtualizing the interconnection process and providing organizations with unprecedented control and flexibility over their network connections, SD-IX empowers businesses to optimize their network performance, enhance security, and reduce costs. With its ability to scale on-demand and seamlessly reroute traffic, SD-IX is well-suited for the evolving needs of cloud-based applications, IoT devices, and emerging technologies such as edge computing.

4: – ) Defined Internet Exchange represents a paradigm shift in how organizations connect to the Internet. By virtualizing the interconnection process and providing enhanced performance, reliability, cost efficiency, scalability, and security, SD-IX offers a compelling solution for businesses seeking to optimize their network infrastructure. As the digital landscape continues to evolve, SD-IX is set to revolutionize the way we connect to the internet, enabling organizations to stay ahead of the curve and unlock new possibilities in the digital era.

Key SD-IX Considerations:

– Enhanced Performance and Latency Reduction: SD-IX brings networks closer to end-users by establishing globally distributed points of presence (PoPs). This proximity reduces latency and improves application performance, resulting in a superior user experience.

– Seamless Network Scalability: With SD-IX, organizations can quickly scale their network resources up or down based on demand. This agility empowers businesses to adapt rapidly to changing network requirements, ensuring optimal performance and cost-efficiency.

– Simplified Network Management: Traditional IXPs often require complex physical infrastructure and manual configurations. SD-IX simplifies network management by providing a centralized control plane, allowing administrators to automate provisioning, traffic engineering, and policy enforcement.

– Cloud Service Providers: SD-IX enables providers to establish direct and secure customer connections. This direct access bypasses the public internet, ensuring better security, lower latency, and improved data transfer speeds.

– Content Delivery Networks (CDNs): CDNs can leverage SD-IX to optimize content delivery by strategically placing their PoPs closer to end-users. This reduces latency, minimizes bandwidth costs, and enhances content delivery performance.

– Enterprises and Multi-Cloud Connectivity: Enterprises can benefit from SD-IX by establishing private connections between their networks and multiple cloud service providers. This enables secure, high-performance multi-cloud connectivity, facilitating seamless data transfer and workload migration.

Understanding SD-IX

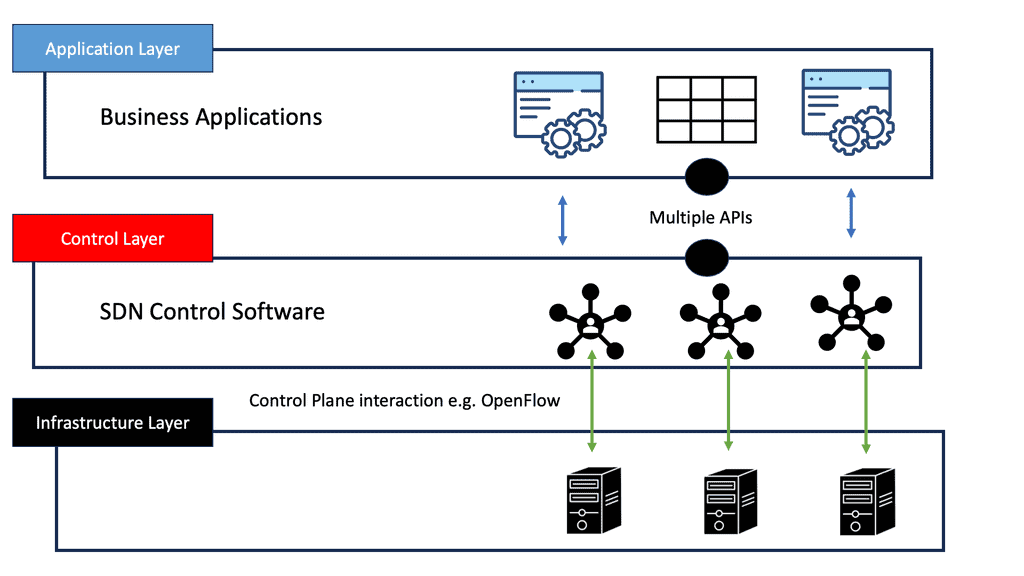
At its core, SD-IX is an architectural framework enabling the dynamic and automated internet traffic exchange between networks. Unlike traditional methods that rely on physical infrastructure, SD-IX leverages software-defined networking (SDN) principles to create a virtualized exchange ecosystem. By decoupling the control plane from the data plane, SD-IX brings flexibility, agility, and scalability to internet exchange.

One of SD-IX’s critical advantages is its ability to provide enhanced performance through optimized routing. By leveraging intelligent algorithms and real-time analytics, SD-IX can intelligently direct traffic along the most efficient paths, reducing latency and improving overall network performance. Moreover, SD-IX offers improved scalability, allowing networks to dynamically adjust their capacity based on demand, ensuring seamless connectivity even during peak usage.

Security and Privacy Advancements

SD-IX brings significant advancements in an era where data security and privacy are of the utmost concern. With the ability to implement granular access control policies and encryption mechanisms, SD-IX ensures secure data transmission across networks. SD-IX’s centralized management and monitoring capabilities enable network administrators to detect and mitigate potential security threats in real-time, bolstering overall network security.

Software-defined networks

A software-defined network (SDN) optimizes and simplifies network operations by closely tying applications and network services, whether real or virtual. By establishing a logically centralized network control point (typically an SDN controller), the control point orchestrates, mediates, and facilitates communication between applications that wish to interact with network elements and network elements that want to communicate information with those applications. The controller exposes and abstracts network functions and operations through modern, application-friendly, bidirectional programmatic interfaces.

As a result, software-defined, software-driven, and programmable networks have a rich and complex history and various challenges and solutions to those challenges. Because of the success of technologies that preceded them, software-defined, software-driven, and programmable networks are now possible.IP, BGP, MPLS, and Ethernet are the fundamental elements of most networks worldwide.

Control and Data Plane Separation

SDN’s early proponents advocated separating a network device’s control and data planes as a potential advantage. Network operators benefit from this separation regarding centralized or semi-centralized programmatic control. As well as being economically advantageous, it can consolidate into a few places, usually a complex piece of software to configure and control, onto less expensive, so-called commodity hardware.

One of SDN’s most controversial tenets is separating control and data planes. It’s not a new concept, but the contemporary way of thinking puts a twist on it: how far should the control plane be from the data plane, how many instances are needed for resiliency and high availability, and if 100% of the control plane can be moved beyond a few inches are all intensely debated. There are many possible control planes, ranging from the simplest, the fully distributed, to the semi- and logically centralized, to the strictly centralized.

OpenFlow Matching

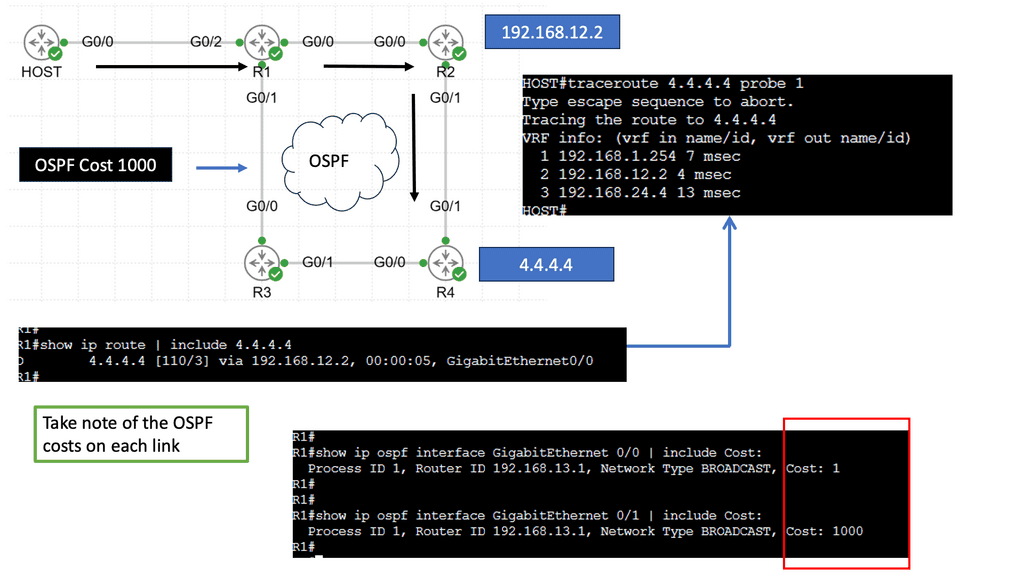
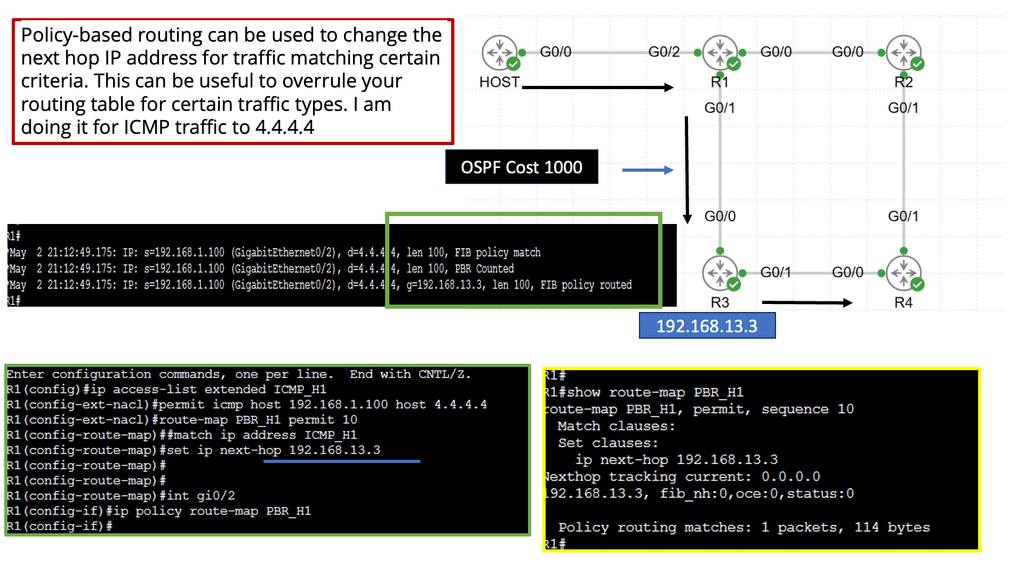
With OpenFlow, the forwarding path is determined more precisely (matching fields in the packet) than traditional routing protocols because the tables OpenFlow supports more than just the destination address. Using the source address to determine the next routing hop is similar to the granularity offered by PBR.

In the same way that OpenFlow would do many years later, PBR permits network administrators to forward traffic based on “nontraditional” attributes, such as the source address of a packet. However, PBR-forwarded traffic took quite some time for network vendors to offer equivalent performance, and the final result was very vendor-specific.

Example Technology: Policy Based Routing

**How Policy-Based Routing Works**

At its core, policy-based routing operates by applying a series of rules to incoming packets. These rules, defined by network administrators, determine the next hop for packets based on criteria such as source or destination IP address, protocol type, or even application-level data. Unlike conventional routing protocols that rely solely on destination IP addresses to make decisions, PBR provides the ability to consider a broader set of parameters, thus enabling more granular control over network traffic flows.

**Benefits of Implementing Policy-Based Routing**

One of the primary advantages of PBR is its ability to optimize network performance. By directing traffic along paths that make the most sense for specific types of data, network operators can reduce congestion and improve response times. Additionally, PBR can enhance security by allowing sensitive data to be routed over secure, encrypted pathways while less critical data takes a different route. This capability is particularly valuable in environments where network resources are shared across multiple departments or where specific compliance requirements must be met.

**Challenges and Considerations**

Despite its benefits, policy-based routing is not without challenges. The complexity of configuring and maintaining PBR rules can be daunting, especially in large networks with diverse requirements. Careful planning and ongoing management are essential to ensure that PBR implementations remain effective and do not introduce unintended routing behaviors. Moreover, network administrators must keep an eye on the broader network architecture to ensure that PBR policies align with overall network goals and do not conflict with other routing protocols in use.

**Use Cases: Real-World Applications of Policy-Based Routing**

Policy-based routing finds its place in a variety of real-world applications. In enterprise networks, PBR is often used to prioritize business-critical applications or to implement cost-saving measures by routing traffic over less expensive links when possible. It also plays a significant role in multi-tenant environments, where different customers or departments may require distinct levels of service. Additionally, PBR is instrumental in hybrid cloud environments, where data flows between on-premises infrastructure and cloud services must be managed efficiently.
**The Role of SDN Solutions**

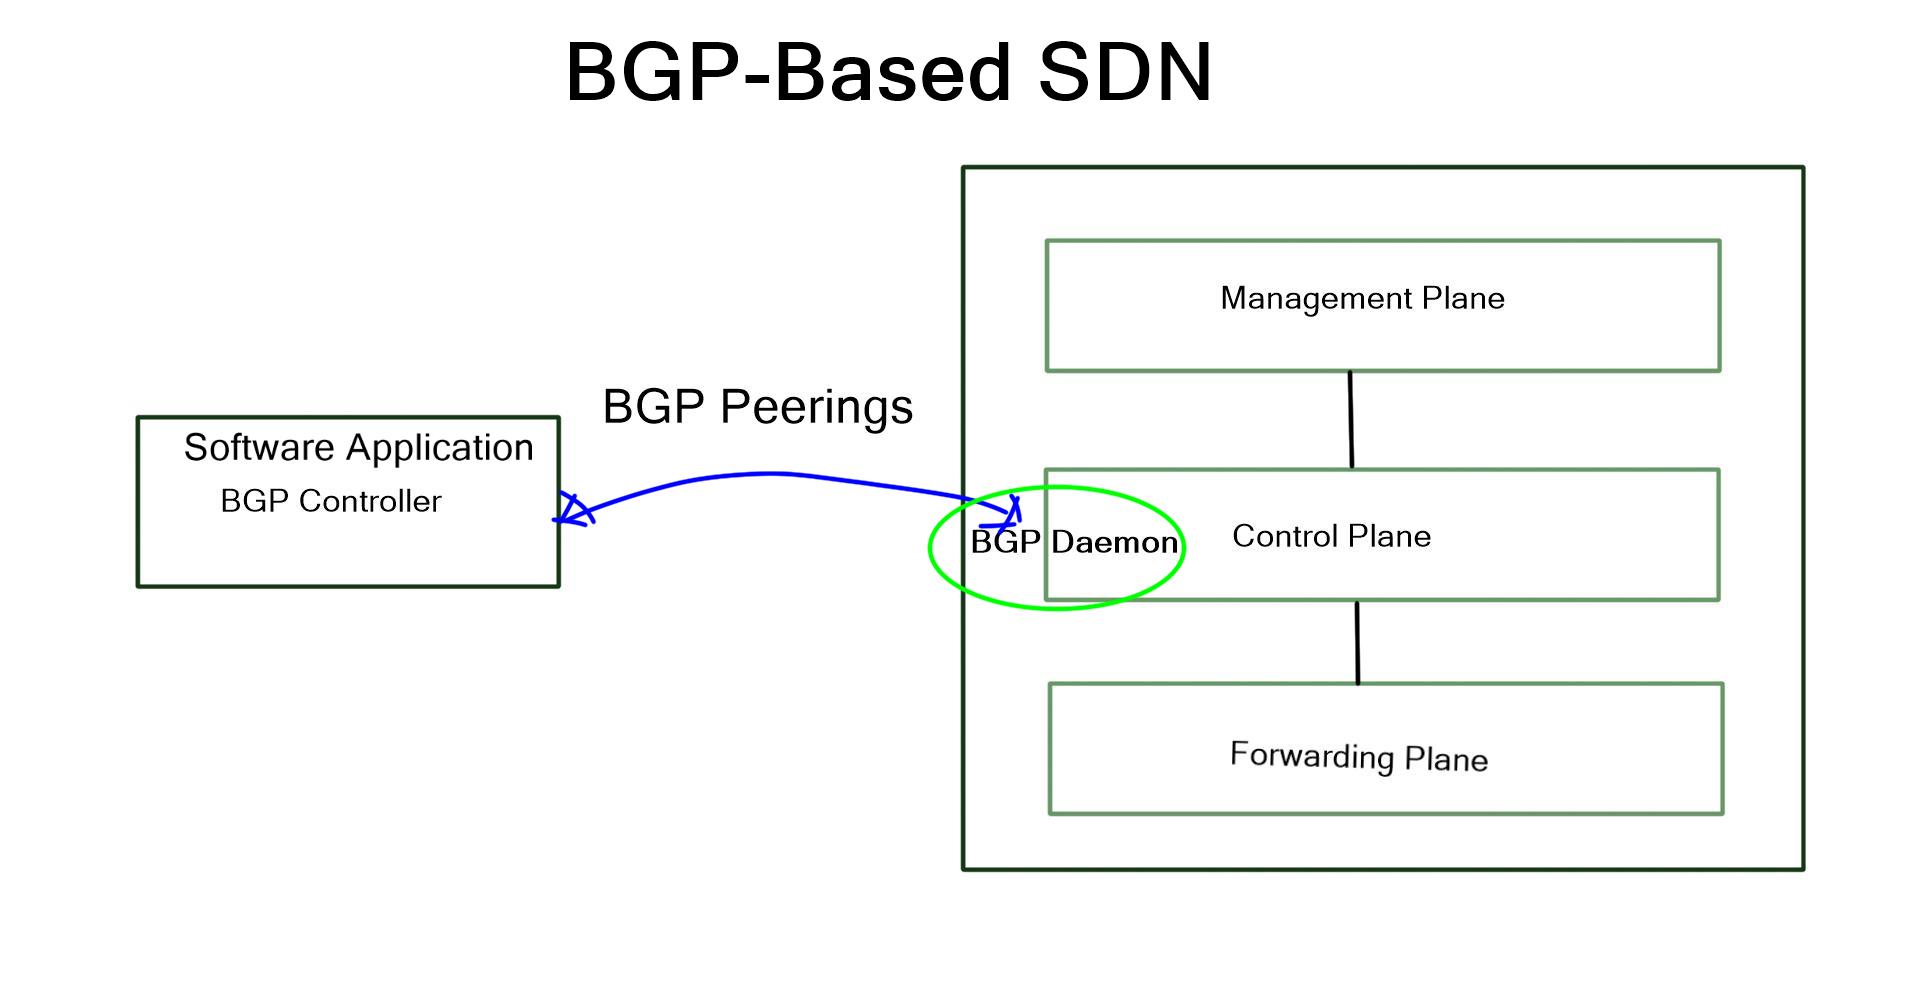
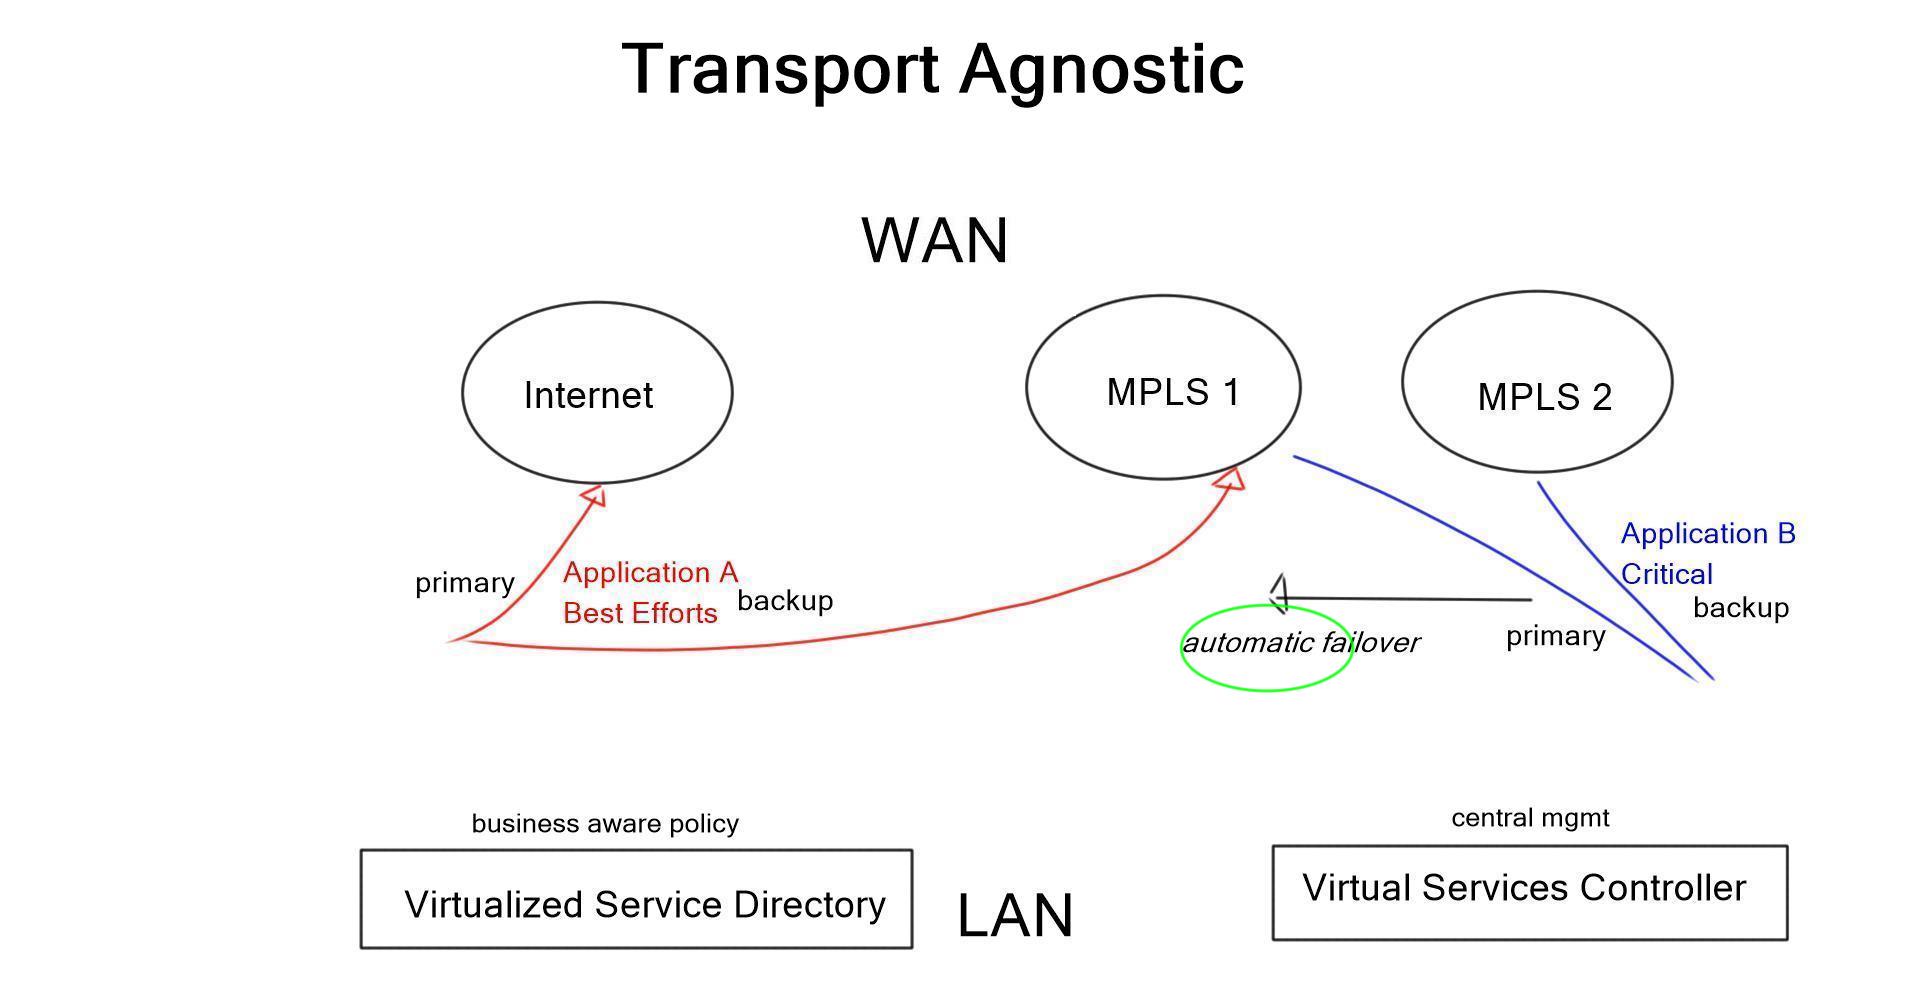
Most existing SDN solutions are aimed at cellular core networks, enterprises, and the data center. However, at the WAN edge, SD-WAN and WAN SDN are leading a solid path, with many companies offering a BGP SDN solution augmenting natural Border Gateway Protocol (BGP) IP forwarding behavior with a controller architecture, optimizing both inbound and outbound Internet-bound traffic. So, how can we use these existing SDN mechanisms to enhance BGP for interdomain routing at Internet Exchange Points (IXP)?

**The Role of IXPs**

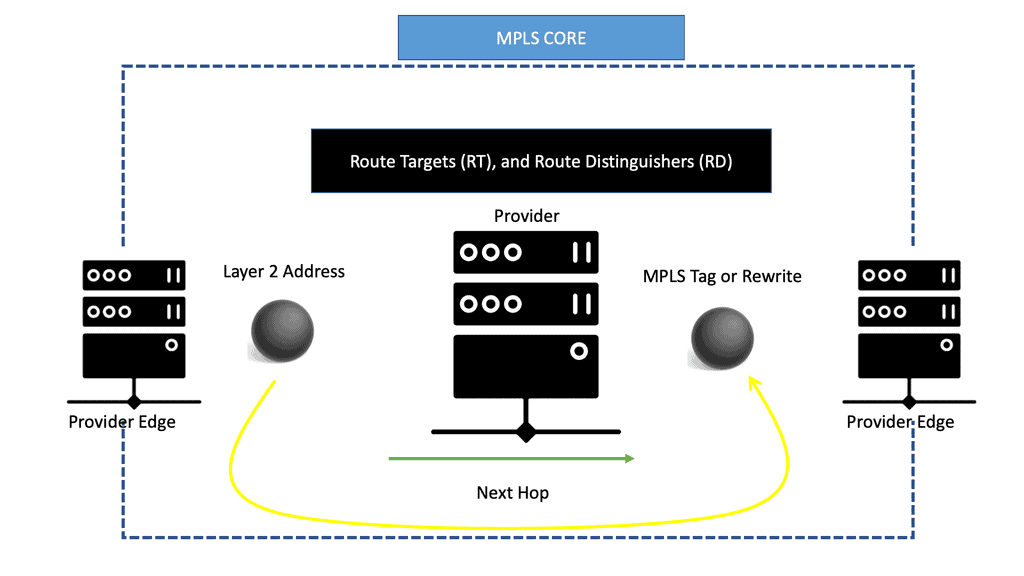
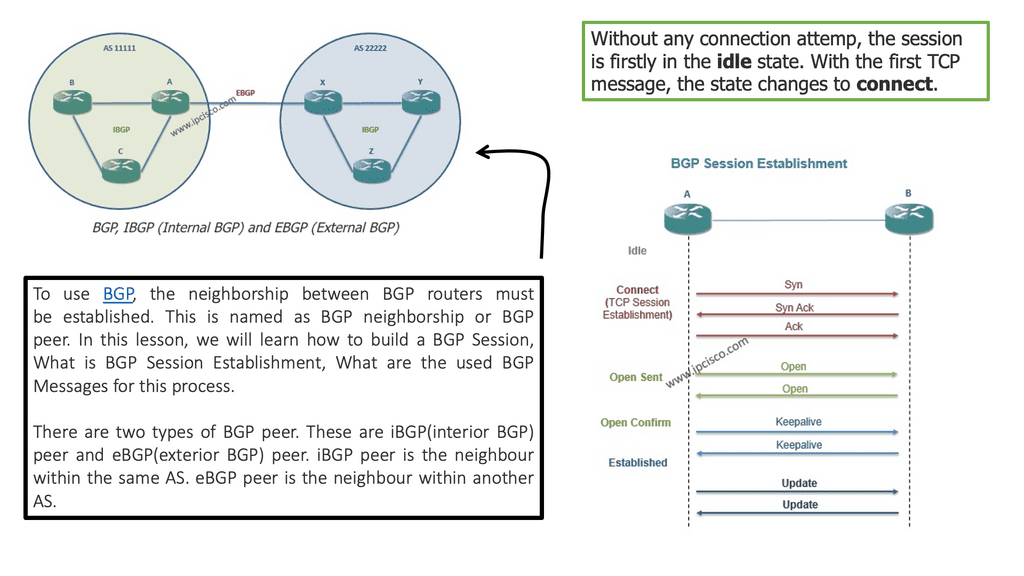
IXPs are location points where networks from multiple providers meet to exchange traffic with BGP routing. Each participating AS exchanges BGP routes by peering eBGP with a BGP route server, which directs traffic to another network ASes over a shared Layer 2 fabric. The shared Layer 2 fabric provides the data plane forwarding of packets. The actual BGP route server is the control plane to exchange routing information.
  1.  
SD-IX / SDX · INTERACTIVE LAB 02

What Can BGP Control — and What Needs a Programmable Policy?

Experiment with different traffic-engineering objectives and control mechanisms. See how destination-prefix routing differs from policies that can consider additional packet attributes.

Policy Compilation Path READY
PKT
Traffic Flow Destination prefix
POL
Policy Engine BGP route policy
FAB
IXP Fabric Forwarding decision
Available Match Fields Destination
Destination
Source
Protocol
Port
Application
Select a traffic objective and policy mechanism, then evaluate the design.
Policy Match Prefix
Path Choice Not Evaluated
Granularity Destination
Control Fit —
BGP Excellent for scalable inter-domain reachability and destination-prefix policy.
PBR Can introduce additional match criteria, but deployment and scale depend heavily on the network design.
SDX Adds a programmable policy layer capable of compiling richer traffic rules into the exchange fabric.
Conceptual simulation. The exact match fields, controller model, route-server behaviour and forwarding capabilities vary between implementations. This lab illustrates the architectural distinction rather than a specific SDX product.
Policy Evaluation
Awaiting evaluation...
Control-Plane Console
[READY] Policy engine awaiting input...
Engineering Insight

BGP is intentionally powerful at what it does: exchanging reachability information and selecting paths toward destination prefixes. More granular traffic steering requires additional mechanisms.

Software Defined Internet Exchange

An Internet exchange point (IXP) is a physical location through which Internet infrastructure companies such as Internet Service Providers (ISPs) and CDNs connect. These locations exist on the “edge” of different networks and allow network providers to share transit outside their network.

IXPs will run BGP.  Also, it is essential to understand that Internet exchange point participants often require that the BGP NEXT_HOP specified in UPDATE messages be that of the peer’s IP address, as a matter of policy.

Route Server

A route server provides an alternative to full eBGP peering between participating AS members, enabling network traffic engineering. It’s a control plane device and does not participate in data plane forwarding. There are currently around 300 IXPs worldwide. Because of their simple architecture and flat networks, IXPs are good locations to deploy SDN.

There is no routing for forwarding, so there is a huge need for innovation. They usually consist of small teams, making innovation easy to introduce. Fear is one of the primary emotions that prohibit innovation, and one thing that creates fear is Loss of Service.

This is significant for IXP networks, as they may have over 5 Terabytes of traffic per second. IXPs are major connecting points, and a slight outage can have a significant ripple effect.

  • A key point. Internet Exchange Design

SDX, a software-defined internet exchange, is an SDN solution based on the combined efforts of Princeton and UC Berkeley. It aims to address IXP pain points (listed below) by deploying additional SDN controllers and OpenFlow-enabled switches. It doesn’t try to replace the entire classical IXP architecture with something new but rather augments existing designs with a controller-based solution, enhancing IXP traffic engineering capabilities. However, the risks associated with open-source dependencies shouldn’t be ignored.

Challenges: Software Defined Internet Exchange: IXP Pain Points

BGP is great for scalability and reducing complexity but severely limits how networks deliver traffic over the Internet. One tricky thing to do with BGP is good inbound TE. The issue is that IP routing is destination-based, so your neighbor decides where traffic enters the network. It’s not your decision.

The forwarding mechanism is based on the destination IP prefix. A device forwards all packets with the same destination address to the same next hop, and the connected neighbor decides.

The main pain points for IXP networks:

As already mentioned, routing is based on the destination IP prefix. BGP selects and exports routes for destination prefixes only. It doesn’t match other criteria in the packet header, such as source IP address or port number. Therefore, it cannot help with application steering, which would be helpful in IXP networks.

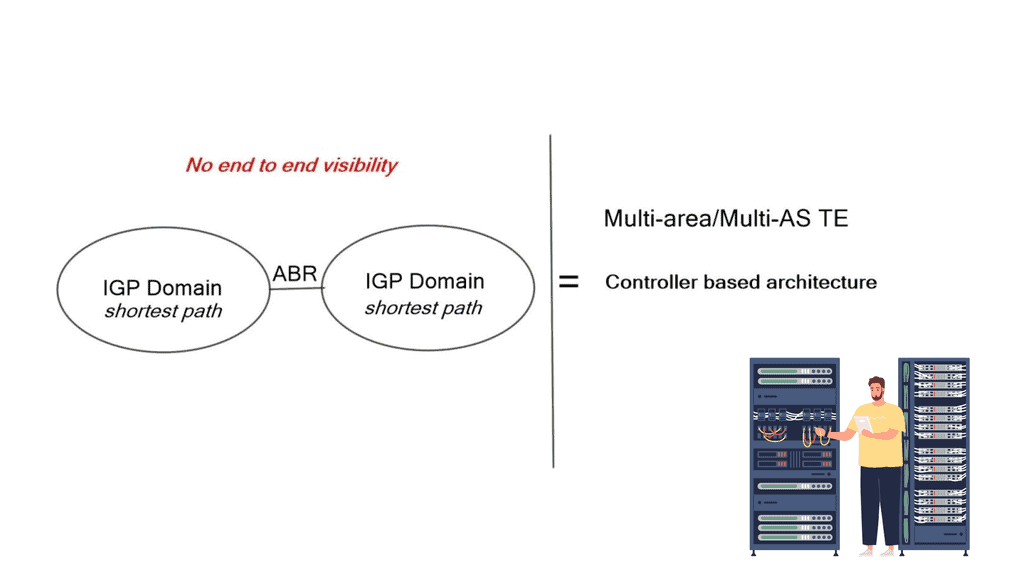
Secondly, you can only influence direct neighbors. There is no end-to-end control, and it’s hard to influence neighbors that you are not peering. Some BGP attributes don’t carry across multiple ASes; others may be recognized differently among vendors. We also use a lot of de-aggregation to TE. Everyone is doing this, which is why we have the problem of 540,000 prefixes on the Internet. De-aggregation and multihoming create lots of scalability challenges.

Finally, there is an indirect expression of policy. Local Preference (LP) and Multiple Exit Discriminator (MED) are ineffective mechanisms influencing traffic engineering. We should have better inbound and outbound TE capabilities. MED, AS Path, pretending, and Local Preference are widely used attributes for TE, but they are not the ultimate solution.

They are inflexible because they can only influence routing decisions based on destination prefixes. You can not do source IP or application type. They are very complex, involving intense configuration on multiple network devices. All these solutions involve influencing the remote party to decide how it enters your AS, and if the remote party does not apply them correctly, TE becomes unpredictable.

SDX: Software-Defined Internet Exchange

The SDX solution proposed by Laurent is a Software-Defined Internet Exchange. As previously mentioned, it consists of a controller-based architecture with OpenFlow 1.3-enabled physical switches. It aims to solve the pain points of BGP at the edge using SDN.

Transport SDN offers direct control over packet-processing rules that match on multiple header fields (not just destination prefixes) and perform various actions (not just forwarding), offering direct control over the data path. SDN enables the network to execute a broader range of decisions concerning end-to-end traffic delivery.

How does it work?

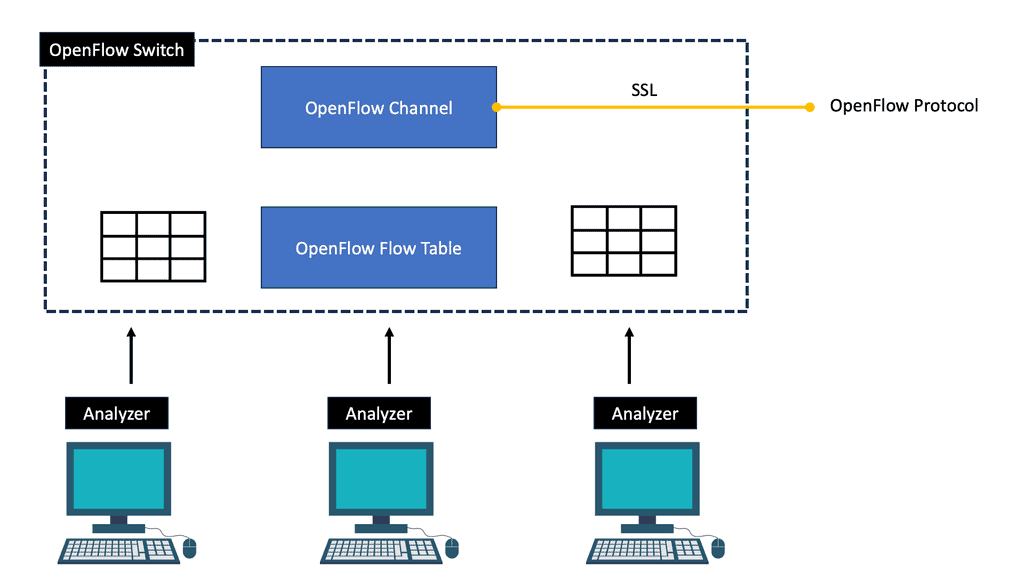
What is OpenFlow? Is the IXP fabric replaced with OpenFlow-enabled switches? Now, network traffic engineering is based on granular OpenFlow rules. It’s more predictable as it does not rely on third-party neighbors to decide the entry. OpenFlow rules can be based on any packet header field, so they’re much more flexible than existing TE mechanisms. An SDN-enabled data plane enables networks to have optimal WAN traffic with application steering capabilities. 

The existing route server has not been modified, but now we can push SDN rules into the fabric without requiring classical BGP tricks (local preference, MED, AS prepend). The solution matches the destination MAC address, not the destination IP prefix, and uses an ARP proxy to convert the IP prefixes to MAC addresses.

The participants define the forwarding policies, and the controller’s role is to compile the forwarding entries into the fabric. The SDX controller implementation has two main pipelines: a policy compiler based on Pyretic and a route server based on ExaBGP. The policy compiler accepts input policies (custom route advertisements) written in Pyretic from individual participants and BGP routes from the route server. This produces forwarding rules that implement the policies.

SDX Controller

The SDX controller combines the policies from multiple member ASes into one policy for the physical switch implementation. The controller is like an optimized compiler, compiling down the policy and optimizing the code in the forwarding by using a virtual next hop. There are other potential design alternatives to SDX, such as BGP FlowSpec. But in this case, BGP FlowSpec would have to be supported by all participating member AS edge devices.

Closing Points on Software Defined Internet Exchange

At its core, SDX is an evolution of traditional Internet Exchange Points (IXPs), which are critical nodes in the internet’s infrastructure, allowing different networks to interconnect. Traditional IXPs are hardware-driven, requiring physical switches and routers to manage traffic between networks. SDX, on the other hand, leverages the principles of SDN to introduce a software layer that enhances flexibility and control over these exchanges. This software-defined approach allows for dynamic configuration and management of network policies, enabling more efficient and tailored data traffic handling.

One of the primary benefits of SDX is its capacity for greater agility and adaptability in managing network traffic. Unlike traditional IXPs, SDX can quickly respond to changing network demands, optimizing the flow of data in real time. This adaptability is particularly beneficial for handling peak traffic periods or unexpected surges, ensuring that data exchanges remain smooth and uninterrupted. Additionally, SDX provides enhanced security features, as the software layer can be programmed to detect and mitigate potential threats more effectively than conventional hardware solutions.*

The implications of adopting SDX are vast and varied. For internet service providers, SDX offers the potential to provide more personalized services to their customers, adjusting bandwidth and routing protocols based on individual needs. Enterprises can benefit from SDX by gaining more control over their data exchanges, optimizing their network performance, and reducing operational costs. Furthermore, SDX is particularly advantageous for emerging technologies like the Internet of Things (IoT) and 5G networks, where the ability to efficiently handle large volumes of data is crucial.

Despite its many advantages, the transition to SDX is not without its challenges. Implementing SDX requires significant changes to existing network infrastructures, which can be costly and complex. Moreover, the shift to a software-centric model necessitates a new skill set for IT professionals, who must be adept in both networking and software development. There is also the consideration of interoperability, as networks must ensure that their SDX solutions can work seamlessly with other networks and legacy systems.

SD-IX / SDX · INCIDENT CHALLENGE

SDX Traffic Engineering Challenge

A customer wants only one class of traffic to use a different exchange path. Can conventional BGP policy solve the requirement, or does the problem need a more granular traffic-steering layer?

!
Incident: Video Traffic Is Taking the Wrong Exit AS65010 has two exchange paths. Peer A is congested, while Peer B has available capacity. General routing remains healthy, but the customer wants only video traffic to prefer Peer B.
AS65010 Customer Network
→
Peer A Congested · 92%
or
Peer B Healthy · 38%
→
Destination Content Network
BGP Sessions Established
Reachability Healthy
Peer A Congested
Peer B Available
Requirement Video Only
What is the best engineering response?
Challenge Score
Result — / 4
Select the response you believe best matches the evidence.
Incident Console
[READY] Incident loaded.
[BGP] Peer sessions established.
[PATH] Multiple exchange paths available.
[ALERT] Peer A congestion detected.
Engineering Insight

The important clue is “video only.” A global routing preference may affect more traffic than intended. The engineering challenge is therefore one of policy granularity, not basic reachability.

control room of railway,computers and train scheduling,China

SDN Router

SDN Router

In the ever-evolving world of networking, innovation plays a crucial role in driving efficiency and flexibility. One such groundbreaking technology that has gained significant momentum in recent years is Software-Defined Networking (SDN). At the heart of this transformative approach lies the SDN router, a key component that promises to revolutionize network infrastructure. In this blog post, we will explore the concept of SDN routers, their benefits, and their impact on network management and performance.

SDN routers are the backbone of Software-Defined Networking. Unlike traditional routers, which rely on static configurations, SDN routers separate the control plane from the data plane. This decoupling allows for centralized network management and enables dynamic and programmable control over network traffic flows. By leveraging open protocols, such as OpenFlow, SDN routers provide a level of flexibility and agility that was previously unimaginable.

Enhanced Scalability: SDN routers facilitate seamless scalability by abstracting the underlying physical infrastructure. Network administrators can easily add or remove virtual network functions, making it simpler to accommodate growing network demands.

Simplified Network Management: With the centralized control plane, SDN routers streamline network management tasks. Administrators can define and enforce network policies from a single point, simplifying configuration, monitoring, and troubleshooting processes.

mproved Network Performance: SDN routers enable intelligent traffic engineering and load balancing. By dynamically redirecting traffic based on real-time conditions and application needs, network performance and efficiency are significantly enhanced.

Data Centers: SDN routers find extensive application in data center environments. They enable efficient virtual machine migration, facilitate workload balancing, and ensure optimal utilization of network resources.

Wide Area Networks (WANs): In WAN deployments, SDN routers offer centralized control and visibility, making it easier to manage geographically dispersed networks. They enhance security, simplify policy enforcement, and enable seamless integration of multiple service providers.

Internet of Things (IoT): The scalability and flexibility of SDN routers make them ideal for IoT deployments. They provide efficient connectivity, intelligent traffic routing, and support for various IoT protocols, enabling seamless integration of diverse devices and applications.

The rise of SDN routers marks a paradigm shift in network infrastructure. By decoupling the control and data planes, these routers unlock unprecedented levels of flexibility, scalability, and performance. With benefits ranging from simplified network management to enhanced scalability and improved traffic engineering, SDN routers are poised to transform the way we design, deploy, and manage networks. As organizations embrace digital transformation, SDN routers will continue to play a vital role in shaping the future of networking.

SDN ROUTER · INTERACTIVE LAB 01

How Does an SDN Controller Choose the Best Path?

Traditional routing distributes path information and lets routers calculate forwarding decisions locally. An SDN architecture can instead build a broader network view, evaluate multiple paths and program the resulting forwarding behaviour into the data plane.

SDN Control Plane → Data Plane READY
CTRL
SDN Controller Network state available
Selected Path —
Latency —
Capacity —
Backup Path —
Conceptual simulation. Real SDN controllers use platform-specific topology, telemetry, policy and forwarding mechanisms. This lab illustrates the control-plane decision process rather than a particular vendor implementation.
Decision
Run the experiment to calculate the forwarding decision.
Network View —
Path Evaluation —
Forwarding Action —
Control-Plane Trace
[READY] Controller awaiting network event.
Engineering Insight

The important architectural distinction is not that SDN magically creates better routes. The advantage is that a controller can combine a broader network view with policy and telemetry before programming forwarding behaviour.

Highlights: SDN Router

SDN routers serve as the crucial building blocks of Software-Defined Networking. Unlike traditional routers, they separate the control plane from the data plane, enabling centralized network management and programmability. By decoupling these two planes, SDN routers empower network administrators with unprecedented flexibility and control over network traffic.

SDN routers incorporate cutting-edge features that set them apart from their conventional counterparts. These routers leverage OpenFlow, a key protocol in the SDN ecosystem, to manage and direct network traffic flows. With granular flow control, quality of service (QoS) prioritization, and dynamic traffic engineering, SDN routers optimize network performance and enhance overall efficiency.

**Benefits of SDN Routers**

1. Enhanced Network Agility: By centralizing the control plane, SDN routers provide network administrators with complete visibility and control over the network. This enables them to quickly adapt to changing network requirements, allocate resources efficiently, and respond to real-time security threats.

2. Simplified Network Management: SDN routers simplify network management by providing a single interface for configuring, monitoring, and troubleshooting the network. By programmatically defining network policies, administrators can automate routine tasks and reduce the complexity associated with traditional router configurations.

3. Scalability and Flexibility: SDN routers offer unparalleled scalability, allowing networks to grow and efficiently accommodate increasing traffic demands. With programmable routing policies and traffic engineering capabilities, SDN routers enable dynamic network provisioning, ensuring optimal resource utilization and performance across the network.

4. Improved Security: SDN routers provide enhanced security features like fine-grained access control and traffic isolation. By centralizing security policies and implementing them consistently across the network, SDN routers mitigate security risks and provide a robust defense against potential threats.

**Real-world Applications**

SDN routers have found wide-ranging applications across various industries. Some notable examples include:

1. Data Centers: SDN routers enable agile and efficient management of large-scale data center networks. By abstracting network control from the underlying physical infrastructure, administrators can create virtual networks, provision resources on demand, and implement fine-grained security policies.

2. Wide Area Networks (WAN): SDN routers offer significant advantages in WAN environments. They enable network administrators to optimize traffic routing, dynamically allocate bandwidth, and prioritize critical applications, improving network performance and reducing costs.

3. Internet Service Providers (ISPs): SDN routers empower ISPs to deliver innovative services and offerings to their customers. With programmable routing policies, ISPs can offer tailored services, implement Quality of Service (QoS) guarantees, and ensure optimal utilization of network resources.

SDN Control‑Plane Decision Engine

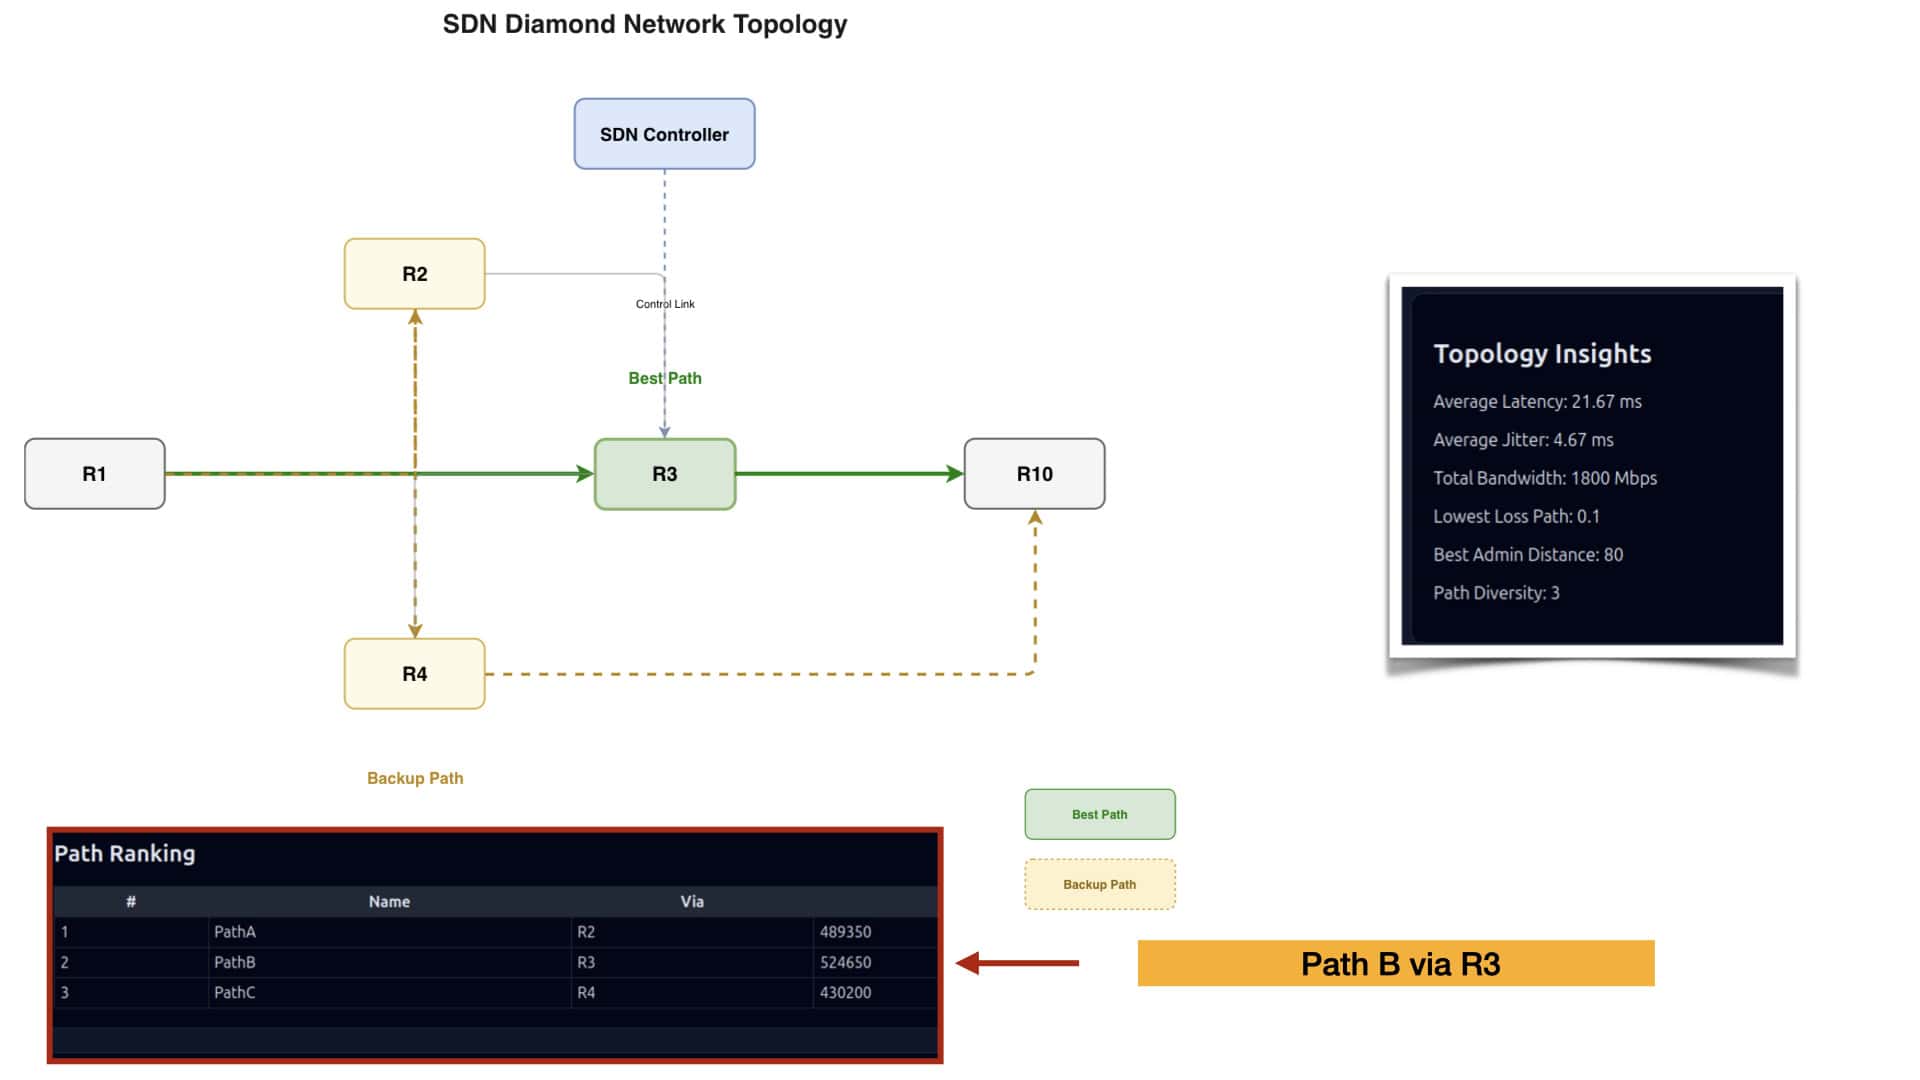
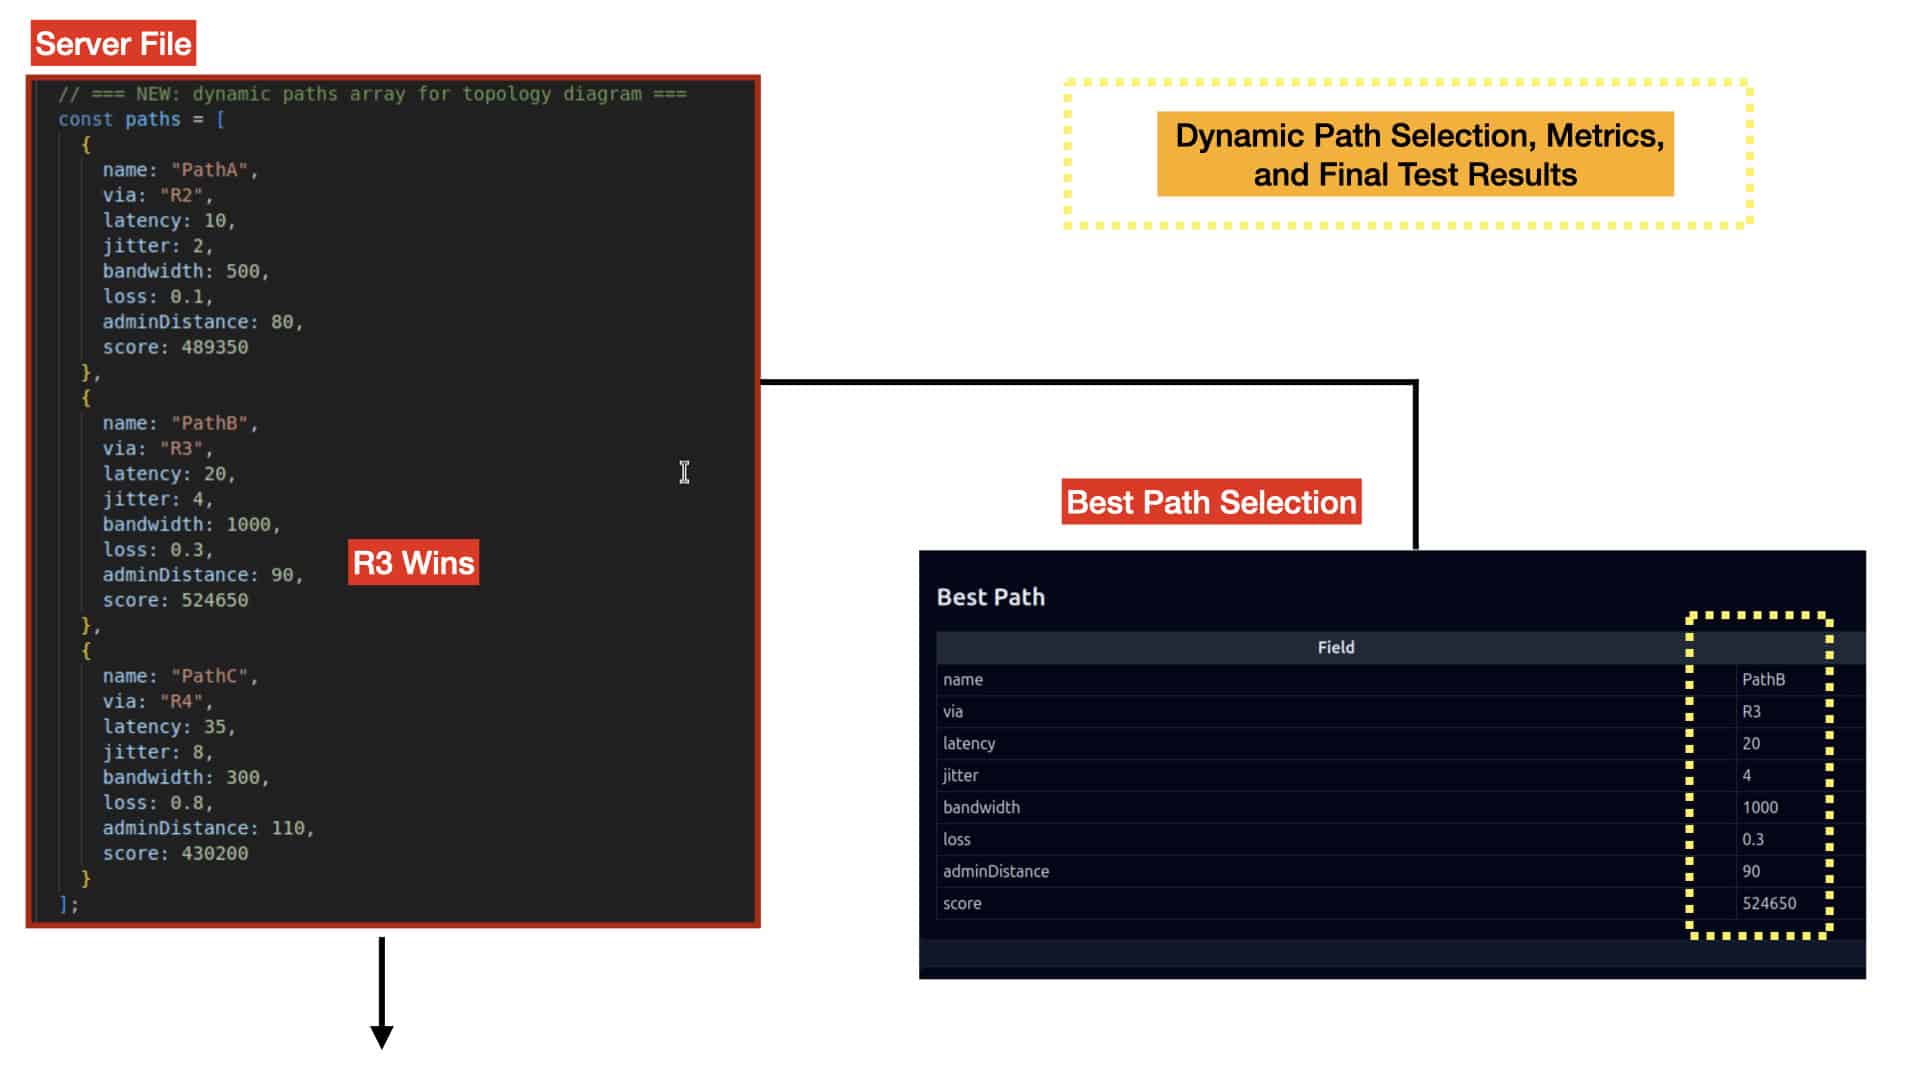
This lab demonstrates how an SDN controller evaluates multiple forwarding paths between a source router (R1) and a destination router (R10) using real‑time metrics such as latency, jitter, bandwidth, loss, and administrative distance. The physical topology is arranged in a diamond‑mesh layout, allowing the controller to select an optimal best path while maintaining a redundant backup path. The SDN controller sits above the data plane and pushes flow rules to the routers based on the computed best path. The lab includes a dynamic dashboard that visualizes the topology, highlights the active and passive paths, and displays the full decision trace produced by the control‑plane logic

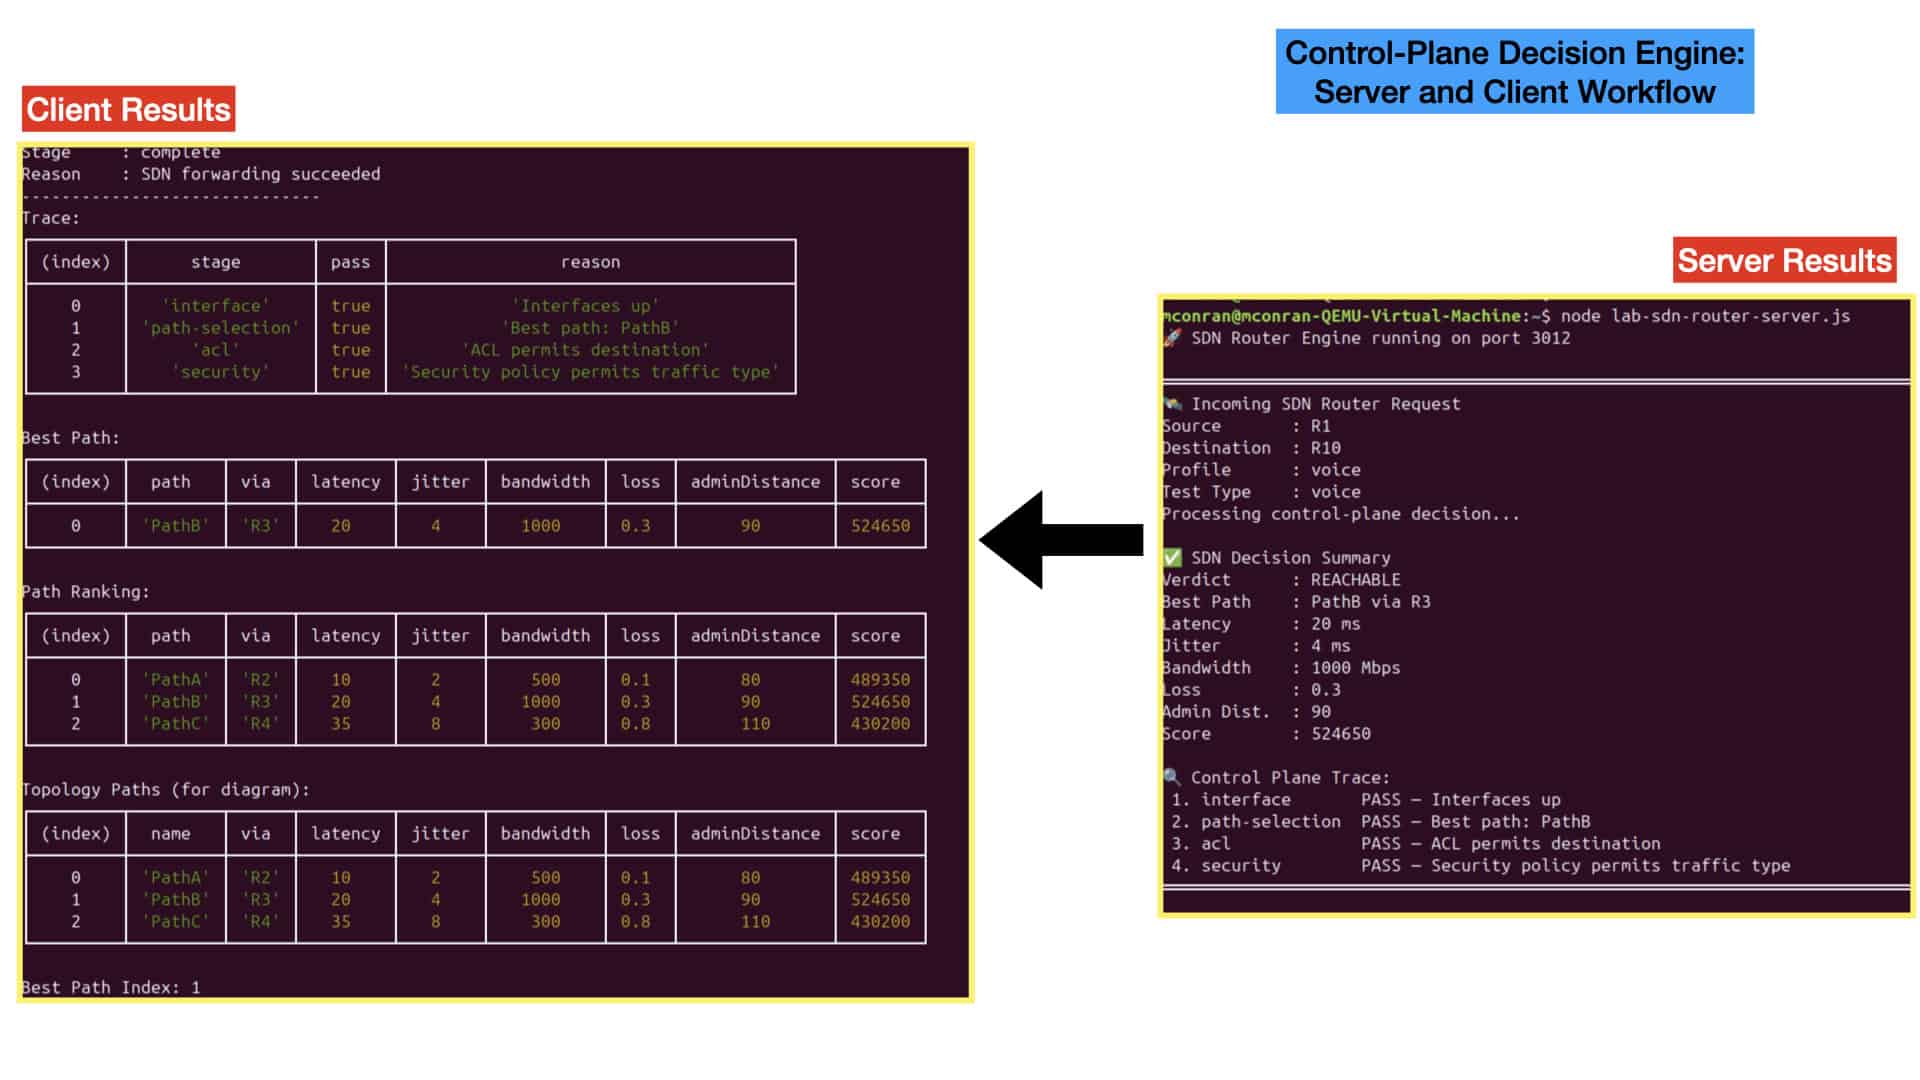
The backend engine (lab-sdn-router-server.js) exposes a JSON API that computes path metrics, ranks all available routes, and determines the best forwarding path using a scoring algorithm. It returns structured decision data including the best path, backup path, full path ranking, and a detailed control‑plane trace. The client file (lab-sdn-router-client.js) sends a test request to the server, receives the JSON response, and prints a formatted summary of the SDN decision to the terminal. Together, the server and client provide both machine‑readable and human‑readable outputs, ensuring the lab behaves like a real SDN controller and router environment.

When the lab runs, the server computes three candidate paths and selects the highest‑scoring one as the active best path. The dashboard receives this data and dynamically updates the topology diagram: the best path is drawn as a high glowing arc, the backup path as a lower dashed arc, and the SDN controller pulse is directed toward the chosen via router. The insights panel displays aggregated metrics such as average latency, jitter, total bandwidth, lowest loss, and path diversity. The final decision node confirms whether the destination is reachable and shows the exact reasoning behind each control‑plane stage. This creates a complete, end‑to‑end SDN lab experience with live metrics, visual feedback, and full traceability.

A Key Points: Changing the network paradigm

The success of SDN makes it clear that operators want to manage networks in a centralized and programmable way. Operating with a central viewpoint brings many advantages to existing networks and significantly enhances traffic engineering capabilities for a new data center design guide. However, changing the network paradigm with brand-new technologies comes at an operational and security cost.

OSPF SDN

The Role of Fibbing with OSPF

Fibbing is an OSPF SDN mechanism that controls the forwarding behavior of an unmodified router-speaking OSPF without losing the benefits of distributed routing protocols. It combines the centralized approach of SDN with the advantages of traditional link-state protocols. The workings originate from a combined approach between Princeton University and ETH Zurich. The controller code is available on Github, found at this link.

Fibbing is a technique that offers direct control over the router’s forwarding by manipulating the distributed routing protocol. The solution works on the concept of lying or fibbing to the router to make more effective routing control decisions. In addition, it makes OSPF more flexible by adding central control over distributed routing. OSPF operates as usual with shortest path routing, and Fibbing introduces methods to trick the router into computing any path it wants.

Traditional Routing vs Routing Control

The routing algorithms implemented by routers are decentralized. They communicate and converge toward the best routing path over time. Once a router fails or is added to the network, the network self-heals and again converges towards the best routing path.

An SDN implements centralized routing, meaning that a central controller knows where all the switches and end hosts are and can map the shortest path across the network. The controller will then install rules on the switches that allow flows to traverse that path without further interaction with the controller (the controller typically sees the first packet).

To communicate with your neighboring network, you still need a router on the border of an SDN network. Your SDN controller can’t know about their network, nor can it write permissions to their switches.

**Traditional Routing: The Old Guard of Network Management**

Traditional routing relies on a distributed architecture where routers independently make decisions based on protocols like RIP, OSPF, and BGP. These routers use pre-defined algorithms to determine the best path for data transmission, considering factors such as hop count, bandwidth, and delay. While this method has proven reliable over the years, it often lacks the flexibility and adaptability needed in today’s dynamic network environments. The distributed nature can lead to longer convergence times and is less adept at handling rapid changes in network topology.

**Routing Control in SDN: A Paradigm Shift**

Enter Software-Defined Networking, a revolutionary approach that separates the control plane from the data plane, centralizing network intelligence. In SDN, routing control is managed by a centralized controller that has a global view of the network. This allows for more dynamic and efficient routing decisions, adapting quickly to network changes and optimizing paths based on real-time data. SDN’s programmability means that new routing protocols and policies can be implemented without the need for hardware changes, offering unparalleled flexibility.

**Comparative Advantages: Traditional vs. SDN Routing**

When comparing traditional routing and SDN routing control, several key differences emerge. Traditional routing is known for its robustness and stability, qualities developed over decades of use in various environments. However, it can be rigid and slow to adapt. In contrast, SDN offers agility and rapid adaptability, making it ideal for environments that require frequent updates and changes. The centralized control of SDN also enables better network management and security, as policies can be quickly enforced across the entire network.

**Challenges and Considerations**

Despite its advantages, SDN is not without challenges. The centralized nature can be a single point of failure, and the initial setup can be complex and costly. Organizations must weigh these factors against the potential for improved network performance and flexibility. On the other hand, sticking with traditional routing may mean missing out on the benefits of modern network innovation. It’s essential for businesses to evaluate their specific needs and network demands when deciding between these approaches.

Example Routing Technology: OSPFv3

**The Evolution from OSPFv2 to OSPFv3**

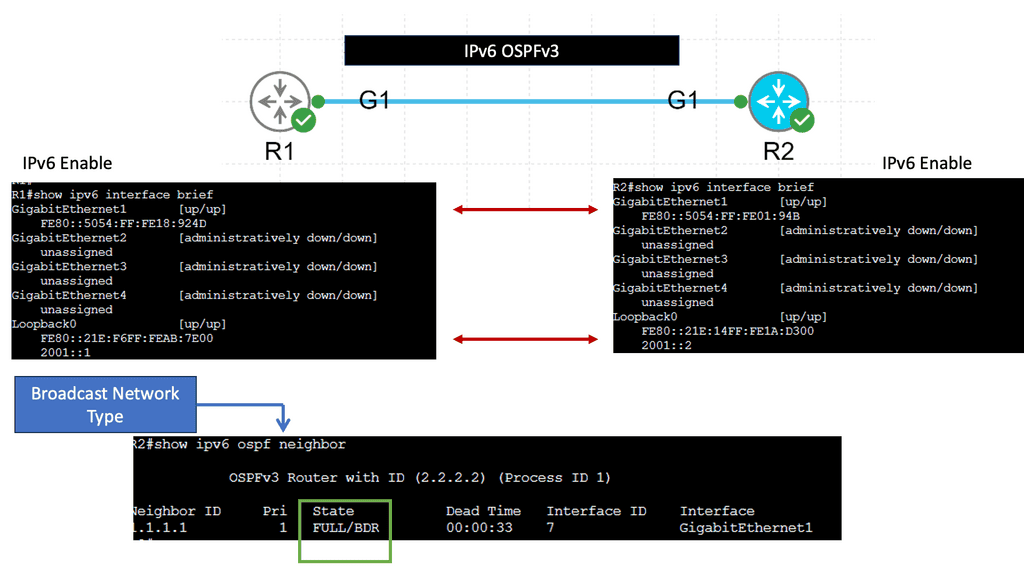
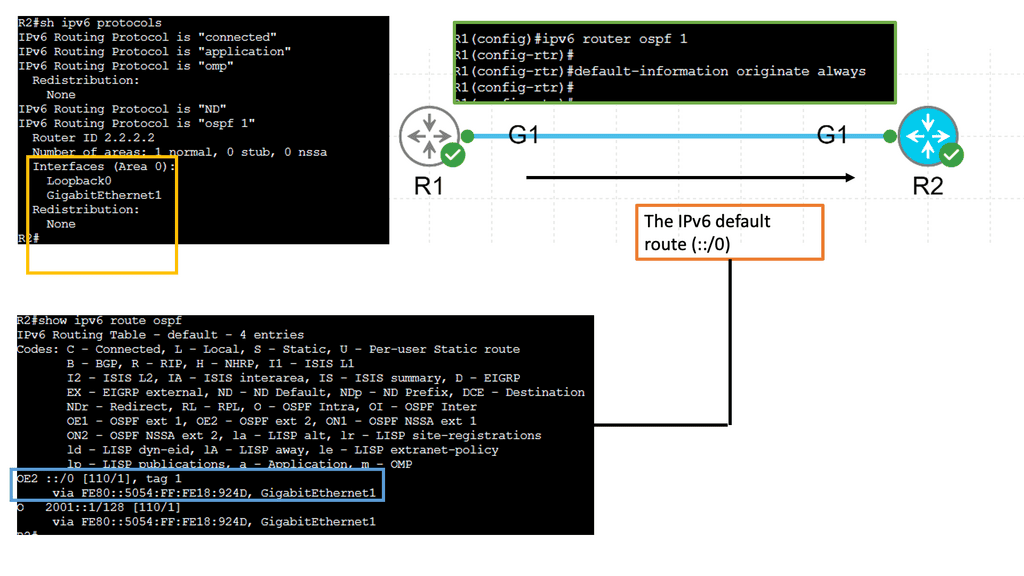
OSPFv3 is essentially an adaptation of OSPFv2 to support IPv6. While OSPFv2 was designed for IPv4 networks, the shift to IPv6 necessitated a protocol capable of handling its expanded address space and improved capabilities. One of the significant changes in OSPFv3 is its ability to separate protocol and address families, allowing for more flexibility and scalability. This evolution not only supports IPv6 but also maintains backward compatibility with IPv4, ensuring a seamless transition for organizations upgrading their network infrastructure.

**Key Features of OSPFv3**

OSPFv3 introduces several new features that make it a robust choice for modern networks. One notable feature is its support for multiple instances per link, which allows for more granular control and segmentation of network traffic. Additionally, OSPFv3 employs a link-local address for neighbor discovery, enhancing security and reducing overhead. Another critical enhancement is the use of IPv6’s inherent security features, such as IPsec, which provides built-in authentication and encryption capabilities. These features collectively make OSPFv3 a powerful and secure routing protocol for IPv6 environments.


SDN ROUTER · INTERACTIVE LAB 02

What Can Routing Policy Influence?

Not every traffic-engineering mechanism gives the same level of control. Experiment with distributed routing, routing-policy techniques and programmable SDN policy to see how the scope of the forwarding decision changes.

Policy → Forwarding Path READY
SRC
Traffic Source Customer / application
Routing Policy Select a mechanism to see its control scope.
EXIT
Preferred Exit Awaiting policy decision
Granularity —
Policy Scope —
Event Response —
Path State —
Illustrative model only. BGP attributes, OSPF metrics, PBR and programmable forwarding behave differently across platforms and are subject to routing policy, topology and implementation.
Experiment Result
Choose a traffic class and control mechanism, then run the experiment.
Traffic Match —
Forwarding Influence —
Remote Impact —
Failure Behaviour —
Policy Trace
[READY] Policy experiment awaiting input.
Engineering Insight

The key question is not simply whether a mechanism can change a route. It is what information the mechanism can match and whether it influences your own forwarding decision, a neighbour's decision, or the data plane directly.

SDN Router

Highlighting SDN

Software-defined Networking (SDN) involves separating routing control from the individual network elements and putting it in the hands of a centralized control layer. For instance, an SDN such as OpenFlow lets you choose the correct forwarding information per flow.

This means there need not be any separation on a VLAN level within a data center to enforce traffic separation between tenants. Instead, the controller would have a set of policies that only allow the traffic from within one “VLAN” to be forwarded to other devices within that same “VLAN” on a per source/destination (or flow) basis.

SDN Router: OSPF SDN

OSPF is still destination-based forwarding, meaning a device will forward all packets with the same destination address to the next hop. Paths are computed as the shortest path over a shared weighted graph. The Fibbing mechanism does not try to change OSPF default behavior. However, the mechanisms involved in the solution enable the forwarding of different flows destined for the same destination over different paths, increasing link utilization and the total available bandwidth. The controller introduces fake nodes and links through standard routing protocol messages.

OSPF SDN: How can I use existing protocols to program my network with SDN?

Routing protocols are an excellent API for programming a router’s state. Vendors may incorporate different implementations and CLI contexts, but they all speak the same protocol and follow RFC guidelines. Routing protocols are well known, and their behaviors have been studied for years.

Vendors have enhanced and optimized OSPF differently, but its framework does not change. They are using OSPF in the context of SDN leverages over 25 years of solid engineering. Combining SDN with existing routing protocols to enhance forwarding behavior is not new.

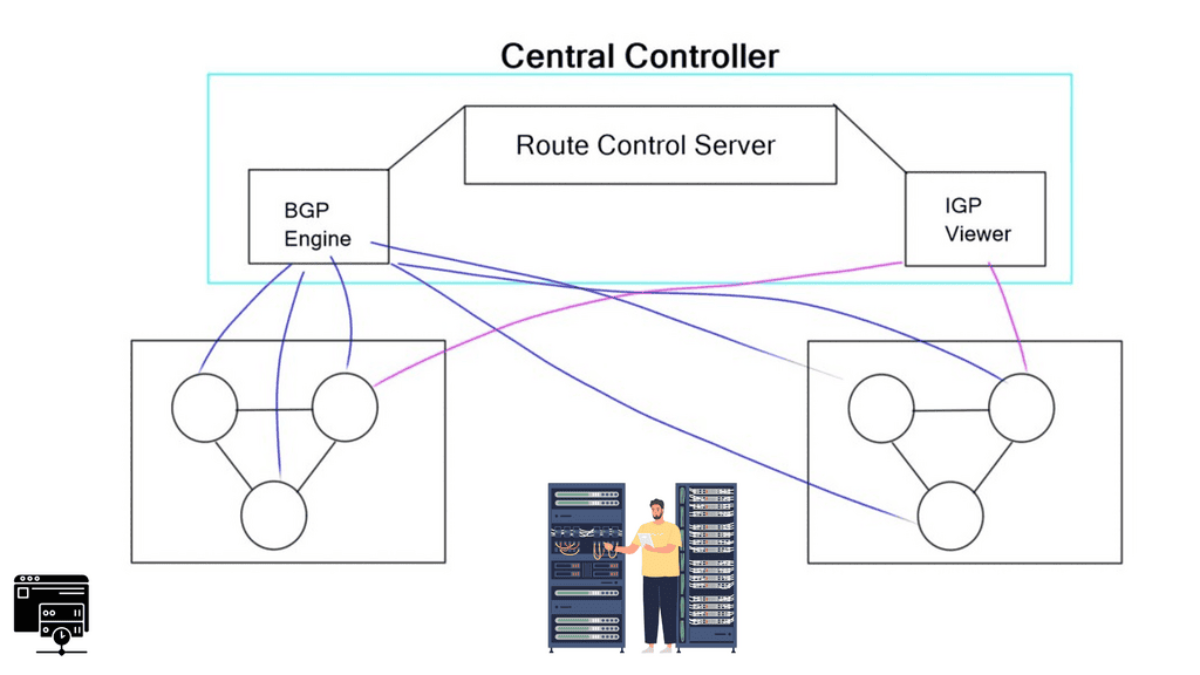
The first solution was the routing control platform (RCP), proposed by Princeton University and AT&T Labs-Research. The RCP solution has an IGP viewer and a BGP function to provide a central function. More recently, P. Lapukhov & E. Nkposong proposed a centralized routing model and introduced the concept of BGP SDN.

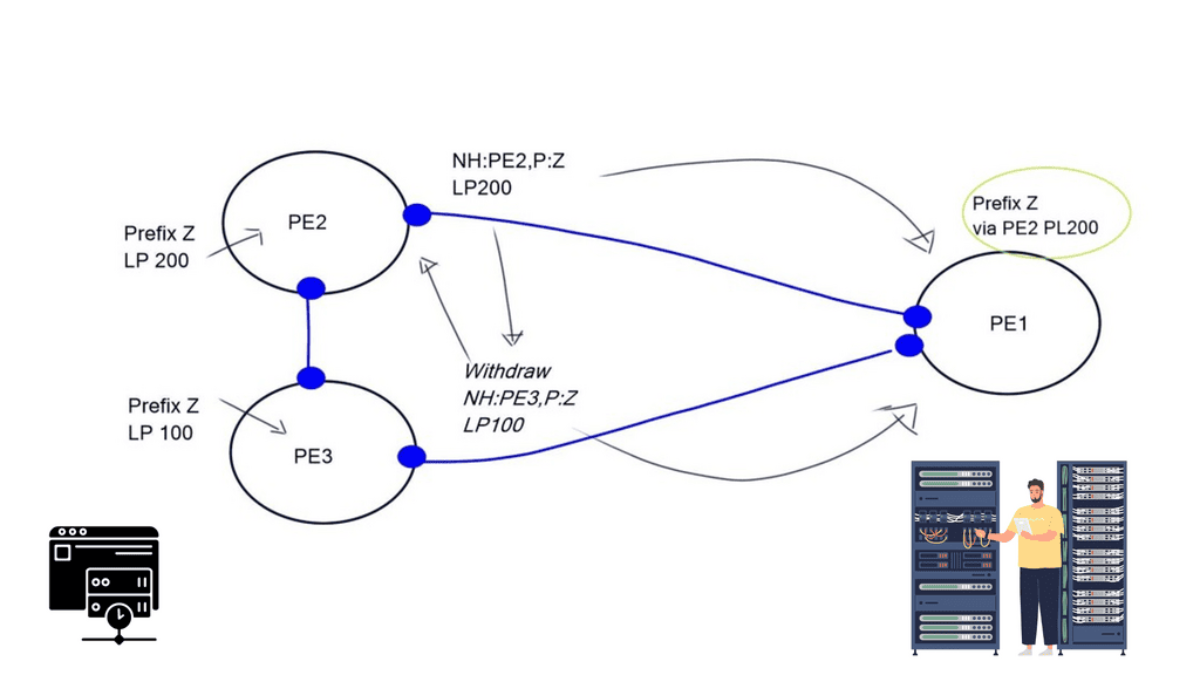
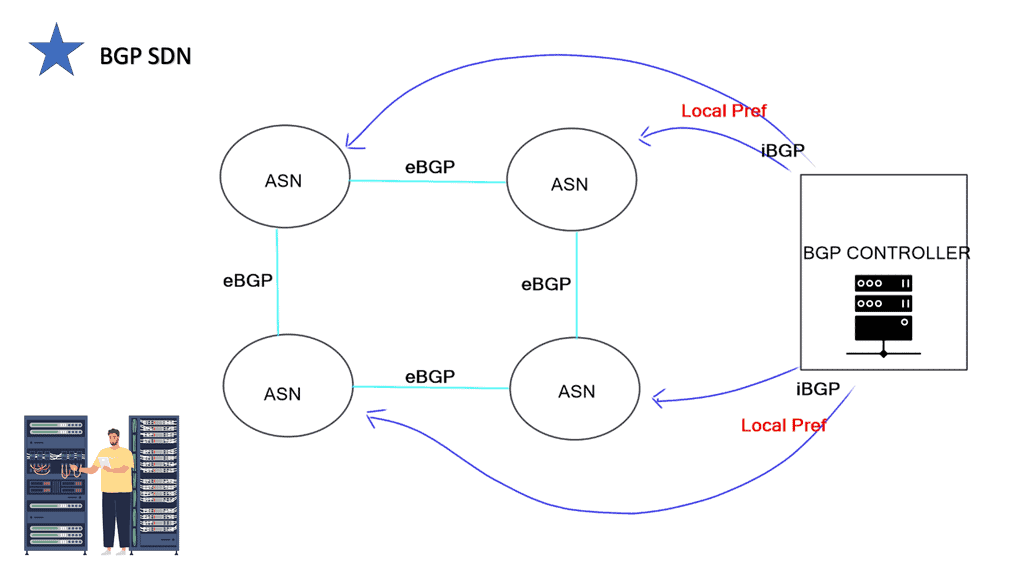
Petre solution uses a BGP controller to manipulate BGP parameters (Local Preference) and influence forwarding. It enables networks to run only BGP routing with enhanced traffic behavior.

OSPF SDN

How do you move traffic over a less congested link? 

With OSPF-TE, you can change the cost or deploy some other 3rd party product, which is potentially expensive. If you want to change the forwarding state and don’t want to configure complex nested route maps or policy-based routing (PBR), the only remaining resource available to you is the routing protocol.

Fibbing is limited to the semantics of OSPF destination-based forwarding and is less potent than OpenFlow traffic optimizations. You can change the forwarding paths for specific prefixes, but OpenFlow doesn’t have total traffic engineering flexibility. However, you can use the solution with FlowSpec to gain extra granularity.

OSPF Forwarding Address

There are two ways to lie to a router: a Global lie and a Local lie.

Fibbing inserts an extra Type-5 LSA, allowing you to set a third-party next hop with the Forwarding Address (FA) feature. Type-5 LSAs are external link LSAs used to advertise external routes. They are flooded through the OSPF domain and point packets for those external addresses. The concept of an FA within a Type-5 LSA allows the selection of third-party next hops. The solution relies on third-party next hops to influence packet forwarding.

The FA is usually set to 0.0.0.0, meaning packets should be sent directly to the ASBR. In a Fibbing configured network, Type-5 LSA is injected with an FA to direct traffic to the destination at a better cost; the forwarding address is set with a specific address combined with a preferred metric. The costs can be tweaked to attract more or fewer people.

Influence Forwarding with Type5-LSA

There are two ways to influence forwarding with Type-5 LSA. One way is to have the forwarding address resolvable by ALL routers in the network. The FA is injected into the IGP, and all nodes can reach it. This method is used to make global decisions.

The other method is to have a locally known FA, influencing individual OSPF router decisions. For this, they create an FA for every next hop in the network, which has to be statically configured. On every router on your network, you need a static host route for each outgoing interface that you need to include for Fibbing. One fake static route per interface needs to be done once. If the FA is configured to be one of these, only that single router will use it.

Benefit: Not a Full SPF

The benefit of using a Type 5 LSA is that it does not cause a full SPF; it’s the distance vector part of OSPF. The impact is small and linear with the number of LSA. The team at Princeton and Zurich proposes that the Fibbing solution can scale to 100,000 Type-5 LSA.

Closing Points on SDN Routers

Unlike traditional routers, which rely heavily on physical hardware and manual configurations, SDN routers leverage software-based control. This shift allows for more dynamic, efficient, and responsive networking solutions. By decoupling the control plane from the data plane, SDN routers provide enhanced flexibility and programmability, enabling network administrators to manage network resources more effectively.

SDN routers bring a myriad of advantages to the table. One of the most significant benefits is the ability to automate network management tasks, reducing the need for manual intervention and minimizing human error. Additionally, SDN routers offer improved scalability, allowing networks to grow and adapt without significant hardware investments. Moreover, the centralized control provided by SDN technology results in better network visibility and the ability to implement advanced security measures more efficiently. These features make SDN routers an attractive option for businesses looking to future-proof their network infrastructure.

The impact of SDN routers can be seen across various industries. In telecommunications, SDN technology is transforming how service providers manage and deliver services, offering faster and more reliable connections. In the enterprise sector, companies are leveraging SDN routers to enhance their data centers, streamline operations, and support cloud-based applications. Educational institutions are also benefiting, using SDN to create flexible and secure campus networks that can adapt to the ever-changing technological landscape. These real-world applications highlight the versatility and potential of SDN routers to revolutionize networking.

Despite the numerous benefits, the adoption of SDN routers does come with its challenges. One of the primary concerns is the need for new skills and expertise to manage and operate SDN environments. Network professionals must be trained in the latest software-defined technologies to fully capitalize on these systems. Additionally, interoperability with existing legacy systems can be a hurdle, requiring careful planning and execution for seamless integration. Organizations must weigh these challenges against the potential rewards when considering a shift to SDN routers.

SDN ROUTER · INCIDENT CHALLENGE

SDN Routing Challenge: Move Traffic Without Breaking Reachability

You are operating an R1–R10 network. The primary path is becoming congested, but the requirement is very specific: move API traffic to another path while leaving normal web traffic unchanged. Choose the control mechanism that best matches the problem.

Incident API latency has increased on the preferred path. An alternative path has spare capacity. The network must continue carrying web traffic on its existing path while API traffic is selectively redirected.
Current Network State
A
R1 → R2 → R6 → R10 12 ms · 88% utilisation · Current preferred path
CONGESTED
B
R1 → R3 → R7 → R10 19 ms · 42% utilisation · Available capacity
AVAILABLE
C
R1 → R4 → R8 → R10 27 ms · 61% utilisation · Backup path
STANDBY
Web traffic Remain on the existing preferred path.
API traffic Move to the lower-utilisation path.
Reachability Must remain available throughout.
Choose Your Control Mechanism
Challenge Score 0 / 4
Select a mechanism and evaluate the incident.
Investigation target: Determine which control mechanism can change API forwarding without unnecessarily changing the forwarding behaviour of web traffic.
Incident Trace
[READY] Incident investigation started.
Engineer Hint
Ask what the mechanism can match. A destination-based routing metric can change the path for a destination, while more granular policy mechanisms can classify traffic before selecting a forwarding action.
This is a conceptual challenge. Actual PBR, SDN and routing-policy capabilities vary by platform, protocol implementation and controller/data-plane design.
African man in glasses gesturing while playing in virtual reality game

Virtual Firewalls

Virtual Firewalls

In cybersecurity, firewalls protect networks from unauthorized access and potential threats. Traditional firewalls have long been employed to safeguard organizations' digital assets. However, with the rise of virtualization technology, virtual firewalls have emerged as a powerful solution to meet the evolving security needs of the modern era. This blog post will delve into virtual firewalls, exploring their advantages and why they should be considered an integral part of any comprehensive cybersecurity strategy.

Virtual firewalls, or software firewalls, are software-based security solutions operating within a virtualized environment. Unlike traditional hardware firewalls, which are physical devices, virtual firewalls are implemented and managed at the software level. They are designed to protect virtual machines (VMs) and virtual networks by monitoring and controlling incoming and outgoing network traffic.

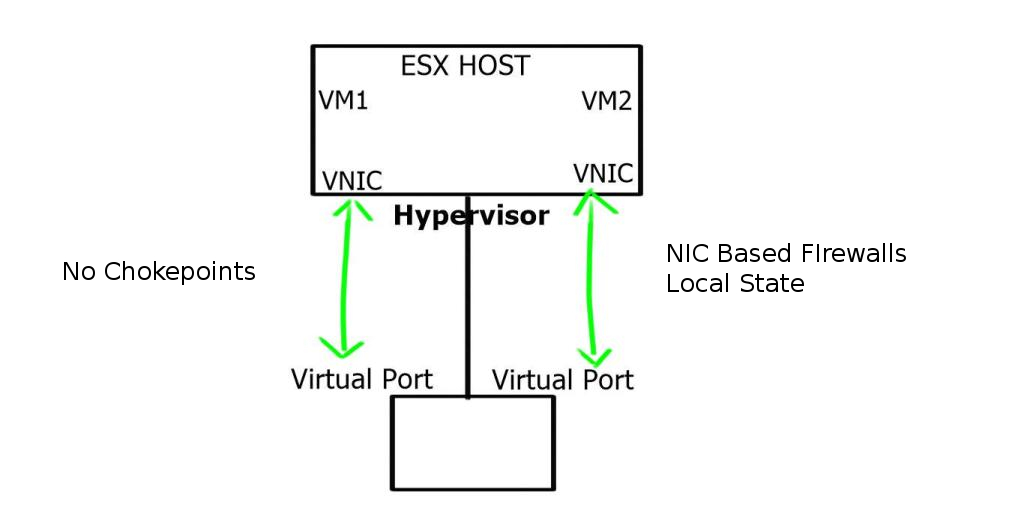
Virtual firewalls, also known as software firewalls, are security solutions designed to monitor and control network traffic within virtualized environments. Unlike traditional hardware firewalls, which operate at the network perimeter, virtual firewalls are deployed directly on virtual machines or within hypervisors. This positioning enables them to provide granular security policies and protect the internal network from threats that may originate within virtualized environments.

Segmentation: Virtual firewalls facilitate network segmentation by isolating virtual machines or groups of VMs, preventing lateral movement of threats within the virtual environment.
Intrusion Detection and Prevention: By analyzing network traffic, virtual firewalls can detect and prevent potential intrusions, helping organizations proactively defend against cyber threats.

Application Visibility and Control: With deep packet inspection capabilities, virtual firewalls provide organizations with comprehensive visibility into application-layer traffic, allowing them to enforce fine-grained policies and mitigate risks.

Enhanced Security: Virtual firewalls strengthen the overall security posture by augmenting traditional perimeter defenses, ensuring comprehensive protection within the virtualized environment.

Scalability and Flexibility: Virtual firewalls are highly scalable, allowing organizations to easily expand their virtual infrastructure while maintaining robust security measures. Additionally, they offer flexibility in terms of deployment options and configuration.

Centralized Management: Virtual firewalls can be managed centrally, simplifying administration and enabling consistent security policies across the virtualized environment.

Performance Impact: Virtual firewalls introduce additional processing overhead, which may impact network performance. It is essential to evaluate the performance implications and choose a solution that meets both security and performance requirements.

Integration with Existing Infrastructure: Organizations should assess the compatibility and integration capabilities of virtual firewalls with their existing virtualization platforms and network infrastructure.

Virtual firewalls have become indispensable tools in the fight against cyber threats, providing organizations with a robust layer of protection within virtualized environments. By leveraging their advanced features, such as segmentation, intrusion detection, and application control, businesses can fortify their digital fortresses and safeguard their critical assets. As the threat landscape continues to evolve, investing in virtual firewalls is a proactive step towards securing the future of your organization.

VIRTUAL FIREWALL · INTERACTIVE LAB 01

Where Should a Virtual Firewall Enforce Security?

Virtual firewalls can enforce policy at different points in a virtualised environment. Follow traffic from an external client or workload, through a virtual security boundary, to the protected application and see how placement changes the security model.

Virtual Security Path READY
SRC
Traffic Source Internet / workload
FW
Virtual Firewall Select a placement and inspection model.
APP
Protected Workload Application / service
Enforcement —
Traffic Scope —
Inspection —
Security Model —
Illustrative architecture model. Real virtual firewall products differ in enforcement point, inspection depth, performance model, integration and supported policy features.
Architecture Result
Select the traffic, enforcement model and inspection depth, then trace the flow.
Primary Boundary —
East-West Visibility —
Workload Mobility —
Central Chokepoint —
Traffic Trace
[READY] Virtual firewall trace awaiting input.
Engineering Insight

The major architectural question is where the security decision is enforced. A perimeter control can provide a strong north-south boundary, while workload-level or distributed enforcement can bring policy closer to east-west traffic.

Highlights: Virtual Firewalls

Background: Virtual Firewalls

– The virtual firewall (VF) is a network firewall appliance that runs within a virtualized environment and provides packet filtering and monitoring functions similar to those of a physical firewall. You can implement a VF on an existing guest virtual machine, as a traditional software firewall, as a virtual security appliance, as a virtual switch with enhanced security capabilities, or as a kernel process within the host hypervisor.

– A virtual firewall provides packet filtering and monitoring in a virtualized environment, even as another virtual machine, but also within the hypervisor. A guest VM running within a virtualized environment can be installed with VF as a traditional software firewall, a virtual security appliance designed to protect virtual networks, a virtual switch with additional security capabilities, or a kernel process that runs on top of all VM activity within the host hypervisor.

– There is a trend in virtual firewall technology to combine security-capable virtual switches with virtual security appliances. Virtual firewalls can incorporate additional networking features like VPN, QoS, and URL filtering.

Note: Types of Virtual Firewalls

a) Host-based Virtual Firewalls: Host-based virtual firewalls are installed on individual virtual machines (VMs) or servers. They monitor and control network traffic at the host level, providing added security for each VM.

b) Network-based Virtual Firewalls: Network-based virtual firewalls are deployed at the network perimeter, allowing for centralized monitoring and control of inbound and outbound traffic. They are instrumental in cloud environments where multiple VMs are running.

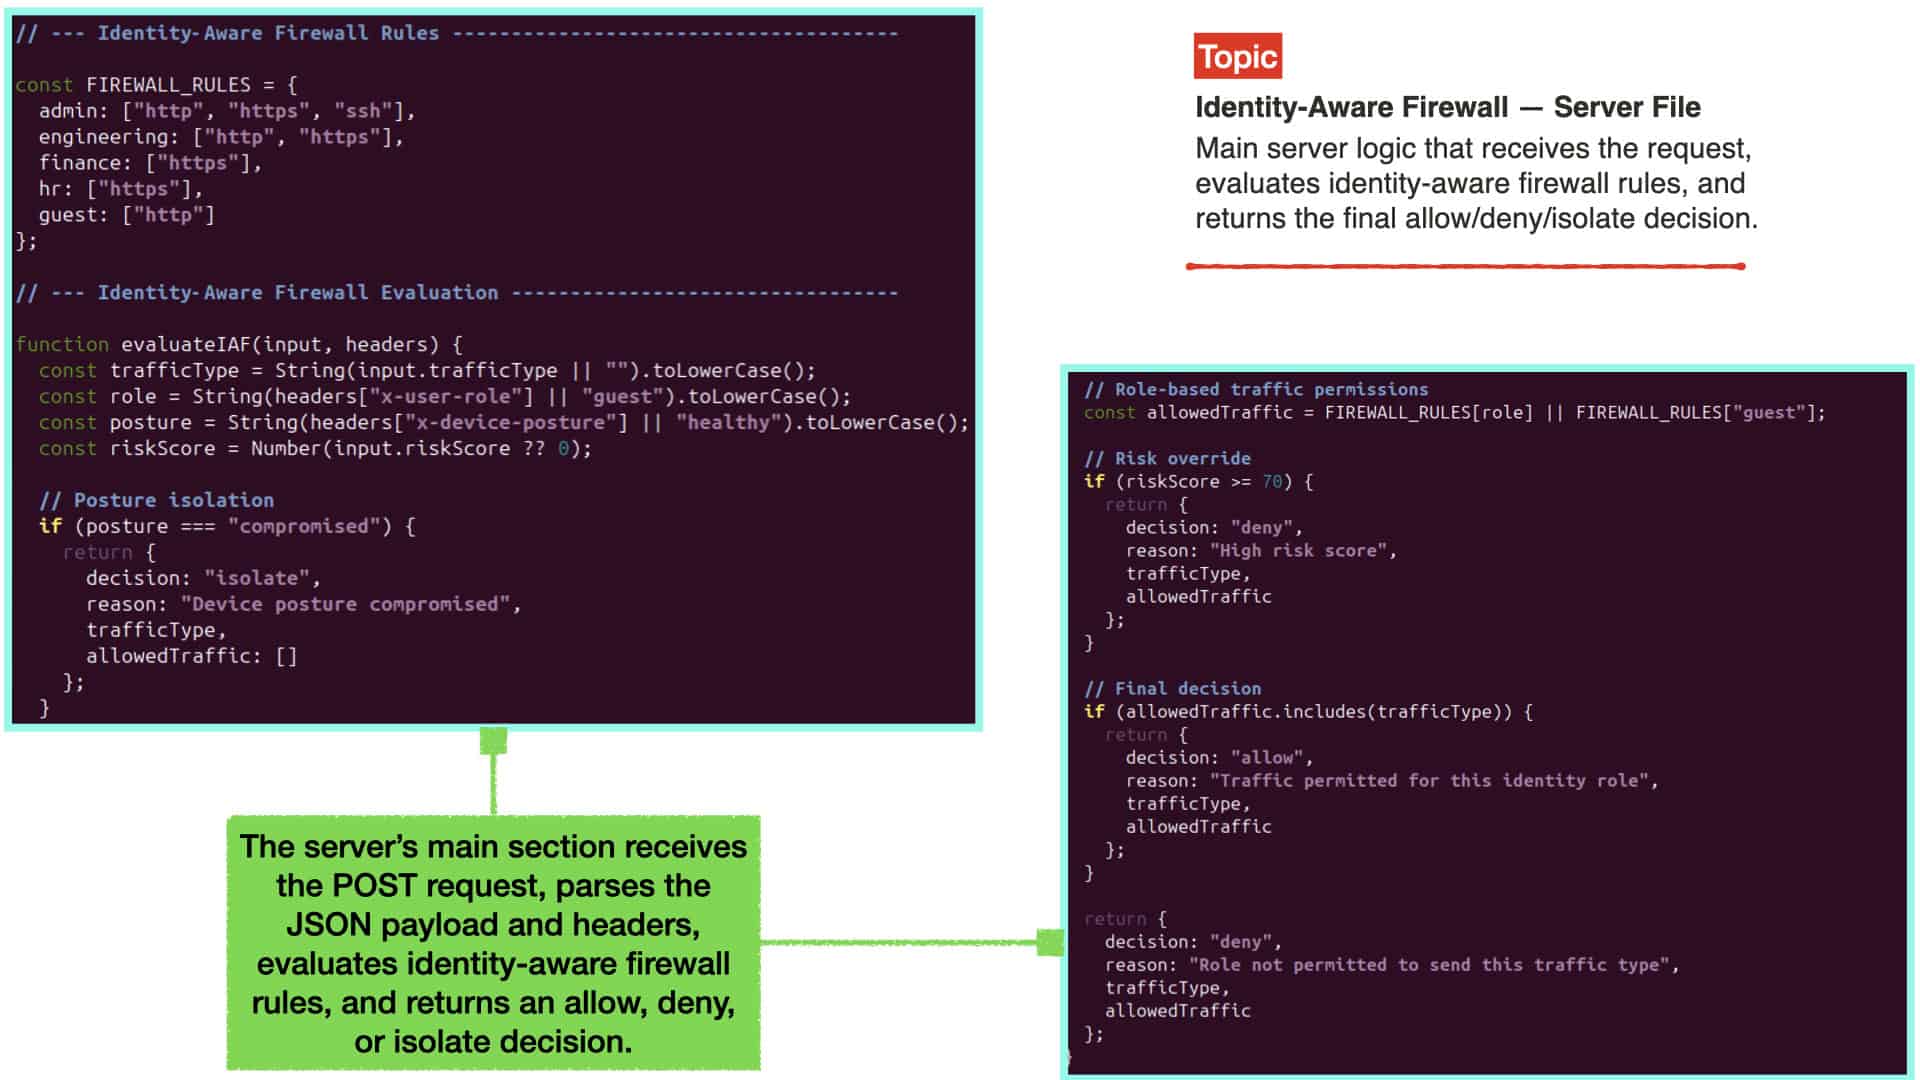
Virtual Firewall — Identity‑Driven Access Enforcement

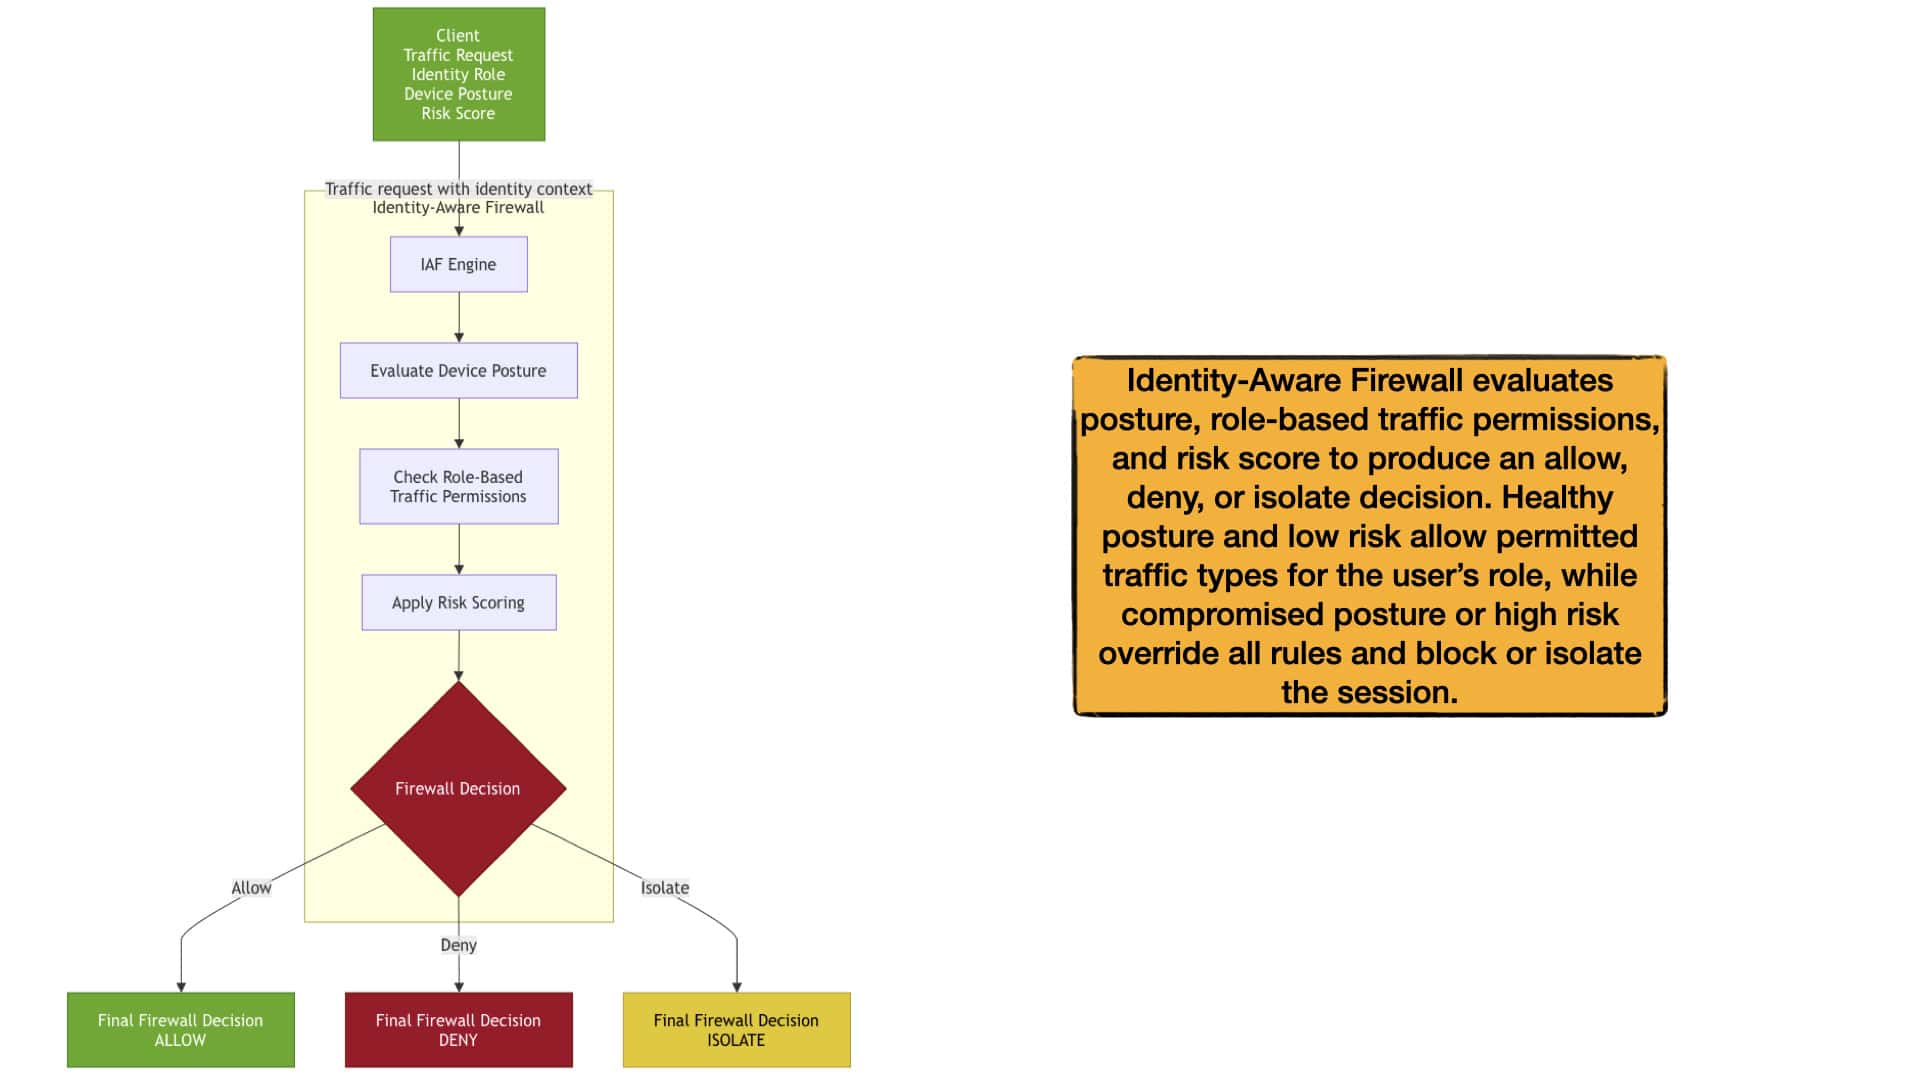
This lab demonstrates how a virtual firewall enforces identity‑driven access by validating user role, device posture, and behavioural context before allowing any traffic. Instead of relying on physical appliances or static network boundaries, the virtual firewall applies identity‑centric checks to determine whether a request should be permitted. This shows how modern virtual firewalls shift trust decisions away from IP‑based rules and toward identity‑focused security.

Identity aware firewall

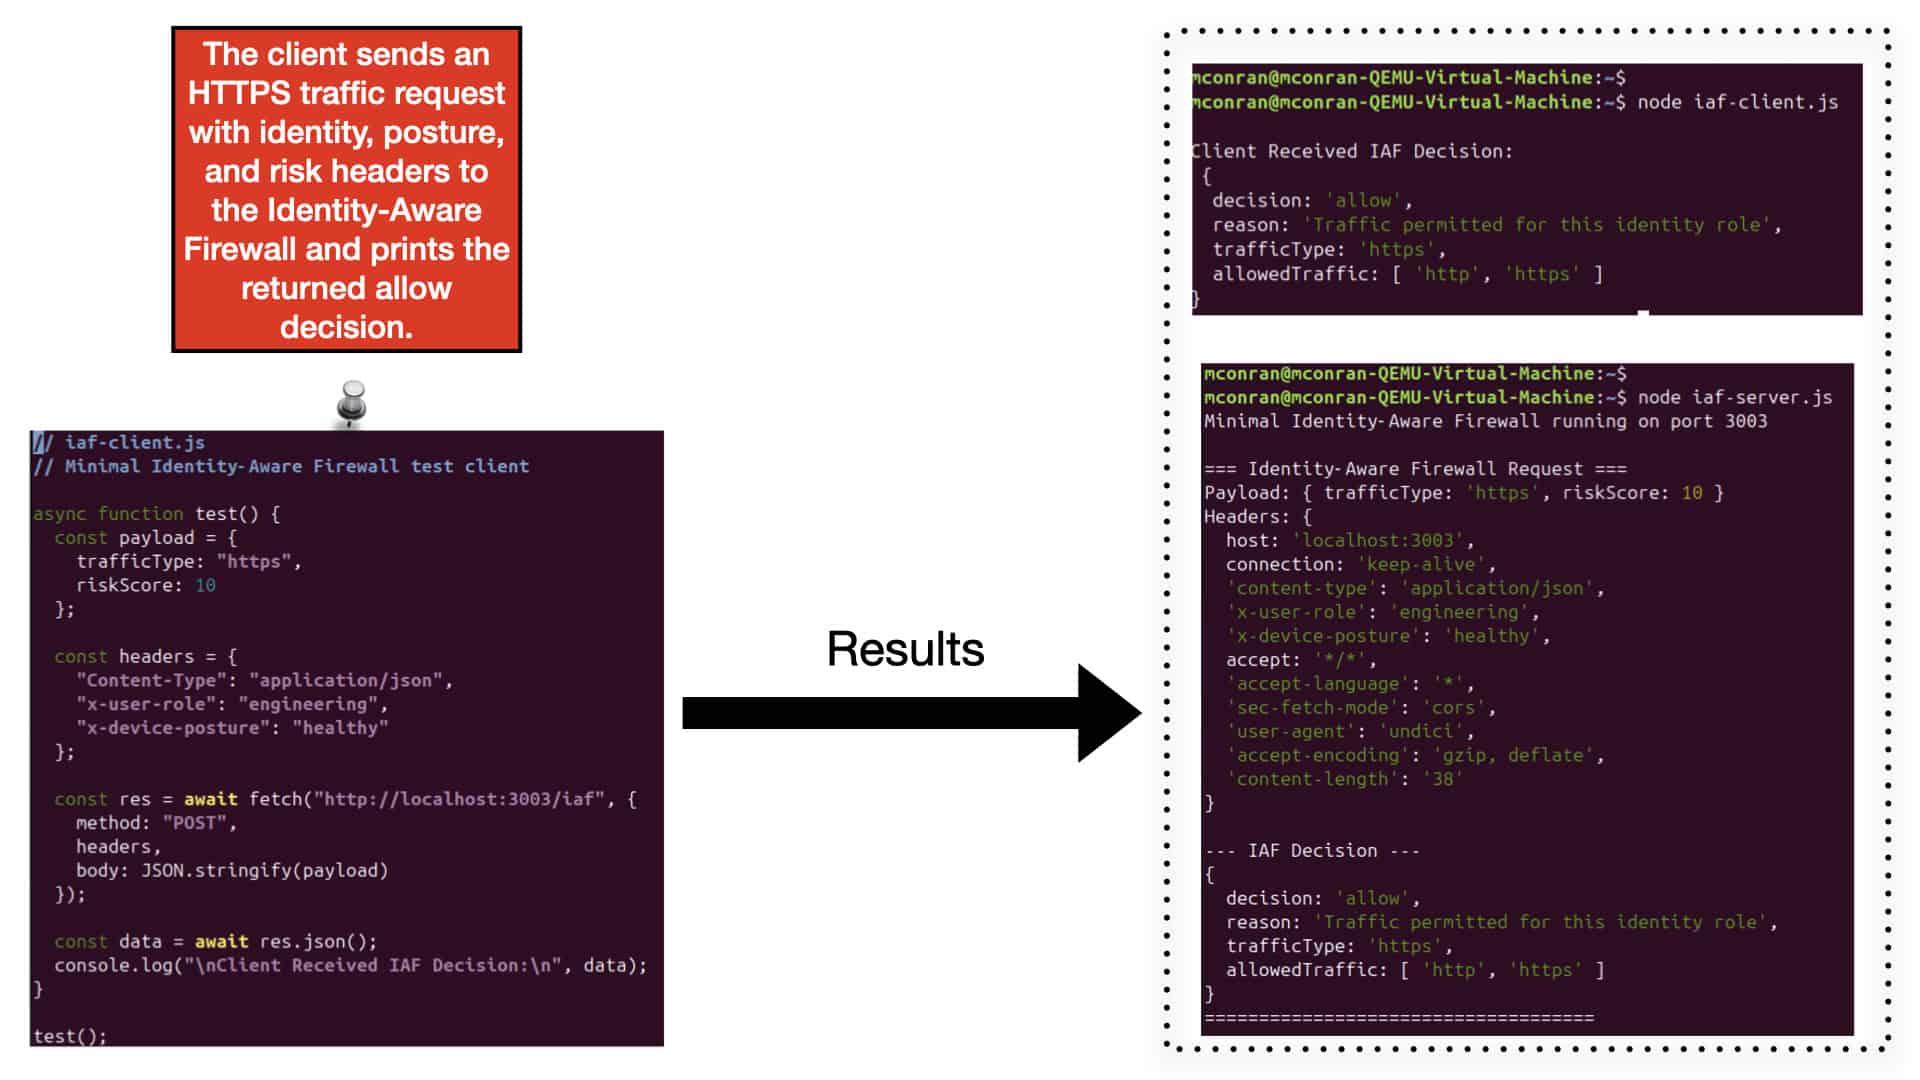
When the server receives a request, it applies virtual firewall rules that combine identity permissions, posture validation, and risk scoring. Each identity role is mapped to specific allowed traffic types, while compromised posture or elevated risk immediately restricts access. Because the test payload represents a healthy device, low risk, and a role aligned with the requested traffic type, the virtual firewall returns an allow decision. This demonstrates how virtual firewalls use dynamic, context‑aware enforcement to prevent unauthorized access and lateral movement.

The lab provides complete visibility into how the virtual firewall evaluates and enforces access. The server logs the payload, identity headers, posture signals, risk score, and final decision, while the client displays the JSON response returned by the firewall. This end‑to‑end flow illustrates how virtual firewalls merge identity validation, posture assessment, and behavioural analytics into a unified enforcement pipeline. With this foundation, learners can expand into advanced virtual firewall topics such as adaptive access, identity‑driven segmentation, and continuous verification.

Integration with Virtualization Platforms:

Virtual firewalls seamlessly integrate with popular virtualization platforms such as VMware and Hyper-V. This integration enables centralized management, simplifying the configuration and monitoring of virtual firewalls across your virtualized infrastructure. Additionally, virtual firewalls can leverage the dynamic capabilities of virtualization platforms, adapting to changes in the virtual environment automatically.

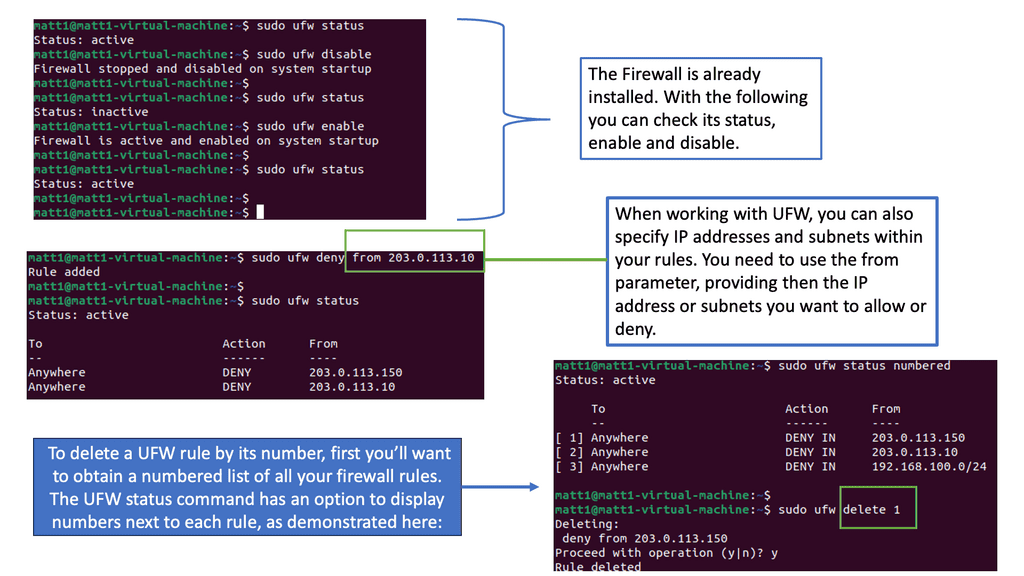
Example Technology: Linux Firewalling

Understanding UFW Firewall

To begin our journey, let’s first understand a UFW firewall. UFW, short for Uncomplicated Firewall, is a user-friendly interface that simplifies managing netfilter firewall rules. It is built upon the robust iptables framework and provides an intuitive command-line interface for configuring firewall rules.

UFW firewall offers many features that contribute to a secure network environment. From simple rule management to support for IPv4 and IPv6 protocols, UFW ensures your network is protected against unauthorized access. It also provides flexible configuration options, allowing you to define rules based on ports, IP addresses, and more.

Implementing Virtual Firewalls:

Assessing Network Requirements: Before implementing virtual firewalls, it’s crucial to assess your network environment, identify potential vulnerabilities, and determine the specific security needs of your organization. This comprehensive assessment enables you to tailor your virtual firewall deployment to address specific threats and risks effectively.

Choosing the Right Virtual Firewall Solution: There are various virtual firewall solutions available in the market, each with its own set of features and capabilities. It’s essential to evaluate your organization’s requirements, such as throughput, performance, and integration with existing security infrastructure. This evaluation will help you select the most suitable virtual firewall solution for your network.

Configuring Security Policies: Once you have selected a virtual firewall solution, the next step is to configure security policies. This involves defining access control rules, setting up intrusion detection and prevention systems, and configuring virtual private networks (VPNs) if necessary. It’s crucial to align these policies with your organization’s security objectives and industry best practices.

Advantages of Virtual Firewalls:

1. Enhanced Flexibility: Virtual firewalls offer greater flexibility than their hardware counterparts. They are software-based and can be easily deployed, scaled, and managed in virtualized environments without additional hardware. This flexibility enables organizations to adapt to changing business requirements more effectively.

2. Cost-Effectiveness: Virtual firewalls eliminate the need to purchase and maintain physical hardware devices. Organizations can significantly reduce their capital and operational expenses by leveraging existing virtualization infrastructure. This cost-effectiveness makes virtual firewalls an attractive option for businesses of all sizes.

3. Centralized Management: Virtual firewalls can be centrally managed through a unified interface, providing administrators with a consolidated view of the entire virtualized network. This centralized management simplifies the configuration, monitoring, and enforcement of security policies across multiple virtual machines and networks, saving time and effort.

4. Segmentation and Isolation: Virtual firewalls enable organizations to segment their virtual networks into different security zones, isolating sensitive data and applications from potential threats. This segmentation ensures that the rest of the network remains protected even if one segment is compromised. By enforcing granular access control policies, virtual firewalls add a layer of security to prevent lateral movement within the virtualized environment.

5. Scalability: Virtual firewalls are software-based and can be easily scaled up or down to accommodate changing network demands. This scalability allows organizations to expand their virtual infrastructure without investing in additional physical hardware. With virtual firewalls, businesses can ensure that their security solutions grow with their evolving needs.

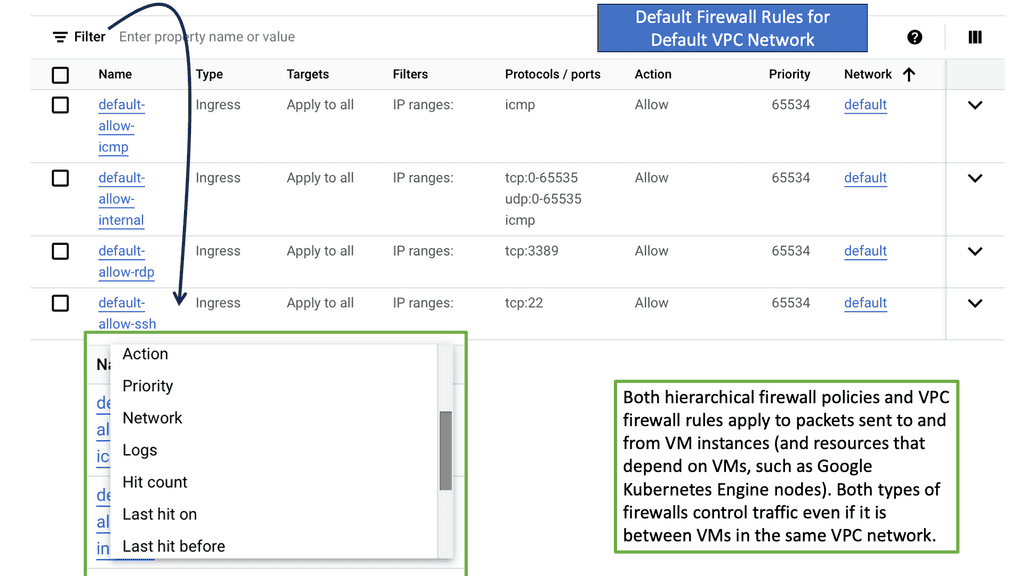
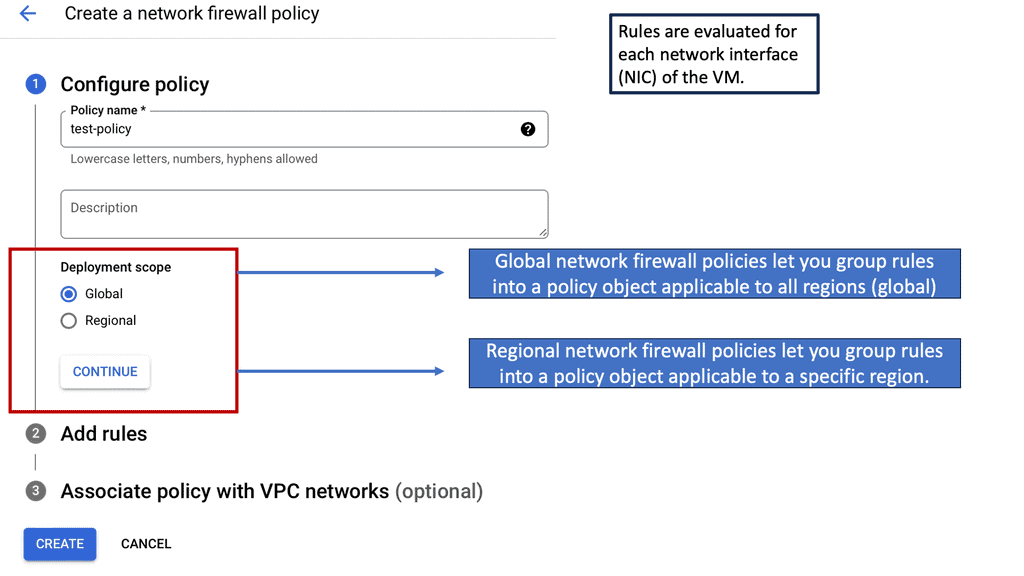
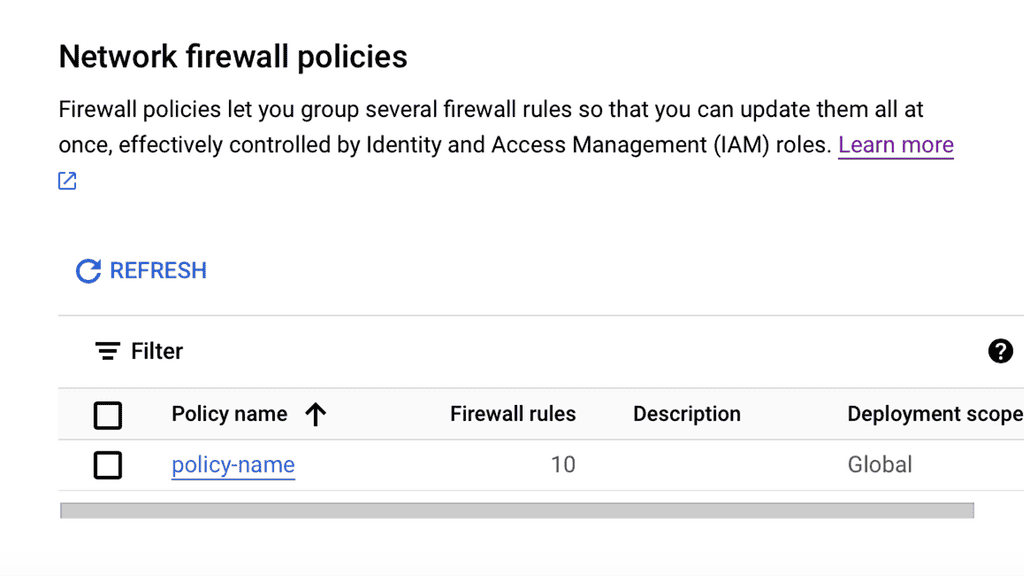
Example Default Firewall Rules in VPC Network

### What Are Default Firewall Rules?

When you create a new VPC network, it typically comes with a set of default firewall rules. These rules are designed to allow basic network functionality and to provide a base layer of security for your network. Understanding these default rules is crucial for managing your network’s security posture effectively.

### The Role of Ingress and Egress Rules

Default firewall rules usually include both ingress (incoming) and egress (outgoing) rules. Ingress rules determine what traffic can enter your VPC, while egress rules control the traffic leaving your VPC. Typically, default rules allow all egress traffic, enabling your resources to communicate with external networks, but restrict ingress traffic to ensure that only authorized connections can be established.

### Customizing Default Rules

While default rules provide a starting point, they may not fit the specific needs of your application or organization. It’s essential to review and customize these rules based on your security policies and compliance requirements. This involves defining more specific rules that allow or deny traffic based on various parameters such as IP address ranges, protocols, and ports.

### Best Practices for Managing Firewall Rules

To maintain a secure and efficient VPC network, follow best practices when managing firewall rules. Regularly review and audit your rules to ensure they align with your security policies. Document changes and maintain a clear understanding of the purpose of each rule. Additionally, consider implementing a least privilege approach, where only necessary traffic is permitted, minimizing the potential attack surface.

distributed firewalls Distributed Firewalls

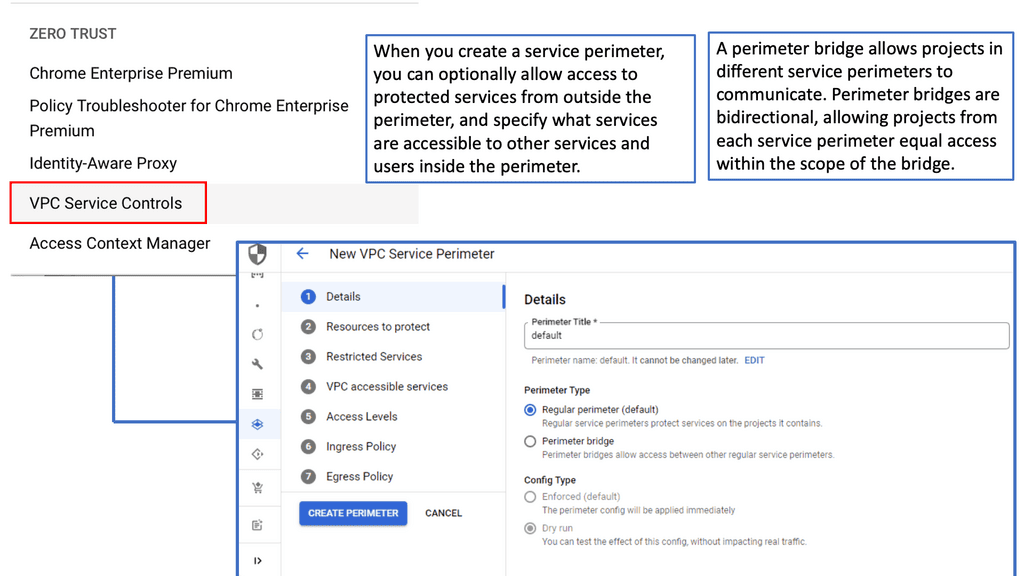
VPC Service Controls

**Understanding the Basics**

VPC Service Controls provide an additional layer of security by enabling organizations to set up a virtual perimeter that restricts data access and movement. By configuring service perimeters, businesses can enforce security policies that prevent data exfiltration and unauthorized access. This is particularly beneficial for organizations handling sensitive information, such as financial data or personal customer information, as it helps maintain compliance with stringent data protection regulations.

**Implementing VPC Service Controls**

Implementing VPC Service Controls involves creating service perimeters around the resources you want to protect. These perimeters act like a security fence, allowing only authorized access to the data within. To get started, identify the resources you want to include and configure policies that define who and what can access these resources. Google Cloud’s intuitive interface makes it easy to set up and manage these perimeters, ensuring that your cloud environment remains secure without compromising performance.

VPC Security Controls

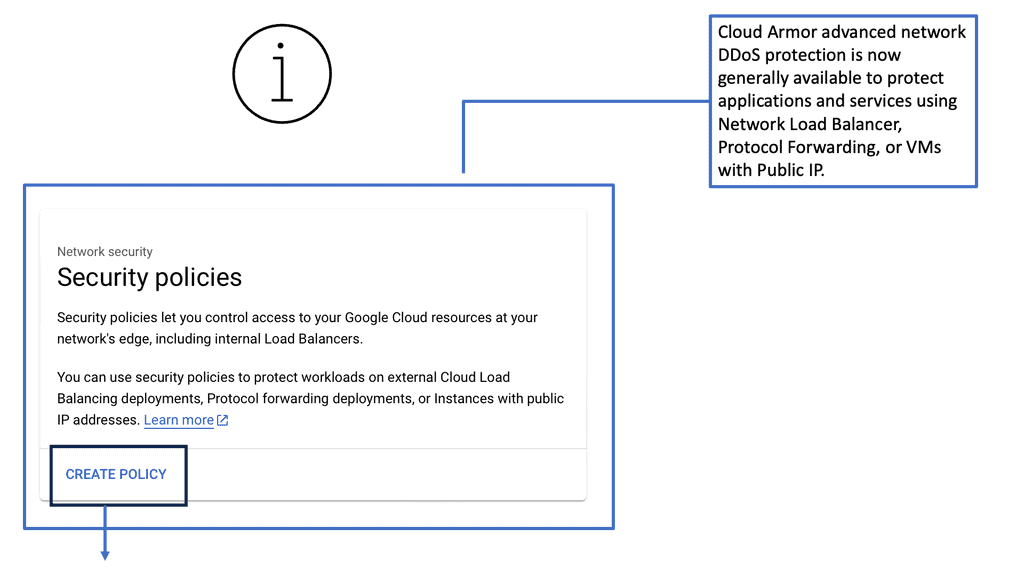
Virtual Firewall with Cloud Armor

**What is Cloud Armor?**

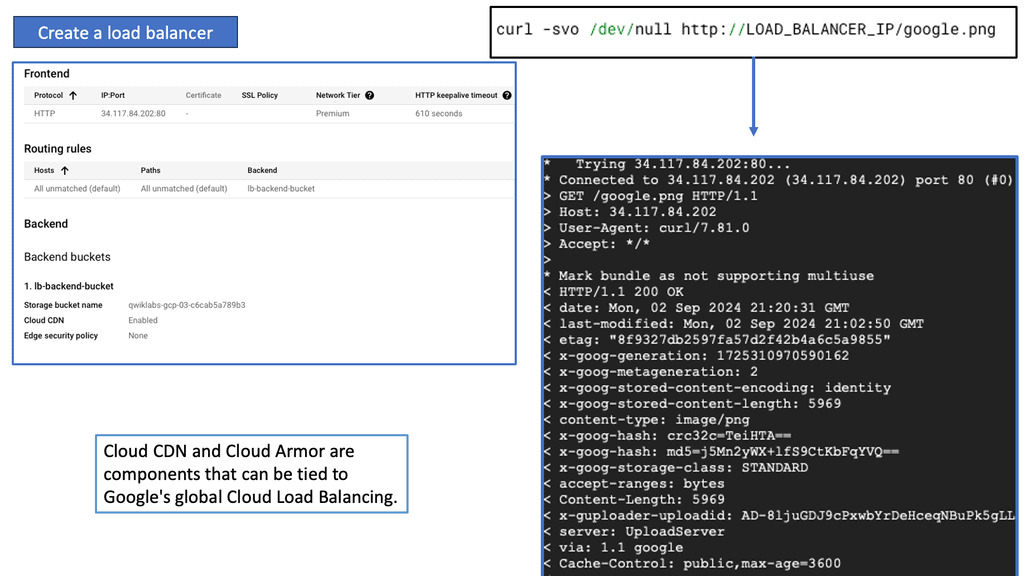
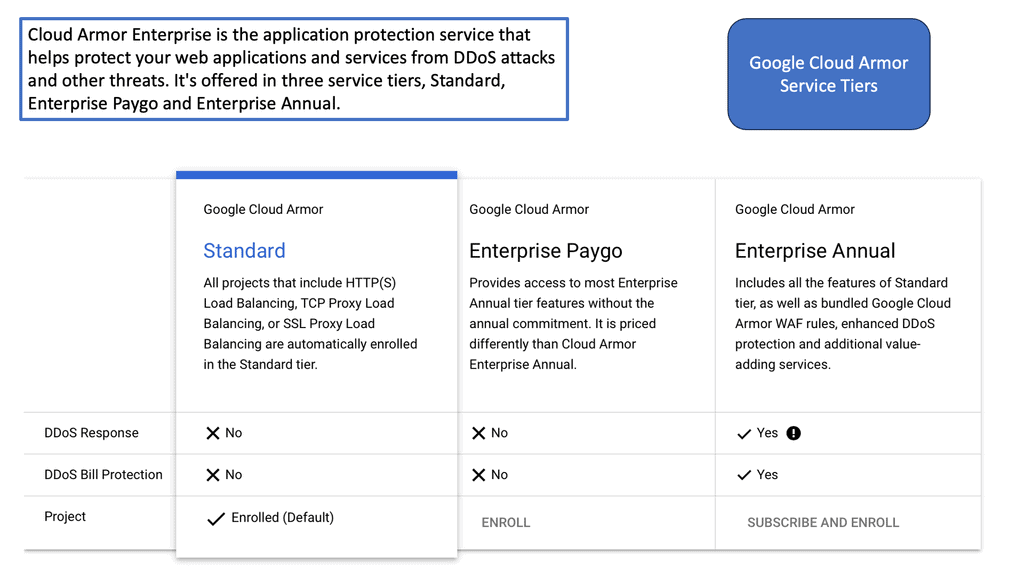
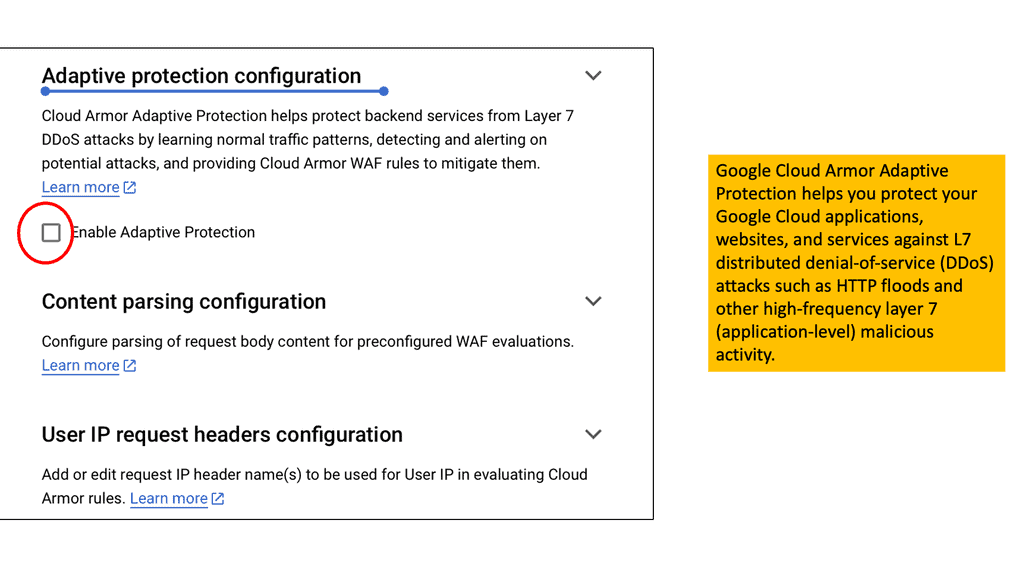
Cloud Armor is a security service that offers advanced protection for your applications hosted on the cloud. It provides a robust shield against various cyber threats, including DDoS attacks, SQL injections, and cross-site scripting. By leveraging Google’s global infrastructure, Cloud Armor ensures that your applications remain secure and available, even during the most sophisticated attacks.

**Key Features of Cloud Armor**

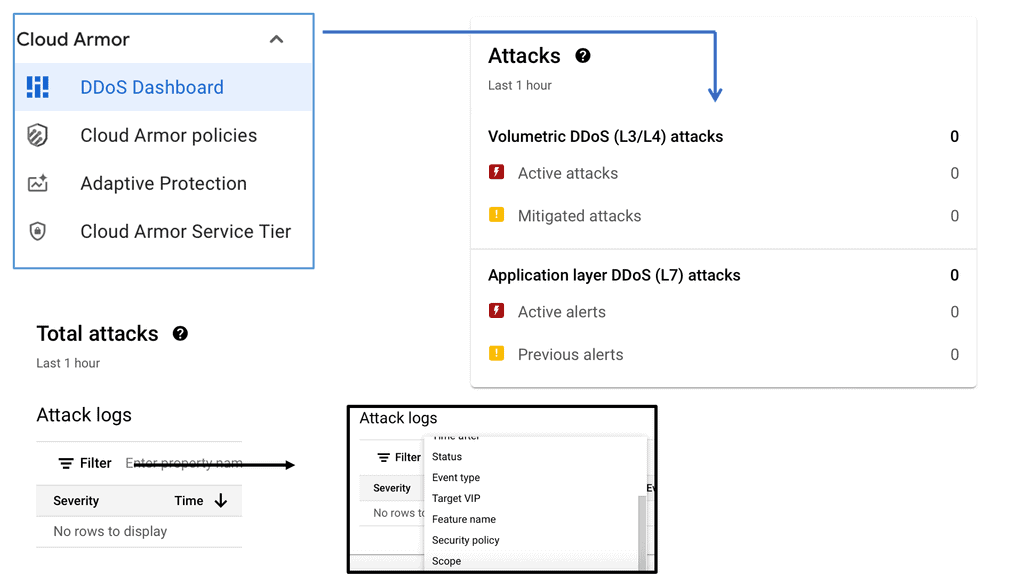
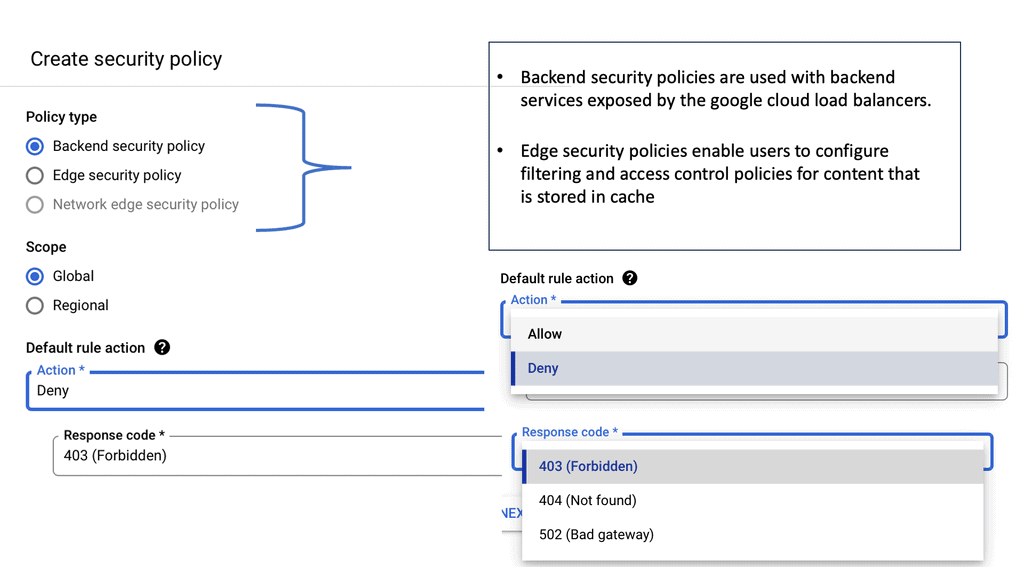
One of the standout features of Cloud Armor is its ability to create and enforce edge security policies. These policies allow you to control and monitor traffic to your applications, ensuring that only legitimate users gain access. Additionally, Cloud Armor provides real-time monitoring and alerts, enabling you to respond swiftly to potential threats. With its customizable rules and rate limiting capabilities, you can fine-tune your security settings to meet your specific needs.

**Edge Security Policies: Your First Line of Defense**

Edge security policies are a critical component of Cloud Armor. These policies act as your first line of defense, filtering out malicious traffic before it reaches your applications. By defining rules based on IP addresses, geographic locations, and other criteria, you can block unwanted traffic and reduce the risk of attacks. Moreover, edge security policies help in mitigating DDoS attacks by distributing traffic across multiple regions, ensuring your applications remain accessible.

**Benefits of Using Cloud Armor**

Implementing Cloud Armor offers numerous benefits. Firstly, it enhances the security of your applications, protecting them from a wide range of cyber threats. Secondly, it ensures high availability, even during large-scale attacks, by distributing traffic and preventing overload. Thirdly, Cloud Armor’s real-time monitoring and alerts enable proactive threat management, allowing you to respond quickly to potential issues. Lastly, its customizable policies provide flexibility, ensuring your security settings align with your specific requirements.

**Range of attack vectors**

On-campus networks, mobile devices, and laptops are highly vulnerable to malware and ransomware, as well as to phishing, smishing, malicious websites, and infected applications. Thus, a solid network security design is essential to protect endpoints from such security threats and enforce endpoint network access control. End users can validate their identities before granting access to the network to determine who and what they can access.

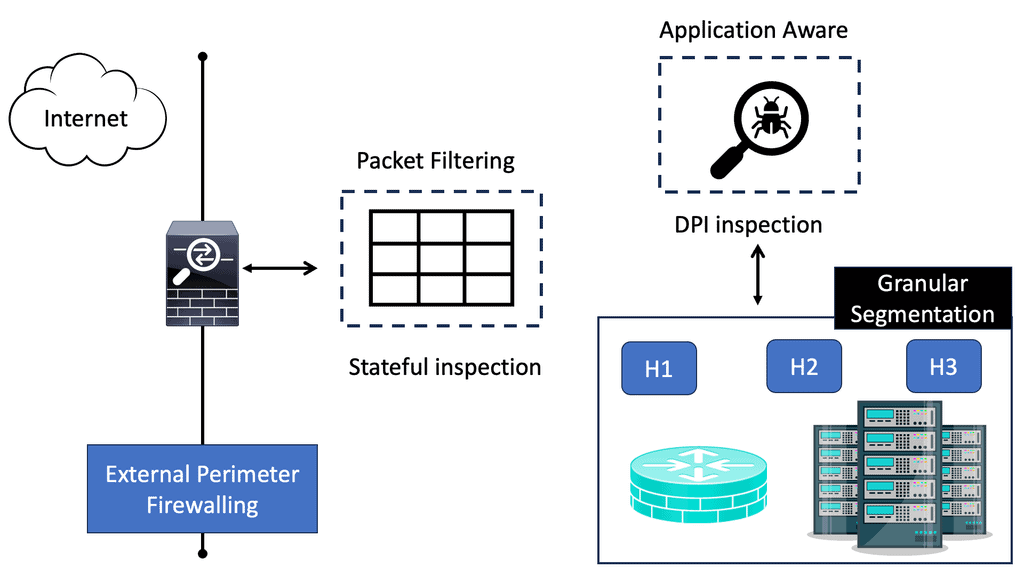
Virtual firewalls, also known as cloud firewalls or virtualized NGFWs, grant or deny network access between untrusted zones. They provide inline network security and threat prevention in cloud-based environments, allowing security teams to gain visibility and control over cloud traffic. In addition to being highly scalable, virtual network firewalls are ideal for protecting virtualized environments because they are deployed in a virtualized form factor.

data center firewall
Diagram: The data center firewall.

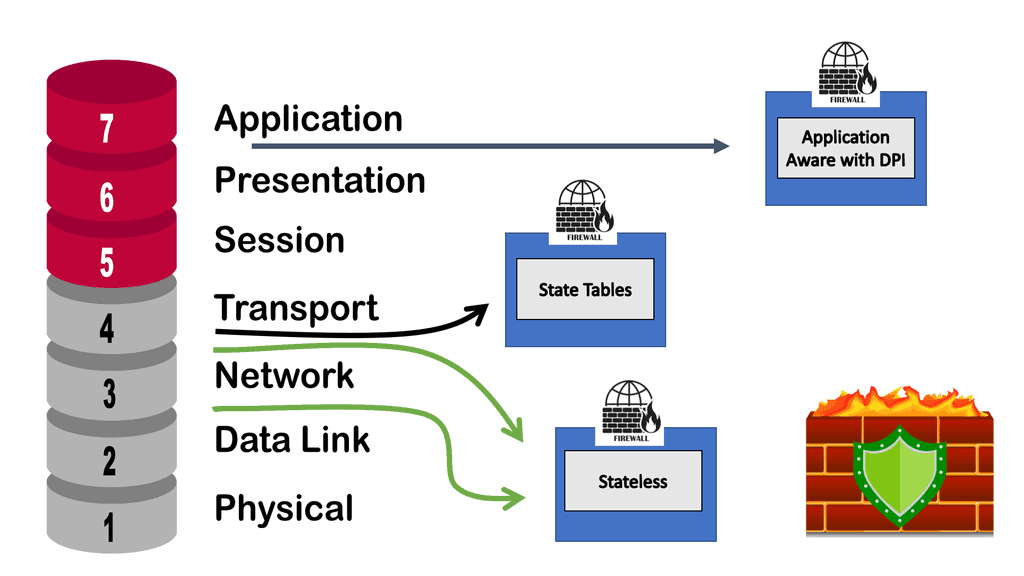
Because Layer 4 firewalls cannot detect attacks at the application layer, virtual firewalls are ideal for cloud service providers (CSPs). Virtual firewalls can determine if requests are allowed based on their content by examining applications and not just port numbers. This feature can prevent DDoS attacks, HTTP floods, SQL injections, cross-site scripting attacks, parameter tampering attacks, and Slowloris attacks.

**Network Security Components**

This post discusses the network security components of virtual firewalls and the virtual firewall appliance that enables a zero-trust network design. In the Secure Access Service Edge (SASE ) world, virtual firewalling or any virtual device brings many advantages, such as having a stateful inspection firewall closer to the user sessions. Depending on the firewall design, the inspection and filtering are closer to the user’s sessions or workloads. Firstly, Let us start with the basics of IP networks and their operations.

**Virtual SDN Data Centers**

In a virtual data center design, IP networks deliver various services to consumers and businesses. As a result, they heavily rely on network availability for business continuity and productivity. As the reliance on IP networks grows, so does the threat and exposure to network-based attacks. New technologies and mechanisms address new requirements but also come with the risk of new threats. It’s a constant cat-and-mouse game. It’s your job as network admins to ensure the IP network and related services remain available.


VIRTUAL FIREWALL · INTERACTIVE LAB 02

How Should a Virtual Firewall Decide What to Allow?

A firewall does more than sit in the traffic path. It evaluates attributes such as source, destination, protocol, port, connection state and, where supported, identity or application context. Experiment with the policy model and see how the resulting security boundary changes.

Policy Decision Path READY
SRC
Internet External client
Firewall Policy Awaiting evaluation
DST
Web Server TCP 443
Decision —
Policy Match —
Session —
Context —
Illustrative policy engine. Real products differ in supported match fields, identity integration, application inspection, state tracking and enforcement architecture.
Firewall Decision
Configure the scenario and evaluate the policy.
Source —
Destination —
Protocol / Port —
Security Context —
Decision Trace
[READY] Policy engine awaiting evaluation.
Engineering Insight

Effective virtual firewall policy combines traffic attributes with the security context available to the enforcement point. Least-privilege policy should permit required communication while limiting unnecessary lateral movement.

Virtual Firewalls

The term “firewall” refers to a device or service that allows some traffic but denies other traffic. Positioning a firewall at a network gateway point in the network infrastructure is an aspect of secure design. A firewall so set at strategic points in the network intercepts and verifies all traffic crossing that gateway point. Some other places that firewalls are often deployed include in front of (i.e., on the public Internet side), behind (inside the data center), or in load-balancing systems.

Traffic Types and Virtual Firewalls

Firstly, a thorough understanding of the traffic types that enter and leave the network is critical. Network devices process some packets differently from others, resulting in different security implications. Transit IP packets, receive-adjacency IP packets, exception, and non-IP packets are all handled differently.

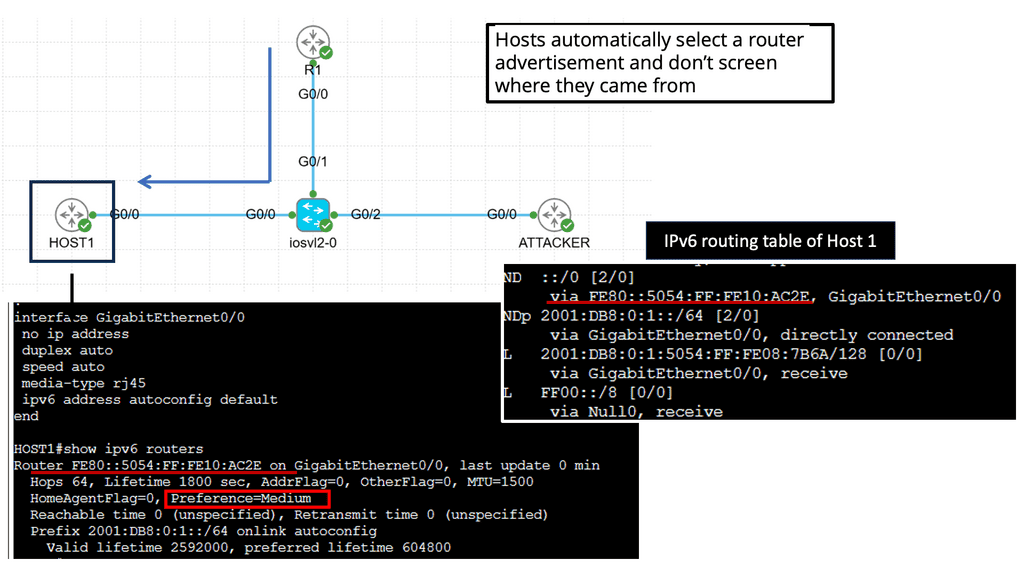
You also need to keep track of the plethora of security attacks, such as resource exhaustion attacks (direct attacks, transit attacks, reflection attacks), spoofing attacks, transport protocol attacks (UDP & TCP), and routing protocol/control plane attacks.

Various attacks target Layer 2, including MAC spoofing, STP, and CAM table overflow. Overlay virtual networking introduces two control planes, both of which require protection.

The introduction of cloud and workload mobility is changing the network landscape and security paradigm. Workload fluidity and the movement of network states are putting pressure on traditional physical security devices. It isn’t easy to move physical appliances around the network. Physical devices cannot follow workloads, which drives the world of virtual firewalls with distributed firewalls, NIC-based Firewalls, Microsegmentation, and Firewall VM-based appliances. 

**Session state**

Simple packet filters match on Layer 2 to 4 headers – MAC, IP, TCP, and UDP port numbers. If they don’t match the TCP SYN flags, it’s impossible to identify established sessions. Tracking the state of the TCP SYN tells you if this is the first packet of a session or a subsequent packet of an existing session. Matching on TCP flags allows you to differentiate between TCP SYN, SYN-ACK, and ACK.

Matching established TCP sessions would match on packets with the ACK/RST/FIN bit set. All packets without a SYN flag will not start a new session, and all packets with ACK/RST/FIN can appear anywhere in the established session.

Checking these three flags indicates if the session is established or not. In any adequately implemented TCP stack, the packet filtering engine will not open a new session unless it receives a TCP packet with the SYN flag. In the past, we used a trick. If a packet arrives with a destination port over 1024, it must be a packet from an established session, as no services were running on a high number of ports.

The term firewall originally referred to a wall to confine a potential fire. Regarding networking, a firewalling device is a barrier between a trusted and untrusted network. It can be classed into several generations. First-generation firewalls are simple packet filters, the second-generation refers to stateful devices, and the third-generation refers to application-based firewalls. A stateful firewall doesn’t mean it can examine the application layer and determine users’ actions.

A- The starting points of packet filters

Firewalls initially started with packet filters at each end and an application proxy in the middle. The application proxy would inspect the application level, and the packet filters would perform essential scrubbing. All sessions terminate on the application proxy where new sessions are initiated. Second-generation devices came into play, and we started tracking the sessions’ state.

Now, we have a single device that can do the same job as the packet filter combined with the application proxy. But it wasn’t inspected at the application level. The devices were stateful and could track the session’s state but could not go deeper into the application. For example, examine the HTTP content and inspect what users are doing. Generation 2 was a step back in terms of security.

We then moved into generation 3, which marketing people call next-generation firewalls. They offer Layer 7 inspection with packet filtering. Finally, niche devices called Application-Level firewalls, also known as web application Firewalls (WAF), are usually only concerned with HTTP traffic. They have similar functionality to reverse web proxy, terminating the HTTP session.

B- The rise of virtual firewalls and virtual firewall appliances

Almost all physical firewalls offer virtual contexts. Virtual contexts divide the firewall and solve many multi-tenancy issues. They provide separate management plans, but all the contexts share the same code. They also run over the same interfaces competing for the same bandwidth, so if one tenant gets DoS attacked, the others might be affected. However, virtual contexts constitute a significant drawback because they are tied to the physical device, so unlike VM-based firewalls, you lose all the benefits of virtualization. 

A firewall in a VM can run on any transport provided by the hypervisor. The VM thinks it has an ethernet interface, enabling you to put a VM-based firewall on top of any virtualization technology. The physical firewall must be integrated with the network virtualization solution, and many vendors have limited support for overlay networking solutions.

The physical interface supports VXLAN, but that doesn’t mean it can help the control plane in which the overlay network solution runs. For example, the network overlay solution might use IP multicast, OVSDB, or EVPN over VXLAN. Deploying Virtual firewalling offers underlay transport independence. It is flexible and easy to deploy and manage.

C- Virtual firewall appliance: VM and NIC-based firewalls

Traditionally, we used VLANs and IP subnets as security zones. This introduced problems with stretched VLANs, so they came with VXLAN and NVGRE. However, we are still using IP as the isolation mechanism. Generally, firewalls are implemented between subnets so all the traffic goes through the firewall, which can result in traffic trombones and network chokepoints.

The new world is all about VM and NIC-based firewalls. NIC-based firewalls are mostly packet filters or, at the very most, reflective ACLs. Vmware NSX distributed firewall does slightly more with some application-level functionality for SIP and FTP traffic.

virtual firewalls

NIC-based firewalls force you to redesign your security policy. Now, all the firewall rules are directly in front of the virtual NIC, offering optimal access to any traffic between VMs, as traffic does not need to go through a central firewall device. The session state is kept local and only specific to that VM. This makes them very scalable. It allows you to eliminate IP subnets as security zones and provides isolation between VMs in the same subnet.

This protects individual VMs by design, so all others are protected even if an attacker breaks into one VM. VMware calls this micro-segmentation in NSX. You can never fully replace physical firewalls with virtual firewalls. Performance and security audits come to mind. However, they can be used to augment each other. NIC is based on the east-to-west traffic and physical firewalls at the perimeter to filter north-to-south traffic.

Closing Points on Virtual Firewalls

Virtual firewalls, unlike their hardware counterparts, are software-based solutions that provide network security for virtualized environments. They operate within the cloud or on virtual machines, offering the flexibility to protect dynamic environments where traditional firewalls might fall short. With the rise of cloud computing, virtual firewalls have become indispensable, allowing organizations to enforce security policies consistently across their virtual infrastructures.

The advantages of virtual firewalls are numerous. Firstly, they offer scalability. As your business grows, so does your network, and virtual firewalls can expand seamlessly to accommodate this growth. Secondly, they are cost-effective. Without the need for physical hardware, virtual firewalls reduce both upfront costs and ongoing maintenance expenses. Additionally, they provide agility, enabling rapid deployment and configuration changes to adapt to evolving security needs. Finally, virtual firewalls enhance security by integrating with other security tools to provide a comprehensive defense strategy.

Deploying a virtual firewall requires careful planning to ensure it aligns with your organization’s specific needs. One common strategy is to implement them in a public cloud environment, where they can protect against threats targeting cloud-based applications and data. Another approach is using them within private cloud infrastructures to secure internal communications and sensitive data. Hybrid environments, which combine on-premises and cloud resources, can also benefit from virtual firewalls, allowing for a unified security policy across diverse platforms.

Effective management of virtual firewalls involves regular monitoring and updates. Keeping firewall software up-to-date ensures protection against the latest threats and vulnerabilities. Additionally, conducting regular security audits helps identify potential weaknesses in your network. Implementing a centralized management system can also streamline configuration and monitoring processes, making it easier to maintain a strong security posture. Educating your IT team about the latest trends and threats in cybersecurity further strengthens your defense strategy.

VIRTUAL FIREWALL · INCIDENT CHALLENGE

Why Can't the API Reach the Database?

The application is healthy, routing is working and the database is online. Yet API requests to TCP/5432 are failing. Your task is to identify where the security decision is being made and determine the most likely cause.

Incident Brief

After a workload migration, api-01 can no longer reach db-01. Web users can still reach the application. The failure affects only the east-west API → database flow.

API Workload Healthy
Database Healthy
Routing Reachable
TCP / 5432 Denied
Recent Change Workload Migration
Live Incident Path
East-West Application Flow INCIDENT
WEB
web-01 Frontend workload
Healthy
API
api-01 Application tier
Healthy
POLICY DENY TCP 5432
Security classification mismatch
DB
db-01 Database tier
Healthy
Routing HEALTHY
API REACHABLE
Policy DENY
Likely Layer SECURITY
Choose Your Investigation

What should you investigate first?

Investigation Score
0 / 4
Investigation Result
Select an investigation path to diagnose the incident.
Incident Console
[ALERT] API → Database TCP/5432 failure detected.
[CHECK] Routing path remains reachable.
[CHECK] Both workloads report healthy.
[CLUE] Failure began after workload migration.
Engineering Insight

East-west failures are often caused by the security policy classification rather than by basic routing. Distributed enforcement can continue filtering traffic even when the perimeter path is completely healthy.

The scenario is intentionally simplified. Real environments may involve routing, security groups, identity providers, service discovery, workload tags, distributed enforcement points and multiple policy layers.
Rear view of hacker in front of computer with multiple screens in dark room.

DDoS Attacks

DDoS Attacks

In today's digital age, cyber threats have become increasingly sophisticated, posing a significant challenge to individuals and organizations. One such malevolent force that has gained notoriety is Distributed Denial of Service (DDoS) attacks. In this blog post, we will delve into the world of DDoS attacks, uncovering their inner workings, motives, and the devastating impact they can have on their victims.

DDoS attacks are orchestrated attempts to overwhelm a target system or network with a flood of traffic, rendering it inaccessible to legitimate users. These attacks involve multiple compromised devices, forming a botnet army, which is controlled by a malicious entity. By harnessing the combined bandwidth of these devices, the attacker can launch a massive assault that cripples the target's online presence.

DDoS attacks can be motivated by various factors. Hacktivism, where attackers aim to make a political or social statement, is one such motive. Cybercriminals may also carry out DDoS attacks as a smokescreen to divert attention from other malicious activities, such as data breaches or theft. Additionally, in some instances, competitors or disgruntled individuals may resort to DDoS attacks to gain a competitive advantage or exact revenge.

DDoS attacks utilize a range of techniques to overwhelm targeted systems. One commonly employed method is the "volumetric attack," which floods the target with an enormous volume of traffic, exceeding its capacity to handle requests. Another technique is the "application layer attack," where the attacker targets specific vulnerabilities in the application layer, exhausting server resources and causing service disruptions. Furthermore, "amplification attacks" exploit the vulnerabilities of certain protocols or services to amplify the volume of traffic directed at the target.

Given the severity of DDoS attacks, it is crucial for individuals and organizations to implement robust mitigation strategies. Proactive measures involve employing traffic filtering mechanisms, such as firewalls or intrusion prevention systems, to identify and block malicious traffic. Content Delivery Networks (CDNs) can also help mitigate attacks by distributing traffic across multiple servers, reducing the impact of an attack on any single server.

As technology evolves, so do the methods employed by attackers. The future of DDoS attacks holds the potential for more sophisticated techniques, including the utilization of artificial intelligence and the Internet of Things (IoT) devices as botnet components. This calls for enhanced security measures, industry collaboration, and continuous research to stay one step ahead of the attackers.

DDoS attacks present a significant threat to the digital landscape, capable of disrupting businesses, causing financial losses, and compromising user trust. Understanding the inner workings of these attacks, their motives, and implementing effective mitigation strategies are vital in safeguarding against this insidious menace. By staying informed and proactive, we can collectively build a safer and more resilient online ecosystem.

DDOS DEFENCE · INTERACTIVE LAB 01

Follow a DDoS Attack Through the Network

A DDoS event is not one single type of traffic. Volumetric, protocol-state and application-layer events place pressure on different resources. Trace the traffic path and see where different defensive controls can reduce the impact before legitimate users are affected.

Traffic Path
Internet → Protected Service READY
BOT
Distributed Sources Many traffic sources
WAN
Internet Edge Transit / ingress
Mitigation Layer Awaiting trace
APP
Protected Service Origin application
Attack Class —
Primary Pressure —
Mitigation —
Origin Risk —
Defence Assessment
Select an attack profile and protection model, then trace the event.
Detection Console
[READY] Waiting for traffic trace.
Engineering Insight

The most important question is not simply “Is traffic malicious?” It is also “Where can the organisation absorb, classify and remove that traffic before critical resources are exhausted?”

This is a defensive architecture simulation. Traffic rates and outcomes are illustrative rather than measurements of a real network or mitigation provider.

Highlights: DDoS Attacks

Understanding DDoS Attacks

DDoS attacks are orchestrated attempts to overwhelm a target system, network, or website with an overwhelming amount of traffic. By flooding the target with an unmanageable influx of requests, DDoS attacks render the system inaccessible to legitimate users. The motives behind these attacks can vary, ranging from hacktivism and revenge to financial gain or even political sabotage.

To execute a DDoS attack, perpetrators typically harness a botnet—an army of compromised computers or devices under their control. These compromised machines, often referred to as “zombies,” are used to generate a massive volume of traffic towards the target. The attack may exploit vulnerabilities in network protocols, application layers, or even the target’s bandwidth capacity. With the combined firepower of the botnet, the target’s resources are overwhelmed, resulting in service disruption.

The Ramifications of DDoS Attacks

1: The implications of a successful DDoS attack can be severe. Businesses may experience significant financial losses due to prolonged service downtime, tarnished reputation, and potential legal consequences. Moreover, the psychological impact on users who rely on the targeted services can lead to a loss of trust and confidence in the affected organization. The fallout from DDoS attacks extends beyond immediate damages, making it crucial to be prepared and proactive in safeguarding against such threats.

2: Mitigating the risks associated with DDoS attacks requires a multi-layered approach. Implementing robust network security measures, such as firewalls and intrusion detection systems, can help identify and filter out suspicious traffic.

3: Employing content delivery networks (CDNs) can distribute the load and provide additional protection. Utilizing traffic monitoring and anomaly detection tools can aid in early detection and response to potential attacks. Additionally, collaborating with internet service providers (ISPs) and implementing rate limiting measures can help mitigate the impact of an attack.

**DDoS Attacks**

The underlying mechanism of software or infrastructure does not need to be understood to carry out a successful DDoS attack. Some of the more successful attacks have been carried out by industry outsiders who understand the architecture.

The attacker must control many administrated sources for the attack to be complex. With everyone carrying a smartphone in their pocket, living in a home with embedded computers, and traveling in self-driving cars with supercomputers for brains, it is not hard to imagine such hosts.

What is a DDoS Attack?

At its core, a DDoS attack aims to overwhelm a target server or network with an enormous volume of traffic, rendering it unable to handle legitimate requests. Attackers achieve this by harnessing a compromised computer network, forming a botnet, and directing it towards the target. The motive behind such attacks can vary, including extortion, revenge, or malicious intent.

There are several types of DDoS attacks, each with its unique characteristics. Some common variations include:

1. Volume-Based Attacks: These attacks flood the target with massive traffic, consuming all available bandwidth and resources.

2. Protocol Attacks: Instead of targeting the target’s bandwidth, protocol attacks exploit vulnerabilities in network protocols (e.g., TCP/IP) to exhaust server resources or disrupt communication.

3. Application Layer Attacks: These attacks target web applications or services, overwhelming them with requests until they become unresponsive.

Key Considerations on DDoS Attacks:

In DoS attacks, the attacker disrupts the services of a host connected to a network to make the host or resource unavailable to its intended users. To achieve denial of service, extra requests are flooded onto a targeted machine or resource to overload it and prevent some or all legitimate requests from being fulfilled. Various attacks can slow down a server, including flooding it with millions of requests, overloading it with invalid data, and sending requests from an illegitimate IP address.

Distributed denial-of-service attacks (DDoS attacks) flood the victim with traffic from many sources. Managing this type of attack requires more sophisticated strategies, as blocking one source is insufficient. The effects of a DDoS attack are similar to crowding the entrance of a business, disrupting trade, and causing the company to lose money. DoS attacks are often perpetrated against high-profile web servers, including banks and payment gateways. Motives for these attacks include revenge, blackmail, or hacktivism.

Cloud Armor DoS Protection

### What is Cloud Armor?

Cloud Armor is a security service designed to protect applications and websites from harmful internet traffic. Leveraging the power of global cloud infrastructure, Cloud Armor provides scalable and reliable defense mechanisms against DDoS attacks. It acts as a shield, filtering out malicious traffic while allowing legitimate users to access the services they need. With its ability to scale according to the size and scope of an attack, Cloud Armor ensures that your digital assets remain safe and operational.

### Key Features of Cloud Armor

Cloud Armor boasts several features that make it an essential tool for DDoS protection. Firstly, its global reach allows it to detect and mitigate threats from any part of the world, offering comprehensive protection. Additionally, Cloud Armor’s intelligent algorithms can differentiate between normal and malicious traffic, ensuring that genuine users experience no disruption. Another significant feature is its real-time monitoring and reporting capabilities, which provide insights into attack patterns and help in fine-tuning security strategies.

### How Cloud Armor Enhances Security

Beyond its primary role in DDoS mitigation, Cloud Armor also enhances overall security through its integration with other security services. By working in tandem with firewalls and intrusion detection systems, Cloud Armor creates a multi-layered defense strategy that is harder for attackers to penetrate. This holistic approach not only safeguards against DDoS attacks but also protects against other types of cyber threats, ensuring a robust security posture.

### Implementing Cloud Armor in Your Organization

Integrating Cloud Armor into your organization’s security framework is a strategic move towards ensuring digital resilience. The process begins with an assessment of your current infrastructure to identify vulnerabilities and determine the level of protection needed. Once implemented, Cloud Armor’s customizable rules and policies allow you to tailor its functionalities to suit your specific needs. Regular updates and security audits will help in maintaining optimal performance and protection levels.

Example Yo-yo attack

A yo-yo attack is a DoS/DDoS targeting cloud-hosted applications using autoscaling. An attacker generates a flood of traffic until a cloud-hosted service can handle the increase in traffic, then stops the attack, leaving the victim with overprovisioned resources. The attack resumes when the victim scales down again, causing resources to be rescaled. As a result, the quality of service may be reduced during scaling up and down, and over-provisioning can drain resources. However, an attacker will pay a lower cost than a typical DDoS attack since it only needs to generate traffic for a portion of the attack period.

Popular DDOS Attacking Tools

1. LOIC (Low Orbit Ion Cannon): LOIC is a widely known DDOS attacking tool that enables users to flood a target with traffic, often rendering it inaccessible. Its simplicity and accessibility have made it a popular choice among inexperienced attackers.

2. HOIC (High Orbit Ion Cannon): HOIC is an upgraded LOIC version capable of launching more powerful attacks. It utilizes a decentralized approach, making it harder to trace the source of the attack.

3. Slowloris: Unlike traditional flood attacks, Slowloris takes a stealthy approach. It sends partial HTTP requests to the target server, gradually consuming its resources until it becomes overwhelmed and unresponsive.

#### Botnets – The Army of Attackers

Botnets represent a more sophisticated and dangerous form of DDoS attack. By hijacking thousands of vulnerable devices, attackers create a network capable of executing massive DDoS campaigns. Tools like Mirai have demonstrated the destructive power of botnets, bringing down major websites and services. Defending against botnets requires robust security measures and constant vigilance.

Protecting Docker Containers

Understanding Docker Images

Docker Images are the building blocks of Docker containers. They contain everything needed to run software, including the code, runtime, system tools, libraries, etc. Using Docker Images, developers can ensure consistency, portability, and efficiency across different environments.

The Stress tool is a powerful utility that allows developers to simulate high-stress scenarios and measure the performance and reliability of their systems. It can generate high CPU, memory, I/O, or network loads, helping identify potential bottlenecks and areas for improvement. By combining Docker Images with the Stress tool, developers can create controlled testing environments that resemble real-world usage scenarios.

DDoS Mitigation

It is already well known that a DDoS attack can have catastrophic effects on your service, business, and infrastructure.

Even though macro and micro behavior can detect an attack, we need to get down to the nitty-gritty of the attack to devise a mitigation strategy. Mitigation strategies must be tailored to the attack you are experiencing, just as doctors prescribe precise medication based on symptoms. For example, a payload filter that stops HTTP GET floods cannot stop TCP SYN floods.

As a general rule, DDoS attacks rely on the same type of exploit repeated several times. An example of a TCP SYN Flood attack is when a packet, TCP SYN, is repeated from different sources repeatedly and reaches your network. The volumetric and differentiation aspects of the attack present the biggest challenge to mitigating it. Using a very high traffic rate, the mitigation distinguishes the legitimate request (in this instance, TCP SYN) from the malicious request.

**Identifying the Warning Signs**

One of the most crucial steps in DDoS mitigation is early detection. Recognizing the warning signs can make a significant difference in your response strategy. Common indicators include unusual slow network performance, unavailability of a particular website, or an increase in spam emails. By setting up alerts for unusual traffic patterns and regularly monitoring network activity, businesses can identify potential DDoS threats before they escalate.

**Implementing Robust Defense Mechanisms**

Once a potential threat has been identified, implementing a robust defense mechanism is essential. A multi-layered approach is often the most effective strategy. This includes deploying firewalls, intrusion detection systems, and anti-DDoS hardware and software solutions. Additionally, working with a DDoS mitigation service provider can offer specialized expertise and resources that are tailored to your specific needs. These providers use advanced technologies and methodologies to filter out malicious traffic and ensure legitimate traffic can reach its destination.

**Developing a Response Plan**

Having an established response plan is a critical component of any DDoS mitigation strategy. This plan should outline the steps to be taken in the event of an attack, including communication protocols, roles and responsibilities, and escalation procedures. Regularly updating and testing this plan ensures that all team members are prepared and can respond quickly and efficiently. A well-developed response plan can minimize downtime and help maintain customer trust and business continuity.

DNS Reflection Attack
Diagram: DNS Reflection Attack.

**A mechanism for distraction**

DDoS attacks are deliberate attempts to make resources unavailable for their intended use. They are like lightning and are very common in today’s internet landscape, having a wide range of adverse effects on public, private, and small businesses. A DDoS goal is to draw systems, bandwidth, or human resources and block service from legitimate connections. They are commonly not isolated events and are often implemented to facilitate a more significant sophisticated attack. In addition, they can be used as a mechanism for distraction.

Example: NTP Reflection Attack

For example, a large UDP flood combined with a slow HTTP GET flood. Internet history’s most significant denial of service event was an NTP reflection DDoS attack that peaked at 400Gbps. Now, we have a range of new IPv6 DDoS attacks to circumvent. Opening up a range of IPv6 attacks, some targeting IPv6 host exposure. 

  1.  
DDoS Defence Experiment

Which Mitigation Control Actually Changes the Outcome?

Experiment with traffic conditions and defensive controls. The model shows why a single mitigation mechanism is rarely sufficient: volumetric, protocol/state-exhaustion and application-layer pressure require different control points.

Traffic Path Ready
Traffic Distributed Sources
→
Control Point Edge / CDN
→
Mitigation Filtering Layer
→
Protected Service Application
Attack Pressure Moderate
Traffic Reaching Origin 82%
Service Availability Degraded
Best Control Edge Filtering
Origin Load
Protection
Visibility
Defence Trace
Waiting for mitigation test...
Select a scenario and defensive controls.
Engineering Insight

Different DDoS conditions require different enforcement points. Edge filtering and scrubbing can reduce volumetric pressure before it reaches the origin, while application-aware controls are more useful when the traffic itself resembles legitimate requests.

Illustrative defensive simulation — values represent relative pressure and protection, not measured performance of a real CDN, WAF, network or DDoS mitigation service.

DDoS Attacks

DNS Security 

### The Role of DNS Security

DNS Security forms a cornerstone of the Security Command Center’s offerings. As one of the primary protocols that keep the internet functioning seamlessly, the Domain Name System (DNS) is a frequent target for cybercriminals. From cache poisoning to DNS tunneling, the threats are diverse and evolving. The SCC employs advanced DNS security measures to detect and neutralize these threats, ensuring your domain’s integrity and availability remain uncompromised. By leveraging these capabilities, businesses can protect sensitive data and maintain the trust of their users.

### Leveraging Google Cloud for Enhanced Protection

Google Cloud’s integration with the Security Command Center enhances its utility manifold. This synergy offers unparalleled insights and control over cloud resources, ensuring that security is not just an afterthought but an integral part of the cloud strategy. With Google Cloud’s advanced analytics and threat intelligence, the SCC can identify vulnerabilities across various layers of infrastructure. This integration also facilitates automated responses to incidents, minimizing downtime and potential damage.

### Defending Against DDoS Attacks

DDoS (Distributed Denial of Service) attacks remain a persistent threat to online services. These attacks can cripple a network by overwhelming it with traffic, leading to significant downtime and financial losses. The Security Command Center provides robust defenses against such threats by monitoring traffic patterns and deploying countermeasures in real-time. By utilizing machine learning algorithms, the SCC can differentiate between legitimate traffic and potential DDoS attempts, ensuring continuous availability of services.

DDoS attacks have existed for almost as long as the web has existed. Unfortunately, they remain one of the most effective ways to disrupt online services. The most common DDoS attack is to congest your network, which can be performed in several ways. This congestion can happen at your internet egress or another network bottleneck.

The pre-mitigation step against these flooding scenarios demands that you understand your current capacities. These can be your bandwidth capacity and packets-per-second capabilities. This information will be matched to the flood level you are observing; at this point, you need to initiate the different mitigation tools you have at your disposal.

Types of DDOS Attacks:

1. Volume-based attacks aim to saturate the target’s network or server capacity by flooding it with massive traffic. Standard techniques used in volume-based attacks include ICMP floods, UDP floods, and amplification attacks.

2. Application-layer attacks exploit vulnerabilities in the target’s web applications or services. By sending many seemingly legitimate requests, the attacker aims to exhaust the target’s resources, rendering it unable to serve genuine users. Examples of application-layer attacks include HTTP floods and Slowloris attacks.

3. Protocol attacks: These attacks exploit vulnerabilities in network protocols to overwhelm the target’s resources. For instance, SYN floods flood the target with high SYN requests, depleting its capacity to respond to legitimate traffic.

Impact of DDOS Attacks:

DDOS attacks can have severe consequences for both individuals and organizations. Some of the notable impacts include:

1. Financial losses: A successful DDOS attack can result in significant financial losses for businesses, as their online services become unavailable, leading to decreased productivity, lost sales, and potential reputational damage.

2. Reputation damage: Organizations that fall victim to DDOS attacks may suffer reputational damage, as customers and clients lose trust in their ability to provide reliable services. This can further impact their long-term growth and success.

3. Disruption of critical services: DDOS attacks can disrupt critical services, such as banking, healthcare, or government systems, leading to potential chaos and loss of essential services for individuals and communities.

Mitigating DDOS Attacks:

While it is impossible to eliminate the risk of DDOS attacks completely, there are several measures individuals and organizations can take to mitigate the impact:

1. Implementing robust network infrastructure: Organizations should invest in scalable and resilient network infrastructure that can withstand high traffic volumes. This includes load balancing, traffic filtering, and redundant systems.

2. Utilizing DDOS mitigation services: Professional DDOS mitigation services can help organizations identify, mitigate, and respond to attacks effectively. These services employ advanced techniques like traffic analysis, rate limiting, and behavior-based anomaly detection.

3. Regular security audits: Regular security audits can help identify vulnerabilities that could be exploited in a DDOS attack. By addressing these vulnerabilities promptly, organizations can reduce their risk exposure.

DDoS: An Expensive Type of Attack

A port on a firewall or an IPS device is expensive. Third-party infrastructure-as-a-service options are available on a demand basis. In this case, you don’t need to overprovision bandwidth or purchase specialist hardware, as third-party DDoS companies already have the capacity and capability to deal with such attacks.

Content distribution networks help by absorbing DDoS traffic. There are also cloud-based firms specializing in DDoS mitigation. If you are under an attack, you can redirect your traffic to their network, which is scrubbed and sent back. They put a shield in front of your services. 

Cloud Flare offered a content delivery network and distributed domain name server service. They are known to have protected the LulzSec website from several high-profile attacks. They use reverse proxy technology and an anycast network, enabling them to take high-volume DDoS attacks and spread them over a large surface area.

Cloudflare recently experienced an attack using Google IP addresses as a reflector; they called this the Google ACK reflection attack. Cloud Flare has special rules, so they never block Google’s legitimate crawler traffic. With a Google ACK reflection, the attacker sends a TCP SYN with a fake header pointing back at an IP address to Google, causing Google to respond with an ACK. It was resolved by blocking the ACK that didn’t have an SYN attached.

IPv6 Link-Local DoS

IPv6 Link-Local DoS attack is an IPv6 RA ( Router Advertisement ) attack. With this IPv6 attack, one attacker can bring down a whole network. It only needs a few packets/sec. With IPv4 DHCP, the host looks up and retrieves an IPv4 address, a PULL process. IPv6 is not done this way. IPv6 addresses are provided by IPv6 router advertising, a PUSH process.

The IPv6 router advertises itself to everyone to join its networks. It uses multicast to all node addresses, similar to broadcast, which uses one packet to every node. The problem is that you can send many RA messages, which causes the target to join ALL networks.

DDoS is a growing problem that gets more sophisticated every year. ISP and user collaboration are essential, but we are not winning the game. Who owns the problem? The end-user doesn’t know they are compromised, and the ISP is just transiting network traffic.

Traffic can quickly go through multiple ISPs, so how do the ISPs trace back and channel to each other? Who do you hold responsible, and in what way are they accountable? Is it fair to personalize an end-user if they don’t know about it? There need to be terms of service for abuse policies. Users should control their computers more and understand that Anti-Virus software is not a complete solution.

DDOS attacks continue to be a persistent threat in the digital world, with potentially devastating consequences for individuals and organizations. By understanding the nature of these attacks and implementing appropriate security measures, we can better protect ourselves and ensure a more secure online environment.

DDoS attacks: Types

There are three main types of DOS attacks: a) Network-centric Layer 4, b) Application-centric Layer 7, and c) IPv6 DDoS Link-Local DoS attacks. The DDoS umbrella holds lots of variations: SYN packets usually fill up connection tables, while ICMP and UDP attacks consume bandwidth.

Layer 4 attacks

Layer 4 is the simplest type of attack and has been used to take down companies such as MasterCard and Visa. These attacks use thousands of machines to bring down one. They’re primitive-style attacks in which multiple machines send simple packets to a target, attempting to deplete computing resources like CPU, memory, and network bandwidth.

The connections are standard; they establish fully and terminate as regular connections do, unlike Layer 7 attacks (discussed below). The connection only takes a few seconds, so thousands of hosts must overload a single target. For example, the tools for Layer 4 attacks are readily available – low orbit ion cannon (LOIC). LOIC is an open-source denial-of-service attack application written in C#. Layer 4 DDoS attacks are easily tracked back and blocked.

Layer 7  attacks

Layer 7 attacks are more sophisticated and usually require one to bring down many. For example, Wikileaks’s whistle-blowing website went down for one day with only one attacker penetrating a Layer 7 attack. A SlowLoris attack is an elegant Layer 7 attack associated with several high-profile attacks. It opens multiple connections to the targeted web server and keeps them open.

It uses up all the lines and blocks legitimate traffic, designed to keep all the tables full. Layer 4 attacks cannot be run through anonymity networks (ToR networks), but Layer 7 attacks can, due to their small packets/second rate. Layer 7 attacks are like guided missiles. The pending requests take up to 400 seconds, so you don’t need to send many.

Common types of attacks

The most common type of attacks right now are carried out with HTTP. About 80% of the attack surface is coming through HTTP. A Layer 7 HTTP GET attack requests to send only part of the HTTP GET. As a result, the server assumes you are on an unreliable network and have fragmented packets. It waits for the other half, which ties up resources, freezing all available lines.

All you need is about one packet per second. The R-U-Dead-Yet attack is similar to the HTTP GET attack but uses HTTP POSTS instead of HTTP GETs. It works by sending incomplete HTTP POSTs, which affects IIS servers. IIS is not affected by the SlowLoris attack that sends incomplete HTTP GET. There are other variations called HTTP Keep-Alive DoS. HTTP Keepalives allows 100 requests in a single connection. 

Closing Points on DDoS Attacks

Essentially, a DDoS attack is an attempt to crash a server, a service, or a network by overwhelming it with a flood of internet traffic. Imagine hundreds of people trying to squeeze through a single door at once; the result is chaos and congestion, preventing legitimate users from entering. This is precisely what happens during a DDoS attack, where multiple compromised systems are used to target a single system, causing a denial of service for users of the targeted resource.

Understanding the mechanics of a DDoS attack can help in developing strategies to mitigate its impact. These attacks harness the power of botnets—networks of infected computers controlled by attackers—to flood targets with traffic. The targeted system is inundated with requests, rendering it slow or completely inoperative. There are several types of DDoS attacks, including volumetric attacks, which saturate the bandwidth of the victim, and application-layer attacks, which target web applications to exhaust resources.

The implications of a successful DDoS attack can be devastating. Beyond the immediate disruption of services, there are financial repercussions, including lost revenue, the cost of mitigation, and potential regulatory fines. Moreover, the reputational damage can be long-lasting, as customers lose trust in the reliability of a company’s digital services. For businesses, especially those that rely heavily on their online presence, a DDoS attack can be catastrophic.

Given the potential damage, it’s crucial to implement robust defense strategies against DDoS attacks. Organizations can invest in DDoS protection services that detect and mitigate attacks in real-time. Additionally, creating a response plan that includes identifying vulnerabilities, developing incident response teams, and conducting regular security audits can help in preparing for potential threats. Leveraging cloud-based solutions, which can absorb and disperse attack traffic, is another effective strategy to protect against these attacks.

Network Insight • DDoS Incident Response

DDoS Incident: The Website Is Suddenly Slow

You are on the response team. The service is degrading, but the evidence does not yet tell you whether the dominant problem is bandwidth, connection state or application demand. Classify the incident before choosing the mitigation.

Incident Evidence Live Snapshot
Edge traffic 6× baseline
Inbound bandwidth 92% capacity
HTTP requests 4× baseline
TCP connection rate 8× baseline
Origin CPU 48%
Application errors Increasing
WAF anomaly alerts Elevated
Normal user reports Slow / intermittent
The evidence is intentionally mixed. A good incident responder classifies the dominant pressure instead of assuming every traffic spike is the same type of DDoS.
Step 1 — What Should You Investigate First? Decision
The website is slow and traffic is far above baseline. What is the safest first response?
Awaiting Decision

Select the action you would take first, then evaluate the incident.

Decision Score 0 / 4
Incident Class Unknown
Priority Classify
Recommended Response Sequence
01 Detect & Correlate
→
02 Classify Traffic
→
03 Absorb at Edge
→
04 Protect Origin
→
05 Verify Recovery
Incident Console
12:00:00 Monitoring baseline traffic...
12:00:05 Service latency alert received.
12:00:08 Waiting for responder decision...
Defensive training simulation only. No attack traffic, attack tooling or operational DDoS instructions are generated. Real incident response depends on architecture, provider capabilities, telemetry and established escalation procedures.
Layer 2 VPN

EVPN – MPLS-based Layer 2 VPN

EVPN MPLS - What Is EVPN 

In today's rapidly evolving digital landscape, businesses constantly seek ways to enhance their network infrastructure for improved performance, scalability, and security. One technology that has gained significant traction is Ethernet Virtual Private Network (EVPN). In this blog post, we will delve into the world of EVPN, exploring its benefits, use cases, and how it can revolutionize modern networking solutions.

EVPN, short for Ethernet Virtual Private Network, is a cutting-edge technology that combines the best features of Layer 2 and Layer 3 protocols to create a flexible and scalable virtual network overlay. It provides a seamless and secure connectivity solution for local and wide-area networks, making it an ideal choice for businesses of all sizes.

Understanding EVPN: EVPN, at its core, is a next-generation networking technology that combines the best of both Layer 2 and Layer 3 connectivity. It provides a unified and scalable solution for connecting geographically dispersed sites, data centers, and cloud environments. By utilizing Ethernet as the foundation, EVPN enables seamless integration of Layer 2 and Layer 3 services, making it a versatile and flexible option for various networking requirements.

Key Features and Benefits: EVPN boasts several key features that set it apart from traditional networking solutions. Firstly, it offers a simplified and centralized control plane, eliminating the need for complex and cumbersome protocols. This not only enhances network scalability but also improves operational efficiency. Additionally, EVPN provides enhanced network security through mechanisms like MACsec encryption, protecting sensitive data as it traverses the network.

One of the standout benefits of EVPN is its ability to support multi-tenancy environments. With EVPN, service providers can effortlessly segment their networks, ensuring isolation and dedicated resources for different customers or tenants. This makes it an ideal solution for enterprises and service providers alike, empowering them to deliver customized and secure network services.

Use Cases and Applications: EVPN has found widespread adoption across various industries and use cases. In the data center realm, EVPN enables efficient workload mobility and disaster recovery capabilities, allowing seamless migration and failover between servers and data centers. Moreover, EVPN facilitates the creation of overlay networks, simplifying network management and enabling rapid deployment of services.

Beyond data centers, EVPN proves its worth in the context of service providers. It enables the delivery of advanced services such as virtual private LAN services (VPLS), virtualized network functions (VNFs), and network slicing. EVPN's versatility and scalability make it an indispensable tool for service providers looking to stay ahead in the competitive landscape.

Network Insight • EVPN Architecture

How Does EVPN Turn Endpoint Learning Into a Scalable Control Plane?

EVPN separates the question of where an endpoint is from the act of forwarding the packet. MP-BGP distributes endpoint reachability information, while an MPLS or VXLAN transport carries the resulting traffic across the network.

Control Plane → Transport → Forwarding Ready
EVPN
Control Plane
Endpoint MAC / IP
PE / VTEP PE1
MP-BGP EVPN NLRI
PE / VTEP PE2
Data Plane
Ingress Frame Arrives
Transport MPLS Core
Egress PE2 / VTEP
Destination Remote Endpoint
Control Plane MP-BGP EVPN
Endpoint State Distributed
Transport MPLS
Forwarding Model Control-Plane Guided
EVPN Trace
Waiting for topology trace...
Configure the EVPN model and run the trace.
Engineering Insight

EVPN uses BGP as a control plane to distribute endpoint reachability information. The transport beneath it can differ: EVPN can be deployed over MPLS or used with VXLAN in data-center fabrics. The control-plane concept remains distinct from the underlying packet-transport mechanism.

Illustrative architecture model. EVPN route types, multihoming behaviour, transport encapsulation and implementation details vary by deployment and platform.

Highlights: EVPN MPLS - What Is EVPN 

### What is EVPN?

Ethernet VPN (EVPN) is a technology designed to enhance and streamline network virtualization. As businesses increasingly rely on cloud computing and virtualized environments, EVPN provides a scalable and flexible solution for interconnecting data centers and managing complex network architectures. Think of EVPN as a sophisticated method of creating a virtual bridge that connects different network segments, allowing data to flow seamlessly and securely across them.

### How EVPN Works

EVPN operates by using a combination of BGP (Border Gateway Protocol) and MPLS (Multiprotocol Label Switching) to manage and direct traffic flow across virtual networks. This allows for efficient routing and switching, reducing latency and improving overall network performance. By utilizing a centralized control plane, EVPN simplifies network management, making it easier for IT professionals to monitor and adjust network resources as needed.

Discussing EVPN

– Before we delve into the technical intricacies, let’s get a grasp of the fundamentals of EVPN. EVPN is a technology that combines the best of both Layer 2 and Layer 3 connectivity. It offers a flexible and versatile approach to network design, enabling seamless communication between different sites and data centers. By leveraging the power of Multiprotocol Label Switching (MPLS) and Border Gateway Protocol (BGP), EVPN ensures efficient traffic forwarding and network virtualization.

Key EVPN Benefits: 

– Now that we have a basic understanding, let’s explore the key benefits that EVPN brings to the table. Firstly, EVPN provides enhanced scalability, allowing organizations to expand their networks without compromising performance. It offers efficient load balancing and traffic engineering capabilities, ensuring optimized resource utilization. Secondly, EVPN enables seamless integration with existing infrastructure, making it an ideal choice for businesses looking to upgrade their networks. Lastly, EVPN provides built-in support for multipath forwarding, promoting high availability and resilience.

Key EVPN Use Cases:

– EVPN has found its place in various real-world applications, revolutionizing network connectivity across industries. One such application is in cloud service providers’ data centers, where EVPN enables efficient interconnectivity between virtual machines and facilitates workload mobility. Additionally, EVPN is widely used in enterprise networks, enabling seamless connectivity between different branches and ensuring secure communication across the organization. EVPN also plays a crucial role in service provider networks, offering scalable and flexible solutions for delivering services to customers.

Note: EVPN Considerations

1 Enhanced Scalability: Unlike traditional Layer 2 VPNs, EVPN efficiently utilizes network resources by implementing a single control plane. This eliminates the need for flooding broadcasts across the entire network, resulting in improved scalability and more efficient data transmission.

2 Seamless Multicast Support: EVPN provides native support for multicast traffic, making it an ideal choice for applications that rely on efficient multicast distribution. With EVPN, multicast streams can be seamlessly propagated across the network, ensuring optimal performance and reducing bandwidth consumption.

3 Simplified Network Management: EVPN offers a centralized control plane, allowing for simplified network management and configuration, and with the use of BGP as the control protocol, EVPN leverages existing routing mechanisms, making it easier to integrate with existing networks and reducing the complexity of network operations.

Real-World Applications of EVPN

1 Data Center Interconnectivity: EVPN is widely adopted in data centers, enabling efficient interconnectivity between different sites. By supporting Layer 2 and Layer 3 services simultaneously, EVPN simplifies the deployment and management of multi-site architectures, providing seamless connectivity for virtual machines and containers.

2 Service Provider Edge: EVPN has gained traction due to its versatility and scalability in the service provider space. Service providers can leverage EVPN to deliver flexible and robust connectivity services, such as E-LAN and E-VPN, to their customers. EVPN’s ability to support multiple Layer 2 and Layer 3 services on a single platform makes it an attractive solution for service providers.

Understanding EVPN Fundamentals

EVPN, at its core, is a technology that combines the best of both Layer 2 and Layer 3 networking. Utilizing the BGP (Border Gateway Protocol) enables the creation of virtual private networks over an Ethernet infrastructure. This unique approach brings numerous advantages, such as improved scalability, simplified management, and seamless integration with existing protocols.

BGP For the Data Center

A shift in strategy has led to the evolution of data center topologies from three-tiers to three-stage Clos architectures (and five-stage Clos fabrics for large-scale data centers), eliminating protocols such as Spanning Tree, which made the infrastructure more challenging to operate (and more expensive) to maintain by blocking redundant paths by default.

A routing protocol was needed to convert the network natively to Layer 3 with ECMP. The control plane should be simplified, control plane interactions should be minimized, and network downtime should be minimized as much as possible.

Before the introduction of BGP, service provider networks primarily used it to reach autonomous systems. Before recently, BGP was the interdomain routing protocol on the Internet. Unlike interior gateway protocols such as Open Shortest Path First (OSPF) and Intermediate System-to-Intermediate System (IS-IS), which use a shortest path first logic, BGP relies on routing based on policy (with the autonomous system number [ASN] acting as a tiebreaker in most cases).

BGP in the data center

Key Point: RFC 7938

“Use of BGP for Routing in Large-Scale Data Centers,” RFC 7938, explains that BGP with a routed design can benefit data centers with a 3-stage or 5-stage Clos architecture. In VXLAN fabrics, external BGP (eBGP) can be used as an underlay and an overlay. Using eBGP as an underlay, this chapter will show how BGP can be adapted for the data center, offering the following features for large-scale deployments:

Implementation is simplified by relying on TCP for underlying transport and adjacency establishment. Well-known ASN schemes and minimal design changes prevent such problems despite the assumption that BGP will take longer to converge.

Example: In Junos, BGP groups provide a vertical separation between eBGP for the underlay (for IPv4 or IPv6) and eBGP for the overlay (for EVPN addresses). Overlay and underlay BGP simplify maintenance and operations. Besides that, eBGP is generally easier to deploy and troubleshoot than internal BGP (iBGP), which relies on route reflectors (or confederations).

BGP neighbors can be automatically discovered through link-local IPv6 addressing, and NLRI can be transported over IPv6 peering using RFC 8950 (which replaces RFC 5549).

Example BGP Technology: IPv6 and MBGP

VXLAN-based fabrics

VXLAN uses a control plane protocol for remote MAC address learning as a network virtualization overlay. VXLAN-based data center fabrics benefit greatly from BGP Ethernet VPNs (EVPNs) over traditional Layer 2 extension mechanisms like VPLS. Layer 2 and 3 overlays can be built, IP reachability information can be provided, and data-driven learning is no longer required to disseminate MAC addresses due to its inability to scale.

VXLAN-based data center fabrics use several route types, and this chapter explains each type and its packet format.

Extending BGP

What is EVPN? EVPN (Ethernet Virtual Private Network) extends to Border Gateway Protocol (BGP), allowing the network to carry endpoint reachability information such as layer 2 MAC and layer 3 IP addresses. This control plane technology uses MP-BGP for MAC and IP address endpoint distribution. One initial consideration is that layer 2 MAC addresses are treated as IP routes. It is based on standards defined by the IEEE 802.1Q and 802.1ad specifications.

Connects Layer 2 Segments

EVPN, also known as Ethernet VPN, connects L2 network segments separated by an L3 network. This is accomplished by building the L2 VPN network as a virtual Layer 2 network overlay over the Layer 3 network. It uses Border Gateway Protocol (BGP) for routing control as its control protocol. EVPN is a BGP-based control plane that can implement Layer 2 and Layer 3 VPNs.

**Understanding MP-BGP in the Context of EVPN**

MP-BGP is essentially an extension of the traditional BGP, enabling it to carry routing information for multiple network layer protocols. Its application in EVPN is particularly noteworthy. EVPN utilizes MP-BGP to distribute MAC and IP address information, ensuring seamless communication and connectivity across different network segments. This capability is essential for modern data centers, which require high levels of scalability and flexibility.

**Key Advantages of MP-BGP for Endpoint Distribution**

One of the standout benefits of using MP-BGP for MAC and IP endpoint distribution is its scalability. As network demands grow, MP-BGP can handle increased numbers of endpoints without significant degradation in performance. Additionally, its ability to integrate with EVPN allows for dynamic and efficient routing, reducing the complexity often associated with large-scale network operations. This integration results in more stable and reliable network performance, a critical factor for businesses dependent on continuous connectivity.


EVPN Transport Experiment

EVPN over MPLS vs EVPN over VXLAN

Change the transport and service model to see what actually moves through the network. EVPN remains the BGP-based control plane; MPLS or VXLAN provides the underlying data-plane transport.
ILLUSTRATIVE MODEL
EVPN Forwarding Path Ready
A
Endpoint A MAC / IP
V
PE / VTEP 1 EVPN edge
IP UNDERLAY
VXLAN Tunnel VTEP → VTEP · VNI encapsulation
V
PE / VTEP 2 EVPN edge
B
Endpoint B MAC / IP
Control Plane MP-BGP EVPN
Data Plane VXLAN / UDP / IP
Service State MAC Reachability
Multi-Homing Single-Homed

Experiment Result

Transport VXLAN over IP
EVPN Function Endpoint Reachability
Encapsulation VXLAN VNI
Failure / Event Normal
Flooding Dependency Reduced by control-plane learning
EVPN Event Trace
12:00:00 Waiting for experiment...
12:00:01 MP-BGP EVPN control plane ready
Engineering insight: EVPN separates the control-plane job from the transport technology. MP-BGP advertises endpoint reachability, while VXLAN or MPLS carries the resulting traffic across the network.
Conceptual EVPN model. Exact route types, encapsulation, VTEP/PE behaviour, multi-homing mechanisms and vendor implementations vary.

EVPN MPLS - What Is EVPN 

Hierarchical networks

Organizations have built hierarchical networks in the past decades using hierarchical addressing mechanisms such as the Internet Protocol (IP) or creating and interconnecting multiple network domains. Large bridged domains have always presented a challenge for scaling and fault isolation due to Layer 2 and nonhierarchical address spaces. As endpoint mobility has increased, technologies are needed to build more efficient Layer 2 extensions and reintroduce hierarchies.

The Data Center Interconnect (DCI) technology uses dedicated interconnectivity to restore hierarchy within the data center. Even though DCI can interconnect multiple data centers within a single data center, large fabrics enable borderless endpoint placement and mobility. This trend resulted in an explosion of ARP and MAC entries. VXLAN’s Layer 2 over Layer 3 capabilities were supposed to address this challenge. However, they have only added to it, allowing even larger Layer 2 domains to be built as the location boundary is overcome.

**Spine and Leaf Designs**

The spine and leaf, fat tree, and folded Clos topologies became standard for fabrics. VXLAN, an over-the-top network, flattens out the hierarchy of the new network topology models. With the introduction of the overlay network, the network hierarchy was hidden, even though the underlying topology was predominantly Layer 3, and hierarchies were present. In addition to its benefits, flattening has some drawbacks as well. The simplicity of building a network over the top without touching every switch makes it easy to extend across multiple sites.

As a result, this new overlay networking design presents a risk without failure isolation, especially in large, stretched Layer 2 networks. Whatever is sent through the ingress point to the respective egress point will leave the overlay network. This is done using the “closest to the source” and “closest to the destination” approaches.

With EVPN Multi-Site, overlay networks can maintain hierarchies again. A new version of EVPN Multi-Site for VXLAN BGP EVPN networks introduces external BGP (eBGP), while interior BGP (iBGP) has been the dominant model. The Border Gateways (BGWs) were introduced with autonomous systems (ASs) as a response to eBGP next-hop behavior. Hierarchies are effectively used to classify and connect multiple overlay networks using this approach. Moreover, network extensions within and beyond one data center are controlled and enforced by a control point.

**The Role of Layer 2**

It started as a pure Layer 2 solution and got some Layer 3 functionality pretty early on. Later, it got all the blown IP prefixes, so now you can use EPVN to implement complete Layer 2 and Layer VPNs. EVPN is now considered a mature technology that has been available in multiprotocol label switching (MPLS) networks for some time.

Therefore, many refer to this to it as EVPN over MPLS. When discussing EVPN-MPLS or MPLS EVPN, EPVN still uses Route Distinguisher (RD) and Route Targets (RT).

RD creates separate address spaces, and RT integrates VPN membership. Remember that the precursor to EVPN was Over-the-Top Virtualization (OTV), a proprietary technology invented by Dino Farinacci while working at Cisco. Dino also worked heavily with the LISP protocol.

OTV used Intermediate System–to–Intermediate System (IS-IS) as the control plane and ran over IP networks. IS-IS can build paths for both unicast and multicast routes. 

Data center fabric journey

Spanning Tree and Virtual PortChannel

We have evolved data center networks over the past several years. Spanning Tree Protocol (STP)–-based networks served network requirements for several years. Virtual PortChannel (vPC) was introduced to address some of the drawbacks of STP networks while providing dual-homing abilities. Subsequently, overlay technologies such as FabricPath and TRILL came to the forefront, introducing routed Layer 2 networks with a MAC-in-MAC overlay encapsulation. This evolved into a MAC-in-IP overlay with the invention of VXLAN.

vpc virtual port channel

While Layer 2 networks evolved beyond the loop-free topologies with STP, the first-hop gateway functions for Layer 3 also became more sophisticated. The traditional centralized gateways hosted at the distribution or aggregation layers have transitioned to distributed gateway implementations, which has allowed for scaling out and the removal of choke points.

Virtual port channels
Diagram: Virtual port channels. Source Cisco

Cisco FabricPath is a MAC-in-MAC

Cisco FabricPath is a MAC-in-MAC encapsulation that eliminates the use of STP in Layer 2 networks. Instead, it uses Layer 2 Intermediate System to Intermediate System (IS-IS) with appropriate extensions to distribute the topology information among the network switches. In this way, switches behave like routers, building switch reachability tables and inheriting all the advantages of Layer 3 strategies such as ECMP. In addition, no unused links exist in this scenario, while optimal forwarding between any pair of switches is promoted.

The rise of VXLAN

While FabricPath has been immensely popular and adopted by thousands of customers, it has faced skepticism because it is associated with a single vendor, Cisco, and lacks multivendor support. In addition, with IP being the de facto standard in the networking industry, an IP-based overlay encapsulation was pushed. As a result, VXLAN was introduced. VXLAN, a MAC-in-IP/UDP encapsulation, is currently the most popular overlay encapsulation.

As an open standard, it has received widespread adoption from networking vendors. Just like FabricPath, VXLAN addresses all the STP limitations previously described. However, with VXLAN, a 24-bit number identifies a virtual network segment, thereby allowing support for up to 16 million broadcast domains as opposed to the traditional 4K limitations imposed by VLANs.

Example VXLAN Technology:  VXLAN

### Understanding the Basics

VXLAN operates by encapsulating Layer 2 Ethernet frames within Layer 3 UDP packets, enabling networks to stretch across large IP networks. This encapsulation process is facilitated by the VXLAN Network Identifier (VNI), a unique identifier that replaces the traditional VLAN ID. With a 24-bit field, VXLAN can support up to 16 million logical networks, compared to the 4,096 limit imposed by VLANs.

### The VXLAN Architecture

At the core of VXLAN’s architecture are Virtual Tunnel Endpoints (VTEPs). These endpoints are responsible for encapsulating and de-encapsulating packets as they traverse the network. VTEPs can be implemented in both physical and virtual switches, making VXLAN a versatile choice for hybrid network environments. Moreover, the use of a multicast or unicast underlay network ensures that broadcast, unknown unicast, and multicast traffic is efficiently managed.

EVPN MPLS: History

Layer 3 VPNs and MPLS

In the late 1990s, we witnessed the introduction of Layer 3 VPNs and Multiprotocol Label Switching (MPLS). Layer 3 VPNs distribute IP prefixes with a control plane, offering any connectivity. So, we have MPLS VPN with PE and CE routers, and EVPN still uses these devices. MPLS also has RD and RT to create different address spaces.

This is also used in EVPN. Layer 3 VPN needed MPLS encapsulation. This signaling was done with LDP; you can use segment routing today. MPLS L3 VPN supports a range of topologies that can be created with Route Targets. Some of which led to complex design scenarios.

MPLS layer 3 VPN
Diagram: MPLS Layer 3 VPN. Source Aruba Networks.

Layer 2 VPNs and VPLS

Layer 2 VPNs arrived more humbly with a standard point-to-point connectivity model using Frame Relay, ATM, and Ethernet. Finally, in the early 2000s, pseudowires and layer 2 VPNs arrived. Each of these VPN services operates on different VPN connections, with few working on a Level 3 or MPLS connection. Point-to-point connectivity models no longer satisfied all designs, and services required multipoint Ethernet connectivity.

As a result, Virtual Private LAN Service (VPLS) was introduced. Virtual Private LAN Service (VPLS) is an example of L2VPN and has many drawbacks with using pseudowires to create the topology. A mesh of pseudowires with little control plane leads to much complexity.

VPLS with data plane learning

VPLS offered a data plane learning solution that could emulate a bridge and provide multipoint connectivity for Ethernet stations. It was widely deployed but had many shortcomings, such as support for multi-homing, BUM (BUM = Broadcast, Unknown unicast, and Multicast) optimization, flow-based load balancing, and multipathing. So, EVPN was born to answer this problem.

In the last few years, we have entered a different era of data center architecture with other requirements. For example, we need efficient Layer 2 multipoint connectivity, active-active flows, and better multi-homing capability. Unfortunately, the shortcomings of existing data plane solutions hinder these requirements.

EVPN MPLS: Multi-Homing With Per-Flow Capabilities 

Some data centers require Layer 2 DCI (data center interconnect) and active-active flows between locations. Current L2 VPN technologies do not fully address these DCI requirements. A DCI with better multi-homing capability was needed without compromising network convergence and forwarding. Per-flow redundancy and proper load balancing introduced a BGP MPLS-based Ethernet VPN (EVPN) solution.

**No more pseudowires**

With EVPN, pseudowires are no longer needed. All the hard work is done with BGP. A significant benefit of EVPN operations is that MAC learning between PEs occurs not in the data plane but in the control plane (unlike VPLS). It utilizes a hybrid control/data plane model. First, data plane address learning occurs in the access layer.

This would be the CE to PE link in an SP model using IEEE 802.1x, LLDP, or ARP. Then, we have control-plane address advertisements / learning over the MPLS core. The PEs run MP-BGP to advertise and learn customer MAC addresses. EVPN has many capabilities, and its use case is extended to act as the control plane for open standard VXLAN overlays.

Cisco EVPN
Diagram: EVPN with Cisco Catalyst. Source Cisco

L2 VPN challenges

There are several challenges with traditional Layer 2 VPNs. They do not offer an ALL-active per-flow redundancy model, traffic can loop between PEs, MAC flip-flopping may occur, and there is the duplication of BUM traffic (BUM = Broadcast, Unknown unicast, and Multicast).

In the diagram below, a CE has an Ethernet bundle terminating on two PEs: PE1 and PE2. The problem with the pseudowires VPLS data plane learning approach is that PE1 receives traffic on one of the bundle member links. The traffic is sent over the full mesh of PW and eventually learned by PE2. PE2 cannot know if traffic originated on CE1, and PE2 will return it. CEs also get duplicated BUM traffic.

L2 VPN
Diagram: L2 VPN challenges and the need for EVPN.

Another challenge with VPLS and L2 VPN is MAC Flip-flopping over pseudowires. Like the above, you have dual-homed CEs sending traffic from the same MAC but with a different IP address. Now, you have MAC address learning by PE1 and forwarded to the remote PE3. PE3 learns that the MAC address is via PE1, but the same MAC with a different flow can arrive via PE2.

PE3 learns the same MAC over the different links, so it keeps flipping the MAC learning from one link to another. All these problems are forcing us to move to a control plane Layer 2 VPN solution – EVPN.

What Is EVPN

EVPN operates with the same principles and operational experiences as Layer 3 VPNs, such as MP-BGP, route targets (RT), and route distinguishers (RD). EVPN takes BGP, puts a Layer 2 address in it, and advertises as if it were a Layer 3 destination with an MPLS rewrite or MPLS tag as the rewritten header or as the next hop.

It enables the routing of Layer 2 addresses through MP-BGP. Instead of encapsulating an Ethernet frame in IPv4, a MAC address with MPLS tags is sent across the core.

The MPLS core swaps labels as usual and thinks it is another IPv4 packet. This is conceptually similar to IPv6 transportation across an IPv4 LDP core, a feature known as 6PE.

what is evpn

EVPN MPLS: Layer 3 principles apply

All Layer 3 principles apply, allowing you to prepend MAC addresses with RDs to make them unique and permitting overlapping addresses for Layer 2. RTS offers separation, allowing constraints on flooding to interested segments. EVPN gives all your policies with BGP – LP, MED, etc., enabling efficient MAC address flooding control. EVPN is more efficient on your BGP tables; you can control the distribution of the MAC address to the edge of your network.

You control where the MAC addresses are going and where the state is being pushed. It’s a lot simpler than VPLS. You look at the destination MAC address at the network edge and shove a label on it. EVPN has many capabilities. Not only do we use BGP to advertise the reachability of MAC addresses and Ethernet segments, but it may also advertise MAC-to-IP correlation. BGP can provide information that hosts A has this IP and MAC address.

VXLAN & EVPN control plane

Datacenter fabrics started with STP, which is the only thing you can do at Layer 2. Its primary deficiency was that you could only have one active link. We later introduced VPC and VSS, allowing all link forwarding in a non-looped topology. Cisco FabricPath / BGP introduces MAC-in-MAC layer 2 multipathing.

In the gateway area, they added Anycast HSRP, which was limited to 4 gateways. More importantly, they exchanged states.

The industry is moving on, and we now see the introduction of VXLAN as a MAC in IP mechanism. VXLAN allows us to cross a layer 3 boundary and build an overlay over a layer 3 network. Its initial forwarding mechanism was flood and learn, but it had many drawbacks. So now, they have added a control plane to VXLAN—EVPN.

A VXLAN/EVPN solution is an MP-BGP-based control plane using the EVPN NLRI. BGP carries out Layer-2 MAC and Layer-3 IP information distribution. It reduces flooding as forwarding decisions are based on the control plane. The VPN control plane offers VTEP peer discovery and end-host reachability information distribution.

Closing Points on EVPN

Network virtualization has come a long way since its inception. Traditional methods, while effective, often struggled with scalability and flexibility. Enter EVPN, a technology designed to overcome these barriers. By leveraging the power of Border Gateway Protocol (BGP), EVPN provides a multipoint-to-multipoint Layer 2 VPN service, enhancing network performance and efficiency. This evolution reflects a shift towards more dynamic, adaptable networking solutions that cater to the ever-changing demands of businesses.

EVPN offers a myriad of benefits that set it apart from traditional network solutions. Firstly, its ability to support multi-tenancy without compromising security is a game-changer for enterprises. EVPN also simplifies network operations by reducing the need for complex configurations and manual interventions. Additionally, its inherent redundancy and load balancing capabilities ensure high availability and optimal resource utilization. These benefits collectively make EVPN a preferred choice for businesses looking to future-proof their network infrastructure.

At the heart of EVPN’s architecture is its use of BGP for control plane operations, which allows for efficient route distribution and scalability. The EVPN model consists of Provider Edge (PE) routers that communicate through BGP, exchanging reachability information for Layer 2 and Layer 3 services. This architecture not only simplifies network management but also enables seamless integration with existing infrastructures. By decoupling the data plane from the control plane, EVPN provides a flexible framework that supports a wide range of applications and services.

The versatility of EVPN extends into various real-world applications, from data center interconnects to cloud networking. In data centers, EVPN facilitates seamless connectivity and resource sharing, optimizing workload distribution and enhancing operational efficiency. For cloud services, EVPN ensures secure and scalable connectivity across multiple locations, supporting hybrid and multi-cloud environments. These applications highlight EVPN’s role as a critical enabler of modern, agile networking solutions.

EVPN Incident Challenge

EVPN Incident: The Remote MAC Is Missing

A workload is reachable locally but cannot be reached from the remote EVPN edge. Use the evidence to identify where the control-plane learning process has failed.
DIAGNOSE THE FAILURE
Incident Evidence
Alert: Endpoint B is active on PE/VTEP 2, but PE/VTEP 1 has no usable remote MAC entry.
Endpoint B local attachment UP
Local MAC learning PRESENT
MP-BGP EVPN session DOWN
VNI / service mapping MATCH
IP underlay reachability UP
Remote MAC state MISSING
Control Plane → Data Plane Investigation ready
Endpoint B Local MAC
PE / VTEP 2 MAC learned
MP-BGP EVPN Session DOWN
PE / VTEP 1 MAC missing
What Should You Investigate First?
ENGINEERING SCORE
0 / 4
Investigation Trace
12:00:00 Incident loaded
12:00:01 Waiting for engineer diagnosis...
Engineer hint: EVPN endpoint reachability is distributed through the control plane. If the local PE/VTEP has learned the MAC but the remote device has not, investigate the EVPN control-plane exchange before changing the transport.
Conceptual troubleshooting scenario. Real EVPN deployments may involve additional checks such as route targets, VRF/VLAN/VNI mapping, Ethernet Segments, route-type state, next-hop reachability and vendor-specific control-plane behaviour.

BGP FlowSpec

Network Engineering Guide · BGP Security · Traffic Control

BGP FlowSpec enables networks to distribute traffic-filtering and traffic-treatment rules through BGP, helping engineers respond to specific traffic patterns without relying solely on destination-based routing changes.

During a denial-of-service attack or other disruptive traffic event, changing a destination route may be too broad to address the problem. FlowSpec provides a more granular approach: a controller or routing system can distribute rules that match supported traffic characteristics and apply actions supported by the receiving platform.

But receiving a rule is not the same as enforcing it. Engineers must establish whether the policy was accepted, installed at the intended enforcement point, matched the relevant packets, and produced the expected result. They must also check that legitimate traffic remains available and that the response does not create a new operational problem.

This guide takes an engineering-led approach to FlowSpec, moving from policy architecture and visibility through incident diagnosis to remediation and verification. The interactive exercises let you change policy choices, examine evidence, and investigate why an apparently valid rule may fail to affect traffic.

01 · SEE Understand the architecture Follow how a FlowSpec rule is constructed, distributed, and intended to reach an enforcement point.
02 · OBSERVE Examine the evidence Compare policy state, traffic measurements, and enforcement visibility.
03 · INVESTIGATE Isolate the failure Use incident evidence to distinguish distribution, validation, installation, and matching problems.
04 · CORRELATE Verify the outcome Connect routing and forwarding evidence, apply a justified correction, and confirm recovery.
The central engineering question

Can you prove that the intended FlowSpec rule reached the correct enforcement point, matched the intended traffic, and produced the expected outcome without unnecessarily disrupting legitimate services?

Engineering Preview · 01 / Architecture

Follow a FlowSpec Rule Through the Network

A FlowSpec rule has to move from policy definition through BGP distribution and validation before the receiving platform can enforce it. Select a stage to see what the engineer should verify.

**Define:** Identify the traffic pattern, match fields and intended action. Start with evidence, not a broad guess.
Section 01 · See the system

BGP FlowSpec Architecture and Policy Distribution

BGP FlowSpec extends BGP beyond conventional route-prefix advertisement. It allows supported traffic-matching rules and associated actions to be distributed to participating routers, creating a control-plane mechanism for coordinating more granular traffic treatment.

The key architectural distinction is between the control plane, which distributes and processes policy, and the data plane, which evaluates packets against installed forwarding rules. A rule can appear in BGP without being successfully installed or enforced in hardware or software. Understanding that separation is essential when designing a FlowSpec deployment or investigating an incident.

1.1 The FlowSpec policy lifecycle

A typical deployment starts with a traffic event or a policy decision. A controller or authorised routing process creates a FlowSpec NLRI describing the traffic to match and associates it with supported actions. BGP distributes the rule to eligible peers, where import policy, validation, platform capabilities, and forwarding resources determine whether it can be used.

STAGE 01 Define the flow

Identify the relevant traffic characteristics and construct a rule with an appropriate scope.

STAGE 02 Distribute through BGP

Advertise the FlowSpec NLRI to eligible peers under the configured routing policy.

STAGE 03 Validate and install

Evaluate acceptance, validation, supported actions, and forwarding-resource constraints.

STAGE 04 Enforce and verify

Confirm the intended packets are affected and service behaviour matches expectations.

Engineering principle BGP distribution proves that a control-plane exchange occurred. It does not, by itself, prove that the receiving router installed the rule or that packets matched it.

1.2 The main architectural components

FlowSpec controller or policy origin

The origin creates or selects the rule based on a security event, operational decision, or traffic-analysis result. In a production design, its permissions, input validation, and policy-generation process should be controlled and auditable.

BGP speakers and route reflectors

BGP peers carry FlowSpec NLRI between participating systems. Route reflectors may help distribute eligible routes across an iBGP topology, but their behaviour depends on platform support and configuration. Ordinary route-reflection assumptions should not replace FlowSpec-specific verification.

Policy validation and import controls

Receiving routers may apply import policy, origin and route validation checks, rule-consistency checks, and deployment-specific restrictions. A session being Established does not guarantee that every advertised FlowSpec rule will be accepted.

Forwarding enforcement point

The router that actually handles the traffic must translate an accepted rule into a supported forwarding or filtering action. Hardware table capacity, software support, resource limits, and the actual traffic path can all affect the result.

1.3 What does a FlowSpec rule describe?

A FlowSpec rule identifies a class of traffic using supported match components. Depending on the address family, implementation, and negotiated capabilities, these can include source or destination prefixes, IP protocol, ports, TCP flags, ICMP fields, packet length, and other defined traffic characteristics.

The rule is associated with one or more actions, such as discarding matching packets or applying a supported rate limit. Other actions and combinations may be available on particular platforms, but engineers must verify the implementation rather than assume universal support. Match specificity, rule precedence, and interactions with existing policy also require careful consideration.

Design element Engineering question Evidence to inspect
Match components Does the rule describe the unwanted traffic precisely enough? Advertised NLRI, decoded match fields, and observed packet characteristics.
Policy distribution Did the intended routers receive the rule? BGP peer state, received FlowSpec entries, and import-policy results.
Acceptance and installation Was the rule accepted and programmed for enforcement? Validation results, installed-policy tables, platform logs, and resource status.
Traffic outcome Did the rule affect the intended traffic without unacceptable side effects? Traffic rates, counters, packet observations, and service-health measurements.

1.4 FlowSpec is not the same as changing a destination route

Conventional BGP route advertisements primarily describe reachability to destination prefixes. FlowSpec distributes traffic classification and treatment rules. It can therefore target selected traffic without necessarily changing the destination prefix's best path in the routing table.

This distinction matters during incident response. A FlowSpec rule might be distributed correctly but fail to affect traffic because the rule is not installed, the match does not describe the actual packets, or the traffic does not traverse the intended enforcement point. Changing an unrelated destination route may not solve any of those problems.

Section 1 takeaway Treat FlowSpec as a complete policy lifecycle—not simply a BGP advertisement. Follow the rule from its origin through distribution and validation to forwarding installation, then verify its effect on real traffic.

Implementation note: FlowSpec support, validation behaviour, supported actions, precedence, and forwarding-resource limits vary across network operating systems and hardware. Confirm the relevant platform documentation before applying these concepts to a production network.

Network Insight · Interactive Engineering Lab 01

How Does a FlowSpec Policy Reach the Forwarding Plane?

Trace a conceptual FlowSpec rule from policy origin through BGP distribution, receiver validation and installation. Step through the evidence and see where the process can stop.
Ready to investigate
FlowSpec Control and Enforcement Path
0 / 7 stages
◈
POLICY ORIGIN
Controller / BGP speaker
Not originated
⇄
BGP DISTRIBUTION
RR / BGP peers
Waiting
▤
ENFORCEMENT EDGE
Receiver · FlowSpec
Waiting
Illustrative match: TCP · SYN traffic · destination service
Proposed action: Rate-limit matching traffic
Distribution target: One intended edge receiver
Architecture principle: FlowSpec distributes traffic-match and action information through BGP. The receiving platform must still accept and install the policy before enforcement can be confirmed.
Policy Specification
Illustrative
Match criteria
Protocol: TCP
TCP flags: SYN
Destination: protected service
Action
Rate-limit matching packets
Platform support required
Rule originConfigured policy speaker
Receiver scopeSingle edge
AcceptanceNot evaluated
InstallationNot evaluated
Receiver Evidence
Simulated state
BGP sessionEstablished
Rule receivedNo
Policy acceptedPending
Forwarding stateNot installed
Traffic outcomeNot measured
Policy Lifecycle Trace
Select Step Forward
01
Originate
The policy origin defines the FlowSpec match and intended action.
02
Encode
The speaker constructs a FlowSpec NLRI and associated path attributes.
03
Distribute
BGP advertises the policy to eligible peers and configured receivers.
04
Receive
The intended receiver processes the update and evaluates its policy controls.
05
Validate
The receiver evaluates acceptance and validation requirements.
06
Install
The platform attempts to install the accepted rule for enforcement.
07
Verify
The engineer checks installation evidence and measures the traffic outcome.
Live Engineering Readout
Evidence-led
Current Stage
Ready to begin
Step through the lifecycle to follow the rule and distinguish BGP distribution from forwarding enforcement.
Lifecycle Progress
Engineering takeaway: a healthy BGP session does not prove that a FlowSpec rule has been accepted, installed or enforced.
Training model only. The topology, lifecycle and evidence are conceptual; no live BGP session or router is controlled. FlowSpec match components, actions, validation rules, forwarding installation and route-reflector behaviour depend on platform capabilities and configuration.

Engineering Preview · 02 / Observability

Where Can You Prove What Happened?

FlowSpec troubleshooting requires evidence from multiple layers. Choose a vantage point to discover what it can prove—and what it cannot prove on its own.

BGP control plane: Peer state and received NLRI show distribution progress. They do not independently prove that a forwarding rule is installed.
Section 02 · Observe the evidence

Flow Matching, Telemetry and Enforcement Evidence

A FlowSpec policy is only useful if engineers can establish what happened after the rule was created. Effective troubleshooting requires visibility across BGP distribution, policy acceptance, forwarding installation, packet matching, and the resulting traffic behaviour.

No single counter or status proves the entire chain. A BGP session can be healthy while a particular rule is rejected. A rule can appear in a received-policy table without being installed for forwarding. An installed rule can remain ineffective if its match criteria do not describe the actual traffic or if the packets take a different path.

2.1 Observe the system at multiple points

Start by dividing the policy lifecycle into observable stages. At each stage, identify the evidence available and the question it can answer. This prevents an engineer from treating a successful control-plane event as proof of a successful data-plane outcome.

01
BGP session and route reception

Check peer state, address-family negotiation, received FlowSpec entries, and relevant import-policy results. This establishes whether the distribution path is functioning for the rule under investigation.

02
Validation and accepted policy

Determine whether the rule passed the receiver's applicable validation and policy checks. Inspect the decoded NLRI and associated actions where the platform exposes them.

03
Forwarding installation

Inspect the platform's installed FlowSpec or forwarding-policy state, including any programming errors, unsupported actions, resource exhaustion, or hardware-table constraints.

04
Traffic and service outcome

Compare traffic rates, packet or policy counters where available, interface measurements, and application health before and after enforcement. Check whether legitimate traffic is also being affected.

Evidence rule Match every operational claim to the layer that can prove it. Peer state proves session health; installed-policy state provides evidence of programming; traffic measurements help establish whether the intended operational outcome occurred.

2.2 Understand what each measurement tells you

Control-plane visibility

BGP neighbour state, address-family status, received and advertised FlowSpec entries, route attributes, and policy logs help explain how a rule moved through the routing system.

Useful for: locating distribution, import-policy, and validation problems.

Forwarding-plane visibility

Installed-policy tables, supported hardware or software counters, programming logs, and resource utilisation help establish whether the intended rule is available for packet processing.

Useful for: identifying installation failures or forwarding limitations.

Traffic telemetry

Interface utilisation, packet rates, flow records, sampled traffic, and upstream or downstream measurements help characterise the event and evaluate changes after enforcement.

Useful for: determining where traffic volume changes and whether the attack pattern persists.

Service-level evidence

Application availability, latency, error rates, synthetic tests, and customer-impact indicators help establish whether the mitigation protects the service rather than simply changing a network counter.

Useful for: confirming business impact and detecting collateral damage.

2.3 Validate the match against real traffic

A rule can be syntactically valid and successfully installed yet fail to mitigate the intended event. The match may be too narrow, too broad, or based on an incorrect assumption about the traffic. Engineers should compare the FlowSpec components with observed packet or flow characteristics rather than relying only on the policy description.

Observation Possible interpretation Next verification
Rule received, but not installed Validation, policy, capability, or forwarding-resource issue. Inspect rejection reasons, platform support, and installation logs.
Rule installed, but traffic is unchanged Match mismatch, wrong enforcement point, alternate traffic path, or ineffective measurement. Compare actual packet characteristics, routing path, policy counters, and measurements on both sides of enforcement.
Traffic volume falls, but service remains unhealthy The mitigation may be incomplete, congestion may persist elsewhere, or the service may have another fault. Correlate multiple interfaces, upstream traffic, resource utilisation, and application telemetry.
Traffic falls, but legitimate requests also fail The match may be too broad or the action may be too aggressive. Review rule scope, compare legitimate traffic patterns, and validate the effect before retaining the policy.

2.4 Compare measurements from the right vantage points

A traffic measurement is meaningful only in context. An ingress interface may show the full attack volume, while an interface beyond an effective discard point may show a substantial reduction. However, measurements taken at different sampling intervals, interfaces, or traffic directions can produce misleading comparisons.

Establish a baseline, record when the policy was installed, and compare equivalent measurement windows. Where possible, inspect both sides of the enforcement point and monitor unaffected traffic or service probes as a control. This helps distinguish a genuine mitigation effect from an upstream traffic change, measurement gap, or unrelated outage.

Practical measurement sequence Record the initial traffic pattern, identify the intended enforcement point, confirm the rule's installed state, observe traffic after the change, and validate service health. If these signals disagree, investigate the discrepancy before declaring success.

2.5 Build an evidence chain, not a collection of screenshots

Useful incident evidence should be time-correlated. Capture the policy identifier or match definition, the relevant BGP state, acceptance or rejection information, installation status, traffic measurements, and service observations with timestamps. This lets another engineer reconstruct what happened and distinguish cause from coincidence.

Record the expected result before changing the policy. For example, a mitigation may be expected to reduce a particular traffic class beyond an enforcement point while keeping legitimate application probes healthy. That expectation gives the investigation a testable outcome instead of an ambiguous target such as “traffic looks better.”

Section 2 takeaway Effective FlowSpec observability connects control-plane state, forwarding installation, traffic behaviour, and service health. A rule is not proven effective until the available evidence supports the intended outcome and checks for unwanted side effects.

Telemetry availability and command output vary by platform. Counters may be absent, aggregated, sampled, or updated asynchronously. Treat each measurement according to its scope and limitations, and consult the relevant network operating system documentation.

Engineering Evidence · Lab 02 · Observe

BGP FlowSpec Visibility & Telemetry Lab

Compare what an engineer can observe at the policy origin, route reflector and enforcement edge. A healthy BGP session does not by itself prove that a policy was accepted, installed or effective.
SIMULATION READY
FlowSpec visibility mapConceptual topology
⌘
Policy Origin Rule defined and advertisedOrigin evidence
⇄
Route Reflector Distribution, if deployedDistribution evidence
◈
Enforcement Edge Validation and forwarding installSelected
BGP sessionEstablishedPeer/session evidence
Policy stateInstalledLocal enforcement evidence
Traffic rate2.1 GbpsIllustrative telemetry
Evidence matrixSignal versus state
Evidence sourceWhat it provesObserved result
Selected vantage pointEdge router

Inspect local enforcement

Confirm that the rule was received, accepted, installed and matched by traffic counters.

Ready to observe

Choose a scenario and run an observation to inspect the evidence.

Ready — select a vantage point and scenario.
Observation traceSimulated evidence
READYWaiting for observationIDLE
Engineering takeaway: Correlate BGP session state, received FlowSpec NLRI, local validation, forwarding installation, rule counters and traffic measurements. Each provides a different piece of evidence.
Training simulation only. Commands, telemetry, validation behaviour, counters and supported actions vary by vendor, software release, hardware and configuration. A route reflector is optional and represents one possible distribution design.

Engineering Preview · 03 / Investigation

A Policy Failed. Where Do You Start?

When unwanted traffic continues, avoid jumping straight to a configuration change. Select the first evidence category you would investigate.

Start with the session and received rule. Establish whether the intended receiver actually received the update before investigating later stages.
Section 03 · Investigate the failure

BGP FlowSpec Incident Investigation

When a FlowSpec mitigation fails, the fastest route to a reliable fix is to isolate the failure stage before changing configuration. A healthy BGP session, a received rule, and continuing attack traffic are important clues—but they do not, on their own, identify the root cause.

Consider an incident in which a network is experiencing a high-volume traffic surge. The FlowSpec BGP session is Established and the rule appears to have been received, yet the traffic rate remains high. The operational question is not simply whether FlowSpec is enabled; it is where the expected policy lifecycle stopped producing the intended result.

3.1 Start with impact, scope, and a timeline

Before altering the policy, establish the customer or service impact, the affected destinations and traffic classes, and the time the incident began. Compare the event timeline with policy changes, BGP updates, device alarms, interface measurements, and service-health signals.

Define the incident

Record the affected service, traffic direction, observed volume, onset time, and expected mitigation outcome. Establish whether the impact is confined to one path or affects multiple locations.

Preserve the baseline

Capture relevant routing and policy state, traffic measurements, logs, and service indicators before making changes. This provides a comparison point and helps prevent evidence from being lost during remediation.

Incident discipline Separate observed facts from hypotheses. “The BGP session is Established” is an observation. “The mitigation should therefore be working” is an assumption that still needs evidence.

3.2 Follow a fault-isolation sequence

01
Confirm distribution

Verify that the intended FlowSpec rule was advertised and received by the relevant peer. Check the correct address family, policy scope, and actual rule contents—not just the neighbour state.

02
Check acceptance and validation

Determine whether the receiving router accepted the rule under its configured import and validation behaviour. Inspect rejection reasons, route-policy decisions, and any required consistency checks.

03
Verify installation

Check whether the rule was programmed for forwarding. Investigate unsupported components or actions, resource constraints, installation errors, and differences between the accepted control-plane entry and the installed state.

04
Test the match and traffic path

Compare the rule's source, destination, protocol, ports, and other selected fields with observed traffic. Verify that the packets traverse the router where the rule is installed and that the action applies to the intended direction.

05
Measure the actual outcome

Compare equivalent pre- and post-mitigation measurements. Confirm whether the targeted traffic changes, whether congestion remains elsewhere, and whether legitimate service traffic continues to work.

3.3 Distinguish the main failure classes

Evidence observed Potential failure class Investigation priority
BGP is Established, but the expected rule is absent on the receiving router. Distribution, address-family, advertisement, or policy-scope problem. Check advertised and received entries, negotiated capabilities, and import policy.
The rule is received but rejected or unavailable for use. Validation, import-policy, or implementation restriction. Inspect the rule contents, rejection reason, validation requirements, and platform behaviour.
The rule is accepted but not installed for forwarding. Forwarding programming, unsupported feature, or resource problem. Inspect installation state, platform logs, supported actions, and resource utilisation.
The rule is installed but the targeted traffic remains unchanged. Incorrect match, unexpected traffic path, wrong enforcement point, or misleading telemetry. Compare actual packet characteristics, traffic direction, route path, and counters at the enforcement point.
Targeted traffic falls but service health remains poor. Incomplete mitigation, congestion elsewhere, or an independent service fault. Correlate upstream and downstream traffic, device health, and application measurements.

3.4 Use evidence to test competing hypotheses

A disciplined investigation avoids committing to the first plausible explanation. If a rule appears in the received FlowSpec table but is missing from the installed-policy state, prioritise acceptance and forwarding-programming evidence. If it is installed and no targeted traffic changes, investigate match accuracy and the actual traffic path before repeatedly resetting the BGP session.

Each diagnostic action should distinguish between hypotheses. Inspecting an installed-policy table may separate an installation failure from a traffic-matching problem. Comparing measurements immediately before and after the enforcement point may help determine whether packets are being treated there. Reviewing application probes may show whether the network mitigation actually restores service.

Prefer a discriminating test

Choose the next check because its result can rule a hypothesis in or out. Avoid making several unrelated configuration changes at once, as they make cause and effect harder to establish.

Respect the production risk

Use read-only checks first. Any change to a filtering policy should follow the operational change process, account for legitimate traffic, and include a rollback path appropriate to the incident.

3.5 Choose remediation based on the confirmed fault

Once the failure stage is supported by evidence, make the smallest justified correction. A distribution problem calls for a different response from an unsupported forwarding action or a rule that does not match the attack traffic. Repeatedly re-advertising the same rule will not fix every one of these conditions.

After the change, repeat the relevant checks. Confirm the updated rule is received and accepted, verify installation at the intended enforcement point, and measure both mitigation effectiveness and legitimate-service impact. If the expected result is not observed, return to the evidence chain rather than assuming the change succeeded.

Section 3 takeaway Isolate the failure before changing the network: distribution, validation, installation, matching, traffic path, and service outcome are separate diagnostic stages. The root cause should explain the evidence, and the remediation should produce a measurable, repeatable improvement.

FlowSpec validation and installation details differ by platform and configuration. Use device-specific operational commands and logs to confirm each stage; the sequence above is a vendor-neutral investigation framework, not a claim that every implementation exposes identical state.

Engineering Evidence · Lab 03

BGP FlowSpec Incident Investigation

Trace a traffic-control incident from policy origin to enforcement. Refresh the evidence, inspect the path, and identify the most likely failure stage. This is a simulated engineering exercise; real commands and platform behaviour vary by vendor.

BGP session—
FlowSpec at edge—
Forwarding state—
Observed traffic—
Waiting for evidenceChoose a scenario and press Refresh Evidence.

Choose your diagnosis

Diagnosis not submittedRefresh the evidence first, then select a likely cause.

Live policy path & enforcement

Waiting for evidence
FlowSpec OriginPolicy source
Route Reflector / PeerPropagation path
Enforcement EdgeAwaiting rule
Traffic OutcomeAwaiting counters
Refresh the incident evidence to illuminate the simulated path and show the likely failure point.

Correlated incident timeline

No observations collected
  • Choose an incident and refresh evidence.
Engineering takeaway
A healthy BGP session does not prove that a FlowSpec rule has been accepted, installed in the forwarding plane, or matched the traffic you intend to control.

Engineering Preview · 04 / Correlation

Did the Mitigation Actually Restore the Service?

Successful operations correlate the policy state with network measurements and user-facing service health. Select a verification signal to see how it contributes to the recovery decision.

Policy state: Verify the rule is accepted and installed at the intended enforcement points. This confirms policy progress, not full service recovery.
Section 04 · Correlate and operate

FlowSpec Policy Correlation, Remediation and Recovery Verification

An effective FlowSpec response requires more than a rule that appears in the routing system. Engineers must correlate control-plane events, forwarding state, traffic measurements, and service health to establish what changed, why it changed, and whether the incident is actually resolved.

Each telemetry source describes a different part of the system. BGP logs show distribution activity; installed-policy state helps establish forwarding readiness; traffic measurements describe observed network behaviour; and service probes reveal whether users can access the application. Considered together, these signals provide a stronger operational picture than any one indicator alone.

4.1 Correlate the evidence across the network

Routing and policy events

Correlate advertisements, withdrawals, neighbour events, import-policy decisions, and validation results. Establish which rule version was present at each relevant point in the incident timeline.

Forwarding and device health

Compare installed-policy state with programming errors, forwarding-resource utilisation, interface counters, and relevant device alarms. Look for evidence that the intended action became operational.

Traffic-path measurements

Compare observations at appropriate ingress and egress points. Account for routing changes, alternate paths, measurement intervals, sampling, and traffic that may bypass the enforcement router.

Application and service health

Correlate latency, availability, request errors, synthetic tests, and customer-impact signals with the network changes. Reduced traffic volume is not sufficient evidence that the service has recovered.

Correlation principle Align timestamps, identify the same policy or incident across data sources, and compare equivalent measurement windows. A change that occurred after a mitigation is evidence to investigate—not automatic proof that the mitigation caused it.

4.2 Establish a measurable success condition

Before changing a policy, define what successful mitigation means for this incident. The expected result should describe the traffic that must change, the observation point where the change should be visible, and the service condition that must remain acceptable.

Validation dimension Example success condition Evidence to collect
Policy state The intended rule is accepted and installed on the expected enforcement router. Accepted and installed policy state, validation output, and device logs.
Target traffic The unwanted traffic class is reduced or treated as intended beyond the enforcement point. Comparable traffic measurements, relevant counters, and flow observations.
Legitimate traffic Permitted traffic continues to receive the intended service. Application probes, legitimate request tests, and appropriate traffic counters.
Infrastructure health Mitigation does not introduce unacceptable device load or resource exhaustion. Forwarding-resource state, CPU or memory where relevant, and interface utilisation.
Recovery The affected service meets its agreed operational health criteria for a suitable observation period. Availability, latency, error rates, and incident-specific monitoring.

4.3 Apply a controlled remediation

Remediation should address the failure confirmed by the evidence. A rule that does not match the observed traffic needs a different correction from a rule rejected by policy or one that cannot be installed by the forwarding platform. Avoid broadening a match or applying a more aggressive action simply because the original policy did not deliver the expected result.

01
State the diagnosed fault

Document the evidence that identifies the failed stage and distinguish it from other plausible explanations.

02
Select the narrowest justified change

Correct the specific distribution, validation, installation, matching, or path issue. Consider the potential effect on legitimate traffic and other policies.

03
Plan rollback and ownership

Use the applicable change-control process, identify who is responsible for validation, and define how to withdraw or reverse the change if the outcome is unsafe.

04
Recheck the complete policy chain

Verify the updated rule, its acceptance and installation, the traffic effect, and the health of the protected service. Do not infer success from a successful configuration change alone.

4.4 Verify recovery—and know when to remove the mitigation

Once the immediate threat is controlled, continue monitoring long enough to establish that the result is stable. Check for residual attack traffic, congestion elsewhere in the network, unexpected effects on permitted flows, and any remaining application symptoms. Where the service remains unhealthy, investigate independent or downstream causes rather than assuming the FlowSpec rule is still the only issue.

Mitigation policies also need a controlled lifecycle. When the triggering condition has passed, determine whether the rule should be withdrawn, retained temporarily, or replaced by a more appropriate policy. Confirm that withdrawal or modification propagates as expected and that the network returns to the intended normal state. Do not remove an active protection solely because one traffic counter has fallen.

4.5 Operational recovery checklist

  • The incident scope and expected mitigation outcome are documented.
  • The intended FlowSpec rule is received, accepted, and installed at the correct enforcement point.
  • Measurements show the expected change in the targeted traffic class.
  • Legitimate traffic and application health remain within acceptable limits.
  • Device health and forwarding resources show no unacceptable side effects.
  • The result remains stable for an appropriate observation period.
  • Policy withdrawal or continued operation is planned, documented, and verified.
  • The timeline, evidence, remediation, and lessons learned are recorded for future incidents.
Section 4 takeaway Recovery is proven by correlated evidence: the policy is in the intended state, the targeted traffic behaves as expected, legitimate services remain healthy, and the result is stable. Close the incident only when the agreed operational criteria are met.

Success thresholds, observation windows, rollback procedures, and telemetry sources should be defined for the specific service and platform. This framework supports engineering judgement; it does not replace production change control or vendor-specific operational guidance.

Engineering Evidence · Lab 04

BGP FlowSpec Correlation & Operational Verification

A policy is not proven effective just because BGP reports an established session or a rule appears installed. Correlate policy state, forwarding counters and traffic telemetry, then verify the outcome after a simulated operational change.

1 · Configure the verification test

Verification not runSelect a scenario and run the test to correlate simulated evidence.

2 · Correlated live readout

BGP sessionAwaiting test
FlowSpec ruleAwaiting test
Forwarding counterAwaiting test
Traffic rateAwaiting test
Cross-domain correlationRun a test to see whether control-plane, forwarding-plane and traffic evidence agree.

3 · Dependency verification chain

Waiting for verification
1
BGP control planeSession and received policy
Pending
2
Policy acceptanceRule accepted by the edge
Pending
3
Forwarding enforcementInstallation and packet counters
Pending
4
Traffic outcomeObserved rate and expected behaviour
Pending
Operational principle
Verify the result at the traffic and forwarding layers. A successful control-plane update alone is not proof of mitigation.

4 · Event and validation timeline

No test executed
  • Choose a scenario, then run verification.
Next operational actionCollect correlated evidence before declaring the incident resolved.

Engineering Preview · 05 / Production Design

Is This FlowSpec Policy Safe to Deploy?

Before a rule reaches production, assess more than its syntax. Explore three operational design checks that help limit unintended impact.

Policy scope: Confirm the intended destinations, receivers and traffic match. Prefer a narrowly justified rule over a broad match that could affect legitimate traffic.
Section 05 · Design for production

BGP FlowSpec Deployment, Security and Operational Design

FlowSpec can help operators respond to specific traffic threats, but its effectiveness depends on more than protocol support. A production deployment needs controlled policy origination, deliberate distribution scope, compatible enforcement platforms, and safeguards against rules that are incorrect, overly broad, or operationally expensive.

Because a distributed rule can influence packet treatment across multiple routers, a mistake at the policy source may have a much wider effect than a local filtering change. The engineering objective is to make mitigation fast enough to respond to an incident while keeping its scope, authority, and consequences under control.

5.1 Define the policy distribution boundary

Decide which routers should receive a FlowSpec rule and where enforcement is intended to occur. A rule distributed to every eligible router may provide broad coverage, but it can also increase policy exposure and the number of forwarding devices affected by a mistake.

Edge enforcement

Applying policy near a relevant network edge may prevent unwanted traffic from consuming resources further inside the network. Confirm that the edge sees the traffic and supports the required match and action.

Regional enforcement

Distributing policy across a defined region can provide broader coverage, but requires consistent platform capability, appropriate routing policy, and visibility into each enforcement point.

Multi-router deployment

Wider distribution may help when traffic uses multiple paths. Validate the intended recipients, avoid unnecessary propagation, and check that enforcement remains consistent where required.

Controlled policy origin

Restrict who or what can originate FlowSpec rules. Authenticate and authorise control-plane peers appropriately, and use explicit policy controls to limit which rules and actions are accepted.

Design principle Distribute a rule only to the systems that need it and can enforce it safely. The correct scope depends on the traffic path, service requirements, platform capabilities, and the network's policy architecture.

5.2 Protect the network from unsafe policy

FlowSpec introduces a mechanism for distributing traffic-treatment policy through the routing system. That makes policy governance and validation important security controls. A rule that matches too much traffic, uses an inappropriate action, or reaches unintended routers can create a service outage even when the BGP session itself is operating normally.

Risk Potential consequence Operational safeguard
Overly broad match Legitimate traffic is discarded, rate-limited, or otherwise affected. Validate match fields against observed traffic and test expected legitimate-flow behaviour.
Unauthorised or erroneous policy origin Unintended traffic treatment is distributed to participating routers. Restrict policy origination, peer access, and permitted rule scope through explicit controls.
Inconsistent platform support Some routers reject a rule or cannot implement its intended action. Maintain a capability matrix and verify acceptance and installation on each relevant platform.
Excessive rule volume Control-plane processing or forwarding resources may become constrained. Set appropriate limits, monitor resource utilisation, and test expected policy scale.
Missing withdrawal or expiry process Temporary mitigations persist after the incident or conflict with later policy. Assign policy ownership, track active mitigations, and verify removal or replacement when appropriate.

5.3 Understand forwarding capacity and scale

A router may support FlowSpec in principle yet have limits on rule count, match combinations, supported actions, or available forwarding resources. Hardware acceleration and software implementation details differ, so a design that works in a small lab may behave differently at production scale.

Engineers should establish expected peak rule volume, update frequency, convergence behaviour, and the effect of adding or withdrawing policies. They should also understand how the platform handles overlapping rules and action precedence. Do not assume that all implementations resolve every combination identically.

Capacity planning

Measure the policy scale expected during normal operation and a major incident. Monitor forwarding resources and understand the platform's documented limits before relying on large numbers of dynamic rules.

Failure behaviour

Determine what happens if a rule cannot be installed, a resource limit is reached, or a peer becomes unavailable. Make sure monitoring distinguishes partial deployment from complete enforcement.

5.4 Integrate FlowSpec into change and incident management

Automated mitigation can shorten response time, but speed should not eliminate accountability. Define who can request a rule, who approves high-impact actions, which conditions permit automation, and how operators can suspend or reverse a policy when its effects are unsafe.

Use staged validation where the environment permits it. A policy can first be checked against the intended traffic definition and deployment target, then applied under the appropriate operational controls. After deployment, collect evidence of acceptance, installation, traffic effect, and service health. Record the rule's purpose and owner so another engineer can understand why it exists.

5.5 Production-readiness checklist

  • The FlowSpec-capable routers and their supported actions are documented.
  • Policy origination and distribution are restricted to authorised systems.
  • Match scope and expected legitimate traffic have been reviewed.
  • Validation, installation, and forwarding-resource monitoring are available.
  • Expected rule volume and update behaviour have been assessed.
  • Incident ownership, approval boundaries, and rollback procedures are defined.
  • Policy withdrawal, expiry, and post-incident review are part of the operational process.
Section 5 takeaway Reliable FlowSpec operations combine protocol knowledge with policy governance, platform-capability checks, capacity planning, and controlled change management. Fast mitigation is valuable only when the policy can be enforced safely and its effects can be verified.

Exact validation rules, action support, precedence, resource limits, and failure behaviour depend on the network operating system, hardware, configuration, and FlowSpec specification in use. Confirm these details against the relevant platform documentation and test them before production deployment.

Engineering Preview · 06 / Operational Runbook

Can You Prove the Mitigation Worked?

Use this final checkpoint to connect the whole workflow. Select a phase and identify the evidence required before declaring the incident resolved.

Detect: Establish the affected traffic pattern and service impact using a timestamped baseline. This becomes the reference for later verification.

Engineering Runbook · Detection to Verification

BGP FlowSpec Engineering Runbook: From Detection to Verified Mitigation

A FlowSpec policy is not successful simply because a BGP session is established or a rule appears in a routing table. The engineering objective is to identify a specific traffic problem, distribute an appropriately scoped policy, confirm that the intended forwarding systems enforce it, and prove that the service remains healthy.

This final section turns the architecture, telemetry, investigation methods and deployment considerations from the earlier sections into a repeatable operational workflow. It is a conceptual runbook: exact commands, validation rules and forwarding evidence depend on the network platform and software release.

1. Follow the operational sequence

01 Detect and scope Establish which service, destination, protocol and traffic pattern are affected. Record the observed impact and the measurement source.
02 Define the match Translate the evidence into the narrowest practical FlowSpec match. Confirm that the selected fields accurately describe the unwanted traffic.
03 Validate the policy Review the action, policy origin, import controls, validation requirements and intended distribution scope before deployment.
04 Distribute and inspect Confirm that the relevant BGP peers receive the rule and that policy controls allow it to be accepted.
05 Verify enforcement Inspect the receiving platform's FlowSpec state and available forwarding evidence. Receipt of a rule does not prove installation.
06 Measure the outcome Compare traffic, service health and collateral impact against the baseline. Adjust or withdraw the policy if the evidence does not support success.

2. Define evidence-based exit criteria

Every phase should produce evidence that justifies moving to the next one. A useful incident record distinguishes control-plane progress from forwarding-plane behaviour and the actual service outcome.

Phase Evidence to collect Exit criterion
Detection Traffic rates, service alerts, destination and protocol details The affected traffic pattern is sufficiently understood to formulate a match.
Policy definition Match fields, action, scope and policy owner The proposed rule targets the intended traffic without an unjustifiably broad match.
BGP distribution Peer state, received FlowSpec NLRI and policy acceptance status The intended receivers have accepted the rule under their configured controls.
Installation Platform policy state, validation results and available forwarding-resource evidence The enforcement point confirms installation or exposes a specific reason for failure.
Service verification Traffic measurements, application probes, interface counters and relevant alerts The unwanted traffic is controlled and legitimate service behaviour remains acceptable.
Closure Change record, final policy state, outcome measurements and rollback status The mitigation is documented and the policy's continued need is understood.
Engineering rule: “BGP Established” proves a session state. “Rule received” proves distribution to a point. Neither alone proves that the intended packets are being handled correctly.

3. Worked scenario: a TCP SYN surge

Imagine that monitoring identifies an unusual rise in TCP SYN traffic toward a service. The engineering team considers a FlowSpec policy intended to control the matching traffic while preserving legitimate access.

Before deployment

Confirm the affected destination and protocol, examine traffic characteristics, review the proposed match and action, and identify which routers should enforce the rule. Check platform support, policy validation requirements and the procedure for withdrawing the rule.

During deployment

Observe the FlowSpec update at the source and intended receivers. Check acceptance and installation separately. If the rule is rejected or cannot be installed, investigate that failure rather than assuming the traffic should already have changed.

After deployment

Compare the relevant traffic measurements with the original baseline. Check application reachability, legitimate connection behaviour and relevant error rates. If traffic falls but the service remains unhealthy, continue investigating other possible causes; a reduction in one traffic metric does not prove complete recovery.

Evidence that supports a successful mitigation

The intended rule is accepted and installed at the correct enforcement points; the targeted traffic changes in the expected direction; legitimate service probes remain healthy; and no unexpected collateral impact appears in the monitoring window.

If one of these conditions fails, record the missing evidence and return to the relevant stage of the investigation.

4. Plan for withdrawal and recovery

FlowSpec is an operational control, not a reason to leave emergency policy in place indefinitely. Every temporary mitigation should have an owner, a review point and a defined withdrawal procedure.

✓ Confirm that the incident or traffic condition has changed.
✓ Review whether the policy is still necessary and correctly scoped.
✓ Withdraw or modify the policy through the approved control path.
✓ Verify the expected policy state at relevant receivers.
✓ Monitor traffic and application behaviour after withdrawal.
✓ Record the final outcome, residual risks and follow-up actions.

Withdrawal should be verified rather than assumed. Check that the intended rule is no longer active where expected and that removing it has not exposed a continuing incident or caused a new service problem. If the threat persists, follow the approved response process before deciding whether to reapply or replace the mitigation.

5. Build an auditable incident record

A strong FlowSpec incident record allows another engineer to reconstruct the decision without relying on memory. Capture the detection time, affected service, evidence source, policy definition, distribution scope, validation result, installation state, measured outcome, approval and withdrawal or review decision.

Record the distinction between facts and hypotheses. For example, “the receiver reports installation failure” is observed evidence; “the forwarding table is full” is a hypothesis until platform telemetry confirms it.

Final engineering takeaway

Detect precisely. Match narrowly. Validate before distribution. Prove installation. Measure the real traffic and service outcome. Verify recovery and withdrawal.

These steps turn BGP FlowSpec from a policy-distribution feature into a controlled engineering capability. The strongest operational result is not merely a rule that exists in the network, but a mitigation whose behaviour, impact and removal can all be demonstrated with evidence.

BGP FlowSpec Control Lab

How Does BGP FlowSpec Turn a Traffic Pattern Into a Network Policy?

Build a flow match, distribute it through BGP, and see how the receiving edge can enforce an action without changing the destination route itself.
CONTROL PLANE → POLICY → ENFORCEMENT
FlowSpec Policy Distribution Ready
IN
Traffic Source Suspicious flow
FlowSpec Controller Constructs a flow specification and advertises it using BGP
Flow Match
dst-prefix + TCP + dst-port
PE
FlowSpec Client Receives BGP NLRI
FX
Rate Limit Traffic enforcement
Match Model L3 + L4
Distribution BGP FlowSpec
Action Rate Limit
Enforcement Point Network Edge

Policy Result

Traffic Class TCP SYN surge
Match Criteria Destination + Protocol + Port
Control Plane MP-BGP FlowSpec
Enforcement Rate Limit
Routing Impact Destination route unchanged
FlowSpec Event Trace
12:00:00 FlowSpec policy engine ready
12:00:01 Waiting for policy deployment...
Engineering insight: Traditional BGP answers “where is this destination prefix?” FlowSpec adds a distributed policy mechanism that can identify traffic using multiple flow attributes and associate an action with the matching traffic.
Conceptual FlowSpec model. Supported match fields, actions, validation behaviour, policy propagation and hardware enforcement vary by platform and implementation. FlowSpec policies should be carefully scoped and validated before deployment.
BGP FlowSpec Policy Experiment

Which FlowSpec Policy Fits the Traffic?

Experiment with traffic classification, match fields and enforcement actions. Then test whether your policy is appropriately targeted for the scenario.
MATCH → ACTION → VALIDATE

TCP SYN flood

High Volume

A large number of TCP connection attempts are arriving at an Internet-facing service. The policy should identify the unwanted flow without changing the destination route.

Traffic Internet sources
→
FlowSpec Policy Match + action
→
Router Enforce policy
→
Service Protected destination
Policy Quality
—
Traffic Specificity
Action Suitability
Deployment Reach
Ready: Select match fields and an action, then run the policy test.
Policy Validation Trace
12:00:00 FlowSpec experiment ready
12:00:01 Waiting for policy test...
Illustrative FlowSpec experiment. Real implementations differ in supported match components, validation rules, actions, hardware resources and policy scale. Always validate policies before production deployment.
BGP FlowSpec Incident Investigation

Why Didn't the FlowSpec Policy Work?

The network is still receiving unwanted traffic even though the FlowSpec session is established. Examine the evidence, identify the failed control, and choose the most likely root cause.
INCIDENT MODE
Incident Evidence
LIVE SNAPSHOT
FlowSpec BGP Session Established
Policy Received Yes
Traffic at Edge 9.4 Gbps
Origin Bandwidth 87%
Policy Installed No
Destination Route Unchanged
Current Traffic Path
TRACE
Internet Unwanted traffic
→
Edge Router FlowSpec client
→
Policy Not installed
→
Origin Still receiving traffic
Choose Your Diagnosis
1 OF 4
Investigation Score
—
Investigator briefing: The FlowSpec BGP session is healthy and the rule has been received. Focus on the point between policy reception and actual enforcement.
Engineering Trace
CONTROL → DATA
Incident Console
14:32:01 FlowSpec NLRI received
14:32:01 BGP session state = Established
14:32:02 Policy matched expected traffic class
14:32:02 Forwarding installation = Failed
14:32:03 Origin continues receiving traffic
14:32:03 Investigation required
What Should You Check?
METHOD
Separate the problem into three stages:

1. Distribution — Did the FlowSpec NLRI reach the client?
2. Acceptance — Did the client accept the policy?
3. Enforcement — Was the policy actually installed?

A healthy BGP session does not automatically prove that traffic filtering is active.
Defensive training simulation. The scenario is intentionally simplified: real FlowSpec validation, policy installation, forwarding resources, route-target handling and supported actions vary by platform and design.
☕
Support Network Insight
Help support the development of interactive networking labs, BGP simulations, and educational content.
Support the Project
software-2021-09-02-15-38-08-utc

Transport SDN

Transport SDN

Transport Software-Defined Networking (SDN) revolutionizes how networks are managed and operated. By decoupling the control and data planes, Transport SDN enables network operators to control and optimize their networks programmatically, leading to enhanced efficiency, agility, and scalability. In this blog post, we will explore the Transport SDN concept and its key benefits and applications.<br
Transport SDN is an architecture that brings the principles of SDN to the transport layer of the network. Traditionally, transport networks relied on static configurations, making them inflexible and difficult to adapt to changing traffic patterns and demands. Transport SDN introduces a centralized control plane that dynamically manages and configures the transport network elements, such as routers, switches, and optical devices.

Transport SDN is a paradigm that combines the principles of Software Defined Networking (SDN) with the unique requirements of the transportation sector. At its core, Transport SDN aims to provide a centralized control and management framework for the diverse components of a transportation network. By separating the control plane from the data plane, Transport SDN enables network operators to have a holistic view of the entire infrastructure, allowing for improved efficiency and flexibility.

In this section, we will explore the key components that make up a Transport SDN architecture. These include the Transport SDN controller, network orchestrator, and the underlying transport network elements. The controller acts as the brain of the system, orchestrating the traffic flows and dynamically adjusting the network parameters. The network orchestrator ensures the seamless integration of various network services and applications. Lastly, the transport network elements, such as routers and switches, form the foundation of the physical infrastructure.

Transport SDN has the potential to transform various aspects of transportation, ranging from intelligent traffic management to efficient logistics. One notable application is the optimization of traffic flows. By leveraging real-time data and analytics, Transport SDN can dynamically reroute traffic based on congestion levels, minimizing delays and maximizing resource utilization. Additionally, Transport SDN enables the creation of virtual private networks, enhancing security and privacy for sensitive transportation data.

While Transport SDN holds immense promise, it is not without its challenges. One of the key hurdles is the integration of legacy systems with the new SDN infrastructure. Many transportation networks still rely on traditional, siloed approaches, making the transition to Transport SDN a complex task. Furthermore, ensuring the security and reliability of the network is of paramount importance. As the technology evolves, addressing these challenges will pave the way for a more connected and efficient transportation ecosystem.

Transport SDN represents a paradigm shift in the transportation industry. By leveraging the power of software-defined networking, it opens up a world of possibilities for creating smarter, more efficient transportation networks. From optimizing traffic flows to enhancing security, Transport SDN has the potential to create a future where transportation is seamless and sustainable. Embracing this technology will undoubtedly shape the way we move and revolutionize the world of transportation.

</br

Highlights:Transport SDN

Transport SDN • Control Model

How Does Transport SDN Optimise a WAN Path?

Transport SDN adds global visibility and traffic-engineering intelligence to a transport network. The controller can optimise paths, while distributed routing continues to provide resilient network convergence.

Input
Traffic / SLA Demand
Applications generate traffic with latency, bandwidth and service-level requirements.
→
Visibility
Telemetry
Utilisation, topology and path-state information reveal the current network condition.
→
Intelligence
SDN Controller / PCE
Global topology and policy information can be used to calculate a better transport path.
→
Forwarding
Transport Network
Distributed forwarding elements carry traffic across the selected path.
→
Outcome
Destination
Traffic reaches its destination while the selected policy and SLA objective are maintained.
The Hybrid Control Principle
Distributed Routing IGP mechanisms continue to provide local reachability and resilient convergence.
Global Traffic Engineering The controller can compare available paths using topology, utilisation and policy information.
Transport Programming Computed decisions can be translated into transport path or policy changes.
Network Visibility
Global
Path Decision
Optimised
SLA Risk
Low
Control Model
Hybrid
Decision Trace
Traffic demand received: SLA-aware WAN flow Telemetry collected: topology + utilisation + path state Controller evaluates available transport paths Hybrid control model selected
Engineering insight: Transport SDN does not necessarily replace distributed routing. A common architecture keeps IGP convergence in the network while adding controller-based visibility and global traffic engineering above it.

Understanding Transport SDN

Transport SDN is a network architecture that brings software-defined principles to the transport layer. Transport SDN enables centralized network management, programmability, and dynamic resource allocation by decoupling the control plane from the data plane. This empowers network operators to adapt to changing demands and optimize network performance swiftly.

Understanding its key components is essential to comprehend the inner workings of Transport SDN. These include the Transport SDN Controller, which acts as the brain of the network, orchestrating and managing network resources. Additionally, the Transport SDN Switches play a crucial role in forwarding traffic based on the instructions received from the controller. Lastly, the OpenFlow protocol is the communication interface between the controller and the switches, facilitating seamless data flow.

Real-World Applications of Transport SDN

1 = Transport SDN has found wide-ranging applications across various industries. In the telecommunications sector, it enables service providers to efficiently provision bandwidth, optimize traffic routing, and enhance network resilience.

2 = Within data centers, Transport SDN simplifies network management, allowing for dynamic resource allocation and improved scalability. Moreover, Transport SDN facilitates intelligent traffic management in smart transportation and enables seamless vehicle connectivity.

3 = While Transport SDN offers immense potential, it also has its fair share of challenges. Organizations must address some hurdles to ensure interoperability between different vendor solutions, security concerns, and the need for skilled personnel.

4 = Looking ahead, the future of Transport SDN holds promise. Advancements in technologies like artificial intelligence and machine learning are anticipated to enhance the capabilities of Transport SDN further, unlocking new possibilities for intelligent network management.

Critical Benefits of Transport SDN:

1. Improved Network Efficiency: Transport SDN allows for intelligent traffic engineering, enabling network operators to optimize network resources and minimize congestion. Transport SDN maximizes network efficiency and improves overall performance by dynamically adjusting routes and bandwidth allocation based on real-time traffic conditions.

2. Enhanced Network Agility: With Transport SDN, network operators can rapidly deploy new services and applications. Leveraging programmable interfaces and APIs can automate network provisioning, eliminating manual configurations and reducing deployment times from days to minutes. This level of agility enables organizations to respond quickly to changing business needs and market demands.

3. Increased Network Scalability: Transport SDN provides a scalable and flexible solution for network growth. Network operators can scale their networks independently by separating the control and data planes and adding or removing network elements. This scalability ensures that the network can keep pace with the ever-increasing demands for bandwidth without compromising performance or reliability.

SDN data plane

Forwarding network elements (mainly switches) are distributed around the data plane and are responsible for forwarding packets. An open, vendor-agnostic southbound interface is required for software-based control of the data plane in SDN.

OpenFlow is a well-known candidate protocol for the southbound interface (McKeown et al. 2008; Costa et al. 2021). Each follows the basic principle of splitting the control and forwarding plane into network elements, and both standardize communication between the two planes. However, the network architecture design of these two solutions differs in many ways.

What is OpenFlow

SDN control plane

The control plane, an essential part of SDN architecture, consists of a centralized software controller that handles communications between network applications and devices. As a result, SDN controllers translate the requirements of the application layer down to the underlying data plane elements and provide relevant information to the SDN applications.

As the SDN control layer supports the network control logic and provides the application layer with an abstracted view of the global network, the network operating system (NOS) is commonly called the network operating system (NOS). In addition to providing enough information to specify policies, all implementation details are hidden from view.

The control plane is typically logically centralized but is physically distributed for scalability and reliability reasons, as discussed in sections 1.3 and 1.4. The network information exchange between distributed SDN controllers is enabled through east-westbound application programming interfaces (APIs) (Lin et al. 2015; Almadani et al. 2021).

Despite numerous attempts to standardize SDN protocols, there has been no standard for the east-west API, which remains proprietary for each controller vendor. It is becoming increasingly advisable to standardize that communication interface to provide greater interoperability between different controller technologies in different autonomous SDN networks, even though most east-westbound communications occur only at the data store level and don’t require additional protocol specifics.

However, API east-westbound standards require advanced data distribution mechanisms and other special considerations.

Applications of Transport SDN:

1. Data Center Interconnect: Transport SDN enables seamless connectivity between data centers, allowing for efficient data replication, backup, and disaster recovery. Organizations can optimize resource utilization and ensure reliable and secure data transfer by dynamically provisioning and managing connections between data centers.

2. 5G Networks: Transport SDN plays a crucial role in deploying 5G networks. With the massive increase in traffic volume and diverse service requirements, Transport SDN enables network slicing, network automation, and dynamic resource allocation, ensuring efficient and high-performance delivery of 5G services.

3. Multi-domain Networks: Transport SDN facilitates the management and orchestration of complex multi-domain networks. A unified control plane enables seamless end-to-end service provisioning across different network domains, such as optical, IP, and microwave. This capability simplifies network operations and improves service delivery across diverse network environments.

SDN in the application plane

SDN applications are control programs that implement network control logic and strategies. In this higher-level plane, a northbound API communicates with the control plane. SDN controllers translate the network requirements of SDN applications into southbound commands and forwarding rules that dictate the behavior of data plane devices. In addition to existing controller platforms, SDN applications include routing, traffic engineering, firewalls, and load balancing.

In the context of SDN, applications benefit from the decoupling of the application logic from the network hardware along with the logical centralization of the network control to directly express the desired goals and policies in a centralized, high-level manner without being tied to the implementation and state-distribution details of the underlying networking infrastructure. Similarly, SDN applications consume network services and functions provided by the control plane by utilizing the abstracted network view exposed to them through the northbound interface.

SDN controllers implement northbound APIs as network abstraction interfaces that ease network programmability, simplify control and management tasks, and enable innovation. Northbound APIs are not supported by an accepted standard, contrary to southbound APIs

SDN and OpenFlow

**Data and Control Planes**

The traditional ways to build routing networks are where the SDN revolution is happening. Networks started with tight coupling between data and control planes. The control plane was distributed, meaning each node had a control element and performed its control plane activities. SDN changed this architecture, centralized the control plane with a controller, and used OpenFlow or another protocol to communicate with the data plane. However, all control functions are handled by a central controller, which has many scaling drawbacks.

**Distribution and Centralized**

Therefore, we seem to be moving to a scalable hybrid control plane architecture. The hybrid control plane is a mixture of distributed and centralized controls. Centralization offers global visibility, better network operations, and optimizations. However, distributed control remains best for specific use cases, such as IGP convergence. More importantly, a centralized element introduces additional value to the Wide Area Network (WAN) network, such as network traffic engineering (TE) placement optimization, aka Transport SDN.


Transport SDN

Transport SDN • Traffic Engineering Lab

What Happens When WAN Conditions Change?

Change the traffic demand, link utilisation, SLA priority and path strategy. The transport-engineering decision changes as the network state changes.

Available Transport Paths
Path A · Direct Core
Candidate
Latency 18 ms
Capacity 100 Gbps
Reliability 99.99%
Path B · Alternate Core
Candidate
Latency 27 ms
Capacity 140 Gbps
Reliability 99.995%
Path C · Long Haul
Candidate
Latency 41 ms
Capacity 200 Gbps
Reliability 99.998%
Selected Path
Path A
Estimated Load
50%
SLA Condition
Healthy
TE Confidence
High
Traffic Engineering Decision
Engineering insight: A path with the lowest latency is not automatically the best path. Transport traffic engineering can balance latency, available capacity, utilisation and SLA requirements against one another.

The two elements involved in forwarding packets through routers are a control function, which decides the route the traffic takes and its relative priority, and a data function, which delivers data based on control-function policy. Before the introduction of SDN, these functions were integrated into each network device. This inflexible approach requires all the network nodes to implement the same protocols. A central controller performs all complex functionality with SDN, including routing, naming, policy declaration, and security checks.

Transport SDN: The SDN Design

SDN has two buckets: the Wide Area Network (WAN) and the Data Centre (DC). What SDN is trying to achieve in the WAN differs from what it is trying to accomplish in the DC. Every point is connected within the DC, and you can assume unconstrained capacity.

A typical data center design is a leaf and spine architecture, where all nodes have equidistant endpoints. This is not the case in the WAN, which has completely different requirements and must meet SLA with less bandwidth. The WAN and data center requirements are entirely different, resulting in two SDN models.

The SDN data center model builds logical network overlays over fully meshed, unconstrained physical infrastructure. The WAN does not follow this model. The SDN DC model aims to replace, while the SD-WAN model aims to augment. SD-WAN is built on SDN, and this SD WAN tutorial will bring you up to speed on the drivers for SD WAN overlay and the main environmental challenges forcing the need for WAN modernization.

We can evolve the IP/MPLS control plane to a hybrid one. We go from a fully distributed control plane architecture where we maintain as much of the distributed control plane as it makes sense (convergence). At the same time, produce a controller that can help you enhance the control plane functionality of the network and interact with applications. Global optimization of traffic engineering offers many benefits.

**WAN is all about SLA**

Service Providers assure Service Level Agreement (SLA), ensuring sufficient capacity relative to the offered traffic load. Traffic Engineering (TE) and Intelligent load balancing aim to ensure adequate capacity to deliver the promised SLA, routing customers’ traffic where the network capacity is. In addition, some WAN SPs use point-to-point LSP TE tunnels for individual customer SLAs. 

WAN networks are all about SLA, and there are several ways to satisfy them: Network Planning and Traffic Engineering. The better planning you do, the less TE you need. However, planning requires accurate traffic flow statistics to understand the network’s capabilities fully. An accurate network traffic profile sometimes doesn’t exist, and many networks are vastly over-provisioned.

A key point: Netflow

Netflow is one of the most popular ways to measure your traffic mix. Routers collect “flow” information and export the data to a collector agent. Depending on the NetFlow version, different approaches are taken to aggregate flows. Netflow version 5 is the most common, and version 9 offers MPLS-aware Netflow. BGP Policy Accounting and Destination Class Usage enables routers to collect aggregated destination statistics (limited to 16/64/126 buckets). BGP permits accounting for traffic mapping to a destination address.

For MPLS LSP, we have LDP and RSVP-TE. Unfortunately, LDP and RSVP-TE have inconsistencies in vendor implementations, and RSVP-TE requires a full mesh of TE tunnels. Is this good enough, or can SDN tools enhance and augment existing monitoring? Juniper NorthStar central controller offers friendly end-to-end analytics.

Transport SDN: Traffic Engineering

The real problem comes with TE. IP routing is destination-based, and path computation is based on an additive metric. Bandwidth availability is not taken into account. Some links may be congested, and others underutilized. By default, the routing protocol has no way of knowing this. The main traditional approaches to TE are MPLS TE and IGP Metric-based TE.

Varying the metric link moves the problem around. However, you can tweak metrics to enable ECMP, spreading traffic via a hash algorithm over-dispersed paths. ECMP suits local path diversity but lacks global visibility for optimum end-to-end TE. A centralized control improves the distribution-control insufficiency needed for optimal Multi-area/Multi-AS TE path computation.transport SDN

BGP-LS & PCEP

OpenDaylight is an SDN infrastructure controller that enhances the control plane, offering a service abstraction layer. It carries out network abstraction of whatever service exists on the controller. On top of that, there are APIs enabling applications to interface with the network. It supports BGP-LS and PCEP, two protocols commonly used in the transport SDN framework.

BGP-LS makes BGP an extraction protocol.

The challenge is that the contents of a Link State Database (LSDB) and an IGP’s Traffic Engineering Database (TED) describe only the links and nodes within that domain. When end-to-end TE capabilities are required through a multi-domain and multi-protocol architecture, TE applications require visibility outside one area to make better decisions. New tools like BGP-LS and PCEP combined with a central controller enhance TE and provide multi-domain visibility.

We can improve the IGP topology by extending BGP to BGP Link-State. This wraps up the LSDB in BGP transport and pushes it to BGP speakers. It’s a valuable extension used to introduce link-state into BGP. Vendors introduced PCEP in 2005 to solve the TE problem.

Initially, it was stateless, but it is now available in a stateful mode. PCEP address path computation uses multi-domain and multi-layer networks.

Its main driver was to decrease the complexity around MPLS and GMPLS traffic engineering. However, the constrained shortest path (CSPF) process was insufficient in complex typologies. In addition, Dijkstra-based link-state routing protocols suffer from what is known as bin-packing, where they don’t consider network utilization as a whole.

Closing Points on Transport SDN

Transport SDN is a specific application of the broader SDN technology that focuses on the management and optimization of transport networks. These networks are the backbone of any telecommunications infrastructure, responsible for carrying large volumes of data across vast distances. Transport SDN separates the control plane from the data plane, enabling network administrators to manage traffic dynamically and efficiently. This separation allows for improved network performance, reduced latency, and enhanced scalability.

One of the primary advantages of Transport SDN is its ability to enhance network agility. By providing a centralized control system, Transport SDN enables administrators to reconfigure the network in real time to adapt to changing demands. This flexibility is crucial in today’s fast-paced digital environment, where the need for quick adjustments is constant. Additionally, Transport SDN can lead to cost savings by optimizing resource usage and minimizing the need for manual interventions.

While Transport SDN offers numerous benefits, it is not without its challenges. Implementing this technology requires a significant investment in both time and resources. Organizations must carefully plan their migration to ensure a seamless transition. Security is another critical consideration, as the centralized nature of SDN can create potential vulnerabilities. It is essential for companies to adopt robust security measures to protect their network infrastructure.

Transport SDN is making its mark across various industries. In telecommunications, it is used to streamline operations and improve service delivery. Enterprises are leveraging Transport SDN to enhance their internal networks, facilitating better collaboration and communication. Additionally, data centers are employing this technology to manage traffic more effectively and ensure optimal performance for cloud-based services.

Transport SDN • Incident Investigation

Why Is the WAN Healthy but the SLA Is Degrading?

The routing protocol reports a valid path and all links are reachable. Application latency has nevertheless increased. Investigate the evidence and identify the most likely transport-engineering problem.

Active Incident
Application traffic between the primary sites is experiencing increased latency and packet delay. No routing adjacency is down and the IGP has not reported a topology failure.
IGP Adjacency
Established
Reachability
Healthy
Primary Link
87% Utilised
Application Latency
+42 ms
Controller
TE Alert
Observed Forwarding Path
Site A Application traffic
→
Core Link 87% utilisation
→
PE Router IGP path valid
→
Site B Application endpoint
What Is the Most Likely Root Cause?
Investigation Console
Incident opened: application latency increased IGP state checked: adjacency remains established Reachability checked: destination remains reachable Telemetry checked: primary path utilisation elevated
Engineering insight: A healthy routing path is not necessarily an optimal traffic-engineering path. This is one of the important distinctions between basic reachability and global WAN optimisation: the IGP can correctly maintain connectivity while a controller uses telemetry and policy to improve how traffic is distributed across available paths.
BGP Multipath

BGP Multipath

NETWORK INSIGHT · BGP ENGINEERING GUIDE
BGP Multipath: From Route Selection to Forwarding

A BGP router can learn several routes to the same destination, select a preferred path, and still install multiple next hops for forwarding. Understanding how these decisions interact is essential when designing resilient, load-sharing networks and troubleshooting unexpected traffic behaviour.

BGP Multipath allows a router to install multiple eligible paths for a prefix, subject to its configuration, path-selection rules and platform capabilities. Instead of relying on a single forwarding next hop, the router can use a set of next hops to distribute traffic and maintain forwarding options when a path becomes unavailable.

The important distinction is that routes learned by BGP are not automatically routes installed in the forwarding table. A route may be present in the BGP table yet fail a multipath eligibility check. Even when several paths are installed, the actual traffic distribution depends on the forwarding implementation and its hashing behaviour.

The engineering question

If a router learns two or more paths to the same prefix, what determines which next hops reach the FIB, how is traffic distributed across them, and what happens when one path fails?

01 · SEE

Understand the path set

Follow candidate routes from BGP selection through multipath eligibility to the next hops installed in the forwarding table.

02 · OBSERVE

Verify traffic distribution

Compare installed paths with forwarding state, interface counters, traffic demand and path characteristics.

03 · INVESTIGATE

Find the missing path

Use routing evidence to identify why a candidate path is excluded and validate the result after a change or failure.

This guide combines routing concepts with interactive engineering labs. You will examine candidate paths, change the permitted multipath count, investigate a missing forwarding next hop, and explore how Route Reflectors and BGP Add-Path affect the visibility and advertisement of alternative routes.

Engineering guide · Navigation

4 investigation stages

BGP Multipath: Engineering Navigation

Follow the route from BGP selection to real forwarding behaviour. Each stage builds on the previous one, moving from architecture and visibility to fault isolation and verified recovery.

SECTION 01 · SEE THE FORWARDING PATH

When Does a BGP Route Become a Forwarding Next Hop?

Learning multiple routes does not mean installing every route. A router evaluates candidate paths, applies its BGP decision process and checks which alternatives qualify for multipath forwarding. Follow the decision chain below.

STAGE 01 Learn routes Receive candidate paths from BGP peers.
STAGE 02 Evaluate paths Compare policy attributes and route eligibility.
STAGE 03 Check multipath Apply maximum-paths and implementation-specific rules.
STAGE 04 Install next hops Program eligible paths into forwarding, if installation succeeds.
Engineering question: Which candidate paths qualify for the multipath set, and how can you prove that their next hops were actually installed in the FIB?

Section 1 — From BGP Paths to Forwarding

BGP multipath is the ability to install multiple eligible routes to the same destination into a router's forwarding state, rather than relying on a single next hop. It can improve link utilisation and provide additional forwarding options, but only when the routes satisfy the platform's multipath rules and the forwarding hardware can use them.

The important engineering distinction is between routes BGP knows about and next hops the router actually uses to forward packets. A router may learn several paths for a prefix yet select only one for installation. Seeing multiple paths in a BGP table is therefore not proof that multipath forwarding is active.

Engineering question: For a destination prefix, which candidate paths qualify for multipath, which next hops are installed in the forwarding information base (FIB), and what evidence proves packets can use those next hops?

1.1 The path from route learning to packet forwarding

BGP receives route advertisements from peers and evaluates the attributes and policies associated with each path. The routing process then determines the eligible route or routes. If multipath is configured and the relevant eligibility conditions are met, the router may install multiple next hops for the same prefix. The data plane uses the installed forwarding state to direct packets.

Stage 01 Learn routes

Receive BGP UPDATEs and maintain paths learned from peers.

Stage 02 Evaluate paths

Apply policy, compare attributes and assess route eligibility.

Stage 03 Check multipath

Determine whether additional paths satisfy configured rules.

Stage 04 Install next hops

Program usable forwarding entries and verify the resulting FIB.

These stages describe the conceptual workflow; exact implementation details differ between vendors and operating systems. Some platforms expose a separate multipath set, while others present the selected route and additional forwarding next hops through different commands.

1.2 BGP RIB versus FIB: two different views

The routing information base (RIB) represents route information maintained by the control plane. The forwarding information base (FIB) contains the entries used by the forwarding plane. The two are related, but they answer different operational questions.

Evidence source What it tells you What it does not prove alone
BGP route table Which BGP paths are known, their attributes and their selection status. That every visible path is installed for forwarding.
Routing table / RIB Which route or routes the routing process has selected for the destination. That all intended next hops are programmed and usable in hardware.
Forwarding table / FIB Which next-hop entries the forwarding plane uses for matching packets. That traffic is distributed evenly or that every path is healthy under load.
Interface and traffic counters Whether interfaces carry traffic and how utilisation changes. That BGP multipath is the only cause of the observed traffic pattern.

1.3 What makes a path eligible for multipath?

Enabling a maximum-paths setting does not mean that any route to the same prefix can be installed alongside the current best path. The router must still apply its route-selection process and its implementation-specific multipath criteria. Those criteria can include path attributes, peer type, next-hop reachability, routing policy and other platform-specific constraints.

Best-path selection and multipath eligibility are related, but not identical

BGP first evaluates routes according to its decision process. Multipath then permits additional paths that satisfy the implementation's requirements to be installed alongside the selected path. Depending on the platform and configuration, some attributes that matter to best-path selection may need to match or meet specific conditions for multipath. Do not assume identical requirements across vendors.

Path attributes

Compare attributes such as Local Preference, AS_PATH, origin and MED where relevant to the platform's multipath rules.

Next-hop reachability

Verify that each candidate next hop resolves through the routing table and has a usable forwarding path.

Configuration and limits

Check the applicable maximum-paths command, address family, peer type, policy and platform limits.

1.4 Configuring multipath: verify the scope, not just the command

Many BGP implementations provide a command such as maximum-paths to control how many eligible paths can be installed. The precise command, supported path types and default behaviour depend on the vendor, software release and address family. eBGP and iBGP multipath may use separate configuration.

Treat the following as an illustrative configuration pattern, not a universal command sequence:

Illustrative BGP configuration router bgp 65001 address-family ipv4 unicast maximum-paths 2

Before applying configuration, confirm the syntax and placement in your platform's documentation. After making a change, verify the operational result in both the routing table and the FIB. A configured limit of two paths is a ceiling, not a guarantee that two paths will qualify.

1.5 Worked example: three candidate paths, two installed next hops

Consider router R1 learning prefix 203.0.113.0/24 through three candidate paths. Assume Paths A and B meet the configured multipath criteria, while Path C does not. In this example, the router installs two next hops for the destination.

Candidate Control-plane observation Forwarding result
Path A Selected best path and eligible for multipath. Installed
Path B Meets the configured additional-path eligibility rules. Installed
Path C Visible as a candidate but fails a required eligibility condition in this scenario. Not installed

The router can now forward matching traffic using the installed next-hop set. How traffic is divided depends on the forwarding platform, hashing algorithm, flow characteristics and configuration. Two installed next hops do not guarantee a 50/50 traffic split, and packet ordering or per-flow behaviour depends on the implementation.

1.6 How to prove multipath is operational

Validate the state at three levels. First, inspect BGP to confirm the candidate routes and their attributes. Second, inspect the routing and forwarding tables to confirm that the expected next hops are installed. Third, observe interface counters or traffic telemetry under an appropriate test load to see whether traffic is actually using the available paths.

Vendor-neutral verification checklist 1. Identify the destination prefix. 2. Inspect all relevant BGP paths and attributes. 3. Check the selected route and multipath eligibility. 4. Inspect the installed FIB next hops. 5. Compare interface counters before and during traffic. 6. Repeat after a controlled path failure and recovery.

Command names differ across platforms, so use the equivalent BGP route, routing-table, forwarding-table and interface-counter commands for your environment. Establish a baseline before testing, and avoid injecting a failure into production without an approved maintenance or test procedure.

Section 1 · Engineering takeaway

Multipath is proven by more than seeing two BGP routes. Establish which paths are eligible, verify the installed next-hop set in the FIB, and then measure forwarding behaviour. This separates control-plane visibility from actual packet forwarding.

BGP Routing Lab

How Does BGP Multipath Turn Several Routes into One Forwarding Decision?

BGP normally identifies a single best path. With multipath enabled, multiple paths that satisfy the implementation's multipath eligibility rules can be installed and used for forwarding. Explore the difference between candidate paths and installed next hops.

Candidate paths for 203.0.113.0/24
Path A · PE1
Installed
LocalPref 200
AS Path 65010
MED 50
Next-hop 10.0.1.1
Path B · PE2
Installed
LocalPref 200
AS Path 65010
MED 50
Next-hop 10.0.2.1
Path C · PE3
Not eligible
LocalPref 200
AS Path 65020 65010
MED 50
Next-hop 10.0.3.1
BGP RIB candidate routes
→
Multipath Check eligibility rules
→
FIB multiple next hops
10.0.1.1 · PE1
10.0.2.1 · PE2
Forwarding decision
Destination 203.0.113.0/24
Best policy value LocalPref 200
Eligible paths 2
Forwarding model ECMP / Multipath
Engineering insight: Paths A and B have matching policy and path characteristics for this simplified example, so both can be installed. Path C has a longer AS path and is outside the multipath set.
BGP UPDATE received for 203.0.113.0/24
→ compare candidate attributes
→ Path A eligible for multipath
→ Path B eligible for multipath
→ Path C excluded: path attributes differ
FIB programmed with 2 next hops
SECTION 02 · OBSERVE THE EVIDENCE

Are Multiple Paths Carrying Traffic as Intended?

A multipath configuration is not proof of successful forwarding. Engineers need to compare routing state with the forwarding table and real traffic measurements. Each evidence source answers a different operational question.

EVIDENCE 01
BGP and RIB state

Confirm which candidate routes are learned, which paths qualify for multipath, and whether the expected number of next hops is selected for installation.

EVIDENCE 02
FIB and interface counters

Verify that multiple next hops are programmed and inspect interface packet and byte counters to see whether traffic traverses the expected links.

EVIDENCE 03
Traffic and utilisation

Compare per-link utilisation and traffic over time. Uneven distribution is not automatically a fault: flow hashing, traffic patterns and link capacity all matter.

BGP route table FIB next hops Interface counters Per-link utilisation
Engineering question: Do the installed next hops match the expected forwarding design, and does measured traffic provide evidence that those paths are being used?

Section 2 — Verify Traffic Distribution

Installing multiple BGP next hops creates the possibility of multipath forwarding; it does not prove that traffic is being distributed as expected. Engineers must correlate the control-plane view with forwarding entries, interface counters and measured traffic to establish what the network is actually doing.

A routing table can show two installed next hops while one physical link carries substantially more traffic than another. That observation is not automatically a fault. Traffic distribution depends on the forwarding implementation, hash inputs, flow sizes, path capacity, traffic direction and other network conditions.

Engineering question: Are all intended next hops installed and healthy, and does observed traffic behaviour match the forwarding design and expected workload?

2.1 Three evidence sources, one operational picture

Reliable validation combines evidence from different layers. No single command or counter provides the complete picture.

Evidence 01 BGP and routing state

Confirm the destination prefix, candidate paths, selected route, path attributes and the router's multipath status.

Evidence 02 FIB and next hops

Verify the actual installed forwarding entries, resolved next hops and outgoing interfaces for the prefix.

Evidence 03 Traffic and utilisation

Compare interface counters, flow telemetry, drops, errors and utilisation over a consistent measurement interval.

2.2 Why two paths rarely mean an exact 50/50 split

Many routers use a hash to map flows or packets to next hops. Depending on the platform and configuration, hash inputs may include source and destination addresses, transport ports, protocol identifiers or other fields. This helps preserve packet ordering for a flow, but it does not guarantee equal byte counts across links.

Imagine two installed next hops. If a few high-volume flows hash to the first path while many small flows hash to the second, their utilisation can differ considerably. The paths may both be functioning correctly.

Observation Possible explanation Next check
Both next hops are installed, but one link is busier. Uneven flow sizes or hash distribution. Compare flow-level telemetry, byte counters and the hashing policy.
One expected next hop is absent from the FIB. Multipath eligibility, route resolution, policy or programming issue. Recheck the BGP paths, routing table and forwarding entries.
A link's utilisation rises while drops also increase. Congestion, insufficient capacity, errors or a downstream bottleneck. Inspect queue drops, interface errors and downstream links.
Traffic changes after a path failure. Traffic has moved to surviving paths, possibly with a temporary convergence effect. Check route state, FIB changes, loss, latency and remaining capacity.

2.3 Measure counters correctly

Interface counters are cumulative, so compare changes over a defined interval rather than relying only on their absolute values. Record the starting and ending byte or packet counts, the elapsed time, and whether the interface counters reset during the test.

Measurement method 1. Record interface counters at time T1. 2. Generate or observe representative traffic. 3. Record counters again at time T2. 4. Calculate counter deltas over T2 − T1. 5. Compare utilisation, drops and errors across paths. 6. Repeat under comparable traffic conditions.

For byte counters, the approximate average bit rate over the interval is:

Average bit rate (bits/s)
\((\text{byte delta} \times 8) \div \text{elapsed seconds}\)

Compare this value with the interface's usable capacity. Account for units, counter width, measurement interval and traffic direction when interpreting the result.

2.4 Confirm the measurement point

A router's egress interface counters show traffic transmitted through that interface; they do not necessarily describe what the remote endpoint received. Conversely, ingress counters measure traffic arriving at that interface. Drops, encapsulation overhead, congestion and measurement placement can make these values differ.

When investigating an imbalance, identify where each measurement was taken and which traffic direction it represents. If possible, correlate interface counters with flow records, queue statistics and application-level observations. This helps distinguish a routing issue from a congestion, capacity or measurement issue.

2.5 Validate behaviour during a controlled failure

Multipath can provide alternate forwarding options, but it does not guarantee uninterrupted service. A failed link may trigger interface-state changes, route withdrawal, next-hop resolution changes and FIB reprogramming. The observed impact depends on the topology, protocol convergence, forwarding hardware and available capacity on the surviving paths.

In a controlled test, establish a baseline first. Then remove or fail one path using an approved method, observe the routing and forwarding changes, and measure traffic on the surviving path. Restore the path and verify that the expected operational state returns.

Before Capture baseline

Record installed next hops, link utilisation, packet loss, latency and interface health.

During Observe the transition

Correlate the failed path with route changes, FIB updates, traffic movement and any loss.

After Verify recovery

Confirm the restored path is eligible, installed as expected and carrying traffic when appropriate.

2.6 Operational verification checklist

Before declaring multipath healthy, verify each of the following against the intended design:

Control plane: The required paths are learned and the expected route state is present.

Forwarding plane: The intended next hops appear in the FIB and resolve to usable interfaces.

Traffic plane: Counters or flow telemetry demonstrate actual traffic movement, with no unexplained drops or errors.

Resilience: A controlled path failure produces the expected transition, and recovery restores the intended state.
Section 2 · Engineering takeaway

Multiple FIB next hops prove that forwarding options are installed; they do not prove equal load sharing, sufficient capacity or zero packet loss. Correlate route state, forwarding entries and time-based traffic measurements to determine whether multipath is operating as designed.

BGP Multipath Experiment

How Many Paths Actually Reach the FIB?

Multipath is not simply “use every route.” Change the number of permitted paths, traffic demand and path similarity to see how the forwarding set changes. The model below illustrates the engineering decision rather than a vendor-specific command syntax.

Network controls
Maximum installed paths 2
Traffic demand 60%
Path similarity High
Forwarding policy
Candidate paths
Path A · 10.0.1.1
Excluded
Direct path · 20 ms · 100 Gbps
Path B · 10.0.2.1
Excluded
Alternate path · 28 ms · 140 Gbps
Path C · 10.0.3.1
Excluded
Long-haul path · 41 ms · 200 Gbps
Path D · 10.0.4.1
Excluded
Diverse path · 47 ms · 240 Gbps
Installed
0 / 4
Aggregate capacity
0 Gbps
Average latency
—
FIB state
Single path
Engineering insight: Increase the maximum path count to allow more eligible paths into the forwarding set.
SECTION 03 · INVESTIGATE THE FAILURE

Two Routes Are Visible. Why Is Only One Installed?

When a second path is missing from the FIB, do not assume that the BGP neighbour is down or that multipath is broken. Start with the evidence and work through the routing and forwarding decision chain until the exclusion point is identified.

01
Confirm route availability

Check the peer session, received prefix, route validity and next-hop reachability. Establish whether the candidate path is actually usable.

02
Compare path attributes

Examine Local Preference, AS_PATH, origin, MED where applicable, and other attributes required by the implementation's multipath rules.

03
Verify multipath configuration

Check the relevant maximum-paths settings, peer-type requirements, address family and platform-specific eligibility conditions.

04
Inspect forwarding installation

Compare the BGP path set with the installed FIB next hops. If a path qualifies but is absent from forwarding, investigate programming errors and resource constraints.

Investigation principle: Identify the first point where observed state differs from expected state. A route missing from the FIB can have several causes, so validate each layer before changing configuration.

Section 3 — Investigate: Why Is the Second Path Missing?

When a router learns two BGP paths but installs only one forwarding next hop, the correct response is not to increase the maximum-paths value blindly. The task is to discover where the expected state diverges from the actual state, using evidence from route learning, path selection, multipath eligibility and forwarding installation.

A missing path can result from route policy, a difference in path attributes, an unresolved next hop, an incompatible peer type, an address-family configuration issue, a platform limitation or a forwarding-programming problem. These causes occur at different stages and require different remedies.

Engineering question: At which stage does the second path stop qualifying, and what observable evidence identifies the cause?

3.1 Troubleshoot in dependency order

Follow the route through the system in sequence. This prevents an engineer from changing a downstream setting before confirming that the upstream prerequisite is satisfied.

01
Confirm the route exists

Verify the prefix is learned from the expected peer and has not been rejected, filtered or withdrawn.

02
Compare path attributes

Compare the candidate paths and identify differences that affect best-path selection or multipath eligibility.

03
Check configuration and policy

Verify the correct address family, peer type, maximum-paths setting, import policy and platform-specific requirements.

04
Inspect next-hop resolution

Confirm each next hop resolves through a valid route and is usable by the forwarding plane.

05
Inspect routing and forwarding tables

Determine whether the path is excluded during route selection, omitted from the multipath set or missing from the FIB.

06
Validate the correction

Repeat the checks after a targeted change and confirm both forwarding state and traffic behaviour.

3.2 Read the evidence before changing the configuration

A useful incident investigation records what was expected, what was observed and what the evidence rules out. The following examples illustrate how to narrow the search without assuming that a single attribute explains every multipath failure.

Observed evidence Likely investigation area Next verification
Only one path appears in the received routes. Advertisement, route policy, session or route visibility. Check peer state, received routes where supported, filters and upstream advertisement.
Two paths are known, but one is rejected by policy. Import policy, route map, prefix list or community-based filtering. Inspect policy evaluation and the resulting accepted route attributes.
Both paths are known but differ in a relevant attribute. Best-path decision or platform-specific multipath criteria. Compare the full attribute set and the vendor's documented eligibility rules.
Attributes appear compatible, but one next hop is unresolved. Reachability, recursive resolution or IGP dependency. Check the route to the next-hop address and the associated outgoing interface.
The routing table shows multipath, but the FIB has one next hop. Forwarding installation, hardware constraints or implementation-specific state. Inspect platform forwarding diagnostics, resource limits and programming status.
The FIB has multiple next hops but traffic looks uneven. Traffic hashing, flow distribution, capacity or measurement placement. Compare time-based counters, flow telemetry, errors and drops.

3.3 Do not confuse a best-path difference with a multipath failure

BGP attributes affect route selection, but not every attribute difference automatically makes multipath impossible on every platform. For example, the treatment of AS_PATH, MED, IGP cost to the next hop and other attributes can depend on the implementation and configuration. Use the router's best-path explanation and documented multipath rules rather than relying on a generic list of attributes that must match.

Local Preference is an important example. A higher Local Preference normally favours a path in the BGP decision process. If two routes have different Local Preference values, do not assume they will be installed together as equal multipath alternatives. Establish which path wins, then verify whether the platform supports any relevant relaxation or special configuration.

Evidence discipline

Record the complete relevant path attributes, the selected best path, the platform's multipath eligibility result and the installed next hops. Matching two visible attributes is not proof that two paths meet all eligibility requirements.

3.4 Distinguish three different failure points

Failure point A — The path never reaches the router's usable candidate set

The route may not be advertised, may be filtered, or may be unavailable because the peer or address family is not functioning as expected. Investigate the sender, session, policy and received-route visibility first.

Failure point B — The path is learned but not selected for multipath

The router knows the route, but its selection process or multipath rules do not include it in the installed set. Investigate attributes, next-hop reachability, peer type, configuration scope and vendor-specific criteria.

Failure point C — The path qualifies, but forwarding state is unexpected

If the control plane reports the expected multipath set but the FIB does not reflect it, examine route installation status, hardware capabilities, resource constraints and platform diagnostics. Do not assume a control-plane configuration change is the right fix until the discrepancy is understood.

3.5 A disciplined CLI investigation

Command syntax varies by vendor and release. Use the equivalent commands for your platform to collect the following evidence before modifying configuration.

Investigation sequence 1. Inspect the BGP session and address-family state. 2. Display all available paths for the destination prefix. 3. Compare attributes and the best-path decision. 4. Inspect import policy and multipath configuration. 5. Verify recursive next-hop reachability. 6. Display the routing-table and FIB entries. 7. Review platform diagnostics and interface counters.

Save the initial outputs and note the time of each observation. This creates a baseline for comparing state after a targeted correction. In production, use approved change controls and avoid clearing BGP sessions or withdrawing routes as a first-line diagnostic action.

3.6 Confirm that the problem is actually fixed

A configuration command completing successfully is not the same as a successful operational outcome. Re-run the same checks used to establish the original fault and compare them with the expected state.

A
Control-plane proof

The expected candidate routes are present, and the multipath decision is consistent with the intended design.

B
Forwarding proof

The FIB contains the intended usable next hops, without unexplained installation errors.

C
Traffic proof

Appropriate counters or flow telemetry confirm forwarding, and the original symptom no longer occurs.

D
Resilience proof

Where required, a controlled failure and restoration test confirms the intended alternate-path behaviour.

Section 3 · Engineering takeaway

Find the first point where the expected route state diverges from reality. Separate route visibility, multipath eligibility and FIB installation, then verify the fix at both the control plane and forwarding plane. This is more reliable than changing maximum-paths or comparing only a subset of BGP attributes.

Engineering workflow · Correlate & operate

Can You Prove the Alternate Path Is Visible, Installed and Ready?

A route advertised by a peer is not automatically installed as an additional forwarding path. Correlate what the router receives, which paths qualify for local multipath, what reaches the FIB, and what happens when a link fails.

01
Route visibility

Check which paths the upstream router or Route Reflector advertises and which paths the receiving router actually learns.

BGP updates · Adj-RIB-In
02
Local eligibility

Verify multipath configuration, path compatibility, next-hop reachability and platform-specific selection rules.

Best path · Multipath rules
03
Forwarding state

Inspect the FIB and next-hop entries, then compare interface counters and traffic measurements to confirm actual forwarding.

FIB · Counters · Utilisation
04
Failover & recovery

Withdraw or fail one path in a controlled test. Confirm the remaining path forwards traffic and the expected state returns after recovery.

Failure · Convergence · Validation
Key distinction Add-Path is a negotiated BGP capability that can advertise multiple paths; it does not itself install multiple next hops in the FIB. Route advertisement, local multipath eligibility and forwarding installation must be verified separately.

Section 4 — Correlate & Operate: Route Reflectors, Add-Path and Failover

Multiple paths can exist in the network without all of them reaching the router that needs to forward traffic. To understand the complete forwarding outcome, an engineer must correlate what upstream peers advertise, what route reflectors propagate, what the local router accepts, and what the forwarding plane actually installs.

This is the operational difference between path visibility and multipath forwarding. A route may be available somewhere in the BGP system but hidden from a particular router by route-reflection behaviour, policy, or the capabilities negotiated between peers. Even when multiple routes reach the router, local eligibility and next-hop resolution still determine whether multiple next hops can be installed.

The end-to-end evidence chain

Peer advertisement → Route Reflector decision → Receiving router's BGP table → Multipath eligibility → RIB/FIB installation → Measured traffic.

Each stage answers a different question. If a path disappears between two stages, investigate that boundary before changing configuration elsewhere.

4.1 — Route Reflectors: Which Paths Reach the Client?

Route Reflectors reduce the need for a full mesh of iBGP sessions. In a conventional route-reflection design, a reflector generally advertises its selected best path to a client for a given prefix, subject to its routing policy and implementation. A client may therefore receive fewer paths than the reflector itself knows about.

This matters when investigating multipath. If a router has only one usable candidate route, enabling a local multipath setting cannot create a second route that was never advertised or learned. First establish whether the alternate path is available at the point where the forwarding decision is made.

What the reflector knows

The reflector may learn several paths from different peers but select one path for normal advertisement to a client. Inspect its received routes, best-path decision, export policy, and advertised-route state.

What the client receives

The client can only evaluate routes available to it. Confirm its BGP table and next-hop reachability before concluding that local multipath eligibility is the problem.

Engineering rule: distinguish “the network has another path” from “this router has another eligible path.” These are different statements and require different evidence.

4.2 — Add-Path: Advertise More Than One Path

BGP Add-Path extends BGP so that a peer can advertise multiple paths for the same Network Layer Reachability Information (NLRI), rather than being limited to a single path in the relevant advertisement context. The capability must be supported and negotiated between the peers, and the implementation and configuration must permit the intended paths to be sent and accepted.

Add-Path can improve path visibility in designs where a single advertised best path would otherwise hide useful alternatives. It can be relevant to route-reflector topologies, redundant exits, and scenarios where downstream routers need more candidate paths to make their own routing decisions.

Mechanism Primary purpose What it does not guarantee
Multipath Allows multiple eligible paths to be installed for forwarding, subject to platform and configuration rules. It does not guarantee that upstream peers advertise every alternate path.
Add-Path Allows multiple paths for a prefix to be advertised to a peer when negotiated and configured. It does not, by itself, make the receiver install multiple next hops in its FIB.
Best External Can advertise an eligible external path in addition to the selected best path, where supported and configured. It is not a general replacement for Add-Path or local multipath.
Optimal Route Reflection (ORR) Can help a route reflector select paths that better reflect a client's IGP perspective in supported designs. It does not itself install multiple forwarding paths on the client.

When Add-Path is involved, verify both ends of the relationship: the negotiated capability and the actual routes advertised and received. Then inspect the receiver's own best-path and multipath decisions. A capability being enabled in configuration is not, by itself, proof that the desired paths are reaching the destination router.

4.3 — Next-Hop Reachability, IGP Cost and Egress Choice

A BGP path is useful for forwarding only if its next hop can be resolved. In many designs, that resolution depends on the IGP and the local routing table. A path can be present in BGP but unusable for forwarding if its next hop is unreachable or cannot be resolved according to the platform's rules.

IGP cost can also influence which exit a router prefers. With hot-potato routing, a network commonly prefers to hand traffic to an external network at the closest eligible exit, often based on IGP cost after higher-priority BGP decision criteria have been considered. A topology or IGP metric change can therefore alter the selected egress even if the externally learned route attributes have not changed.

Check next-hop resolution

Confirm the BGP next hop resolves through the expected route, interface, tunnel, or recursive path. Compare the BGP next-hop value with the route used to reach it.

Check the forwarding exit

Compare IGP costs to candidate exits, installed FIB next hops, interface state, and traffic counters. A change in egress may reflect normal routing behaviour rather than a BGP session failure.

Understand the design before diagnosing instability

Interactions between MED comparison rules, route-reflection design, hot-potato decisions, topology changes, and policy can contribute to route instability in some networks. MED is not necessarily compared globally across every candidate path in the same way on every implementation or configuration, and route reflectors do not inevitably cause oscillation.

If a prefix repeatedly changes its selected path, examine the sequence of received updates, the attributes considered at each decision point, the relevant IGP metrics, and the policy applied by each router. Look for a repeatable feedback pattern rather than attributing the problem to one feature based on the symptom alone.

4.4 — Correlate Control Plane, Forwarding Plane and Telemetry

A reliable diagnosis joins several evidence sources. No single BGP command proves that traffic is using all intended paths. Likewise, interface counters alone cannot explain why a path was selected or excluded.

Evidence source Question answered What to correlate next
Peer and update state Are sessions established, and are route updates being exchanged? Received prefixes, advertised routes, withdrawals, and session events.
Route Reflector Which candidate paths are learned, selected, and advertised to the client? Export policy, Add-Path negotiation, path identifiers where applicable, and client receive state.
Local BGP table and RIB Which paths are available and eligible at the destination router? Path attributes, multipath rules, next-hop resolution, and routing policy.
FIB and adjacency state Which next hops are programmed for forwarding? Installed interfaces, recursive resolution, hardware or software programming status.
Interface counters and telemetry Is traffic actually using the intended links? Counter deltas, traffic direction, hash behaviour, utilisation, drops, and latency.
Evidence standard: capture a baseline and timestamps. Align routing events, FIB changes, interface counters, and traffic measurements to the same interval. Otherwise, normal update delays can make unrelated observations look like one failure.

4.5 — Run a Controlled Failover and Recovery Test

A second path is operationally valuable only if the network can use it under the conditions the design is intended to tolerate. Validate the failure and recovery sequence in a controlled maintenance window or lab, with a defined rollback plan and measurable acceptance criteria.

  1. Record the baseline Capture BGP paths, selected route, FIB next hops, peer state, interface counters, and representative traffic measurements.
  2. Trigger one controlled failure Disable or isolate the intended path in the test environment. Avoid changing several variables at once.
  3. Observe convergence Record the failure signal, route withdrawal or selection change, FIB update, traffic movement, packet loss, and recovery time.
  4. Restore and verify Re-enable the path, confirm session and route recovery, inspect the resulting FIB, and compare traffic against the original baseline.
Operational acceptance checklist
  • The intended alternate path is visible at the router that needs it.
  • Its next hop resolves and it satisfies the platform's multipath eligibility rules.
  • The forwarding table contains the expected next hops before the test.
  • A single controlled failure causes the expected route and forwarding changes.
  • Traffic moves to surviving paths within the defined convergence objective.
  • After restoration, routing and forwarding state return to an acceptable condition.
  • Logs, timestamps, counters, and test results provide evidence for the outcome.
Engineering takeaway

Multipath is an end-to-end outcome, not a single configuration command. Prove that alternate routes are advertised and received, eligible locally, resolved through valid next hops, installed in the FIB, and used as intended. Then test both failure and recovery to establish that the design behaves correctly under operational conditions.

Conclusion — Proving BGP Multipath Works

BGP multipath is about more than learning two routes. It is about determining whether multiple paths are available, eligible for simultaneous installation, programmed into the forwarding plane, and used correctly when traffic flows through the network.

Effective troubleshooting follows the evidence from the control plane to the data plane. Start with the routes the router receives, establish why each path is accepted or excluded, verify the installed next hops, and measure what happens to real traffic.

01 · SEE

Understand the path

Identify the candidate routes, their attributes, next hops, and the decisions that determine which paths are eligible.

02 · OBSERVE

Prove forwarding behaviour

Compare the routing table and FIB with interface counters and traffic measurements. Multiple installed paths do not guarantee equal traffic distribution.

03 · INVESTIGATE

Find the first failure point

Determine whether the alternate route is missing, ineligible for multipath, unresolved, or absent from the forwarding table.

04 · CORRELATE & OPERATE

Validate resilience

Correlate route advertisements, route-reflector behaviour, next-hop resolution, FIB changes, and telemetry during failure and recovery.

The key engineering principle: a route visible in BGP is not necessarily installed for forwarding, and a path installed in the FIB is not proof that traffic is distributed as intended. Each stage requires its own evidence.

From configuration to operational confidence

Use the interactive labs in this guide to explore path eligibility, experiment with the maximum number of paths, and investigate why a second route might not be installed. Change one condition at a time, observe the resulting state, and use the evidence to support your diagnosis.

A resilient BGP design is not proven by configuration alone. It is proven when the expected paths are visible, the intended next hops are installed, traffic behaves as designed, and controlled failure-and-recovery testing confirms the result.

BGP Incident Investigation

Why Isn't the Second BGP Path Being Installed?

Two routes appear to reach the router, but only one next hop is present in the forwarding table. Investigate the evidence and identify the most likely reason the second path is not entering the multipath set.

Incident evidence
!
Forwarding imbalance detected Prefix 203.0.113.0/24 is reachable through two eBGP peers, but only one next hop is installed.
Path A · Local Preference 200
Path B · Local Preference 200
Path A · AS Path 65010
Path B · AS Path 65010
Configured maximum paths 2
FIB next hops 1 / 2
Observed forwarding state
Router 203.0.113.0/24
→
PE1 10.0.1.1 · FIB
×
PE2 10.0.2.1 · not installed
Investigation score
0 / 1
What is the most likely diagnosis?
Investigation required.
Review the evidence before selecting a diagnosis.
Engineer takeaway: Matching Local Preference and AS Path does not automatically guarantee multipath installation. Implementations can require additional attributes and next-hop or path conditions to match before multiple paths become eligible.
BGP prefix 203.0.113.0/24 received from PE1 and PE2
→ LocalPref comparison: equal
→ AS_PATH comparison: equal
→ Multipath eligibility requires further validation
→ FIB currently contains next-hop 10.0.1.1 only
☕
Support Network Insight
Help support the development of interactive networking labs, BGP simulations, and educational content.
Support the Project
Routing Control Platform

BGP-based Routing Control Platform (RCP)

Routing Control Platforms: Centralised Intelligence for BGP

How can a network make routing decisions using a wider view of topology, policy and reachability than any individual router has locally? A Routing Control Platform (RCP) explores one answer: separate the computation of routing decisions from the routers that forward packets.

In a traditional BGP design, routers select paths using the routing information and policies available to them. Route Reflectors improve iBGP scalability, but their path-selection perspective can affect which routes are advertised to clients. An RCP-style architecture combines BGP information with an IGP topology view to compute routing decisions with a broader understanding of the network.

The engineering question: Can centralised routing intelligence improve path selection and scalability without placing the controller in the packet-forwarding path—and what happens when its network view is incomplete or stale?
01 · SEE

Understand the architecture

Explore how IGP topology, BGP reachability and routing policy feed a control platform that computes route decisions.

02 · OBSERVE

Compare routing perspectives

Examine why a Route Reflector and a controller using per-router topology information may choose different exits.

03 · INVESTIGATE

Diagnose incorrect decisions

Correlate topology freshness, IGP costs, BGP state and controller output to identify the cause of a suboptimal route.

Engineering outcome: understand the distinction between centralised route computation and distributed packet forwarding, evaluate RCP against Route Reflector designs, and identify the evidence needed to validate routing correctness.
NETWORK INSIGHT · ENGINEERING GUIDE
Routing Control Platform — Investigation Path

Follow the routing decision from architecture to operational verification. Each stage builds on the evidence collected in the previous one.

ENGINEERING ORIENTATION · 01 / SEE

How a routing decision travels through RCP

Select each stage to follow the control-plane workflow, from network information to packet forwarding.

Discover the networkThe platform needs a view of IGP topology, BGP routes and relevant policy before it can calculate a useful routing decision.

RCP Architecture: From Network State to Routing Decision

A Routing Control Platform (RCP) is an architectural approach to computing BGP routing decisions with a broader view of network topology, reachability and policy. Rather than relying exclusively on each router's local view, an RCP-style system collects routing information, evaluates it centrally and communicates routing decisions back to routers.

The important distinction is between where a routing decision is calculated and where packets are forwarded. RCP moves part of the route-computation process into a control platform. The routers still perform the actual packet forwarding using their local forwarding information base (FIB).

The engineering question

Can a controller use BGP information and IGP topology to make better-informed routing decisions without becoming a dependency in the normal packet-forwarding path?

1.1 The components of an RCP-style architecture

The original RCP concept separates information collection, route computation and route distribution. Exact component names and implementation details vary, but the following model captures the core responsibilities.

INPUT · TOPOLOGY
IGP topology view

Collects information about the internal network, including links, reachability and routing metrics. This helps the controller estimate the internal cost from a relevant router to a BGP next hop or external exit.

INPUT · REACHABILITY
BGP information

Provides reachable prefixes and path attributes such as AS_PATH, LOCAL_PREF, MED and next-hop information. The available paths depend on BGP propagation, policy and the architecture used to expose routes to the platform.

COMPUTE · CONTROL
Route Control Server (RCS)

Combines the available routing information with topology and policy to calculate routing decisions. Depending on the design, it may evaluate decisions from the perspective of particular routers or regions.

OUTPUT · ROUTING
Router RIB and FIB

Routers receive and process routing information, install eligible routes and program their local forwarding tables. Their forwarding hardware or software then sends packets toward the selected next hop.

1.2 Follow the route-decision flow

A useful way to understand the design is to trace one destination prefix from discovery to forwarding. The platform needs enough accurate information to make a decision, and the routers need a valid route and resolvable next hop to forward traffic successfully.

CONTROL-PLANE WORKFLOW
01 · Discover Learn IGP topology and BGP reachability.
02 · Correlate Combine paths, metrics and routing policy.
03 · Calculate Evaluate the appropriate route decision.
04 · Distribute Routers process routes and program forwarding state.
Simplified conceptual flow: actual RCP implementations differ in how they learn routes, compute decisions and distribute results.

1.3 Control plane versus data plane

RCP is not the same as a controller that forwards every packet centrally. It is primarily concerned with the computation and distribution of routing information. Once a router has installed a route and resolved its next hop, packets are normally forwarded locally.
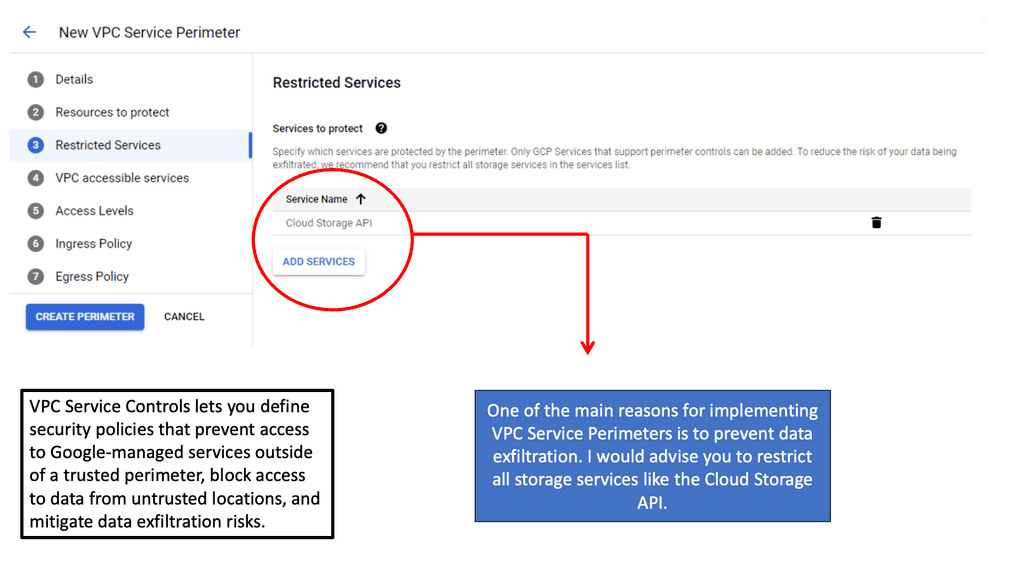
Function Control plane Data plane
Primary purpose Learn reachability and determine usable routes. Forward packets using installed forwarding entries.
RCP's role Correlate BGP information, topology and policy to calculate routing decisions. Not normally in the packet-by-packet forwarding path.
Router's role Maintain routing protocols and process received routing information. Resolve the destination against the FIB and forward toward the next hop.
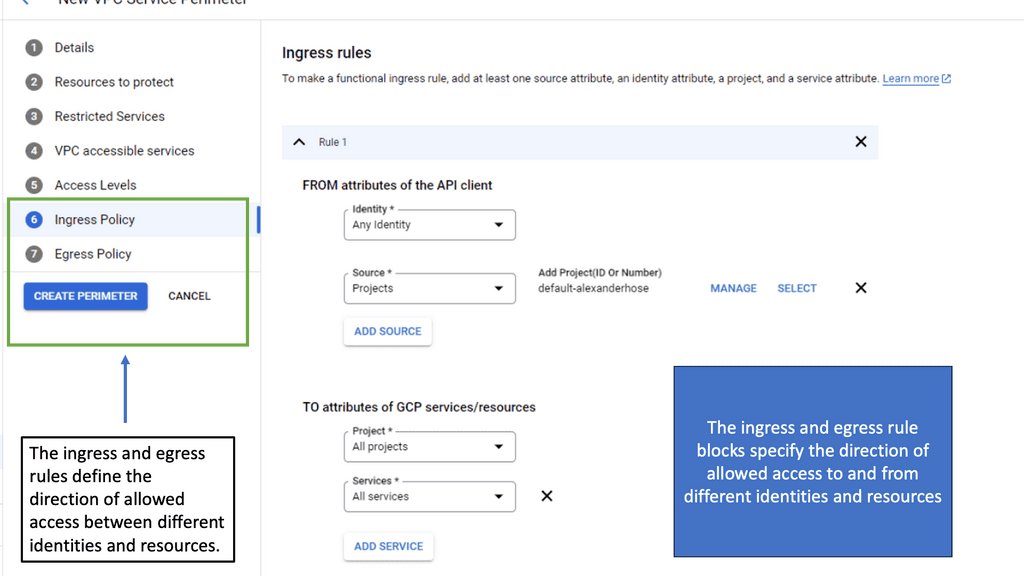
Evidence to inspect BGP routes, attributes, IGP topology, policy and controller state. Installed route, FIB entry, next-hop resolution and observed traffic.

1.4 Why the topology view matters

BGP path selection and internal path costs answer different questions. BGP attributes and policy influence which routes are eligible and preferred; IGP information helps establish internal reachability and costs to next hops. An RCP design attempts to use both kinds of information when calculating a decision.

Consider two external exits advertising the same destination. A central platform might know that Exit A is closer to one region while Exit B is closer to another. That information can support more appropriate router-specific decisions, provided the architecture can calculate and distribute those decisions correctly.

This does not mean that the lowest IGP cost always wins. LOCAL_PREF, AS_PATH, MED, next-hop reachability, policy and the implementation's decision process can affect the outcome. Engineers must inspect the full decision chain rather than infer the chosen route from one metric.

1.5 The design's dependency: accurate, current state

Centralised computation creates a strong dependency on the quality and freshness of the information being used. If a link fails but the controller still sees an older topology, it may calculate a route using a path that is no longer available. The resulting problem may appear as a route-selection issue even when the underlying cause is stale state or failed next-hop reachability.

  • Topology: Does the controller's view match the current IGP state?
  • Reachability: Are the BGP route and its next hop still valid?
  • Policy: Are route attributes and policy applied as intended?
  • Distribution: Did the target router receive and accept the intended route?
  • Forwarding: Does the local FIB reflect the route, and does traffic succeed?

1.6 RCP and Route Reflectors are not interchangeable terms

Route Reflectors address the scaling problem of a full iBGP mesh by reducing the number of required iBGP sessions. However, a reflector generally advertises selected paths according to its BGP decision process and configuration. Clients may therefore not receive every available path, and the reflector's routing perspective may differ from a client's perspective.

RCP was proposed as an alternative architectural approach to route computation and distribution, aiming to combine BGP information with topology knowledge. It should not be treated as a universal replacement for Route Reflectors or as a guarantee of optimal routing. Results depend on the implementation, information available, policies and network design.

Section 1 engineering takeaway

RCP separates routing-decision computation from packet forwarding. To understand a route, trace the complete chain: topology and BGP inputs → policy-aware calculation → route distribution → router RIB/FIB → verified traffic outcome. The next section compares the routing perspectives behind RCP and Route Reflectors.

How Does a Routing Control Platform Make a Routing Decision?

An RCP does not sit in the packet-forwarding path. It builds a broader view of routing and topology, computes policy-aware decisions, and communicates those decisions back to the routers.

Control Plane
Network State
IG
IGP / Topology
Link-state information gives the controller visibility of network connectivity and costs.
→
Routing Inputs
BG
BGP Information
The platform learns reachable prefixes, attributes and policy-relevant routing information.
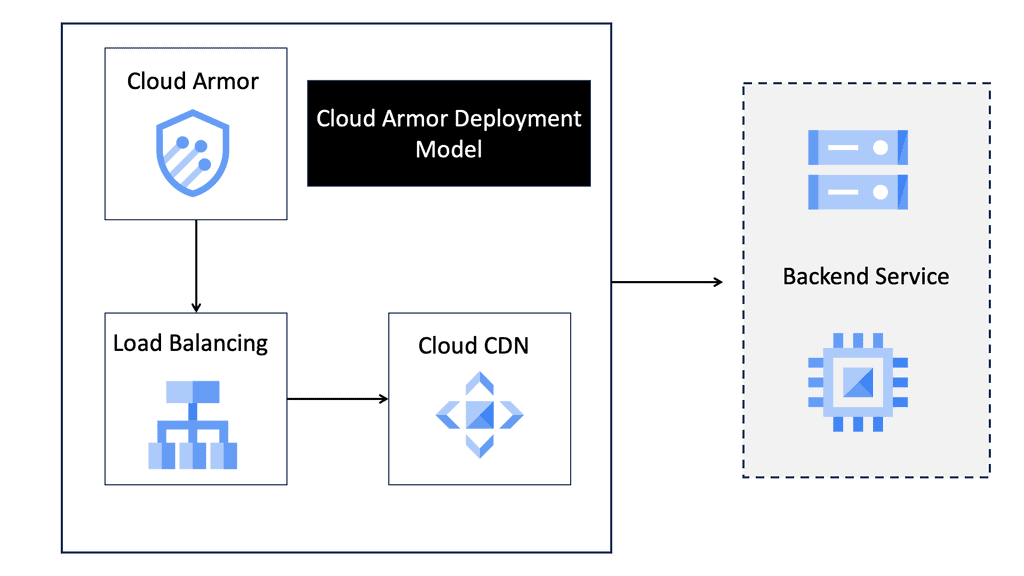
→
Control Platform
R
Route Control Server
Combines topology, BGP state and policy to calculate the appropriate route for each perspective.
→
Decision Output
IB
Routing Update
The resulting route decision is distributed to the relevant BGP speakers.
→
Forwarding
F
Router FIB
Routers continue to forward packets locally using the route installed in their forwarding plane.
Topology Visibility
The controller needs a complete network view.

The key RCP idea is visibility. Instead of making a routing decision from the limited perspective of one router, the platform combines IGP topology information with BGP reachability and policy information.

Data Plane Routers forward traffic locally
Control Plane RCP computes routing decisions
Design Goal Global visibility + scalable distribution
rcp> Collecting IGP topology + BGP reachability → building routing view...
ENGINEERING ORIENTATION · 02 / OBSERVE

Who has the right view of the network?

Choose a routing model to examine how its decision-making perspective can affect exit selection.

Available evidenceThe reflector learns BGP paths it receives and evaluates them using its own routing information and policy context.
Engineering questionDoes the selected path suit the forwarding router, or only the reflector's perspective?
What to verify: Compare the selected BGP path with the client router's IGP cost, next-hop reachability and local policy. A reflector's best path is not automatically the best path for every client.
Section 2 · Observe routing perspectives

Compare Route Reflector and RCP Perspectives

Two routers can reach the same destination but have different internal costs to the available exits. Understanding which routing information is visible—and whose perspective drives the decision—is essential when investigating unexpected BGP paths.

Route Reflectors improve iBGP scalability by reducing the need for a full mesh of internal BGP sessions. A Routing Control Platform takes a different architectural approach: it seeks to combine BGP reachability and policy with a wider view of the IGP topology when calculating routing decisions.

Observation is not the same as optimisation

A controller or reflector can only make a decision from the information and policies available to it. To establish whether a route is appropriate, compare the selected BGP path, the relevant router's IGP costs, next-hop reachability and the actual forwarding state.

2.1 What does a Route Reflector see?

In a conventional route-reflector design, clients advertise routes to the reflector, which applies BGP selection and reflection rules. The reflector generally advertises selected paths rather than every path it learns. This reduces control-plane overhead, but it can limit which alternatives are visible to clients.

SCALABILITY
Fewer iBGP sessions

Route reflection reduces the need for every internal BGP router to peer directly with every other router. This simplifies session management as the network grows.

PATH VISIBILITY
Selected paths are reflected

Standard route reflection can hide alternatives that were not selected by the reflector. Additional mechanisms or design choices may be needed when greater path diversity is required.

ROUTING PERSPECTIVE
The reflector has its own view

The reflector's BGP decision is made in its own routing context. Its IGP cost to an exit can differ from the cost seen by a client in another part of the network.

VALIDATION
Check the receiving router

The reflected route must still be evaluated in the receiving router's context, including its installed next hop, local forwarding state and reachability.

2.2 What does an RCP-style design add?

RCP was proposed to address limitations associated with distributed route computation and route reflection. By combining BGP information with an IGP topology view, a controller can attempt to calculate decisions that account for the internal cost from a particular router or region to an exit.

The goal is not simply to select one globally best exit. In some designs, the appropriate choice differs by router because internal topology and policy differ. A platform that models these differences may be able to make better-informed decisions than one relying solely on a single reflector's perspective.

Example · Two exits, two router perspectives
Exit A IGP cost from West: 20
IGP cost from East: 70
Exit B IGP cost from West: 40
IGP cost from East: 15

Illustrative IGP costs only. If the relevant BGP paths and policy permit these choices, West may favour Exit A while East may favour Exit B. Actual BGP selection is not determined by IGP cost alone.

2.3 Compare the models using evidence

Engineering question Route Reflector RCP-style approach
What is the routing input? Received BGP routes, path attributes, local topology and configured policy. BGP reachability and policy combined with a collected view of IGP topology.
How are decisions made? The reflector applies its BGP decision process to the paths it knows. The platform calculates decisions using its available routing information and design-specific logic.
Can path diversity be limited? Yes. Conventional reflection may advertise only selected paths. Potentially different path visibility, depending on how the platform learns and distributes routes.
Can topology freshness matter? Yes. Local IGP state and next-hop reachability affect routing outcomes. Yes. Stale or incomplete topology information can undermine a calculated decision.
What proves the outcome? Received route, BGP attributes, local route selection and FIB. Input freshness, computed decision, distributed route, router RIB/FIB and traffic results.

2.4 Why the shortest internal path may not win

A common troubleshooting mistake is to assume that the router must use the exit with the lowest IGP cost. BGP selection is policy-driven and considers several attributes and decision steps. LOCAL_PREF, AS_PATH, MED, next-hop validity and implementation-specific configuration can influence which route is selected before or alongside internal forwarding considerations.

For example, a higher LOCAL_PREF can cause one path to be preferred even when its exit is farther away in the IGP. That can be intentional: an organisation may prefer a particular transit provider for commercial, security or traffic-engineering reasons. The engineer must first determine the intended policy, then compare the observed decision against it.

2.5 Build a reliable observation checklist

  • Route availability: Does the relevant router know the destination prefix?
  • Path attributes: Which candidate routes are visible, and what are their LOCAL_PREF, AS_PATH and MED values?
  • Router perspective: What are the IGP costs and next-hop reachability from the affected router?
  • Reflection or distribution: Was the intended route actually advertised to the client?
  • Controller freshness: If RCP is involved, does its topology snapshot reflect the current network?
  • Forwarding state: Does the local FIB match the expected route, and can traffic reach the destination?
Section 2 engineering takeaway

Do not judge a routing architecture by the route it selects in isolation. Compare the paths it can see, the topology and policy it uses, the router for which the decision is intended, and the resulting forwarding state. In the interactive lab that follows, compare exit selection from different router perspectives before investigating a deliberately incorrect decision in Section 3.

RCP Incident: Why Did One Region Get the Wrong Exit?

A routing incident has been reported. Reachability is healthy, BGP sessions are established, but one region is taking a suboptimal exit. Examine the evidence and identify the real control-plane problem.

Troubleshooting
Incident Report

Traffic from the West region is exiting through Exit B even though Exit A is significantly closer from the West router's IGP perspective. No BGP session is down.

BGP Session Established
Prefix Reachability Available
West → Exit A 18 IGP cost
West → Exit B 61 IGP cost
RR Selected Path Exit B
Controller Topology Stale by 9 min

What is the most likely root cause?

Network State West is closer to Exit A
→
Control Decision RR perspective selects Exit B
→
Topology Visibility Controller information is stale
→
Corrective Action Refresh topology and compute per-router paths
Engineering Insight

RCP does not simply mean “put BGP in a central box.” The value is the ability to combine network-wide state with the perspective of the router that actually needs the decision. That requires accurate topology visibility. If the controller is stale, the centralised decision process can be consistently wrong even though BGP sessions and basic reachability remain healthy.

ENGINEERING ORIENTATION · 03 / INVESTIGATE

A route looks valid—but the chosen exit is wrong

Explore the evidence an engineer should check before changing routing policy.

Check session health firstAn established BGP session confirms that the peer relationship is up; it does not prove the selected exit is optimal for this router.
Section 3 · Investigate the incident

Why Did One Region Get the Wrong Exit?

A BGP session can be established, a destination prefix can be present, and traffic can still take an unexpected path. When a Routing Control Platform uses topology information to calculate route decisions, an engineer must investigate both the routing inputs and the state from which those decisions were derived.

The critical skill is separating a symptom from its cause. An unexpected exit does not automatically mean that BGP is broken, that the destination is unreachable, or that LOCAL_PREF needs to be changed. The route may have been calculated using an outdated view of the internal network.

Incident hypothesis

One region prefers Exit B even though Exit A is closer according to the current IGP topology. BGP remains established and the destination is available. The controller's topology snapshot is several minutes old. Treat stale state as a hypothesis to verify—not as a conclusion to assume.

3.1 Start with the observed symptom

Imagine a network with two external exits advertising the same destination. The West region currently forwards through Exit B. An engineer's current IGP measurements show a lower cost to Exit A, but the controller still reports Exit B as the selected path.

OBSERVED
Unexpected exit selection

Traffic from West uses Exit B even though current topology measurements suggest Exit A is closer. Confirm the actual forwarding path instead of relying only on a dashboard summary.

KNOWN EVIDENCE
BGP is still established

The relevant BGP neighbour is up and the destination prefix is available. This makes a completely failed BGP session less likely, but does not rule out route-policy or path-distribution problems.

TOPOLOGY
Current costs differ

West's measured IGP costs are 18 to Exit A and 61 to Exit B. These figures are evidence about internal reachability—not proof that BGP must choose Exit A.

SUSPICIOUS STATE
Controller data is stale

The controller's topology snapshot is reported to be nine minutes old. Verify that timestamp and compare it with the actual IGP state and recent topology changes.

3.2 Follow the evidence in a deliberate order

Use a consistent investigation sequence to avoid changing policy before the cause is known. Each check should either support or eliminate a plausible failure mode.

01 · Confirm Reproduce the wrong exit and identify the affected router, prefix and traffic direction.
02 · Inspect Check BGP neighbour state, candidate paths, attributes and route availability.
03 · Compare Compare current IGP costs and next-hop reachability with the controller's recorded view.
04 · Validate Reconcile the topology, recompute the decision and verify the router's installed route and traffic.

3.3 Distinguish the possible causes

Possible cause Evidence to collect What it tells you
BGP session failure Neighbour state, logs, route withdrawal and session history. A down session can affect route availability, but an established session does not prove that the selected path is correct.
Missing route or next hop Received prefix, next-hop resolution, RIB and FIB entries. The route may be unavailable or unusable even when other BGP sessions remain up.
Policy or BGP attributes LOCAL_PREF, AS_PATH, MED, import/export policy and candidate-path visibility. A policy decision may legitimately override an engineer's expectation based on IGP distance alone.
Stale controller topology Snapshot timestamp, topology events, current IGP database and controller refresh status. The controller may be calculating from an older network state than the routers are using.
Distribution or installation problem Computed decision, advertised route, received route and local FIB. The intended decision may not have reached the router or may not have been installed as expected.

3.4 Why stale topology can produce a wrong decision

A topology-aware controller can only calculate from the information it has. If a link changes, a metric is updated or a failure occurs, the controller needs to learn the change and update its model. Until that happens, the controller's estimate of the path to an exit may no longer match the actual network.

This is a consistency problem between the observed network and the model used for route computation. The controller might produce a decision that was reasonable under the old topology but is no longer appropriate under the current one.

The effect depends on the implementation and the failure. A stale snapshot does not always cause an incorrect exit, a forwarding loop or a blackhole. It becomes operationally significant when the outdated information changes the computed decision or leaves a next hop unreachable.

3.5 Remediate the cause, not just the symptom

If evidence confirms that the topology view is stale, the corrective action is to restore accurate information and recalculate the route decision using the platform's supported recovery procedure. Avoid applying a blanket LOCAL_PREF change simply to force the desired exit: that may mask the issue and create unintended results for other regions or destinations.

  • Refresh: Restore topology collection or synchronisation and confirm that the controller has received the current state.
  • Recompute: Recalculate the route decision with current topology, BGP routes and policy.
  • Redistribute: Confirm that the intended routing update reaches the correct router or client.
  • Verify installation: Inspect the selected route, next hop and local FIB.
  • Verify service: Test the actual traffic path and confirm reachability and performance meet expectations.

3.6 What counts as proof that the incident is resolved?

A green controller status or a successful recalculation is not sufficient on its own. The investigation is complete when the inputs are current, the selected route matches the intended policy and topology, the router installs the expected forwarding entry, and traffic follows the intended path.

Section 3 engineering takeaway

Investigate unexpected routing by correlating BGP state, route attributes, current IGP costs, controller topology freshness, route distribution and FIB state. When the controller's view is stale, repair and verify the data pipeline before changing routing policy. The incident lab that follows lets you test this reasoning against the West-region scenario.

ENGINEERING ORIENTATION · 04 / CORRELATE & OPERATE

Recovery is not proven by a single green status

Select the evidence you have verified. A routing change is complete only when the control-plane decision and forwarding outcome agree.

Evidence verified: 0 of 4
Engineering takeaway: correlate topology, route selection, forwarding state and observed traffic. A correct BGP decision alone does not guarantee end-to-end service recovery.

Correlate and Operate: Validate the Routing Decision

A routing decision is not proven correct simply because a controller calculated a path or a router received an update. Engineers need to connect the network's topology, BGP information, policy decision, installed forwarding state and observed traffic into one evidence chain.

That is the operational challenge behind a Routing Control Platform (RCP). Its value depends not only on the decision logic, but also on the freshness and consistency of the information used to make decisions—and on whether the resulting routes are distributed and installed as intended.

Follow the evidence across the control and data planes

When a region takes an unexpected exit, investigate the complete sequence. A controller may have selected a valid route using an outdated topology snapshot; a router may have received the intended route but rejected it through policy; or the routing table may be correct while forwarding still fails because of a next-hop or downstream connectivity problem.

01
Topology and reachability Check IGP state, link costs, BGP sessions and reachable prefixes.
02
Decision and policy Confirm route attributes, policy inputs, router perspective and calculation time.
03
Distribution and installation Check the advertised route, receiving router's RIB and installed FIB entry.
04
Traffic and stability Test the real path, service outcome, convergence and post-change behaviour.

Correlate symptoms with the right evidence

Observed symptom Evidence to correlate Engineering interpretation
Unexpected exit selected IGP costs, BGP attributes, policy, topology timestamp and router perspective The choice may reflect policy or a different network view—not necessarily a failed session.
Route missing from a router Received updates, import policy, next-hop reachability and routing table The route may be unavailable, filtered, ineligible or not installed.
Route present, traffic fails FIB entry, resolved next hop, interface state, ACLs and end-to-end probes Control-plane reachability does not by itself prove successful packet delivery.
Repeated path changes Update history, attribute changes, topology events, timers and policy interactions Look for interacting decisions or unstable inputs before changing attributes.

Understand the mechanisms around route selection

Hot-potato routing

Hot-potato routing generally favours the closest eligible exit according to the router's IGP view after higher-priority BGP decision criteria have been considered. Two routers can legitimately choose different exits because their IGP costs differ. A controller's view must therefore match the intended decision perspective; a low IGP cost alone does not override every BGP attribute or policy.

Multipath and BGP Add-Path

BGP multipath can allow multiple eligible paths to be installed or used, subject to implementation and configuration. BGP Add-Path allows multiple paths for a prefix to be advertised to a peer, helping reduce some path-visibility limitations. Neither feature automatically guarantees a better path or removes the need to validate policy, next-hop resolution and forwarding behaviour.

Next-hop tracking and MED

Next-hop tracking helps a router reassess route eligibility when next-hop reachability changes. MED can influence selection between routes from the same neighbouring AS, depending on the comparison rules and policy. In complex designs, interacting MED values, route reflection and changing topology can contribute to repeated path changes—but oscillation is not inevitable. Examine the actual attributes, decision order and update sequence before attributing a problem to MED.

Design boundary: RCP is a historically important control-plane architecture, not a universal modern product or a guaranteed replacement for Route Reflectors. Any centralised or controller-assisted design must account for failure modes, topology freshness, policy consistency, route distribution, controller redundancy and safe fallback behaviour.

A safe recovery workflow

Once the evidence points to stale or inconsistent topology, avoid making unrelated policy changes just to force a preferred exit. Correct the underlying input first, then confirm each downstream stage.

DetectReconcileRecomputeRedistributeVerify

  1. Capture the baseline. Record the affected prefix, selected exit, IGP costs, BGP attributes, relevant updates and current RIB/FIB state.
  2. Reconcile the network view. Confirm that topology data and reachability reflect current link and routing state. Check timestamps and the source of the data.
  3. Recompute and distribute. Re-evaluate the route using the intended policy and perspective, then verify that the expected decision reaches the affected routers.
  4. Verify installation. Confirm the route in the router's RIB, resolve the next hop and check the corresponding FIB entry. A received update is not the same as an installed route.
  5. Test the service and monitor. Use appropriate path probes or traffic tests, watch for unexpected updates or route churn, and retain a rollback path if the change causes regressions.

How do you know the incident is resolved?

Recovery is complete only when the intended route decision is visible, the forwarding entry is installed, the next hop is reachable, traffic behaves as expected and the system remains stable after convergence. Record the before-and-after evidence so that the fix can be explained and repeated—not merely assumed from a green status indicator.

Engineering takeaway Treat routing as an evidence chain: topology and reachability → BGP attributes and policy → route decision → route distribution → RIB/FIB installation → observed traffic. Verify every stage before declaring recovery.

Engineering conclusion · Routing control

From Centralised Routing Intelligence to Verified Forwarding

The Routing Control Platform concept highlights a fundamental challenge in BGP engineering: a route-selection decision is only as reliable as the network information, policy and router perspective behind it.

By combining BGP reachability with IGP topology information, an RCP can calculate routing decisions with a broader view of the network. The operational challenge is ensuring that this view remains accurate, the intended decisions reach the relevant routers, and the resulting forwarding state delivers the expected outcome.

Four engineering principles to take away

01 · Understand the architecture Separate topology discovery, BGP route information, route computation and packet forwarding.
02 · Compare perspectives Account for route visibility, IGP costs, BGP attributes and policy before explaining an exit choice.
03 · Investigate with evidence Distinguish session failure, missing reachability, policy effects, stale topology and installation problems.
04 · Verify the outcome Confirm the selected route, installed forwarding entry, next-hop reachability, traffic behaviour and stability.

The broader lesson for software-defined networking

RCP is a useful architectural case study in separating routing intelligence from packet forwarding. Its ideas remain relevant when evaluating controller-assisted networking, centralised policy, topology-aware path computation and modern network automation. However, an architecture should be judged against its actual implementation, failure handling, scalability and operational requirements—not treated as a universal replacement for established BGP designs.

The engineer's final test is not whether the controller calculated a route. It is whether the intended route was installed, traffic followed the expected path, and the network remained stable.

RCP vs Route Reflector: Which Exit Does Each Router Choose?

Experiment with the network perspective, IGP costs and routing policy. Then run the decision engine to see how a traditional Route Reflector and an RCP can produce different exit choices.

Interactive Lab
Ready: Change the conditions and run the decision engine.
Route Reflector Shared decision
Selected Exit Exit A
The RR makes the best-path decision from its own reference point and reflects that selected route to clients.
RR → Exit A 20
RR → Exit B 40
Result delivered to client Exit A
Routing Control Platform Per-router decision
Selected Exit Exit A
The RCP evaluates the available exits using the selected router's network perspective.
Router → Exit A 20
Router → Exit B 65
Decision comparison Same as RR
Routing Perspective Awaiting calculation
SOURCE WEST
RR1 RR view
ROUTER WEST VIEW
EXIT A EGRESS
EXIT B EGRESS
A: 20
B: 40
RR-selected path
Exit A
Exit B
Engineering Insight

The important difference is network perspective. A Route Reflector provides scalability by reflecting selected routes, while an RCP can calculate the appropriate route for the individual router using broader topology visibility.

☕
Support Network Insight
Help support the development of interactive networking labs, BGP simulations, and educational content.
Support the Project
data center security

BGP SDN – Centralized Forwarding

BGP SDN

The networking landscape has significantly shifted towards Software-Defined Networking (SDN) in recent years. With its ability to centralize network management and streamline operations, SDN has emerged as a game-changing technology. One of the critical components of SDN is Border Gateway Protocol (BGP), a routing protocol that plays a vital role in connecting different autonomous systems. In this blog post, we will explore the concept of BGP SDN and its implications for the future of networking.

Border Gateway Protocol (BGP) is a dynamic routing protocol that facilitates the exchange of routing information between different networks. It enables the establishment of connections and the exchange of network reachability information across autonomous systems. BGP is the glue that holds the internet together, ensuring that data packets are delivered efficiently across various networks.

Scalability and Flexibility: BGP SDN empowers network administrators with the ability to scale their networks effortlessly. By leveraging BGP's inherent scalability and SDN's programmability, network expansion becomes a seamless process. Additionally, the flexibility provided by BGP SDN allows for the customization of routing policies, enabling network administrators to adapt to changing network requirements.

Traffic Engineering and Optimization: Another significant advantage of BGP SDN is its capability to perform traffic engineering and optimization. With granular control over routing decisions, network administrators can efficiently manage traffic flow, ensuring optimal utilization of network resources. This results in improved network performance, reduced congestion, and enhanced user experience.

Dynamic Path Selection: BGP SDN enables dynamic path selection based on various parameters, such as network congestion, link quality, and cost. This dynamic nature of BGP SDN allows for intelligent and adaptive routing decisions, ensuring efficient data transmission and load balancing across the network.

Policy-Based Routing: BGP SDN allows network administrators to define routing policies based on specific criteria. This capability enables the implementation of fine-grained traffic management strategies, such as prioritizing certain types of traffic or directing traffic through specific paths. Policy-based routing enhances network control and enables the optimization of network performance for specific applications or user groups.

BGP SDN represents a significant leap forward in network management. By combining the robustness of BGP with the flexibility of SDN, organizations can unlock new levels of scalability, control, and optimization. Whether it's enhancing network performance, enabling dynamic path selection, or implementing policy-based routing, BGP SDN paves the way for a more efficient and agile network infrastructure.

Highlights: BGP SDN

BGP SDN, which stands for Border Gateway Protocol Software-Defined Networking, combines the power of traditional BGP routing protocols with the flexibility and programmability of SDN. It enables network administrators to have granular control over their routing decisions and allows for dynamic and automated network provisioning.

**BGP SDN Centralized Forwarding**

In today’s rapidly evolving digital landscape, network management and optimization have become more critical than ever. With the burgeoning demands for higher bandwidth, lower latency, and greater network reliability, traditional networking methods are increasingly finding themselves inadequate. This is where BGP SDN Centralized Forwarding comes into play, offering a revolutionary approach to network management by combining the strengths of Border Gateway Protocol (BGP) and Software-Defined Networking (SDN).

**Understanding BGP and SDN**

Before delving into the centralized forwarding aspect, it’s crucial to understand the foundational components: BGP and SDN. BGP, a robust and mature protocol, has been the cornerstone of the internet’s routing infrastructure for decades. It is responsible for making core routing decisions and ensuring data packets find their way across the networks of different organizations. On the other hand, SDN is a modern paradigm that separates the control plane from the data plane, allowing for more agile and flexible network management. By integrating these two technologies, we can create a more efficient and manageable network.

**The Need for Centralized Forwarding**

Traditional BGP implementations operate in a distributed manner, which, while reliable, can lead to inefficiencies and complexities in network management. Centralized forwarding through SDN changes this by offering a holistic view and control over the network. This centralized approach allows network administrators to implement policies and changes from a single point, reducing complexities and potential errors. This is especially beneficial in large-scale networks where consistent and efficient routing decisions are imperative.

Key BGP SDN Considerations:

Enhanced Flexibility and Scalability: BGP SDN brings unmatched flexibility to network operators. By decoupling the control plane from the data plane, it allows for dynamic rerouting and network updates without disrupting the overall network operation. This flexibility also enables seamless scalability as networks grow or evolve over time.

Improved Network Performance and Efficiency: With BGP SDN, network administrators can optimize traffic flow by dynamically adjusting routing decisions based on real-time network conditions. This intelligent traffic engineering ensures efficient resource utilization, reduced latency, and improved overall network performance.

Simplified Network Management: By leveraging programmability, BGP SDN simplifies network management tasks. Network administrators can automate routine configuration changes, implement policies, and troubleshoot network issues more efficiently. This leads to significant time and cost savings.

Rapid Deployment of New Services: BGP SDN enables faster service deployment by allowing administrators to define routing policies and service chaining through software. This eliminates the need for manual configuration changes on individual network devices, reducing deployment time and potential human errors.

Improved Network Security: BGP SDN provides enhanced security features by allowing fine-grained control over network access and traffic routing. It enables the implementation of robust security policies, such as traffic isolation and encryption, to protect against potential threats.

BGP-based SDN

BGP SDN, also known as BGP-based SDN, is an approach that leverages the strengths of BGP and SDN to enhance network control and management. Unlike traditional networking architectures, where individual routers make routing decisions, BGP SDN centralizes the control plane, allowing for more efficient routing and dynamic network updates. By separating the control plane from the data plane, operators can gain greater visibility and control over their networks.

BGP SDN offers a range of features and benefits that make it an attractive choice for network operators. First, it provides enhanced scalability and flexibility, allowing networks to adapt to changing demands and traffic patterns. Second, operators can easily define and modify routing policies, ensuring optimal traffic distribution across the network.

Another notable feature is the ability to enable network programmability. Using APIs and controllers, network operators can dynamically provision and configure network services, making deploying new applications and services easier. This programmability also opens doors for automation and orchestration, simplifying network management and reducing operational costs.

Use Cases of BGP SDN: BGP SDN has found applications in various domains, from data centers to wide-area networks. In data centers, it enables efficient load balancing, traffic engineering, and rapid service deployment. It also allows for the creation of virtual networks, enabling secure multi-tenancy and resource isolation.

BGP SDN brings benefits such as traffic engineering and improved network resilience in wide-area networks. It enables dynamic path selection, optimizes traffic flows, and reduces congestion. Additionally, BGP SDN can enable faster network recovery during failures, ensuring uninterrupted connectivity.

BGP vs SDN:

BGP, also known as the routing protocol of the Internet, plays a vital role in facilitating communication between autonomous systems (AS). It enables the exchange of routing information and determines the best path for data packets to reach their destinations. With its robust and scalable design, BGP has become the go-to protocol for inter-domain routing.

SDN, on the other hand, is a paradigm shift in network architecture. SDN centralizes network management and allows for programmability and flexibility by decoupling the control plane from the forwarding plane. With SDN, network administrators can dynamically control network behavior through a centralized controller, simplifying network management and enabling rapid innovation.

Synergizing BGP and SDN

When BGP and SDN converge, the result is a potent combination that transcends the limitations of traditional networking. SDN’s centralized control plane empowers network operators to control BGP routing policies dynamically, optimizing traffic flow and enhancing network performance. By leveraging SDN controllers to manipulate BGP attributes, operators can quickly implement traffic engineering, load balancing, and security policies.

The Role of SDN:

In contrast to the decentralized control logic that underpins the construction of the Internet as a complex bundle of box-centric protocols and vertically integrated solutions, software-defined networking (SDN) advocates the separation of control logic from hardware and its centralization in software-based controllers. Introducing innovative applications and incorporating automatic and adaptive control into these fundamental tenets can ease network management and enhance user experience.

Recap Technology: EBGP over IBGP

EBGP, or External Border Gateway Protocol, is a routing protocol typically used between different autonomous systems (AS). It facilitates the exchange of routing information between these AS, allowing efficient data transmission across networks. EBGP’s primary characteristic is that it operates between routers in different AS, enabling interdomain routing.

IBGP, or Internal Border Gateway Protocol, operates within a single autonomous system (AS). It establishes peering relationships between routers within the same AS, ensuring efficient routing within the network. Unlike EBGP, IBGP does not involve exchanging routes between different AS; instead, it focuses on sharing routing information between routers within the same AS.

While both EBGP and IBGP serve to facilitate routing, there are crucial differences between them. One significant distinction lies in the scope of their operation. EBGP connects routers across different AS, making it ideal for interdomain routing. On the other hand, IBGP connects routers within the same AS, providing efficient intradomain routing.

EBGP is commonly used by internet service providers (ISPs) to exchange routing information with other ISPs, ensuring global reachability. It enables autonomous systems to learn about and select the best paths to reach specific destinations. IBGP, on the other hand, helps maintain synchronized routing information within an AS, preventing routing loops and ensuring efficient internal traffic flow.

BGP Configuration

Recap Technology: BGP Route Reflection

Understanding BGP Route Reflection

BGP (Border Gateway Protocol) is a crucial routing protocol in large-scale networks. However, route propagation can become cumbersome and resource-intensive in traditional BGP setups. BGP route reflection offers an elegant solution by reducing the number of full-mesh connections needed in a network.

By implementing BGP route reflection, network administrators can achieve significant advantages. Firstly, it reduces resource consumption by eliminating the need for every router to maintain full mesh connectivity. This leads to improved scalability and reduced overhead. Additionally, it enhances network stability and convergence time, ensuring efficient routing updates.

To implement BGP route reflection, several key steps need to be followed. Firstly, identify the routers that will act as route reflectors in the network. These routers should have sufficient resources to handle the increased routing information. Next, configure the route reflectors and their respective clients, ensuring proper peering relationships. Finally, monitor and fine-tune the route reflection setup to optimize performance.
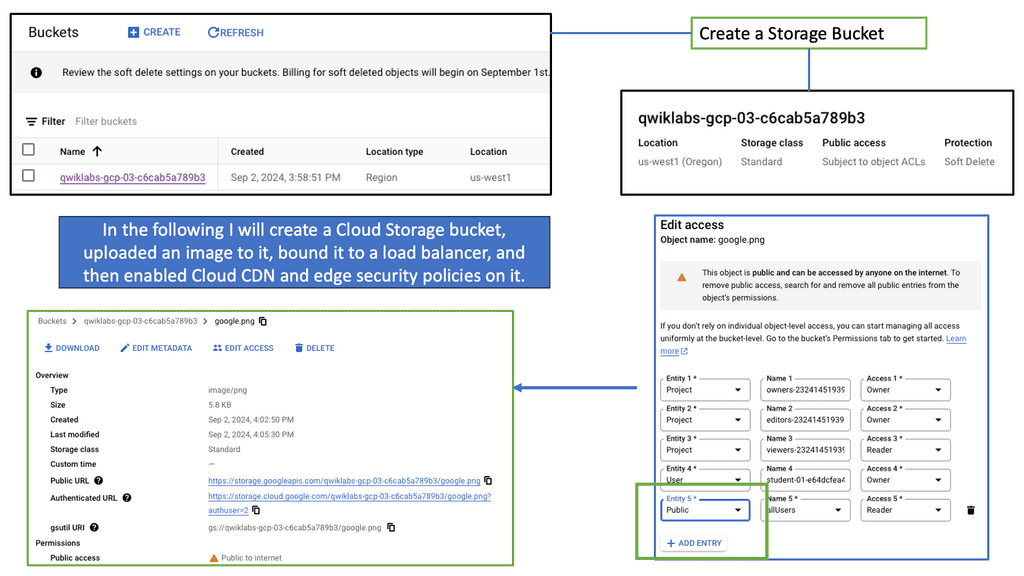
Challenges to Networking

Over the past few years, there has been a growing demand for a new approach to networking to address the many issues associated with current networks. According to the SDN approach, networking operations can be simplified, network management can be optimized, and innovation and flexibility can be introduced.

According to Kim and Feamster (2013), four key reasons can be identified for the problems encountered in managing existing networks:

(1) Complex and low-level network configuration: Network configuration is a distributed task typically configured vendor-specific at the low level. Moreover, network operators constantly change configurations manually due to the rapid growth of the network and changing networking conditions, adding complexity and introducing additional configuration errors to the configuration process.

(2) Growing complexity and dynamic network state: networks are becoming increasingly complex and more extensive. Moreover, as mobile computing trends continue to develop and network virtualization (Bari et al. 2013; Alam et al. 2020) and cloud computing (Zhang et al. 2010; Sharkh et al. 2013; Shamshirband et al. 2020) become more prevalent, the networking environment becomes even more dynamic as hosts are constantly moving, arriving and departing due to the flexibility offered by virtual machine migration, which results in a rapid and significant change of traffic patterns and network conditions.

(3) Exposed complexity: today’s large-scale networks are complicated by distributed low-level network configuration interfaces that expose great complexity. Many control and management features are implemented in hardware, which generates this complexity.

(4) Heterogeneous: Current networks contain many heterogeneous network devices, including routers, switches, and middleboxes of various kinds. As a result, network management becomes more complex and inefficient because each appliance has its proprietary configuration tools.

Because legacy networks’ static, inflexible architecture is ill-suited to cope with today’s increasingly dynamic networking trends and meet modern users’ QoE expectations, network management is becoming increasingly challenging. As a result, complex, high-level policies must be adopted to adapt to current networking environments, and network operations must be automated to reduce the tedious work of low-level device configuration.

Traffic Engineering

Networks with multiple Border Gateway Protocol (BGP) Autonomous Systems (ASNs) under the same administrative control implement traffic engineering with policy configurations at border edges. Policies are applied on multiple routers distributedly, which can be hard to manage and scale. Any per-prefix traffic engineering changes may need to occur on various devices and levels.

A new BGP Software-Defined Networking (SDN) solution introduced by P. Lapukhov and E. Nkposong proposes a centralized routing model. It introduces the concept of a BGP SDN controller, also known as an SDN BGP controller with a routing control platform. No protocol extensions or additional protocols are needed to implement the SDN architecture. BGP is employed to push down new routes and peers iBGP with all existing BGP routers.

BGP-only Network

A BGP-only network has many advantages, and this solution promotes a more stable Layer 3-only network, utilizing one control plane protocol – BGP. BGP captures topology discovery and links up/down events. BGP can push different information to different BGP speakers, while an IGP has to flood the same LSA throughout the IGP domain.

For additional pre-information, you may find the following helpful:

  1. OpenFlow Protocol
  2. What Does SDN Mean
  3. BGP Port 179
  4. WAN SDN

BGP SDN

BGP Peering Session Overview

In BGP terminology, a BGP neighbor relationship is called a peer relationship, unlike OSPF and EIGRP, which implement their transport mechanism. In place of TCP, BGP utilizes BGP TCP port 179 as its transport protocol. A BGP peering session can only be established between two routers after a TCP session has been established between them. Selecting a BGP session consists of establishing a TCP session and exchanging BGP-specific information to establish a BGP peering session.

A TCP session operates on a client/server model. On a specific TCP port number, the server listens for connection attempts. Upon hearing the server’s port number, the client attempts to establish a TCP session. Next, the client sends a TCP synchronization (TCP SYN) message to the listening server to indicate that it is ready to send data.

Upon receiving the client’s request, the server responds with a TCP synchronization acknowledgment (TCP SYN-ACK) message. Finally, the client acknowledges receipt of the SYN-ACK packet by sending a simple TCP acknowledgment (TCP ACK). TCP segments can now be sent from the client to the server. As part of this process, TCP performs a three-way handshake.

BGP explained
Diagram: BGP explained. The source is IPcisco.

So, how does BGP work? BGP is a path-vector protocol that stores routes in the Routing Information Bases (RIBs). The RIB within a BGP speaker consists of three parts:

  1. The Adj-RIB-In,
  2. The Loc-RIB,
  3. The Adj-RIB-Out.

The Adj-RIB-In stores routing information learned from the inbound UPDATE messages advertised by peers to the local router. The routes in the Adj-RIB-In define routes that are available to the path decision process. The Loc-RIB contains routing information the local router selected after applying policy to the routing information in the Adj-RIB-In.

The Emergence of BGP in SDN:

Software-defined networking (SDN) introduces a paradigm shift in managing and operating networks. Traditionally, network devices such as routers and switches were responsible for handling routing decisions. However, with the advent of SDN, the control plane is decoupled from the data plane, allowing for centralized management and control of the network.

BGP plays a crucial role in the SDN architecture by acting as a control protocol that enables communication between the controller and the network devices. It provides the intelligence and flexibility required for orchestrating network policies and routing decisions in an SDN environment.

Layer-2 and Layer-3 Technologies

Traditional forwarding routing protocols and network designs comprise a mix of Layer 2 and 3 technologies. Topologies resemble trees with different aggregation levels, commonly known as access, aggregation, and core. IP routing is deployed at the top layers, while Layer 2 is in the lower tier to support VM mobility and other applications requiring Layer 2 VLANs to communicate.

Fully routed networks are more stable as they confine the Layer 2 broadcast domain to certain areas. Layer 2 is segmented and confined to a single switch, usually used to group ports. Routed designs run Layer 3 to the Top of the Rack (ToR), and VLANs should not span ToR switches. As data centers grow in size, the stability of IP has been preferred over layer 2 protocols.

  • A key point: Traffic patterns

Traditional traffic patterns leave the data center, known as north-to-south traffic flow. In this case, conventional tree-like designs are sufficient. Upgrades consist of scale-out mechanisms, such as adding more considerable links or additional line cards. However, today’s applications, such as Hadoop clusters, require much more server-to-server traffic, known as east-to-west traffic flow.

Scaling up traditional tree topologies to match these traffic demands is possible but not an optimum way to run your network. A better choice is to scale your data center horizontally with a CLOS topology ( leaf and spine ), not a tree topology.

Leaf and spine topologies permit equidistant endpoints and horizontal scaling, resulting in a perfect combination for optimum east-to-west traffic patterns. So, what layer 3 protocol do you use for your routing design? An Interior Gateway Protocol (IGP), such as ISIS or OSPF? Or maybe BGP? BGP’s robustness makes it a popular Layer 3 protocol for reducing network complexity.

How BGP works with BGP SDN: Centralized forwarding

What is BGP protocol in networking? Regarding internal data structures, BGP is less complex than a link-state IGP. Instead of forming adjacency maintenance and controls, it runs all its operations over Transmission Control Protocol (TCP) and uses TCP’s robust transport mechanism.

BGP has considerably less flooding overhead than IGPs, with a single flooding domain propagation scope. For these reasons, BGP is great for reducing network complexity and is selected as this SDN solution’s singular control plane mechanism.

Peter has written a draft called “Centralized Routing Control in BGP Networks Using Link-State Abstraction,” which discusses the use case of BGP for centralized routing control in the network.

The main benefit of the architecture is centralized rather than distributed control. There is no need to configure policies on multiple devices. All changes are made with an API in the controller.

BGP SDN
Diagram: BGP SDN. The inner workings.

A link-state map 

The network looks like a collection of BGP ASN, and the entire routing is done with BGP only. First, BGP builds a link-state map of the network in the controller memory.

Then, they use BGP to discover the topology and notice link-up and link-down events. Instead of installing a 5-tuple that can install flows based on the entire IP header, the BGP SDN solution offers destination-based forwarding only. For additional granularity, implement BGP flow spec, RFC 55745, entitled “Dissemination of Flow Specification Rules.” 

Routing Control Platform

The proposed method was inspired by the Routing Control Platform (RCP). The RCP platform uses a controller-based function and selects BGP routes for the routers in an AS using a complete view of the available routes and IGP topology. The RCP platform has properties similar to those of the BGP SDN solution.

Both run iBGP peers to all routers in the network and influence the default topology by changing the controller and pushing down new routes. However, a significant difference is that the RCP has additional IGP peerings. It’s not a BGP-only network. BGP SDN promotes a single control plane of BGP without any IGPs.

BGP detects health, builds a link-state map, and represents the network to a third-party application as multiple topologies. You can map prefixes to different topologies and change link costs from the API.

Multi-Topology view

The agent builds the link-state database and presents a multi-topology view of this data to the client applications. You may clone this topology and give certain links higher costs, mapping some prefixes to this new non-default topology. The controller pushes new routes down with BGP.

The peering is based on iBGP, so new routes are set with a better Local Preference, enabling them to be selected higher in the BGP path decision process. It is possible to do this with eBGP, but iBGP can be more accessible. With iBGP, you don’t need to care about the next hops.

BGP and OpenFlow

What is OpenFlow? BGP works like OpenFlow and pushes down the forwarding information. It populates routes in the forwarding table. Instead of using BGP in a distributed fashion, they centralize it. One main benefit of using BGP over OpenFlow is that you can shut the controller down, and regular BGP operation continues on the network.
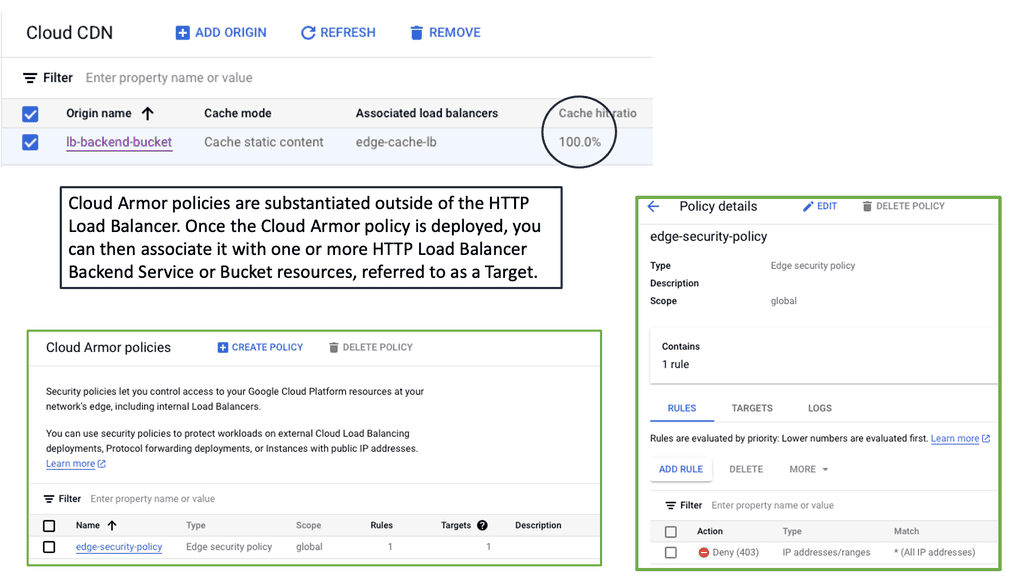
But if you transition to an OpenFlow configuration, you cannot roll back as quickly as you could with BGP. Using BGP inband has great operational benefits. It is a great design by P. Lapukhov. There is no need to deploy BGP-LS or any other enhancements to BGP.

Closing Points on BGP SDN

Border Gateway Protocol (BGP) and Software-Defined Networking (SDN). BGP has long been the backbone of internet routing, while SDN is redefining how we manage and configure networks. But what happens when these two paradigms intersect? The convergence of BGP and SDN centralized forwarding presents an exciting frontier in network management, offering enhanced flexibility and control.

BGP is the protocol that holds the internet together by deciding the best paths for data to travel from source to destination across autonomous systems. It’s like the GPS for the internet, ensuring data packets find their way. However, traditional BGP lacks agility, often requiring manual configuration and offering limited adaptability to rapid network changes. This rigidity can lead to inefficiencies and delays, particularly in large-scale networks.

Enter SDN, a transformative approach that decouples the network control plane from the data plane, allowing for centralized management of network resources. SDN introduces a layer of abstraction that provides network administrators with the flexibility to program and configure network behavior dynamically, using software-based controllers. This means that network policies can be adjusted on the fly, responding swiftly to changing demands and conditions.

Combining BGP with SDN centralized forwarding brings the best of both worlds. SDN controllers can leverage BGP for routing decisions while maintaining centralized control over network policies and configurations. This synergy allows for automated, real-time optimization of routing paths, better resource allocation, and improved network resilience. In this hybrid model, networks become more efficient, scalable, and responsive to the needs of modern applications and services.

While the integration of BGP and SDN centralized forwarding offers numerous advantages, it also presents challenges. Compatibility issues between legacy systems and modern SDN architectures can arise, requiring careful planning and execution. Additionally, security considerations must be addressed to protect the centralized control plane from potential threats. However, the potential benefits—such as enhanced performance, reduced operational costs, and greater adaptability—make overcoming these hurdles worthwhile.

Summary: BGP SDN

In the ever-evolving networking world, two key technologies have emerged as game-changers: Border Gateway Protocol (BGP) and Software-Defined Networking (SDN). In this blog post, we delved into the intricacies of these powerful tools, exploring their functionalities, benefits, and impact on the networking landscape.

Understanding BGP

BGP, an exterior gateway protocol, plays a crucial role in enabling communication between different autonomous systems on the internet. It allows routers to exchange information about network reachability, facilitating efficient routing decisions. With its robust path selection mechanisms and ability to handle large-scale networks, BGP has become the de facto protocol for inter-domain routing.

Exploring SDN

SDN, on the other hand, represents a paradigm shift in network architecture. SDN centralizes network management and provides a programmable and flexible infrastructure by decoupling the control plane from the data plane. SDN empowers network administrators to dynamically configure and manage network resources through controllers and open APIs, leading to greater automation, scalability, and agility.

The Synergy Between BGP and SDN

While BGP and SDN are distinct technologies, they are not mutually exclusive. They can complement each other to enhance network performance and efficiency. SDN can leverage BGP’s routing capabilities to optimize traffic flows and improve network utilization. Conversely, BGP can benefit from SDN’s centralized control, enabling faster and more adaptive routing decisions.

Benefits and Challenges

The adoption of BGP and SDN brings numerous benefits to network operators. BGP provides stability, scalability, and fault tolerance in inter-domain routing, ensuring reliable connectivity across the internet. SDN offers simplified network management, quick provisioning, and the ability to implement security policies at scale. However, implementing these technologies may also present challenges, such as complex configurations, interoperability issues, and security concerns that need to be addressed.

Conclusion:

In conclusion, BGP and SDN have revolutionized the networking landscape, offering unprecedented control, flexibility, and efficiency. BGP’s role as the backbone of inter-domain routing, combined with SDN’s programmability and centralized management, paves the way for a new era of networking. As technology advances, a deep understanding of BGP and SDN will be essential for network professionals to adapt and thrive in this rapidly evolving domain.

nuage-logo-black-background-hr

Smarter Networks: Nuage Networks & SD-WAN Part 2


Nuage Networks: SD-WAN 

Traditional WANs hinder business operations and don’t meet the demands of today’s applications. A new emerging WAN architecture called SD-WAN replaces existing WANs with a business-aware approach to networking. This approach is now thoroughly adopted by Nuage Networks, and their SD-WAN solution solves the limitations of conventional WANs.

Nuage Networks SD-WAN offers a centralized solution, adding intelligence to the WAN in forwarding, policy, and monitoring. Nuage understands all the existing WAN pitfalls, and their SD-WAN solution enables policy-based traffic forwarding. If you make routing aware of the application, you can steer traffic down different links based on business logic, not just destination-based forwarding. This is a two-part post – Part 1 introduces the challenges of traditional WAN, and Part 2 (this post) describes Nuage Networks SD-WAN solution. 


For additional pre-information, you may find the following helpful:

  1. SD-WAN Overlay
  2. SD-WAN Tutorial
  3. WAN Virtualization
  4. SD WAN Security


WAN edge into the data center

Nuage Networks are one of the first companies to incorporate the WAN edge into the data center, enabling one large network fabric and management entity. The entire solution is Virtualized Network Services (VNS), which uses many components from the existing Virtualized Service Platform (VSP). The WAN is no longer managed with complex control planes, Policy Based Routing (PBR), IP SLA, enhanced object tracking, and per-link QoS configurations. As the WAN is now combined with the internal data center, it can be managed as one entity via a central controller, known as Virtualized Services Controller (VSC), and a policy engine, known as Virtualized Service Directory (VSD). 

Nuage networks


A central viewpoint can now set policy based on business logic. Policies are then pushed down to the end nodes, Network Service Gateways (NSG), to carry out data plane forwarding. All these components combined create an overlay network – a network built on top of another. Overlay networking provides flexible topologies, allowing the application to control the network, not the network controlling the application. 


Design Principles 

Nuage’s SD-WAN solution might be new, but the control plane functions have been lifted from the 15-year-old source code of the 7750 SR Alcatel-Lucent routers. This provides network engineers with the comfort of knowing the IP stack is robust and proven in some of the largest global networks. 

Nuage employs intelligent product design principles and does not try to reinvent the wheel. They use proven and field-tested protocols as much as possible. Virtual Extensible LAN (VXLAN) and Internet Protocol Security (IPsec) are employed to form the Layer 2 & Layer 3 overlay. For scale-out controller clustering, MP-BGP is implemented between controllers.

MP-BGP is an enhancement to native BGP. BGP supports only unicast IPv4, while MP-BGP supports a wide variety of protocols. It is extensible and can carry a wide variety of information. The data plane NSG nodes are based on the popular Open vSwitch but optimized for enhanced performance. For optimized flow forwarding, Nuage decided to implement OpenFlow with proprietary extensions. 
Nuage Networks SD-WAN transforms the WAN into a business-aware network, mapping application requirements to the network. This allows the creation of independent topologies per application. For example, mission-critical applications may use expensive leased lines, while lower-priority applications can use inexpensive best-effort Internet links. Previously, the application had to match and “fit” into the network, but with a Nuage SD-WAN, the application now controls the network topology. Multiple independent topologies per application is a key drivers for SD-WAN.
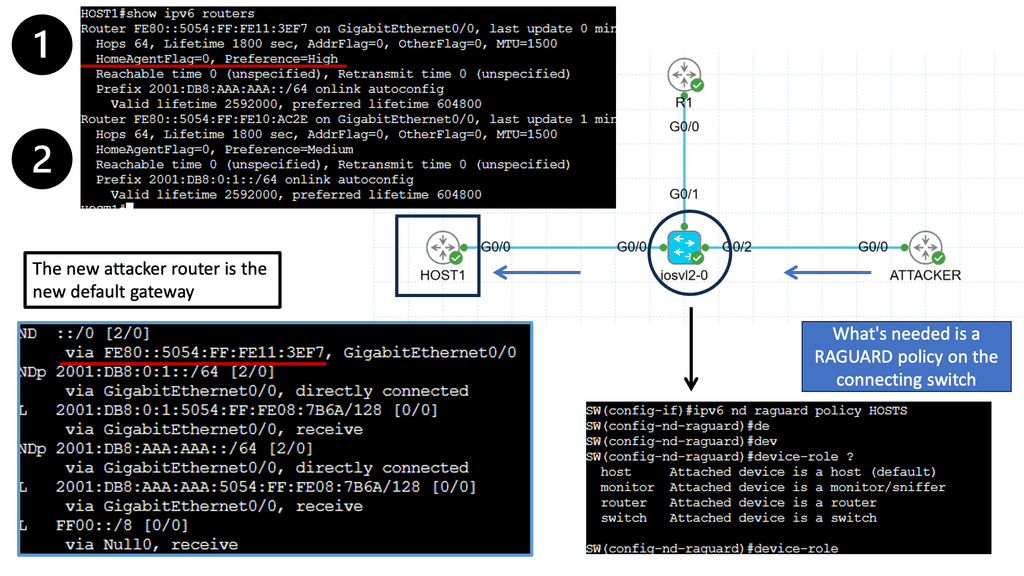
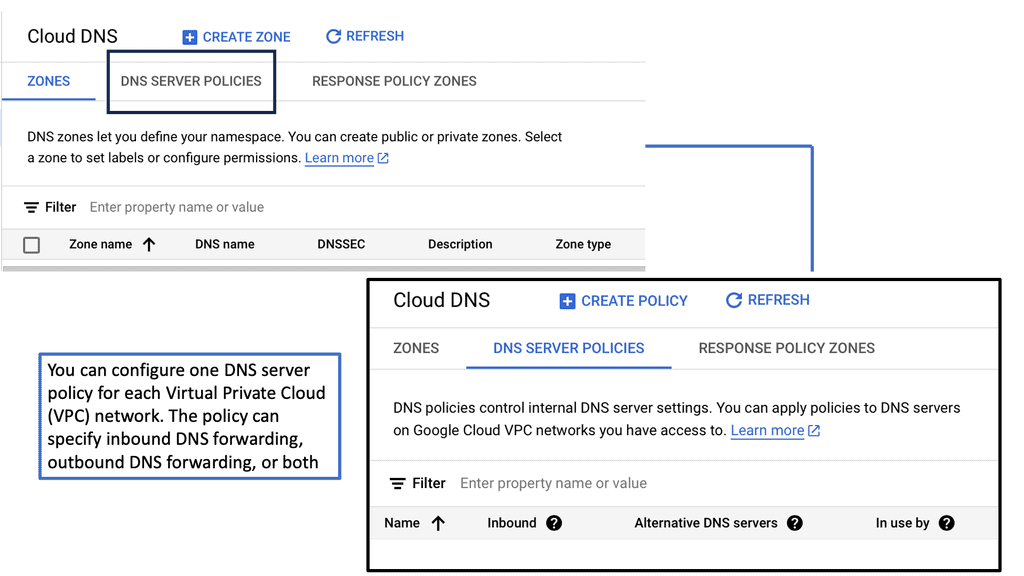
“Nuage Networks sponsor this post. All thoughts and opinions expressed are the authors.”