data center design

Open Networking

ENGINEERING GUIDE · OPEN NETWORKING

Open Networking — From Disaggregated Hardware to Programmable Fabrics

Open networking is not a single product or protocol. It is an architectural approach that separates hardware, network software, control, telemetry and automation so infrastructure can become more programmable, interoperable and adaptable.

The important engineering shift is not simply replacing a proprietary platform. It is separating the components of the network so that hardware, software, control and operations can evolve independently.
01 · DISAGGREGATE

Separate Hardware

Treat switching hardware and network software as independently selectable components.

02 · PROGRAM

Expose Control

Use protocols, APIs and software interfaces to make network behaviour programmable.

03 · AUTOMATE

Operate at Fabric Scale

Move from box-by-box configuration toward repeatable desired-state workflows.

04 · OBSERVE

Measure Network State

Use telemetry and analytics to understand actual network behaviour continuously.

ENGINEERING MODEL
HARDWARE → NETWORK OS → CONTROL → AUTOMATION → TELEMETRY → ANALYTICS
ENGINEERING QUESTION

Can the network change without requiring every layer to be redesigned or every device to be configured independently?

Open networking moves intelligence toward software, automation and common interfaces.
White-Box Networking Open NOS SONiC FRRouting BGP EVPN VXLAN Leaf-Spine OpenConfig gNMI Automation Telemetry
Interactive Open Networking Architecture

Open Networking Architecture Explorer

Explore how open networking separates hardware, network software, control, telemetry and automation to create a more flexible, programmable and vendor-neutral infrastructure.
From hardware dependency to programmable fabric
Hardware
→
Network Software
→
Control
→
Operations
Disaggregation creates independence
DATA PLANE Forward packets
CONTROL PLANE Build routing state
MANAGEMENT Automate & observe
HW
White-Box Hardware
Disaggregated infrastructure

Open networking separates the physical switching platform from the software controlling it, allowing organizations greater freedom in hardware selection.

Layer Data plane
Principle Hardware / software separation
Benefit Vendor flexibility
Result Reduced lock-in
OPEN NETWORKING PRINCIPLE
Hardware becomes a replaceable platform rather than the sole source of network intelligence.

Why disaggregation matters

Traditional networking commonly couples hardware, operating system and features into a single vendor stack. Open networking separates these functions so each layer can evolve independently.

OPEN STANDARDS Common protocols and models allow different components to interoperate.
OPEN SOFTWARE Network operating systems and routing software can evolve independently of hardware.
OPEN APIs Automation systems can program and integrate the network.
OPEN TELEMETRY Network state becomes observable through streaming data and common models.
Open Networking · Interactive Use Case
How the Open Fabric Works
See how a modern leaf-spine fabric separates the routed underlay from the VXLAN overlay while BGP and EVPN provide the control plane.
L3 UNDERLAY
VXLAN OVERLAY
WORKLOADS
BGP EVPN CONTROL PLANE
VNI 10100 · VXLAN SEGMENT
SPINE 1
S1
Transit
SPINE 2
S2
Transit
LEAF 1
L1
VTEP
LEAF 2
L2
VTEP
VM-A
Host A
10.10.1.10
VM-B
Host B
10.10.1.20
VM-C
Host C
10.10.1.30
Open Fabric
Click a device to explore its role in the open fabric.
Underlay
IP + BGP
Control Plane
BGP EVPN
Overlay
VXLAN VNI 10100
Architecture
Leaf / Spine
BGP Underlay Routed IP connectivity between leaf and spine switches.
EVPN Control Plane BGP distributes MAC/IP and endpoint reachability information.
VXLAN Overlay VXLAN carries logical network segments across the IP fabric.
VTEP Leaf switches encapsulate and decapsulate VXLAN traffic.
01 · DEFINE · ARCHITECTURE

What Does “Open” Actually Mean?

Open networking begins by separating the components that traditionally arrive as one integrated platform: hardware, network operating system, control protocols and operational tooling. The engineering objective is reduced coupling, greater choice and programmable interfaces.

Engineering Question Can each layer evolve without forcing the entire network architecture to change with it?
01 · DEFINE · OPEN NETWORKING ARCHITECTURE

Open Networking Starts With Separation

Open networking begins by separating the functions that traditional networking often bundles together. Hardware provides forwarding capability, network software provides operating and routing functions, control protocols build network state, and automation and telemetry provide the operational feedback loop.

ARCHITECTURAL LAYERS
HARDWARE Switching silicon, ports, memory and physical forwarding resources.
NETWORK OS Operating system, routing software, interfaces and platform services.
CONTROL BGP, OSPF, IS-IS, EVPN and other mechanisms that establish network state.
OPERATIONS APIs, automation, configuration management, telemetry and analytics.
OPEN NETWORKING PRINCIPLES
Hardware Independence

Hardware can become a replaceable platform rather than defining the entire software stack.

Software Choice

Network operating systems and routing software can be selected according to operational requirements.

Open Interfaces

Standards, APIs and models allow systems to exchange state and participate in common workflows.

Operational Automation

Configuration and lifecycle operations can move from individual devices toward repeatable fabric-wide processes.

ENGINEERING PRINCIPLE

Open networking is not simply “using open source.” The architectural objective is to reduce unnecessary coupling between hardware, software, control and operations so that each layer can evolve without forcing the entire network to change with it.

DATA PLANE
Forward the packet

The forwarding infrastructure moves traffic according to the state programmed into the network.

CONTROL PLANE
Build network state

Routing protocols and control systems determine reachability and distribute network information.

MANAGEMENT PLANE
Operate the fabric

APIs, automation and telemetry provide the mechanisms for configuring, observing and validating the network.

02 · DISAGGREGATE · PLATFORM

Separate the Platform From the Network Software

Disaggregation separates the physical switching platform from the network software that controls it. White-box hardware, open network operating systems and routing software can therefore become independent architectural choices rather than a single fixed product.

Engineering Question Which parts of the network platform actually need to come from the same supplier?
ENGINEERING LAB · 01 · DEFINE

Open Networking Architecture Explorer

Explore the four architectural layers that turn a traditional integrated network platform into a more modular and programmable system. Select a layer or use the architecture tabs to inspect what becomes separated and why that separation matters.

OPEN NETWORKING STACK
● MODULAR
LAYER INSPECTOR
SELECTED
01 · PLATFORM

Hardware

Open networking separates the physical switching platform from the software that operates it. This creates greater freedom in choosing the underlying hardware platform, but also introduces responsibility for validating compatibility and lifecycle support.

Network software
Platform choice
Integration & support
White-box switching
OPENNESS SIGNAL

The hardware platform no longer has to dictate which network software is used.

02 · DISAGGREGATE · HARDWARE, NOS & CONTROL PLANE

Separate the Platform From the Network Software

Disaggregation separates the physical switching platform from the network operating system and the control protocols running above it. This creates greater architectural choice, but it also makes lifecycle, integration, compatibility and operational ownership more important.

THE DISAGGREGATED STACK
WHITE-BOX HARDWARE Switching ASICs, interfaces, buffers and physical resources. The platform provides forwarding capability without necessarily defining the complete software stack.
NETWORK OS Software responsible for operating the device, exposing interfaces and integrating routing and forwarding functions.
ROUTING SOFTWARE Protocol implementations such as BGP, OSPF or IS-IS build control-plane state and calculate reachability.
MANAGEMENT APIs, configuration models and automation systems provide the operational interface to the device or fabric.
CONTROL-PLANE EXAMPLES
BGP

Exchanges reachability information between routing peers and is widely used for data-centre and service-provider fabrics.

OSPF

Link-state routing protocol commonly used to build internal IP reachability within an autonomous system.

IS-IS

Link-state protocol used extensively in large-scale provider and data-centre network designs.

EVPN

A BGP-based control-plane technology commonly used to distribute MAC and IP reachability information for modern overlays.

01 · HARDWARE
Forwarding Resources

ASICs and interfaces determine what the platform can physically forward at line rate.

02 · NOS
Operating Environment

The network OS provides the software environment that connects the platform to routing and operational functions.

03 · CONTROL
Network Intelligence

Routing protocols exchange information and construct the state used to make forwarding decisions.

04 · OPERATE
Automation Interface

APIs, models and automation turn individual device configuration into repeatable operational workflows.

ENGINEERING REALITY

Disaggregation increases choice, but choice introduces responsibility. Hardware compatibility, NOS support, routing features, lifecycle management, observability and operational skills must all be considered as part of the architecture.

ENGINEERING LAB · 02 · DISAGGREGATE

Disaggregation Decision Lab

Build an open networking platform by selecting the hardware, network operating system and control model. The objective is not simply to choose “open” components — it is to understand the engineering trade-offs created when the layers are separated.

PLATFORM BUILDER
MODULARITY 82%
01 · Hardware Choose platform
02 · Network OS Choose software
03 · Control Choose model
ARCHITECTURE RESULT
CONFIGURATION READY
Selected Architecture
Hardware White-Box Switching Platform
Network Operating System Open Network OS
Control Open Standards & APIs
Operations Automation + Telemetry
Engineering Assessment
Platform choice
88
Software freedom
86
Integration effort
42
Vendor coupling
24
High platform and software choice
More integration responsibility
ENGINEERING DECISION

Disaggregation increases architectural choice, but the responsibility for validating hardware, software, interoperability and lifecycle support also increases.

03 · FABRIC · BGP EVPN

Build the Fabric With a Routed Underlay

Once the hardware and software layers are separated, the network can be designed as a programmable fabric. A routed IP underlay provides predictable transport while BGP EVPN and VXLAN can provide the control and overlay mechanisms required for scalable workload connectivity.

Engineering Question Can the physical fabric remain simple while the overlay provides the required logical connectivity?
03 · FABRIC · LEAF-SPINE & BGP EVPN

Build the Fabric With a Routed Underlay and Programmable Overlay

Open networking becomes especially powerful when disaggregated components are assembled into a fabric. A routed leaf-spine underlay provides predictable IP connectivity, while BGP and EVPN can distribute the control-plane information required for scalable workload and overlay connectivity.

FABRIC ARCHITECTURE
SPINE
High-speed routed transit between leaf switches. The spine provides fabric connectivity rather than directly hosting workloads.
LEAF
Connects servers, appliances and external networks while providing the edge of the fabric.
UNDERLAY
Routed IP transport between fabric devices. BGP, OSPF or IS-IS can provide the reachability required by the design.
OVERLAY
VXLAN can provide virtual network segmentation while EVPN distributes endpoint reachability through the control plane.
SERVER
→
LEAF
→
SPINE
→
LEAF
→
SERVER
CONTROL-PLANE MODEL
IP UNDERLAY

Provides simple routed reachability between the devices that make up the fabric.

BGP

Can provide scalable routing between leaf and spine devices and establish the fabric's IP reachability.

EVPN

Uses BGP to distribute MAC and IP reachability information for modern Ethernet VPN designs.

VXLAN

Encapsulates tenant traffic across the IP underlay and identifies virtual networks using a VNI.

01 · UNDERLAY
Transport Layer

The underlay answers a fundamental question: can the fabric devices reach one another reliably?

02 · CONTROL
Reachability State

Routing protocols exchange information so devices can calculate paths through the fabric.

03 · OVERLAY
Virtual Networks

VXLAN separates logical networks from the physical topology and provides scalable segmentation.

04 · EVPN
Endpoint Knowledge

EVPN distributes endpoint reachability through the control plane, reducing reliance on traditional flood-and-learn behaviour.

ENGINEERING PRINCIPLE

Keep the underlay simple and predictable. Put the complexity required for tenant connectivity, segmentation and endpoint distribution into the overlay and its control plane. This separation makes the fabric easier to reason about, troubleshoot and automate.

ENGINEERING LAB · 03 · FABRIC

Open Fabric Path Lab

Follow a packet through a modern open networking fabric. Select each stage to expose the engineering evidence behind the underlay, BGP control plane, EVPN and VXLAN overlay.

Stage 1 of 6
Fabric Path
Host A → Host B
Packet context: Host A · 10.10.10.21 → Host B · 10.10.20.31 · VNI 10100
Underlay
Keep Transport Simple
The routed fabric provides IP reachability between loopbacks and VTEPs. The underlay should not need to understand tenant networks.
Overlay
Move Tenant State Into EVPN
EVPN distributes endpoint and MAC/IP reachability information through the control plane rather than relying only on data-plane flooding.
Live Trace
Path Evidence
00:00 Path investigation initialised
00:01 Ingress leaf selected
04 · PROGRAM · AUTOMATION

Turn Network Operations Into a Programmable System

Open interfaces become valuable when they can be used consistently by automation. Models such as OpenConfig, interfaces such as gNMI, and tools such as Ansible and Terraform allow network intent to become repeatable change rather than a sequence of manual device commands.

Engineering Question Can the same intended network state be deployed repeatedly and then verified automatically?
04 · PROGRAM · APIs, AUTOMATION & DESIRED STATE

Turn Network Operations Into a Programmable System

Once hardware and network software are separated, the next engineering challenge is operating the infrastructure consistently. APIs, configuration models and automation allow engineers to describe, deploy and validate network state without relying on repetitive device-by-device configuration.

FROM INTENT TO NETWORK STATE
01
INTENT

Define what the network should provide.

02
MODEL

Represent configuration using structured data and models.

03
AUTOMATE

Apply repeatable changes across the infrastructure.

04
DEPLOY

Push validated state into network devices and services.

05
VERIFY

Compare the resulting state with the intended state.

06
REPEAT

Treat network change as an operational lifecycle.

OPEN PROGRAMMABILITY TOOLBOX
OpenConfig

Open, vendor-neutral data models commonly used to represent network configuration and operational state.

gNMI

A management interface commonly used to retrieve and modify structured configuration and operational data.

Ansible

Automation and configuration-management tooling suited to repeatable network changes and operational workflows.

Terraform

Infrastructure-as-code tooling commonly used to provision and manage infrastructure through declarative configuration.

DAY 0 → DAY 1 → DAY 2
DAY 0 · BOOTSTRAP Establish the initial platform, management connectivity, credentials and baseline configuration.
DAY 1 · DEPLOY Introduce production services such as routing, VLANs, VRFs, interfaces and fabric configuration.
DAY 2 · OPERATE Continue monitoring, changing, validating and remediating the network throughout its lifecycle.
ENGINEERING PRINCIPLE

Automation should not simply make configuration faster. The stronger objective is repeatability: the same intent should produce a predictable result, and the resulting network state should be measurable and verifiable.

API
Expose the Network

APIs provide a programmable interface instead of forcing every operation through manual CLI interaction.

MODEL
Structure the State

Models provide a consistent representation of configuration and operational information.

AUTOMATION
Scale the Change

Automation turns individual operations into repeatable workflows that can be applied across the fabric.

ENGINEERING LAB · 04 · PROGRAM

Desired-State Automation Lab

Define the network you want, generate the intended configuration, deploy the change, then verify that the fabric actually reached the desired state.

Intent not deployed
Define Intent
Desired state
Fabric Protocol
Overlay
Automation
Validation
Automation Pipeline
Awaiting plan
01
Intent
Defined
02
Model
Pending
03
Deploy
Pending
04
Observe
Pending
05
Verify
Pending
Generated Plan
Configuration Intent
# intent fabric.protocol = BGP overlay = EVPN/VXLAN automation = model-driven validation = telemetry
Configuration Diff
Proposed Change
+ enable bgp fabric + enable evpn overlay + configure telemetry
PENDING
Config State
PENDING
Control Plane
PENDING
Data Plane
PENDING
Telemetry
05 · OBSERVE · TELEMETRY

You Cannot Automate What You Cannot Observe

Programmable infrastructure needs equally strong visibility. Interface state, routing information, traffic flows and system health provide the evidence required to understand what the network is actually doing. Telemetry turns network state into operational data.

Engineering Question Can the network prove what changed, what is happening now and whether the resulting state is healthy?
05 · OBSERVE · TELEMETRY & NETWORK VISIBILITY

Expose the State of the Network

Programmability is only useful when engineers can also observe the resulting network state. Open networking therefore depends on telemetry that exposes interfaces, routing state, traffic behaviour and system health so that automation can be validated against what the network is actually doing.

NETWORK TELEMETRY SIGNALS
INTERFACES

Counters, errors, link state and utilisation reveal the health of physical and logical interfaces.

ROUTING STATE

BGP, OSPF, IS-IS and EVPN state shows whether the control plane is building the expected reachability.

TRAFFIC FLOWS

Flow records and sampled telemetry provide visibility into communication patterns and traffic volumes.

SYSTEM HEALTH

CPU, memory, buffers, process state and platform health provide additional operational context.

OBSERVABILITY PIPELINE
NETWORK STATE Devices generate operational and protocol information.
TELEMETRY State is exposed through streaming telemetry, APIs or sampled visibility mechanisms.
COLLECT Data is transported into monitoring, analytics or observability systems.
CORRELATE Signals are combined to understand relationships and anomalies.
ACT Engineers or automation can investigate, validate and respond.
STREAMING TELEMETRY
Continuous State

Streaming telemetry can deliver operational state continuously rather than relying entirely on periodic polling.

OPEN MODELS
Structured Data

OpenConfig and interfaces such as gNMI help expose structured configuration and operational information.

FLOW VISIBILITY
Traffic Behaviour

Technologies such as sFlow provide sampled visibility into traffic patterns without requiring full packet capture.

ENGINEERING PRINCIPLE

Automation without telemetry creates blind change. Telemetry without automation creates visibility without scale. The stronger architecture connects both: change the network, observe the result, compare it with the intended state, and investigate any deviation.

ENGINEERING LAB · 05 · OBSERVE

Telemetry Investigation Console

Select the signals you would use to investigate a fabric event, correlate them against the timeline, and build enough evidence to distinguish a control-plane problem from a forwarding or workload problem.

Select evidence
Telemetry Signals
Select multiple
Correlation View
No correlation yet
Signals Selected
0 / 5
Evidence Quality
LOW
Likely Domain
UNKNOWN
Confidence
0%
10:42:01 Baseline stable Leaf and spine interfaces operating normally.
10:42:17 EVPN state changed Remote endpoint reachability changed on Leaf-02.
10:42:18 Traffic drop observed Flow telemetry reports loss toward remote workload.
10:42:21 Interface remains up No physical link failure detected.
10:42:24 System health normal No resource saturation detected.
Investigation Finding
0 evidence sources
Select telemetry sources, then correlate them with the event timeline. The objective is to identify which layer changed first.
06 · OVERLAY · VXLAN

Separate Logical Networks From the Physical Fabric

Modern fabrics often carry many logical networks across the same physical infrastructure. VXLAN provides the encapsulation mechanism, while EVPN can provide the control-plane information required to distribute endpoint and reachability state across the fabric.

Engineering Question Can multiple logical networks share the same physical fabric without coupling tenant connectivity to the physical topology?
06 · OVERLAY · VXLAN & NETWORK VIRTUALISATION

Separate Logical Networks From the Physical Fabric

Network virtualisation allows logical connectivity to span a physical fabric without requiring every physical link to represent a separate tenant or broadcast domain. VXLAN provides the encapsulation mechanism, while EVPN can provide the control-plane information needed to discover and distribute endpoint reachability.

UNDERLAY → OVERLAY MODEL
PHYSICAL FABRIC

Switches, links and interfaces provide the physical transport between fabric nodes.

IP UNDERLAY

Routed connectivity provides the transport path between VTEPs across the fabric.

VXLAN OVERLAY

Tenant Ethernet frames can be encapsulated inside IP packets for transport across the underlay.

EVPN CONTROL PLANE

BGP EVPN distributes endpoint information so VTEPs can make informed forwarding decisions.

VTEP A Workload / VLAN
VNI 10100
VTEP B Workload / VLAN
CONTROL VS DATA PLANE
FUNCTION ROLE
UNDERLAY Provides IP reachability between the physical fabric devices.
VTEP Encapsulates and decapsulates VXLAN traffic at the edge of the overlay.
VNI Identifies a VXLAN virtual network and separates logical connectivity within the overlay.
EVPN Distributes MAC and IP reachability information through the control plane.
VXLAN Carries the overlay traffic across the IP underlay using encapsulation.
01 · VNI
Logical Identifier

VXLAN uses a 24-bit VNI, providing a large identifier space for logical networks.

02 · VTEP
Overlay Edge

VTEPs connect local workloads to the VXLAN overlay and perform encapsulation and decapsulation.

03 · EVPN
Reachability

EVPN provides control-plane distribution of endpoint information rather than relying entirely on flood-and-learn behaviour.

04 · MOBILITY
Physical Independence

Logical networks can span different physical locations and paths without changing the underlying fabric topology.

ENGINEERING PRINCIPLE

The underlay should answer “How do I reach the VTEP?” while the overlay answers “Which logical network and endpoint am I trying to reach?” Keeping those responsibilities separate makes large fabrics easier to scale, troubleshoot and automate.

ENGINEERING LAB · 06 · OVERLAY

VXLAN Overlay Packet Trace

Trace an Ethernet frame across a shared IP fabric and see where the logical network, VNI, VTEPs and VXLAN encapsulation fit into the forwarding path.

Ready to trace
Overlay Parameters
Packet context
H
Host A
10.10.10.21
Ethernet frame
V
VTEP A
Leaf-01
Encapsulation
I
IP Fabric
Underlay
ECMP
V
VTEP B
Leaf-02
Decapsulation
H
Host B
10.10.20.31
Ethernet frame
Current Packet Representation
ETH SRC=H-A DST=H-B
VNI
Logical Network Identity
The VNI identifies the logical VXLAN segment carried across the shared physical fabric. Different VNIs can use the same underlay.
VTEP
Where Encapsulation Happens
The VTEP sits at the edge of the overlay. It encapsulates traffic entering VXLAN and decapsulates traffic leaving the overlay.
Underlay
Transport Does Not Need Tenant State
The IP fabric forwards toward the remote VTEP. The physical transport can remain largely independent from the logical tenant network.
07 · OPERATE · WORKLOAD NETWORKING

Extend Open Networking Into the Host

The network does not end at the top-of-rack switch. Linux networking, virtual switching and container networking extend connectivity into servers and workloads. This creates another programmable layer that must be automated, observed and secured alongside the physical fabric.

Engineering Question Where does the network boundary actually end when applications run inside virtualised or containerised workloads?
07 · OPERATE · LINUX, VIRTUAL SWITCHING & CONTAINERS

Extend Open Networking Into the Workload Layer

Open networking does not stop at the physical switch. Linux networking, virtual switches and container networking extend the same programmable principles into the systems and workloads connected to the fabric. The result is a network model that spans physical interfaces, virtual interfaces, workloads and applications.

SOFTWARE NETWORKING STACK
PHYSICAL NIC Provides host connectivity into the physical network and participates in the server's forwarding path.
LINUX NETWORKING Interfaces, routing, namespaces, bridges, filtering and other kernel networking functions provide the host network layer.
VIRTUAL SWITCH Software such as Open vSwitch can provide programmable switching between physical interfaces, virtual interfaces and workloads.
WORKLOAD NETWORK Containers and virtual workloads consume the networking services provided by the host and its virtual switching layer.
OPEN SOFTWARE COMPONENTS
Linux Networking

Provides interfaces, routing, namespaces, bridges, firewalling and other host-level networking capabilities.

Open vSwitch

A software switch designed for programmable virtual networking and integration with physical and virtual infrastructure.

Network Namespaces

Provide isolated network views that can separate interfaces, routing tables and network resources.

Container Networking

Connects containers to host and external networks through bridges, virtual interfaces or additional networking systems.

01
PHYSICAL

Server connects to the fabric.

02
HOST

Linux provides the local network stack.

03
VIRTUAL

Software switching connects logical interfaces.

04
WORKLOAD

Containers or VMs consume network connectivity.

05
FABRIC

Traffic exits through the physical network.

LINUX
Programmable Host

Linux provides a powerful networking environment that can be automated alongside the physical fabric.

OPEN VSWITCH
Virtual Forwarding

OVS provides software-based switching between virtual and physical network interfaces.

CONTAINERS
Workload Connectivity

Containers consume network connectivity through host and container networking mechanisms rather than directly owning the physical fabric.

ENGINEERING PRINCIPLE

The physical fabric and workload network should be treated as connected layers rather than one giant control plane. The fabric provides transport, while Linux, virtual switching and workload networking provide connectivity closer to the application.

ENGINEERING LAB · 07 · OPERATE

Host Networking Stack Inspector

Follow connectivity from an application workload through the Linux network namespace, virtual switch, physical NIC and finally into the upstream fabric.

Select a host layer
Host Networking Path
Click any layer
Compute Host · worker-07
Linux
External Network Fabric
BGP / EVPN
HOST VTEP 192.0.2.11
↔
FABRIC Leaf / Spine
Linux
Host Networking Is Its Own Layer
Interfaces, namespaces, routing tables and policy exist below the application but above the physical fabric.
Virtual Switching
Forwarding Can Move Into Software
Open vSwitch and other virtual switching mechanisms connect workload interfaces to host uplinks and can apply forwarding policy locally.
Engineering Boundary
Do Not Collapse Every Layer
The physical fabric transports traffic while host networking provides connectivity closer to the workload. Automation and observability need visibility across both.
08 · VALIDATE · CLOSED LOOP

The Network Becomes a Continuous Feedback System

The final step is connecting intent, automation and telemetry into a controlled feedback loop. The network should not simply accept changes; it should provide evidence that the resulting state matches the design, detect meaningful drift and support controlled remediation.

Engineering Question Can the network detect when reality has diverged from the intended state and safely guide it back into compliance?
08 · VALIDATE · CLOSED-LOOP OPEN NETWORKING

Turn Open Networking Into a Closed-Loop System

The real advantage of an open network appears when programmability, automation and telemetry operate as one system. Desired state defines the intended configuration, automation applies it, the fabric delivers connectivity, telemetry exposes the resulting state and validation determines whether the network still matches the design.

01 · INTENT
DESIRED STATE

Define what the network should look like.

02 · CHANGE
AUTOMATION

Translate intent into repeatable configuration.

03 · FORWARD
NETWORK FABRIC

The physical and virtual network delivers connectivity.

04 · OBSERVE
TELEMETRY

Collect evidence about the resulting network state.

05 · DETECT
DRIFT

Compare observed state with intended state.

06 · ACT
REMEDIATE

Correct validated deviations and verify again.

CLOSED-LOOP OPERATING CYCLE
01
Define Intent Specify topology, policy, connectivity and operational requirements.
02
Automate Change Use models, APIs and automation to produce consistent changes.
03
Observe State Gather configuration, routing, interface and traffic evidence.
04
Compare Determine whether observed state matches the intended design.
05
Validate & Remediate Correct confirmed drift and return the system to the desired state.
ENGINEERING SAFETY GATES
01 · INTENT
Define Before Change

Automation should operate against an explicit desired state rather than an undocumented collection of commands.

02 · EVIDENCE
Observe Before Acting

Telemetry and state data provide the evidence required to determine whether a deviation is real.

03 · CONTROL
Validate Before Remediation

Not every difference should trigger an automatic change. Context and policy must determine the response.

04 · RECOVERY
Verify After Change

A successful configuration deployment is not the final result. The resulting network state must also be verified.

CHECK 01
Configuration State

Does the deployed configuration match the intended model?

CHECK 02
Control-Plane State

Are routing adjacencies and learned paths behaving as expected?

CHECK 03
Data-Plane State

Is traffic actually following the expected forwarding path?

CHECK 04
Operational State

Does telemetry confirm that the network remains healthy over time?

ENGINEERING PRINCIPLE

Open networking becomes strategically valuable when openness is combined with automation and evidence. The goal is not simply to make individual devices programmable, but to create a network that can be defined, changed, observed, validated and safely corrected as a system.

ENGINEERING LAB · 08 · VALIDATE

Closed-Loop Network Validation

Introduce configuration drift into a network, collect evidence, identify the affected state and safely drive the system back toward the intended design.
Network converged
Closed-Loop Cycle
STATE · CONVERGED
01
Desired State
Declared network intent and policy baseline
→
02
Deploy
Automation applies intended configuration
→
03
Observe
Telemetry exposes operational state
→
04
Detect Drift
Compare intended and observed state
→
05
Remediate
Controlled correction and verification
Network Evidence
Configuration State MATCH
Control Plane HEALTHY
Data Plane FORWARDING
Telemetry NORMAL
Evidence
Observe Before You Act
Telemetry provides evidence of what the network is actually doing. A desired-state system should not remediate solely because a configuration differs.
Safety Gate
Validate the Failure Domain
Compare configuration, control-plane, data-plane and operational evidence before deciding that automated remediation is appropriate.
Convergence
Verify After Remediation
Closed-loop automation is incomplete until the resulting state is checked and confirmed against the original intent.
Open Networking · Interactive Use Case
Automation & Observability Lab
Follow the operational lifecycle from desired state and Day 0 provisioning through Day 1/2 services, telemetry, drift detection and remediation.
DESIRED STATE
AUTOMATION
NETWORK FABRIC
OBSERVABILITY / FEEDBACK
Desired State
Intent
Policy
Inventory
Devices
Source of Truth
Templates
Config Model
Reusable
Automation
Pipeline
Ansible / Terraform
Day 0
Provision
Base Fabric
Day 1 / 2
Services
VRF / EVPN
Leaf / Spine
Fabric
BGP / EVPN
Network State
Running State
Actual Config
Telemetry
gNMI / gRPC
Streaming
Analytics
Visibility
Health / KPIs
Drift Detection
Compare
Desired ≠ Actual
Remediation
Closed Loop
Restore State
Closed-Loop Networking
Modern open networking connects desired state, automation, network operation and telemetry into a continuous lifecycle.
Automation
Desired State
Network
Leaf / Spine
Telemetry
Streaming Telemetry
State
In Sync
● FABRIC OPERATING NORMALLY
Day 0 Provision the base fabric using repeatable infrastructure-as-code workflows.
Day 1 / 2 Automate services such as VRFs, EVPN, VXLAN and network policy.
Telemetry Continuously observe network state using streaming telemetry.
Closed Loop Detect drift and, where policy permits, restore the intended state.
```
☕
Support Network Insight
Help support independent engineering guides, interactive networking tools, and future learning labs.
Support Network Insight ```
Cisco ACI

ACI Cisco

Cisco ACI Components

Cisco Application Centric Infrastructure (ACI) represents a different way of approaching data centre networking. Rather than treating the network primarily as a collection of individually configured switches and interfaces, ACI uses application requirements and policy as the foundation for how connectivity, segmentation, and network behaviour are defined. This becomes particularly valuable as organizations operate physical servers, virtual machines, containers, and workloads across increasingly dynamic environments.

Cisco ACI brings the physical data centre fabric and software-defined policy model together through a centralized operational framework. The underlying network still provides the forwarding infrastructure, but administrators can define how applications and workloads should communicate without having to express every requirement as a series of device-by-device configurations. This separation between intent and implementation is central to the ACI model.

A major benefit is policy consistency. Instead of relying entirely on individual switch configurations, teams can define application relationships, network connectivity, and security requirements through policy. Those policies can then be applied across the fabric as workloads are deployed or changed, helping reduce configuration drift and making large environments easier to operate.

Security is another important part of the architecture. ACI supports segmentation and policy-based control between application tiers and workloads, allowing organizations to restrict communication according to defined requirements rather than relying solely on broad network boundaries. Integration with external security and operational platforms can further extend visibility and enforcement across the environment.

The model is also designed for scale. Modern data centres may contain large numbers of applications, virtual workloads, containers, and rapidly changing endpoints. A policy-driven fabric allows network operations to respond to those changes through automation and orchestration rather than requiring every network change to be handled manually. This can improve deployment consistency while reducing operational overhead.

ACI also provides a framework for connecting traditional physical infrastructure with virtualized and container-based workloads. This is important because most enterprise environments are not completely homogeneous: legacy applications, modern distributed applications, databases, virtualization platforms, and containerized services often coexist within the same broader architecture.

Hybrid and multi-cloud environments add another dimension. Organizations increasingly need consistent connectivity and policy across on-premises infrastructure and external cloud platforms. ACI can participate in these architectures through its integration and multi-site capabilities, helping organizations extend network and application policy across environments while recognizing that each cloud still has its own native networking and security model.

Cisco ACI is therefore best understood as a policy-driven data centre networking architecture, rather than simply a replacement for traditional switching. Its value comes from combining a scalable fabric with centralized policy, automation, segmentation, and application-aware operational models. For organizations managing complex data centre environments, this approach can provide a more consistent way to connect applications, enforce policy, and adapt the network as workloads evolve.

Cisco ACI • Interactive Architecture
ACI Fabric Architecture Explorer
Explore how APIC policy, the spine–leaf fabric and endpoint connectivity work together to create a policy-driven data-center network.
Learning objective: Understand how Cisco ACI separates policy and management from distributed forwarding — APIC defines intent while leaf and spine switches enforce and transport that policy.
MANAGEMENT / POLICY PLANE SPINE FABRIC LEAF / DATA-PLANE EDGE ENDPOINTS / WORKLOADS APIC CLUSTER Policy • Management • Orchestration SPINE 1 Fabric Transit SPINE 2 Fabric Transit LEAF 1 Endpoint Edge LEAF 2 Endpoint Edge LEAF 3 Endpoint Edge SERVER A EPG: WEB SERVER B EPG: APP SERVER C EPG: DB MULTI-PATH FABRIC / ECMP POLICY ENFORCEMENT AT THE LEAF EDGE
Fabric
Policy
Endpoint
Interactive Inspector
Cisco ACI Fabric
Fabric concept
Select a device or connection in the diagram to see how that component participates in the ACI architecture.
Selected component
Architecture overview
ACI concept
Policy-driven spine–leaf fabric
Why it matters
ACI separates centralized policy definition from distributed packet forwarding.

Highlights: Cisco ACI Components

The ACI Fabric

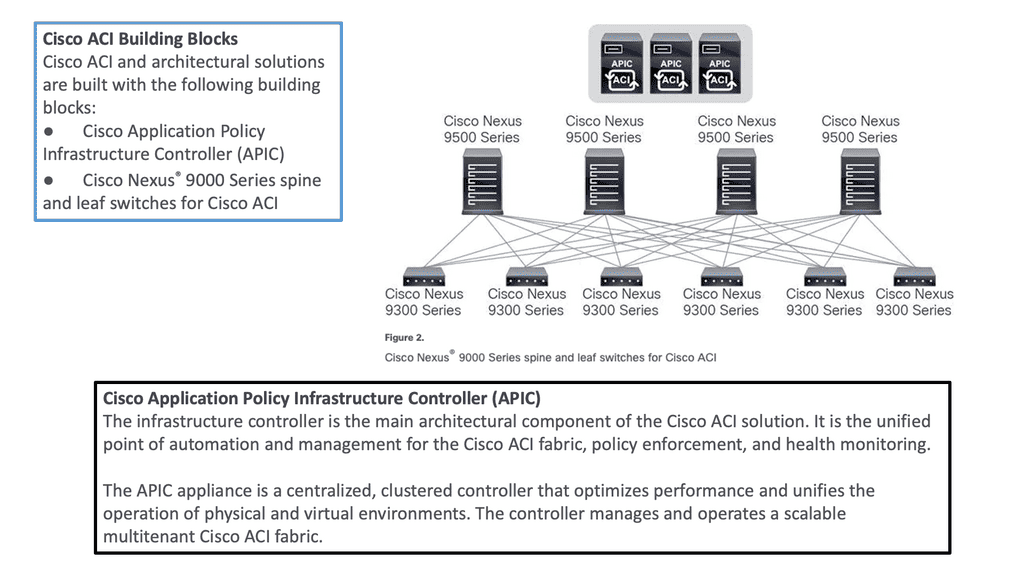
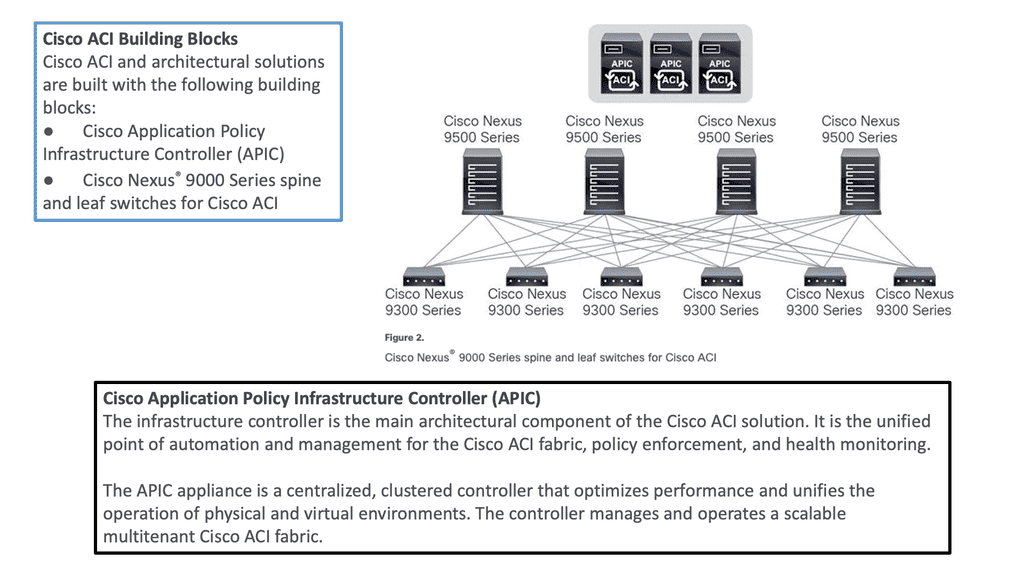
Cisco ACI is a software-defined networking (SDN) solution that integrates with software and hardware. With the ACI, we can create software policies and use hardware for forwarding, an efficient and highly scalable approach offering better performance. The hardware for ACI is based on the Cisco Nexus 9000 platform product line. The APIC centralized policy controller drives the software, which stores all configuration and statistical data.

–The Cisco Nexus Family–

To build the ACI underlay, you must exclusively use the Nexus 9000 family of switches. You can choose from modular Nexus 9500 switches or fixed 1U to 2U Nexus 9300 models. Specific models and line cards are dedicated to the spine function in ACI fabric; others can be used as leaves, and some can be used for both purposes. You can combine various leaf switches inside one fabric without any limitations.

a) Cisco ACI Fabric: Cisco ACI’s foundation lies in its fabric, which forms the backbone of the entire infrastructure. The ACI fabric comprises leaf switches, spine switches, and the application policy infrastructure controller (APIC). Each component ensures a scalable, agile, and resilient network.

b) Leaf Switches: Leaf switches serve as the access points for endpoints within the ACI fabric. They provide connectivity to servers, storage devices, and other network devices. With their high port density and advanced features, such as virtual port channels (vPCs) and fabric extenders (FEX), leaf switches enable efficient and flexible network designs.

c) Spine Switches: Spine switches serve as the core of the ACI fabric, providing high-bandwidth connectivity between the leaf switches. They use a non-blocking, multipath forwarding mechanism to ensure optimal traffic flow and eliminate bottlenecks. With their modular design and support for advanced protocols like Ethernet VPN (EVPN), spine switches offer scalability and resiliency.

d) Application Policy Infrastructure Controller (APIC): At the heart of Cisco ACI is the APIC, a centralized management and policy control plane. The APIC acts as a single control point, simplifying network operations and enabling policy-based automation. It provides a comprehensive view of the entire fabric, allowing administrators to define and enforce policies across the network.

e) Integration with Virtualization and Cloud Environments: Cisco ACI seamlessly integrates with virtualization platforms such as VMware vSphere and Microsoft Hyper-V and cloud environments like Amazon Web Services (AWS) and Microsoft Azure. This integration enables consistent policy enforcement and visibility across physical, virtual, and cloud infrastructures, enhancing agility and simplifying operations.

Cisco ACI — Policy‑Driven, Application‑Centric Networking

Cisco ACI (Application Centric Infrastructure) is Cisco’s flagship data‑center fabric built around policy‑driven automation, centralized control, and application‑aware networking. Instead of configuring individual switches, ACI abstracts the network into application policies, endpoint groups, and contracts. This creates a programmable, intent‑based fabric where the network automatically aligns with application requirements. Data analytics strengthens ACI by providing visibility into fabric health, policy behavior, endpoint movement, and application flows, ensuring that the fabric remains consistent, secure, and optimized.

Policy Model — Endpoint Groups, Contracts, and Intent

ACI’s core innovation is its policy model:

  • Endpoint Groups (EPGs) define logical groupings of workloads
  • Contracts define how EPGs communicate
  • Application Network Profiles (ANPs) map application tiers to policies
  • Tenants provide multi‑domain isolation

This model replaces traditional VLANs, ACLs, and manual segmentation with intent‑based policies. Analytics enhances this by identifying unused contracts, misaligned EPGs, shadow policies, and unexpected east‑west flows. With analytics, ACI’s policy model becomes adaptive and identity‑aware rather than static.

Fabric Architecture — Spine‑Leaf, VXLAN, and Distributed Control

ACI uses a spine‑leaf architecture with VXLAN overlays and a centralized policy controller (APIC). The fabric provides:

  • consistent forwarding across all leaf switches
  • distributed anycast gateways
  • scalable multi‑tenant segmentation
  • automated endpoint learning

Analytics correlates fabric telemetry—routing updates, VXLAN behavior, endpoint mobility, and link performance—to detect anomalies such as asymmetric routing, endpoint flapping, or misconfigured policies. This ensures the fabric remains stable and predictable even under dynamic workloads.

Security and Microsegmentation in ACI

ACI provides built‑in microsegmentation through EPGs and contracts. Security becomes application‑centric rather than IP‑centric. Analytics enhances ACI security by monitoring:

  • unusual endpoint movement
  • abnormal contract usage
  • unexpected east‑west communication
  • privilege escalation inside application tiers

This transforms ACI into a Zero Trust‑aligned data‑center fabric where segmentation is continuously validated and enforced.

Operational Visibility — Telemetry, Health Scores, and Assurance

ACI includes extensive telemetry and health scoring across:

  • fabric nodes
  • policies
  • endpoints
  • application flows

Analytics consumes this telemetry to provide deeper insights into performance, security, and policy alignment. Tools like ACI AppDynamics integration, Nexus Dashboard Insights, and fabric assurance engines use analytics to detect drift, highlight anomalies, and recommend remediation. ACI becomes a self‑optimizing fabric driven by real‑time intelligence.

ACI in Hybrid and Multi‑Cloud Architectures

ACI extends beyond the data center into cloud environments through ACI Anywhere and Cloud ACI. Policies can be pushed to AWS, Azure, and GCP, creating a unified segmentation and security model across hybrid environments. Analytics ensures consistency across on‑prem and cloud fabrics, detecting mismatches, drift, and cross‑cloud anomalies. This creates a seamless, policy‑driven hybrid architecture.

–ACI Architecture: Spine and Leaf–

To be used as ACI spines or leaves, Nexus 9000 switches must be equipped with powerful Cisco CloudScale ASICs manufactured using 16-nm technology. The following figure shows the Cisco ACI based on the Nexus 9000 series. Cisco Nexus 9300 and 9500 platform switches support Cisco ACI. As a result, organizations can use them as spines or leaves to utilize an automated, policy-based systems management approach fully. 

Cisco ACI Components
Diagram: Cisco ACI Components. Source is Cisco

**Hardware-based Underlay**

Server virtualization helped by decoupling workloads from the hardware, making the compute platform more scalable and agile. However, the server is not the main interconnection point for network traffic. So, we need to look at how we could virtualize the network infrastructure similarly to the agility gained from server virtualization.

**Mapping Network Endpoints**

This is carried out with software-defined networking and overlays that could map network endpoints and be spun up and down as needed without human intervention. In addition, the SDN architecture includes an SDN controller and an SDN network that enables an entirely new data center topology.

**Specialized Forwarding Chips**

In ACI, hardware-based underlay switching offers a significant advantage over software-only solutions due to specialized forwarding chips. Furthermore, thanks to Cisco’s ASIC development, ACI brings many advanced features, including security policy enforcement, microsegmentation, dynamic policy-based redirect (inserting external L4-L7 service devices into the data path), or detailed flow analytics—besides the vast performance and flexibility.


Cisco ACI • Fabric Mechanics

ACI Overlay & Underlay Lab

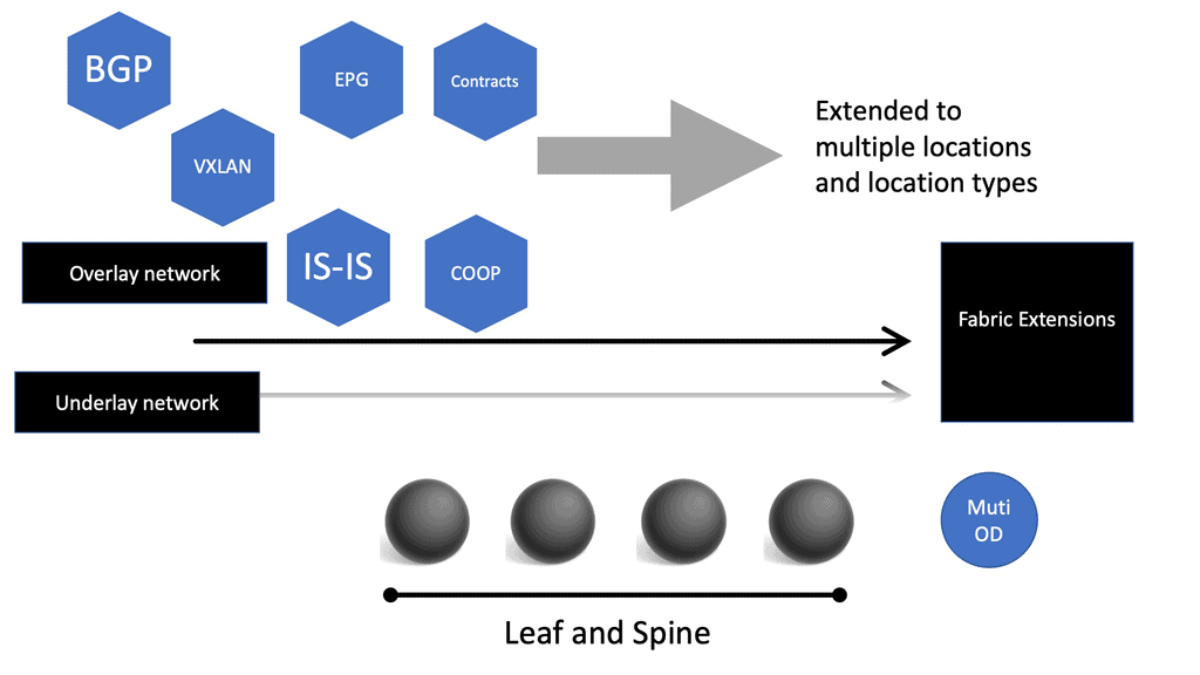
See how ACI builds the fabric: IS-IS provides the underlay, VXLAN carries the overlay, VTEPs connect endpoints, and COOP helps the fabric locate endpoints.
ACI FABRIC MECHANICS OVERLAY UNDERLAY ENDPOINTS VXLAN OVERLAY Leaf 1 VTEP Leaf 2 VTEP IS-IS UNDERLAY Spine Fabric transport Leaf 1 Underlay node Leaf 2 Underlay node COOP Endpoint database Server A Endpoint Server B Endpoint FABRIC TRANSPORT ATTACHMENT ATTACHMENT
IS-IS Underlay
VXLAN Overlay
COOP Control Plane
Endpoint Attachment
Selected Component
ACI Fabric Flow
Start here. ACI separates the physical transport network from the logical VXLAN overlay. Click a tab, node, or connection to explore how the pieces work together.
Technology
IS-IS + VXLAN + VTEP + COOP
Role
Build transport, carry overlay traffic, and locate endpoints.
Why it matters
This separation allows ACI to provide scalable fabric connectivity without making applications depend on the physical topology.

Cisco ACI Components

 Introduction to Leaf and Spine

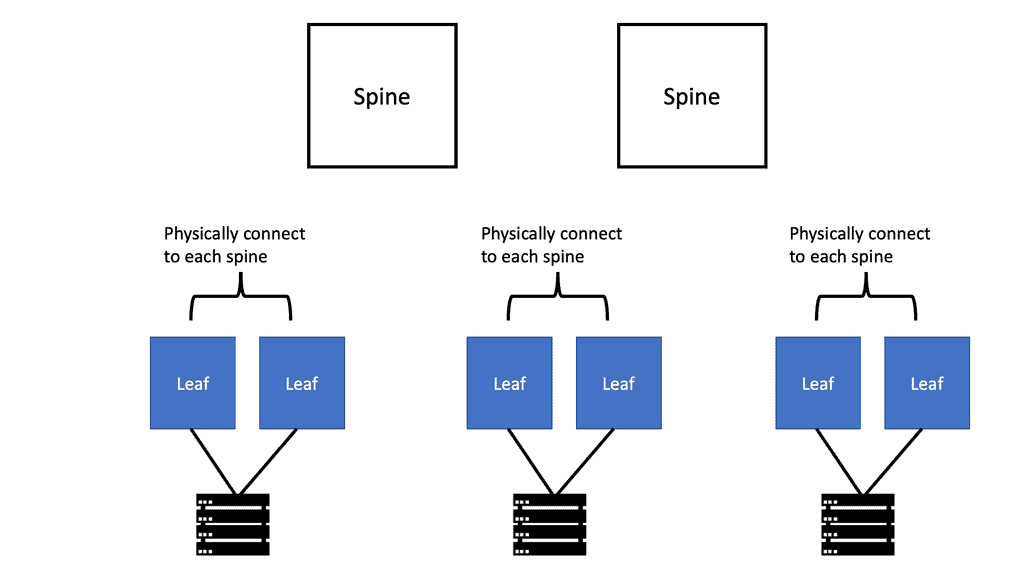
The Cisco SDN ACI works with a Clos architecture, a fully meshed ACI network. Based on a spine leaf architecture. As a result, every Leaf is physically connected to every Spine, enabling traffic forwarding through non-blocking links. Physically, a leaf switch set creates a leaf layer attached to the spines in a full BIPARTITE graph. This means that each Leaf is connected to each Spine, and each Spine is connected to each Leaf. 

The ACI uses a horizontally elongated Leaf and Spine architecture with one hop to every host in an entirely messed ACI fabric, offering good throughput and convergence needed for today’s applications.

The ACI fabric: Does Not Aggregate Traffic

A key point in the spine-and-leaf design is the fabric concept, like a stretch network. One of the core ideas around a fabric is that it does not aggregate traffic. This does increase data center performance along with a non-blocking architecture. With the spine-leaf topology, we are spreading a fabric across multiple devices.

Required: Increased Bandwidth Available

The result of the fabric is that each edge device has the total bandwidth of the fabric available to every other edge device. This is one big difference from traditional data center designs; we aggregate the traffic by either stacking multiple streams onto a single link or carrying the streams serially.

Challenge: Oversubscription

With the traditional 3-tier design, we aggregate everything at the core, leading to oversubscription ratios that degrade performance. With the ACI Leaf and Spine design, we spread the load across all devices with equidistant endpoints, allowing us to carry the streams parallel.

Required: Routed Multipathing

Then, we have horizontal scaling load balancing.  Load balancing with this topology uses multipathing to achieve the desired bandwidth between the nodes. Even though this forwarding paradigm can be based on Layer 2 forwarding ( bridging) or Layer 3 forwarding ( routing), the ACI leverages a routed approach to the Leaf and Spine design, and we have Equal Cost Multi-Path (ECMP) for both Layer 2 and Layer 3 traffic. 

**Overlay and Underlay Design**

Mapping Traffic:

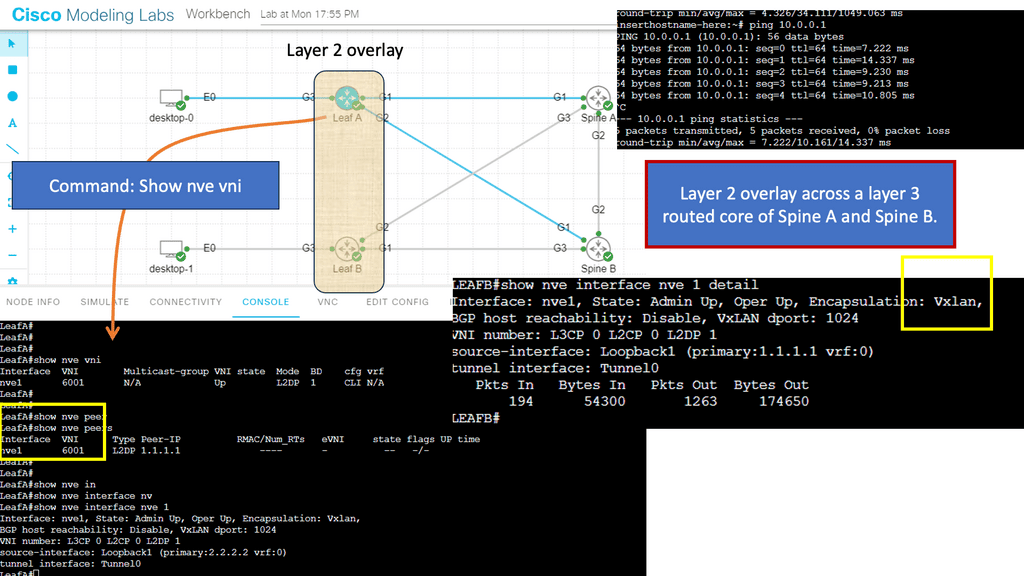
So you may be asking how we can have Layer 3 routed core and pass Layer 2 traffic. This is done using the overlay, which can map different traffic types to other overlays. So, we can have Layer 2 traffic mapped to an overlay over a routed core.

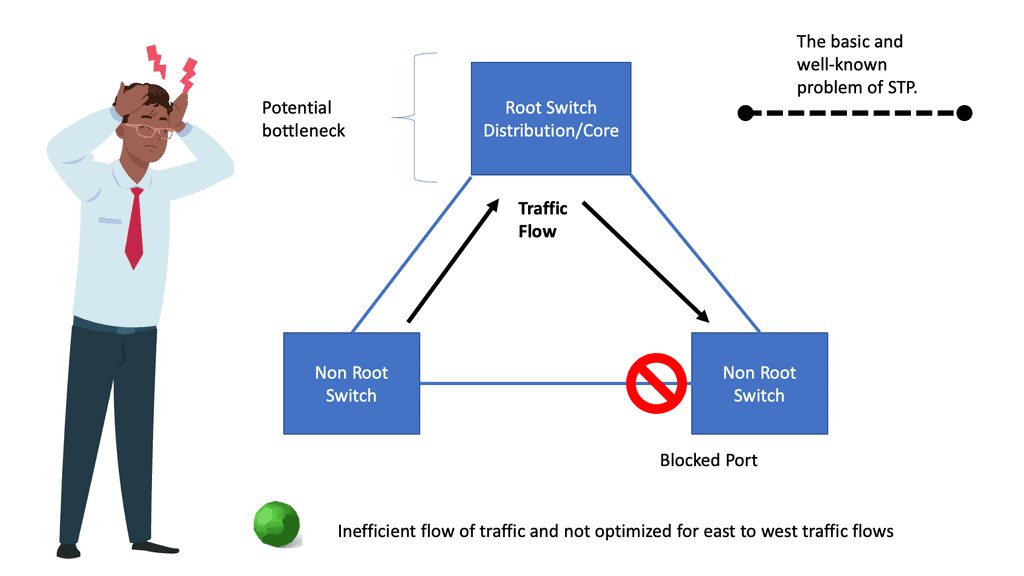
L3 active-active links: ACI links between the Leaf and the Spine switches are L3 active-active links. Therefore, we can intelligently load balance and traffic steer to avoid issues. We don’t need to rely on STP to block links or involve STP in fixing the topology.

Challenge: IP – Identity & Location

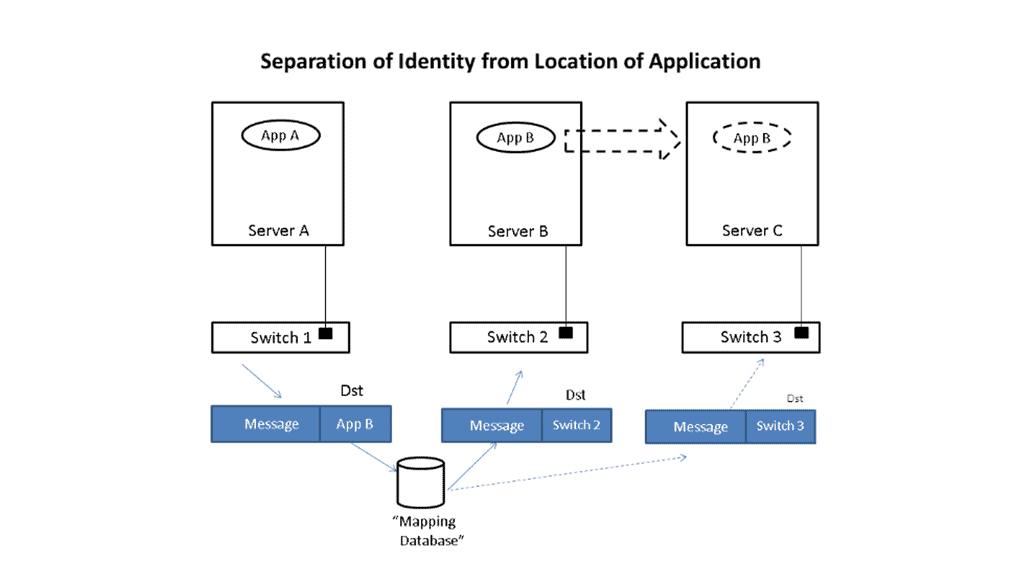
When networks were first developed, there was no such thing as an application moving from one place to another while it was in use. So, the original architects of IP, the communication protocol used between computers, used the IP address to indicate both the identity of a device connected to the network and its location on the network. Today, in the modern data center, we need to be able to communicate with an application or application tier, no matter where it is.

Required: Overlay Encapsulation

One day, it may be in location A and the next in location B, but its identity, which we communicate with, is the same on both days. An overlay is when we encapsulate an application’s original message with the location to which it needs to be delivered before sending it through the network. Once it arrives at its final destination, we unwrap it and deliver the original message as desired.

The identities of the devices (applications) communicating are in the original message, and the locations are in the encapsulation, thus separating the place from the identity. This wrapping and unwrapping is done on a per-packet basis and, therefore, must be done quickly and efficiently.

**Overlay and Underlay Components**

The Cisco SDN ACI has an overlay and underlay concept, which forms a virtual overlay solution. The role of the underlay is to glue together devices so the overlay can work and be built on top. So, the overlay, which is VXLAN, runs on top of the underlay, which is IS-IS. In the ACI, the IS-IS protocol provides the routing for the overlay, which is why we can provide ECMP from the Leaf to the Spine nodes. The routed underlay provides an ECMP network where all leaves can access Spine and have the same cost links. 

ACI overlay
Diagram: Overlay. Source Cisco

Underlay & Overlay Interaction

Example: 

Let’s take a simple example to illustrate how this is done. Imagine that application App-A wants to send a packet to App-B. App-A is located on a server attached to switch S1, and App-B is initially on switch S2. When App-A creates the message, it will put App-B as the destination and send it to the network; when the message is received at the edge of the network, whether a virtual edge in a hypervisor or a physical edge in a switch, the network will look up the location of App-B in a “mapping” database and see that it is attached to switch S2.

It will then put the address of S2 outside of the original message. So, we now have a new message addressed to switch S2. The network will forward this new message to S2 using traditional networking mechanisms. Note that the location of S2 is very static, i.e., it does not move, so using traditional mechanisms works just fine.

Upon receiving the new message, S2 will remove the outer address and thus recover the original message. Since App-B is directly connected to S2, it can easily forward the message to App-B. App-A never had to know where App-B was located, nor did the network’s core. Only the edge of the network, specifically the mapping database, had to know the location of App-B. The rest of the network only had to see the location of switch S2, which does not change.

Let’s now assume App-B moves to a new location switch S3. Now, when App-A sends a message to App-B, it does the same thing it did before, i.e., it addresses the message to App-B and gives the packet to the network. The network then looks up the location of App-B and finds that it is now attached to switch S3. So, it puts S3’s address on the message and forwards it accordingly. At S3, the message is received, the outer address is removed, and the original message is delivered as desired.

App-A did not track App-B’s movement at all. App-B’s address identified It, while the switch’s address, S2 or S3, identified its location. App-A can communicate freely with App-B no matter where It is located, allowing the system administrator to place App-B in any area and move it as desired, thus achieving the flexibility needed in the data center.

Multicast Distribution Tree (MDT)

We have a Multicast Distribution Tree MDT tree on top that is used to forward multi-destination traffic without having loops. The Multicast distribution tree is dynamically built to send flood traffic for specific protocols. Again, it does this without creating loops in the overlay network. The tunnels created for the endpoints to communicate will have tunnel endpoints. The tunnel endpoints are known as the VTEP. The VTEP addresses are assigned to each Leaf switch from a pool that you specify in the ACI startup and discovery process.

Normalize the transports

VXLAN tunnels in the ACI fabric normalize the transports in the ACI network. Therefore, traffic between endpoints can be delivered using the VXLAN tunnel, resulting in any transport network regardless of the device connecting to the fabric. 

So, using VXLAN in the overlay enables any network, and you don’t need to configure anything special on the endpoints for this to happen. The endpoints that connect to the ACI fabric do not need special software or hardware. The endpoints send regular packets to the leaf nodes they are connected to directly or indirectly. As endpoints come online, they send traffic to reach a destination.

Bridge Domains and VRF

Therefore, the Cisco SDN ACI under the hood will automatically start to build the VXLAN overlay network for you. The VXLAN network is based on the Bridge Domain (BD), or VRF ACI constructs deployed to the leaf switches. The Bridge Domain is for Layer 2, and the VRF is for Layer 3. So, as devices come online and send traffic to each other, the overlay will grow in reachability in the Bridge Domain or the VRF. 

Direct host routing for endoints

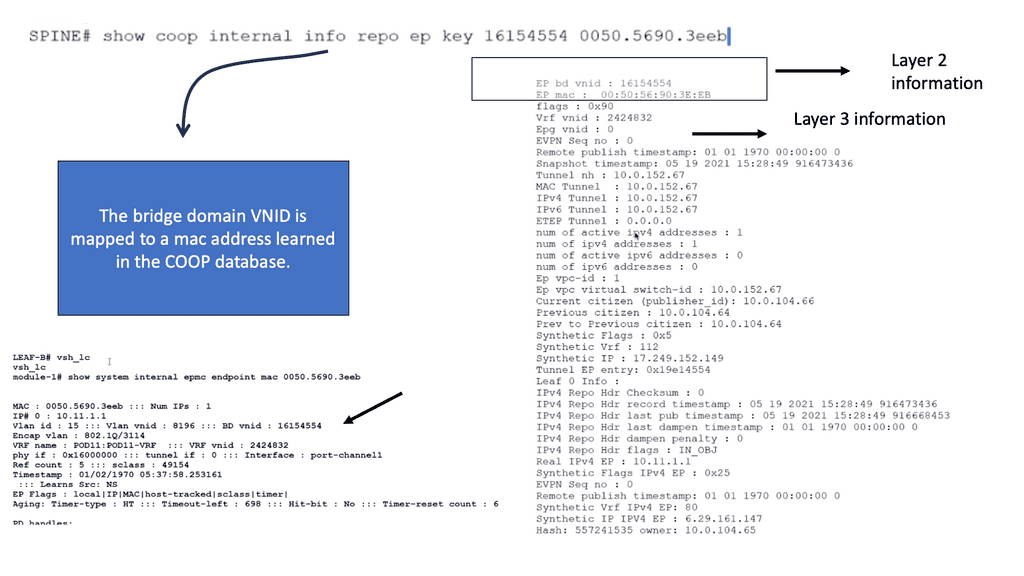
Routing within each tenant, VRF is based on host routing for endpoints directly connected to the Cisco ACI fabric. For IPv4, the host routing is based on the /32, giving the ACI a very accurate picture of the endpoints. Therefore, we have exact routing in the ACI.  In conjunction, we have a COOP database that runs on the Spines and offers remarkably optimized fabric to know where all the endpoints are located.

To facilitate this, every node in the fabric has a TEP address, and we have different types of TEPs depending on the device’s role. The Spine and the Leaf will have TEP addresses but will differ from each other.

COOP database
Diagram: COOP database

The VTEP and PTEP

The Leaf’s nodes are the Virtual Tunnel Endpoints (VTEP), which are also known as the physical tunnel endpoints (PTEP) in ACI. These PTEP addresses represent the “WHERE” in the ACI fabric where an endpoint lives. Cisco ACI uses a dedicated VRF and a subinterface of the uplinks from the Leaf to the Spines as the infrastructure to carry VXLAN traffic. In Cisco ACI terminology, the transport infrastructure for VXLAN traffic is known as Overlay-1, which is part of the tenant “infra.” 

**The Spine TEP**

The Spines also have a PTEP and an additional proxy TEP, which are used for forwarding lookups into the mapping database. The Spines have a global view of where everything is, which is held in the COOP database synchronized across all Spine nodes. All of this is done automatically for you.

**Anycast IP Addressing**

For this to work, the Spines have an Anycast IP address known as the Proxy TEP. The Leaf can use this address if they do not know where an endpoint is, so they ask the Spine for any unknown endpoints, and then the Spine checks the COOP database. This brings many benefits to the ACI solution, especially for traffic optimizations and reducing flooded traffic in the ACI. Now, we have an optimized fabric for better performance.

The ACI optimizations

**Mouse and elephant flow**

This provides better performance for load balancing different flows. For example, in most data centers, we have latency-sensitive flows, known as mouse flows, and long-lived bandwidth-intensive flows, known as elephant flows. 

The ACI has more precisely load-balanced traffic using algorithms that optimize mouse and elephant flows and distribute traffic based on flow lets: flow let load-balancing. Within a Leaf, Spine latency is low and consistent from port to port.

The max latency of a packet from one port to another in the architecture is the same regardless of the network size. So you can scale the network without degrading performance. Scaling is often done on a POD-by-POD basis. For more extensive networks, each POD would be its Leaf and Spine network.

**ARP optimizations: Anycast gateways**

The ACI comes by default with a lot of traffic optimizations. Firstly, instead of using an ARP and broadcasting across the network, that can hamper performance. The Leaf can assume that the Spine will know where the destination is ( and it does via the COOP database ), so there is no need to broadcast to everyone to find a destination.

If the Spine knows where the endpoint is, it will forward the traffic to the other Leaf. If not, it will drop it.

**Fabric anycast addressing**

This again adds performance benefits to the ACI solution as the table sizes on the Leaf switches can be kept smaller than they would if they needed to know where all the destinations were, even if they were not or never needed to communicate with them. On the Leaf, we have an Anycast address too.

These fabric Anycast addresses are available for Layer 3 interfaces. On the Leaf ToR, we can establish an SVI that uses the same MAC address on every ToR; therefore, when an endpoint needs to route to a ToR, it doesn’t matter which ToR you use. The Anycast Address is spread across all ToR leaf switches. 

**Pervasive gateway**

Now we have predictable latency to the first hop, and you will use the local route VRF table within that ToR instead of traversing the fabric to a different ToR. This is the Pervasive Gateway feature that is used on all Leaf switches. The Cisco ACI has many advanced networking features, but the pervasive gateway is my favorite. It does take away all the configuration mess we had in the past.

ACI Cisco: Integrations

  • Routing Control Platform

Then came along Cisco SDN ACI, the ACI Cisco, which operates differently from the traditional data center with an application-centric infrastructure. The Cisco application-centric infrastructure achieves resource elasticity with automation through standard policies for data center operations and consistent policy management across multiple on-premises and cloud instances.

  • Extending & Integrating the fabric

What makes the Cisco ACI interesting is its several vital integrations. I’m not talking about extending the data center with multi-pod and multi-site, for example, with AlgoSec, Cisco AppDynamics, and SD-WAN. AlgoSec enables secure application delivery and policy across hybrid network estates, while AppDynamic lives in a world of distributed systems Observability. SD-WAN enabled path performance per application with virtual WANs.

Cisco Multi-Pod Design

Cisco ACI Multi-Pod is part of the “Single APIC Cluster / Single Domain” family of solutions, as a single APIC cluster is deployed to manage all the interconnected ACI networks. These separate ACI networks are named “pods,” Each looks like a regular two-tier spine-leaf topology. The same APIC cluster can manage several pods, and to increase the resiliency of the solution, the various controller nodes that make up the cluster can be deployed across different pods.

ACI Multi-Pod
Diagram: Cisco ACI Multi-Pod. Source Cisco.

ACI Cisco and AlgoSec

With AlgoSec integrated with the Cisco ACI, we can now provide automated security policy change management for multi-vendor devices and risk and compliance analysis. The AlgoSec Security Management Solution for Cisco ACI extends ACI’s policy-driven automation to secure various endpoints connected to the Cisco SDN ACI fabric.

These simplify network security policy management across on-premises firewalls, SDNs, and cloud environments. They also provide visibility into ACI’s security posture, even across multi-cloud environments. 

ACI Cisco and AppDynamics 

Then, with AppDynamics, we are heading into Observability and controllability. Now, we can correlate app health and network for optimal performance, deep monitoring, and fast root-cause analysis across complex distributed systems with numbers of business transactions that need to be tracked.

This will give your teams complete visibility of your entire technology stack, from your database servers to cloud-native and hybrid environments. In addition, AppDynamics works with agents that monitor application behavior in several ways. We will examine the types of agents and how they work later in this post.

ACI Cisco and SD-WAN 

SD-WAN brings a software-defined approach to the WAN. These enable a virtual WAN architecture to leverage transport services such as MPLS, LTE, and broadband internet services. So, SD-WAN is not a new technology; its benefits are well known, including improving application performance, increasing agility, and, in some cases, reducing costs.

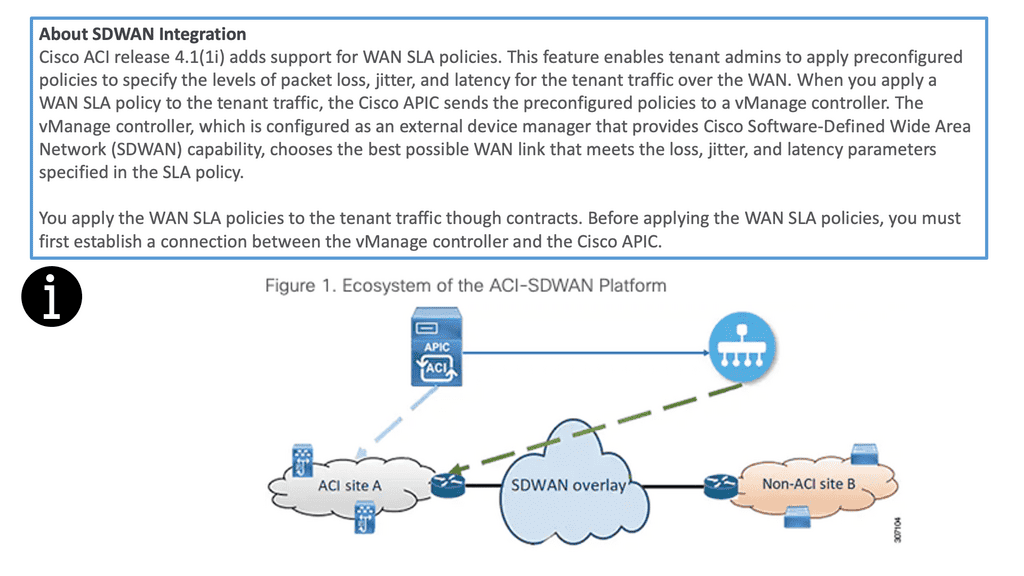
The Cisco ACI and SD-WAN integration makes active-active data center design less risky than in the past. The following figures give a high-level overview of the Cisco ACI and SD-WAN integration. For pre-information generic to SD-WAN, go here: SD-WAN Tutorial

SD WAN integration
Diagram: Cisco ACI and SD-WAN integration

The Cisco SDN ACI with SD-WAN integration helps ensure an excellent application experience by defining application Service-Level Agreement (SLA) parameters. Cisco ACI releases 4.1(1i) and adds support for WAN SLA policies. This feature enables admins to apply pre-configured policies to specify the packet loss, jitter, and latency levels for the tenant traffic over the WAN.

When you apply a WAN SLA policy to the tenant traffic, the Cisco APIC sends the pre-configured policies to a vManage controller. The vManage controller, configured as an external device manager that provides SDWAN capability, chooses the best WAN link that meets the loss, jitter, and latency parameters specified in the SLA policy.

Openshift and Cisco SDN ACI

OpenShift Container Platform (formerly known as OpenShift Enterprise) or OCP is Red Hat’s offering for the on-premises private platform as a service (PaaS). OpenShift is based on the Origin open-source project and is a Kubernetes distribution, the defacto for container-based virtualization. The foundation of the OpenShift networking SDN is based on Kubernetes and, therefore, shares some of the same networking technology along with some enhancements, such as the OpenShift route construct.

Other data center integrations

Cisco SDN ACI has another integration with Cisco DNA Center/ISE that maps user identities consistently to endpoints and apps across the network, from campus to the data center. Cisco Software-Defined Access (SD-Access) provides policy-based automation from the edge to the data center and the cloud.

Cisco SD-Access provides automated end-to-end segmentation to separate user, device, and application traffic without redesigning the network. This integration will enable customers to use standard policies across Cisco SD-Access and Cisco ACI, simplifying customer policy management using Cisco technology in different operational domains.

OpenShift and Cisco ACI

OpenShift does this with an SDN layer and enhances Kubernetes networking to create a virtual network across all the nodes. It is made with the Open Switch standard. For OpenShift SDN, this pod network is established and maintained by the OpenShift SDN, configuring an overlay network using a virtual switch called the OVS bridge. This forms an OVS network that gets programmed with several OVS rules. The OVS is a popular open-source solution for virtual switching.

OpenShift SDN plugin

We mentioned that you could tailor the virtual network topology to suit your networking requirements, which can be determined by the OpenShift SDN plugin and the SDN model you select. With the default OpenShift SDN, several modes are available. This level of SDN mode you choose is concerned with managing connectivity between applications and providing external access to them. Some modes are more fine-grained than others. The Cisco ACI plugins offer the most granular.

Integrating ACI and OpenShift platform

The Cisco ACI CNI plugin for the OpenShift Container Platform provides a single, programmable network infrastructure, enterprise-grade security, and flexible micro-segmentation possibilities. The APIC can provide all networking needs for the workloads in the cluster. Kubernetes workloads become fabric endpoints, like Virtual Machines or Bare Metal endpoints.

Cisco ACI CNI Plugin

The Cisco ACI CNI plugin extends the ACI fabric capabilities to OpenShift clusters to provide IP Address Management, networking, load balancing, and security functions for OpenShift workloads. In addition, the Cisco ACI CNI plugin connects all OpenShift Pods to the integrated VXLAN overlay provided by Cisco ACI.

Cisco SDN ACI and AppDynamics

AppDynamis overview

So, an application requires multiple steps or services to work. These services may include logging in and searching to add something to a shopping cart. These services invoke various applications, web services, third-party APIs, and databases, known as business transactions.

The user’s critical path

A business transaction is the essential user interaction with the system and is the customer’s critical path. Therefore, business transactions are the things you care about. If they start to go, your system will degrade. So, you need ways to discover your business transactions and determine if there are any deviations from baselines. This should also be automated, as learning baseline and business transitions in deep systems is nearly impossible using the manual approach.

So, how do you discover all these business transactions?

AppDynamics automatically discovers business transactions and builds an application topology map of how the traffic flows. A topology map can view usage patterns and hidden flows, acting as a perfect feature for an Observability platform.

AppDynamic topology

AppDynamics will automatically discover the topology for all of your application components. It can then build a performance baseline by capturing metrics and traffic patterns. This allows you to highlight issues when services and components are slower than usual.

AppDynamics uses agents to collect all the information it needs. The agent monitors and records the calls that are made to a service. This is from the entry point and follows executions along its path through the call stack. 

Types of Agents for Infrastructure Visibility

If the agent is installed on all critical parts, you can get information about that specific instance, which can help you build a global picture. So we have an Application Agent, Network Agent, and Machine Agent for Server visibility and Hardware/OS.

  • App Agent: This agent will monitor apps and app servers, and example metrics will be slow transitions, stalled transactions, response times, wait times, block times, and errors.  
  • Network Agent: This agent monitors the network packets, TCP connection, and TCP socket. Example metrics include performance impact Events, Packet loss, and retransmissions, RTT for data transfers, TCP window size, and connection setup/teardown.
  • Machine Agent Server Visibility: This agent monitors the number of processes, services, caching, swapping, paging, and querying. Example Metrics include hardware/software interrupts, virtual memory/swapping, process faults, and CPU/DISK/Memory utilization by the process.
  • Machine Agent: Hardware/OS – disks, volumes, partitions, memory, CPU. Example metrics: CPU busy time, MEM utilization, and pieces file.

Automatic establishment of the baseline

A baseline is essential, a critical step in your monitoring strategy. Doing this manually is hard, if not impossible, with complex applications. It is much better to have this done automatically. You must automatically establish the baseline and alert yourself about deviations from it.

This will help you pinpoint the issue faster and resolve it before it can be affected. Platforms such as AppDynamics can help you here. Any malicious activity can be seen from deviations from the security baseline and performance issues from the network baseline.

Cisco ACI • Policy & Application Flow

ACI Policy & Application Flow Lab

Follow how ACI turns application requirements into policy: Tenant → VRF → Bridge Domain → EPG → Contract → Application Flow.
ACI POLICY MODEL TENANT & NETWORK CONTEXT APPLICATION GROUPS POLICY APPLICATION FLOW Tenant Administrative container NETWORK CONTEXT VRF Layer 3 routing context Bridge Domain Endpoint network Web EPG Web application endpoints App EPG Application endpoints CONTRACT ALLOWED APPLICATION FLOW Web Servers Endpoint group App Servers Endpoint group
Tenant / VRF
Network
EPG
Contract
Application Flow
Selected Component
ACI Policy Model
ACI expresses application connectivity through a hierarchy of objects. Start at the Tenant and follow the model down to the application flow.
Object
Tenant → VRF → Bridge Domain → EPG
Policy
Contracts define which EPGs can communicate.
Why it matters
ACI lets administrators describe application connectivity as policy rather than configuring every individual switch interface.

Summary: Cisco ACI Components

In the ever-evolving world of networking, organizations are constantly seeking ways to enhance their infrastructure’s performance, security, and scalability. Cisco ACI (Application Centric Infrastructure) presents a cutting-edge solution to these challenges. By unifying physical and virtual environments and leveraging network automation, Cisco ACI revolutionizes how networks are built and managed.

Understanding Cisco ACI Architecture

At the core of Cisco ACI lies a robust architecture that enables seamless integration between applications and the underlying network infrastructure. The architecture comprises three key components:

1. Application Policy Infrastructure Controller (APIC):

The APIC serves as the centralized management and policy engine of Cisco ACI. It provides a single point of control for configuring and managing the entire network fabric. Through its intuitive graphical user interface (GUI), administrators can define policies, allocate resources, and monitor network performance.

2. Nexus Switches:

Cisco Nexus switches form the backbone of the ACI fabric. These high-performance switches deliver ultra-low latency and high throughput, ensuring optimal data transfer between applications and the network. Nexus switches provide the necessary connectivity and intelligence to enable the automation and programmability features of Cisco ACI.

3. Application Network Profiles:

Application Network Profiles (ANPs) are a fundamental aspect of Cisco ACI. ANPs define the policies and characteristics required for specific applications or application groups. By encapsulating network, security, and quality of service (QoS) policies within ANPs, administrators can streamline the deployment and management of applications.

The Power of Network Automation

One of the most compelling aspects of Cisco ACI is its ability to automate network provisioning, configuration, and monitoring. Through the APIC’s powerful automation capabilities, network administrators can eliminate manual tasks, reduce human errors, and accelerate the deployment of applications. With Cisco ACI, organizations can achieve greater agility and operational efficiency, enabling them to rapidly adapt to evolving business needs.

Security and Microsegmentation with Cisco ACI

Security is a paramount concern for every organization. Cisco ACI addresses this by providing robust security features and microsegmentation capabilities. With microsegmentation, administrators can create granular security policies at the application level, effectively isolating workloads and preventing lateral movement of threats. Cisco ACI also integrates with leading security solutions, enabling seamless network enforcement and threat intelligence sharing.

Conclusion

Cisco ACI is a game-changer in the realm of network automation and infrastructure management. Its innovative architecture, coupled with powerful automation capabilities, empowers organizations to build agile, secure, and scalable networks. By leveraging Cisco ACI’s components, businesses can unlock new levels of efficiency, flexibility, and performance, ultimately driving growth and success in today’s digital landscape.

SDN Data Center

SDN Data Center

SDN Data Center

The world of technology consists of data centers that play a crucial role in storing and managing vast amounts of information. Traditional data centers, however, have faced challenges in terms of scalability, flexibility, and efficiency. Enter Software-Defined Networking (SDN), a groundbreaking approach reshaping the landscape of data centers. In this blog post, we will explore the concept of SDN, its benefits, and its potential to revolutionize data centers as we know them.

In SDN, the functions of network nodes (switches, routers, bare metal servers, etc.) are abstracted so they can be managed globally and coherently. A single controller, the SDN controller, manages the whole entity coherently by detaching the network device's decision-making part (control plane) from its operational part (data plane).

The name "Software Defined" comes from this controller, allowing "network programmability." The Open Networking Foundation (ONF) was founded in March 2011 to promote the concept and development of OpenFlow. In 2009, the University of Stanford (US) and its research center (ONRC) published the first OpenFlow specifications, one of the protocols used by SDN controllers.

Traditional data center networks often face challenges such as complex configurations, limited scalability, and lack of agility. SDN technology addresses these issues by introducing a software-based approach to network management. With SDN, data center operators can automate network provisioning, streamline operations, and achieve greater scalability. Moreover, SDN enables network virtualization, allowing multiple virtual networks to coexist on a shared physical infrastructure, leading to improved resource utilization.

Security is a top priority for data centers, and SDN brings notable advancements in this domain. With its centralized control, SDN provides a holistic view of the network, enabling enhanced security policies and threat detection mechanisms. By dynamically allocating resources and isolating traffic, SDN mitigates potential security breaches. Additionally, SDN facilitates network resilience through features like automatic traffic rerouting, load balancing, and real-time network monitoring.

The applications of SDN in data centers are vast and varied. One notable use case is network virtualization, which allows data center operators to create isolated virtual networks for different tenants or applications. This enhances resource allocation and provides better network performance. SDN also enables efficient load balancing across servers, optimizing resource utilization and improving application delivery. Furthermore, SDN facilitates the deployment of network services, such as firewalls and intrusion detection systems, in a more agile and scalable manner.

Highlights: SDN Data Center

SDN Data Center

**The Architecture of SDN**

– At the heart of SDN lies its unique architecture, which comprises three main components: the application layer, the control layer, and the infrastructure layer. The application layer is responsible for delivering network services to the users. The control layer, often referred to as the SDN controller, acts as the brain of the network, making intelligent decisions and managing data flow.

– Finally, the infrastructure layer consists of the physical network devices that execute the commands of the SDN controller. This separation of roles allows for unprecedented control over the network, optimizing performance and resource allocation.

**Benefits of Implementing SDN in Data Centers**

– One of the most significant advantages of SDN is its ability to enhance network agility and flexibility. With SDN, network administrators can programmatically manage, configure, and optimize network resources in real-time. This leads to improved efficiency and reduced operational costs.

– Additionally, SDN supports automation, which minimizes human intervention and the potential for error. It also bolsters security by enabling faster detection and mitigation of threats through centralized control.

**Challenges Faced in SDN Deployment**

– Despite its numerous benefits, the deployment of SDN in data centers is not without challenges. The transition from traditional networking to SDN requires significant investment in both time and resources. There is also a steep learning curve associated with understanding and implementing SDN technologies.

– Furthermore, interoperability with existing systems can pose issues, necessitating careful planning and execution. Organizations must weigh these factors against the potential long-term gains of adopting SDN.

What is SDN:

With SDN, network nodes (switches, routers, bare-metal servers, etc.) are abstracted from their functions, which allows them to be managed globally and coherently. An SDN controller coherently manages the entire system through its control plane (control plane) and data plane (data plane (data plane).

“Network programmability” is enabled by Software Defined Controllers. March 2011 saw the founding of the Open Networking Foundation (ONF), a non-profit organization dedicated to promoting and developing OpenFlow. Research centers, such as Stanford University’s ONRC, which produced the first OpenFlow specifications in 2009, were interested in using OpenFlow as a protocol for SDN controllers.

Why do we need it?

IT teams are responsible for building and managing IT infrastructure and applications, but they should also serve key business drivers for their organization, such as these:

  1. Affordability
  2. Growth
  3. Adaptability
  4. Ability to scale
  5. A secure environment. 

As we know, non-SDN networks in the data center space have many drawbacks and present many operational challenges to modern IT infrastructures. In addition to these challenges, organisations from diverse industries raised new demands for SDN.

Data Analytics with SDN Data Center

Data analytics has become the intelligence layer of modern digital ecosystems, turning continuous streams of operational data into strategic insight. By examining metrics such as flow behavior, device health, latency trends, and workload distribution, analytics platforms help organizations understand how their infrastructure behaves under real conditions. This visibility enables proactive decision‑making—predicting congestion before it occurs, identifying misconfigurations, and optimizing resource usage with precision. As applications grow more distributed and cloud‑native, analytics ensures that performance, reliability, and security remain tightly controlled through evidence‑driven operations.

In an SDN‑powered data center, analytics gains even greater influence because SDN provides centralized control and unified telemetry across the entire fabric. With the control plane abstracted into a programmable controller, every switch, link, and flow becomes observable and adjustable in real time. Analytics feeds this controller with actionable intelligence, allowing automated policy enforcement, dynamic path selection, and rapid adaptation to shifting workloads. The result is a data center that behaves like a responsive, software‑defined organism—capable of scaling, healing, and optimizing itself through continuous feedback. Together, SDN and analytics create a highly agile, efficient, and resilient environment for modern enterprise and cloud applications.

SDN Data Center as a Programmable Fabric

An SDN Data Center transforms the traditional leaf‑spine fabric into a fully programmable, intent‑driven network where forwarding, policy, and telemetry are controlled centrally. In your JavaScript setup, the SDN controller is represented as structured JSON objects describing switches, fabrics, ECMP groups, overlay tunnels, and policy intents. These objects feed directly into your engine pipeline, allowing the simulator to evaluate how SDN intent affects routing, path selection, redundancy, and east‑west traffic behavior. This makes SDN Data Center design not just conceptual, but fully interactive inside your JavaScript environment.

Your SDN Data Center lab uses modular JavaScript engines to validate whether the controller’s intent matches the actual fabric state. The intent‑validation engine checks if leaf‑spine connectivity satisfies the SDN policy. The path‑selection engine evaluates ECMP distribution and overlay tunnel choices. The policy‑enforcement engine verifies segmentation, tenant isolation, and micro‑segmentation rules. Each engine consumes JSON topology and telemetry, returning structured results that classify the SDN fabric as aligned, partially aligned, or misaligned. This modular JavaScript design mirrors how real SDN controllers continuously verify intent against live network state.

SDN Data Centers rely heavily on telemetry, and your JavaScript setup simulates this using metrics such as fabric latency, link utilization, queue depth, and tunnel stability. The telemetry‑correlation engine merges these signals to determine whether the SDN fabric is performing according to intent. By injecting synthetic telemetry into the JSON topology, your tests reveal how SDN reacts to congestion, failures, and traffic bursts. This creates a realistic SDN Data Center visibility model where JavaScript engines evaluate both the control‑plane intent and the data‑plane reality, producing a final SDN health state that is accurate, structured, and ideal for teaching modern data center architecture.

Google Cloud Data Centers

What is Google Network Connectivity Center?

Google Network Connectivity Center (NCC) is a comprehensive network management solution designed to unify and simplify the connectivity experience. It serves as a centralized hub for managing and orchestrating network connectivity, providing a holistic view of an organization’s network. By leveraging NCC, businesses can ensure efficient and secure data flow between their on-premises infrastructure, cloud environments, and remote locations.

### Key Features of NCC

#### Centralized Management

One of the standout features of NCC is its centralized management capability. It allows network administrators to monitor and control multiple network connections from a single interface. This centralization reduces complexity and enhances operational efficiency, making it easier to identify and resolve connectivity issues swiftly.

#### Automation and Orchestration

NCC integrates powerful automation and orchestration tools, which streamline network operations. Automated workflows can be configured to handle routine tasks, reducing the manual effort required and minimizing the risk of human error. This ensures that network operations remain consistent and reliable.

#### Enhanced Security

Security is a top priority for any network management solution, and NCC is no exception. It offers robust security features such as encryption, access control, and threat detection. These features help safeguard the integrity and confidentiality of data as it moves across different network segments.

**What Are Managed Instance Groups?**

Managed Instance Groups are a powerful feature of Google Cloud that allows you to manage a group of identical virtual machine (VM) instances. These groups are designed to provide automated, scalable, and resilient VM operations. By using templates, you can define configurations for your instances, ensuring consistency and control across your infrastructure. Whether you’re running a web application or a large-scale computational workload, MIGs can help you maintain optimal performance and availability.

**The Benefits of Using Managed Instance Groups**

One of the primary benefits of Managed Instance Groups is their ability to automatically scale your infrastructure based on demand. This means you can dynamically add or remove instances in response to traffic patterns, reducing costs during low-demand periods and ensuring capacity during peak times. Additionally, MIGs come with built-in load balancing, distributing incoming traffic evenly across your instances, which enhances application reliability and performance.

**How to Set Up Managed Instance Groups on Google Cloud**

Setting up a Managed Instance Group in Google Cloud is straightforward. First, you’ll need to create an instance template, which specifies the machine type, image, and other instance properties. Then, you can create a Managed Instance Group using this template, defining parameters such as the number of instances and the scaling policy. Google Cloud provides an intuitive interface and comprehensive documentation to guide you through this process, making it accessible even for those new to cloud computing.

**Best Practices for Optimizing Managed Instance Groups**

To get the most out of your Managed Instance Groups, it’s essential to follow best practices. Start by defining clear scaling policies that align with your application’s needs. Regularly update your instance templates to incorporate the latest software updates and patches. Additionally, monitor your instance group’s performance using Google Cloud’s monitoring tools, allowing you to make data-driven decisions and optimize resource allocation.

Managed Instance Group

Understanding Container Networking Fundamentals

Container networking revolves around enabling communication between containers, as well as establishing connections with external networks. It involves various components such as virtual bridges, network namespaces, and IP routing. By understanding these fundamentals, developers and system administrators can harness the full potential of container networking to create robust and scalable applications.

Example IPv6: SDN Data Center 

OSPFv3, which stands for Open Shortest Path First version 3, is an enhanced version of OSPF designed specifically for IPv6 networks. It serves as a dynamic routing protocol that enables routers to exchange information and determine the most efficient paths for packet forwarding. Unlike its predecessor, OSPFv2, OSPFv3 fully supports the IPv6 addressing scheme, making it an essential component of modern network infrastructures.

One notable feature of OSPFv3 is its support for multiple address families, allowing for the simultaneous routing of IPv6, IPv4, and other address families. This flexibility is crucial in transitioning networks from IPv4 to IPv6 while ensuring backward compatibility. Furthermore, OSPFv3 utilizes link-local IPv6 addresses for neighbor discovery and communication, simplifying configuration and improving network scalability.

**The Value of SDN**

In addition to OpenFlow, software-defined networks (SDNs) provide another paradigm shift. In the last few years, the idea of separating the data plane, which runs in hardware ASICs on network switches, from the control plane, which runs on a central controller, has gained traction. This effort aims to develop standardized OpenFlow APIs that expose rich functionality from the hardware to the controller. For the entire data center cluster comprised of different types of switches to be uniformly programmed to enforce a specific policy, SDNs should promote programmatic interfaces that switch vendors should support. At its simplest, the data plane merely programs hardware based on the controller’s directions by serving as a set of “dumb” devices.

SDN and OpenFlow

  • SDN Controllers

SDN controllers serve as the brains of an SDN data center. They are responsible for managing and orchestrating network traffic flow. Through a centralized control plane, SDN controllers provide a unified network view, allowing administrators to implement policies, configure devices, and monitor traffic. These controllers are the driving force behind the agility and programmability offered by SDN data centers.

  • OpenFlow Protocol

The OpenFlow protocol is at the heart of SDN data centers. It enables communication between the SDN controller and network devices such as switches and routers. By separating the control plane from the data plane, OpenFlow allows administrators to control network traffic flow directly, making it easier to implement dynamic and granular network policies. The protocol facilitates the flexibility and adaptability of SDN data centers.

  • SDN Switches

SDN switches play a crucial role in SDN data centers by forwarding network packets based on instructions received from the SDN controller. These switches are programmable and provide a level of intelligence that traditional switches lack. SDN switches can implement traffic engineering, Quality of Service (QoS) policies, and security measures. Their programmability and centralized management make SDN switches an integral part of SDN data centers.

  • Network Virtualization

One of the critical advantages of SDN data centers is network virtualization. By abstracting the underlying physical network infrastructure, SDN enables the creation of virtual networks. These virtual networks can be customized, isolated, and securely provisioned, providing flexibility and scalability to meet the dynamic demands of modern applications. Network virtualization is a game-changer for SDN data centers, offering enhanced resource utilization and simplified network management.

**Scalability**

As server ports increased in density, data centers grew, making it impossible to keep up. A limited number of MAC addresses, inactive links, and multicast streams prevented multicast streams from being transported in this case. Infrastructure growth became more than a “nice to have” as needs evolved. Using SDN controllers and standardized off-the-shelf switches, adding new switches and configuring their configurations quickly became easy.

To maximize downlink throughput, all links on switches must be utilized. Local networks already know about the widespread use of spreading trees (which disable parts of links). As a result of the phenomenal growth of server density, various multipathing scenarios have been addressed using things like Multi-Chassis EtherChannel (MEC) and ECMP (Equal Cost Multi-Path) with CLOS architectures.

Virtualization is one of the abstraction capabilities brought by SDN. Multiple isolated virtual networks were used to compute and store data on servers. There was also a virtualization movement in the network industry. At different layers, SDN has been developed in several variants.

stp port states

ClOS-based architectures

In recent years, high-speed network switches have made CLOS-based31 architectures extremely popular. The CLOS topology has a simple rule: switches at tier x should only be connected to switches at tier x-1 and x+1 and never to other switches at the same tier. In this topology, redundancy provides high resilience, fault tolerance, and traffic load sharing.

Due to the many redundant paths between any two switches, network resources can be utilized efficiently. There is no oversubscription in CLOS-based architectures, which may be advantageous for some applications due to the huge bisection bandwidth. Additionally, the relatively simple topology alleviates the burden of having separate core and aggregation layers inherent in traditional three-tier architectures, which help troubleshoot traffic.

what is spine and leaf architecture

Example Technology: Nexus and VPC

Understanding Nexus Virtual Port Channel

At its core, Nexus vPC is a feature that allows two Nexus switches to appear as a single logical entity. This logical entity enables the creation of redundancy, load balancing, and seamless failover mechanisms. Linking the switches together through a virtual port channel allows them to share the traffic load and act as a unified system. This technology eliminates the traditional limitations of spanning tree protocol and unlocks new levels of performance and resiliency.

The benefits of deploying Nexus vPC are manifold. First and foremost, it enhances network availability by providing active-active links between switches. In the event of a link failure, traffic seamlessly fails over to the remaining links, minimizing downtime. Additionally, vPC enables load balancing across the links, optimizing bandwidth utilization and improving overall network performance. This feature is precious in data centers with high traffic demands.

What problems do we have, and what are we doing about them? Ask yourself: Are data centers ready and available for today’s applications and tomorrow’s emerging data center applications? Businesses and applications are putting pressure on networks to change, ushering in a new era of data center design. From 1960 to 1985, we started with mainframes and supported a customer base of about one million users.
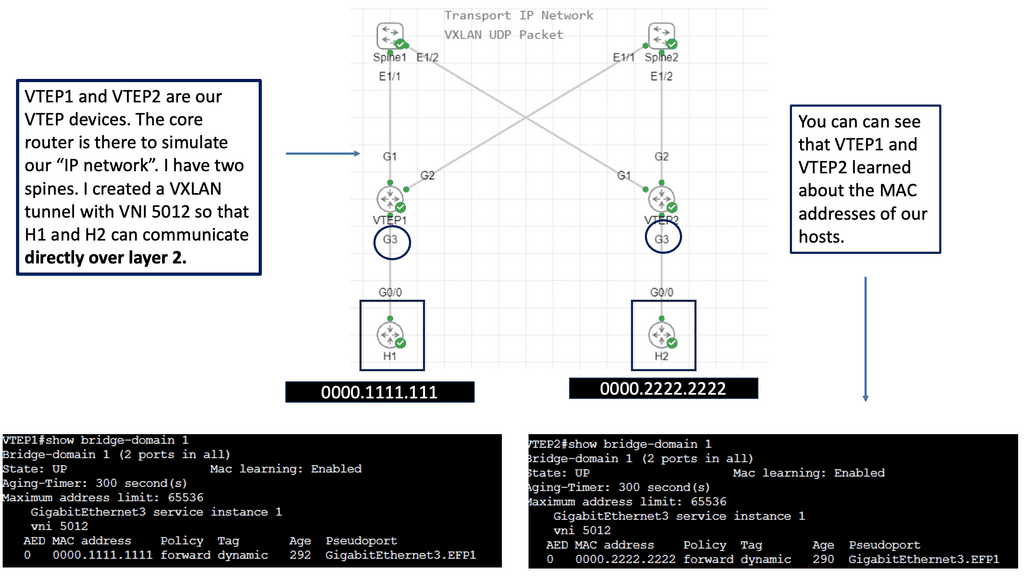
Example: ACI Cisco

ACI Cisco, short for Application Centric Infrastructure, is a software-defined networking (SDN) solution developed by Cisco Systems. It provides a holistic approach to managing and automating network infrastructure, allowing organizations to achieve agility, scalability, and security all in one framework.

Cisco ACI is a software-defined networking (SDN) solution that brings automation, scalability, and agility to network infrastructure. It combines physical and virtual elements, creating a unified and programmable network fabric that simplifies operations and accelerates application deployment. By abstracting network policies from the underlying infrastructure, Cisco ACI enables organizations to achieve policy-driven automation and policy-based security across the entire network.

Example Technology: BGP in the data center

Understanding BGP Multipath

BGP Multipath is a feature that enables the installation of multiple paths for the same destination prefix in the BGP routing table. Unlike traditional BGP, which only selects a single best path, BGP Multipath allows for the utilization of multiple paths simultaneously. This feature significantly enhances network resiliency, load balancing, and routing efficiency.

Load Balancing: BGP Multipath distributes traffic across multiple paths, preventing congestion on a single path and optimizing bandwidth utilization. This load-balancing mechanism enhances network performance and reduces bottlenecks.

Fault Tolerance: BGP Multipath increases network resilience and fault tolerance by providing redundancy. In a link failure or congestion, traffic can be seamlessly rerouted through alternative paths, ensuring uninterrupted connectivity.

Improved Convergence: BGP Multipath reduces convergence time by incorporating multiple paths into the routing decision process. This results in faster route selection and improved network responsiveness.

Security in SDN Data Centers

Example Technology: Nexus and MAC ACLs

Understanding MAC ACLs

MAC ACLs, or Media Access Control Access Control Lists, are powerful tools that allow network administrators to filter traffic based on source or destination MAC addresses. By defining specific rules, administrators can permit or deny traffic at Layer 2 and enhance network security and performance.

Nexus 9000 MAC ACLs offer several advantages over traditional access control methods. Firstly, they provide granular control at the MAC address level, enabling administrators to restrict or allow access to specific devices. Additionally, MAC ACLs can be dynamically applied to VLANs, making them highly scalable and adaptable to evolving network environments.

Configuring MAC ACLs on the Nexus 9000 is straightforward. Administrators can define ACL rules using the command-line interface (CLI) or the graphical user interface (GUI). By specifying the MAC addresses, action (permit/deny), and optional parameters, administrators can create custom access control policies tailored to their network requirements.

VXLAN Overlays

**Scalability and Agility**

With the increasing demands of modern business applications, scalability and agility are paramount. Cisco ACI offers a highly scalable architecture that can adapt to changing network requirements. By leveraging a spine-leaf topology and VXLAN overlays, Cisco ACI provides a flexible and scalable foundation that can seamlessly grow to accommodate evolving business needs.

VXLAN, at its core, is an encapsulation protocol that enables the creation of virtualized networks over existing Layer 3 infrastructure. It extends Layer 2 segments over Layer 3 networks, facilitating scalable and flexible network virtualization. Using unique VXLAN identifiers overcomes the limitations of traditional VLANs, allowing for a significantly more significant number of virtual networks to coexist.

**Benefits of VXLAN**

-Enhanced Scalability and Flexibility: VXLAN addresses the limitations of VLANs, which are often restricted to a maximum of 4096 unique IDs. With VXLAN, the pool of available IDs expands dramatically, creating an almost limitless number of virtual networks. This scalability empowers organizations to meet the demands of modern applications and dynamic workloads.

-Improved Network Segmentation: VXLAN enables efficient network segmentation by isolating traffic within virtual networks. This segmentation enhances security, simplifies network management, and provides a more robust framework for multi-tenancy environments. By leveraging VXLAN, organizations can better control and isolate their network traffic.

-Seamless Network Extension and Migration: VXLAN facilitates seamless network extension and migration across data centers, campuses, or cloud environments. By encapsulating Layer 2 frames within Layer 3 packets, VXLAN enables the creation of virtual networks that span geographically dispersed locations. This capability simplifies workload mobility, disaster recovery, and data center consolidation efforts.

Example Technology: VXLAN Flood and Learn

The Basics of Flood and Learn

As the name suggests, VXLAN Flood and Learn involves flooding network traffic to learn the MAC (Media Access Control) addresses. In traditional Ethernet networks, switches use MAC address tables to determine the destination of incoming frames. However, in VXLAN environments, the MAC addresses of virtual machines and hosts keep changing due to mobility and dynamic provisioning. Flood and Learn addresses this challenge by flooding traffic to all ports, allowing the switches to learn the MAC addresses associated with each VXLAN.

VXLAN Flood and Learn offers several benefits and finds applications in various scenarios. One such application is in data center environments with virtualized networks. It enables seamless communication between virtual machines across different hosts without requiring manual MAC address configuration. VXLAN Flood and Learn also facilitates network mobility, making it suitable for dynamic workloads and cloud environments.

Example: Software-defined data centers

To offer computing and network services to many clients, software-defined data centers (SDDCs) use virtualization technologies to separate hardware infrastructure into virtual machines. All computing, storage, and networking resources can be abstracted and represented as software in a virtualized data center. Anybody could access the data center resources if sold as a service.

SDDCs include software-defined networking (SDN) and virtual machines. In addition to Citrix, KVM, OpenDaylight, OpenStack, OpenFlow, Red Hat, and VMware, many other open and proprietary software platforms exist for virtualizing computing resources.

The advantage of SDDC is that clients do not have to build their infrastructure. They can meet their computing, networking, and storage needs by renting resources from the cloud. It is advantageous for software companies or service providers to have centralized data centers because they can serve many clients simultaneously. Hardware and storage costs are plummeting, a significant factor driving SDDC and cloud computing. Infrastructure as a Service (IaaS) becomes more economical as these resources become cheaper, making it more advantageous to build large data centers on a large scale.

Example: Open Networking Foundation

We also have the Open Networking Foundation ( ONF ), which leverages SDN principles, employs open-source platforms, and defines standards to build and operate open networking. The ONF’s portfolio includes several areas, such as mobile, broadband, and data centers running on white box hardware.

Recap on SDN Principles

SDN Defined:

SDN is an innovative approach to networking that separates the control plane from the data plane, providing a centralized and programmable network architecture. SDN enables dynamic and agile network management by decoupling network control and forwarding functions.

1. Centralized Control:

SDN leverages a central controller that acts as the brain of the network, making intelligent decisions about traffic forwarding, network policies, and resource allocation. This centralized control enhances network visibility and simplifies management tasks.

At its core, SDN centralized control refers to a network architecture in which a central controller governs the behavior of the entire network. Unlike traditional networking models, where intelligence is distributed across different network devices, SDN Centralized Control consolidates control into a single entity. This central controller acts as the brain of the network, making global decisions and orchestrating network flows.

SDN Centralized Control offers many advantages. First, it gives network administrators a holistic view of the entire network, simplifying management and troubleshooting processes. With a centralized controller, administrators can configure and monitor network devices from a single control point, saving time and effort.

2. Programmability:

One of the critical principles of SDN is its programmability. Network administrators can dynamically control and configure the network behavior by utilizing open interfaces and standard protocols like OpenFlow. This programmability empowers network operators to tailor the network to specific needs and applications.

SDN programmability is the ability to control and manipulate network behavior through software-based programming interfaces. It allows network administrators to dynamically configure and manage network resources, making networks more adaptable and responsive to changing business needs. By separating the control plane from the data plane, SDN programmability enables centralized management and control of network infrastructure, leading to simplified operations and increased efficiency.

SDN programmability empowers network administrators to respond to changing demands and quickly adapt network configurations. It allows for the creation of virtual networks, enabling the seamless segmentation and isolation of network traffic. This flexibility allows organizations to optimize network resources and support diverse applications and services.

Traditionally, scaling network infrastructure has been a complex and time-consuming task. SDN programmability simplifies the scaling process by automating the provisioning and deployment of network resources. This scalability ensures that network performance remains optimal even during peak usage periods.

3. Abstraction:

SDN abstracts the underlying network infrastructure, providing a simplified and logical view of the network. By abstracting complex network details, SDN enables higher-level automation, easier troubleshooting, and more efficient resource utilization.

SDN abstraction is the process of separating the underlying network infrastructure from the control logic that governs it. By abstracting the network resources, administrators can interact with the network at a higher level of abstraction, making it easier to manage and automate complex tasks. This abstraction layer provides a simplified, centralized network view independent of the underlying hardware and protocols.

SDN abstraction offers unprecedented flexibility by decoupling network control from the underlying infrastructure. It enables dynamic control and reconfiguration of network resources, allowing for rapid adaptation to changing requirements.

With SDN abstraction, complex network configurations can be managed through a single, intuitive interface. Administrators can define network policies and services without getting involved in the low-level details of network devices.

Abstraction simplifies network management, making it easier to scale the network infrastructure. By automating tasks and reducing the manual effort required, SDN abstraction improves operational efficiency and reduces the risk of human errors.

Google Cloud Data Centers

Understanding Network Tiers

Network tiers, in simple terms, are a hierarchical structure that categorizes the quality, performance, and cost of network connections. Google Cloud offers two main tiers: Premium Tier and Standard Tier. Let’s explore each tier in detail.

The Premium Tier is designed for businesses that demand the utmost in performance, reliability, and low latency. Leveraging Google’s vast global network infrastructure, the Premium Tier ensures optimized routing, reduced congestion, and enhanced end-user experience. Whether your application requires lightning-fast response times or handles mission-critical workloads, the Premium Tier is tailored to meet your needs.

For organizations seeking a cost-effective network solution without compromising on quality, the Standard Tier is an excellent choice. With competitive pricing, this tier offers reliable connectivity while prioritizing affordability. It serves as a viable option for applications that are less latency-sensitive or require less bandwidth.

Understanding VPC Peerings

VPC Peerings serve as a bridge between two VPC networks, allowing them to communicate as if they were part of the same network. It establishes a private and encrypted connection between VPC networks, ensuring data privacy and security. With VPC Peerings, you can extend your network’s reach, enabling collaboration and data sharing across different VPCs.

Enhanced Security: By utilizing VPC Peerings, you can establish secure connections between VPC networks without exposing your services to the public internet. This helps mitigate potential security risks and ensures your data remains protected.

Improved Performance: VPC Peerings enable low-latency and high-throughput communication between VPC networks. This allows for faster data transfer and reduces network bottlenecks, enhancing overall application performance.

Simplified Network Architecture: VPC Peerings eliminate the need for complex VPN configurations or costly dedicated connections. They simplify your network architecture by providing seamless connections and communication between VPC networks.

vCenter Server

**Seamless Management of Virtual Environments**

One of the most compelling features of vCenter Server is its ability to provide a single pane of glass for managing your entire virtual environment. This centralized control allows administrators to monitor resource allocation, optimize performance, and ensure high availability across multiple virtual machines (VMs). With vCenter Server, you can easily create, configure, and manage VMs, clusters, and data stores, ensuring that your infrastructure is always running smoothly.

**Enhanced Security and Compliance**

In today’s digital age, security is more critical than ever. vCenter Server includes robust security features designed to protect your virtual environment. From role-based access control (RBAC) to secure boot and encrypted vMotion, vCenter Server ensures that your data remains protected. Additionally, it offers compliance tools that help you adhere to industry standards and regulations, making it easier to pass audits and avoid potential fines.

**Automation and Orchestration**

Why spend countless hours on repetitive tasks when you can automate them? vCenter Server supports a variety of automation tools, including vRealize Orchestrator and PowerCLI, which allow you to script and automate routine operations. This not only saves time but also reduces the risk of human error, improving overall efficiency. With built-in automation features, you can schedule tasks such as VM provisioning, backups, and updates, freeing up your IT team to focus on more strategic initiatives.

**Scalability and Flexibility**

As your business grows, so does your need for a scalable and flexible IT infrastructure. vCenter Server is designed to scale seamlessly with your organization. Whether you’re managing a small cluster of VMs or an extensive data center, vCenter Server can handle it all. Its flexible architecture supports hybrid cloud environments, allowing you to extend your on-premises infrastructure to the cloud effortlessly. This scalability ensures that you can meet changing business demands without significant disruptions.

Related: Before you proceed, you may find the following post helpful:

  1. DNS Structure
  2. Data Center Network Design
  3. Software Defined Perimeter
  4. ACI Networks
  5. Layer 3 Data Center

SDN Data Center

The Future of Data Centers 

Exploring Software-Defined Networking (SDN)

In recent years, the rapid advancement of technology has given rise to various innovative solutions transforming how data centers operate. One such revolutionary technology is Software-Defined Networking (SDN), which has garnered significant attention and is set to reshape the landscape of data centers as we know them. In this blog post, we will delve into the fundamentals of SDN and explore its potential to revolutionize data center architecture.

SDN is a networking paradigm that separates the control plane from the data plane, enabling centralized control and programmability of network infrastructure. Unlike traditional network architectures, where network devices make independent decisions, SDN offers a centralized management approach, providing administrators with a holistic view and control over the entire network.

**The Benefits of SDN in Data Centers**

Enhanced Network Flexibility and Scalability:

SDN allows data center administrators to allocate network resources dynamically based on real-time demands. Scaling up or down becomes seamless with SDN, resulting in improved flexibility and agility. This capability is crucial in today’s data-driven environment, where rapid scalability is essential to meeting growing business demands.

Simplified Network Management:

SDN abstracts the complexity of network management by centralizing control and offering a unified view of the network. This simplification enables more efficient troubleshooting, faster service provisioning, and streamlined network management, ultimately reducing operational costs and increasing overall efficiency.

Increased Network Security:

By offering a centralized control plane, SDN enables administrators to implement stringent security policies consistently across the entire data center network. SDN’s programmability allows for dynamic security measures, such as traffic isolation and malware detection, making it easier to respond to emerging threats.

SDN and Network Virtualization:

SDN and network virtualization are closely intertwined, as SDN provides the foundation for implementing network virtualization in data centers. By decoupling network services from physical infrastructure, virtualization enables the creation of virtual networks that can be customized and provisioned on demand. SDN’s programmability further enhances network virtualization by allowing the rapid deployment and management of virtual networks.

Back to Basics: SDN Data Center

From 1985 to 2009, we moved to the personal computer, client/server model, and LAN /Internet model, supporting a customer base of hundreds of millions. From 2009 to 2020+, the industry has completely changed. We have various platforms (mobile, social, big data, and cloud) with billions of users, and it is estimated that the new IT industry will be worth 4.8T. All of these are forcing us to examine the existing data center topology.

SDN data center architecture is a type of architectural model that adds a level of abstraction to the functions of network nodes. These nodes may include switches, routers, bare metal servers, etc.), to manage them globally and coherently. So, with an SDN topology, we have a central place to work a disparate network of various devices and device types.

We will discuss the SDN topology in more detail shortly. At its core, SDN enables the entire network to be centrally controlled, or ‘programmed,’ using a software SDN application layer. The significant advantage of SDN is that it allows operators to manage the whole network consistently, regardless of the underlying network technology.

SDN Data Center
SDN Data Center

Statistics don’t lie.

The customer has changed and is making us change our data center topology. Content doubles over the next two years, and emerging markets may overtake mature markets. We expect 5,200 GB of data/per person created in 2020. These new demands and trends are putting a lot of duress on the amount of content that will be made, and how we serve and control this content poses new challenges to data networks.

Knowledge check for other software-defined data center market

The software-defined data center market is considerable. In terms of revenue, it was estimated at $43.178 billion in 2020. However, this has grown significantly; now, the software-defined data center market will grow to $120.3 billion by 2025, representing a CAGR of 22.4%.

Knowledge Check for SDN data center architecture and SDN Topology.

Software Defined Networking (SDN) simplifies computer network management and operation. It is an approach to network management and architecture that enables administrators to manage network services centrally using software-defined policies. In addition, the SDN data center architecture enables greater visibility and control over the network by separating the control plane from the data plane. Administrators can control routing, traffic management, and security by centralized managing networks. With global visibility, administrators can control the entire network. They can then quickly apply network policies to all devices by creating and managing them efficiently.

The Value: SDN Topology

An SDN topology separates the control plane from the data plane connected to the physical network devices. This allows for better network management and configuration flexibility, and configuring the control plane can create a more efficient and scalable network.

The SDN topology has three layers: the control plane, the data plane, and the physical network. The control plane controls the data plane, which carries the data packets. It is also responsible for setting up virtual networks, configuring network devices, and managing the overall SDN topology.

A personal network impact assessment report

I recently approved a network impact assessment for various data center network topologies. One of my customers was looking at rate-limiting current data transfer over the WAN ( Wide Area Network ) at 9.5mbps over 10 hours for 34GB of data transfer at an off-prime time window. Due to application and service changes, this customer plans to triple that volume over the next 12 months.

They result in a WAN upgrade and a change in the scope of DR ( Disaster Recovery ). Big Data, Applications, Social Media, and Mobility force architects to rethink how they engineer networks. We should concentrate more on scale, agility, analytics, and management.

SDN Data Center Architecture: The 80/20 traffic rule

The data center design was based on the 80/20 traffic pattern rule with Spanning Tree Protocol ( 802.1D ), where we have a root, and all bridges build a loop-free path to that root. This results in half ports forwarding and half in a blocking state—completely wasting your bandwidth even though we can load balance based on a certain number of VLANs forwarding on one uplink and another set of VLANs forwarding on the secondary uplink.

We still face the problems and scalability of having large Layer 2 domains in your data center design. Spanning tree is not a routing protocol; it’s a loop prevention protocol, and as it has many disastrous consequences, it should be limited to small data center segments.
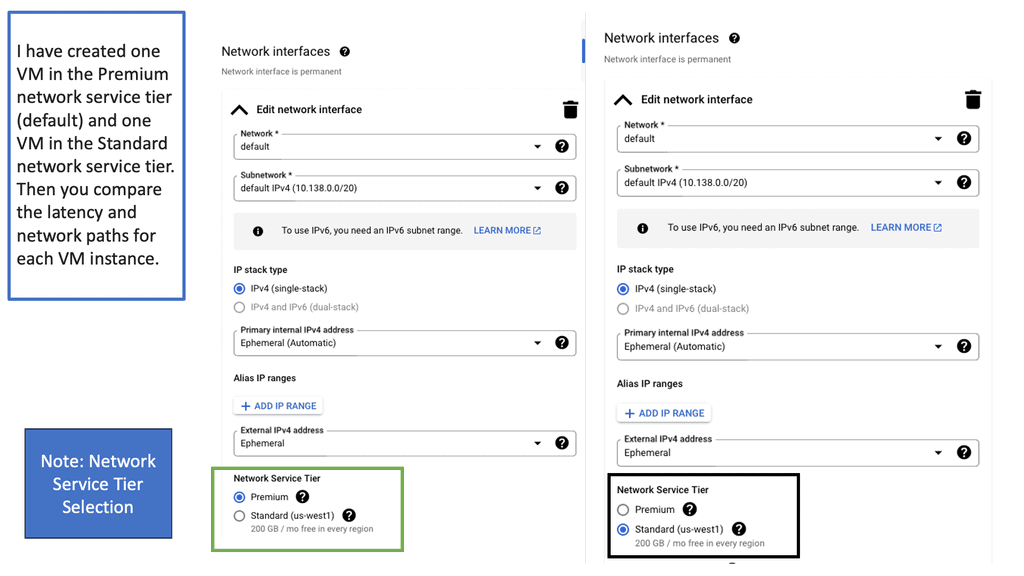
SDN Data Center

Data Center Stability


Layer 2 to the Core layer

STP blocks reduandant links

Manual pruning of VLANs for redudancy design

Rely on STP convergence for topology changes

Efficient and stable design

Data Center Topology: The Shifting Traffic Patterns

The traffic patterns have shifted, and the architecture needs to adapt. Before, we focused on 80% leaving the DC, while now, a lot of traffic is going east to west and staying within the DC. The original traffic pattern made us design a typical data center style with access, core, and distribution based on Layer 2, leading to Layer 3 transport. The route you can approach was adopted as Layer 3, which adds stability to Layer 2 by controlling broadcast and flooding domains.

The most popular data architecture in deployment today is based on very different requirements, and the business is looking for large Layer 2 domains to support functions such as VMotion. We need to meet the challenge of future data center applications, and as new apps come out with unique requirements, it isnt easy to make adequate changes to the network due to the protocol stack used. One way to overcome this is with overlay networking and VXLAN.
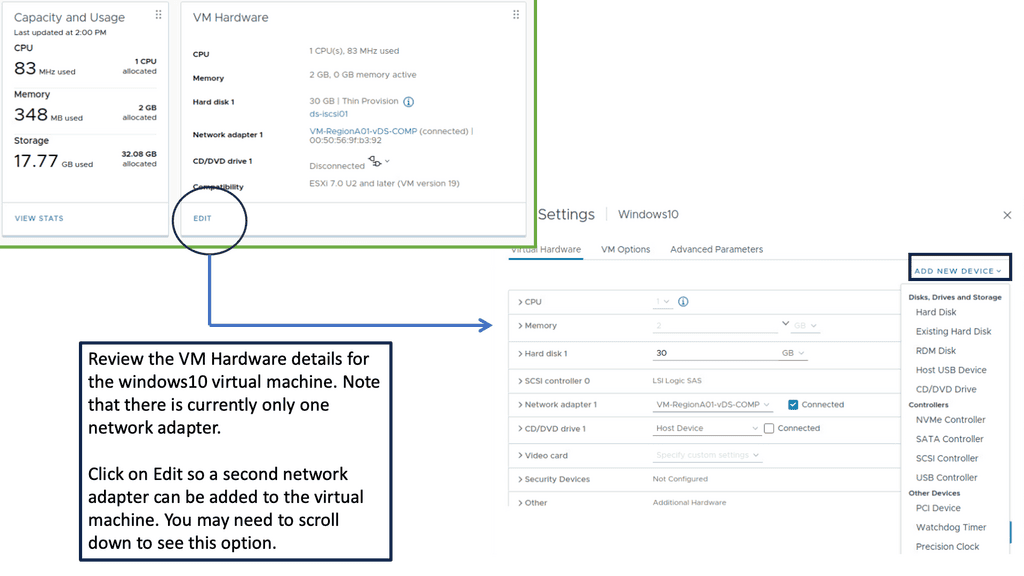
Overlay networking
Diagram: Overlay Networking with VXLAN

The Issues with Spanning Tree

The problem is that we rely on the spanning tree, which was useful before but is past its date. The original author of the spanning tree is now the author of THRILL ( replacement to STP ). STP ( Spanning Tree Protocol ) was never a routing protocol to determine the best path; it was used to provide a loop-free path. STP is also a fail-open protocol ( as opposed to a Layer 3 protocol that fails closed ).

STP Path distribution

One of the spanning trees’ most significant weaknesses is their failure to open. If I don’t receive a BPDU ( Bridge Protocol Data Unit ), I assume I am not connected to a switch and start forwarding on that port. Combining a fail-open paradigm with a flooding paradigm can be disastrous.

STP va Routing Blocking Links

Next, let’s address the Spanning Tree Protocol on a network of 3 switches. STP is there to help, but in some cases, it blocks specific ports based on the default configuration or by the administrator forcing traffic to get a certain way. Either way, you can lose bandwidth. It is easy to demonstrate this by looking at three switches in the diagram. You would want all of these links in a forwarding state, but with STP, one of the links is blocked to prevent loops.

Since the spanning tree is enabled, all our switches will send a unique frame to each other called a BPDU (Bridge Protocol Data Unit). The spanning tree requires two pieces of information in this BPDU: the MAC address and Priority. Together, the MAC address and priority make up the bridge ID.

The spanning tree requires the bridge ID for its calculation. Let me explain how it works:

  • First, a spanning tree will elect a root bridge; this root bridge will have the best “bridge ID.”
  • The switch with the lowest bridge ID is the best one.
  • The priority is 32768 by default, but we can change this value.

Spanning Tree Root Switch

So, who will become the root bridge? In our example, SW1 will become the root bridge! The bridge ID is made up of priority and MAC address. Since all switches have the same priority, the MAC address will be the tiebreaker. SW1 has the lowest MAC address, thus the best bridge ID, and will become the root bridge. The ports on our root bridge are always designated, which means they are forwarding. 

Above, you see that SW1 has been elected as the root bridge, and the “D” on the interfaces stands for designated.

Now we have agreed on the root bridge, our next step for all our “non-root” bridges (so that’s every switch that is not the root) will be to find the shortest path to our root bridge! The shortest path to the root bridge is called the “root port.” Take a look at my example:

stp port states

VPC for Nexus Data Centers

Port States:

 If you have played with some Cisco switches before, you might have noticed that every time you plugged in a cable, the LED above the interface was orange and, after a while, became green. What is happening at this moment is that the spanning tree is determining the state of the interface; this is what happens as soon as you plug in a cable:

  • The port is in listening mode for 15 seconds. In this phase, it will receive and send BPDUs but not learn MAC addresses or transmit data.
  • The port is in learning mode for 15 seconds.  We are still sending and receiving BPDUs, but now the switch will also learn MAC addresses. There is still no data transmission, though.
  • Now we go into forwarding mode, and finally, we can transmit data!

How does this compare to routing? With layer 3, we have a TTL, meaning we can stop loops as long as there is no complicated route redistribution at different points in the network topology. Let’s look at the following example, which uses RIP.

RIP is a distance vector routing protocol and the simplest one. We’ll start by paying attention to the distance vector class. What does the name distance vector mean?

    • Distance: How far away? In the routing world, we use metrics.
    • Vector: Which direction? In the routing world, we care about which interface and the next router’s IP address to send the packet to.

Notice below we are not blocking ports. Instead, we are load balancing.

RIP load balancing

Analysis:

Load-sharing between packets or destinations (actually source/destination IP address pairs) is supported by Cisco Express Forwarding (CEF) without performance degradation (without CEF, per-packet load-sharing requires process switching). Even though there is no performance impact on the router, per-packet load sharing almost always results in out-of-order packets. As a result of packet reordering, TCP throughput might be reduced in high-speed environments (per-packet load-sharing improves per-flow throughput in low-speed/few-flow scenarios) or applications that cannot survive out-of-order packet delivery, for example, Fast Sequenced Transport for SNA over IP or voice/video streams, may suffer.

Use the ip load-sharing per-packet interface configuration command to configure per-packet load-sharing (the default is per destination). This command must be used to configure all outgoing interfaces where traffic is load-shared.

STP has a bad reputation

STP, in theory, prevents bridging loops. Many reasons contribute to STP’s lousy reputation in practice.

You must accept that design choice if you prefer plug-and-pray networking over proper routing protocols. There is little we can do in this situation. To use alternate paths, you need an appropriate routing protocol, regardless of whether you’re routing on layer 2 (TRILL, SPB) or layer 3 (IP). Forward-on behavior is one of the main problems with STP. All links forward traffic until BPDUs block some of them.

A forwarding loop is almost certain to occur if a device drops BPDUs or if a switch loses its control plane (for example, due to a memory leak).

Design a Scalable Data Center Topology

To overcome the limitation, some are now trying to route ( Layer 3 ) the entire way to the access layer, which has its problems, too, as some applications require L2 to function, e.g., clustering and stateful devices—however, people still like Layer 3 as we have stability around routing. You have an actual path-based routing protocol managing the network, not a loop-free protocol like STP, and routing also doesn’t fail to open and prevents loops with the TTL ( Time to Live ) fields in the headers.

Convergence routing around a failure is quick and improves stability. We also have ECMP ( Equal Cost Multi-Path) paths to help with scaling and translating to scale-out topologies. This allows the network to grow at a lower cost. Scale-out is better than scale-up.

Whether you are a small or large network, having a routed network over a Layer 2 network has clear advantages. However, how we interface with the network is also cumbersome, and it is estimated that 70% of network failures are due to human errors. The risk of changes to the production network leads to cautious changes, slowing processes to a crawl.

In summary, the problems we have faced so far;

STP-based Layer 2 has stability challenges; it fails to open. Traditional bridging is controlled flooding, not forwarding, so it shouldn’t be considered as stable as a routing protocol. Some applications require Layer 2, but people still prefer Layer 3. The network infrastructure must be flexible enough to adapt to new applications/services, legacy applications/services, and organizational structures.

There is never enough bandwidth, and we cannot predict future application-driven requirements, so a better solution would be to have a flexible network infrastructure. The consequences of inflexibility slow down the deployment of new services and applications and restrict innovation.

The infrastructure needs to be flexible for the data center applications, not the other way around. It must also be agile enough not to be a bottleneck or barrier to deployment and innovation.

What are the new options moving forward?

Layer 2 fabrics ( Open standard THRILL ) change how the network works and enable a large routed Layer 2 network. A Layer 2 Fabric, for example, Cisco FabricPath, is Layer 2; it acts more than Layer 3 as it’s a routing protocol-managed topology. As a result, there is improved stability and faster convergence. It can also support massive ( up to 32 load-balanced forwarding paths versus a single forwarding path with Spanning Tree ) and scale-out capabilities.

VXLAN: Overlay networking

What is VXLAN?

Suppose you already have a Layer 3 core and must support Layer 2 end to end. In that case, you could go for an Encapsulated Overlay ( VXLAN, NVGRE, STT, or a design with generic routing encapsulation). You have the stability of a Layer 3 core and the familiarity of a Layer 2 core but can service Layer 2 end to end using UDP port numbers as network entropy. Depending on the design option, it builds an L2 tunnel over an L3 core. 

Example: Encrypted GRE with IPsec

Understanding Encrypted GRE

GRE, or Generic Routing Encapsulation, is a network protocol commonly used to encapsulate and transport different network layer protocols over an IP network. It provides a virtual point-to-point connection, allowing the transmission of data between different sites or networks. However, without encryption, the data transmitted through GRE is vulnerable to interception and unauthorized access. This is where encrypted GRE with IPSec comes into play.

IPSec, or Internet Protocol Security, is a suite of protocols used to secure IP communications by authenticating and encrypting the data packets. It provides a secure tunnel between two endpoints, ensuring the transmitted data’s confidentiality, integrity, and authenticity. By combining IPSec with GRE, organizations can create a safe and private communication channel over an untrusted network.

a. Enhanced Data Privacy: With encrypted GRE and IPSec, organizations can ensure the privacy of their data while transmitting it over public or untrusted networks. The encryption algorithms used in IPSec provide high security, making it extremely difficult for unauthorized parties to decipher the transmitted information.

b. Secure Communication: Encrypted GRE with IPSec establishes a secure tunnel between endpoints, protecting the integrity of the data. It prevents tampering, replay attacks, and other malicious activities, ensuring the information reaches its destination without any unauthorized modifications.

c. Flexibility and Compatibility: Encrypted GRE with IPSec can be implemented across various network environments, making it a versatile solution. It is compatible with different operating systems, routers, and firewalls, allowing organizations to integrate it seamlessly into their existing network infrastructure.

GRE with IPsec ipsec plus GRE

Back to VXLAN

A use case for this will be if you have two devices that need to exchange state at L2 or require VMotion. VMs cannot migrate across L3 as they need to stay in the same VLAN to keep the TCP sessions intact. Software-defined networking is changing the way we interact with the network.

It provides faster deployment and improved control. It changes how we interact with the network and has more direct application and service integration. With a centralized controller, you can view this as a policy-focused network.

Many prominent vendors will push within the framework of converged infrastructure ( server, storage, networking, centralized management ) all from one vendor and closely linking hardware and software ( HP, Dell, Oracle ). While other vendors will offer a software-defined data center in which physical hardware is virtual, centrally managed, and treated as abstraction resource pools that can be dynamically provisioned and configured ( Microsoft ).

Summary: SDN Data Center

In the dynamic landscape of technology, data centers play a crucial role in storing, processing, and delivering digital information. Traditional data centers have limitations, but the emergence of Software-Defined Networking (SDN) has revolutionized how data centers operate. In this blog post, we delved into the world of SDN data centers, exploring their benefits, key components, and potential implications.

Understanding SDN

SDN, in essence, separates the control plane from the data plane, enabling centralized network management through software. Unlike traditional networks, where network devices make individual decisions, SDN allows for a more programmable and flexible infrastructure. By abstracting the network’s control, SDN empowers administrators to manage and orchestrate their data centers dynamically.

Key Components of SDN Data Centers

It is crucial to grasp the critical components of SDN data centers to comprehend their inner workings. The SDN architecture comprises three fundamental elements: the Application Layer, Control Layer, and Infrastructure Layer. The Application Layer houses the software applications that utilize the network services, while the Control Layer handles network-wide decisions and policies. Lastly, the Infrastructure Layer comprises the physical and virtual network devices that forward data packets.

Advantages of SDN Data Centers

The adoption of SDN in data centers brings forth a myriad of advantages. Firstly, SDN enables network programmability, allowing administrators to configure and manage their networks through software interfaces. This flexibility reduces manual configuration efforts and enhances overall efficiency. Secondly, SDN data centers boast improved scalability, as the centralized control plane simplifies network expansion and resource allocation. Additionally, SDN enhances network security by enabling fine-grained control and real-time threat detection.

Potential Implications and Challenges

While SDN data centers offer numerous benefits, addressing potential implications and challenges is crucial. One concern is the potential risk of a single point of failure in the centralized control plane. Network disruptions or software vulnerabilities could significantly impact the entire data center. Moreover, transitioning from traditional networks to SDN requires careful planning, as it involves reconfiguring the existing infrastructure and training network administrators to adapt to the new paradigm.

Conclusion:

In conclusion, Software-Defined Networking (SDN) has paved the way for a new era of data centers. By separating the control and data planes, SDN empowers administrators to programmatically manage their networks programmatically, leading to enhanced flexibility, scalability, and security. Despite the challenges and potential implications, SDN data centers hold immense potential for transforming the way we architect and operate modern data centers.