Cisco ACI

ACI Cisco

Cisco ACI Components

Cisco Application Centric Infrastructure (ACI) represents a different way of approaching data centre networking. Rather than treating the network primarily as a collection of individually configured switches and interfaces, ACI uses application requirements and policy as the foundation for how connectivity, segmentation, and network behaviour are defined. This becomes particularly valuable as organizations operate physical servers, virtual machines, containers, and workloads across increasingly dynamic environments.

Cisco ACI brings the physical data centre fabric and software-defined policy model together through a centralized operational framework. The underlying network still provides the forwarding infrastructure, but administrators can define how applications and workloads should communicate without having to express every requirement as a series of device-by-device configurations. This separation between intent and implementation is central to the ACI model.

A major benefit is policy consistency. Instead of relying entirely on individual switch configurations, teams can define application relationships, network connectivity, and security requirements through policy. Those policies can then be applied across the fabric as workloads are deployed or changed, helping reduce configuration drift and making large environments easier to operate.

Security is another important part of the architecture. ACI supports segmentation and policy-based control between application tiers and workloads, allowing organizations to restrict communication according to defined requirements rather than relying solely on broad network boundaries. Integration with external security and operational platforms can further extend visibility and enforcement across the environment.

The model is also designed for scale. Modern data centres may contain large numbers of applications, virtual workloads, containers, and rapidly changing endpoints. A policy-driven fabric allows network operations to respond to those changes through automation and orchestration rather than requiring every network change to be handled manually. This can improve deployment consistency while reducing operational overhead.

ACI also provides a framework for connecting traditional physical infrastructure with virtualized and container-based workloads. This is important because most enterprise environments are not completely homogeneous: legacy applications, modern distributed applications, databases, virtualization platforms, and containerized services often coexist within the same broader architecture.

Hybrid and multi-cloud environments add another dimension. Organizations increasingly need consistent connectivity and policy across on-premises infrastructure and external cloud platforms. ACI can participate in these architectures through its integration and multi-site capabilities, helping organizations extend network and application policy across environments while recognizing that each cloud still has its own native networking and security model.

Cisco ACI is therefore best understood as a policy-driven data centre networking architecture, rather than simply a replacement for traditional switching. Its value comes from combining a scalable fabric with centralized policy, automation, segmentation, and application-aware operational models. For organizations managing complex data centre environments, this approach can provide a more consistent way to connect applications, enforce policy, and adapt the network as workloads evolve.

Cisco ACI • Interactive Architecture
ACI Fabric Architecture Explorer
Explore how APIC policy, the spine–leaf fabric and endpoint connectivity work together to create a policy-driven data-center network.
Learning objective: Understand how Cisco ACI separates policy and management from distributed forwarding — APIC defines intent while leaf and spine switches enforce and transport that policy.
MANAGEMENT / POLICY PLANE SPINE FABRIC LEAF / DATA-PLANE EDGE ENDPOINTS / WORKLOADS APIC CLUSTER Policy • Management • Orchestration SPINE 1 Fabric Transit SPINE 2 Fabric Transit LEAF 1 Endpoint Edge LEAF 2 Endpoint Edge LEAF 3 Endpoint Edge SERVER A EPG: WEB SERVER B EPG: APP SERVER C EPG: DB MULTI-PATH FABRIC / ECMP POLICY ENFORCEMENT AT THE LEAF EDGE
Fabric
Policy
Endpoint
Interactive Inspector
Cisco ACI Fabric
Fabric concept
Select a device or connection in the diagram to see how that component participates in the ACI architecture.
Selected component
Architecture overview
ACI concept
Policy-driven spine–leaf fabric
Why it matters
ACI separates centralized policy definition from distributed packet forwarding.

Highlights: Cisco ACI Components

The ACI Fabric

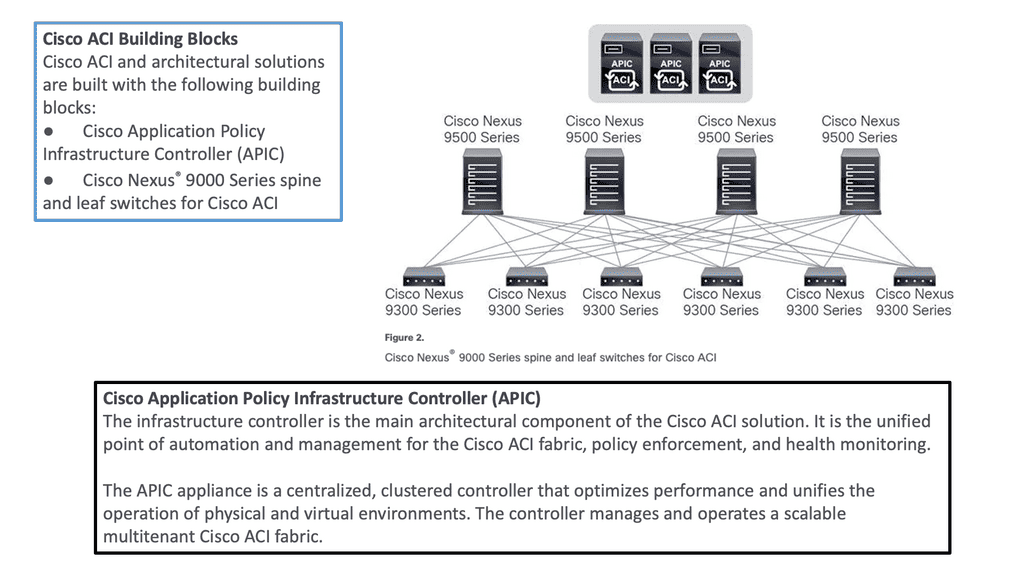
Cisco ACI is a software-defined networking (SDN) solution that integrates with software and hardware. With the ACI, we can create software policies and use hardware for forwarding, an efficient and highly scalable approach offering better performance. The hardware for ACI is based on the Cisco Nexus 9000 platform product line. The APIC centralized policy controller drives the software, which stores all configuration and statistical data.

–The Cisco Nexus Family–

To build the ACI underlay, you must exclusively use the Nexus 9000 family of switches. You can choose from modular Nexus 9500 switches or fixed 1U to 2U Nexus 9300 models. Specific models and line cards are dedicated to the spine function in ACI fabric; others can be used as leaves, and some can be used for both purposes. You can combine various leaf switches inside one fabric without any limitations.

a) Cisco ACI Fabric: Cisco ACI’s foundation lies in its fabric, which forms the backbone of the entire infrastructure. The ACI fabric comprises leaf switches, spine switches, and the application policy infrastructure controller (APIC). Each component ensures a scalable, agile, and resilient network.

b) Leaf Switches: Leaf switches serve as the access points for endpoints within the ACI fabric. They provide connectivity to servers, storage devices, and other network devices. With their high port density and advanced features, such as virtual port channels (vPCs) and fabric extenders (FEX), leaf switches enable efficient and flexible network designs.

c) Spine Switches: Spine switches serve as the core of the ACI fabric, providing high-bandwidth connectivity between the leaf switches. They use a non-blocking, multipath forwarding mechanism to ensure optimal traffic flow and eliminate bottlenecks. With their modular design and support for advanced protocols like Ethernet VPN (EVPN), spine switches offer scalability and resiliency.

d) Application Policy Infrastructure Controller (APIC): At the heart of Cisco ACI is the APIC, a centralized management and policy control plane. The APIC acts as a single control point, simplifying network operations and enabling policy-based automation. It provides a comprehensive view of the entire fabric, allowing administrators to define and enforce policies across the network.

e) Integration with Virtualization and Cloud Environments: Cisco ACI seamlessly integrates with virtualization platforms such as VMware vSphere and Microsoft Hyper-V and cloud environments like Amazon Web Services (AWS) and Microsoft Azure. This integration enables consistent policy enforcement and visibility across physical, virtual, and cloud infrastructures, enhancing agility and simplifying operations.

Cisco ACI — Policy‑Driven, Application‑Centric Networking

Cisco ACI (Application Centric Infrastructure) is Cisco’s flagship data‑center fabric built around policy‑driven automation, centralized control, and application‑aware networking. Instead of configuring individual switches, ACI abstracts the network into application policies, endpoint groups, and contracts. This creates a programmable, intent‑based fabric where the network automatically aligns with application requirements. Data analytics strengthens ACI by providing visibility into fabric health, policy behavior, endpoint movement, and application flows, ensuring that the fabric remains consistent, secure, and optimized.

Policy Model — Endpoint Groups, Contracts, and Intent

ACI’s core innovation is its policy model:

  • Endpoint Groups (EPGs) define logical groupings of workloads
  • Contracts define how EPGs communicate
  • Application Network Profiles (ANPs) map application tiers to policies
  • Tenants provide multi‑domain isolation

This model replaces traditional VLANs, ACLs, and manual segmentation with intent‑based policies. Analytics enhances this by identifying unused contracts, misaligned EPGs, shadow policies, and unexpected east‑west flows. With analytics, ACI’s policy model becomes adaptive and identity‑aware rather than static.

Fabric Architecture — Spine‑Leaf, VXLAN, and Distributed Control

ACI uses a spine‑leaf architecture with VXLAN overlays and a centralized policy controller (APIC). The fabric provides:

  • consistent forwarding across all leaf switches
  • distributed anycast gateways
  • scalable multi‑tenant segmentation
  • automated endpoint learning

Analytics correlates fabric telemetry—routing updates, VXLAN behavior, endpoint mobility, and link performance—to detect anomalies such as asymmetric routing, endpoint flapping, or misconfigured policies. This ensures the fabric remains stable and predictable even under dynamic workloads.

Security and Microsegmentation in ACI

ACI provides built‑in microsegmentation through EPGs and contracts. Security becomes application‑centric rather than IP‑centric. Analytics enhances ACI security by monitoring:

  • unusual endpoint movement
  • abnormal contract usage
  • unexpected east‑west communication
  • privilege escalation inside application tiers

This transforms ACI into a Zero Trust‑aligned data‑center fabric where segmentation is continuously validated and enforced.

Operational Visibility — Telemetry, Health Scores, and Assurance

ACI includes extensive telemetry and health scoring across:

  • fabric nodes
  • policies
  • endpoints
  • application flows

Analytics consumes this telemetry to provide deeper insights into performance, security, and policy alignment. Tools like ACI AppDynamics integration, Nexus Dashboard Insights, and fabric assurance engines use analytics to detect drift, highlight anomalies, and recommend remediation. ACI becomes a self‑optimizing fabric driven by real‑time intelligence.

ACI in Hybrid and Multi‑Cloud Architectures

ACI extends beyond the data center into cloud environments through ACI Anywhere and Cloud ACI. Policies can be pushed to AWS, Azure, and GCP, creating a unified segmentation and security model across hybrid environments. Analytics ensures consistency across on‑prem and cloud fabrics, detecting mismatches, drift, and cross‑cloud anomalies. This creates a seamless, policy‑driven hybrid architecture.

–ACI Architecture: Spine and Leaf–

To be used as ACI spines or leaves, Nexus 9000 switches must be equipped with powerful Cisco CloudScale ASICs manufactured using 16-nm technology. The following figure shows the Cisco ACI based on the Nexus 9000 series. Cisco Nexus 9300 and 9500 platform switches support Cisco ACI. As a result, organizations can use them as spines or leaves to utilize an automated, policy-based systems management approach fully. 
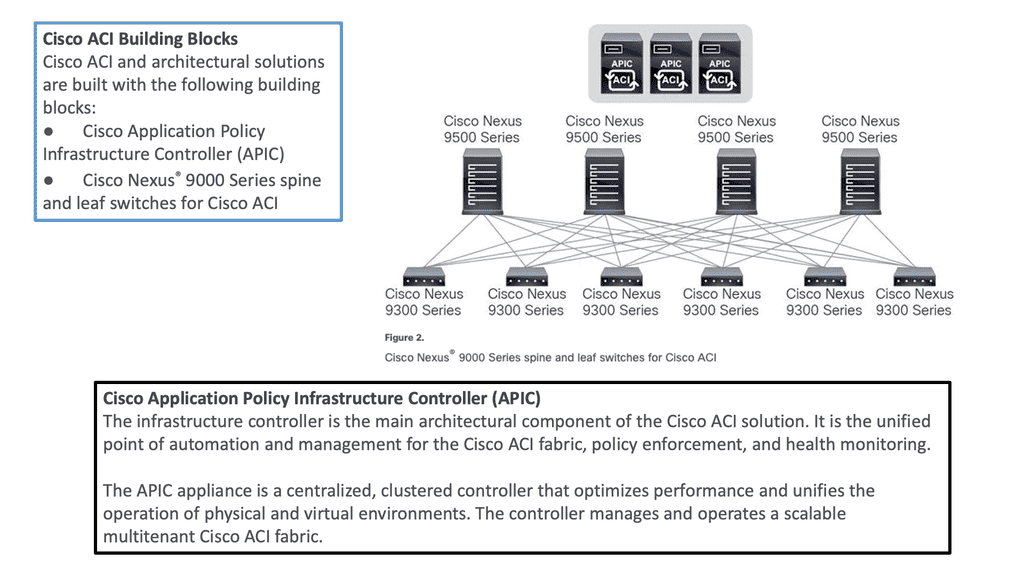
Cisco ACI Components
Diagram: Cisco ACI Components. Source is Cisco

**Hardware-based Underlay**

Server virtualization helped by decoupling workloads from the hardware, making the compute platform more scalable and agile. However, the server is not the main interconnection point for network traffic. So, we need to look at how we could virtualize the network infrastructure similarly to the agility gained from server virtualization.

**Mapping Network Endpoints**

This is carried out with software-defined networking and overlays that could map network endpoints and be spun up and down as needed without human intervention. In addition, the SDN architecture includes an SDN controller and an SDN network that enables an entirely new data center topology.

**Specialized Forwarding Chips**

In ACI, hardware-based underlay switching offers a significant advantage over software-only solutions due to specialized forwarding chips. Furthermore, thanks to Cisco’s ASIC development, ACI brings many advanced features, including security policy enforcement, microsegmentation, dynamic policy-based redirect (inserting external L4-L7 service devices into the data path), or detailed flow analytics—besides the vast performance and flexibility.


Cisco ACI • Fabric Mechanics

ACI Overlay & Underlay Lab

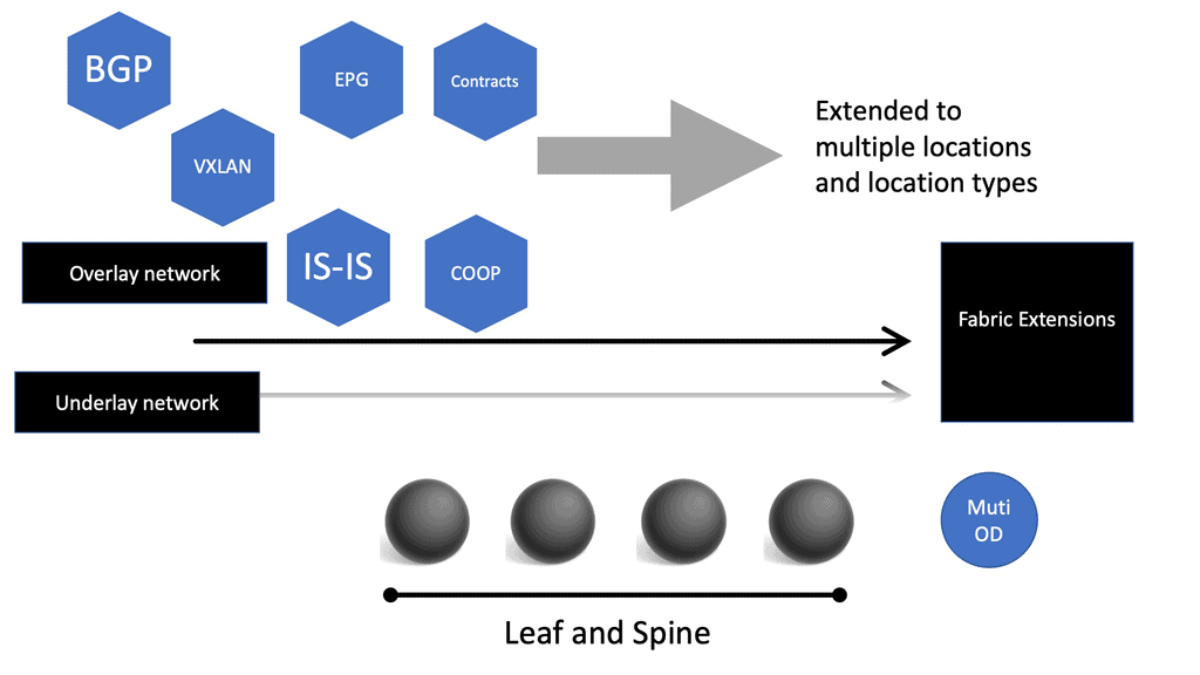
See how ACI builds the fabric: IS-IS provides the underlay, VXLAN carries the overlay, VTEPs connect endpoints, and COOP helps the fabric locate endpoints.
ACI FABRIC MECHANICS OVERLAY UNDERLAY ENDPOINTS VXLAN OVERLAY Leaf 1 VTEP Leaf 2 VTEP IS-IS UNDERLAY Spine Fabric transport Leaf 1 Underlay node Leaf 2 Underlay node COOP Endpoint database Server A Endpoint Server B Endpoint FABRIC TRANSPORT ATTACHMENT ATTACHMENT
IS-IS Underlay
VXLAN Overlay
COOP Control Plane
Endpoint Attachment
Selected Component
ACI Fabric Flow
Start here. ACI separates the physical transport network from the logical VXLAN overlay. Click a tab, node, or connection to explore how the pieces work together.
Technology
IS-IS + VXLAN + VTEP + COOP
Role
Build transport, carry overlay traffic, and locate endpoints.
Why it matters
This separation allows ACI to provide scalable fabric connectivity without making applications depend on the physical topology.

Cisco ACI Components

 Introduction to Leaf and Spine

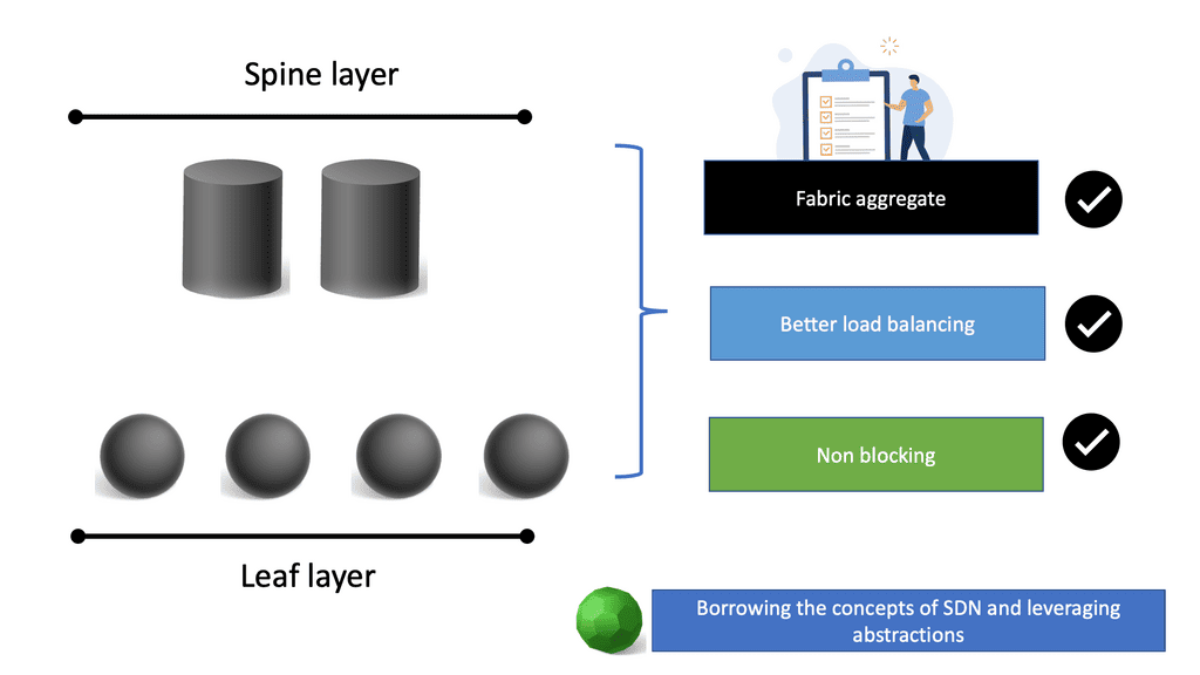
The Cisco SDN ACI works with a Clos architecture, a fully meshed ACI network. Based on a spine leaf architecture. As a result, every Leaf is physically connected to every Spine, enabling traffic forwarding through non-blocking links. Physically, a leaf switch set creates a leaf layer attached to the spines in a full BIPARTITE graph. This means that each Leaf is connected to each Spine, and each Spine is connected to each Leaf. 

The ACI uses a horizontally elongated Leaf and Spine architecture with one hop to every host in an entirely messed ACI fabric, offering good throughput and convergence needed for today’s applications.

The ACI fabric: Does Not Aggregate Traffic

A key point in the spine-and-leaf design is the fabric concept, like a stretch network. One of the core ideas around a fabric is that it does not aggregate traffic. This does increase data center performance along with a non-blocking architecture. With the spine-leaf topology, we are spreading a fabric across multiple devices.

Required: Increased Bandwidth Available

The result of the fabric is that each edge device has the total bandwidth of the fabric available to every other edge device. This is one big difference from traditional data center designs; we aggregate the traffic by either stacking multiple streams onto a single link or carrying the streams serially.

Challenge: Oversubscription

With the traditional 3-tier design, we aggregate everything at the core, leading to oversubscription ratios that degrade performance. With the ACI Leaf and Spine design, we spread the load across all devices with equidistant endpoints, allowing us to carry the streams parallel.

Required: Routed Multipathing

Then, we have horizontal scaling load balancing.  Load balancing with this topology uses multipathing to achieve the desired bandwidth between the nodes. Even though this forwarding paradigm can be based on Layer 2 forwarding ( bridging) or Layer 3 forwarding ( routing), the ACI leverages a routed approach to the Leaf and Spine design, and we have Equal Cost Multi-Path (ECMP) for both Layer 2 and Layer 3 traffic. 

**Overlay and Underlay Design**

Mapping Traffic:

So you may be asking how we can have Layer 3 routed core and pass Layer 2 traffic. This is done using the overlay, which can map different traffic types to other overlays. So, we can have Layer 2 traffic mapped to an overlay over a routed core.

L3 active-active links: ACI links between the Leaf and the Spine switches are L3 active-active links. Therefore, we can intelligently load balance and traffic steer to avoid issues. We don’t need to rely on STP to block links or involve STP in fixing the topology.

Challenge: IP – Identity & Location

When networks were first developed, there was no such thing as an application moving from one place to another while it was in use. So, the original architects of IP, the communication protocol used between computers, used the IP address to indicate both the identity of a device connected to the network and its location on the network. Today, in the modern data center, we need to be able to communicate with an application or application tier, no matter where it is.

Required: Overlay Encapsulation

One day, it may be in location A and the next in location B, but its identity, which we communicate with, is the same on both days. An overlay is when we encapsulate an application’s original message with the location to which it needs to be delivered before sending it through the network. Once it arrives at its final destination, we unwrap it and deliver the original message as desired.

The identities of the devices (applications) communicating are in the original message, and the locations are in the encapsulation, thus separating the place from the identity. This wrapping and unwrapping is done on a per-packet basis and, therefore, must be done quickly and efficiently.

**Overlay and Underlay Components**

The Cisco SDN ACI has an overlay and underlay concept, which forms a virtual overlay solution. The role of the underlay is to glue together devices so the overlay can work and be built on top. So, the overlay, which is VXLAN, runs on top of the underlay, which is IS-IS. In the ACI, the IS-IS protocol provides the routing for the overlay, which is why we can provide ECMP from the Leaf to the Spine nodes. The routed underlay provides an ECMP network where all leaves can access Spine and have the same cost links. 
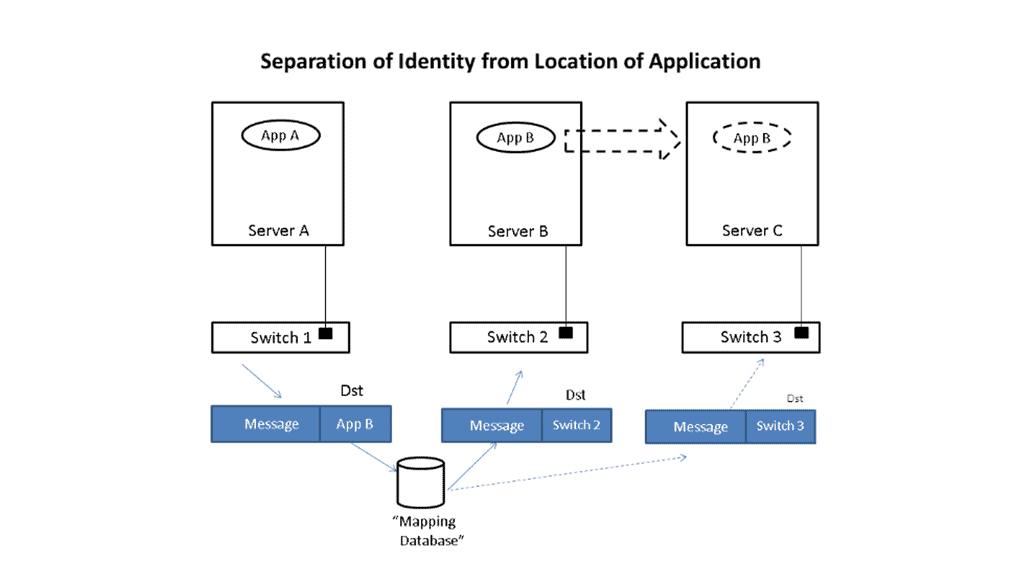
ACI overlay
Diagram: Overlay. Source Cisco

Underlay & Overlay Interaction

Example: 

Let’s take a simple example to illustrate how this is done. Imagine that application App-A wants to send a packet to App-B. App-A is located on a server attached to switch S1, and App-B is initially on switch S2. When App-A creates the message, it will put App-B as the destination and send it to the network; when the message is received at the edge of the network, whether a virtual edge in a hypervisor or a physical edge in a switch, the network will look up the location of App-B in a “mapping” database and see that it is attached to switch S2.

It will then put the address of S2 outside of the original message. So, we now have a new message addressed to switch S2. The network will forward this new message to S2 using traditional networking mechanisms. Note that the location of S2 is very static, i.e., it does not move, so using traditional mechanisms works just fine.

Upon receiving the new message, S2 will remove the outer address and thus recover the original message. Since App-B is directly connected to S2, it can easily forward the message to App-B. App-A never had to know where App-B was located, nor did the network’s core. Only the edge of the network, specifically the mapping database, had to know the location of App-B. The rest of the network only had to see the location of switch S2, which does not change.

Let’s now assume App-B moves to a new location switch S3. Now, when App-A sends a message to App-B, it does the same thing it did before, i.e., it addresses the message to App-B and gives the packet to the network. The network then looks up the location of App-B and finds that it is now attached to switch S3. So, it puts S3’s address on the message and forwards it accordingly. At S3, the message is received, the outer address is removed, and the original message is delivered as desired.

App-A did not track App-B’s movement at all. App-B’s address identified It, while the switch’s address, S2 or S3, identified its location. App-A can communicate freely with App-B no matter where It is located, allowing the system administrator to place App-B in any area and move it as desired, thus achieving the flexibility needed in the data center.

Multicast Distribution Tree (MDT)

We have a Multicast Distribution Tree MDT tree on top that is used to forward multi-destination traffic without having loops. The Multicast distribution tree is dynamically built to send flood traffic for specific protocols. Again, it does this without creating loops in the overlay network. The tunnels created for the endpoints to communicate will have tunnel endpoints. The tunnel endpoints are known as the VTEP. The VTEP addresses are assigned to each Leaf switch from a pool that you specify in the ACI startup and discovery process.

Normalize the transports

VXLAN tunnels in the ACI fabric normalize the transports in the ACI network. Therefore, traffic between endpoints can be delivered using the VXLAN tunnel, resulting in any transport network regardless of the device connecting to the fabric. 

So, using VXLAN in the overlay enables any network, and you don’t need to configure anything special on the endpoints for this to happen. The endpoints that connect to the ACI fabric do not need special software or hardware. The endpoints send regular packets to the leaf nodes they are connected to directly or indirectly. As endpoints come online, they send traffic to reach a destination.

Bridge Domains and VRF

Therefore, the Cisco SDN ACI under the hood will automatically start to build the VXLAN overlay network for you. The VXLAN network is based on the Bridge Domain (BD), or VRF ACI constructs deployed to the leaf switches. The Bridge Domain is for Layer 2, and the VRF is for Layer 3. So, as devices come online and send traffic to each other, the overlay will grow in reachability in the Bridge Domain or the VRF. 

Direct host routing for endoints

Routing within each tenant, VRF is based on host routing for endpoints directly connected to the Cisco ACI fabric. For IPv4, the host routing is based on the /32, giving the ACI a very accurate picture of the endpoints. Therefore, we have exact routing in the ACI.  In conjunction, we have a COOP database that runs on the Spines and offers remarkably optimized fabric to know where all the endpoints are located.

To facilitate this, every node in the fabric has a TEP address, and we have different types of TEPs depending on the device’s role. The Spine and the Leaf will have TEP addresses but will differ from each other.
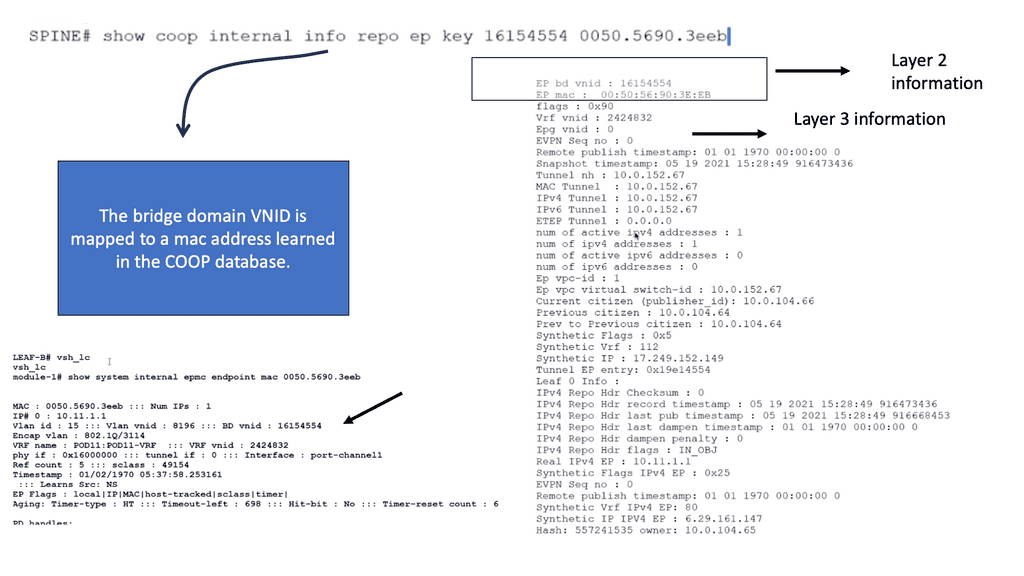
COOP database
Diagram: COOP database

The VTEP and PTEP

The Leaf’s nodes are the Virtual Tunnel Endpoints (VTEP), which are also known as the physical tunnel endpoints (PTEP) in ACI. These PTEP addresses represent the “WHERE” in the ACI fabric where an endpoint lives. Cisco ACI uses a dedicated VRF and a subinterface of the uplinks from the Leaf to the Spines as the infrastructure to carry VXLAN traffic. In Cisco ACI terminology, the transport infrastructure for VXLAN traffic is known as Overlay-1, which is part of the tenant “infra.” 

**The Spine TEP**

The Spines also have a PTEP and an additional proxy TEP, which are used for forwarding lookups into the mapping database. The Spines have a global view of where everything is, which is held in the COOP database synchronized across all Spine nodes. All of this is done automatically for you.

**Anycast IP Addressing**

For this to work, the Spines have an Anycast IP address known as the Proxy TEP. The Leaf can use this address if they do not know where an endpoint is, so they ask the Spine for any unknown endpoints, and then the Spine checks the COOP database. This brings many benefits to the ACI solution, especially for traffic optimizations and reducing flooded traffic in the ACI. Now, we have an optimized fabric for better performance.

The ACI optimizations

**Mouse and elephant flow**

This provides better performance for load balancing different flows. For example, in most data centers, we have latency-sensitive flows, known as mouse flows, and long-lived bandwidth-intensive flows, known as elephant flows. 

The ACI has more precisely load-balanced traffic using algorithms that optimize mouse and elephant flows and distribute traffic based on flow lets: flow let load-balancing. Within a Leaf, Spine latency is low and consistent from port to port.

The max latency of a packet from one port to another in the architecture is the same regardless of the network size. So you can scale the network without degrading performance. Scaling is often done on a POD-by-POD basis. For more extensive networks, each POD would be its Leaf and Spine network.

**ARP optimizations: Anycast gateways**

The ACI comes by default with a lot of traffic optimizations. Firstly, instead of using an ARP and broadcasting across the network, that can hamper performance. The Leaf can assume that the Spine will know where the destination is ( and it does via the COOP database ), so there is no need to broadcast to everyone to find a destination.

If the Spine knows where the endpoint is, it will forward the traffic to the other Leaf. If not, it will drop it.

**Fabric anycast addressing**

This again adds performance benefits to the ACI solution as the table sizes on the Leaf switches can be kept smaller than they would if they needed to know where all the destinations were, even if they were not or never needed to communicate with them. On the Leaf, we have an Anycast address too.

These fabric Anycast addresses are available for Layer 3 interfaces. On the Leaf ToR, we can establish an SVI that uses the same MAC address on every ToR; therefore, when an endpoint needs to route to a ToR, it doesn’t matter which ToR you use. The Anycast Address is spread across all ToR leaf switches. 

**Pervasive gateway**

Now we have predictable latency to the first hop, and you will use the local route VRF table within that ToR instead of traversing the fabric to a different ToR. This is the Pervasive Gateway feature that is used on all Leaf switches. The Cisco ACI has many advanced networking features, but the pervasive gateway is my favorite. It does take away all the configuration mess we had in the past.

ACI Cisco: Integrations

  • Routing Control Platform

Then came along Cisco SDN ACI, the ACI Cisco, which operates differently from the traditional data center with an application-centric infrastructure. The Cisco application-centric infrastructure achieves resource elasticity with automation through standard policies for data center operations and consistent policy management across multiple on-premises and cloud instances.

  • Extending & Integrating the fabric

What makes the Cisco ACI interesting is its several vital integrations. I’m not talking about extending the data center with multi-pod and multi-site, for example, with AlgoSec, Cisco AppDynamics, and SD-WAN. AlgoSec enables secure application delivery and policy across hybrid network estates, while AppDynamic lives in a world of distributed systems Observability. SD-WAN enabled path performance per application with virtual WANs.

Cisco Multi-Pod Design

Cisco ACI Multi-Pod is part of the “Single APIC Cluster / Single Domain” family of solutions, as a single APIC cluster is deployed to manage all the interconnected ACI networks. These separate ACI networks are named “pods,” Each looks like a regular two-tier spine-leaf topology. The same APIC cluster can manage several pods, and to increase the resiliency of the solution, the various controller nodes that make up the cluster can be deployed across different pods.
ACI Multi-Pod
Diagram: Cisco ACI Multi-Pod. Source Cisco.

ACI Cisco and AlgoSec

With AlgoSec integrated with the Cisco ACI, we can now provide automated security policy change management for multi-vendor devices and risk and compliance analysis. The AlgoSec Security Management Solution for Cisco ACI extends ACI’s policy-driven automation to secure various endpoints connected to the Cisco SDN ACI fabric.

These simplify network security policy management across on-premises firewalls, SDNs, and cloud environments. They also provide visibility into ACI’s security posture, even across multi-cloud environments. 

ACI Cisco and AppDynamics 

Then, with AppDynamics, we are heading into Observability and controllability. Now, we can correlate app health and network for optimal performance, deep monitoring, and fast root-cause analysis across complex distributed systems with numbers of business transactions that need to be tracked.

This will give your teams complete visibility of your entire technology stack, from your database servers to cloud-native and hybrid environments. In addition, AppDynamics works with agents that monitor application behavior in several ways. We will examine the types of agents and how they work later in this post.

ACI Cisco and SD-WAN 

SD-WAN brings a software-defined approach to the WAN. These enable a virtual WAN architecture to leverage transport services such as MPLS, LTE, and broadband internet services. So, SD-WAN is not a new technology; its benefits are well known, including improving application performance, increasing agility, and, in some cases, reducing costs.

The Cisco ACI and SD-WAN integration makes active-active data center design less risky than in the past. The following figures give a high-level overview of the Cisco ACI and SD-WAN integration. For pre-information generic to SD-WAN, go here: SD-WAN Tutorial
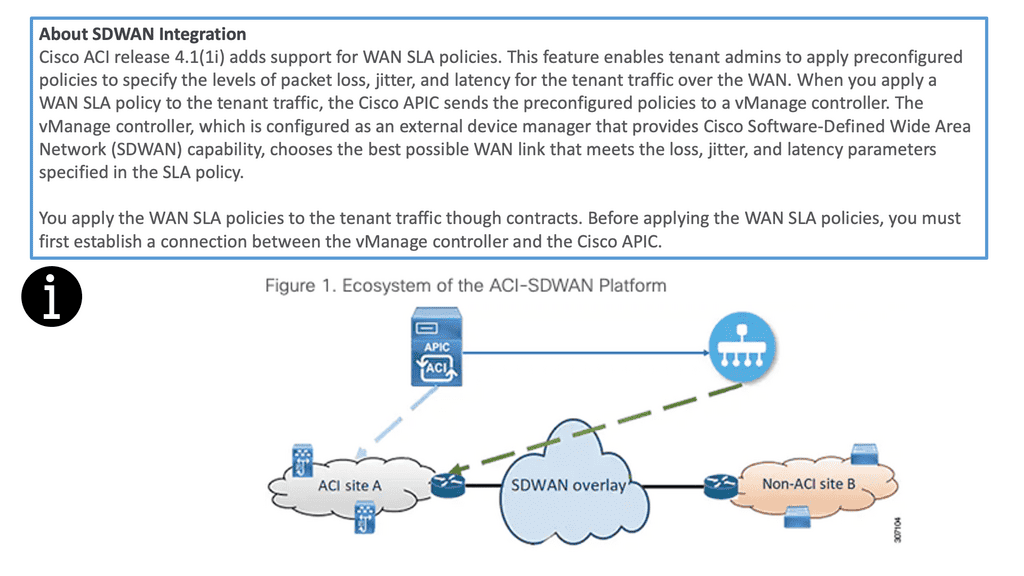
SD WAN integration
Diagram: Cisco ACI and SD-WAN integration

The Cisco SDN ACI with SD-WAN integration helps ensure an excellent application experience by defining application Service-Level Agreement (SLA) parameters. Cisco ACI releases 4.1(1i) and adds support for WAN SLA policies. This feature enables admins to apply pre-configured policies to specify the packet loss, jitter, and latency levels for the tenant traffic over the WAN.

When you apply a WAN SLA policy to the tenant traffic, the Cisco APIC sends the pre-configured policies to a vManage controller. The vManage controller, configured as an external device manager that provides SDWAN capability, chooses the best WAN link that meets the loss, jitter, and latency parameters specified in the SLA policy.

Openshift and Cisco SDN ACI

OpenShift Container Platform (formerly known as OpenShift Enterprise) or OCP is Red Hat’s offering for the on-premises private platform as a service (PaaS). OpenShift is based on the Origin open-source project and is a Kubernetes distribution, the defacto for container-based virtualization. The foundation of the OpenShift networking SDN is based on Kubernetes and, therefore, shares some of the same networking technology along with some enhancements, such as the OpenShift route construct.

Other data center integrations

Cisco SDN ACI has another integration with Cisco DNA Center/ISE that maps user identities consistently to endpoints and apps across the network, from campus to the data center. Cisco Software-Defined Access (SD-Access) provides policy-based automation from the edge to the data center and the cloud.

Cisco SD-Access provides automated end-to-end segmentation to separate user, device, and application traffic without redesigning the network. This integration will enable customers to use standard policies across Cisco SD-Access and Cisco ACI, simplifying customer policy management using Cisco technology in different operational domains.

OpenShift and Cisco ACI

OpenShift does this with an SDN layer and enhances Kubernetes networking to create a virtual network across all the nodes. It is made with the Open Switch standard. For OpenShift SDN, this pod network is established and maintained by the OpenShift SDN, configuring an overlay network using a virtual switch called the OVS bridge. This forms an OVS network that gets programmed with several OVS rules. The OVS is a popular open-source solution for virtual switching.

OpenShift SDN plugin

We mentioned that you could tailor the virtual network topology to suit your networking requirements, which can be determined by the OpenShift SDN plugin and the SDN model you select. With the default OpenShift SDN, several modes are available. This level of SDN mode you choose is concerned with managing connectivity between applications and providing external access to them. Some modes are more fine-grained than others. The Cisco ACI plugins offer the most granular.

Integrating ACI and OpenShift platform

The Cisco ACI CNI plugin for the OpenShift Container Platform provides a single, programmable network infrastructure, enterprise-grade security, and flexible micro-segmentation possibilities. The APIC can provide all networking needs for the workloads in the cluster. Kubernetes workloads become fabric endpoints, like Virtual Machines or Bare Metal endpoints.

Cisco ACI CNI Plugin

The Cisco ACI CNI plugin extends the ACI fabric capabilities to OpenShift clusters to provide IP Address Management, networking, load balancing, and security functions for OpenShift workloads. In addition, the Cisco ACI CNI plugin connects all OpenShift Pods to the integrated VXLAN overlay provided by Cisco ACI.

Cisco SDN ACI and AppDynamics

AppDynamis overview

So, an application requires multiple steps or services to work. These services may include logging in and searching to add something to a shopping cart. These services invoke various applications, web services, third-party APIs, and databases, known as business transactions.

The user’s critical path

A business transaction is the essential user interaction with the system and is the customer’s critical path. Therefore, business transactions are the things you care about. If they start to go, your system will degrade. So, you need ways to discover your business transactions and determine if there are any deviations from baselines. This should also be automated, as learning baseline and business transitions in deep systems is nearly impossible using the manual approach.

So, how do you discover all these business transactions?

AppDynamics automatically discovers business transactions and builds an application topology map of how the traffic flows. A topology map can view usage patterns and hidden flows, acting as a perfect feature for an Observability platform.

AppDynamic topology

AppDynamics will automatically discover the topology for all of your application components. It can then build a performance baseline by capturing metrics and traffic patterns. This allows you to highlight issues when services and components are slower than usual.

AppDynamics uses agents to collect all the information it needs. The agent monitors and records the calls that are made to a service. This is from the entry point and follows executions along its path through the call stack. 

Types of Agents for Infrastructure Visibility

If the agent is installed on all critical parts, you can get information about that specific instance, which can help you build a global picture. So we have an Application Agent, Network Agent, and Machine Agent for Server visibility and Hardware/OS.

  • App Agent: This agent will monitor apps and app servers, and example metrics will be slow transitions, stalled transactions, response times, wait times, block times, and errors.  
  • Network Agent: This agent monitors the network packets, TCP connection, and TCP socket. Example metrics include performance impact Events, Packet loss, and retransmissions, RTT for data transfers, TCP window size, and connection setup/teardown.
  • Machine Agent Server Visibility: This agent monitors the number of processes, services, caching, swapping, paging, and querying. Example Metrics include hardware/software interrupts, virtual memory/swapping, process faults, and CPU/DISK/Memory utilization by the process.
  • Machine Agent: Hardware/OS – disks, volumes, partitions, memory, CPU. Example metrics: CPU busy time, MEM utilization, and pieces file.

Automatic establishment of the baseline

A baseline is essential, a critical step in your monitoring strategy. Doing this manually is hard, if not impossible, with complex applications. It is much better to have this done automatically. You must automatically establish the baseline and alert yourself about deviations from it.

This will help you pinpoint the issue faster and resolve it before it can be affected. Platforms such as AppDynamics can help you here. Any malicious activity can be seen from deviations from the security baseline and performance issues from the network baseline.
Cisco ACI • Policy & Application Flow

ACI Policy & Application Flow Lab

Follow how ACI turns application requirements into policy: Tenant → VRF → Bridge Domain → EPG → Contract → Application Flow.
ACI POLICY MODEL TENANT & NETWORK CONTEXT APPLICATION GROUPS POLICY APPLICATION FLOW Tenant Administrative container NETWORK CONTEXT VRF Layer 3 routing context Bridge Domain Endpoint network Web EPG Web application endpoints App EPG Application endpoints CONTRACT ALLOWED APPLICATION FLOW Web Servers Endpoint group App Servers Endpoint group
Tenant / VRF
Network
EPG
Contract
Application Flow
Selected Component
ACI Policy Model
ACI expresses application connectivity through a hierarchy of objects. Start at the Tenant and follow the model down to the application flow.
Object
Tenant → VRF → Bridge Domain → EPG
Policy
Contracts define which EPGs can communicate.
Why it matters
ACI lets administrators describe application connectivity as policy rather than configuring every individual switch interface.

Summary: Cisco ACI Components

In the ever-evolving world of networking, organizations are constantly seeking ways to enhance their infrastructure’s performance, security, and scalability. Cisco ACI (Application Centric Infrastructure) presents a cutting-edge solution to these challenges. By unifying physical and virtual environments and leveraging network automation, Cisco ACI revolutionizes how networks are built and managed.

Understanding Cisco ACI Architecture

At the core of Cisco ACI lies a robust architecture that enables seamless integration between applications and the underlying network infrastructure. The architecture comprises three key components:

1. Application Policy Infrastructure Controller (APIC):

The APIC serves as the centralized management and policy engine of Cisco ACI. It provides a single point of control for configuring and managing the entire network fabric. Through its intuitive graphical user interface (GUI), administrators can define policies, allocate resources, and monitor network performance.

2. Nexus Switches:

Cisco Nexus switches form the backbone of the ACI fabric. These high-performance switches deliver ultra-low latency and high throughput, ensuring optimal data transfer between applications and the network. Nexus switches provide the necessary connectivity and intelligence to enable the automation and programmability features of Cisco ACI.

3. Application Network Profiles:

Application Network Profiles (ANPs) are a fundamental aspect of Cisco ACI. ANPs define the policies and characteristics required for specific applications or application groups. By encapsulating network, security, and quality of service (QoS) policies within ANPs, administrators can streamline the deployment and management of applications.

The Power of Network Automation

One of the most compelling aspects of Cisco ACI is its ability to automate network provisioning, configuration, and monitoring. Through the APIC’s powerful automation capabilities, network administrators can eliminate manual tasks, reduce human errors, and accelerate the deployment of applications. With Cisco ACI, organizations can achieve greater agility and operational efficiency, enabling them to rapidly adapt to evolving business needs.

Security and Microsegmentation with Cisco ACI

Security is a paramount concern for every organization. Cisco ACI addresses this by providing robust security features and microsegmentation capabilities. With microsegmentation, administrators can create granular security policies at the application level, effectively isolating workloads and preventing lateral movement of threats. Cisco ACI also integrates with leading security solutions, enabling seamless network enforcement and threat intelligence sharing.

Conclusion

Cisco ACI is a game-changer in the realm of network automation and infrastructure management. Its innovative architecture, coupled with powerful automation capabilities, empowers organizations to build agile, secure, and scalable networks. By leveraging Cisco ACI’s components, businesses can unlock new levels of efficiency, flexibility, and performance, ultimately driving growth and success in today’s digital landscape.

Routing Control Platform

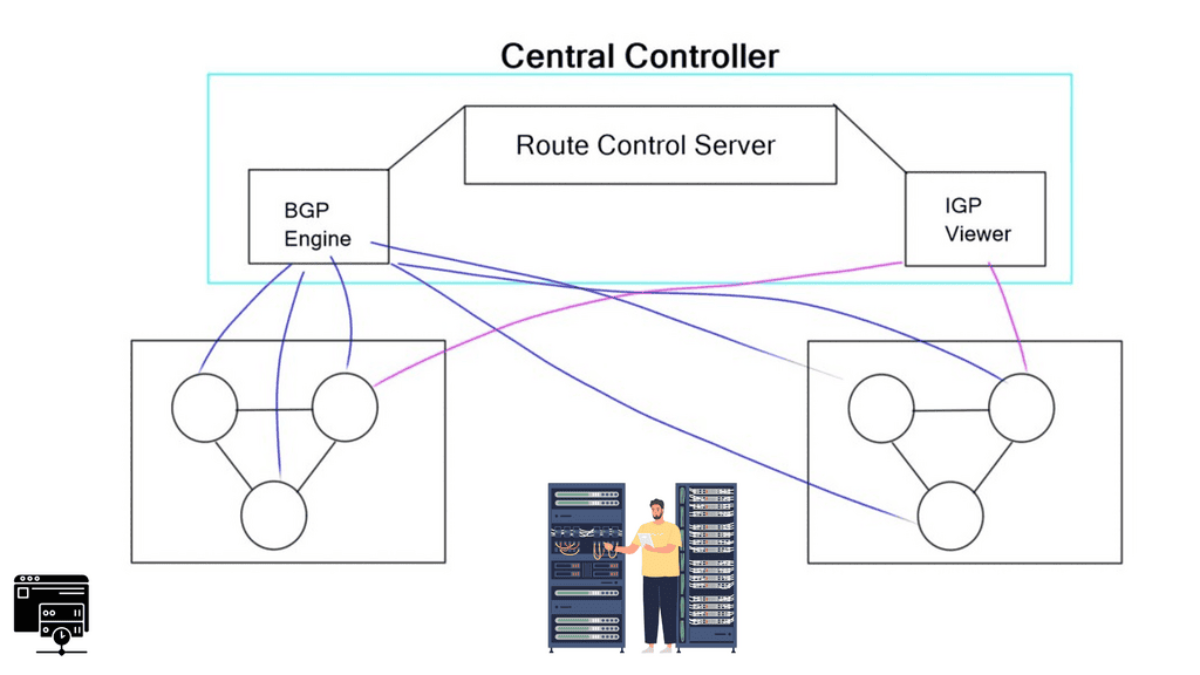
BGP-based Routing Control Platform (RCP)

Routing Control Platforms: Centralised Intelligence for BGP

How can a network make routing decisions using a wider view of topology, policy and reachability than any individual router has locally? A Routing Control Platform (RCP) explores one answer: separate the computation of routing decisions from the routers that forward packets.

In a traditional BGP design, routers select paths using the routing information and policies available to them. Route Reflectors improve iBGP scalability, but their path-selection perspective can affect which routes are advertised to clients. An RCP-style architecture combines BGP information with an IGP topology view to compute routing decisions with a broader understanding of the network.

The engineering question: Can centralised routing intelligence improve path selection and scalability without placing the controller in the packet-forwarding path—and what happens when its network view is incomplete or stale?
01 · SEE

Understand the architecture

Explore how IGP topology, BGP reachability and routing policy feed a control platform that computes route decisions.

02 · OBSERVE

Compare routing perspectives

Examine why a Route Reflector and a controller using per-router topology information may choose different exits.

03 · INVESTIGATE

Diagnose incorrect decisions

Correlate topology freshness, IGP costs, BGP state and controller output to identify the cause of a suboptimal route.

Engineering outcome: understand the distinction between centralised route computation and distributed packet forwarding, evaluate RCP against Route Reflector designs, and identify the evidence needed to validate routing correctness.
NETWORK INSIGHT · ENGINEERING GUIDE
Routing Control Platform — Investigation Path

Follow the routing decision from architecture to operational verification. Each stage builds on the evidence collected in the previous one.

ENGINEERING ORIENTATION · 01 / SEE

How a routing decision travels through RCP

Select each stage to follow the control-plane workflow, from network information to packet forwarding.

Discover the networkThe platform needs a view of IGP topology, BGP routes and relevant policy before it can calculate a useful routing decision.

RCP Architecture: From Network State to Routing Decision

A Routing Control Platform (RCP) is an architectural approach to computing BGP routing decisions with a broader view of network topology, reachability and policy. Rather than relying exclusively on each router's local view, an RCP-style system collects routing information, evaluates it centrally and communicates routing decisions back to routers.

The important distinction is between where a routing decision is calculated and where packets are forwarded. RCP moves part of the route-computation process into a control platform. The routers still perform the actual packet forwarding using their local forwarding information base (FIB).

The engineering question

Can a controller use BGP information and IGP topology to make better-informed routing decisions without becoming a dependency in the normal packet-forwarding path?

1.1 The components of an RCP-style architecture

The original RCP concept separates information collection, route computation and route distribution. Exact component names and implementation details vary, but the following model captures the core responsibilities.

INPUT · TOPOLOGY
IGP topology view

Collects information about the internal network, including links, reachability and routing metrics. This helps the controller estimate the internal cost from a relevant router to a BGP next hop or external exit.

INPUT · REACHABILITY
BGP information

Provides reachable prefixes and path attributes such as AS_PATH, LOCAL_PREF, MED and next-hop information. The available paths depend on BGP propagation, policy and the architecture used to expose routes to the platform.

COMPUTE · CONTROL
Route Control Server (RCS)

Combines the available routing information with topology and policy to calculate routing decisions. Depending on the design, it may evaluate decisions from the perspective of particular routers or regions.

OUTPUT · ROUTING
Router RIB and FIB

Routers receive and process routing information, install eligible routes and program their local forwarding tables. Their forwarding hardware or software then sends packets toward the selected next hop.

1.2 Follow the route-decision flow

A useful way to understand the design is to trace one destination prefix from discovery to forwarding. The platform needs enough accurate information to make a decision, and the routers need a valid route and resolvable next hop to forward traffic successfully.

CONTROL-PLANE WORKFLOW
01 · Discover Learn IGP topology and BGP reachability.
02 · Correlate Combine paths, metrics and routing policy.
03 · Calculate Evaluate the appropriate route decision.
04 · Distribute Routers process routes and program forwarding state.
Simplified conceptual flow: actual RCP implementations differ in how they learn routes, compute decisions and distribute results.

1.3 Control plane versus data plane

RCP is not the same as a controller that forwards every packet centrally. It is primarily concerned with the computation and distribution of routing information. Once a router has installed a route and resolved its next hop, packets are normally forwarded locally.

Function Control plane Data plane
Primary purpose Learn reachability and determine usable routes. Forward packets using installed forwarding entries.
RCP's role Correlate BGP information, topology and policy to calculate routing decisions. Not normally in the packet-by-packet forwarding path.
Router's role Maintain routing protocols and process received routing information. Resolve the destination against the FIB and forward toward the next hop.
Evidence to inspect BGP routes, attributes, IGP topology, policy and controller state. Installed route, FIB entry, next-hop resolution and observed traffic.

1.4 Why the topology view matters

BGP path selection and internal path costs answer different questions. BGP attributes and policy influence which routes are eligible and preferred; IGP information helps establish internal reachability and costs to next hops. An RCP design attempts to use both kinds of information when calculating a decision.

Consider two external exits advertising the same destination. A central platform might know that Exit A is closer to one region while Exit B is closer to another. That information can support more appropriate router-specific decisions, provided the architecture can calculate and distribute those decisions correctly.

This does not mean that the lowest IGP cost always wins. LOCAL_PREF, AS_PATH, MED, next-hop reachability, policy and the implementation's decision process can affect the outcome. Engineers must inspect the full decision chain rather than infer the chosen route from one metric.

1.5 The design's dependency: accurate, current state

Centralised computation creates a strong dependency on the quality and freshness of the information being used. If a link fails but the controller still sees an older topology, it may calculate a route using a path that is no longer available. The resulting problem may appear as a route-selection issue even when the underlying cause is stale state or failed next-hop reachability.

  • Topology: Does the controller's view match the current IGP state?
  • Reachability: Are the BGP route and its next hop still valid?
  • Policy: Are route attributes and policy applied as intended?
  • Distribution: Did the target router receive and accept the intended route?
  • Forwarding: Does the local FIB reflect the route, and does traffic succeed?

1.6 RCP and Route Reflectors are not interchangeable terms

Route Reflectors address the scaling problem of a full iBGP mesh by reducing the number of required iBGP sessions. However, a reflector generally advertises selected paths according to its BGP decision process and configuration. Clients may therefore not receive every available path, and the reflector's routing perspective may differ from a client's perspective.

RCP was proposed as an alternative architectural approach to route computation and distribution, aiming to combine BGP information with topology knowledge. It should not be treated as a universal replacement for Route Reflectors or as a guarantee of optimal routing. Results depend on the implementation, information available, policies and network design.

Section 1 engineering takeaway

RCP separates routing-decision computation from packet forwarding. To understand a route, trace the complete chain: topology and BGP inputs → policy-aware calculation → route distribution → router RIB/FIB → verified traffic outcome. The next section compares the routing perspectives behind RCP and Route Reflectors.

How Does a Routing Control Platform Make a Routing Decision?

An RCP does not sit in the packet-forwarding path. It builds a broader view of routing and topology, computes policy-aware decisions, and communicates those decisions back to the routers.

Control Plane
Network State
IG
IGP / Topology
Link-state information gives the controller visibility of network connectivity and costs.
→
Routing Inputs
BG
BGP Information
The platform learns reachable prefixes, attributes and policy-relevant routing information.
→
Control Platform
R
Route Control Server
Combines topology, BGP state and policy to calculate the appropriate route for each perspective.
→
Decision Output
IB
Routing Update
The resulting route decision is distributed to the relevant BGP speakers.
→
Forwarding
F
Router FIB
Routers continue to forward packets locally using the route installed in their forwarding plane.
Topology Visibility
The controller needs a complete network view.

The key RCP idea is visibility. Instead of making a routing decision from the limited perspective of one router, the platform combines IGP topology information with BGP reachability and policy information.

Data Plane Routers forward traffic locally
Control Plane RCP computes routing decisions
Design Goal Global visibility + scalable distribution
rcp> Collecting IGP topology + BGP reachability → building routing view...
ENGINEERING ORIENTATION · 02 / OBSERVE

Who has the right view of the network?

Choose a routing model to examine how its decision-making perspective can affect exit selection.

Available evidenceThe reflector learns BGP paths it receives and evaluates them using its own routing information and policy context.
Engineering questionDoes the selected path suit the forwarding router, or only the reflector's perspective?
What to verify: Compare the selected BGP path with the client router's IGP cost, next-hop reachability and local policy. A reflector's best path is not automatically the best path for every client.
Section 2 · Observe routing perspectives

Compare Route Reflector and RCP Perspectives

Two routers can reach the same destination but have different internal costs to the available exits. Understanding which routing information is visible—and whose perspective drives the decision—is essential when investigating unexpected BGP paths.

Route Reflectors improve iBGP scalability by reducing the need for a full mesh of internal BGP sessions. A Routing Control Platform takes a different architectural approach: it seeks to combine BGP reachability and policy with a wider view of the IGP topology when calculating routing decisions.

Observation is not the same as optimisation

A controller or reflector can only make a decision from the information and policies available to it. To establish whether a route is appropriate, compare the selected BGP path, the relevant router's IGP costs, next-hop reachability and the actual forwarding state.

2.1 What does a Route Reflector see?

In a conventional route-reflector design, clients advertise routes to the reflector, which applies BGP selection and reflection rules. The reflector generally advertises selected paths rather than every path it learns. This reduces control-plane overhead, but it can limit which alternatives are visible to clients.

SCALABILITY
Fewer iBGP sessions

Route reflection reduces the need for every internal BGP router to peer directly with every other router. This simplifies session management as the network grows.

PATH VISIBILITY
Selected paths are reflected

Standard route reflection can hide alternatives that were not selected by the reflector. Additional mechanisms or design choices may be needed when greater path diversity is required.

ROUTING PERSPECTIVE
The reflector has its own view

The reflector's BGP decision is made in its own routing context. Its IGP cost to an exit can differ from the cost seen by a client in another part of the network.

VALIDATION
Check the receiving router

The reflected route must still be evaluated in the receiving router's context, including its installed next hop, local forwarding state and reachability.

2.2 What does an RCP-style design add?

RCP was proposed to address limitations associated with distributed route computation and route reflection. By combining BGP information with an IGP topology view, a controller can attempt to calculate decisions that account for the internal cost from a particular router or region to an exit.

The goal is not simply to select one globally best exit. In some designs, the appropriate choice differs by router because internal topology and policy differ. A platform that models these differences may be able to make better-informed decisions than one relying solely on a single reflector's perspective.

Example · Two exits, two router perspectives
Exit A IGP cost from West: 20
IGP cost from East: 70
Exit B IGP cost from West: 40
IGP cost from East: 15

Illustrative IGP costs only. If the relevant BGP paths and policy permit these choices, West may favour Exit A while East may favour Exit B. Actual BGP selection is not determined by IGP cost alone.

2.3 Compare the models using evidence

Engineering question Route Reflector RCP-style approach
What is the routing input? Received BGP routes, path attributes, local topology and configured policy. BGP reachability and policy combined with a collected view of IGP topology.
How are decisions made? The reflector applies its BGP decision process to the paths it knows. The platform calculates decisions using its available routing information and design-specific logic.
Can path diversity be limited? Yes. Conventional reflection may advertise only selected paths. Potentially different path visibility, depending on how the platform learns and distributes routes.
Can topology freshness matter? Yes. Local IGP state and next-hop reachability affect routing outcomes. Yes. Stale or incomplete topology information can undermine a calculated decision.
What proves the outcome? Received route, BGP attributes, local route selection and FIB. Input freshness, computed decision, distributed route, router RIB/FIB and traffic results.

2.4 Why the shortest internal path may not win

A common troubleshooting mistake is to assume that the router must use the exit with the lowest IGP cost. BGP selection is policy-driven and considers several attributes and decision steps. LOCAL_PREF, AS_PATH, MED, next-hop validity and implementation-specific configuration can influence which route is selected before or alongside internal forwarding considerations.

For example, a higher LOCAL_PREF can cause one path to be preferred even when its exit is farther away in the IGP. That can be intentional: an organisation may prefer a particular transit provider for commercial, security or traffic-engineering reasons. The engineer must first determine the intended policy, then compare the observed decision against it.

2.5 Build a reliable observation checklist

  • Route availability: Does the relevant router know the destination prefix?
  • Path attributes: Which candidate routes are visible, and what are their LOCAL_PREF, AS_PATH and MED values?
  • Router perspective: What are the IGP costs and next-hop reachability from the affected router?
  • Reflection or distribution: Was the intended route actually advertised to the client?
  • Controller freshness: If RCP is involved, does its topology snapshot reflect the current network?
  • Forwarding state: Does the local FIB match the expected route, and can traffic reach the destination?
Section 2 engineering takeaway

Do not judge a routing architecture by the route it selects in isolation. Compare the paths it can see, the topology and policy it uses, the router for which the decision is intended, and the resulting forwarding state. In the interactive lab that follows, compare exit selection from different router perspectives before investigating a deliberately incorrect decision in Section 3.

RCP Incident: Why Did One Region Get the Wrong Exit?

A routing incident has been reported. Reachability is healthy, BGP sessions are established, but one region is taking a suboptimal exit. Examine the evidence and identify the real control-plane problem.

Troubleshooting
Incident Report

Traffic from the West region is exiting through Exit B even though Exit A is significantly closer from the West router's IGP perspective. No BGP session is down.

BGP Session Established
Prefix Reachability Available
West → Exit A 18 IGP cost
West → Exit B 61 IGP cost
RR Selected Path Exit B
Controller Topology Stale by 9 min

What is the most likely root cause?

Network State West is closer to Exit A
→
Control Decision RR perspective selects Exit B
→
Topology Visibility Controller information is stale
→
Corrective Action Refresh topology and compute per-router paths
Engineering Insight

RCP does not simply mean “put BGP in a central box.” The value is the ability to combine network-wide state with the perspective of the router that actually needs the decision. That requires accurate topology visibility. If the controller is stale, the centralised decision process can be consistently wrong even though BGP sessions and basic reachability remain healthy.

ENGINEERING ORIENTATION · 03 / INVESTIGATE

A route looks valid—but the chosen exit is wrong

Explore the evidence an engineer should check before changing routing policy.

Check session health firstAn established BGP session confirms that the peer relationship is up; it does not prove the selected exit is optimal for this router.
Section 3 · Investigate the incident

Why Did One Region Get the Wrong Exit?

A BGP session can be established, a destination prefix can be present, and traffic can still take an unexpected path. When a Routing Control Platform uses topology information to calculate route decisions, an engineer must investigate both the routing inputs and the state from which those decisions were derived.

The critical skill is separating a symptom from its cause. An unexpected exit does not automatically mean that BGP is broken, that the destination is unreachable, or that LOCAL_PREF needs to be changed. The route may have been calculated using an outdated view of the internal network.

Incident hypothesis

One region prefers Exit B even though Exit A is closer according to the current IGP topology. BGP remains established and the destination is available. The controller's topology snapshot is several minutes old. Treat stale state as a hypothesis to verify—not as a conclusion to assume.

3.1 Start with the observed symptom

Imagine a network with two external exits advertising the same destination. The West region currently forwards through Exit B. An engineer's current IGP measurements show a lower cost to Exit A, but the controller still reports Exit B as the selected path.

OBSERVED
Unexpected exit selection

Traffic from West uses Exit B even though current topology measurements suggest Exit A is closer. Confirm the actual forwarding path instead of relying only on a dashboard summary.

KNOWN EVIDENCE
BGP is still established

The relevant BGP neighbour is up and the destination prefix is available. This makes a completely failed BGP session less likely, but does not rule out route-policy or path-distribution problems.

TOPOLOGY
Current costs differ

West's measured IGP costs are 18 to Exit A and 61 to Exit B. These figures are evidence about internal reachability—not proof that BGP must choose Exit A.

SUSPICIOUS STATE
Controller data is stale

The controller's topology snapshot is reported to be nine minutes old. Verify that timestamp and compare it with the actual IGP state and recent topology changes.

3.2 Follow the evidence in a deliberate order

Use a consistent investigation sequence to avoid changing policy before the cause is known. Each check should either support or eliminate a plausible failure mode.

01 · Confirm Reproduce the wrong exit and identify the affected router, prefix and traffic direction.
02 · Inspect Check BGP neighbour state, candidate paths, attributes and route availability.
03 · Compare Compare current IGP costs and next-hop reachability with the controller's recorded view.
04 · Validate Reconcile the topology, recompute the decision and verify the router's installed route and traffic.

3.3 Distinguish the possible causes

Possible cause Evidence to collect What it tells you
BGP session failure Neighbour state, logs, route withdrawal and session history. A down session can affect route availability, but an established session does not prove that the selected path is correct.
Missing route or next hop Received prefix, next-hop resolution, RIB and FIB entries. The route may be unavailable or unusable even when other BGP sessions remain up.
Policy or BGP attributes LOCAL_PREF, AS_PATH, MED, import/export policy and candidate-path visibility. A policy decision may legitimately override an engineer's expectation based on IGP distance alone.
Stale controller topology Snapshot timestamp, topology events, current IGP database and controller refresh status. The controller may be calculating from an older network state than the routers are using.
Distribution or installation problem Computed decision, advertised route, received route and local FIB. The intended decision may not have reached the router or may not have been installed as expected.

3.4 Why stale topology can produce a wrong decision

A topology-aware controller can only calculate from the information it has. If a link changes, a metric is updated or a failure occurs, the controller needs to learn the change and update its model. Until that happens, the controller's estimate of the path to an exit may no longer match the actual network.

This is a consistency problem between the observed network and the model used for route computation. The controller might produce a decision that was reasonable under the old topology but is no longer appropriate under the current one.

The effect depends on the implementation and the failure. A stale snapshot does not always cause an incorrect exit, a forwarding loop or a blackhole. It becomes operationally significant when the outdated information changes the computed decision or leaves a next hop unreachable.

3.5 Remediate the cause, not just the symptom

If evidence confirms that the topology view is stale, the corrective action is to restore accurate information and recalculate the route decision using the platform's supported recovery procedure. Avoid applying a blanket LOCAL_PREF change simply to force the desired exit: that may mask the issue and create unintended results for other regions or destinations.

  • Refresh: Restore topology collection or synchronisation and confirm that the controller has received the current state.
  • Recompute: Recalculate the route decision with current topology, BGP routes and policy.
  • Redistribute: Confirm that the intended routing update reaches the correct router or client.
  • Verify installation: Inspect the selected route, next hop and local FIB.
  • Verify service: Test the actual traffic path and confirm reachability and performance meet expectations.

3.6 What counts as proof that the incident is resolved?

A green controller status or a successful recalculation is not sufficient on its own. The investigation is complete when the inputs are current, the selected route matches the intended policy and topology, the router installs the expected forwarding entry, and traffic follows the intended path.

Section 3 engineering takeaway

Investigate unexpected routing by correlating BGP state, route attributes, current IGP costs, controller topology freshness, route distribution and FIB state. When the controller's view is stale, repair and verify the data pipeline before changing routing policy. The incident lab that follows lets you test this reasoning against the West-region scenario.

ENGINEERING ORIENTATION · 04 / CORRELATE & OPERATE

Recovery is not proven by a single green status

Select the evidence you have verified. A routing change is complete only when the control-plane decision and forwarding outcome agree.

Evidence verified: 0 of 4
Engineering takeaway: correlate topology, route selection, forwarding state and observed traffic. A correct BGP decision alone does not guarantee end-to-end service recovery.

Correlate and Operate: Validate the Routing Decision

A routing decision is not proven correct simply because a controller calculated a path or a router received an update. Engineers need to connect the network's topology, BGP information, policy decision, installed forwarding state and observed traffic into one evidence chain.

That is the operational challenge behind a Routing Control Platform (RCP). Its value depends not only on the decision logic, but also on the freshness and consistency of the information used to make decisions—and on whether the resulting routes are distributed and installed as intended.

Follow the evidence across the control and data planes

When a region takes an unexpected exit, investigate the complete sequence. A controller may have selected a valid route using an outdated topology snapshot; a router may have received the intended route but rejected it through policy; or the routing table may be correct while forwarding still fails because of a next-hop or downstream connectivity problem.

01
Topology and reachability Check IGP state, link costs, BGP sessions and reachable prefixes.
02
Decision and policy Confirm route attributes, policy inputs, router perspective and calculation time.
03
Distribution and installation Check the advertised route, receiving router's RIB and installed FIB entry.
04
Traffic and stability Test the real path, service outcome, convergence and post-change behaviour.

Correlate symptoms with the right evidence

Observed symptom Evidence to correlate Engineering interpretation
Unexpected exit selected IGP costs, BGP attributes, policy, topology timestamp and router perspective The choice may reflect policy or a different network view—not necessarily a failed session.
Route missing from a router Received updates, import policy, next-hop reachability and routing table The route may be unavailable, filtered, ineligible or not installed.
Route present, traffic fails FIB entry, resolved next hop, interface state, ACLs and end-to-end probes Control-plane reachability does not by itself prove successful packet delivery.
Repeated path changes Update history, attribute changes, topology events, timers and policy interactions Look for interacting decisions or unstable inputs before changing attributes.

Understand the mechanisms around route selection

Hot-potato routing

Hot-potato routing generally favours the closest eligible exit according to the router's IGP view after higher-priority BGP decision criteria have been considered. Two routers can legitimately choose different exits because their IGP costs differ. A controller's view must therefore match the intended decision perspective; a low IGP cost alone does not override every BGP attribute or policy.

Multipath and BGP Add-Path

BGP multipath can allow multiple eligible paths to be installed or used, subject to implementation and configuration. BGP Add-Path allows multiple paths for a prefix to be advertised to a peer, helping reduce some path-visibility limitations. Neither feature automatically guarantees a better path or removes the need to validate policy, next-hop resolution and forwarding behaviour.

Next-hop tracking and MED

Next-hop tracking helps a router reassess route eligibility when next-hop reachability changes. MED can influence selection between routes from the same neighbouring AS, depending on the comparison rules and policy. In complex designs, interacting MED values, route reflection and changing topology can contribute to repeated path changes—but oscillation is not inevitable. Examine the actual attributes, decision order and update sequence before attributing a problem to MED.

Design boundary: RCP is a historically important control-plane architecture, not a universal modern product or a guaranteed replacement for Route Reflectors. Any centralised or controller-assisted design must account for failure modes, topology freshness, policy consistency, route distribution, controller redundancy and safe fallback behaviour.

A safe recovery workflow

Once the evidence points to stale or inconsistent topology, avoid making unrelated policy changes just to force a preferred exit. Correct the underlying input first, then confirm each downstream stage.

DetectReconcileRecomputeRedistributeVerify

  1. Capture the baseline. Record the affected prefix, selected exit, IGP costs, BGP attributes, relevant updates and current RIB/FIB state.
  2. Reconcile the network view. Confirm that topology data and reachability reflect current link and routing state. Check timestamps and the source of the data.
  3. Recompute and distribute. Re-evaluate the route using the intended policy and perspective, then verify that the expected decision reaches the affected routers.
  4. Verify installation. Confirm the route in the router's RIB, resolve the next hop and check the corresponding FIB entry. A received update is not the same as an installed route.
  5. Test the service and monitor. Use appropriate path probes or traffic tests, watch for unexpected updates or route churn, and retain a rollback path if the change causes regressions.

How do you know the incident is resolved?

Recovery is complete only when the intended route decision is visible, the forwarding entry is installed, the next hop is reachable, traffic behaves as expected and the system remains stable after convergence. Record the before-and-after evidence so that the fix can be explained and repeated—not merely assumed from a green status indicator.

Engineering takeaway Treat routing as an evidence chain: topology and reachability → BGP attributes and policy → route decision → route distribution → RIB/FIB installation → observed traffic. Verify every stage before declaring recovery.

Engineering conclusion · Routing control

From Centralised Routing Intelligence to Verified Forwarding

The Routing Control Platform concept highlights a fundamental challenge in BGP engineering: a route-selection decision is only as reliable as the network information, policy and router perspective behind it.

By combining BGP reachability with IGP topology information, an RCP can calculate routing decisions with a broader view of the network. The operational challenge is ensuring that this view remains accurate, the intended decisions reach the relevant routers, and the resulting forwarding state delivers the expected outcome.

Four engineering principles to take away

01 · Understand the architecture Separate topology discovery, BGP route information, route computation and packet forwarding.
02 · Compare perspectives Account for route visibility, IGP costs, BGP attributes and policy before explaining an exit choice.
03 · Investigate with evidence Distinguish session failure, missing reachability, policy effects, stale topology and installation problems.
04 · Verify the outcome Confirm the selected route, installed forwarding entry, next-hop reachability, traffic behaviour and stability.

The broader lesson for software-defined networking

RCP is a useful architectural case study in separating routing intelligence from packet forwarding. Its ideas remain relevant when evaluating controller-assisted networking, centralised policy, topology-aware path computation and modern network automation. However, an architecture should be judged against its actual implementation, failure handling, scalability and operational requirements—not treated as a universal replacement for established BGP designs.

The engineer's final test is not whether the controller calculated a route. It is whether the intended route was installed, traffic followed the expected path, and the network remained stable.

RCP vs Route Reflector: Which Exit Does Each Router Choose?

Experiment with the network perspective, IGP costs and routing policy. Then run the decision engine to see how a traditional Route Reflector and an RCP can produce different exit choices.

Interactive Lab
Ready: Change the conditions and run the decision engine.
Route Reflector Shared decision
Selected Exit Exit A
The RR makes the best-path decision from its own reference point and reflects that selected route to clients.
RR → Exit A 20
RR → Exit B 40
Result delivered to client Exit A
Routing Control Platform Per-router decision
Selected Exit Exit A
The RCP evaluates the available exits using the selected router's network perspective.
Router → Exit A 20
Router → Exit B 65
Decision comparison Same as RR
Routing Perspective Awaiting calculation
SOURCE WEST
RR1 RR view
ROUTER WEST VIEW
EXIT A EGRESS
EXIT B EGRESS
A: 20
B: 40
RR-selected path
Exit A
Exit B
Engineering Insight

The important difference is network perspective. A Route Reflector provides scalability by reflecting selected routes, while an RCP can calculate the appropriate route for the individual router using broader topology visibility.

☕
Support Network Insight
Help support the development of interactive networking labs, BGP simulations, and educational content.
Support the Project
data center security

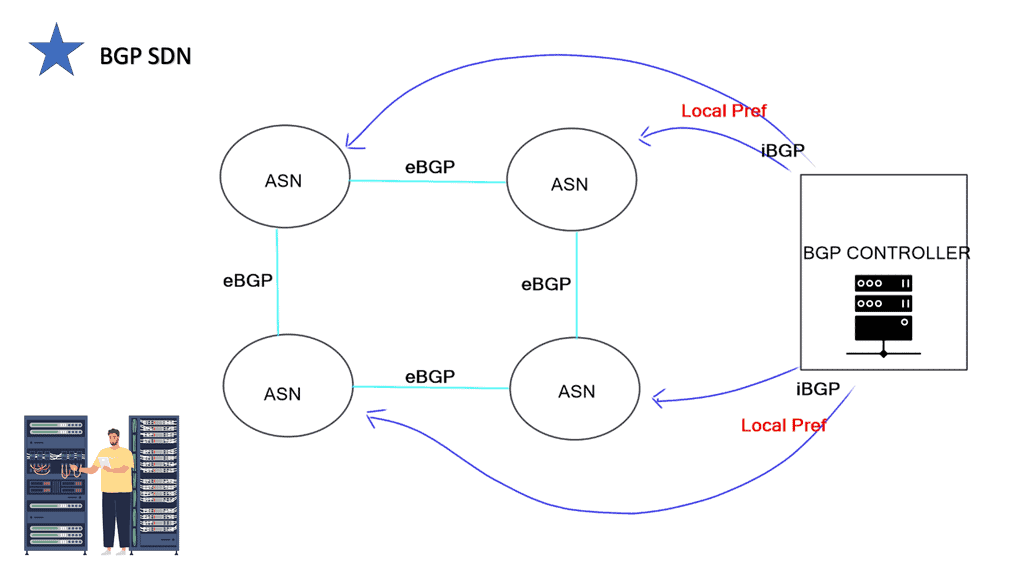
BGP SDN – Centralized Forwarding

BGP SDN

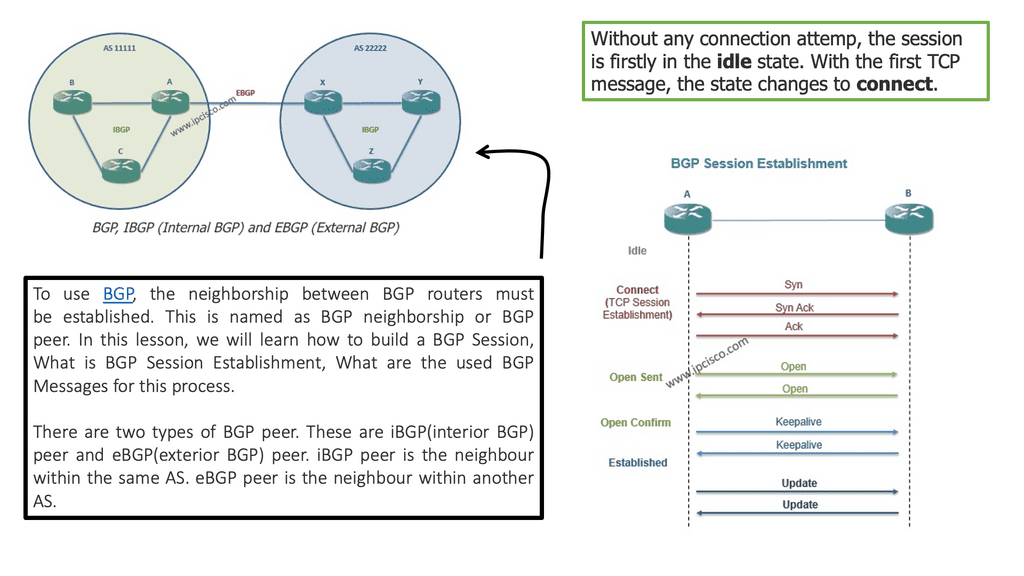
The networking landscape has significantly shifted towards Software-Defined Networking (SDN) in recent years. With its ability to centralize network management and streamline operations, SDN has emerged as a game-changing technology. One of the critical components of SDN is Border Gateway Protocol (BGP), a routing protocol that plays a vital role in connecting different autonomous systems. In this blog post, we will explore the concept of BGP SDN and its implications for the future of networking.

Border Gateway Protocol (BGP) is a dynamic routing protocol that facilitates the exchange of routing information between different networks. It enables the establishment of connections and the exchange of network reachability information across autonomous systems. BGP is the glue that holds the internet together, ensuring that data packets are delivered efficiently across various networks.

Scalability and Flexibility: BGP SDN empowers network administrators with the ability to scale their networks effortlessly. By leveraging BGP's inherent scalability and SDN's programmability, network expansion becomes a seamless process. Additionally, the flexibility provided by BGP SDN allows for the customization of routing policies, enabling network administrators to adapt to changing network requirements.

Traffic Engineering and Optimization: Another significant advantage of BGP SDN is its capability to perform traffic engineering and optimization. With granular control over routing decisions, network administrators can efficiently manage traffic flow, ensuring optimal utilization of network resources. This results in improved network performance, reduced congestion, and enhanced user experience.

Dynamic Path Selection: BGP SDN enables dynamic path selection based on various parameters, such as network congestion, link quality, and cost. This dynamic nature of BGP SDN allows for intelligent and adaptive routing decisions, ensuring efficient data transmission and load balancing across the network.

Policy-Based Routing: BGP SDN allows network administrators to define routing policies based on specific criteria. This capability enables the implementation of fine-grained traffic management strategies, such as prioritizing certain types of traffic or directing traffic through specific paths. Policy-based routing enhances network control and enables the optimization of network performance for specific applications or user groups.

BGP SDN represents a significant leap forward in network management. By combining the robustness of BGP with the flexibility of SDN, organizations can unlock new levels of scalability, control, and optimization. Whether it's enhancing network performance, enabling dynamic path selection, or implementing policy-based routing, BGP SDN paves the way for a more efficient and agile network infrastructure.

Highlights: BGP SDN

BGP SDN, which stands for Border Gateway Protocol Software-Defined Networking, combines the power of traditional BGP routing protocols with the flexibility and programmability of SDN. It enables network administrators to have granular control over their routing decisions and allows for dynamic and automated network provisioning.

**BGP SDN Centralized Forwarding**

In today’s rapidly evolving digital landscape, network management and optimization have become more critical than ever. With the burgeoning demands for higher bandwidth, lower latency, and greater network reliability, traditional networking methods are increasingly finding themselves inadequate. This is where BGP SDN Centralized Forwarding comes into play, offering a revolutionary approach to network management by combining the strengths of Border Gateway Protocol (BGP) and Software-Defined Networking (SDN).

**Understanding BGP and SDN**

Before delving into the centralized forwarding aspect, it’s crucial to understand the foundational components: BGP and SDN. BGP, a robust and mature protocol, has been the cornerstone of the internet’s routing infrastructure for decades. It is responsible for making core routing decisions and ensuring data packets find their way across the networks of different organizations. On the other hand, SDN is a modern paradigm that separates the control plane from the data plane, allowing for more agile and flexible network management. By integrating these two technologies, we can create a more efficient and manageable network.

**The Need for Centralized Forwarding**

Traditional BGP implementations operate in a distributed manner, which, while reliable, can lead to inefficiencies and complexities in network management. Centralized forwarding through SDN changes this by offering a holistic view and control over the network. This centralized approach allows network administrators to implement policies and changes from a single point, reducing complexities and potential errors. This is especially beneficial in large-scale networks where consistent and efficient routing decisions are imperative.

Key BGP SDN Considerations:

Enhanced Flexibility and Scalability: BGP SDN brings unmatched flexibility to network operators. By decoupling the control plane from the data plane, it allows for dynamic rerouting and network updates without disrupting the overall network operation. This flexibility also enables seamless scalability as networks grow or evolve over time.

Improved Network Performance and Efficiency: With BGP SDN, network administrators can optimize traffic flow by dynamically adjusting routing decisions based on real-time network conditions. This intelligent traffic engineering ensures efficient resource utilization, reduced latency, and improved overall network performance.

Simplified Network Management: By leveraging programmability, BGP SDN simplifies network management tasks. Network administrators can automate routine configuration changes, implement policies, and troubleshoot network issues more efficiently. This leads to significant time and cost savings.

Rapid Deployment of New Services: BGP SDN enables faster service deployment by allowing administrators to define routing policies and service chaining through software. This eliminates the need for manual configuration changes on individual network devices, reducing deployment time and potential human errors.

Improved Network Security: BGP SDN provides enhanced security features by allowing fine-grained control over network access and traffic routing. It enables the implementation of robust security policies, such as traffic isolation and encryption, to protect against potential threats.

BGP-based SDN

BGP SDN, also known as BGP-based SDN, is an approach that leverages the strengths of BGP and SDN to enhance network control and management. Unlike traditional networking architectures, where individual routers make routing decisions, BGP SDN centralizes the control plane, allowing for more efficient routing and dynamic network updates. By separating the control plane from the data plane, operators can gain greater visibility and control over their networks.

BGP SDN offers a range of features and benefits that make it an attractive choice for network operators. First, it provides enhanced scalability and flexibility, allowing networks to adapt to changing demands and traffic patterns. Second, operators can easily define and modify routing policies, ensuring optimal traffic distribution across the network.

Another notable feature is the ability to enable network programmability. Using APIs and controllers, network operators can dynamically provision and configure network services, making deploying new applications and services easier. This programmability also opens doors for automation and orchestration, simplifying network management and reducing operational costs.

Use Cases of BGP SDN: BGP SDN has found applications in various domains, from data centers to wide-area networks. In data centers, it enables efficient load balancing, traffic engineering, and rapid service deployment. It also allows for the creation of virtual networks, enabling secure multi-tenancy and resource isolation.

BGP SDN brings benefits such as traffic engineering and improved network resilience in wide-area networks. It enables dynamic path selection, optimizes traffic flows, and reduces congestion. Additionally, BGP SDN can enable faster network recovery during failures, ensuring uninterrupted connectivity.

BGP vs SDN:

BGP, also known as the routing protocol of the Internet, plays a vital role in facilitating communication between autonomous systems (AS). It enables the exchange of routing information and determines the best path for data packets to reach their destinations. With its robust and scalable design, BGP has become the go-to protocol for inter-domain routing.

SDN, on the other hand, is a paradigm shift in network architecture. SDN centralizes network management and allows for programmability and flexibility by decoupling the control plane from the forwarding plane. With SDN, network administrators can dynamically control network behavior through a centralized controller, simplifying network management and enabling rapid innovation.

Synergizing BGP and SDN

When BGP and SDN converge, the result is a potent combination that transcends the limitations of traditional networking. SDN’s centralized control plane empowers network operators to control BGP routing policies dynamically, optimizing traffic flow and enhancing network performance. By leveraging SDN controllers to manipulate BGP attributes, operators can quickly implement traffic engineering, load balancing, and security policies.

The Role of SDN:

In contrast to the decentralized control logic that underpins the construction of the Internet as a complex bundle of box-centric protocols and vertically integrated solutions, software-defined networking (SDN) advocates the separation of control logic from hardware and its centralization in software-based controllers. Introducing innovative applications and incorporating automatic and adaptive control into these fundamental tenets can ease network management and enhance user experience.

Recap Technology: EBGP over IBGP

EBGP, or External Border Gateway Protocol, is a routing protocol typically used between different autonomous systems (AS). It facilitates the exchange of routing information between these AS, allowing efficient data transmission across networks. EBGP’s primary characteristic is that it operates between routers in different AS, enabling interdomain routing.

IBGP, or Internal Border Gateway Protocol, operates within a single autonomous system (AS). It establishes peering relationships between routers within the same AS, ensuring efficient routing within the network. Unlike EBGP, IBGP does not involve exchanging routes between different AS; instead, it focuses on sharing routing information between routers within the same AS.

While both EBGP and IBGP serve to facilitate routing, there are crucial differences between them. One significant distinction lies in the scope of their operation. EBGP connects routers across different AS, making it ideal for interdomain routing. On the other hand, IBGP connects routers within the same AS, providing efficient intradomain routing.

EBGP is commonly used by internet service providers (ISPs) to exchange routing information with other ISPs, ensuring global reachability. It enables autonomous systems to learn about and select the best paths to reach specific destinations. IBGP, on the other hand, helps maintain synchronized routing information within an AS, preventing routing loops and ensuring efficient internal traffic flow.

BGP Configuration

Recap Technology: BGP Route Reflection

Understanding BGP Route Reflection

BGP (Border Gateway Protocol) is a crucial routing protocol in large-scale networks. However, route propagation can become cumbersome and resource-intensive in traditional BGP setups. BGP route reflection offers an elegant solution by reducing the number of full-mesh connections needed in a network.

By implementing BGP route reflection, network administrators can achieve significant advantages. Firstly, it reduces resource consumption by eliminating the need for every router to maintain full mesh connectivity. This leads to improved scalability and reduced overhead. Additionally, it enhances network stability and convergence time, ensuring efficient routing updates.

To implement BGP route reflection, several key steps need to be followed. Firstly, identify the routers that will act as route reflectors in the network. These routers should have sufficient resources to handle the increased routing information. Next, configure the route reflectors and their respective clients, ensuring proper peering relationships. Finally, monitor and fine-tune the route reflection setup to optimize performance.

Challenges to Networking

Over the past few years, there has been a growing demand for a new approach to networking to address the many issues associated with current networks. According to the SDN approach, networking operations can be simplified, network management can be optimized, and innovation and flexibility can be introduced.

According to Kim and Feamster (2013), four key reasons can be identified for the problems encountered in managing existing networks:

(1) Complex and low-level network configuration: Network configuration is a distributed task typically configured vendor-specific at the low level. Moreover, network operators constantly change configurations manually due to the rapid growth of the network and changing networking conditions, adding complexity and introducing additional configuration errors to the configuration process.

(2) Growing complexity and dynamic network state: networks are becoming increasingly complex and more extensive. Moreover, as mobile computing trends continue to develop and network virtualization (Bari et al. 2013; Alam et al. 2020) and cloud computing (Zhang et al. 2010; Sharkh et al. 2013; Shamshirband et al. 2020) become more prevalent, the networking environment becomes even more dynamic as hosts are constantly moving, arriving and departing due to the flexibility offered by virtual machine migration, which results in a rapid and significant change of traffic patterns and network conditions.

(3) Exposed complexity: today’s large-scale networks are complicated by distributed low-level network configuration interfaces that expose great complexity. Many control and management features are implemented in hardware, which generates this complexity.

(4) Heterogeneous: Current networks contain many heterogeneous network devices, including routers, switches, and middleboxes of various kinds. As a result, network management becomes more complex and inefficient because each appliance has its proprietary configuration tools.

Because legacy networks’ static, inflexible architecture is ill-suited to cope with today’s increasingly dynamic networking trends and meet modern users’ QoE expectations, network management is becoming increasingly challenging. As a result, complex, high-level policies must be adopted to adapt to current networking environments, and network operations must be automated to reduce the tedious work of low-level device configuration.

Traffic Engineering

Networks with multiple Border Gateway Protocol (BGP) Autonomous Systems (ASNs) under the same administrative control implement traffic engineering with policy configurations at border edges. Policies are applied on multiple routers distributedly, which can be hard to manage and scale. Any per-prefix traffic engineering changes may need to occur on various devices and levels.

A new BGP Software-Defined Networking (SDN) solution introduced by P. Lapukhov and E. Nkposong proposes a centralized routing model. It introduces the concept of a BGP SDN controller, also known as an SDN BGP controller with a routing control platform. No protocol extensions or additional protocols are needed to implement the SDN architecture. BGP is employed to push down new routes and peers iBGP with all existing BGP routers.

BGP-only Network

A BGP-only network has many advantages, and this solution promotes a more stable Layer 3-only network, utilizing one control plane protocol – BGP. BGP captures topology discovery and links up/down events. BGP can push different information to different BGP speakers, while an IGP has to flood the same LSA throughout the IGP domain.

For additional pre-information, you may find the following helpful:

  1. OpenFlow Protocol
  2. What Does SDN Mean
  3. BGP Port 179
  4. WAN SDN

BGP SDN

BGP Peering Session Overview

In BGP terminology, a BGP neighbor relationship is called a peer relationship, unlike OSPF and EIGRP, which implement their transport mechanism. In place of TCP, BGP utilizes BGP TCP port 179 as its transport protocol. A BGP peering session can only be established between two routers after a TCP session has been established between them. Selecting a BGP session consists of establishing a TCP session and exchanging BGP-specific information to establish a BGP peering session.

A TCP session operates on a client/server model. On a specific TCP port number, the server listens for connection attempts. Upon hearing the server’s port number, the client attempts to establish a TCP session. Next, the client sends a TCP synchronization (TCP SYN) message to the listening server to indicate that it is ready to send data.

Upon receiving the client’s request, the server responds with a TCP synchronization acknowledgment (TCP SYN-ACK) message. Finally, the client acknowledges receipt of the SYN-ACK packet by sending a simple TCP acknowledgment (TCP ACK). TCP segments can now be sent from the client to the server. As part of this process, TCP performs a three-way handshake.

BGP explained
Diagram: BGP explained. The source is IPcisco.

So, how does BGP work? BGP is a path-vector protocol that stores routes in the Routing Information Bases (RIBs). The RIB within a BGP speaker consists of three parts:

  1. The Adj-RIB-In,
  2. The Loc-RIB,
  3. The Adj-RIB-Out.

The Adj-RIB-In stores routing information learned from the inbound UPDATE messages advertised by peers to the local router. The routes in the Adj-RIB-In define routes that are available to the path decision process. The Loc-RIB contains routing information the local router selected after applying policy to the routing information in the Adj-RIB-In.

The Emergence of BGP in SDN:

Software-defined networking (SDN) introduces a paradigm shift in managing and operating networks. Traditionally, network devices such as routers and switches were responsible for handling routing decisions. However, with the advent of SDN, the control plane is decoupled from the data plane, allowing for centralized management and control of the network.

BGP plays a crucial role in the SDN architecture by acting as a control protocol that enables communication between the controller and the network devices. It provides the intelligence and flexibility required for orchestrating network policies and routing decisions in an SDN environment.

Layer-2 and Layer-3 Technologies

Traditional forwarding routing protocols and network designs comprise a mix of Layer 2 and 3 technologies. Topologies resemble trees with different aggregation levels, commonly known as access, aggregation, and core. IP routing is deployed at the top layers, while Layer 2 is in the lower tier to support VM mobility and other applications requiring Layer 2 VLANs to communicate.

Fully routed networks are more stable as they confine the Layer 2 broadcast domain to certain areas. Layer 2 is segmented and confined to a single switch, usually used to group ports. Routed designs run Layer 3 to the Top of the Rack (ToR), and VLANs should not span ToR switches. As data centers grow in size, the stability of IP has been preferred over layer 2 protocols.

  • A key point: Traffic patterns

Traditional traffic patterns leave the data center, known as north-to-south traffic flow. In this case, conventional tree-like designs are sufficient. Upgrades consist of scale-out mechanisms, such as adding more considerable links or additional line cards. However, today’s applications, such as Hadoop clusters, require much more server-to-server traffic, known as east-to-west traffic flow.

Scaling up traditional tree topologies to match these traffic demands is possible but not an optimum way to run your network. A better choice is to scale your data center horizontally with a CLOS topology ( leaf and spine ), not a tree topology.

Leaf and spine topologies permit equidistant endpoints and horizontal scaling, resulting in a perfect combination for optimum east-to-west traffic patterns. So, what layer 3 protocol do you use for your routing design? An Interior Gateway Protocol (IGP), such as ISIS or OSPF? Or maybe BGP? BGP’s robustness makes it a popular Layer 3 protocol for reducing network complexity.

How BGP works with BGP SDN: Centralized forwarding

What is BGP protocol in networking? Regarding internal data structures, BGP is less complex than a link-state IGP. Instead of forming adjacency maintenance and controls, it runs all its operations over Transmission Control Protocol (TCP) and uses TCP’s robust transport mechanism.

BGP has considerably less flooding overhead than IGPs, with a single flooding domain propagation scope. For these reasons, BGP is great for reducing network complexity and is selected as this SDN solution’s singular control plane mechanism.

Peter has written a draft called “Centralized Routing Control in BGP Networks Using Link-State Abstraction,” which discusses the use case of BGP for centralized routing control in the network.

The main benefit of the architecture is centralized rather than distributed control. There is no need to configure policies on multiple devices. All changes are made with an API in the controller.

BGP SDN
Diagram: BGP SDN. The inner workings.

A link-state map 

The network looks like a collection of BGP ASN, and the entire routing is done with BGP only. First, BGP builds a link-state map of the network in the controller memory.

Then, they use BGP to discover the topology and notice link-up and link-down events. Instead of installing a 5-tuple that can install flows based on the entire IP header, the BGP SDN solution offers destination-based forwarding only. For additional granularity, implement BGP flow spec, RFC 55745, entitled “Dissemination of Flow Specification Rules.” 

Routing Control Platform

The proposed method was inspired by the Routing Control Platform (RCP). The RCP platform uses a controller-based function and selects BGP routes for the routers in an AS using a complete view of the available routes and IGP topology. The RCP platform has properties similar to those of the BGP SDN solution.

Both run iBGP peers to all routers in the network and influence the default topology by changing the controller and pushing down new routes. However, a significant difference is that the RCP has additional IGP peerings. It’s not a BGP-only network. BGP SDN promotes a single control plane of BGP without any IGPs.

BGP detects health, builds a link-state map, and represents the network to a third-party application as multiple topologies. You can map prefixes to different topologies and change link costs from the API.

Multi-Topology view

The agent builds the link-state database and presents a multi-topology view of this data to the client applications. You may clone this topology and give certain links higher costs, mapping some prefixes to this new non-default topology. The controller pushes new routes down with BGP.

The peering is based on iBGP, so new routes are set with a better Local Preference, enabling them to be selected higher in the BGP path decision process. It is possible to do this with eBGP, but iBGP can be more accessible. With iBGP, you don’t need to care about the next hops.

BGP and OpenFlow

What is OpenFlow? BGP works like OpenFlow and pushes down the forwarding information. It populates routes in the forwarding table. Instead of using BGP in a distributed fashion, they centralize it. One main benefit of using BGP over OpenFlow is that you can shut the controller down, and regular BGP operation continues on the network.

But if you transition to an OpenFlow configuration, you cannot roll back as quickly as you could with BGP. Using BGP inband has great operational benefits. It is a great design by P. Lapukhov. There is no need to deploy BGP-LS or any other enhancements to BGP.

Closing Points on BGP SDN

Border Gateway Protocol (BGP) and Software-Defined Networking (SDN). BGP has long been the backbone of internet routing, while SDN is redefining how we manage and configure networks. But what happens when these two paradigms intersect? The convergence of BGP and SDN centralized forwarding presents an exciting frontier in network management, offering enhanced flexibility and control.

BGP is the protocol that holds the internet together by deciding the best paths for data to travel from source to destination across autonomous systems. It’s like the GPS for the internet, ensuring data packets find their way. However, traditional BGP lacks agility, often requiring manual configuration and offering limited adaptability to rapid network changes. This rigidity can lead to inefficiencies and delays, particularly in large-scale networks.

Enter SDN, a transformative approach that decouples the network control plane from the data plane, allowing for centralized management of network resources. SDN introduces a layer of abstraction that provides network administrators with the flexibility to program and configure network behavior dynamically, using software-based controllers. This means that network policies can be adjusted on the fly, responding swiftly to changing demands and conditions.

Combining BGP with SDN centralized forwarding brings the best of both worlds. SDN controllers can leverage BGP for routing decisions while maintaining centralized control over network policies and configurations. This synergy allows for automated, real-time optimization of routing paths, better resource allocation, and improved network resilience. In this hybrid model, networks become more efficient, scalable, and responsive to the needs of modern applications and services.

While the integration of BGP and SDN centralized forwarding offers numerous advantages, it also presents challenges. Compatibility issues between legacy systems and modern SDN architectures can arise, requiring careful planning and execution. Additionally, security considerations must be addressed to protect the centralized control plane from potential threats. However, the potential benefits—such as enhanced performance, reduced operational costs, and greater adaptability—make overcoming these hurdles worthwhile.

Summary: BGP SDN

In the ever-evolving networking world, two key technologies have emerged as game-changers: Border Gateway Protocol (BGP) and Software-Defined Networking (SDN). In this blog post, we delved into the intricacies of these powerful tools, exploring their functionalities, benefits, and impact on the networking landscape.

Understanding BGP

BGP, an exterior gateway protocol, plays a crucial role in enabling communication between different autonomous systems on the internet. It allows routers to exchange information about network reachability, facilitating efficient routing decisions. With its robust path selection mechanisms and ability to handle large-scale networks, BGP has become the de facto protocol for inter-domain routing.

Exploring SDN

SDN, on the other hand, represents a paradigm shift in network architecture. SDN centralizes network management and provides a programmable and flexible infrastructure by decoupling the control plane from the data plane. SDN empowers network administrators to dynamically configure and manage network resources through controllers and open APIs, leading to greater automation, scalability, and agility.

The Synergy Between BGP and SDN

While BGP and SDN are distinct technologies, they are not mutually exclusive. They can complement each other to enhance network performance and efficiency. SDN can leverage BGP’s routing capabilities to optimize traffic flows and improve network utilization. Conversely, BGP can benefit from SDN’s centralized control, enabling faster and more adaptive routing decisions.

Benefits and Challenges

The adoption of BGP and SDN brings numerous benefits to network operators. BGP provides stability, scalability, and fault tolerance in inter-domain routing, ensuring reliable connectivity across the internet. SDN offers simplified network management, quick provisioning, and the ability to implement security policies at scale. However, implementing these technologies may also present challenges, such as complex configurations, interoperability issues, and security concerns that need to be addressed.

Conclusion:

In conclusion, BGP and SDN have revolutionized the networking landscape, offering unprecedented control, flexibility, and efficiency. BGP’s role as the backbone of inter-domain routing, combined with SDN’s programmability and centralized management, paves the way for a new era of networking. As technology advances, a deep understanding of BGP and SDN will be essential for network professionals to adapt and thrive in this rapidly evolving domain.