Linux Networking Commands

Linux Networking Subsystem

Linux Networking Subsystem

Linux provides one of the most flexible networking stacks available on a general-purpose operating system. It can operate as an endpoint, router, firewall, bridge, VPN gateway, container host, virtual network platform, or network appliance. Its networking capabilities extend from conventional IP configuration to advanced routing, namespaces, virtual interfaces, traffic control, packet filtering, and high-performance packet processing.

The Linux Network Model: At the foundation of Linux networking are interfaces, IP addresses, routes, neighbour information, and sockets. A network interface can represent a physical NIC, but it can also be virtual, such as a VLAN interface, bridge, bond, tunnel, virtual Ethernet pair, or interface inside a network namespace. The kernel networking stack uses this information to determine how packets are received, routed, filtered, and transmitted.

IP Addressing and Routing: Linux supports IPv4 and IPv6 and provides extensive routing capabilities. The routing table determines where packets should be forwarded, while neighbour discovery mechanisms resolve Layer 2 information required to reach directly connected destinations. More advanced deployments can use multiple routing tables and policy-based routing, allowing traffic to be selected according to attributes such as source address, destination, interface, or packet marking.

Modern Network Configuration: The traditional ifconfig utility has largely been replaced by the iproute2 toolset. Commands such as ip addr, ip link, ip route, and ip neigh provide a consistent interface for inspecting and configuring networking. Higher-level systems such as NetworkManager and systemd-networkd can manage persistent configuration, connection profiles, addresses, routes, DNS settings, VLANs, bonds, bridges, and other interfaces depending on the Linux distribution and deployment model.

Virtual Networking: Linux networking is not limited to physical interfaces. Bridges can connect multiple interfaces at Layer 2, VLANs provide logical segmentation, bonding can combine interfaces for redundancy or bandwidth, and virtual Ethernet pairs can connect different network namespaces. These capabilities form the foundation for many virtualization and container networking architectures.

Network Namespaces: Network namespaces provide isolated networking environments with their own interfaces, addresses, routes, firewall state, and other network resources. They are fundamental to modern container networking because each container or workload can receive its own network environment while the host provides the underlying connectivity. Virtual Ethernet pairs, bridges, routing, NAT, and overlay technologies can then connect these isolated environments.

Linux as a Router and Network Appliance: Linux can perform Layer 3 forwarding between interfaces and can be configured as a router, firewall, VPN gateway, or edge device. Advanced routing features include multiple routing tables, policy rules, route metrics, tunnelling, VRFs, and dynamic routing through software such as FRRouting. This makes Linux capable of performing many functions traditionally associated with dedicated network appliances.

Packet Filtering and Security: Linux provides powerful packet-filtering capabilities through the Netfilter framework. Modern Linux systems commonly use nftables as the primary packet-filtering framework, although compatibility layers may still expose legacy iptables commands. Filtering can be applied at different points in the packet path and can support stateful inspection, NAT, logging, packet marking, and other security controls.

DNS and Network Services: Linux hosts frequently provide or consume network services such as DNS, DHCP, SSH, HTTP, NTP, and various application protocols. DNS configuration is particularly important because modern applications commonly depend on name resolution for service discovery and connectivity. Linux systems may use different DNS management approaches depending on the distribution, including systemd-resolved, NetworkManager, or traditional resolver configuration.

Traffic Control and Performance: Linux also includes sophisticated traffic-management capabilities through the tcsubsystem. Queues, shaping, scheduling, classification, and packet marking can be used to control how traffic is transmitted. These features are useful for bandwidth management, latency-sensitive workloads, congestion control, and testing network behaviour under constrained conditions.

Network Observability and Troubleshooting: Linux provides an extensive collection of diagnostic tools. ss can inspect sockets and listening services, ip can expose interfaces, routes, and neighbour state, while tcpdump can capture packets directly from interfaces. Tools such as ethtool provide visibility into NIC capabilities and statistics, while ping, tracepath, and traceroute can help investigate reachability and path behaviour. For deeper analysis, packet captures can be examined with tools such as Wireshark.

Containers, Virtual Machines, and Cloud Networking: Linux networking forms the foundation of much of modern infrastructure. Container platforms use namespaces, virtual interfaces, bridges, routing, filtering, and often overlay networks to connect workloads. Virtual machines can use Linux bridges, Open vSwitch, or other virtual networking technologies. Cloud platforms similarly build higher-level network abstractions on top of Linux networking primitives.

A useful way to visualise the Linux networking stack is:

Application → Socket → Network Namespace → Interface → Routing/Filtering → Kernel Datapath → NIC → Network

The exact path varies depending on whether the system is acting as an endpoint, router, firewall, container host, or virtual network platform.

Linux networking is therefore much more than configuring an IP address on an Ethernet interface. It provides a programmable networking environment covering addressing, routing, switching, segmentation, virtualisation, security, traffic control, observability, and network automation.

Understanding these components provides a strong foundation for working with modern Linux infrastructure, from a single server to container platforms, cloud environments, software-defined networks, and high-performance network appliances.

Linux Networking · Kernel Data Path

Follow a Packet Through Linux

A Linux host can receive traffic for a local application, forward it between interfaces, or filter it before delivery. Choose the traffic type and follow the conceptual path through the network device, kernel networking stack, routing and filtering layers.

Conceptual Linux Packet Path
Network Device NIC / virtual interface
→
Kernel Driver device receive/transmit
→
Network Stack L2 / L3 / L4 processing
→
Routing local or forwarded
→
Netfilter filter / NAT / state
→
Endpoint socket or output interface
Packet Analysis
Ready to trace
Traffic Local
Route Decision Local
Filtering Allow
Endpoint Socket
Kernel Trace
linux-net: trace ready
interface: eth0
route: awaiting packet
netfilter: awaiting packet
destination: awaiting decision
Networking Insight
One Linux networking stack, several paths. The important distinction is whether traffic is destined for the local host or needs to be forwarded onward. Filtering and connection tracking can add additional processing along the path.

Linux Networking Subsystem

The Networking Stack

Nowadays, the Linux stack is no longer a standalone operating system and serves various functions around the network, including the base for container based virtualization and docker container security. The number and type of applications the networking stack must support varies from Android handsets to data center routers and switches; both virtualized and bare metal.

Applications are a sign of today’s variety. Some are outbound oriented, and others are inbound oriented. There are many different spectrums of applications, and when you have a variety in your application space, it is hard to have one networking solution. 

This puts pressure on Linux networking to evolve and support a variety of application stacks with different network requirements. The challenge arises from the various expectations of end hosts to that of a middle node running Linux. The Linux stack with Netlink Linux must perform differently in all these areas. 


Linux Networking Experiment

What Happens When a Linux Packet Moves?

Change the traffic path, routing state and firewall behaviour to see how the Linux networking stack processes the packet.

INTERACTIVE LAB
Experiment Controls
Experiment Logic
Linux networking decisions are distributed across the interface, kernel networking stack, routing subsystem and filtering layer. Change one variable and rerun the test to see which stage becomes decisive.
Packet Processing Path
Interface NIC / veth / VLAN
→
Network Stack Kernel packet processing
→
Routing Destination decision
→
Netfilter Filtering / conntrack
→
Endpoint Local or forwarded path
Ready to run experiment
Live Result
Reachability Not tested
Route Decision Waiting
Filtering Waiting
Namespace Waiting
Kernel Processing 0%
Path Complexity 0%
Kernel Trace
$ waiting for connectivity test...
Change the experiment controls and select Run Connectivity Test.
Networking Insight
Try removing the required route or changing the firewall policy. The same interface can remain operational while the packet still fails later in the Linux networking path.

Highlights:Linux Networking Subsystem

1. The Core Components:

The Linux Networking Subsystem comprises several core components that work in unison to deliver robust networking capabilities. These components include:

Network Devices: Linux supports many network devices, including Ethernet, Wi-Fi, Bluetooth, and Virtual Private Network (VPN) interfaces. The Linux kernel provides the necessary drivers to communicate with these devices, ensuring seamless integration and compatibility.

Network Protocols: Linux supports a plethora of network protocols, such as Internet Protocol (IP), Transmission Control Protocol (TCP), User Datagram Protocol (UDP), and Internet Control Message Protocol (ICMP). These protocols form the foundation of reliable and efficient data transmission over networks.

Network Interfaces: Linux offers various network interfaces that enable communication between different network layers. These interfaces include loopback, ethernet, wireless, and virtual interfaces. Each interface serves a specific purpose and is crucial in maintaining network connectivity.

2. Network Configuration:

The Linux Networking Subsystem provides comprehensive tools to configure network settings. Administrators can leverage these tools to manage IP addresses, set up routing tables, configure network interfaces, apply firewall rules, and monitor network traffic. Some of the commonly used tools include ifconfig, ip, route, firewall-cmd, and tcpdump.

3. Network Virtualization:

Virtualization has become an integral part of modern IT infrastructure. With its robust networking subsystem, Linux offers excellent network virtualization support. Technologies like Virtual LAN (VLAN), Virtual Extensible LAN (VXLAN), and Network Namespaces enable the creation of isolated network environments, allowing multiple virtual networks to coexist on a single physical infrastructure.

4. Packet Filtering and Firewalling:

The Linux Networking Subsystem incorporates Netfilter, a powerful packet-filtering framework. Netfilter enables administrators to implement firewall rules, perform network address translation (NAT), and control traffic flow. With tools like iptables and nftables, Netfilter empowers administrators with fine-grained control over network security and access control.

5. Network Monitoring and Troubleshooting:

With Linux’s Networking Subsystem, network administrators have various tools to monitor and troubleshoot network-related issues. Tools like tcpdump, Wireshark, netstat, and ping enable administrators to capture and analyze network packets, monitor network connections, diagnose network problems, and measure network performance.

Highlighting Linux Networking

Linux is a powerful and versatile operating system, capable of powering a wide range of devices, from the smallest Raspberry Pi to the largest supercomputers. It is also well-respected for its networking capabilities. Linux networking technologies provide users a secure, reliable, and fast way to connect to the Internet and other devices on the same network.

Linux supports several popular networking protocols, such as TCP/IP, IPv4, IPv6, and the latest wireless technologies. Linux also supports a wide range of networking hardware, from Ethernet cards to wireless routers. With the help of these networking technologies, users can easily connect to the Internet, share files and printers, and access networked resources from other computers.

Linux provides a range of tools for managing and configuring networks. These include a range of graphical user interfaces and powerful command-line tools such as netstat and ifconfig. Network administrators can also use tools such as iptables and iproute to set up firewalls and control network access.
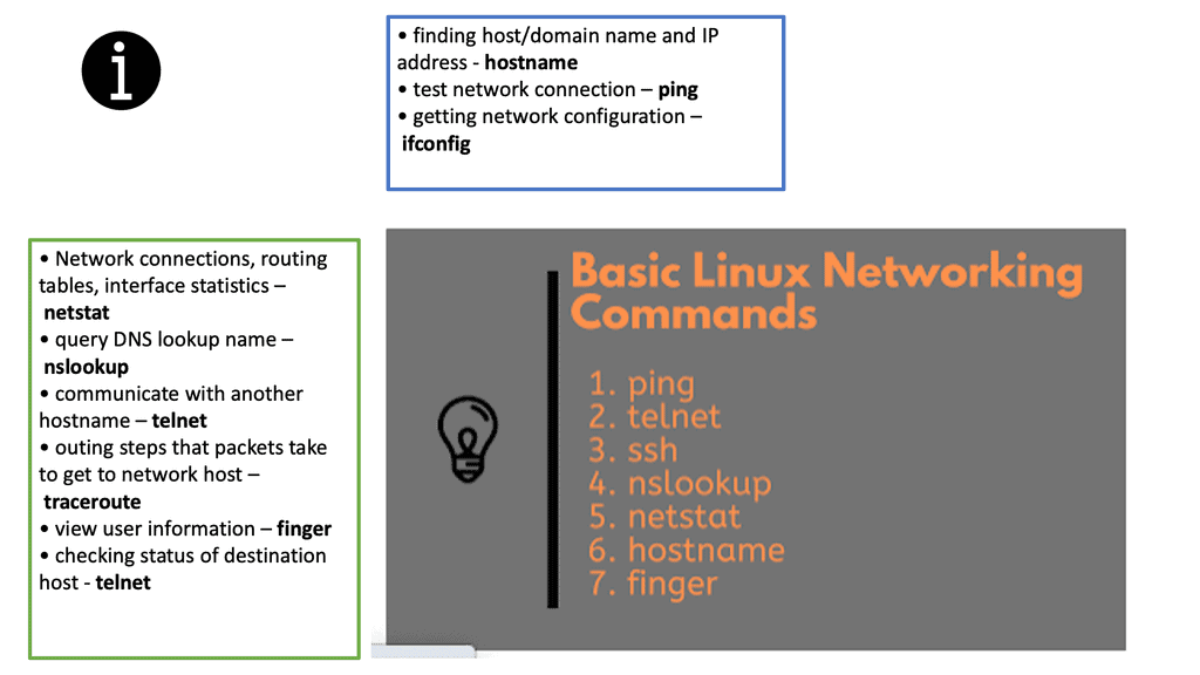
Linux Networking Commands
Diagram: Basic Linux Networking Commands. The source is JavaRevisited.

Linux has almost forever had an integrated firewall available.

Linux Firewall is an essential security feature for any Linux system. It is a barrier between the outside world and the internal network, keeping malicious and unauthorized users from accessing your system. Firewalls also help protect against viruses, worms, Trojans, and other malware.

A Linux firewall is a combination of software and hardware components that together provide a secure network environment. It is designed to permit or deny network traffic based on user-defined rules. Rules can be based on various criteria, such as the source or destination IP address, type of service, or application.

To configure a Linux firewall, you must use the iptables command. This command line utility allows you to set up rules for filtering and routing data within your network. Iptables is a powerful tool that can be used to create complex firewall rules. The following figure shows an example of a firewall that can filter requests based on protocol or target-based rules.
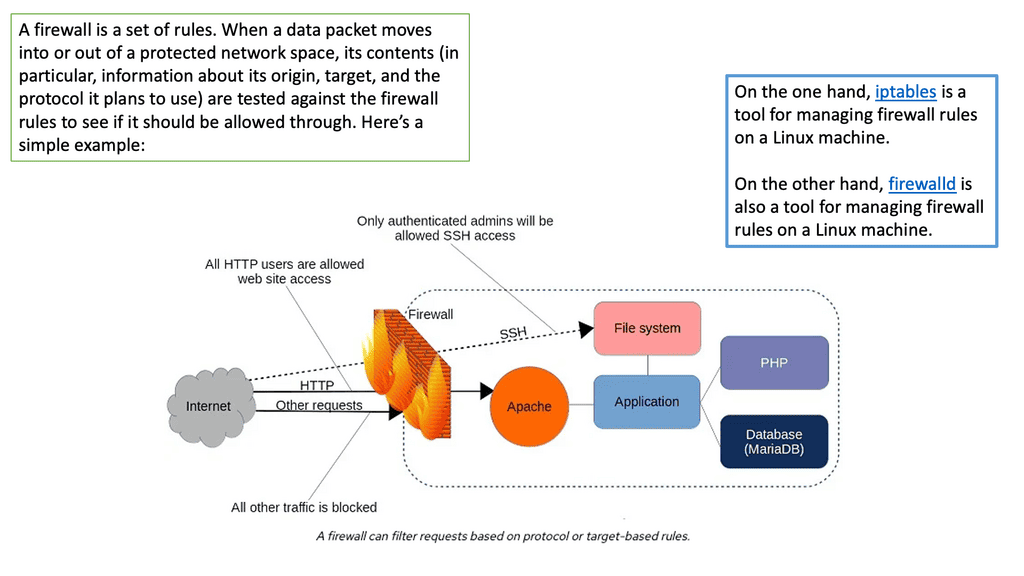
Linux Firewall
Diagram: Linux Firewall. Source is OpenSource.

With the native firewall tools, you can prepare a traditional perimeter firewall with address translation or a proxy server. While egress filtering (outbound access controls) is recommended, this is often implemented at network perimeters – on firewalls and routers between VLANs or facing less-trusted networks such as the public internet.

Linux Network Subsystem: Netlink Linux

The Linux system architecture contains the user space, kernel, and hardware. At the top of the Linux framework, user space exists with various user applications—the kernel space forwards packets in the middle, accepting instruction from the user space element.

At the bottom, we have the hardware, such as CPU, RAM, and NIC. One way to communicate between userspace and kernel is via Netlink. The Linux Netlink socket handles bidirectional communication between the two.

It can be created in user space with the socket() system call or in the kernel with netlink_kernel_create(). For example, the following shows a Netlink Linux socket created in both the kernel and user space.
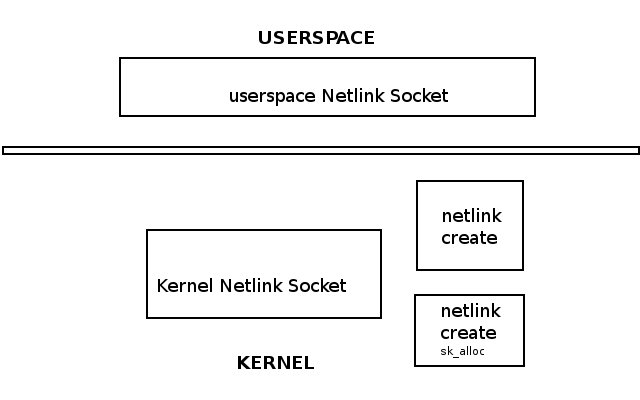
Linux networking subsystem
Diagram: Linux networking subsystem

The Linux Netlink protocol implementation resides under the net/netlink folder listed below. In addition, the af_netlink provides the Netlink Linux kernel socket API, genetlink provides the generic Netlink API, and diag provides information about the Netlink sockets.
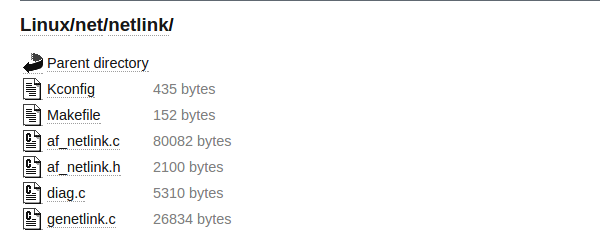
Linux Networking subsystem

The Linux networking subsystem is part of the kernel space and is one of the most critical subsystems. Even if hosts are not connected, the network subsystem is used for the client-server interaction of X-Windows. The Linux Kernel networking stack processes incoming packets from Layer 2 to the network layer.

It then passes for local delivery to the transport layer protocols listening to TCP or UDP sockets. Any packets not destined for the local system are sent back down the stack for transmission. The kernel does not handle anything above Layer 4. Userspace applications handle all layers above Layer 4. 

 The sk_buff and net_device

The sk_buff and net_device are fundamental to the networking subsystem. The network device driver ( net_device structure ) receives and transmits packets to pass them up the stack ( Layer 3 to Layer 4 ) or transmit them to an outgoing interface. The routing subsystem looks up every incoming/outgoing packet to determine the interface and specific packet handling activities.

Many things may affect packet traversal, such as Netfilter hooks, IPsec subsystem, TTL, etc. The sk_buff ( Socket Buffer ) represents data and headers. Packets are received on the wire by a NIC (net device), placed in the sk_buff, and passed through the network stack.

The userspace networking stack can slow down the CPU’s performance. Everything that crosses over to the kernel affects performance, so if the application crosses over the user/kernel boundary, it will cost a lot.

It would help if you minimized this by keeping as much in the kernel and below as possible and only going to userspace for a quick breath. For example, transit traffic might not need to go to userspace constantly.

Linux Networking and Android

Linux is used extensively as the base for Android phones. The Linux networking stack has different needs for mobile devices than for data center devices. The phone moves continuously, connecting to other networks of varying quality. Phones are connected to multiple networking nearly all the time.

If devices are on the WIFI network and require sending an SMS, you must bring up the cell network on a different IP interface.

Multipath TCP

Users want all networks simultaneously, and the Linux stack must seamlessly switch across network boundaries. For this, the application has to shoot all the TCP connections so they don’t get blocked on reads they will never compete.

Usually, when you remove the IP address in Linux, the TCP connection will stay there, hoping that the IP address will return. As a result, the TCP connections are closed for every network switch.

Linux must also support different applications and socket routing, such as connecting to a wireless printer while on the CELL network. There is also a method to let users know if they are connecting to a WIFI network that doesn’t have a backhaul connection.

To do this, Linux must use DNS and open a TCP connection on the backhaul network. The networking stack needs to handle many functions for such a small device.

Linux Network subsystem: Linux networking and the data center

Linux has accelerated in the data center and is the base for open-source cloud environments and containerized architecture in the Kubernetes network namespace environments. Many virtual switch functions are available with hardware offload for accelerated performance.

The Linux kernel supports three software bridges – Bridge, macvlan, and Open vSwitch. A NIC-embedded switch solution with SR-IOV may be used instead of the software switch. Recently, there have been many new bridge features such as FDB manipulation, VLAN filtering, Learning/flooding control, Non-promiscuous bridge, and VLAN filtering for 802.1as (Q-in-Q).

  • A typical packet processing pipeline of a switch includes:
    • Packet parsing and classification – L2, L3, L4, tunneling, VXLAN VNI, inner packet L2, L3, L4.
    • Push/pop for VLAN or encapsulation/decapsulation for tunneling.
    • QoS-related functions such as Metering, Shaping, Marking, and scheduling.
    • Switching operations.

The data plane is accelerated by decomposing the packet processing pipeline and offloading some stages to the hardware ASICs. For example, layer 2 features that can be offloaded to ASIC may include MAC learning and aging, STP handling, IGMP snooping, and VLXAN. It is also possible to offload Layer 3 functions to ASICs.

The following figure shows an example of a data center design known as the leaf and spine. Each node can run a version of Linux to perform Linux networking for the data center.
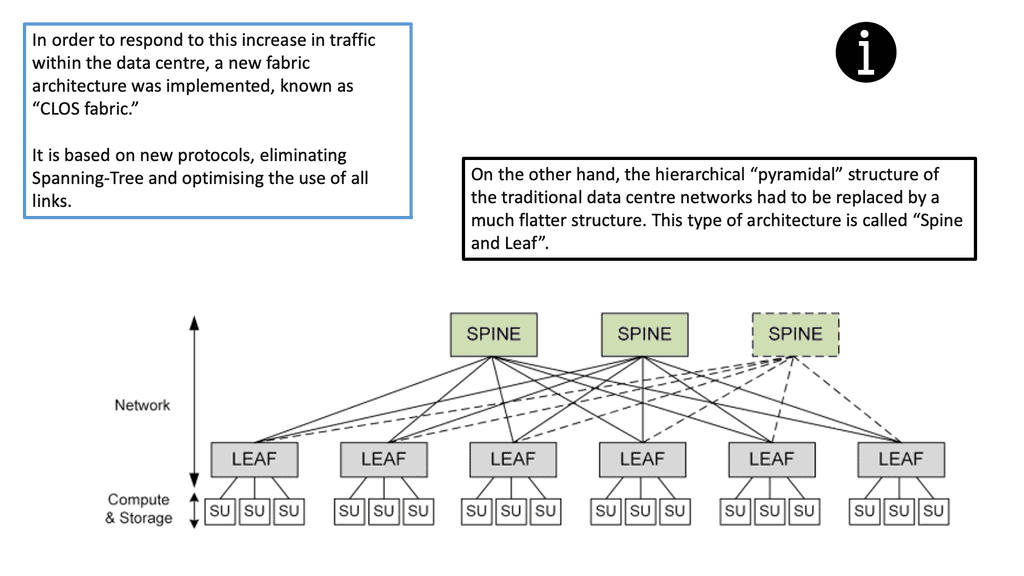
Linux networking
Diagram: Linux Networking in the data center. Source Ubuntu.

Linux switch types

The bridge is a MAC&VLAN standard bridge containing an FDB ( forwarding DB), STP ( spanning tree), and IGMP functions. The FDB contains a record of MAC to port allocation. Building up the FDB is called “MAC learning” or simply the “learning process.” MAC VLAN is a switch based on STATIC MAC&VLAN.

It uses unicast filtering instead of promiscuous mode and supports several modes – private, VEPA, bridge, and pass-thru. MAC VLAN is a reverse VLAN under Linux. It takes a single interface and creates multiple virtual interfaces with different MAC addresses.

Essentially, it enables the creation of independent logical devices over a single ethernet device – a “many to one” relationship in contrast to a “one to many” relationship where you map a single NIC to multiple networks. In addition, MAC VLAN offers isolation because it will only see traffic on an interface with a specified MAC address.
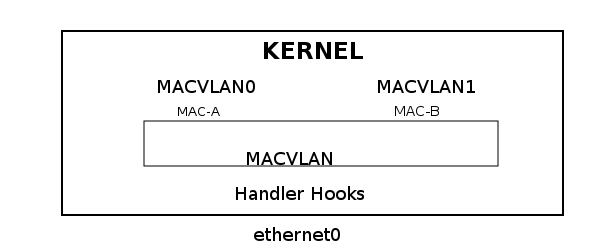
MACVLAN

Open vSwitch is a flow-based switch that performs MAC learning like the Linux bridge enabling container networking. It supports protocols like STP and, more importantly, OpenFlow. Its forwarding is based on flows, and everything is based on a flow table. It is becoming the de facto software switch and has an impressive feature list, now including stateful services and connection tracking.

It is also used in complex cases involving nested Open vSwitch designs with OVN (Open-source virtual networking). By default, the OVS acts as a learning switch and learns like a standard Layer 2 switch. For advanced operations, it can be connected to an SDN controller, or the command line can be used to add OpenFlow rules manually.

The Linux Networking Subsystem is a critical component that underpins the networking capabilities of Linux-based systems. Its robust architecture, comprehensive toolset, and support for virtualization make it a preferred choice for network administrators. By delving into the core components, network configuration, virtualization, packet filtering, and network monitoring, we have gained a deeper understanding of the Linux Networking Subsystem’s significance and its role in enabling efficient networking in Linux environments.
Linux Troubleshooting Challenge

Why Can't This Linux Host Reach the Internet?

The interface is up and the gateway responds. Your job is to identify the next place to investigate.

DIAGNOSE THE FAULT
Incident
⌁
web-01 Linux application server · eth0
Symptoms:
web-01 can communicate with hosts on its local subnet and can ping the default gateway, but external IP connectivity fails. The interface is UP and the local address is correct.
Evidence Collected
eth0 state UP
IPv4 address 10.20.1.25/24
Local subnet ping PASS
Gateway 10.20.1.1 PASS
8.8.8.8 FAIL
Application symptoms NETWORK
Choose Your Investigation
Where The Investigation Leads
eth0 Interface
→
Kernel IP stack
→
Routing Route lookup
→
Netfilter Policy
→
External Network
Diagnostic Score
Select an investigation and evaluate it.
—
The evidence deliberately narrows the problem. Because the gateway is reachable and the failed test targets an IP address, start with the kernel's routing decision rather than DNS or the application.
Investigation Console
$ incident status
host: web-01
interface: eth0 UP
local subnet: reachable
gateway: reachable
external IP: unreachable
awaiting engineer diagnosis...
Engineer Hint: A host can have a perfectly healthy interface and still have no valid path to an external destination. Separate Layer 2 reachability from the Layer 3 routing decision.
container based virtualization

Container Networking

Container Networking

Container networking provides the connectivity layer that allows containers to communicate with each other, with host systems, with services and with external networks. As container platforms have evolved from individual hosts to distributed orchestration environments, networking has become an important part of application architecture rather than simply a mechanism for assigning an IP address to a container.

Containers are isolated using operating-system primitives such as Linux network namespaces. A network namespace provides an independent networking environment containing interfaces, addresses, routes, neighbour information and sockets. Virtual Ethernet pairs can then connect a container namespace to the host networking stack, allowing traffic to move between the isolated workload and the wider network.

On a single container host, a common architecture uses a virtual bridge to connect containers. Each container can have a virtual interface connected to the bridge, while the host provides routing, filtering and external connectivity. Depending on the platform, outbound traffic may be translated using NAT, while published ports provide controlled inbound access from the host or external network.

Container networking becomes more complex when workloads are distributed across multiple hosts. Containers may need to communicate regardless of which node they are running on. Overlay networks can provide logical connectivity across the underlying physical network, while routing-based designs can provide direct Layer 3 connectivity between container networks. The appropriate model depends on scale, performance requirements, infrastructure and the container platform.

Kubernetes introduces another important networking model. Pods, rather than individual containers, normally provide the primary workload networking boundary. Containers within the same Pod share a network namespace and therefore share the Pod IP address and port space. The Container Network Interface (CNI) provides the mechanisms required to connect Pod network namespaces to the cluster network.

Container networking also requires reliable IP address management. As workloads are dynamically created and removed, addresses must be allocated, tracked and reclaimed without creating conflicts. Larger platforms may therefore use dedicated IPAM mechanisms and carefully planned address ranges for containers, Pods, services and underlying infrastructure.

Service discovery is another fundamental requirement. Applications should not normally depend on dynamically changing container IP addresses. Container platforms can provide DNS-based discovery, virtual service addresses or other service abstractions that allow applications to locate services while the underlying workloads change.

Network isolation is equally important. Containers should not automatically have unrestricted access to every other workload or network segment. Security controls can restrict traffic between workloads based on namespaces, labels, identities, IP addresses, ports or other policy attributes. In Kubernetes environments, NetworkPolicy provides a standard policy model, although enforcement depends on the networking implementation.

Modern container networking can also use eBPF-based data planes. These implementations can provide high-performance packet processing, service load balancing, network policy enforcement, observability and routing directly within the Linux networking stack. eBPF does not replace the fundamental networking model; it provides an alternative way of implementing and extending parts of the data plane.

Different networking models involve different trade-offs. Host networking can reduce networking overhead but provides less isolation. Bridge networking is simple and effective for single-host environments. Overlay networking simplifies multi-host connectivity but introduces encapsulation and additional processing. Routed networking can provide efficient connectivity but requires appropriate routing integration with the underlying infrastructure.
Security should therefore be designed into the networking architecture from the beginning. Important controls include network segmentation, least-privilege communication policies, restricted exposed ports, encrypted traffic where appropriate, host firewalling, workload identity and monitoring of unexpected connections.

Troubleshooting container networking requires following the complete packet path rather than looking only at the container itself. Engineers may need to inspect the container or Pod network namespace, virtual interfaces, routes, DNS resolution, bridges or tunnels, service endpoints, network policies, node routing, host firewall rules and the underlying physical network.

Observability is particularly important in dynamic environments. Useful telemetry includes connection state, packet loss, latency, DNS behaviour, interface statistics, flow information, policy decisions and application-level errors. Tools such as ip, ss, tcpdump and platform-specific networking commands can be combined with metrics, logs and flow telemetry to identify where connectivity is failing.
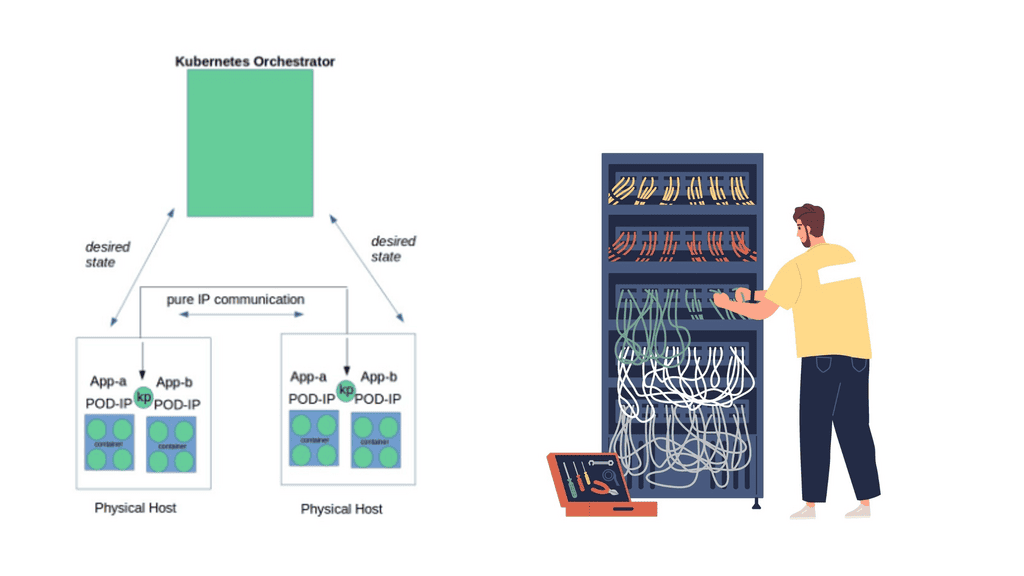
The key principle is that container networking is an end-to-end system:

Workload → Network Namespace → Virtual Interface → Container Network → Service/Route → Node → Physical or Cloud Network

Effective container networking therefore requires more than selecting a network driver. It involves addressing, routing, service discovery, security, performance, observability and automation working together to provide predictable connectivity for dynamic workloads.

Container Networking • Interactive Lab

Follow a Packet Through Container Networking

See how an application packet moves from a container's isolated network namespace through a virtual interface and network fabric. Switch between local, multi-host and external traffic paths.

Packet Processing Path
[ready] Select a traffic path and trace the packet.
Network State
Namespace Isolated
Virtual Interface veth pair
Network Scope Single Host
Path Function L2 Bridge
Connectivity Ready
Engineering Insight
Containers have their own network namespace. A virtual Ethernet pair commonly connects that namespace to the host networking domain. The exact datapath depends on the runtime and networking implementation.

Highlights: Container Networking

Understanding Container Networking

Container networking refers to the process of establishing communication between containers and external networks. Unlike traditional networking methods, container networking provides isolation, scalability, and flexibility, making it ideal for modern application architectures. We can achieve better resource utilization and application performance by encapsulating applications and their dependencies within containers.

Container networking serves as the bridge that connects containers to each other and to external networks. It facilitates communication, data exchange, and resource sharing. This section will delve into the foundational concepts of container networking, covering topics such as network namespaces, virtual Ethernet devices, and bridge networks.

Key Points To Consider:

– Scalability and Resource Optimization: Container networking enables unprecedented scalability by allowing applications to be broken down into smaller, independent containers. These containers can be easily replicated and distributed across a cluster of machines, ensuring efficient resource utilization. With container networking, organizations can effortlessly scale their applications based on demand without incurring unnecessary costs or compromising performance.

– Enhanced Security and Isolation: One of the key advantages of container networking is the built-in security and isolation it offers. Each container operates within its own isolated environment, preventing any potential vulnerabilities from affecting other containers or the underlying host system. Container networking allows for the implementation of fine-grained access controls and network policies, ensuring that sensitive data and critical services remain safeguarded.

– Seamless Communication and Service Discovery: Container networking facilitates seamless communication between containers within and across different hosts. Containers can be connected through virtual networks, enabling them to exchange data and interact with each other effortlessly. Moreover, container orchestration platforms provide built-in service discovery mechanisms, allowing containers to locate and communicate easily with other services in the cluster, further simplifying the development and deployment process.

– Flexibility and Portability: Container networking offers unparalleled flexibility and portability, making it an ideal choice for modern application development. Containers can be easily moved or migrated between hosts, irrespective of the underlying infrastructure. This portability eliminates the need for tedious system configurations, making deployments swift and hassle-free. Furthermore, container networking enables developers to encapsulate the entire application stack, ensuring consistency across different environments, from development to production.

Connecting Containers

Container networking refers to establishing communication channels between containers and external resources, such as other containers, host machines, or the Internet. It allows containers to exchange data and access necessary services while maintaining isolation and security. By comprehending the basics of container networking, we can unlock its potential for building scalable and resilient applications.

Multiple networking models are available for containers, each with its advantages and use cases. We will explore three common models:

1. Bridge Networking: This model creates a bridge network interface on the host machine, enabling containers to communicate with each other through the bridge. It provides automatic DNS resolution and IP address assignment but lacks direct connectivity to the host network.

2. Overlay Networking: Overlay networks facilitate container communication on different hosts or multiple data centers. By encapsulating container traffic within virtual networks, overlay networking ensures seamless connectivity and flexibility, but it may introduce additional overhead.

3. Host Networking: This model allows containers to share the host network stack, leveraging its IP address and network interfaces. Host networking offers maximum performance but compromises container isolation and may lead to port conflicts.

Example: Docker Networking

GKE Network Policies

Why Network Policies Matter

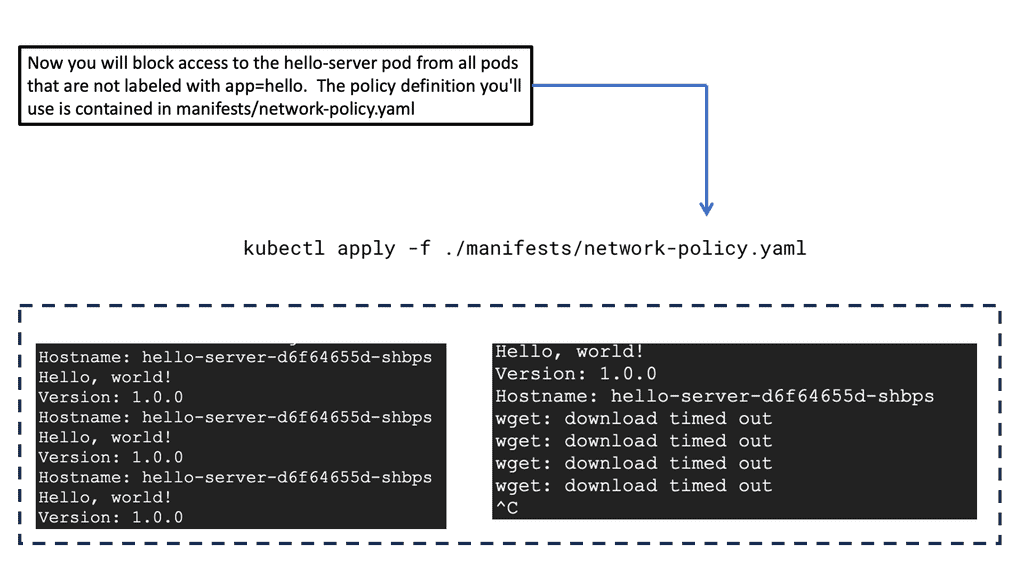
The importance of network policies cannot be overstated. In a typical Kubernetes cluster, all pods can communicate with each other by default. While this might be convenient for development, it poses a significant security risk in production environments. Network policies provide a way to enforce rules that dictate which pods can communicate with each other. This level of control is crucial in maintaining a secure and robust microservices architecture. By implementing well-defined network policies, you can prevent potential attacks, such as lateral movement within the cluster, thus fortifying your application’s security posture.
### Crafting Effective Network Policies

Creating effective network policies requires a thorough understanding of your application’s architecture and communication patterns. Start by mapping out the data flow between your services. Identify which services need to communicate and which ones should be isolated. Use this information to define network policies that permit only the required traffic. When crafting these policies, it’s beneficial to follow the principle of least privilege—allow only what is necessary and deny everything else by default. This approach not only minimizes the attack surface but also simplifies policy management over time.

### Implementing Network Policies in GKE

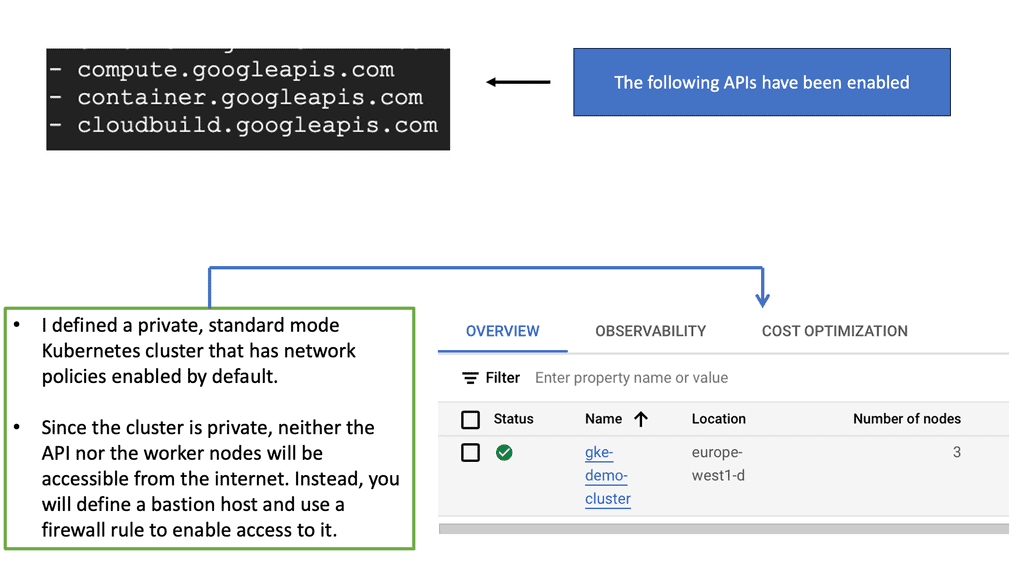
Implementing network policies in GKE involves defining policy resources using YAML configuration files. These files specify the allowed ingress and egress rules for your pods. Begin by enabling network policy enforcement on your GKE cluster. Once enabled, you can apply your custom network policies using the `kubectl` command-line tool. It’s essential to test these policies in a controlled environment before deploying them to production. Regular audits and updates to your network policies are also crucial to adapt to changes in your application’s architecture and security requirements.

Kubernetes network policy

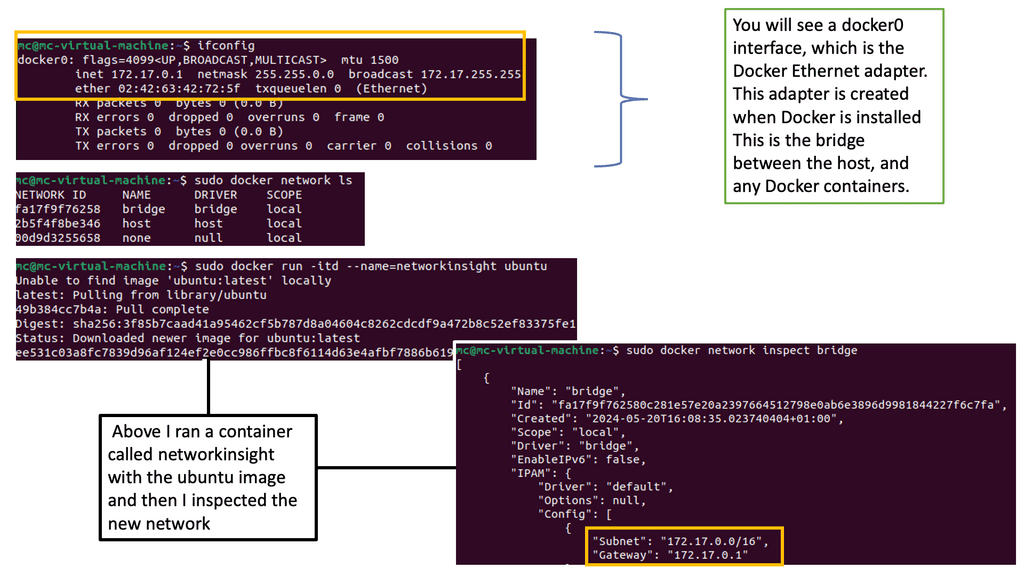
Understanding Docker’s Default Networking

– Docker’s default networking is based on a bridge network driver that creates a virtual network interface on the host machine. This bridge acts as a gateway, enabling containers to communicate with each other and the host. By default, Docker assigns IP addresses from a predefined range to containers, facilitating seamless connectivity within the network.

– One of the fundamental aspects of Docker’s default networking is container-to-container communication. Containers within the same bridge network can effortlessly communicate with each other using their respective IP addresses or container names. This opens up endless possibilities for building complex, interconnected systems composed of microservices.

– While container-to-container communication is vital, Docker also provides mechanisms to connect containers with the external world. We can expose services running inside containers to the host machine or the entire network by mapping container ports to host ports. This allows seamless integration of Dockerized applications with external systems.

– In addition to the default bridge network, Docker offers advanced networking techniques such as overlay networks. Overlay networks allow containers to communicate across multiple Docker hosts, enabling the creation of distributed systems and facilitating scalability. Understanding these advanced networking options expands the possibilities of using Docker in complex scenarios.

Container Orchestration

**Understanding Container Networking**

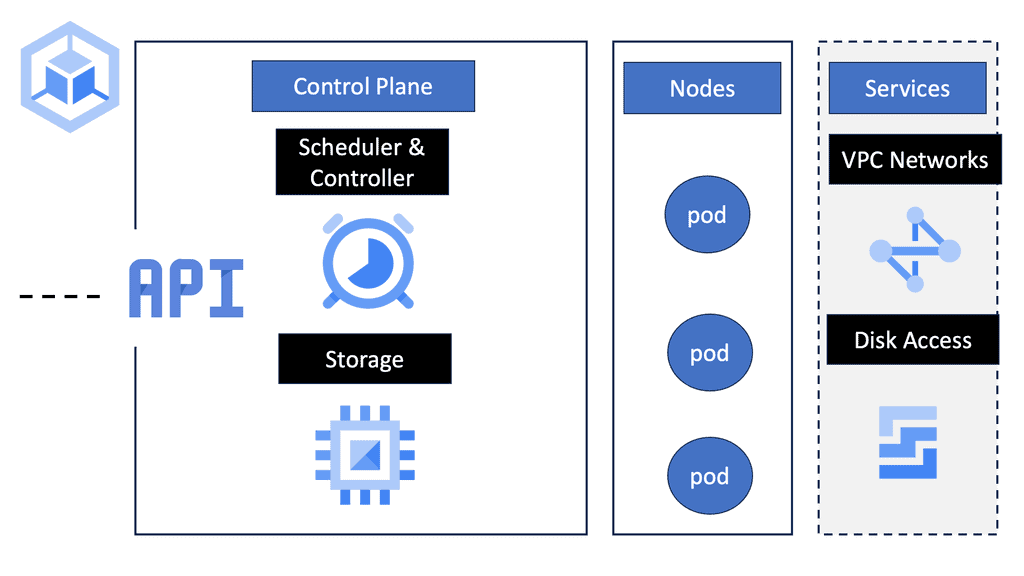
Container networking is a critical aspect of application deployment in GKE. It involves the communication between containers, nodes, and external services. In GKE, this process is streamlined with the integration of Kubernetes networking policies and the use of Google Cloud’s Virtual Private Cloud (VPC). These components work together to provide a secure and efficient networking environment, where each container can communicate with others while maintaining isolation and security.

**The Role of Kubernetes Networking Policies**

Kubernetes networking policies are essential for managing traffic flow within a GKE cluster. These policies define how pods communicate with each other and with external endpoints. By specifying rules for ingress and egress traffic, developers can fine-tune the security and performance of their applications. In GKE, networking policies are implemented using YAML configurations, providing a flexible and scalable approach to managing container networks.

**Integrating Google Cloud’s Virtual Private Cloud (VPC)**

Google Cloud’s VPC plays a pivotal role in enhancing the networking capabilities of GKE. With VPC, users can create isolated networks within Google Cloud, allowing for fine-grained control over IP address ranges, subnets, and routing. This integration ensures that containers within a GKE cluster can securely communicate with other Google Cloud services, on-premises resources, and the internet, while maintaining compliance with organizational security policies.

**Optimizing Performance with Container Networking**

Optimizing container networking in GKE involves balancing performance and security. By leveraging features like Network Endpoint Groups (NEGs) and Cloud Load Balancing, developers can ensure high availability and low latency for their applications. Additionally, monitoring tools provided by Google Cloud, such as Stackdriver, offer insights into network performance, enabling proactive management and troubleshooting of networking issues.

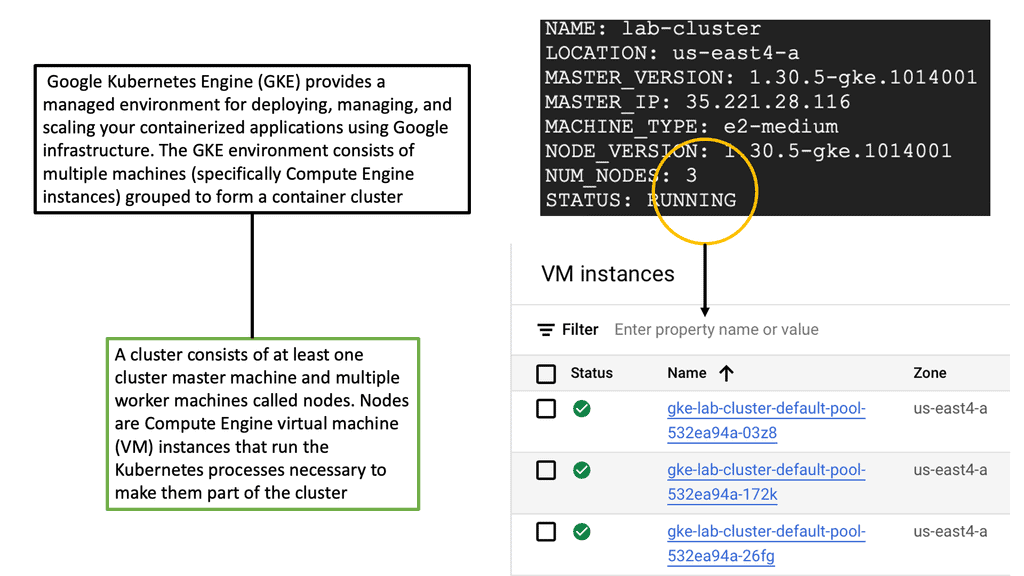
Google Kubernetes EngineUnderstanding Docker Swarm

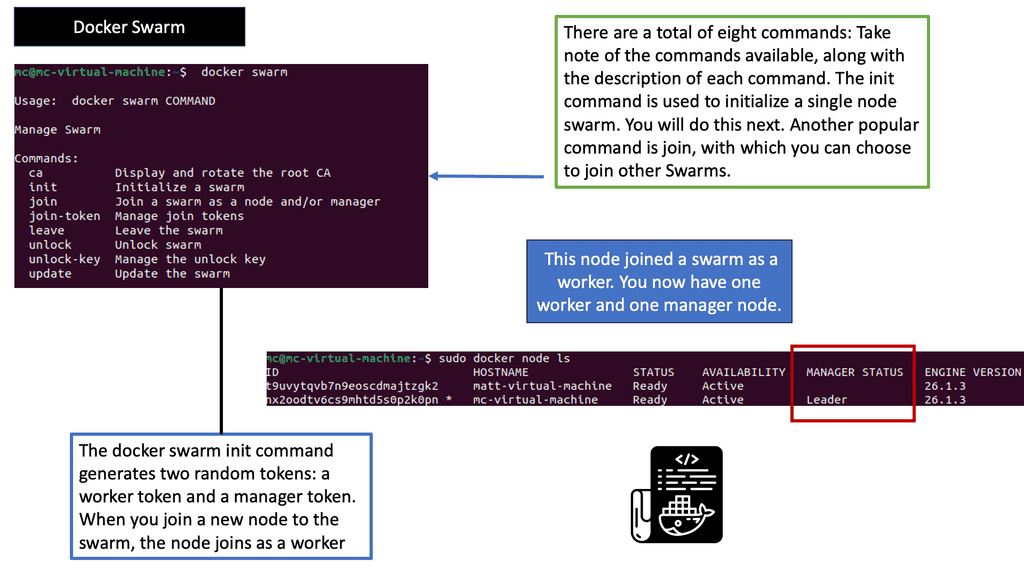
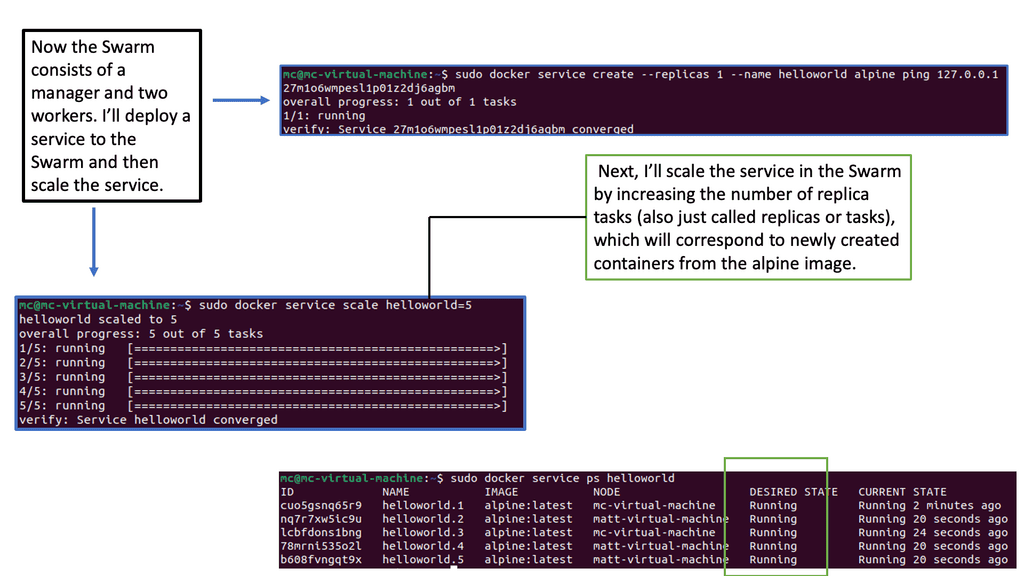
At its core, Docker Swarm is a native clustering and orchestration solution for Docker containers. It enables the creation of a swarm, a group of Docker nodes that work together in a distributed system. Each node in the swarm can run multiple containers, forming a resilient and scalable infrastructure. By abstracting away the complexity of managing individual containers, Docker Swarm empowers developers and operators to focus on their applications’ logic rather than infrastructure intricacies.

Docker Swarm offers a plethora of features that streamline container deployment and management. Automatic load balancing, service discovery, and rolling updates are just a few of the capabilities that make Swarm an attractive choice for container orchestration. Additionally, Swarm provides fault tolerance, ensuring high availability even in the face of node failures. Its intuitive command-line interface and integration with Docker CLI make it easy to adopt and incorporate into existing workflows.

Benefits and Advantages

The advantages of Docker Swarm are manifold. Firstly, Swarm allows horizontal scaling, enabling applications to handle increased workloads effortlessly. Scaling up or down can be achieved seamlessly without downtime or disruptions. Furthermore, Swarm promotes fault tolerance through its replication and distribution mechanisms, ensuring that applications remain highly available even when faced with failures.

With built-in service discovery and load balancing, Swarm simplifies deploying and managing microservices architectures. Additionally, Swarm integrates well with other Docker tools and services, such as Docker Compose and Docker Registry, further enhancing its versatility.

What is Minikube?

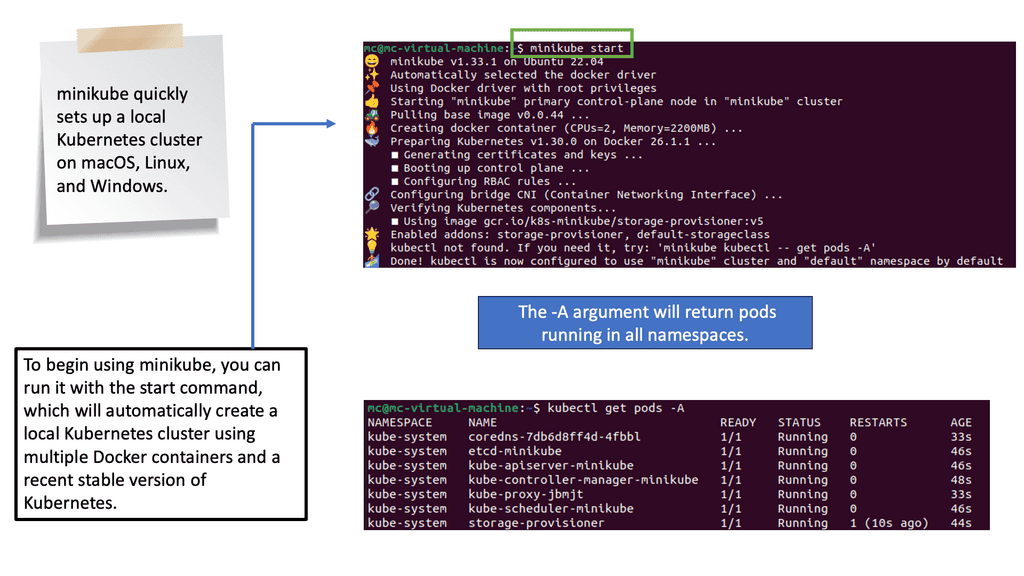
Minikube is a lightweight, open-source tool that enables developers to run a single-node Kubernetes cluster locally. It provides a simplified way to set up and manage a Kubernetes environment on your machine, allowing developers to experiment, test, and develop applications without needing a full-scale production cluster. With Minikube, developers can replicate the production environment on their local machines, saving time and effort during development.

Example OpenShift: Network Services

The most common network service allows a source to reach an application endpoint. Nowadays, the network function no longer solely satisfies endpoint reachability; it is fully integrated into the application. In the case of OpenShift networking, the Route and Sevice construct provides both reachability and an abstraction layer for application access.

In the past, applications had three standard components: cache, web server, and database. Applications look very different now. Several services interact, are completely decoupled into units, and are packaged in containers; all are mobile and may move around.

Container Networking and the CNI

Running a container requires a host. On-premises data centers may use physical machines such as bare-metal servers, or virtual machines may be used in the cloud.

Docker daemon and client access interactive container registry. Containers can also be started, stopped, paused, and inspected, and container images pulled/pushed. Modern containers often comply with Open Container Initiative (OCI), and Docker is not the only option. Kubernetes and other alternatives to Docker can also be helpful.

Hosts and containers have a 1:N relationship. Typically, one host runs several containers. Facebook reports running 10 to 40 containers per host, depending on the machine’s beefiness.

You will likely have to deal with networking whether you use a single host or a cluster:

  • A single-host deployment almost always requires connecting to other containers on the same host; for example, WildFly might need to connect to a database.

  • During multi-host deployments, you must consider how containers communicate inside and between hosts. Your design decisions will likely be influenced by performance and security concerns. An Apache Spark or Apache Kafka cluster generally requires multiple hosts when a single host’s capacity is insufficient or for resilience reasons.

Docker networking

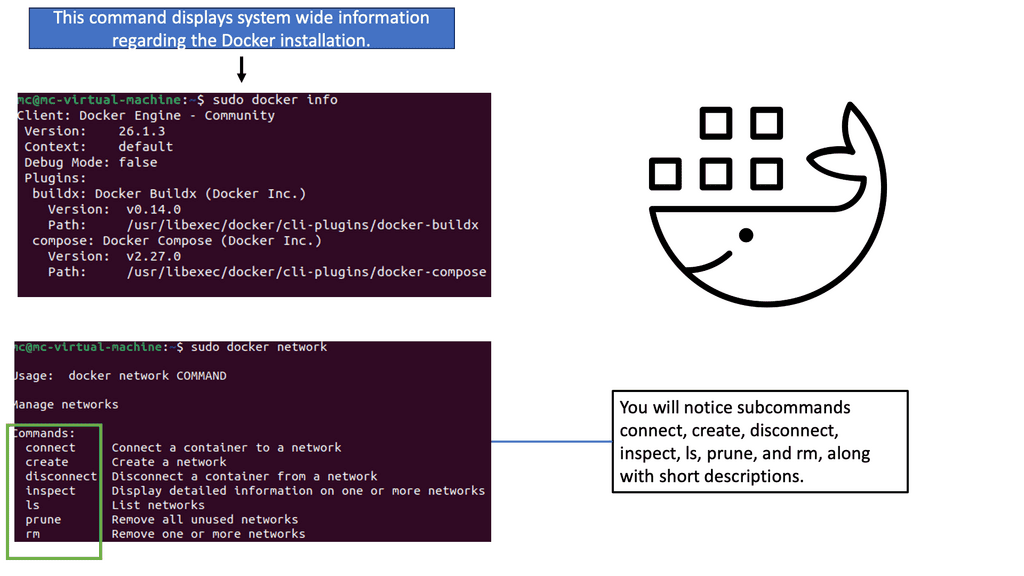
In a nutshell, Docker offers four single-host networking modes:

  • Bridge mode

This is the default network driver for apps running in standalone containers.

  • Host mode

It is also used for standalone containers, removing network isolation from the host.

  • Container mode

It lets you reuse another container’s network namespace. Used in Kubernetes.

  • No networking

It disables Docker networking support and allows you to set up custom networking.’

Knowledge Check: Container Security

Understanding Namespaces

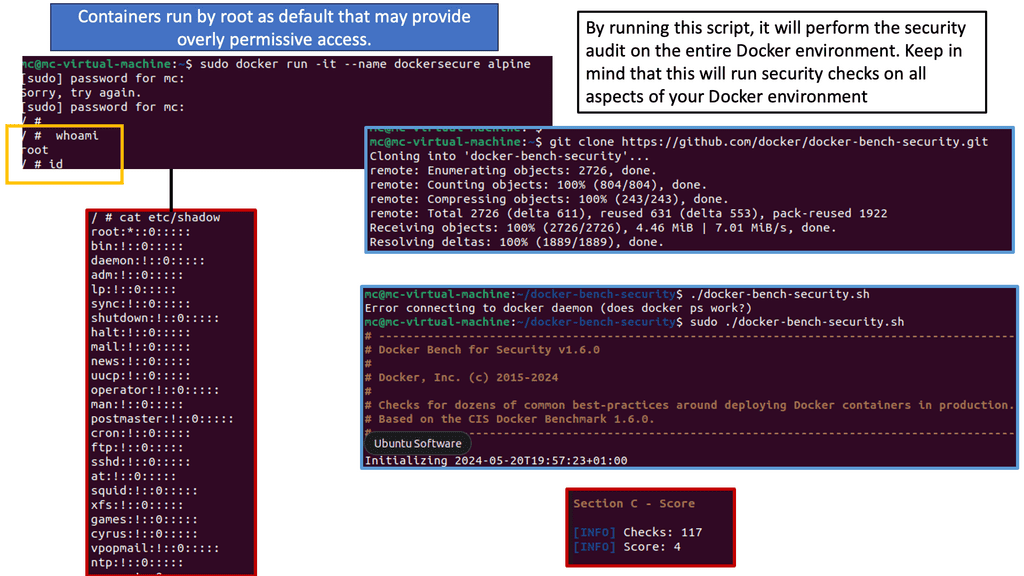
Namespaces is a fundamental building block for achieving resource isolation within a Linux environment. They can virtualize system resources like process IDs, network interfaces, and file systems. By creating separate namespaces for different processes or groups of processes, we can ensure that each entity operates in its isolated environment, oblivious to other processes outside its namespace.

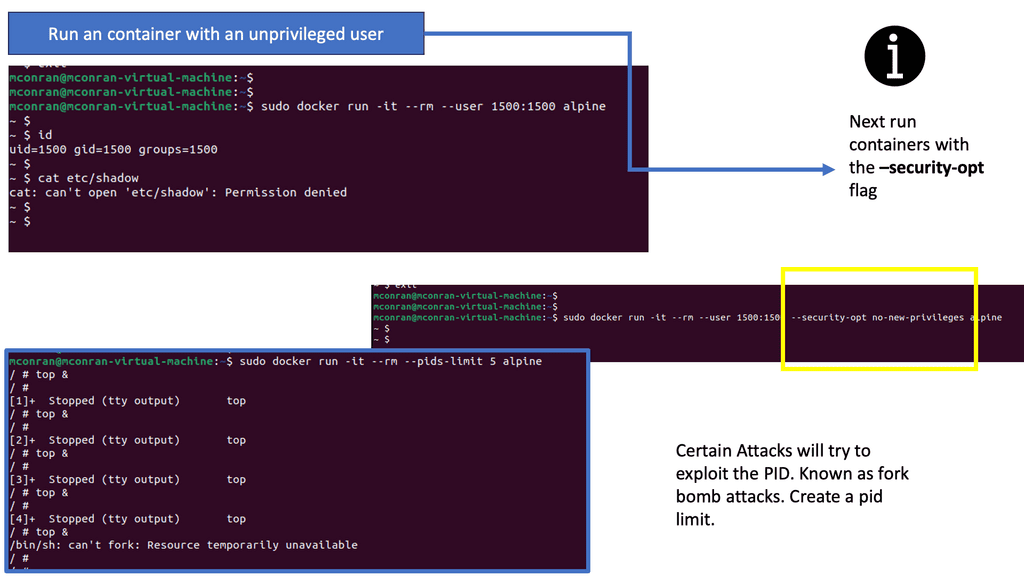
While namespaces focus on resource isolation, control groups take the concept further by enabling resource management. Control groups, commonly known as cgroups, allow administrators to allocate and limit system resources to specific processes or groups of processes, such as CPU, memory, and I/O. This fine-grained control enhances system performance, prevents resource starvation, and ensures fair distribution among entities.

**Network Security for Docker**

Securing the network connectivity of your Docker environment is essential to protect against potential attacks. Consider implementing these practices:

– Utilize Docker’s network security features, such as network segmentation and access control lists (ACLs).

– Enable and enforce firewall rules to control inbound and outbound traffic to and from containers.

– Consider using encrypted communication protocols (e.g., HTTPS) for containerized applications.

**Docker Host Security**

Securing the underlying Docker host is paramount for overall container security. Here are a few tips to enhance host security:

– Regularly update the host operating system and Docker daemon to patch known vulnerabilities.

– Employ strong access control measures to limit administrative privileges on the host.

– Implement intrusion detection and prevention systems to monitor and detect any unauthorized activities on the host.

container security

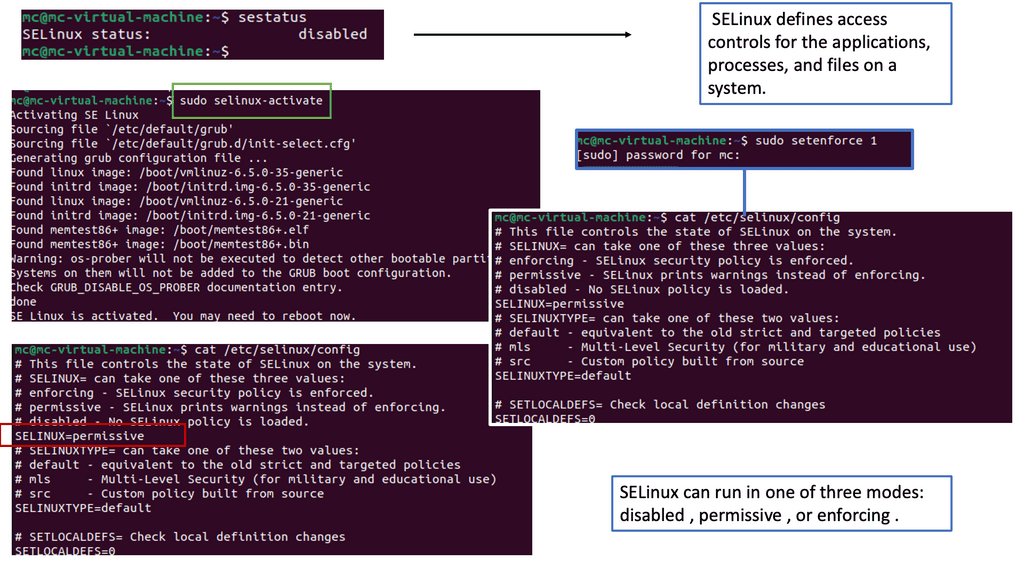
**Understanding SELinux**

SELinux is a mandatory access control (MAC) system that enforces fine-grained policies to restrict access and actions within a Linux system. It defines rules and labels for processes, files, and network resources, ensuring that only authorized activities are allowed.

When SELinux is enabled, it actively enforces access control policies on Docker containers and their associated network resources. SELinux labels define and implement rules regarding network communication, preventing unauthorized access or tampering.

One critical benefit of SELinux in Docker networking is its ability to mitigate network-based attacks. By leveraging SELinux’s access control capabilities, containers are isolated and protected from potential network threats. Unauthorized network interactions are blocked, reducing the attack surface and enhancing overall security.

Container Networking • Architecture Experiment

Which Container Network Model Fits the Job?

Change the networking model and traffic scenario to see how isolation, multi-host connectivity, performance characteristics and operational complexity change. The results are an educational comparison, not a benchmark.

Network Topology
HOST A
app-01
api-01
⇄
CONTAINER
NETWORK
⇄
HOST B
db-01
cache-01
Illustrative Behaviour
Isolation
70%
Performance
70%
Multi-host
30%
Simplicity
75%
[ready] Select a model and traffic scenario.
[lab] Results are illustrative networking behaviour.
Experiment Result
Network Scope Single Host
Namespace Isolated
Connectivity Available
Isolation Strong
Operational Trade-off Balanced
Engineering Insight
Bridge networking is a useful baseline for understanding container connectivity. It preserves network namespace isolation while providing a host-local virtual network.

Container Networking

Docker Networking

The Docker networking model uses a virtual bridge network by default, defined per host, and a private network where containers attach. The container’s IP address is allocated a private IP address, which indicates containers operating on different machines cannot communicate with each other.

In this case, you will have to map host ports to container ports and then proxy the traffic to reach across nodes with Docker. Therefore, it is up to the administrator to avoid port clashes between containers. Kubernetes networking handles this differently.

**Challenges in Container Networking**

Container networking presents several challenges that must be addressed to ensure optimal performance and reliability. Some of the key challenges include:

  • Network Isolation: Containers should be isolated from each other to prevent unauthorized access and potential security breaches.
  • IP Address Management: Containers are assigned unique IP addresses, which can quickly become challenging to manage as the number of containers grows.
  • Scalability: As the container ecosystem expands, the networking infrastructure must scale effortlessly to accommodate the increasing number of containers.
  • Service Discovery: Containers need a reliable mechanism to discover and communicate with other services within the network, especially in a microservices architecture.

**Solutions and Best Practices**

To overcome these challenges, several solutions and best practices have emerged in the realm of container networking:

1. Container Network Interface (CNI): CNI is a specification that defines how container runtimes interact with networking plugins. It enables easy integration of various networking solutions into container orchestration platforms like Kubernetes and Docker.

2. Overlay Networking: Overlay networks create a virtual network that spans multiple hosts, allowing containers to communicate seamlessly, regardless of physical location. Technologies like VXLAN, GRE, and WireGuard are commonly used for overlay networking.

3. Network Policies: Network policies define the rules and restrictions for incoming and outgoing traffic between containers. By implementing network policies, organizations can enforce security and control network traffic flow within their containerized environments.
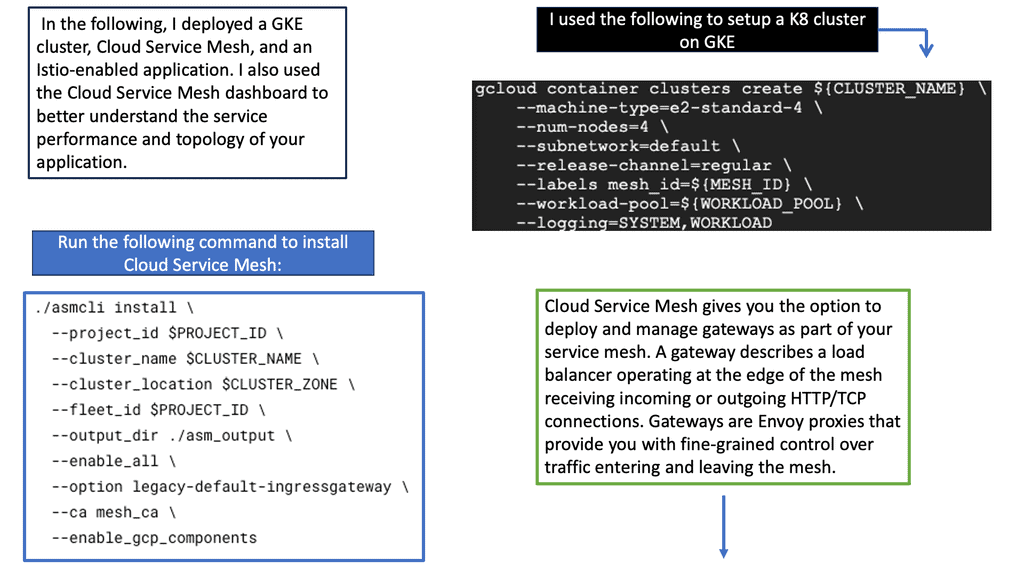
4. Service Mesh: Service mesh technologies, such as Istio and Linkerd, provide advanced networking capabilities, including traffic management, load balancing, and observability. They enhance the resilience and reliability of containerized applications by offloading complex networking tasks from individual services.

Service Mesh & Networking

### What is a Cloud Service Mesh?

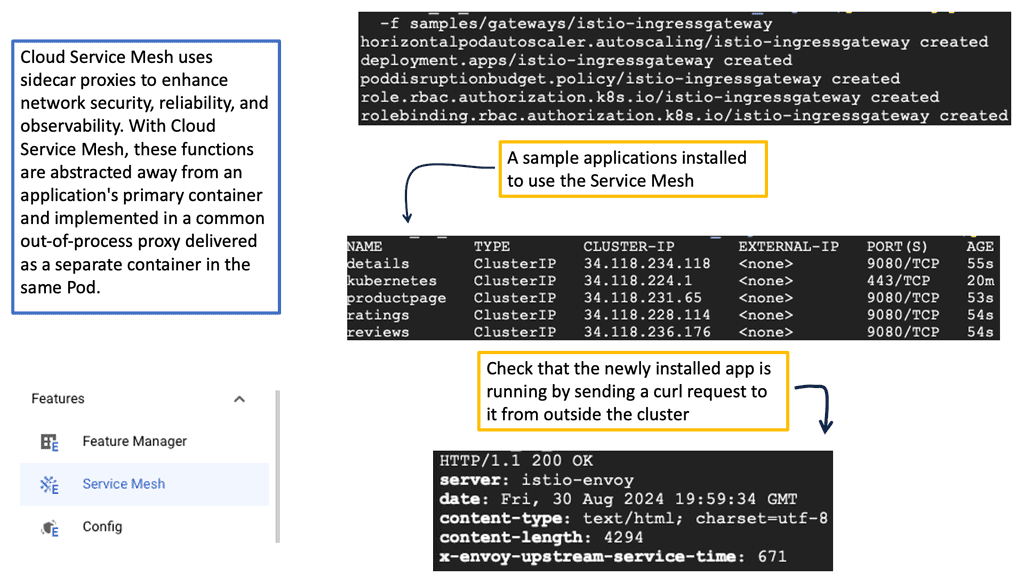
A Cloud Service Mesh is designed to handle the complex communication needs between various microservices within a cloud-native application. It provides a unified way to secure, connect, and observe services without the need to modify the application code. By abstracting the network logic from the business logic, a service mesh ensures that services can communicate seamlessly and securely, regardless of the underlying infrastructure.

### The Role of Container Networking

Container networking refers to the methods and protocols used to enable communication between containerized applications. Containers, which package applications and their dependencies, need an efficient way to communicate to ensure smooth operation. This is where Cloud Service Mesh comes into play. It provides advanced networking capabilities such as load balancing, traffic management, and secure communication channels specifically designed for containers. By integrating with container orchestrators like Kubernetes, a service mesh can automate and optimize these networking tasks.

### Key Benefits of Using a Cloud Service Mesh

1. **Enhanced Security**: A service mesh can handle encryption and secure communication between services, ensuring that data remains protected as it travels across the network.

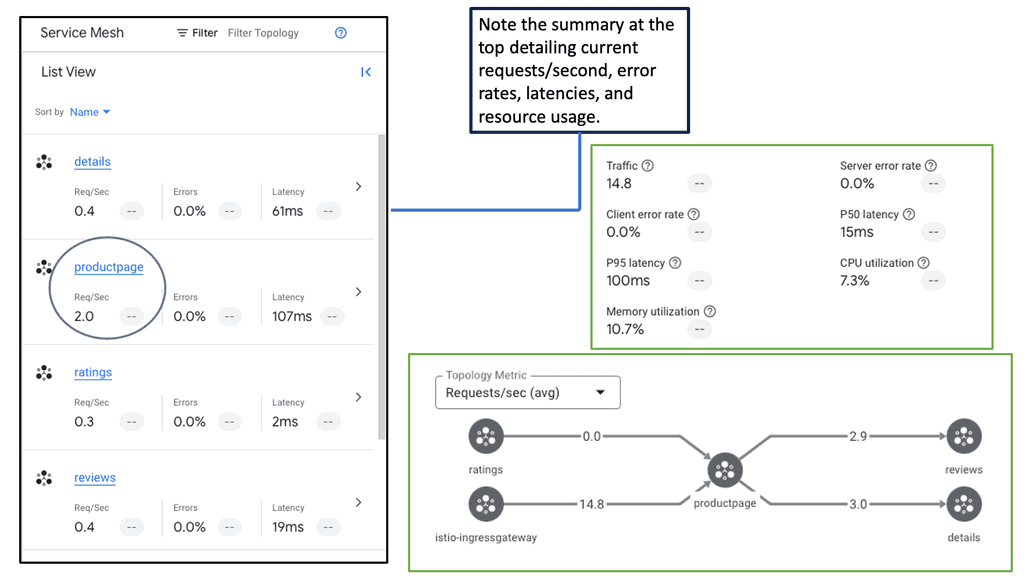
2. **Observability**: It provides insights into service performance and operational metrics, making it easier to diagnose issues and optimize performance.

3. **Traffic Management**: With features like traffic splitting, retries, and circuit breaking, a service mesh allows more granular control over how traffic flows between services.

4. **Resilience**: By managing retries and failovers, a service mesh can improve the overall resilience of applications, ensuring they remain available even during partial failures.

### Challenges and Considerations

While the benefits are compelling, implementing a Cloud Service Mesh is not without its challenges. Complexity in setup and management, potential performance overhead, and the need for specialized knowledge are some of the hurdles that organizations might face. It’s essential to evaluate whether the benefits outweigh these challenges in the context of your specific use case.

### Real-World Use Cases

Several leading organizations have already adopted Cloud Service Mesh to streamline their container networking. For instance, companies in the finance and healthcare sectors leverage service meshes to ensure secure and compliant communication between microservices. Meanwhile, tech giants use it to manage massive, distributed systems with ease, ensuring high availability and optimal performance.

Container Networking: A Different Application Philosophy

Computing is distributed over multiple elements, and they all interact arbitrarily. Network integration allows the application to be divided into several microservice components. Microservices will enable the application to be packaged into pieces and deployed on different hosts or even different cloud providers.

The application stack no longer belongs to a single server. Small, composable units enhance application replication and fault tolerance services. Containers and the ability to interconnect them make all this possible.

Containers offer a single-purpose environment. They are a bunch of lightweight namespaces and processes sharing a common kernel. Typically, you don’t run a full stack in a single container.

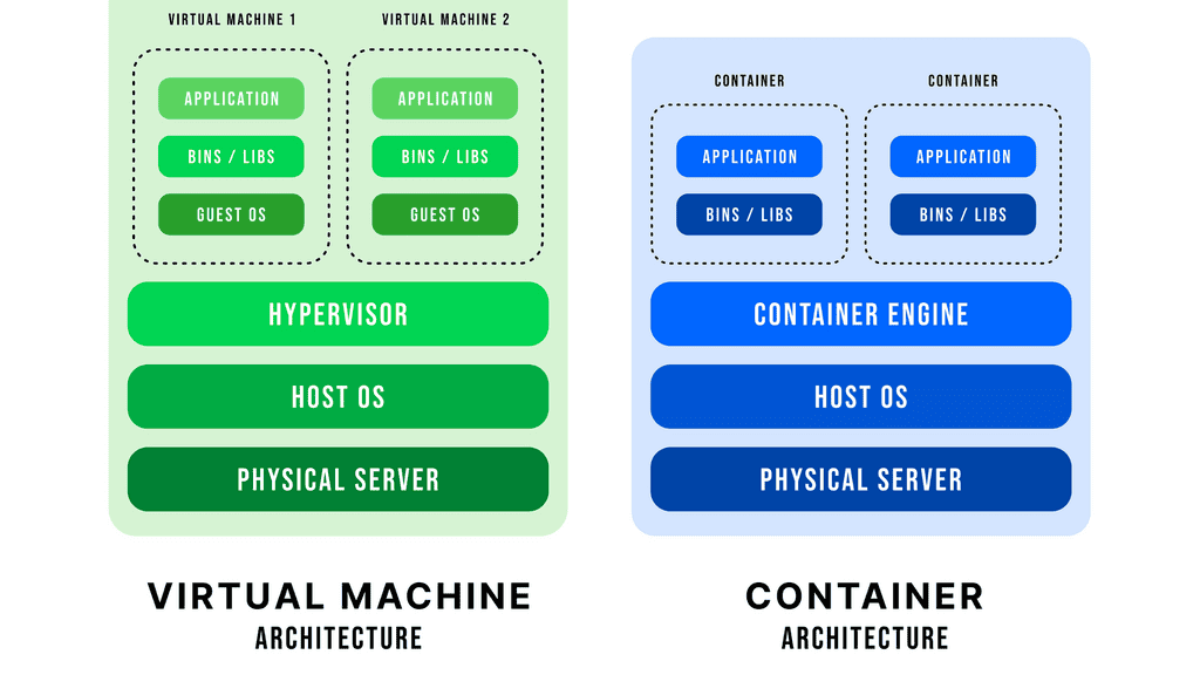
Ideally, there is only one process per container, which makes them very lightweight. VMs with guest O/S are resource-heavy; containers are a far better option if the application can be containerized.

However, containers offer an utterly different endpoint type for the network. With virtual machines spinning, they arrive and disappear quickly, measured in milliseconds, not seconds or minutes. The speed is down to their light properties. Some containerized application transactions only live for the length of transaction time. The infrastructure and network must be pre-built to support this type of endpoint.

Despite containerization’s advantages, remember that Docker container security and Docker security options are enabled at each point in the defense layer.

Introducing Docker Network Types

Docker Default Networking 101

Docker networking comes with several Docker network types and setups. The latest release is Docker version 1.10, which has enhancements, including linking with user-defined networks. There are other solutions available to enhance Docker networking functionality.

Docker is pluggable and allows ecosystem partners to plug into Docker networking. Project Calico offers a pure IP-based solution that utilizes the same principles of the Internet. Every host is an IP router. Calico uses a Felix agent and a BGP BIRD demon. This would be a clean option if the application only needs Layer 3 connectivity. 

The weave is another solution that operates an overlay function and aims to fit the multi-data center requirements. Each host in a Weave network thinks it belongs to one large switched fabric. The physical locations are abstracted, and they all have reachability. A multi-datacenter solution must concern itself with metrics other than endpoint reachability.

Container Networking with Linux Kernel and User Namespaces

Several unique resources, such as network interfaces and file systems, appear isolated inside each container even though the containers share the Linux kernel. Global resources are abstracted to appear unique per container, an abstraction made available using Linux namespaces.

Namespaces initially provided resource isolation for the first Linux containers project, offering a process virtualization solution. They do not create additional operating system instances on the host but instead use a single system with resource isolation.

Similarly, FreeBSD, where Jails provides resource isolation while running one kernel instance. In 2002, mount namespaces were the first type of Linux namespace with kernel 2.4.19. User namespaces emerged with kernel 3.8. 

The Different Namespaces

Containers have namespaces for each type of resource. We have six namespaces. 

    • Mount namespace makes the container feel like it has its filesystem. 
    • UTS namespace offers individual hostnames and domain names. 
    • User namespace provides isolation between the user and group IDs. 
    • IPC namespace isolates message queue systems. 
    • PID namespace offers different PIDs inside the container.

Finally, the network namespace gives the container a separate network stack. When you issue the docker ps command, you will see what ports are bound; these ports are on the namespace network interface.

Docker Networking and Docker Network Types

Install docker creates three network types – bridge, host, and none. You cannot delete these networks; you only interact with the default bridge network. There is the option to create user-defined networks and customized plugins. 

Network plugins (LibNetwork project) extend the docker network to support additional networking features such as IP VLAN or macvlan. User-defined networks can take the form of bridge or overlay networks.

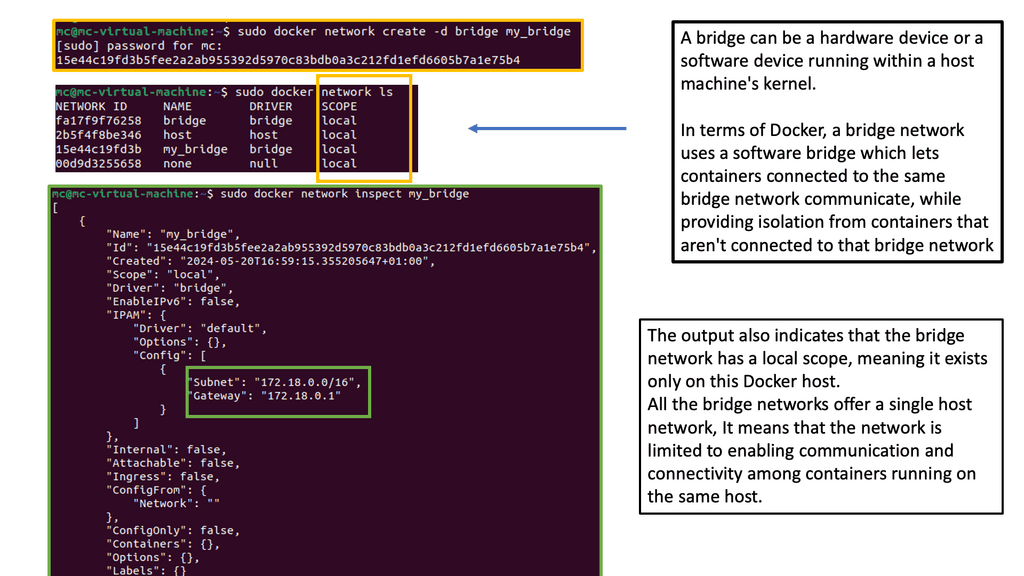
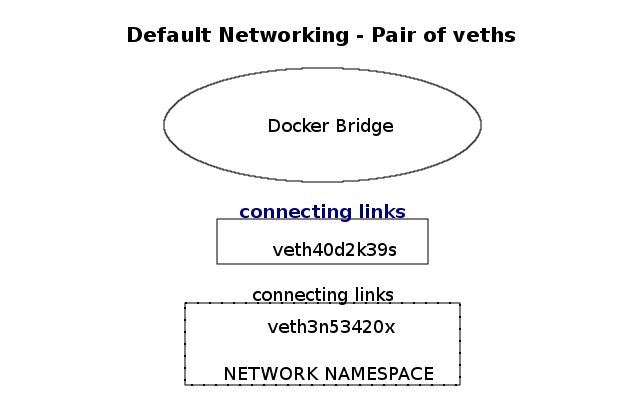
Bridge networks have a single-host local scope, and overlay networks have a multi-host global scope. The diagram below displays the default bridge and the corresponding attached containers. The driver is “default,” meaning it has local scope.

Container Networking

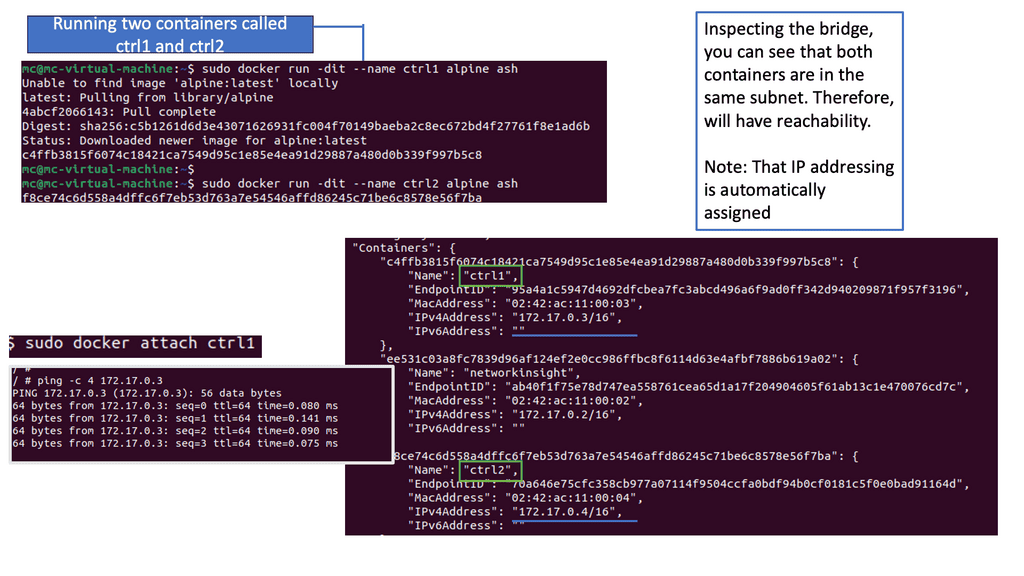
The user-defined bridge is similar to the default bridge0. Containers from the same host are added and can cross-communicate. External access is not prohibited, but you can expose network sections with port mappings.

The user-defined overlay networking feature enables multi-host networking using the VXLAN networking driver libnetwork and Docker’s libkv library. The overlay function requires a valid key-value store.

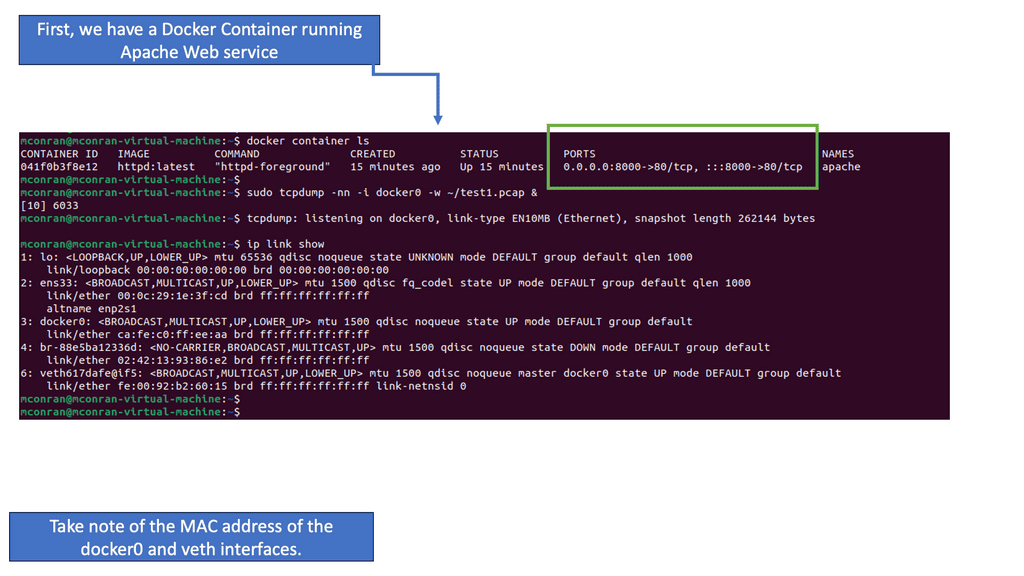
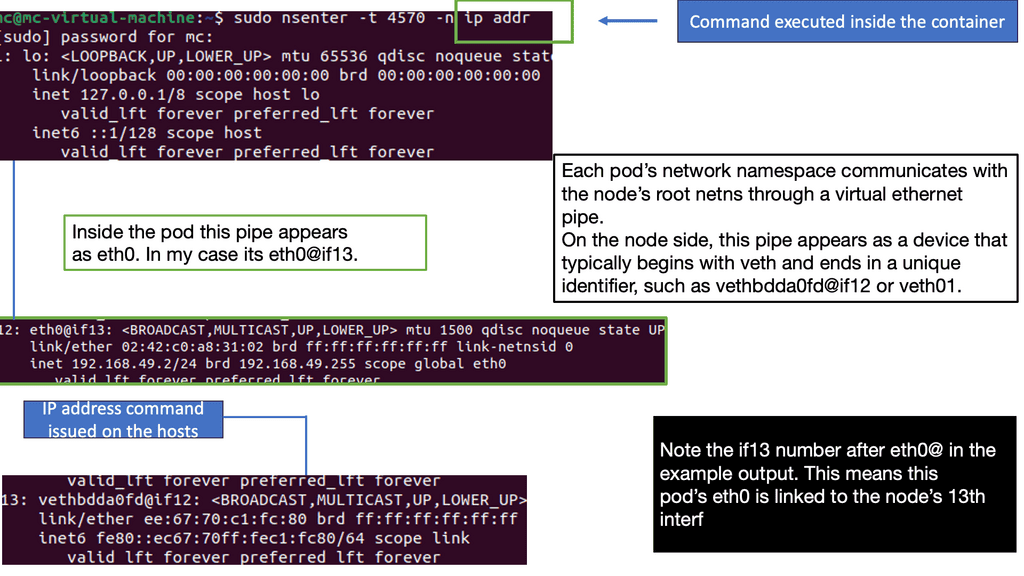
The Docker libkv library supports Consul, Etcd, and ZooKeeper. With Docker default networking, a veth pair is created—one inside the container and the other outside in the namespaces. All are connected via the docker bridge. The veth is mapped to appear as eth0 in the container, using Linux namespaces.

Container Networking

Container networking, port mapping, and traffic flow.

Docker container networking cross-communicates if they are on the same machine and thus connect to the same virtual bridge. Containers can also connect to multiple networks at the same time. By default, containers on different machines can not reach each other. Cross-communication on different nodes must be allocated ports on the machine’s IP address, which are then proxied to the containers.

Port mapping provides access to the container from the outside. Docker allocates a DNAT port in the range of 49153 – 65535. This additional functionality continues to use the default Docker0 bridge but adds IPtables rules for the DNAT.

When you spin up a container and do a port mapping, you can see it inside the docker ps command that you have a port mapping from, for example, the host 8080 to container 80. IPtables is setting a port mapping between 8080 and the IP addresses assigned to the container.

The problem with Docker is that you may have to coordinate ports and plenty of NAT. NAT was designed to address the shortage of IPv4 addresses and was only meant to be used for a short period. It is so ingrained in people’s minds we still see it come out in fresh designs.

Ports and NAT are problematic at scale and expose users to cluster-level issues outside their control. This can lead to port conflicts and many complexities in scheduling. 

Kubernetes

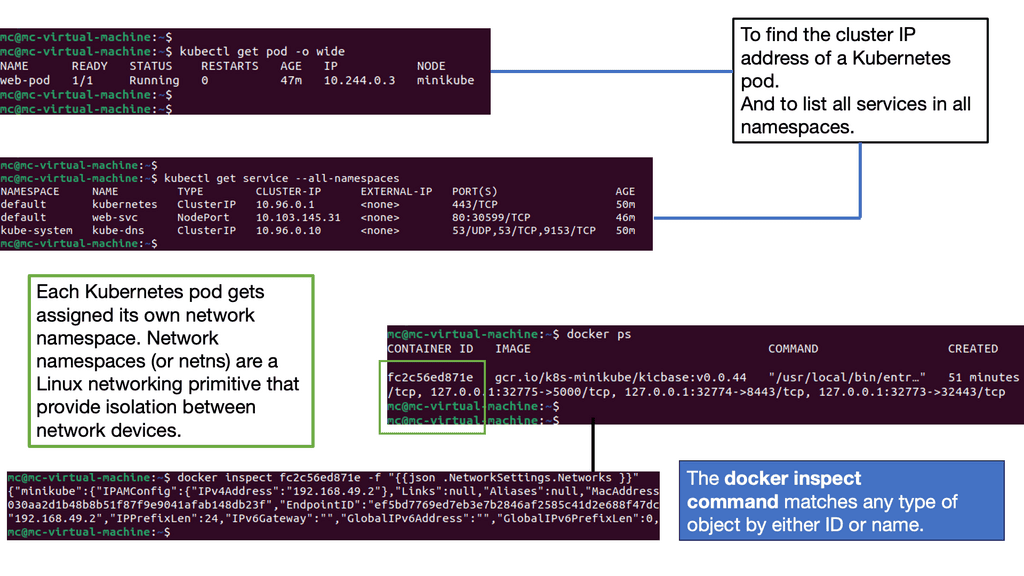
Kubernetes networking does not use any NAT. Instead, it applies IP addresses at the Pod scope level. Remember that containers within a Pod share network namespaces, including their IP address. This means containers within a Pod can all reach each other’s ports on localhost. Kubernetes makes finding and configuring Kubernetes services much easier due to the unique IP addresses per Pod model.

Kubernetes Networking 101

Kubernetes Networking 101: IP-per-pod-model

Kubernetes network namespace has two fundamental abstractions – Pods and Services. Pods are essentially scheduling ATOMs in Kubernetes. They represent a group of tightly integrated containers that share resources and fate. An example of an application container grouping in a Pod might be a file puller and a web server.

Frontend / Backend tiers usually fall outside this category as they can be scaled separately. Pods share a network namespace and talk to each other as local hosts.

Pods are assigned a private IP that is routable within the internal fabric. Docker doesn’t give you an IP; you must do weird things like going through a host and exposing a port. This is not a great idea, as port deployment may have issues and operational complexities.

With Kubernetes, all containers talk to each other, even across nodes, without NAT. The entire solution is NAT-less, flat address space. Pods can talk to Pods without any translations. Communications on ports can be done but with well-known port numbers, avoiding service discovery systems like DNS-SD, Consul, or Etcd.

Understanding Pod Networking

At the heart of Kubernetes networking lies the concept of pods. Pods are the basic building blocks of any Kubernetes cluster, encapsulating one or more containers that work together. To ensure seamless communication between pods, Kubernetes assigns each pod a unique IP address and exposes it to other pods within the cluster. 

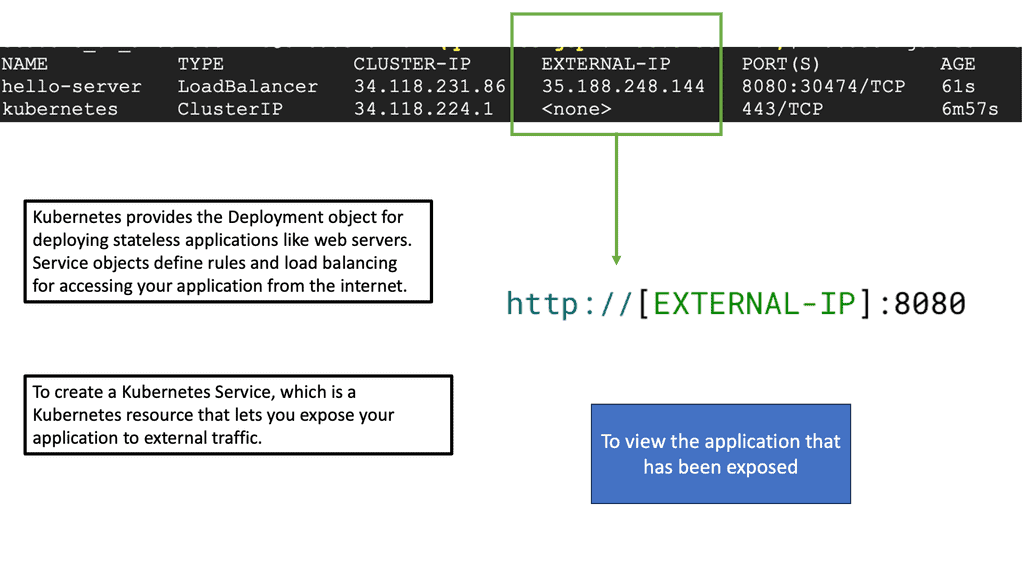
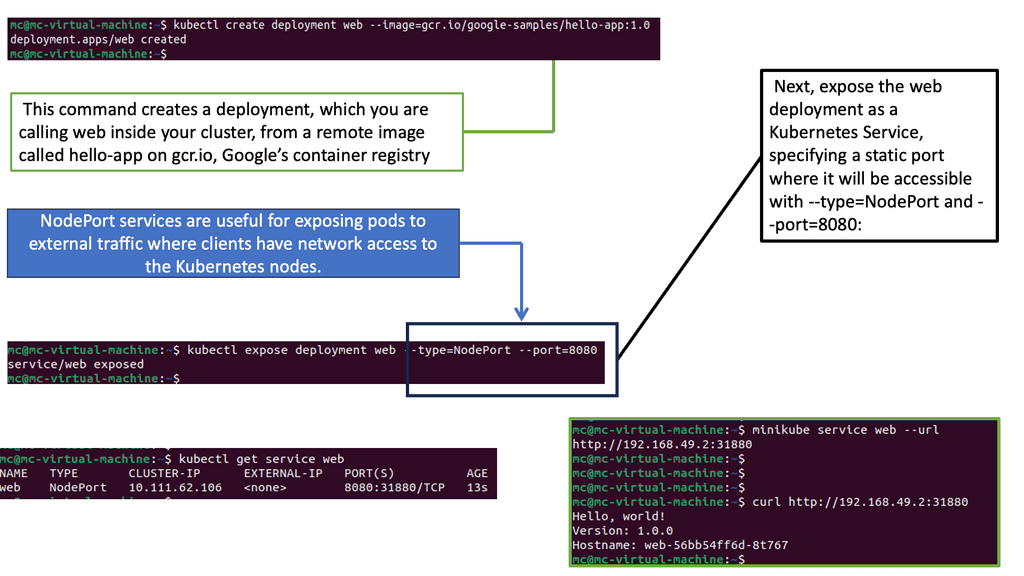
While pods enable communication within a cluster, services take it further by providing a stable endpoint for accessing a set of pods. There are various services in Kubernetes, including ClusterIP, NodePort, and LoadBalancer, with their use cases and how they enable service discovery.

Container network and services

The second abstraction is services. Services are similar to a load balancer. They are groups of Pods that act as one. It may be better to reference the service with an IP address, not a Pod. This is because Pods can go away, but services are more dedicated.

A typical flow would be something like this: a client on a cluster looks for IP for a particular service. The Kubernetes nodes that it is running on do an iptables DNAT. Instead of going to the service, it reroutes to the Kube proxy, which is a proxy running on every Kubernetes node.

It programs iptables rules to trap access to service IPs and redirect them to the backends using round-robin load balancing. It also watches the API server to determine which pods are active and ready to serve requests.

Several implementations include Google Compute Engine, Flannel, Calico, and OVS with GRE/VxLAN to support the IP-per-pod model. OpenVSwitch connects Pods on different hosts with GRE or VxLAN. The Linux bridge replaces the docker0 bridge, encapsulating traffic to and from Pods. Flannel may also be used with Kubernetes.

It creates an overlay network and gives a subnet to each host. Flannel can be used on cloud providers that cannot offer an entire /24 to each host. Flannels’ flannel agent runs on each host and controls the IP assignment. Calico, already mentioned, is also an IP-based solution that relies on traditional BGP.

Closing Points on Container Networking 

Container networking refers to the methods and protocols that enable containers to communicate with each other, with other applications, and with external networks. Unlike traditional virtual machines, containers share the same operating system but operate in isolated environments. This isolation necessitates specialized networking solutions to facilitate connectivity. From simple bridge networks to more complex overlay networks, container networking offers a variety of options to suit different needs and environments.

1. **Bridge Networks**: The default networking option for many container platforms, bridge networks allow containers on the same host to communicate with each other. This setup is ideal for simple applications or when all containers are on a single machine.

2. **Overlay Networks**: Perfect for multi-host deployments, overlay networks create a virtual network that spans across multiple machines. This type of network is essential for scaling applications across different infrastructure and provides a level of abstraction that simplifies network management.

3. **Host Networks**: In this configuration, containers share the host’s network stack. This can lead to improved performance since there’s no network address translation (NAT) overhead, but it also means less isolation compared to other networking types.

4. **Macvlan Networks**: These networks assign a unique MAC address to each container, allowing them to appear as physical devices on the network. This is useful for legacy applications that require direct network access.

Several tools and technologies have emerged to facilitate container networking, each offering unique features and capabilities:

– **Docker Networking**: Docker provides built-in networking capabilities that cater to a range of use cases, from simple bridge networks to more robust overlay networks.

– **Kubernetes Networking**: As one of the most popular container orchestration platforms, Kubernetes offers powerful networking features through its network plugins and service mesh integrations.

– **Cilium**: Leveraging eBPF technology, Cilium provides advanced networking and security capabilities, making it a popular choice for Kubernetes environments.

– **Weave Net**: A simple yet effective solution, Weave Net offers automatic network creation and service discovery, making it easier to manage container networks.

Container Networking • Incident Investigation

Why Can't the API Container Reach the Database?

Diagnose the failure using the evidence rather than immediately rebuilding the containers. Choose the most likely investigation path, then evaluate your diagnosis.

Incident Scenario
PRODUCTION CONNECTIVITY ALERT

api-01 cannot establish a TCP connection to db-01:5432. The application reports a connection timeout. The database itself appears healthy.

Evidence Collected
API Container
RUNNING
Database Container
RUNNING
Local Network
REACHABLE
DB TCP/5432
LISTENING
API → DB
TIMEOUT
Recent Change
NETWORK POLICY
Suspected Packet Path
▣
api-01
Application
→
◇
Container Network
Virtual Path
→
◈
Policy / Filter
TCP/5432
→
▣
db-01
TCP/5432
Choose Your Investigation
Investigation Result
Diagnostic Score
— / 4
Select the investigation path that best matches the evidence.
Incident Console
[incident] api-01 → db-01 TCP/5432 timeout
[evidence] both containers are RUNNING
[evidence] database socket is LISTENING
[evidence] local network is REACHABLE
[change] network policy modified recently
[action] select a diagnosis
Engineering Insight
Good troubleshooting narrows the failure domain before making destructive changes. Here, the containers and database service are healthy, while the recent policy change provides a strong lead.