Cisco ACI

ACI Cisco

Cisco ACI Components

Cisco Application Centric Infrastructure (ACI) represents a different way of approaching data centre networking. Rather than treating the network primarily as a collection of individually configured switches and interfaces, ACI uses application requirements and policy as the foundation for how connectivity, segmentation, and network behaviour are defined. This becomes particularly valuable as organizations operate physical servers, virtual machines, containers, and workloads across increasingly dynamic environments.

Cisco ACI brings the physical data centre fabric and software-defined policy model together through a centralized operational framework. The underlying network still provides the forwarding infrastructure, but administrators can define how applications and workloads should communicate without having to express every requirement as a series of device-by-device configurations. This separation between intent and implementation is central to the ACI model.

A major benefit is policy consistency. Instead of relying entirely on individual switch configurations, teams can define application relationships, network connectivity, and security requirements through policy. Those policies can then be applied across the fabric as workloads are deployed or changed, helping reduce configuration drift and making large environments easier to operate.

Security is another important part of the architecture. ACI supports segmentation and policy-based control between application tiers and workloads, allowing organizations to restrict communication according to defined requirements rather than relying solely on broad network boundaries. Integration with external security and operational platforms can further extend visibility and enforcement across the environment.

The model is also designed for scale. Modern data centres may contain large numbers of applications, virtual workloads, containers, and rapidly changing endpoints. A policy-driven fabric allows network operations to respond to those changes through automation and orchestration rather than requiring every network change to be handled manually. This can improve deployment consistency while reducing operational overhead.

ACI also provides a framework for connecting traditional physical infrastructure with virtualized and container-based workloads. This is important because most enterprise environments are not completely homogeneous: legacy applications, modern distributed applications, databases, virtualization platforms, and containerized services often coexist within the same broader architecture.

Hybrid and multi-cloud environments add another dimension. Organizations increasingly need consistent connectivity and policy across on-premises infrastructure and external cloud platforms. ACI can participate in these architectures through its integration and multi-site capabilities, helping organizations extend network and application policy across environments while recognizing that each cloud still has its own native networking and security model.

Cisco ACI is therefore best understood as a policy-driven data centre networking architecture, rather than simply a replacement for traditional switching. Its value comes from combining a scalable fabric with centralized policy, automation, segmentation, and application-aware operational models. For organizations managing complex data centre environments, this approach can provide a more consistent way to connect applications, enforce policy, and adapt the network as workloads evolve.

Cisco ACI • Interactive Architecture
ACI Fabric Architecture Explorer
Explore how APIC policy, the spine–leaf fabric and endpoint connectivity work together to create a policy-driven data-center network.
Learning objective: Understand how Cisco ACI separates policy and management from distributed forwarding — APIC defines intent while leaf and spine switches enforce and transport that policy.
MANAGEMENT / POLICY PLANE SPINE FABRIC LEAF / DATA-PLANE EDGE ENDPOINTS / WORKLOADS APIC CLUSTER Policy • Management • Orchestration SPINE 1 Fabric Transit SPINE 2 Fabric Transit LEAF 1 Endpoint Edge LEAF 2 Endpoint Edge LEAF 3 Endpoint Edge SERVER A EPG: WEB SERVER B EPG: APP SERVER C EPG: DB MULTI-PATH FABRIC / ECMP POLICY ENFORCEMENT AT THE LEAF EDGE
Fabric
Policy
Endpoint
Interactive Inspector
Cisco ACI Fabric
Fabric concept
Select a device or connection in the diagram to see how that component participates in the ACI architecture.
Selected component
Architecture overview
ACI concept
Policy-driven spine–leaf fabric
Why it matters
ACI separates centralized policy definition from distributed packet forwarding.

Highlights: Cisco ACI Components

The ACI Fabric

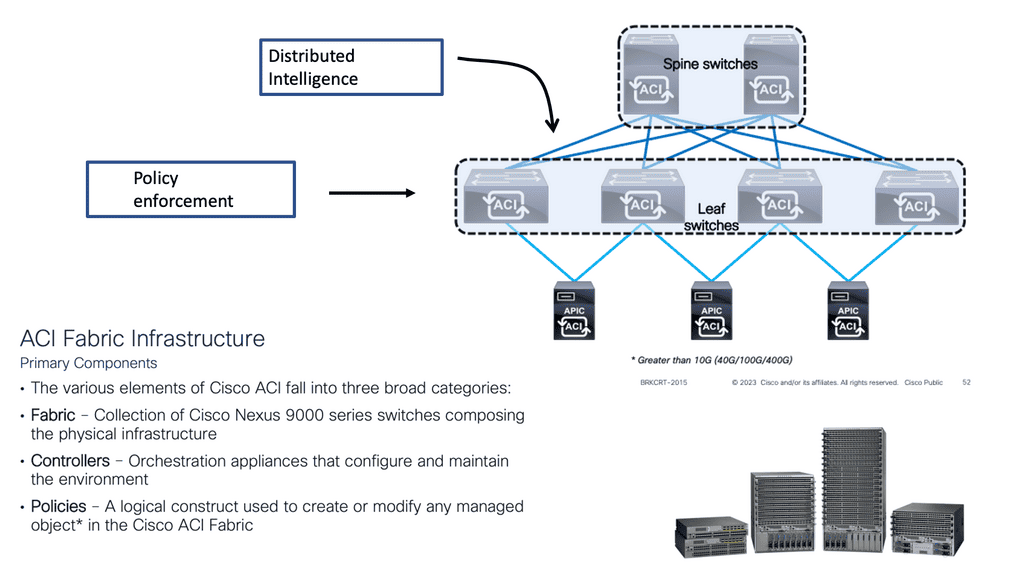
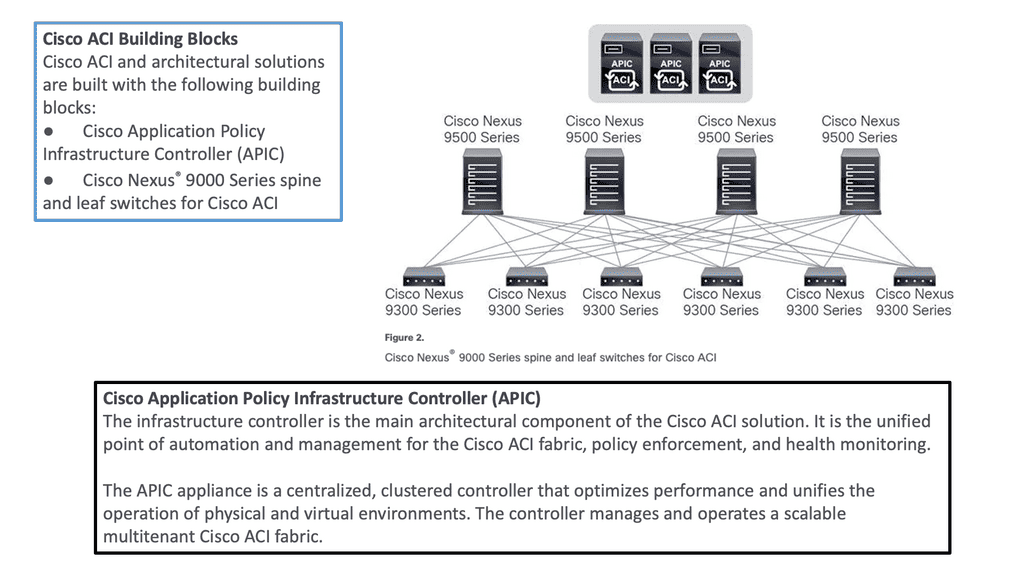
Cisco ACI is a software-defined networking (SDN) solution that integrates with software and hardware. With the ACI, we can create software policies and use hardware for forwarding, an efficient and highly scalable approach offering better performance. The hardware for ACI is based on the Cisco Nexus 9000 platform product line. The APIC centralized policy controller drives the software, which stores all configuration and statistical data.

–The Cisco Nexus Family–

To build the ACI underlay, you must exclusively use the Nexus 9000 family of switches. You can choose from modular Nexus 9500 switches or fixed 1U to 2U Nexus 9300 models. Specific models and line cards are dedicated to the spine function in ACI fabric; others can be used as leaves, and some can be used for both purposes. You can combine various leaf switches inside one fabric without any limitations.

a) Cisco ACI Fabric: Cisco ACI’s foundation lies in its fabric, which forms the backbone of the entire infrastructure. The ACI fabric comprises leaf switches, spine switches, and the application policy infrastructure controller (APIC). Each component ensures a scalable, agile, and resilient network.

b) Leaf Switches: Leaf switches serve as the access points for endpoints within the ACI fabric. They provide connectivity to servers, storage devices, and other network devices. With their high port density and advanced features, such as virtual port channels (vPCs) and fabric extenders (FEX), leaf switches enable efficient and flexible network designs.

c) Spine Switches: Spine switches serve as the core of the ACI fabric, providing high-bandwidth connectivity between the leaf switches. They use a non-blocking, multipath forwarding mechanism to ensure optimal traffic flow and eliminate bottlenecks. With their modular design and support for advanced protocols like Ethernet VPN (EVPN), spine switches offer scalability and resiliency.

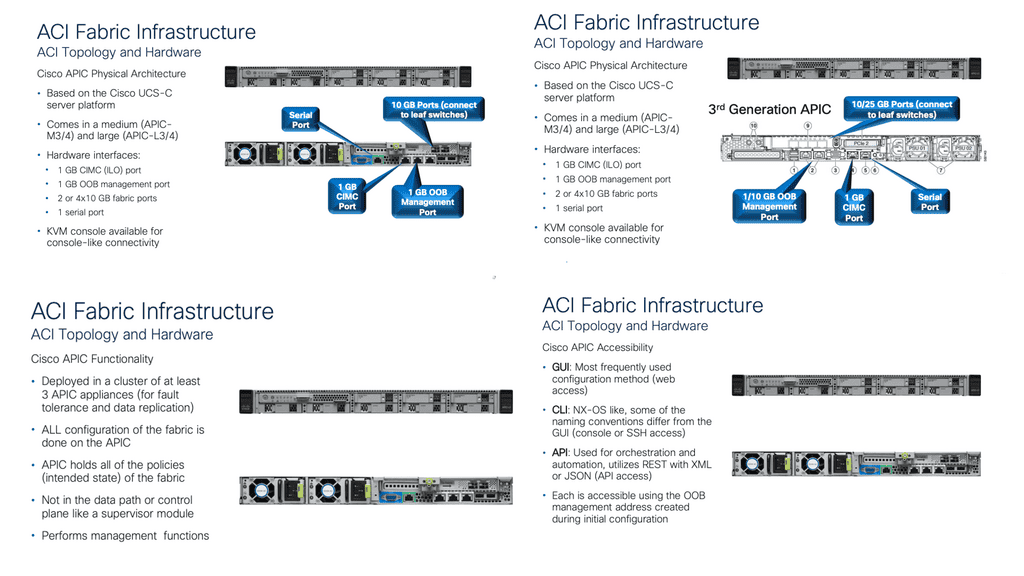
d) Application Policy Infrastructure Controller (APIC): At the heart of Cisco ACI is the APIC, a centralized management and policy control plane. The APIC acts as a single control point, simplifying network operations and enabling policy-based automation. It provides a comprehensive view of the entire fabric, allowing administrators to define and enforce policies across the network.

e) Integration with Virtualization and Cloud Environments: Cisco ACI seamlessly integrates with virtualization platforms such as VMware vSphere and Microsoft Hyper-V and cloud environments like Amazon Web Services (AWS) and Microsoft Azure. This integration enables consistent policy enforcement and visibility across physical, virtual, and cloud infrastructures, enhancing agility and simplifying operations.

Cisco ACI — Policy‑Driven, Application‑Centric Networking

Cisco ACI (Application Centric Infrastructure) is Cisco’s flagship data‑center fabric built around policy‑driven automation, centralized control, and application‑aware networking. Instead of configuring individual switches, ACI abstracts the network into application policies, endpoint groups, and contracts. This creates a programmable, intent‑based fabric where the network automatically aligns with application requirements. Data analytics strengthens ACI by providing visibility into fabric health, policy behavior, endpoint movement, and application flows, ensuring that the fabric remains consistent, secure, and optimized.

Policy Model — Endpoint Groups, Contracts, and Intent

ACI’s core innovation is its policy model:

  • Endpoint Groups (EPGs) define logical groupings of workloads
  • Contracts define how EPGs communicate
  • Application Network Profiles (ANPs) map application tiers to policies
  • Tenants provide multi‑domain isolation

This model replaces traditional VLANs, ACLs, and manual segmentation with intent‑based policies. Analytics enhances this by identifying unused contracts, misaligned EPGs, shadow policies, and unexpected east‑west flows. With analytics, ACI’s policy model becomes adaptive and identity‑aware rather than static.

Fabric Architecture — Spine‑Leaf, VXLAN, and Distributed Control

ACI uses a spine‑leaf architecture with VXLAN overlays and a centralized policy controller (APIC). The fabric provides:

  • consistent forwarding across all leaf switches
  • distributed anycast gateways
  • scalable multi‑tenant segmentation
  • automated endpoint learning

Analytics correlates fabric telemetry—routing updates, VXLAN behavior, endpoint mobility, and link performance—to detect anomalies such as asymmetric routing, endpoint flapping, or misconfigured policies. This ensures the fabric remains stable and predictable even under dynamic workloads.

Security and Microsegmentation in ACI

ACI provides built‑in microsegmentation through EPGs and contracts. Security becomes application‑centric rather than IP‑centric. Analytics enhances ACI security by monitoring:

  • unusual endpoint movement
  • abnormal contract usage
  • unexpected east‑west communication
  • privilege escalation inside application tiers

This transforms ACI into a Zero Trust‑aligned data‑center fabric where segmentation is continuously validated and enforced.

Operational Visibility — Telemetry, Health Scores, and Assurance

ACI includes extensive telemetry and health scoring across:

  • fabric nodes
  • policies
  • endpoints
  • application flows

Analytics consumes this telemetry to provide deeper insights into performance, security, and policy alignment. Tools like ACI AppDynamics integration, Nexus Dashboard Insights, and fabric assurance engines use analytics to detect drift, highlight anomalies, and recommend remediation. ACI becomes a self‑optimizing fabric driven by real‑time intelligence.

ACI in Hybrid and Multi‑Cloud Architectures

ACI extends beyond the data center into cloud environments through ACI Anywhere and Cloud ACI. Policies can be pushed to AWS, Azure, and GCP, creating a unified segmentation and security model across hybrid environments. Analytics ensures consistency across on‑prem and cloud fabrics, detecting mismatches, drift, and cross‑cloud anomalies. This creates a seamless, policy‑driven hybrid architecture.

–ACI Architecture: Spine and Leaf–

To be used as ACI spines or leaves, Nexus 9000 switches must be equipped with powerful Cisco CloudScale ASICs manufactured using 16-nm technology. The following figure shows the Cisco ACI based on the Nexus 9000 series. Cisco Nexus 9300 and 9500 platform switches support Cisco ACI. As a result, organizations can use them as spines or leaves to utilize an automated, policy-based systems management approach fully. 
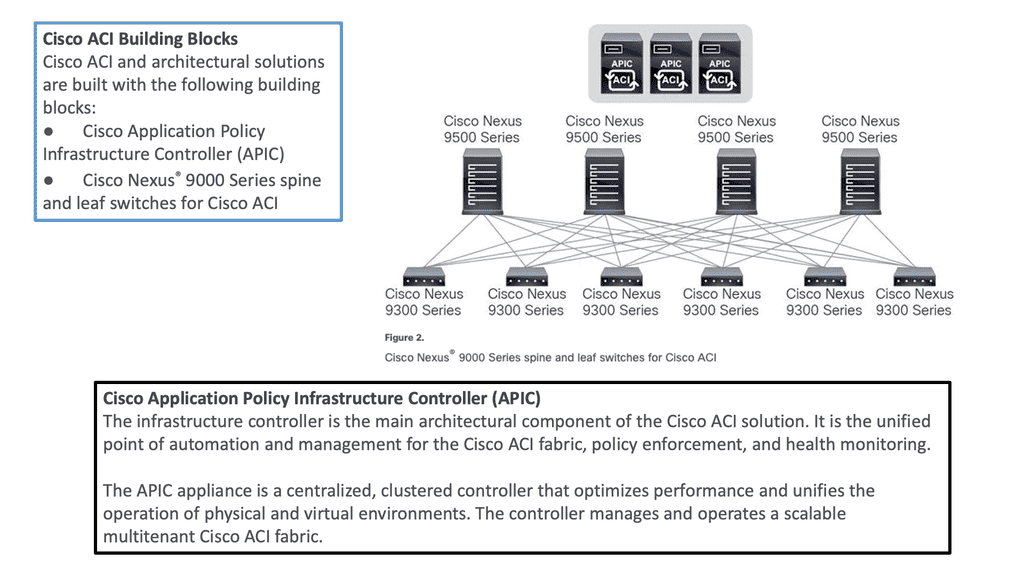
Cisco ACI Components
Diagram: Cisco ACI Components. Source is Cisco

**Hardware-based Underlay**

Server virtualization helped by decoupling workloads from the hardware, making the compute platform more scalable and agile. However, the server is not the main interconnection point for network traffic. So, we need to look at how we could virtualize the network infrastructure similarly to the agility gained from server virtualization.

**Mapping Network Endpoints**

This is carried out with software-defined networking and overlays that could map network endpoints and be spun up and down as needed without human intervention. In addition, the SDN architecture includes an SDN controller and an SDN network that enables an entirely new data center topology.

**Specialized Forwarding Chips**

In ACI, hardware-based underlay switching offers a significant advantage over software-only solutions due to specialized forwarding chips. Furthermore, thanks to Cisco’s ASIC development, ACI brings many advanced features, including security policy enforcement, microsegmentation, dynamic policy-based redirect (inserting external L4-L7 service devices into the data path), or detailed flow analytics—besides the vast performance and flexibility.


Cisco ACI • Fabric Mechanics

ACI Overlay & Underlay Lab

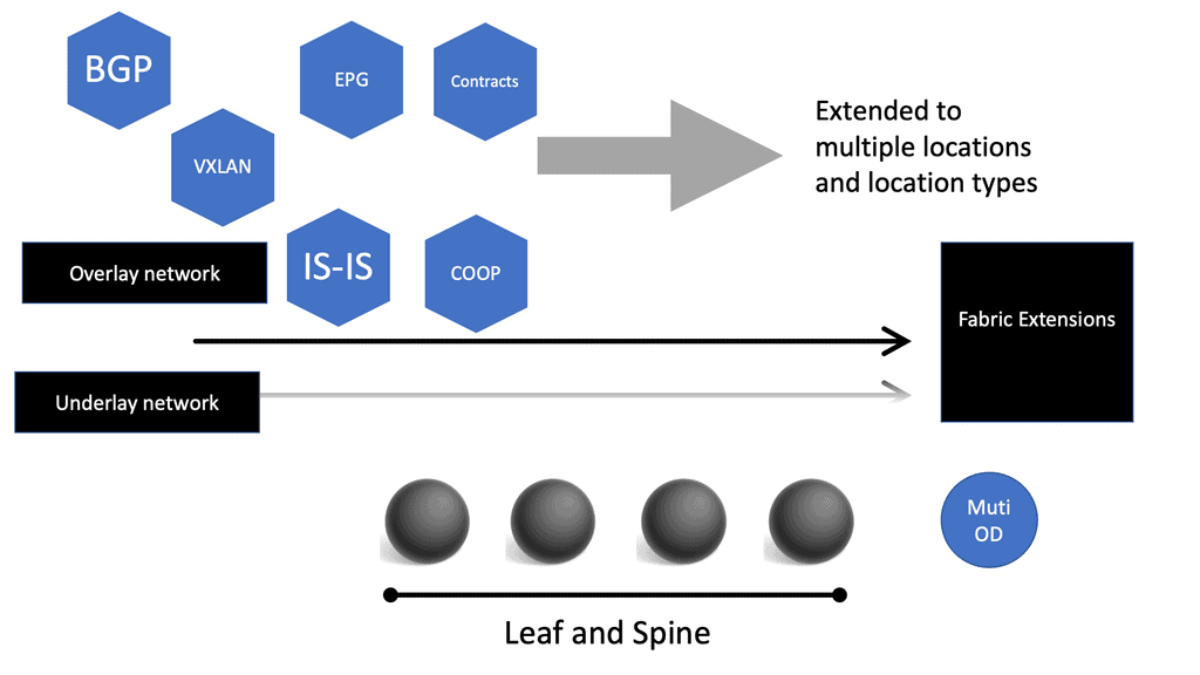
See how ACI builds the fabric: IS-IS provides the underlay, VXLAN carries the overlay, VTEPs connect endpoints, and COOP helps the fabric locate endpoints.
ACI FABRIC MECHANICS OVERLAY UNDERLAY ENDPOINTS VXLAN OVERLAY Leaf 1 VTEP Leaf 2 VTEP IS-IS UNDERLAY Spine Fabric transport Leaf 1 Underlay node Leaf 2 Underlay node COOP Endpoint database Server A Endpoint Server B Endpoint FABRIC TRANSPORT ATTACHMENT ATTACHMENT
IS-IS Underlay
VXLAN Overlay
COOP Control Plane
Endpoint Attachment
Selected Component
ACI Fabric Flow
Start here. ACI separates the physical transport network from the logical VXLAN overlay. Click a tab, node, or connection to explore how the pieces work together.
Technology
IS-IS + VXLAN + VTEP + COOP
Role
Build transport, carry overlay traffic, and locate endpoints.
Why it matters
This separation allows ACI to provide scalable fabric connectivity without making applications depend on the physical topology.

Cisco ACI Components

 Introduction to Leaf and Spine

The Cisco SDN ACI works with a Clos architecture, a fully meshed ACI network. Based on a spine leaf architecture. As a result, every Leaf is physically connected to every Spine, enabling traffic forwarding through non-blocking links. Physically, a leaf switch set creates a leaf layer attached to the spines in a full BIPARTITE graph. This means that each Leaf is connected to each Spine, and each Spine is connected to each Leaf. 

The ACI uses a horizontally elongated Leaf and Spine architecture with one hop to every host in an entirely messed ACI fabric, offering good throughput and convergence needed for today’s applications.

The ACI fabric: Does Not Aggregate Traffic

A key point in the spine-and-leaf design is the fabric concept, like a stretch network. One of the core ideas around a fabric is that it does not aggregate traffic. This does increase data center performance along with a non-blocking architecture. With the spine-leaf topology, we are spreading a fabric across multiple devices.

Required: Increased Bandwidth Available

The result of the fabric is that each edge device has the total bandwidth of the fabric available to every other edge device. This is one big difference from traditional data center designs; we aggregate the traffic by either stacking multiple streams onto a single link or carrying the streams serially.

Challenge: Oversubscription

With the traditional 3-tier design, we aggregate everything at the core, leading to oversubscription ratios that degrade performance. With the ACI Leaf and Spine design, we spread the load across all devices with equidistant endpoints, allowing us to carry the streams parallel.

Required: Routed Multipathing

Then, we have horizontal scaling load balancing.  Load balancing with this topology uses multipathing to achieve the desired bandwidth between the nodes. Even though this forwarding paradigm can be based on Layer 2 forwarding ( bridging) or Layer 3 forwarding ( routing), the ACI leverages a routed approach to the Leaf and Spine design, and we have Equal Cost Multi-Path (ECMP) for both Layer 2 and Layer 3 traffic. 

**Overlay and Underlay Design**

Mapping Traffic:

So you may be asking how we can have Layer 3 routed core and pass Layer 2 traffic. This is done using the overlay, which can map different traffic types to other overlays. So, we can have Layer 2 traffic mapped to an overlay over a routed core.

L3 active-active links: ACI links between the Leaf and the Spine switches are L3 active-active links. Therefore, we can intelligently load balance and traffic steer to avoid issues. We don’t need to rely on STP to block links or involve STP in fixing the topology.

Challenge: IP – Identity & Location

When networks were first developed, there was no such thing as an application moving from one place to another while it was in use. So, the original architects of IP, the communication protocol used between computers, used the IP address to indicate both the identity of a device connected to the network and its location on the network. Today, in the modern data center, we need to be able to communicate with an application or application tier, no matter where it is.

Required: Overlay Encapsulation

One day, it may be in location A and the next in location B, but its identity, which we communicate with, is the same on both days. An overlay is when we encapsulate an application’s original message with the location to which it needs to be delivered before sending it through the network. Once it arrives at its final destination, we unwrap it and deliver the original message as desired.

The identities of the devices (applications) communicating are in the original message, and the locations are in the encapsulation, thus separating the place from the identity. This wrapping and unwrapping is done on a per-packet basis and, therefore, must be done quickly and efficiently.

**Overlay and Underlay Components**

The Cisco SDN ACI has an overlay and underlay concept, which forms a virtual overlay solution. The role of the underlay is to glue together devices so the overlay can work and be built on top. So, the overlay, which is VXLAN, runs on top of the underlay, which is IS-IS. In the ACI, the IS-IS protocol provides the routing for the overlay, which is why we can provide ECMP from the Leaf to the Spine nodes. The routed underlay provides an ECMP network where all leaves can access Spine and have the same cost links. 
ACI overlay
Diagram: Overlay. Source Cisco

Underlay & Overlay Interaction

Example: 

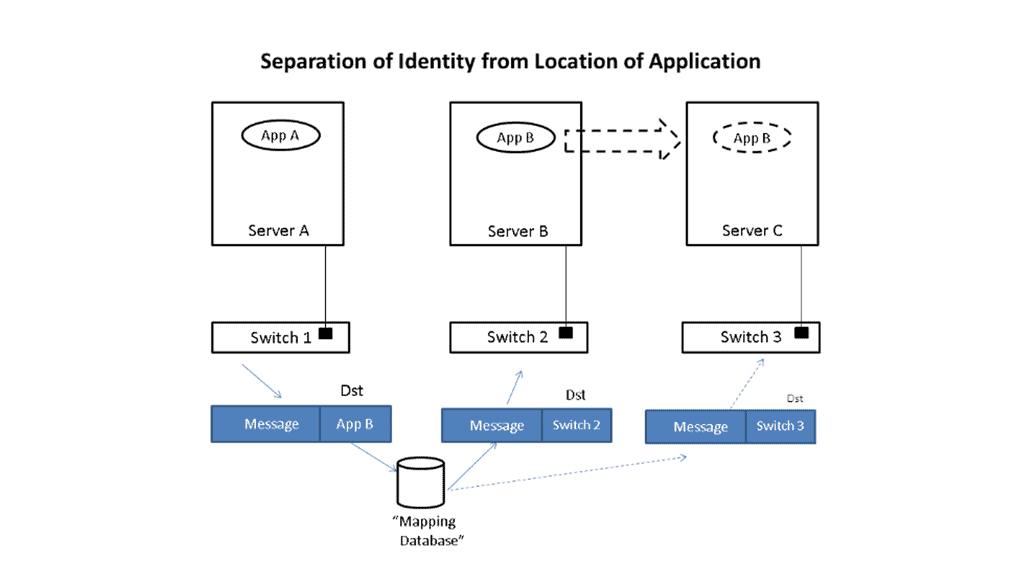
Let’s take a simple example to illustrate how this is done. Imagine that application App-A wants to send a packet to App-B. App-A is located on a server attached to switch S1, and App-B is initially on switch S2. When App-A creates the message, it will put App-B as the destination and send it to the network; when the message is received at the edge of the network, whether a virtual edge in a hypervisor or a physical edge in a switch, the network will look up the location of App-B in a “mapping” database and see that it is attached to switch S2.

It will then put the address of S2 outside of the original message. So, we now have a new message addressed to switch S2. The network will forward this new message to S2 using traditional networking mechanisms. Note that the location of S2 is very static, i.e., it does not move, so using traditional mechanisms works just fine.

Upon receiving the new message, S2 will remove the outer address and thus recover the original message. Since App-B is directly connected to S2, it can easily forward the message to App-B. App-A never had to know where App-B was located, nor did the network’s core. Only the edge of the network, specifically the mapping database, had to know the location of App-B. The rest of the network only had to see the location of switch S2, which does not change.

Let’s now assume App-B moves to a new location switch S3. Now, when App-A sends a message to App-B, it does the same thing it did before, i.e., it addresses the message to App-B and gives the packet to the network. The network then looks up the location of App-B and finds that it is now attached to switch S3. So, it puts S3’s address on the message and forwards it accordingly. At S3, the message is received, the outer address is removed, and the original message is delivered as desired.

App-A did not track App-B’s movement at all. App-B’s address identified It, while the switch’s address, S2 or S3, identified its location. App-A can communicate freely with App-B no matter where It is located, allowing the system administrator to place App-B in any area and move it as desired, thus achieving the flexibility needed in the data center.

Multicast Distribution Tree (MDT)

We have a Multicast Distribution Tree MDT tree on top that is used to forward multi-destination traffic without having loops. The Multicast distribution tree is dynamically built to send flood traffic for specific protocols. Again, it does this without creating loops in the overlay network. The tunnels created for the endpoints to communicate will have tunnel endpoints. The tunnel endpoints are known as the VTEP. The VTEP addresses are assigned to each Leaf switch from a pool that you specify in the ACI startup and discovery process.

Normalize the transports

VXLAN tunnels in the ACI fabric normalize the transports in the ACI network. Therefore, traffic between endpoints can be delivered using the VXLAN tunnel, resulting in any transport network regardless of the device connecting to the fabric. 

So, using VXLAN in the overlay enables any network, and you don’t need to configure anything special on the endpoints for this to happen. The endpoints that connect to the ACI fabric do not need special software or hardware. The endpoints send regular packets to the leaf nodes they are connected to directly or indirectly. As endpoints come online, they send traffic to reach a destination.

Bridge Domains and VRF

Therefore, the Cisco SDN ACI under the hood will automatically start to build the VXLAN overlay network for you. The VXLAN network is based on the Bridge Domain (BD), or VRF ACI constructs deployed to the leaf switches. The Bridge Domain is for Layer 2, and the VRF is for Layer 3. So, as devices come online and send traffic to each other, the overlay will grow in reachability in the Bridge Domain or the VRF. 

Direct host routing for endoints

Routing within each tenant, VRF is based on host routing for endpoints directly connected to the Cisco ACI fabric. For IPv4, the host routing is based on the /32, giving the ACI a very accurate picture of the endpoints. Therefore, we have exact routing in the ACI.  In conjunction, we have a COOP database that runs on the Spines and offers remarkably optimized fabric to know where all the endpoints are located.

To facilitate this, every node in the fabric has a TEP address, and we have different types of TEPs depending on the device’s role. The Spine and the Leaf will have TEP addresses but will differ from each other.
COOP database
Diagram: COOP database

The VTEP and PTEP

The Leaf’s nodes are the Virtual Tunnel Endpoints (VTEP), which are also known as the physical tunnel endpoints (PTEP) in ACI. These PTEP addresses represent the “WHERE” in the ACI fabric where an endpoint lives. Cisco ACI uses a dedicated VRF and a subinterface of the uplinks from the Leaf to the Spines as the infrastructure to carry VXLAN traffic. In Cisco ACI terminology, the transport infrastructure for VXLAN traffic is known as Overlay-1, which is part of the tenant “infra.” 

**The Spine TEP**

The Spines also have a PTEP and an additional proxy TEP, which are used for forwarding lookups into the mapping database. The Spines have a global view of where everything is, which is held in the COOP database synchronized across all Spine nodes. All of this is done automatically for you.

**Anycast IP Addressing**

For this to work, the Spines have an Anycast IP address known as the Proxy TEP. The Leaf can use this address if they do not know where an endpoint is, so they ask the Spine for any unknown endpoints, and then the Spine checks the COOP database. This brings many benefits to the ACI solution, especially for traffic optimizations and reducing flooded traffic in the ACI. Now, we have an optimized fabric for better performance.

The ACI optimizations

**Mouse and elephant flow**

This provides better performance for load balancing different flows. For example, in most data centers, we have latency-sensitive flows, known as mouse flows, and long-lived bandwidth-intensive flows, known as elephant flows. 

The ACI has more precisely load-balanced traffic using algorithms that optimize mouse and elephant flows and distribute traffic based on flow lets: flow let load-balancing. Within a Leaf, Spine latency is low and consistent from port to port.

The max latency of a packet from one port to another in the architecture is the same regardless of the network size. So you can scale the network without degrading performance. Scaling is often done on a POD-by-POD basis. For more extensive networks, each POD would be its Leaf and Spine network.

**ARP optimizations: Anycast gateways**

The ACI comes by default with a lot of traffic optimizations. Firstly, instead of using an ARP and broadcasting across the network, that can hamper performance. The Leaf can assume that the Spine will know where the destination is ( and it does via the COOP database ), so there is no need to broadcast to everyone to find a destination.

If the Spine knows where the endpoint is, it will forward the traffic to the other Leaf. If not, it will drop it.

**Fabric anycast addressing**

This again adds performance benefits to the ACI solution as the table sizes on the Leaf switches can be kept smaller than they would if they needed to know where all the destinations were, even if they were not or never needed to communicate with them. On the Leaf, we have an Anycast address too.

These fabric Anycast addresses are available for Layer 3 interfaces. On the Leaf ToR, we can establish an SVI that uses the same MAC address on every ToR; therefore, when an endpoint needs to route to a ToR, it doesn’t matter which ToR you use. The Anycast Address is spread across all ToR leaf switches. 

**Pervasive gateway**

Now we have predictable latency to the first hop, and you will use the local route VRF table within that ToR instead of traversing the fabric to a different ToR. This is the Pervasive Gateway feature that is used on all Leaf switches. The Cisco ACI has many advanced networking features, but the pervasive gateway is my favorite. It does take away all the configuration mess we had in the past.

ACI Cisco: Integrations

  • Routing Control Platform

Then came along Cisco SDN ACI, the ACI Cisco, which operates differently from the traditional data center with an application-centric infrastructure. The Cisco application-centric infrastructure achieves resource elasticity with automation through standard policies for data center operations and consistent policy management across multiple on-premises and cloud instances.

  • Extending & Integrating the fabric

What makes the Cisco ACI interesting is its several vital integrations. I’m not talking about extending the data center with multi-pod and multi-site, for example, with AlgoSec, Cisco AppDynamics, and SD-WAN. AlgoSec enables secure application delivery and policy across hybrid network estates, while AppDynamic lives in a world of distributed systems Observability. SD-WAN enabled path performance per application with virtual WANs.

Cisco Multi-Pod Design

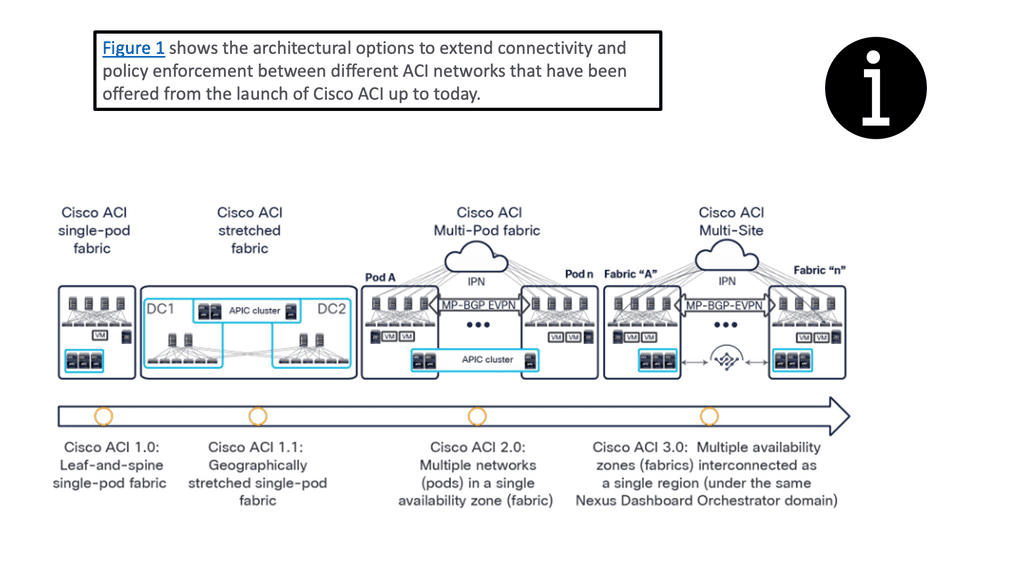
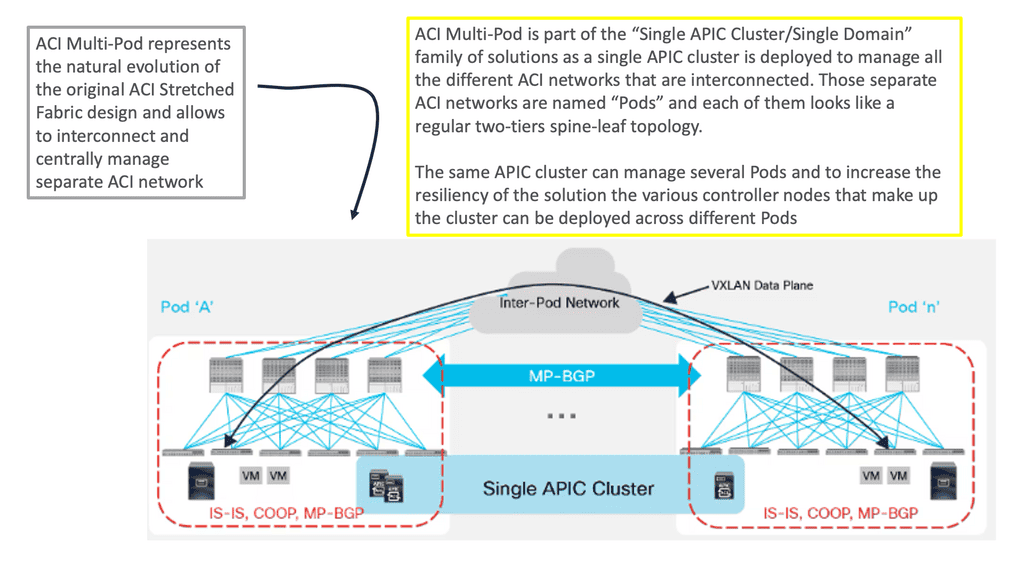
Cisco ACI Multi-Pod is part of the “Single APIC Cluster / Single Domain” family of solutions, as a single APIC cluster is deployed to manage all the interconnected ACI networks. These separate ACI networks are named “pods,” Each looks like a regular two-tier spine-leaf topology. The same APIC cluster can manage several pods, and to increase the resiliency of the solution, the various controller nodes that make up the cluster can be deployed across different pods.
ACI Multi-Pod
Diagram: Cisco ACI Multi-Pod. Source Cisco.

ACI Cisco and AlgoSec

With AlgoSec integrated with the Cisco ACI, we can now provide automated security policy change management for multi-vendor devices and risk and compliance analysis. The AlgoSec Security Management Solution for Cisco ACI extends ACI’s policy-driven automation to secure various endpoints connected to the Cisco SDN ACI fabric.

These simplify network security policy management across on-premises firewalls, SDNs, and cloud environments. They also provide visibility into ACI’s security posture, even across multi-cloud environments. 

ACI Cisco and AppDynamics 

Then, with AppDynamics, we are heading into Observability and controllability. Now, we can correlate app health and network for optimal performance, deep monitoring, and fast root-cause analysis across complex distributed systems with numbers of business transactions that need to be tracked.

This will give your teams complete visibility of your entire technology stack, from your database servers to cloud-native and hybrid environments. In addition, AppDynamics works with agents that monitor application behavior in several ways. We will examine the types of agents and how they work later in this post.

ACI Cisco and SD-WAN 

SD-WAN brings a software-defined approach to the WAN. These enable a virtual WAN architecture to leverage transport services such as MPLS, LTE, and broadband internet services. So, SD-WAN is not a new technology; its benefits are well known, including improving application performance, increasing agility, and, in some cases, reducing costs.

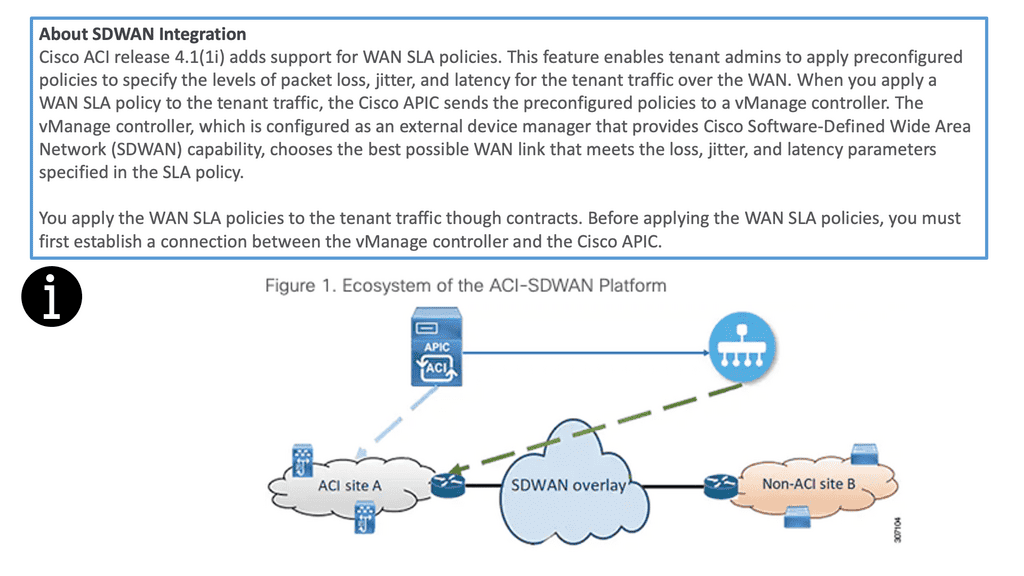
The Cisco ACI and SD-WAN integration makes active-active data center design less risky than in the past. The following figures give a high-level overview of the Cisco ACI and SD-WAN integration. For pre-information generic to SD-WAN, go here: SD-WAN Tutorial
SD WAN integration
Diagram: Cisco ACI and SD-WAN integration

The Cisco SDN ACI with SD-WAN integration helps ensure an excellent application experience by defining application Service-Level Agreement (SLA) parameters. Cisco ACI releases 4.1(1i) and adds support for WAN SLA policies. This feature enables admins to apply pre-configured policies to specify the packet loss, jitter, and latency levels for the tenant traffic over the WAN.

When you apply a WAN SLA policy to the tenant traffic, the Cisco APIC sends the pre-configured policies to a vManage controller. The vManage controller, configured as an external device manager that provides SDWAN capability, chooses the best WAN link that meets the loss, jitter, and latency parameters specified in the SLA policy.

Openshift and Cisco SDN ACI

OpenShift Container Platform (formerly known as OpenShift Enterprise) or OCP is Red Hat’s offering for the on-premises private platform as a service (PaaS). OpenShift is based on the Origin open-source project and is a Kubernetes distribution, the defacto for container-based virtualization. The foundation of the OpenShift networking SDN is based on Kubernetes and, therefore, shares some of the same networking technology along with some enhancements, such as the OpenShift route construct.

Other data center integrations

Cisco SDN ACI has another integration with Cisco DNA Center/ISE that maps user identities consistently to endpoints and apps across the network, from campus to the data center. Cisco Software-Defined Access (SD-Access) provides policy-based automation from the edge to the data center and the cloud.

Cisco SD-Access provides automated end-to-end segmentation to separate user, device, and application traffic without redesigning the network. This integration will enable customers to use standard policies across Cisco SD-Access and Cisco ACI, simplifying customer policy management using Cisco technology in different operational domains.

OpenShift and Cisco ACI

OpenShift does this with an SDN layer and enhances Kubernetes networking to create a virtual network across all the nodes. It is made with the Open Switch standard. For OpenShift SDN, this pod network is established and maintained by the OpenShift SDN, configuring an overlay network using a virtual switch called the OVS bridge. This forms an OVS network that gets programmed with several OVS rules. The OVS is a popular open-source solution for virtual switching.

OpenShift SDN plugin

We mentioned that you could tailor the virtual network topology to suit your networking requirements, which can be determined by the OpenShift SDN plugin and the SDN model you select. With the default OpenShift SDN, several modes are available. This level of SDN mode you choose is concerned with managing connectivity between applications and providing external access to them. Some modes are more fine-grained than others. The Cisco ACI plugins offer the most granular.

Integrating ACI and OpenShift platform

The Cisco ACI CNI plugin for the OpenShift Container Platform provides a single, programmable network infrastructure, enterprise-grade security, and flexible micro-segmentation possibilities. The APIC can provide all networking needs for the workloads in the cluster. Kubernetes workloads become fabric endpoints, like Virtual Machines or Bare Metal endpoints.

Cisco ACI CNI Plugin

The Cisco ACI CNI plugin extends the ACI fabric capabilities to OpenShift clusters to provide IP Address Management, networking, load balancing, and security functions for OpenShift workloads. In addition, the Cisco ACI CNI plugin connects all OpenShift Pods to the integrated VXLAN overlay provided by Cisco ACI.

Cisco SDN ACI and AppDynamics

AppDynamis overview

So, an application requires multiple steps or services to work. These services may include logging in and searching to add something to a shopping cart. These services invoke various applications, web services, third-party APIs, and databases, known as business transactions.

The user’s critical path

A business transaction is the essential user interaction with the system and is the customer’s critical path. Therefore, business transactions are the things you care about. If they start to go, your system will degrade. So, you need ways to discover your business transactions and determine if there are any deviations from baselines. This should also be automated, as learning baseline and business transitions in deep systems is nearly impossible using the manual approach.

So, how do you discover all these business transactions?

AppDynamics automatically discovers business transactions and builds an application topology map of how the traffic flows. A topology map can view usage patterns and hidden flows, acting as a perfect feature for an Observability platform.

AppDynamic topology

AppDynamics will automatically discover the topology for all of your application components. It can then build a performance baseline by capturing metrics and traffic patterns. This allows you to highlight issues when services and components are slower than usual.

AppDynamics uses agents to collect all the information it needs. The agent monitors and records the calls that are made to a service. This is from the entry point and follows executions along its path through the call stack. 

Types of Agents for Infrastructure Visibility

If the agent is installed on all critical parts, you can get information about that specific instance, which can help you build a global picture. So we have an Application Agent, Network Agent, and Machine Agent for Server visibility and Hardware/OS.

  • App Agent: This agent will monitor apps and app servers, and example metrics will be slow transitions, stalled transactions, response times, wait times, block times, and errors.  
  • Network Agent: This agent monitors the network packets, TCP connection, and TCP socket. Example metrics include performance impact Events, Packet loss, and retransmissions, RTT for data transfers, TCP window size, and connection setup/teardown.
  • Machine Agent Server Visibility: This agent monitors the number of processes, services, caching, swapping, paging, and querying. Example Metrics include hardware/software interrupts, virtual memory/swapping, process faults, and CPU/DISK/Memory utilization by the process.
  • Machine Agent: Hardware/OS – disks, volumes, partitions, memory, CPU. Example metrics: CPU busy time, MEM utilization, and pieces file.

Automatic establishment of the baseline

A baseline is essential, a critical step in your monitoring strategy. Doing this manually is hard, if not impossible, with complex applications. It is much better to have this done automatically. You must automatically establish the baseline and alert yourself about deviations from it.

This will help you pinpoint the issue faster and resolve it before it can be affected. Platforms such as AppDynamics can help you here. Any malicious activity can be seen from deviations from the security baseline and performance issues from the network baseline.
Cisco ACI • Policy & Application Flow

ACI Policy & Application Flow Lab

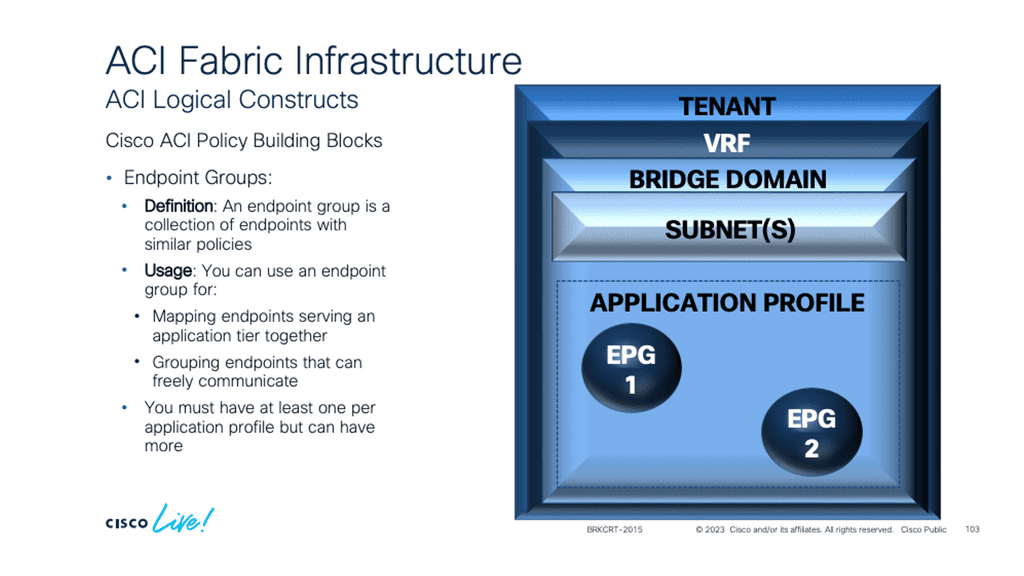
Follow how ACI turns application requirements into policy: Tenant → VRF → Bridge Domain → EPG → Contract → Application Flow.
ACI POLICY MODEL TENANT & NETWORK CONTEXT APPLICATION GROUPS POLICY APPLICATION FLOW Tenant Administrative container NETWORK CONTEXT VRF Layer 3 routing context Bridge Domain Endpoint network Web EPG Web application endpoints App EPG Application endpoints CONTRACT ALLOWED APPLICATION FLOW Web Servers Endpoint group App Servers Endpoint group
Tenant / VRF
Network
EPG
Contract
Application Flow
Selected Component
ACI Policy Model
ACI expresses application connectivity through a hierarchy of objects. Start at the Tenant and follow the model down to the application flow.
Object
Tenant → VRF → Bridge Domain → EPG
Policy
Contracts define which EPGs can communicate.
Why it matters
ACI lets administrators describe application connectivity as policy rather than configuring every individual switch interface.

Summary: Cisco ACI Components

In the ever-evolving world of networking, organizations are constantly seeking ways to enhance their infrastructure’s performance, security, and scalability. Cisco ACI (Application Centric Infrastructure) presents a cutting-edge solution to these challenges. By unifying physical and virtual environments and leveraging network automation, Cisco ACI revolutionizes how networks are built and managed.

Understanding Cisco ACI Architecture

At the core of Cisco ACI lies a robust architecture that enables seamless integration between applications and the underlying network infrastructure. The architecture comprises three key components:

1. Application Policy Infrastructure Controller (APIC):

The APIC serves as the centralized management and policy engine of Cisco ACI. It provides a single point of control for configuring and managing the entire network fabric. Through its intuitive graphical user interface (GUI), administrators can define policies, allocate resources, and monitor network performance.

2. Nexus Switches:

Cisco Nexus switches form the backbone of the ACI fabric. These high-performance switches deliver ultra-low latency and high throughput, ensuring optimal data transfer between applications and the network. Nexus switches provide the necessary connectivity and intelligence to enable the automation and programmability features of Cisco ACI.

3. Application Network Profiles:

Application Network Profiles (ANPs) are a fundamental aspect of Cisco ACI. ANPs define the policies and characteristics required for specific applications or application groups. By encapsulating network, security, and quality of service (QoS) policies within ANPs, administrators can streamline the deployment and management of applications.

The Power of Network Automation

One of the most compelling aspects of Cisco ACI is its ability to automate network provisioning, configuration, and monitoring. Through the APIC’s powerful automation capabilities, network administrators can eliminate manual tasks, reduce human errors, and accelerate the deployment of applications. With Cisco ACI, organizations can achieve greater agility and operational efficiency, enabling them to rapidly adapt to evolving business needs.

Security and Microsegmentation with Cisco ACI

Security is a paramount concern for every organization. Cisco ACI addresses this by providing robust security features and microsegmentation capabilities. With microsegmentation, administrators can create granular security policies at the application level, effectively isolating workloads and preventing lateral movement of threats. Cisco ACI also integrates with leading security solutions, enabling seamless network enforcement and threat intelligence sharing.

Conclusion

Cisco ACI is a game-changer in the realm of network automation and infrastructure management. Its innovative architecture, coupled with powerful automation capabilities, empowers organizations to build agile, secure, and scalable networks. By leveraging Cisco ACI’s components, businesses can unlock new levels of efficiency, flexibility, and performance, ultimately driving growth and success in today’s digital landscape.

Cisco ACI

Cisco ACI | ACI Infrastructure

Cisco ACI | ACI Infrastructure

Modern data centre networks are no longer designed simply around VLANs, subnets, and device-by-device configuration. Applications are distributed across physical servers, virtual machines, containers, private infrastructure, and cloud environments, creating a much more complex set of connectivity and security requirements. Cisco Application Centric Infrastructure (ACI) approaches this problem by making application requirements and policy a central part of how the data centre network is designed and operated.

Cisco ACI combines a physical network fabric with a software-defined policy and management framework. Rather than requiring administrators to configure every switch and network service independently, ACI allows connectivity, segmentation, and application relationships to be expressed through policy. The underlying fabric then provides the network connectivity required to implement that policy. This separation between application intent and individual device configuration is one of the fundamental ideas behind ACI.

The application-centric model changes the way network requirements are represented. Instead of thinking only in terms of individual ports, VLANs, and IP addresses, administrators can define applications through groups of related workloads and describe how those workloads should communicate. Policies can then specify which application components are permitted to communicate, what services they require, and which security boundaries should exist between them.

Automation is another important part of the architecture. Once application and network policies have been defined, ACI can apply those policies consistently across the fabric. This reduces repetitive configuration and helps limit configuration drift as environments grow. It also provides a more structured foundation for integration with orchestration platforms, automation systems, and operational workflows.

Security is closely connected to the policy model. ACI can provide segmentation between application groups and workloads, allowing organisations to establish more granular communication boundaries than a traditional flat network. Microsegmentation can help reduce unnecessary lateral communication, while external security services can be integrated where deeper inspection or specialised security controls are required. The objective is not simply to isolate networks, but to make permitted application communication an explicit policy decision.

ACI also provides visibility into the relationships between applications, endpoints, policies, and the underlying network fabric. This can be particularly valuable when troubleshooting complex application environments because network connectivity can be examined in the context of the policies and endpoint relationships that are driving it.

The architecture can support both physical and virtual workloads, making it useful in environments where traditional servers and newer application platforms operate alongside one another. ACI can also participate in hybrid and multi-site designs, although extending policy across different environments requires careful consideration of each site’s networking model, security requirements, and operational boundaries.

Common use cases include data centre consolidation, application segmentation, private cloud infrastructure, highly automated server environments, and organisations managing large numbers of application workloads. In these environments, the value of ACI is less about replacing individual networking technologies and more about creating a consistent operational model for connecting, securing, and automating applications across the data centre.

The most useful way to understand Cisco ACI is therefore as a policy-driven data centre networking architecture. Its combination of fabric networking, application policy, segmentation, automation, and visibility provides a framework for managing increasingly distributed application environments while reducing the dependency on manual, device-by-device network configuration.

Highlights:Cisco ACI | ACI Infrastructure

ACI Fabric Architecture Explorer
Explore how Cisco ACI combines centralized policy, a leaf-spine fabric, endpoint connectivity and distributed forwarding into one application-centric infrastructure.
MANAGEMENT / POLICY APIC Policy • Automation • Fabric Management FABRIC / SPINE Spine 1 High-Speed Fabric Transport Spine 2 High-Speed Fabric Transport ECMP FABRIC PATHS LEAF / VTEP / POLICY EDGE Leaf 1 VTEP • Policy Leaf 2 VTEP • Policy Leaf 3 VTEP • Policy ENDPOINTS Server A Endpoint Server B Endpoint Server C Endpoint DISTRIBUTED FABRIC • CENTRALIZED POLICY
ACI CONCEPT
Application-Centric Infrastructure
Cisco ACI separates the idea of policy from the physical topology. APIC defines the desired policy while the leaf-spine fabric provides distributed connectivity and forwarding.
Key Idea
The leaf is the most important point for understanding ACI from an endpoint perspective. Endpoints attach to leaves, policy is enforced at the edge, and the leaf participates in VXLAN forwarding.
APIC Leaf Spine VTEP ECMP
Click the Fabric
Click any component or connection in the diagram. The panel explains what that element contributes to the ACI architecture.
HOW TO READ THIS ARCHITECTURE
APIC provides centralized policy and automation. Spines provide the high-speed fabric. Leaves connect endpoints and enforce policy. Endpoints consume the application services. Multiple leaf-spine paths provide predictable ECMP connectivity.

The ACI Cisco Architecture

The ACI Cisco operates with several standard ACI building blocks. These include Endpoint Groups (EPGs) that classify and group similar workloads; then, we have the Bridge Domains (BD), VRFs, Contract constructs, COOP protocol in ACI, and micro-segmentation. With micro-segmentation in the ACI, you can get granular policy enforcement right on the workload anywhere in the network.

Unlike in the traditional network design, you don’t need to place certain workloads in specific VLANs or, in some cases, physical locations. The ACI can incorporate devices separate from the ACI, such as a firewall, load balancer, or an IPS/IDS, for additional security mechanisms. This enables the dynamic service insertion of Layer 4 to Layer 7 services. Here, we have a lot of flexibility with the redirect option and service graphs.

1: – The ACI Infrastructure

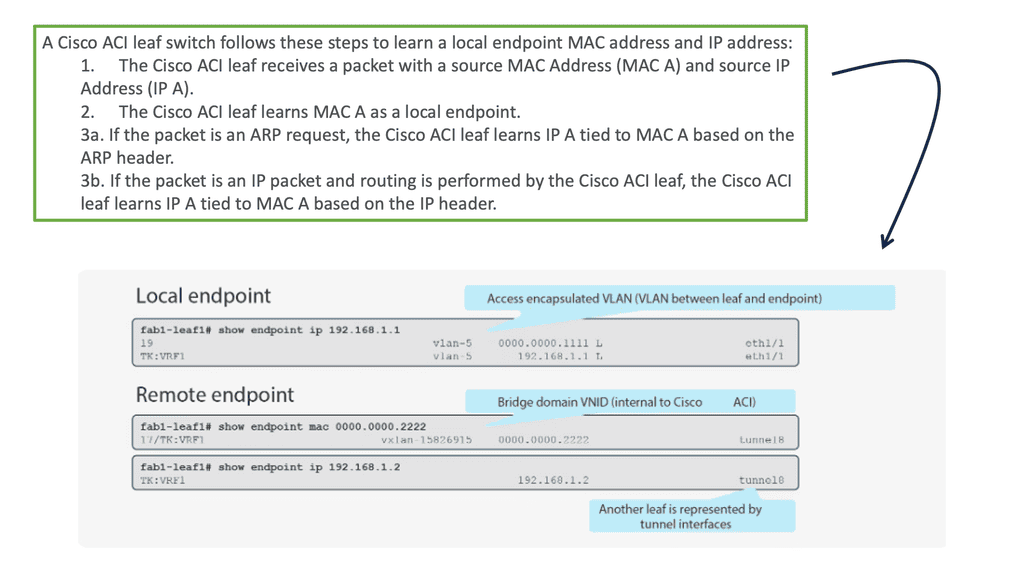
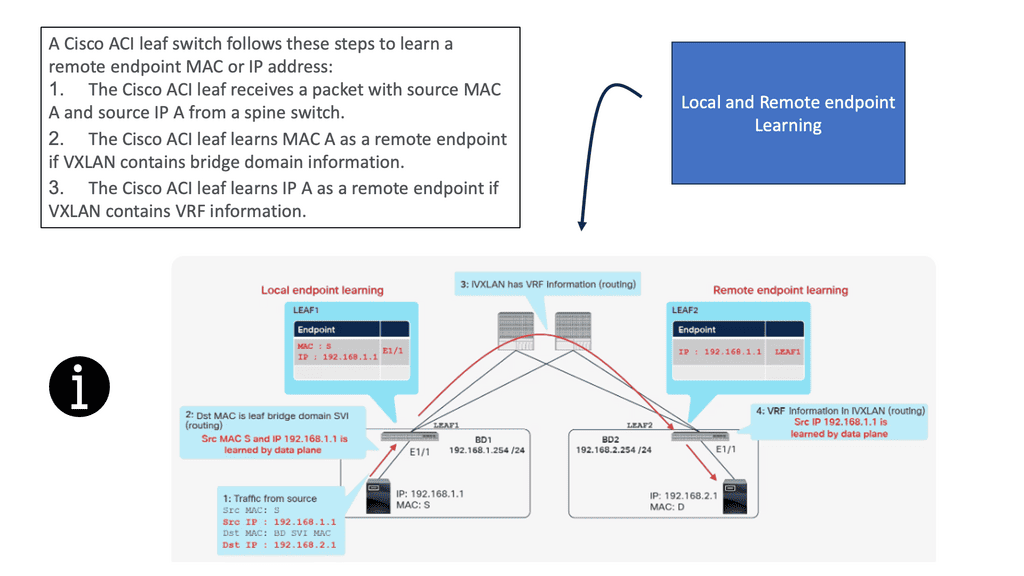
The Cisco ACI architecture is optimized to learn endpoints dynamically with its dynamic endpoint learning functionality. So, we have endpoint learning in the data plane. Therefore, the other devices learn of the endpoints connected to that local leaf switch; the spines have a mapping database that saves many resources on the spine and can optimize the data traffic forwarding. So you don’t need to flood traffic any more. If you want, you can turn off flooding in the ACI fabric. Then, we have an overlay network.

As you know, the ACI network has both an overlay and a physical underlay; this would be a virtual underlay in the case of Cisco Cloud ACI. The ACI uses VXLAN, the overlay protocol that rides on top of a simple leaf and spine topology, with standards-based protocols such as IS-IS and BGP for route propagation. 

2: – ACI Networks

ACI Networks also introduces the concept of the Application Policy Infrastructure Controller (APIC), which acts as the central point of control for the network. The APIC allows administrators to define and enforce network policies, monitor performance, and troubleshoot issues.

In addition to network virtualization and policy management, ACI Cisco offers a range of other features. These include integrated security, intelligent workload placement, and seamless integration with other Cisco products and technologies.

3: – COOP Protocol in ACI

The spine proxy receives mapping information (location and identity) via the Council of Oracle Protocol (COOP). Using Zero Message Queue (ZMQ), leaf switches forward endpoint address information to spine switches. As part of COOP, the spine nodes maintain a consistent copy of the endpoint address and location information and maintain the distributed hash table (DHT) database for mapping endpoint identity to location.

4: – Micro-segmentation

Integrated security is achieved through micro-segmentation, which allows administrators to define fine-grained security policies at the application level. This helps to prevent the lateral movement of threats within the network and provides better protection against attacks.

Intelligent workload placement ensures that applications are placed in the most appropriate locations within the network based on their specific requirements. This improves application performance and resource utilization.

Cisco ACI Infrastructure — A Policy‑Driven Data Center Fabric

Cisco ACI infrastructure is built on a spine‑leaf architecture that delivers high‑performance, scalable, and policy‑centric networking for modern data centers. Instead of configuring individual switches, ACI abstracts the entire fabric into a unified policy model controlled by the APIC (Application Policy Infrastructure Controller). This creates a programmable, intent‑based environment where application requirements dictate how the network behaves. The infrastructure is designed for automation, segmentation, and consistent forwarding across all nodes, making it ideal for cloud‑ready and microservices‑driven environments.

Spine‑Leaf Architecture — High‑Performance and Predictable Forwarding

ACI uses a spine‑leaf topology, where:

  • Leaf switches connect to endpoints (servers, firewalls, load balancers).
  • Spine switches provide high‑speed interconnects between all leaves.
  • Every leaf connects to every spine, ensuring predictable latency and deterministic paths.

This architecture eliminates oversubscription and unpredictable hop counts found in traditional three‑tier networks. VXLAN overlays provide scalable segmentation, while ACI’s distributed anycast gateway ensures consistent L3 forwarding across all leaf nodes. The result is a fabric that supports east‑west heavy workloads, microservices, and containerized applications with minimal latency.

APIC — Centralized Policy, Automation, and Fabric Control

The Application Policy Infrastructure Controller (APIC) is the brain of the ACI infrastructure. It manages:

  • policy creation and enforcement
  • fabric configuration and automation
  • endpoint learning
  • health scores and telemetry
  • integration with orchestration tools (VMware, Kubernetes, OpenStack)

APIC does not sit in the data path; instead, it provides centralized control while the fabric itself handles forwarding. This separation ensures high availability and simplifies operations. Analytics from APIC and Nexus Dashboard Insights provide deep visibility into fabric health, policy alignment, and anomalies.

Integrated Security and Microsegmentation

ACI infrastructure includes built‑in microsegmentation through Endpoint Groups (EPGs) and contracts. Instead of relying on VLANs and ACLs, segmentation is defined by application intent. The fabric enforces:

  • east‑west isolation
  • workload‑level segmentation
  • identity‑aware policies
  • contract‑based communication rules

Analytics strengthens this by detecting unusual endpoint movement, unexpected contract usage, and abnormal flows between EPGs. This transforms the ACI fabric into a Zero Trust‑aligned data‑center architecture.

VXLAN Overlays and Distributed Routing

ACI uses VXLAN overlays to provide scalable segmentation and multi‑tenant isolation. Each leaf switch acts as a distributed router, providing:

  • consistent L3 gateways
  • scalable tenant isolation
  • efficient east‑west forwarding
  • seamless VM and container mobility

Distributed routing reduces traffic hair‑pinning and improves performance for microservices and cloud‑native workloads. Analytics monitors VXLAN behavior, endpoint mobility, and routing consistency to ensure the fabric remains stable.

Hybrid Cloud Extension — ACI Anywhere

ACI infrastructure extends beyond the physical data center through ACI Anywhere, enabling policy‑driven networking across:

  • AWS
  • Azure
  • Google Cloud
  • Remote data centers
  • Colocation environments

This creates a unified segmentation and security model across hybrid and multi‑cloud architectures. Analytics ensures policy consistency across on‑prem and cloud fabrics, detecting drift, mismatches, and cross‑cloud anomalies.

Data Center Network Challenges

Let us examine well-known data center challenges and how the Cisco ACI network solves them.

Challenge: Traditional Complicated Topology

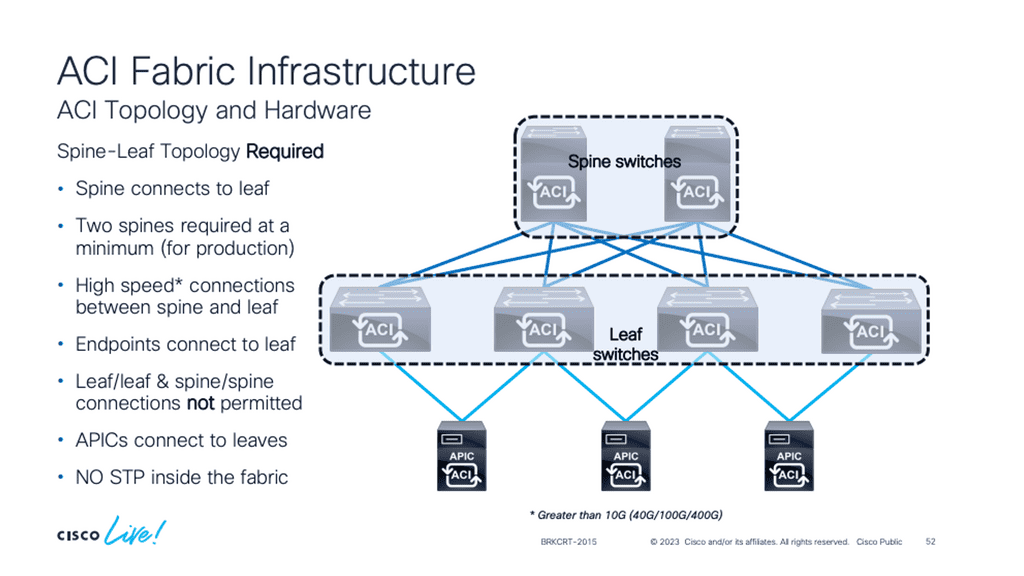
A traditional data center network design usually uses core distribution access layers. When you add more devices, this topology can be complicated to manage. Cisco ACI uses a simple spine-leaf topology, wherein all the connections within the Cisco ACI fabric are from leaf-to-spine switches, and a mesh topology is between them. There is no leaf-to-leaf and no spine-to-spine connectivity.

Required: How ACI Cisco overcomes this

The Cisco ACI architecture uses the leaf-spine, consisting of a two-tier “fat tree” topology with equidistant bandwidths. The leaf layer connects to the physical and virtual workloads and network services, while the spine layer is the transport layer that interconnects the leaves.

Challenge: Oversubscription

Oversubscription generally means potentially requiring more resources from a device, link, or component than are available. Therefore, the oversubscription ratio must be examined at multiple aggregation points in the design, including the line card to switch fabric bandwidth and the switch fabric input to uplink bandwidth.

Oversubscription Example

Let’s look at a typical 2-layer network topology with access switches and a central core switch. The access switches have 24 user ports and one uplink port connected to the core switch. Each access switch has 24 1Gb user ports and a 10Gb uplink port. So, in theory, if all the user ports are transmitted to a server simultaneously, they would require 24 GB of bandwidth (24 x 1 GB).

However, the uplink port is only 10, limiting the maximum bandwidth to all the user ports. The uplink port is oversubscribed because the theoretical required bandwidth (24Gb) exceeds the available bandwidth (10Gb). Oversubscription is expressed as a ratio of bandwidth needed to available bandwidth. In this case, it’s 24Gb/10Gb or 2.

Challenge: Varying bandwidths

We have layers of oversubscription with the traditional core, distribution, and access designs. We have oversubscribed at the access, distribution, and core layers. The cause of this will give varying bandwidth to endpoints if they want to communicate with an endpoint that is near or an endpoint that is far away. With this approach, endpoints on the same switch will have more bandwidth than two endpoints communicating across the core layer.

Users and application owners don’t care about networks; they want to place their workload wherever the computer is and want the same BW regardless of where you put it. However, with traditional designs, the bandwidth available depends on where the endpoints are located.

Required: How ACI Cisco overcomes this

The ACI leaf and spine have equidistant endpoints between any two endpoints. So if any two servers have the same bandwidths, which is a big plus for data center performance, then it doesn’t matter where you place the workload, which is a big plus for virtualized workloads. This gives you unlimited workload placement.

Challenge: Lack of portability

Applications are built on top of many building blocks. We use contracts such as VLANs, IP addresses, and ACLs to create connectivity. We use these constructs to create and translate the application requirements to the network infrastructure. These constructs are hardened into the network with configurations applied before connectivity.

These configurations are not very portable. It’s not that they were severely designed; they were never meant to be portable. Location Independent Separation Protocol (LISP) did an excellent job making them portable. However, they are hard-coded for a particular requirement at that time. Therefore, if we have the exact condition in a different data center location, we must reconfigure the IP address, VLANs, and ACLs. 

Required: How ACI Cisco overcomes this

An application refers to a set of networking components that provides connectivity for a given set of workloads. These workloads’ relationship is what ACI calls an “application,” and the connection is expressed by what ACI calls an application network profile. With a Cisco ACI design, we can create what is known as Application Network Profiles (ANPs).

The ANP expresses the relationship between the application and its communications. It is a configuration template used to express the relationship between segments. The ACI then translates those relationships into networking constructs such as VLANs, VXLAN, VRF, and IP addresses that the devices in the network can then implement.

Challenge: Issues with ACL

The traditional ACL is very tightly coupled with the network topology, and anything that is tightly coupled will kill agility. It is configured on a specific ingress and egress interface and pre-set to expect a particular traffic flow. These interfaces are usually at demarcation points in the network. However, many other points in the network could do so with security filtering.

Required: How ACI Cisco overcomes this

The fundamental security architecture of the Cisco ACI design follows an allow-list model, where we explicitly define what traffic should be permitted. A contract is a policy construct used to describe communication between EPGs. Without a contract, no unicast communication is possible between those EPGs unless the VRF is configured in “unenforced” mode or those EPGs are in a preferred group.

A contract is not required to communicate between endpoints in the same EPG (although transmission can be prevented with intra-EPG isolation or intra-EPG contract). We have a different construct for applying the policy in ACI. We use the contract construct, and within the contract construct, we have subjects and filters that specify how endpoints are allowed to communicate.

These managed objects are not tied to the network’s topology because they are not applied to a specific interface. Instead, the contracts are used in the intersection between EPGs. They represent rules the network must enforce irrespective of where these endpoints are connected.   

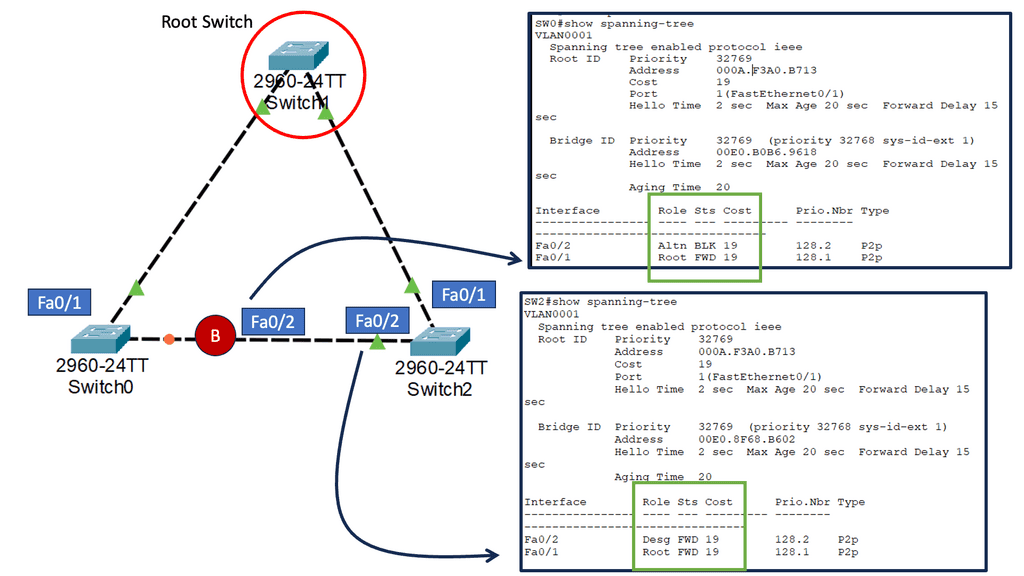
Challenge: Issues with Spanning Tree Protocol (STP)

A significant shortcoming of STP is that it is a brittle failure mode that can bring down entire data centers or campus networks when something goes wrong. Though modifications and enhancements have addressed some of these risks, this has happened at the cost of technical debt in design and maintenance.

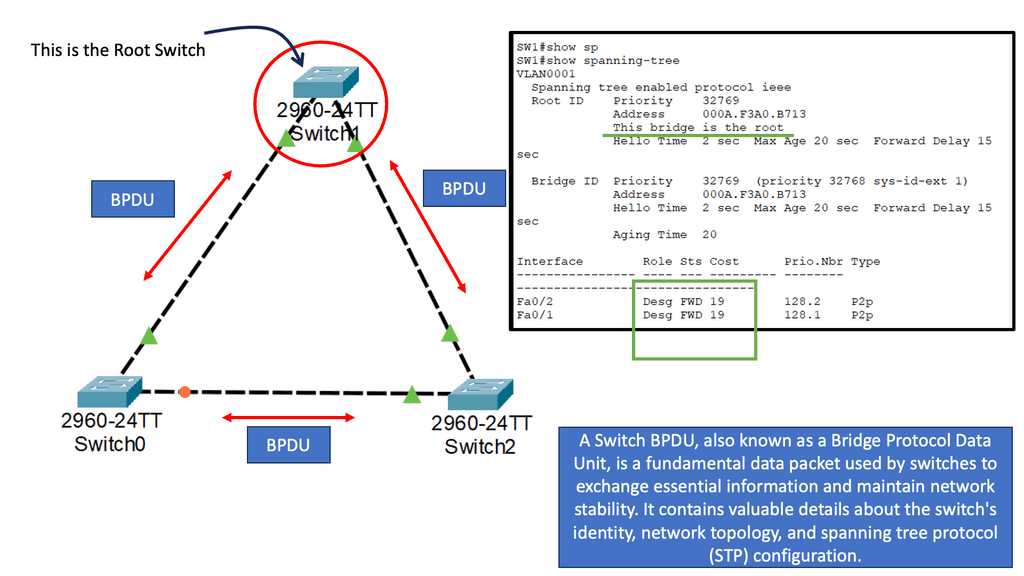
When you think about how this works, we have a BPDU that acts as a HELLO mechanism. When we stop receiving the BPDUs and the link stays up, we forward all the links. So, spanning Tree Protocol causes outages.

Spanning Tree Root Switch stp port states

Required: How ACI Cisco overcomes this

The Cisco ACI does not run Spanning Tree Protocol natively, meaning the ACI control plane does not run STP. Inside the fabric, we are running IS-IS as the interior routing protocol. If we stop receiving, we don’t go into an all-forwarding state with IS-IS. As we have IP reachability between Leaf and Spine, we don’t have to block ports and see actual traffic flows that are not the same as the physical topology.

Within the ACI fabric, we have all the advantages of layer three networks, which are more robust and predictable than with an STP design. With ACI, we don’t rely on SPT for the topology design. Instead, the ACI uses ECMP for layer 2 and Layer 3 forwarding. We can use ECMP because we have routed links between the leaves and spines in the ACI fabric.

Challenge: Core-distribution design

The traditional design uses VLANs to segment Layer 2 boundaries and broadcast domains logically. VLANs use network links inefficiently, resulting in rigid device placement. We also have a cap on the number of VLANs we can create. Some applications require that you need Layer 2 adjacencies.

For example, clustering software requires Layer 2 adjacency between source and destination servers. However, if we are routing at the access layer, only servers connected to the same access switch with the same VLANs trunked down would be Layer 2-adjacent. 

Required: How ACI Cisco overcomes this

VXLAN solves this dilemma in ACI by decoupling Layer 2 domains from the underlying Layer 3 network infrastructure. With ACI, we are using the concepts of overlays to provide this abstract. Isolated Layer 2 domains can be connected over a Layer 3 network using VXLAN. Packets are transported across the fabric using Layer 3 routing.

This paradigm fully supports layer 2 networks. Large layer-2 domains will always be needed, for example, for VM mobility, clusters that don’t or can’t use dynamic DNS and non-IP traffic, and broadcast-based intra-subnet communication.

**Cisco ACI Architecture: Leaf and Spine**

The fabric is symmetric with a leaf and spine design, and we have central bandwidth. Therefore, regardless of where a device is connected to the fabric, it has the same bandwidth as every other device connected to the same fabric. This removes the placement restrictions that we have with traditional data center designs. A spine-leaf architecture is a data center network topology that consists of two switching layers—a spine and a leaf.

The leaf layer comprises access switches that aggregate server traffic and connect directly to the spine or network core. Spine switches interconnect all leaf switches in a full-mesh topology.

With low latency east-west traffic, optimized traffic flows are imperative for performance, especially for time-sensitive or data-intensive applications. A spine-leaf architecture aids this by ensuring traffic is always the same number of hops from its next destination, so latency is lower and predictable.

Displaying a VXLAN tunnel 

We have expanded the original design and added VXLAN. We are creating a Layer 2 network, specifically, a Layer 2 overlay over a Layer 3 routed core. The Layer 2 extension allows the hosts, desktop 0 and desktop 1, to communicate over the Layer 2 overlay that VXLAN creates.

The hosts’ IP addresses are 10.0.0.1 and 10.0.0.2, which are not reachable via the Leaf switches. The Leaf switches cannot ping these. Consider the Leaf and Spine switches a standard Layer 3 WAN or network for this lab. So, we have unicast connectivity over the WAN.

The only IP routing addition I have added is the new loopback addresses on Leafs 1 and 2, of 1.1.1.1/32 and 2.2.2.2/32, used for ingress replication for VXLAN. Remember that the ACI is one of many products that use Layer 2 overlays. VXLAN can be used as a Layer 2 DCI.

Notice below I am running a ping from desktop 0 to the corresponding desktop. These hosts are in the 10.0.0.0/8 range, and the core does not know these subnets. I’m also running a packet capture on the link Gi1 connected to Leaf A.

Notice the source and destination are 1.1.1.1 and 2.2.2.2.2, which are the VTEPs. The IMCP traffic is encapsulated into UDP port 1024, explicitly set in the confirmation as the VXLAN port to use.

ACI Network: VXLAN transport network

In a leaf-spine ACI fabric, we have a native Layer 3 IP fabric that supports equal-cost multi-path (ECMP) routing between any two endpoints in the network. Using VXLAN as the overlay protocol allows any workload to exist anywhere in the network.

We can have physical and virtual machines in the same logical layer 2 domain while running layer 3 routing to the top of each rack. Thus, we can connect several endpoints to each leaf, and for one endpoint to communicate with another, we use VXLAN.

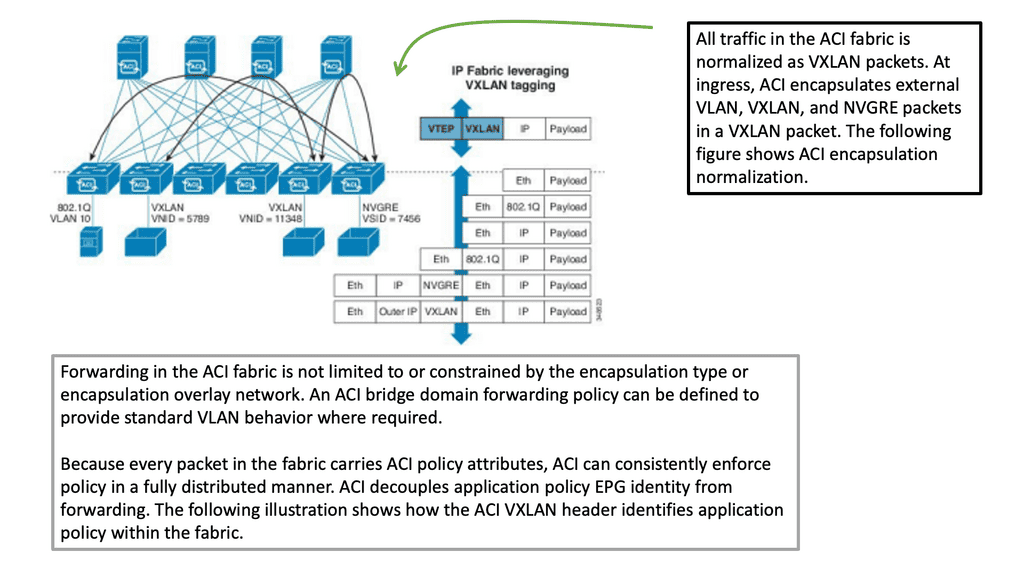
So, the transport of the ACI fabric is carried out with VXLAN. The ACI encapsulates traffic with VXLAN and forwards the data traffic across the fabric. Any policy that needs to be implemented gets applied at the leaf layer. All traffic on the fabric is encapsulated with VXLAN. This allows us to support standard bridging and routing semantics without the standard location constraints.

Diagram: VXLAN operations. The source is Cisco.

Council of Oracle Protocol

COOP protocol in ACI and the ACI fabric

The fabric appears to the outside as one switch capable of forwarding Layers 2 and 3. In addition, the fabric is a Layer 3 network routed network and enables all links to be active, providing ECMP forwarding in the fabric for both Layer 2 and Layer 3. Inside the fabric, we have routing protocols such as BGP; we also use Intermediate System-to-Intermediate System Protocol (IS-IS) and Council of Oracle Protocol (COOP) for all forwarding endpoint-to-endpoint communications.

The COOP protocol in ACI communicates the mapping information (location and identity) to the spine proxy. A leaf switch forwards endpoint address information to the spine switch ‘Oracle’ using Zero Message Queue (ZMQ). The COOP protocol in ACI is something new to data centers. The Leaf switches use COOP to report local station information to the Spine (Oracle) switches.

COOP protocol in ACI

Let’s look at an example of how the COOP protocol in ACI works. We have a Leaf that learns of a host. The Leaf reports this information—let’s say it knows Host B—and sends it to one of the Spine switches chosen randomly using the Council Of Oracle Protocol.

The Spine switch then relays this information to all the other Spines in the ACI fabric so that every Spine has a complete record of every single endpoint. The Spines switches record the information learned via the COOP in the Global Proxy Table, which resolves unknown destination MAC/IP addresses when traffic is sent to the Proxy address.

COOP database.

So, we know that the Spine has a COOP database of all endpoints in the fabric. Council of Oracle Protocol (COOP) is used to communicate the mapping information (location and identity) to the spine proxy. A leaf switch forwards endpoint address information to the spine switch ‘Oracle’ using Zero Message Queue (ZMQ).

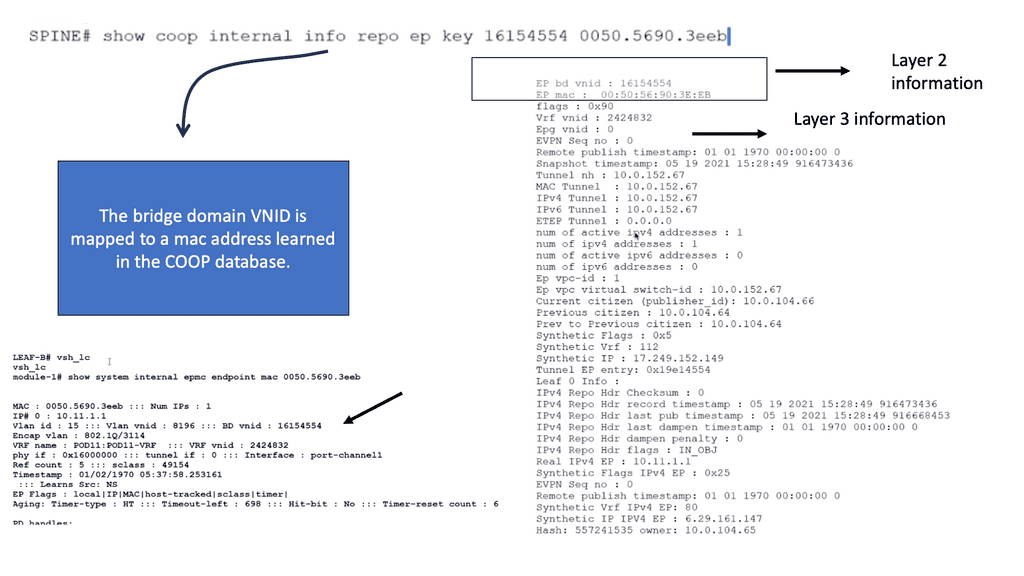
The command: Show coop internal info repo key allows us to verify that the endpoint is in the COOP database using the BD VNID of 16154554 mapped to the MAC address of 0050.5690.3eeb. With this command, you can also see the tunnel next hop and IPv4 and IPv6 addresses tied to this MAC address.

coop protocol in ACI
Diagram: COOP protocol in ACI

**The fabric constructs**

The ACI Fabric contains several new network constructs specific to ACI that enable us to abstract much of the complexity we had with traditional data center designs. These new concepts are ACI’s Endpoint Groups, Contracts, Bridge Domains, and COOP protocol.

In addition, we have a distributed Layer 3 Anycast gateway function that ensures optimal Layer 3 and Layer 2 forwarding. We also have original constructs you may have used, such as VRFs. The Layer 3 Anycast feature is popular and allows flexible placement of the default gateway, which is suited for agile designs.


Cisco ACI • Interactive Learning Widget 2

ACI Traffic Flow & VXLAN Explorer

Follow one packet from the source endpoint through the ACI fabric to the destination endpoint.
ACI PACKET JOURNEY SOURCE FABRIC TRANSPORT DESTINATION Server A Source Endpoint Traffic enters fabric Leaf 1 Source Fabric Edge VTEP 1 VXLAN Encapsulation Policy / Forwarding Edge Spine Fabric Physical Underlay ECMP Multiple Fabric Paths High-Speed Transport No Endpoint Attachment Leaf 2 Destination Fabric Edge VTEP 2 VXLAN Decapsulation Destination Processing Server B Destination Endpoint Final delivery ACCESS UNDERLAY ECMP ACCESS VXLAN OVERLAY • VTEP 1 → VTEP 2 VXLAN PACKET JOURNEY Server A → Leaf 1 → Spine Fabric → Leaf 2 VXLAN overlay runs between VTEP 1 and VTEP 2 Leaf 2 → Server B
PACKET JOURNEY
Complete Packet Journey
A packet enters through the source leaf, is carried across the physical spine fabric, and reaches the destination leaf. The VXLAN overlay provides the logical tunnel between the source and destination VTEPs.
Key Idea VXLAN is the overlay. The spine-leaf fabric is the physical transport underneath it.
Leaf VXLAN VTEP ECMP
What to Watch
  • Server A enters Leaf 1.
  • VTEP 1 starts the VXLAN overlay.
  • The spine provides physical transport.
  • VTEP 2 terminates the overlay.
  • Leaf 2 delivers traffic to Server B.

Source Leaf

Leaf 1 is the endpoint-facing edge. It receives traffic from Server A and provides the source-side VTEP function.

VXLAN / VTEP

VTEP 1 and VTEP 2 define the tunnel endpoints. VXLAN provides the logical overlay across the fabric.

Spine Fabric

The spine provides physical transport between leaves. ECMP gives the fabric multiple forwarding paths.

Cisco ACI | ACI Infrastructure

ACI Infrastructure

Key components that make up the ACI Cisco architecture. By understanding these components, network administrators and IT professionals can harness the power of ACI to optimize their data center operations.

1. Application Policy Infrastructure Controller (APIC):

The cornerstone of the Cisco ACI architecture is the Application Policy Infrastructure Controller (APIC). APIC is the central management and policy engine for the entire ACI fabric. It provides a single point of control, enabling administrators to define and enforce policies that govern the behavior of applications and services within the data center. APIC offers a user-friendly interface for policy configuration, monitoring, and troubleshooting, making it an essential component for managing the ACI fabric.

2. Spine Switches:

Spine switches form the backbone of the ACI fabric. These high-performance switches provide connectivity between leaf switches and facilitate east-west traffic within the fabric. Spine switches operate at Layer 3 and use routing protocols to efficiently distribute traffic across the fabric. With the ability to handle massive amounts of data, spine switches ensure high-speed connectivity and optimal performance in the ACI environment.

3. Leaf Switches:

Leaf switches act as the access layer switches in the ACI fabric. They connect directly to the endpoints, such as servers, storage devices, and other network devices, and serve as the entry and exit points for traffic entering and leaving the fabric. Leaf switches provide Layer 2 connectivity for endpoint devices and Layer 3 connectivity for communication between endpoints within the fabric. They also play a crucial role in implementing policy enforcement and forwarding traffic based on predefined policies.

**Example: Cisco ACI & IS-IS**

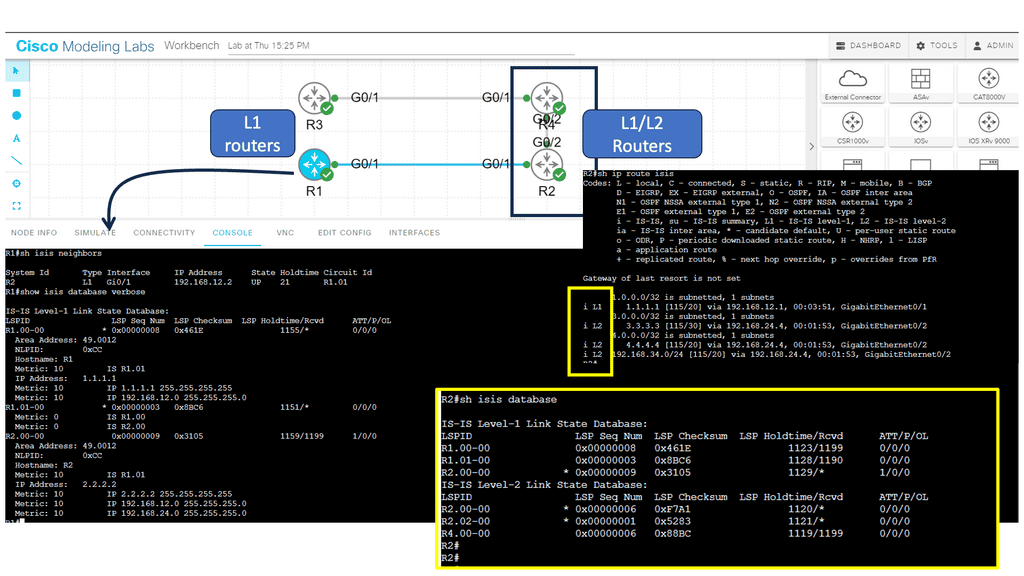
Cisco ACI under the covers runs ISIS. The ISIS routing protocol is an Interior Gateway Protocol (IGP) that enables routers within a network to exchange routing information and make informed decisions on the best path to forward packets. It operates at the OSI model’s Layer 2 (Data Link Layer) and Layer 3 (Network Layer).

ISIS organizes routers into logical groups called areas, simplifying network management and improving scalability. It allows for hierarchical routing, reducing the overhead of exchanging routing information across large networks.

**Note: IS-IS Parameters**

Below, we have four routers. R1 and R2 are in area 12, and R3 and R4 are in area 34. R1 and R3 are intra-area routers so that they will be configured as level 1 routers. R2 and R4 form the backbone so that these routers will be configured as levels 1-2.

Network administrators need to configure ISIS parameters on each participating router to implement ISIS. These parameters include the router’s ISIS system ID, area assignments, and interface settings. ISIS uses the reliable transport protocol (RTP) to exchange routing information between routers.

Routing Protocol
Diagram: Routing Protocol. ISIS.

4. Application Network Profiles (ANPs):

Application Network Profiles (ANPs) are a key Cisco ACI policy model component. They define the policies and configurations required for specific applications or application groups and encapsulate all the necessary information, including network connectivity, quality of service (QoS) requirements, security policies, and service chaining.

By associating endpoints with ANPs, administrators can easily manage and enforce consistent policies across the ACI fabric, simplifying application deployment and ensuring compliance.

5. Endpoint Groups (EPGs):

Endpoint Groups (EPGs) are logical containers that group endpoints with similar network requirements. EPGs provide a way to define and enforce policies at a granular level—endpoints within an EPG share standard policies, such as security, QoS, and network connectivity.

This grouping allows administrators to apply policies consistently to specific endpoints, regardless of their physical location within the fabric. EPGs enable seamless application mobility and simplify policy enforcement within the ACI environment.

**Specific ACI Cisco architecture**

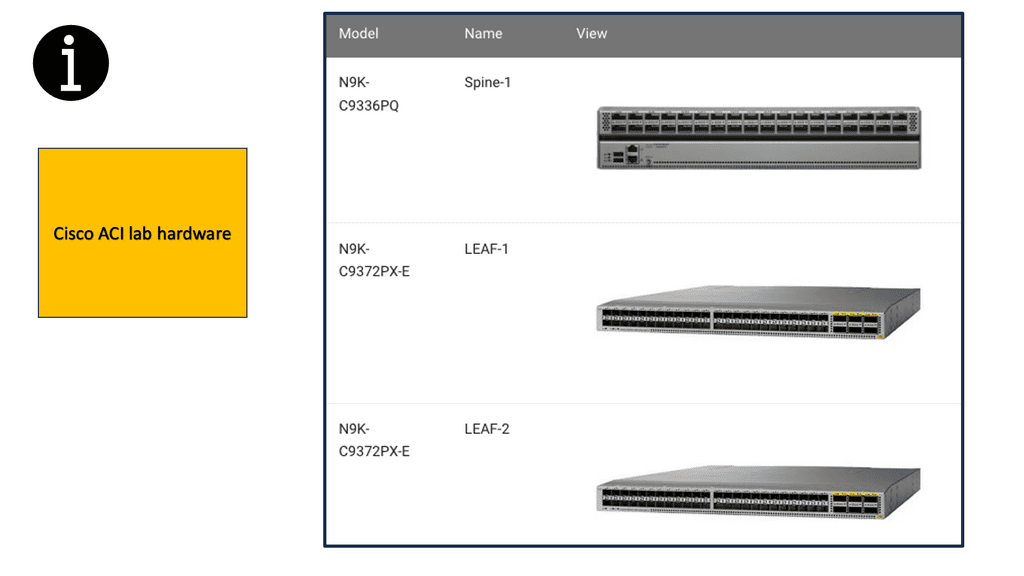
In some of the lab guides in this blog post, we are using the following hardware from a rack rental from Cloudmylabs. Remember that the ACI Fabric is built on the Nexus 9000 Product Family.

The Cisco Nexus 9000 Series Switches are designed to meet the increasing demands of modern networks. With high-performance capabilities, these switches deliver exceptional speeds and low latency, ensuring smooth and uninterrupted data flow. They support high-density 10/25/40/100 Gigabit Ethernet interfaces, allowing businesses to scale and adapt to growing network requirements.

Enhanced Security:

The Cisco Nexus 9000 Series Switches offer comprehensive security features to protect networks from evolving threats. They leverage Cisco TrustSec technology, which provides secure access control, segmentation, and policy enforcement. With integrated security features, businesses can mitigate risks and safeguard critical data, ensuring peace of mind.

Application Performance Optimization:

To meet the demands of modern applications, the Cisco Nexus 9000 Series Switches are equipped with advanced features that optimize application performance. These switches support Cisco Tetration Analytics, which provides deep insights into application behavior, enabling businesses to enhance performance, troubleshoot issues, and improve efficiency.

Diagram: The source is Cloudmylabs.

Cisco ACI Simulator:

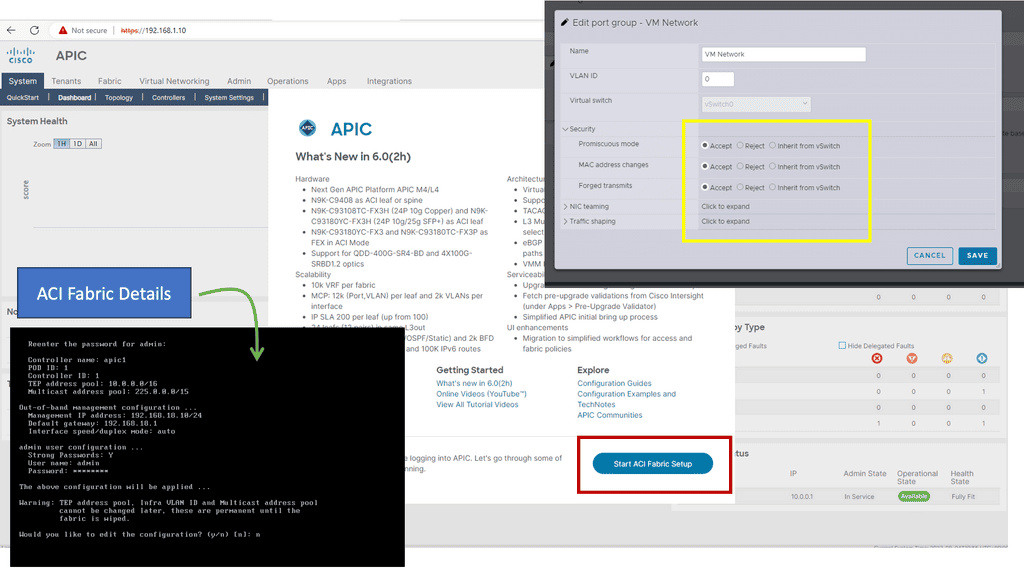
Below is a screenshot from Cisco ACI similar to the one below. At the start, you will be asked for the details of the fabric. Remember that once you set the out-of-band management address for the API, you need to change the port group settings on the ESXi VM network. If you don’t change “Promiscuous mode, MAC address changes, and Forged Transmits,” you cannot access the UI from your desktop.

ACI fabric Details
Diagram: Cisco ACI fabric Details

Leaf and spine design

Network Design Methodology

Leaf and spine architecture is a network design methodology commonly used in data centers. It provides a scalable and resilient infrastructure that can handle the increasing demands of modern applications and services. The term “leaf and spine” refers to the physical and logical structure of the network.

In leaf and spine architecture, the network is divided into two main layers: the leaf and spine layers. The leaf layer consists of leaf switches connected to the servers or endpoints in the data center. These leaf switches act as the access points for the servers, providing high-bandwidth connectivity and low-latency communication.

The spine layer, on the other hand, consists of spine switches that connect the leaf switches. The spine switches provide high-speed and non-blocking interconnectivity between the leaf switches, forming a fully connected fabric. This allows for efficient and predictable traffic patterns, as any leaf switch can communicate directly with any other leaf switch through the spine layer.

ACI Cisco with leaf and spine.

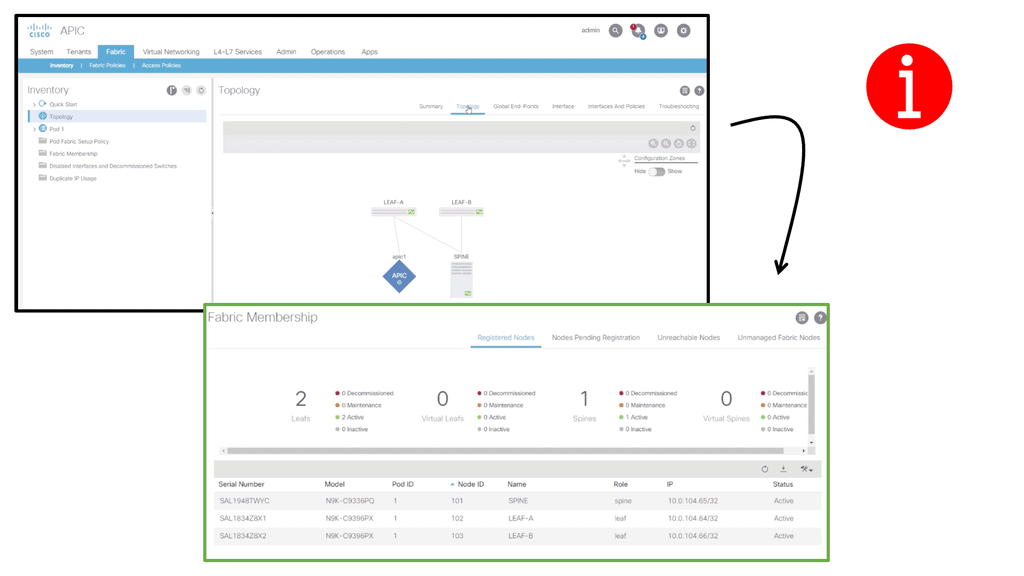
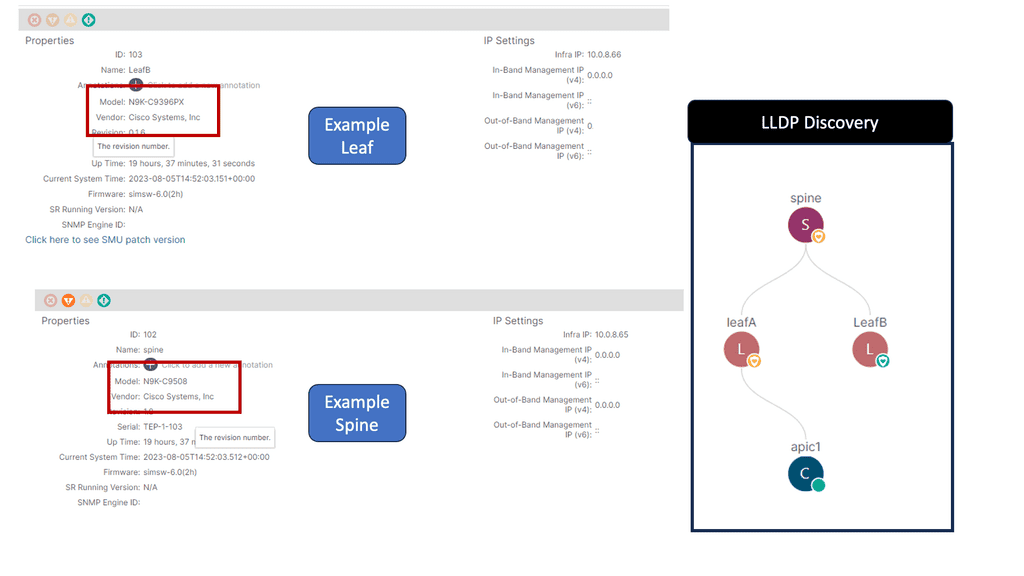
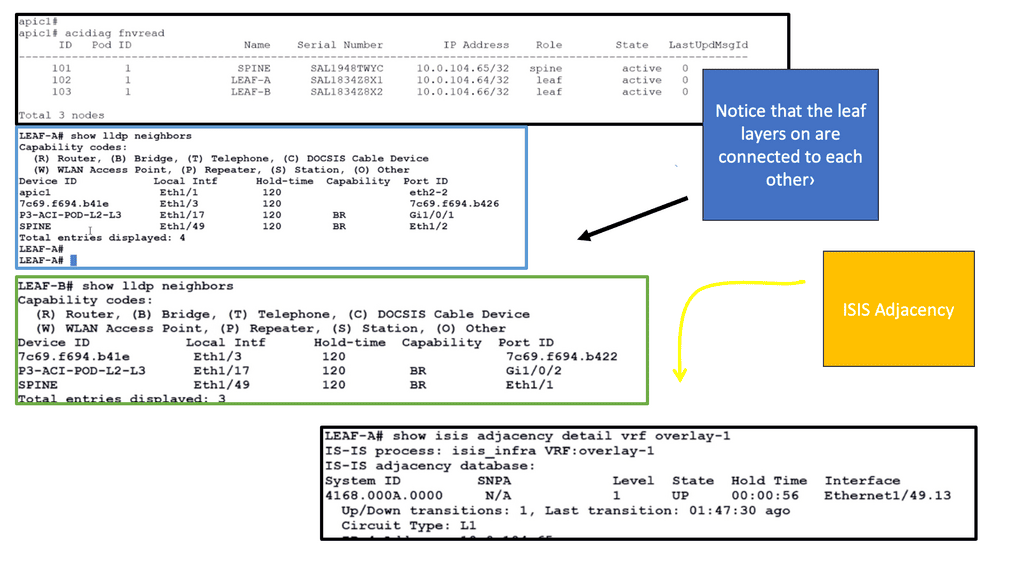
The following lab guide has a leaf and spine ACI design that includes 2 leaf switches acting as the leaf layer where the workloads connect. Then, we have a spine attached to the leaf. When the ACI hardware installation is done, all Spines and Leafs are linked and powered up. Once the basic configuration of APIC is completed, the Fabric discovery process starts working.

Note: IFM process

In the discovery process, ACI uses the Intra-Fabric Messaging (IFM) process in which APIC and nodes exchange heartbeat messages.

The process used by the APIC to push policy to the fabric leaf nodes is called the IFM Process. ACI Fabric discovery is completed in three stages. The leaf node directly connected to the APIC is discovered in the first stage. The second discovery stage brings in the spines connected to that initial leaf where APIC was connected. The third stage involves discovering the cluster’s other leaf nodes and APICs.

The fabric membership diagram below shows the inventory, including serial number, Pod, Node ID, Model, Role, Fabric IP, and Status. Cisco ACI consists of the following hardware components: APIC Controller Spine Switches and Leaf Switches.

ACI fabric discovery
Diagram: ACI fabric discovery

Analysis: Overlay based on VXLAN

Cisco ACI uses an overlay based on VXLAN to virtualize physical infrastructure. Like most overlays, this overlay requires the data path at the network’s edge to map from the tenant end-point address in the packet, otherwise referred to as its identifier, to the endpoint’s location, also known as its locator. This mapping occurs in a tunnel endpoint (TEP) function called VXLAN (VTEP).

VTEP Addressing

The VTEP addresses are displayed in the INFRASTRUCTURE IP column. The TEP address pool 10.0.0.0/16 has been configured on the Cisco APIC using the initial setup dialog. The APIC assigns the TEP addresses to the fabric switches via DHCP, so the infrastructure IP addresses in your fabric will differ from the figure.

This configuration is perfectly valid for a Lab but not good for a production environment. The minimum physical fabric hardware for a production environment includes two spines, two leaves, and three APICs.In addition to discovering and configuring the Fabric and applying the Tenant design, the following functionality can be configured:

  1. Routing at Layer 3
  2. Connecting a legacy network at layer 2
  3. Virtual Port Channels at Layer 2

Note: Border Leaf

A note about Border Leafs: ACI fabrics often use this designation along with “Compute Leafs” and “Storage Leafs.” Border Leaf is merely a convention for identifying the leaf pair that hosts all external connectivity external to the fabric (Border Leaf) or the leaf pair that hosts host connectivity (Compute Leaf).

Note: The Link Layer Discovery Protocol (LLDP)

LLDP is responsible for discovering directly adjacent neighbors. When run between the Cisco APIC and a leaf switch, it precedes three other processes: Tunnel endpoint (TEP) IP address assignment, node software upgrade (if necessary), and the intra-fabric messaging (IFM) process, which the Cisco APIC uses to push policy to the leaves.

aci Cisco LLDP

Leaf and Spine: Traffic flows

The leaf and spine network topology is suitable for east-to-west network traffic and comprises leaf switches to which the workloads connect and spine switches to which the leaf switches connect. The spines have a simple role and are geared around performance, while all the intelligence is distributed to the edge of the network, where the leaf layers sit.

This allows engineers to move away from managing individual devices and more efficiently manage the data center architecture with policy. In this model, the Application Policy Infrastructure Controller (APIC) controllers can correlate information from the entire fabric.

**Understanding Leaf and Spine Traffic Flow**

In a leaf and spine architecture, traffic flow follows a structured path. When a device connected to a leaf switch wants to communicate with another device, the traffic is routed through the spine switch to the destination leaf switch. This approach minimizes the hops required for data transmission and reduces latency. Additionally, traffic can be evenly distributed since every leaf switch is connected to every spine switch, preventing congestion and bottlenecks.

**ACI Cisco with leaf and spine**

In the following lab guide, we continue to verify the ACI leaf and spine. To check the ACI fabric, we can run the diagnostic tool Acidiag fnvread. It is also recommended that the LLDP and ISIS adjacencies be checked. With a leaf and spine design, the leaf layer does not connect, and we can see this with the LLDP and ISIS adjacency information below.

ACI leaf and spine
Diagram: ACI leaf and spine

Leaf and Spine Switch Functions

Based on a two-tier (spine and leaf switches) or three-tier (spine switch, tier-1 leaf switch, and tier-2 leaf switch) architecture, Cisco ACI switches provide the following functions:

What are Leaf Switches?

Leaf switches connect between end devices, servers, and the network fabric. They are typically deployed in leaf-spine network architecture, connecting directly to the spine switches. Leaf switches provide high-speed, low-latency connectivity to end devices within a data center network.

Functionalities of Leaf Switches:

1. Aggregation: Leaf switches aggregate traffic from multiple servers and sends it to the spine switches for further distribution. This aggregation helps reduce the network’s complexity and enables efficient traffic flow.

2. High-density Port Connectivity: Leaf switches are designed to provide a high-density port connectivity environment, allowing multiple devices to connect simultaneously. This is crucial in data centers where numerous servers and devices must be interconnected.

These devices have ports connected to classic Ethernet devices, such as servers, firewalls, and routers. In addition, these leaf switches provide the VXLAN Tunnel Endpoint (VTEP) function at the edge of the fabric. In Cisco ACI terminology, IP addresses representing leaf switch VTEPs are called Physical Tunnel Endpoints (PTEPs). The leaf switches route or bridge tenant packets and applies network policies.

What are Spine Switches?

Spine switches, also known as spine or core switches, are high-performance switches that form the backbone of a network. They play a vital role in data centers and large enterprise networks and facilitate the seamless data flow between various leaf switches.

These devices interconnect leaf switches and can also connect Cisco ACI pods to IP networks or WAN devices to build a Cisco ACI Multi-Pod fabric. In addition to mapping entries between endpoints and VTEPs, spine switches also store proxy entries between endpoints and VTEPs. Leaf switches are connected to spine switches within a pod, and spine switches are connected to leaf switches.

No direct connection between tier-1 leaf switches, tier-2 leaf switches, or spine switches is allowed. If you incorrectly cable spine switches to each other or leaf switches in the same tier to each other, the interfaces will be disabled.

Cisco ACI Fabric
Diagram: Cisco ACI Fabric. Source Cisco Live.

BGP Route Reflection

Under the cover, Cisco ACI works with BGP Route-Reflection. BGP Route Reflection creates a hierarchy of routers within the ACI fabric. At the top of the hierarchy is a Route-Reflector (RR), a central point for collecting routing information from other routers within the fabric. The RR then reflects this information to other routers, ensuring that every router in the network has a complete view of the routing table.

The ACI uses MP-BGP protocol to distribute external Network subnets or prefixes inside the ACI fabric. To create an MP-BGP route reflector, we must select two Spines acting as Route Reflectors and make an iBGP Neighbourship to all other leaves.

ACI Cisco and endpoints

In a traditional network, three tables are used to maintain the network addresses of external devices: a MAC address table for Layer 2 forwarding, a Routing Information Base (RIB) for Layer 3 forwarding, and an ARP table for the combination of IP addresses and MAC addresses. Cisco ACI, however, maintains this information differently, as shown below.

ACI Endpoint learning
Diagram: Endpoint Learning. Source Cisco.com

What is ACI Endpoint Learning?

ACI endpoint learning refers to discovering and monitoring the network endpoints within an ACI fabric. Endpoints include devices, virtual machines, physical servers, users, and applications. Network administrators can make informed decisions regarding network policies, security, and traffic optimization by gaining insights into these endpoints’ location, characteristics, and behavior.

How Does ACI Endpoint Learning Work?

ACI fabric leverages a distributed, controller-based architecture to facilitate endpoint learning. When an endpoint is connected to the fabric, ACI utilizes various mechanisms to gather information about it. These mechanisms include Address Resolution Protocol (ARP) snooping, Link Layer Discovery Protocol (LLDP), and even integration with hypervisor-based systems.

Once an endpoint is detected, ACI Fabric builds a comprehensive endpoint database called the Endpoint Group (EPG). This database contains vital information such as MAC addresses, IP addresses, VLANs, and associated policies. By continuously monitoring and updating this database, ACI ensures real-time visibility and control over the network endpoints.

Implementation Endpoint Learning Considerations:

To leverage the benefits of ACI endpoint learning, organizations need to consider a few key aspects:

1. Infrastructure Design: A well-designed ACI fabric with appropriate leaf and spine switches is crucial for efficient endpoint learning. Proper VLAN and subnet design should be implemented to ensure accurate endpoint identification and classification.

2. Endpoint Group (EPG) Definition: Defining and associating EPGs with appropriate policies is essential. EPGs help categorize endpoints based on their characteristics, allowing for granular policy enforcement and simplified management.

Diagram: ACI Endpoint Learning. The source is Cisco.

Forwarding Behavior. The COOP database

Local and remote endpoints are learned from the data plane, but remote endpoints are local caches. Cisco ACI’s fabric relies heavily on local endpoints for endpoint information. A leaf is responsible for reporting its local endpoints to the Council Of Oracle Protocol (COOP) database located on each spine switch, which implies that all endpoint information in the Cisco ACI fabric is stored there.

Each leaf does not need to know about all the remote endpoints to forward packets to the remote endpoints because this database is accessible. When a leaf does not know about a remote endpoint, it can still forward packets to spine switches. This forwarding behavior is called spine proxy.

Diagram: Endpoint Learning. The source is Cisco.

In a traditional network environment, switches rely on the Address Resolution Protocol (ARP) to map IP addresses to MAC addresses. However, this approach becomes inefficient as the network scales, resulting in increased network traffic and complexity. Cisco ACI addresses this challenge by utilizing local endpoint learning, a more intelligent and efficient method of mapping MAC addresses to IP addresses.

Diagram: Local and Remote endpoint learning. The source is Cisco.

ACI Cisco: The Main Features

We are experiencing many changes right now that are impacting almost every aspect of IT. Applications are changing immensely, and we see their life cycles broken into smaller windows as they become less structured. In addition, containers and microservices are putting new requirements on the underlying infrastructure, such as the data centers they live in. This is one of the main reasons why a distributed system, including a data center, is better suited for this environment.

Distributed system/Intelligence at the edge

Like all networks, the Cisco ACI network still has a control and data plane. From the control and data plane perspective, the Cisco ACI architecture is still a distributed system. Each switch has intelligence and knows what it needs to do—one of the differences between ACI and traditional SDN approaches that try to centralize the control plane. If you try to centralize the control plan, you may hit scalability limits, not to mention a single point of failure and an avenue for bad actors to penetrate.

Cisco ACI Design
Diagram: Cisco ACI Design. Source Cisco Live.

Two large core devices

If we examine the traditional data center architecture, intelligence is often in two central devices. You could have two large core devices. What the network used to control and secure has changed dramatically with virtualization via hypervisors. We’re seeing faster change with containers and microservices being deployed more readily.

As a result, an overlay networking model is better suited. However, in a VXLAN overlay network, the intelligence is distributed across the leaf switch layer.

Therefore, distributed systems are better than centralized systems for more scale, resilience, and security. By distributing intelligence to the leaf layer, scalability is not determined by the scalability of each leaf but by the fabric level. However, there are scale limits on each device. Therefore, scalability as a whole is determined by the network design.

A key point: Overlay networking

The Cisco ACI architecture provides an integrated Layer 2 and 3 VXLAN-based overlay networking capability to offload network encapsulation processing from the compute nodes onto the top-of-rack or ACI leaf switches. This architecture provides the flexibility of software overlay networking in conjunction with the performance and operational benefits of hardware-based networking. 

ACI Cisco New Concepts

Networking in the Cisco ACI architecture differs from what you may use in traditional network designs. It’s not different because we use an entirely new set of protocols. ACI uses standards-based protocols such as BGP, VXLAN, and IS-IS. However, the new networking constructs inside the ACI fabric exist only to support policy.

ACI has been referred to as stateless architecture. As a result, the network devices have no application-specific configuration until a policy is defined stating how that application or traffic should be treated on the network.

This is a new and essential concept to grasp. So, now, with the ACI, the network devices in the fabric have no application-specific configuration until there is a defined policy. No configuration is tied to a device. With a traditional configuration model, we have many designs on a device, even if it’s not being used. For example, we had ACL and QoS parameters configured, but nothing was using them.

The APIC controller

The APICs, the management plan that defined the policy, do not need to push resources when nothing connected utilizes that. The APIC controller can see the entire fabric and has a holistic viewpoint.

Therefore, it can correlate configurations and integrate them with devices to help manage and maintain the security policy you define. We see every device on the fabric, physical or virtual, and can maintain policy consistency and, more importantly, recognize when policy needs to be enforced. 

APIC Controller
Diagram: APIC Controller. Source Cisco Live.

Endpoint groups (EPG)

We touched on this a moment ago. Groups or endpoint groups (EPGs) and contracts are core to the ACI. Because this is a zero-trust network by default, communication is blocked in hardware until a policy consisting of groups and contracts is defined. With Endpoint Groups, we can decouple and separate the physical or virtual workloads from the constraints of IP addresses and VLANs. 

So, we are grouping similar workloads into groups known as Endpoint Groups. Then, we can control group behavior by applying policy to the groups and not the endpoints in the group. As a security best practice, it is essential to group similar workloads with similar security sensitivity levels and then apply the policy to the endpoint group.

For example, a traditional data center network could have database and application servers in the same segment controlled by a VLAN with no intra-VLAN filtering. The EPG approach removes the barriers we have had with traditional networks, with the limitation of the IP address being used as the identifier and locator and the restrictions of the VLANs.

This is a new way of thinking, and it allows devices to communicate with each other without changing their IP address, VLAN, or subnet.

ACI Endpoint Groups
Diagram: ACI Endpoint Groups. Source Cisco Live.

EPG Communication

The EPG provides a better segmentation method than the VLAN, which was never meant to live in a world of security. By default, anything in the group can communicate freely, and inter-EPG communication needs a policy. This policy construct that ACI uses is called a contract. So, having similar workloads of similar security levels in the same EPG makes sense. All devices inside the same endpoint group can talk to each other freely.

This behavior can be modified with intra-EPG isolation, similar to a private VLAN where communication between group members is not allowed. Or, intra-EPG contracts can be used only to allow specific communications between devices in an EPG.

Extending the ACI Fabric

Developing the Cisco ACI architecture

I have always found extending data risky when undergoing data center network design projects. However, the Cisco ACI architecture can be extended without the traditional Layer 2 and 3 Data Center Interconnect (DCI) mechanisms. Here, we can use Multi-Pod and Multi-Site to better control large environments that need to span multiple locations and for applications to share those multiple locations in active-active application deployments.

Diagram: Extending the ACI fabric. Source is Cisco

When considering data center designs, terms such as active-active and active-passive are often discussed. In addition, enterprises are generally looking for data center solutions that provide geographical redundancy for their applications.

Enterprises also need to be able to place workloads in any data center where computing capacity exists—and they often need to distribute members of the same cluster across multiple data center locations to provide continuous availability in the event of a data center failure. The ACI gives us options for extending the fabric to multiple locations and location types.

For example, there are stretched fabric, multi-pod, multi-site designs, and, more recently, Cisco Cloud ACI.

ACI design: Multi pod

The ACI Multi-Pod is the next evolution of the original stretch fabric design we discussed. The architecture consists of multiple ACI Pods connected by an IP Inter-Pod Layer 3 network. With the stretched fabric, we have one Pod across several locations. Cisco ACI MultiPod is part of the “single APIC cluster/single domain” family of solutions; a single APIC cluster is deployed to manage all the interconnected ACI networks.

These ACI networks are called “pods,” Each looks like a regular two-tier spine-leaf topology. The same APIC cluster can manage several pods.  All of the nodes deployed across the individual pods are under the control of the same APIC cluster. The separate pods are managed as if they were logically a single entity. This gives you operational simplicity. We also have a fault-tolerant fabric since each Pod has isolated control plane protocols.

Diagram: Multi-pod. Source is Cisco

ACI design: Cisco cloud ACI

Cisco Cloud APIC is an essential new solution component introduced in the architecture of Cisco Cloud ACI. It plays the equivalent of APIC for a cloud site. Like the APIC for on-premises Cisco ACI sites, Cloud APIC manages network policies for the cloud site it runs on by using the Cisco ACI network policy model to describe the policy intent.

ACI design: Multisite

ACI Multi-Site enables you to interconnect separate APIC cluster domains or fabric, each representing a separate availability zone. As a result, we have separate and independent APIC domains and fabrics. This way, we can manage multiple fabrics as regions or availability zones. ACI Multi-Site is the easiest DCI solution in the industry. Communication between endpoints in separate sites (Layers 2 and 3) is enabled simply by creating and pushing a contract between the endpoints’ EPGs.

Cisco ACI • Widget 3

Endpoint Learning & COOP Explorer

Follow how an ACI leaf learns an endpoint locally, how the endpoint is distributed through COOP, and how another leaf can resolve the remote endpoint through the spine.
ENDPOINT Server A 10.10.10.10 MAC AA:AA:AA LEAF EDGE Leaf 1 Local endpoint learning Local Endpoint MAC → EPG / interface COOP Endpoint DB Control-plane endpoint knowledge 10.10.10.10 → Leaf 1 SPINE Spine Proxy COOP lookup remote endpoint resolution REMOTE LEAF Leaf 2 Destination-side edge knows endpoint location and forwarding context REMOTE ENDPOINT Server B 10.20.20.20 MAC BB:BB:BB 1 • LEARN Leaf records local endpoint 2 • REGISTER Endpoint information enters COOP 3 • DISTRIBUTE Fabric shares endpoint knowledge 4 • RESOLVE Remote leaf can resolve destination WHY COOP MATTERS ACI does not require every leaf to independently flood the entire endpoint database. COOP provides a fabric-wide control-plane view used for endpoint resolution.
ACI CONCEPT

Endpoint Learning

An ACI leaf learns endpoints at the edge of the fabric. The leaf can associate an endpoint with information such as its MAC/IP, interface, EPG and local forwarding context.

Key Idea Endpoint learning happens close to the endpoint, while COOP helps distribute endpoint knowledge across the fabric.
Endpoint Learning COOP Spine Proxy Remote Leaf Forwarding
Local Leaf = First Knowledge The leaf directly attached to an endpoint learns where that endpoint exists and builds the local forwarding context.
COOP = Fabric Endpoint Knowledge COOP provides the control-plane mechanism used to maintain and resolve endpoint information across the ACI fabric.
Spine = Proxy for Resolution When a leaf needs information about an endpoint elsewhere in the fabric, the spine can provide the control-plane lookup function.
WAN Design Requirements

Spine Leaf Architecture

Network Architecture · Data Center Fabrics

Spine–Leaf Architecture: Designing Scalable Data Center Fabrics

Modern data centers must move increasing volumes of traffic between distributed applications, virtual machines, containers and storage systems. Traditional hierarchical networks can struggle to deliver the bandwidth, predictable latency and flexibility these workloads demand. Spine–leaf architecture addresses these challenges through a scalable, multi-path network fabric.

Also known as a folded-Clos architecture, a conventional two-tier spine–leaf fabric consists of leaf switches that connect servers and other endpoints, and spine switches that interconnect the leaf layer. Each leaf connects to every spine, creating multiple equal-cost paths between endpoints attached to different leaves. Routing protocols and Equal-Cost Multipath (ECMP) forwarding allow eligible traffic flows to use these alternative paths.

This design is particularly suited to east–west traffic: communication between application servers, distributed services, virtualised workloads and storage systems inside the data center. Rather than forcing traffic through multiple hierarchical aggregation layers, the fabric provides a consistent path structure that can improve capacity planning, simplify expansion and make network behaviour easier to reason about.

The engineering principles behind the fabric
Predictable paths Inter-leaf traffic normally traverses one spine, providing a consistent hop count across the fabric.
Multipath forwarding ECMP distributes eligible flows across available equal-cost routes instead of relying on a single uplink.
Scale-out capacity Add leaf switches for endpoint capacity or additional spines when the design and port budgets permit.
Failure resilience Redundant paths can preserve connectivity after failures, subject to topology, routing and remaining capacity.

However, a spine–leaf diagram alone does not guarantee a non-blocking network. Switch forwarding capacity, link speeds, oversubscription, ECMP hashing, routing convergence and application traffic patterns all influence actual performance. Resilient designs must account for both normal operating conditions and the capacity remaining after a component fails.

What this guide explores

Move from topology fundamentals to real engineering decisions: compare traditional and spine–leaf designs, calculate oversubscription, trace ECMP paths, investigate failures, examine routed underlays and VXLAN/EVPN overlays, and understand how telemetry helps engineers diagnose and optimise a data center fabric.

Interactive Reading Guide
7 SECTIONS · ONE FABRIC

Explore the Spine–Leaf Architecture Guide

Move from the fundamentals of fabric design to capacity planning, resilience, overlays and real-world operations. Select any section to jump directly to its explanation.

FUNDAMENTALS → IMPLEMENTATION
Section 01 · Architecture Fundamentals

Traditional Three-Tier vs. Spine–Leaf Architecture

Data center architecture determines how traffic moves between servers, how bandwidth is distributed, and how the network responds as workloads grow. Understanding the difference between traditional hierarchical designs and spine–leaf fabrics is the starting point for making informed capacity, resilience and routing decisions.

The traditional three-tier model

Traditional data centers commonly use three logical network layers: access, aggregation and core. Access switches connect servers and endpoints. Aggregation switches collect access-layer traffic and may provide Layer 3 routing, policy enforcement and connectivity between network segments. Core switches provide high-speed transport between aggregation blocks and other network domains.

This hierarchy can work well for traffic patterns that move predominantly between access networks and external destinations. However, the aggregation and core layers can become capacity constraints when large numbers of distributed applications exchange traffic internally. Scaling may require additional uplinks, larger chassis or redesigns of existing aggregation blocks.

Traditional design

Three-tier hierarchy

Core
↓ ↑
Aggregation / Distribution
↓ ↑
Access switches
↓ ↑
Servers and endpoints

Multiple hierarchical layers can introduce additional hops and concentrate traffic on aggregation uplinks.

Modern fabric

Two-tier spine–leaf

Spine switches
↕ Multiple routed paths
Leaf switches
↕
Servers and endpoints

Each leaf connects to every spine, providing equal-cost paths between different leaves in a conventional full fabric.

Why the design approach changed

Virtualisation, cloud platforms, distributed databases and containerised applications have increased the importance of east–west traffic—communication between workloads inside the data center. An application request may trigger multiple exchanges between services, storage systems and compute nodes before a response is returned.

Spine–leaf architecture addresses this pattern through a regular, repeatable topology. Endpoints connect to leaf switches, and each leaf connects to every spine. Traffic between endpoints attached to different leaves normally travels from the source leaf to a spine and then to the destination leaf. In a conventional two-tier fabric, this provides a predictable inter-leaf hop count.

Multiple routed paths allow Equal-Cost Multipath (ECMP) to forward eligible flows across available links. This can improve aggregate bandwidth utilisation and provide alternative paths when links or spine devices fail. The actual result depends on link capacity, routing convergence, traffic distribution and the fabric's remaining resources.

Key architectural differences

Design consideration Traditional three-tier Spine–leaf fabric
Topology Hierarchical access, aggregation and core Leaf and spine switching tiers
Inter-leaf path May traverse aggregation and core layers Normally one spine between different leaves
Multipath forwarding Depends on the design and supported protocols Commonly uses ECMP over routed links
Scaling May require uplink or hierarchical redesign Add leaves or spines within design limits
Capacity planning Focuses on hierarchical uplinks and aggregation Focuses on leaf uplinks, spine capacity and oversubscription
Failure behaviour Depends on redundancy and available alternate paths Remaining ECMP paths can maintain connectivity if reachable

What engineers must still consider

Spine–leaf is not automatically non-blocking, congestion-free or fault-tolerant in every deployment. The architect must calculate uplink capacity, understand oversubscription, verify the forwarding capabilities of the switches and test the consequences of losing a spine or a leaf uplink. Redundant server connections also require an appropriate design, such as supported LACP or multichassis link aggregation where needed.

Engineering takeaway

The key difference is not simply two tiers instead of three. Spine–leaf creates a regular multipath fabric that makes inter-leaf connectivity and scale-out capacity more predictable. Good engineering still depends on the routing design, available bandwidth, failure strategy and workload requirements.

Interactive Architecture Explorer · 01

Compare the Network Architectures

Switch architectures, select network devices to inspect their roles, and animate an illustrative server-to-server path. This simplified diagram explains the design concepts rather than representing a vendor-specific production configuration.

Network devices Connections Servers
Selected device / concept
Leaf switches

Leaf switches connect servers and provide uplinks into the spine layer.

Architecture insight
2 tiers
A common spine–leaf fabric has leaf and spine layers. Actual topology and capacity depend on the design.

Traffic animation is illustrative. Actual forwarding paths depend on routing, ECMP hashing, link state, topology and the configured network.

Section 02 · Fabric and Routing

Spine–Leaf Fabric Architecture: Routing, ECMP and Traffic Flow

The defining feature of a spine–leaf network is its regular connectivity pattern. Every leaf switch connects to every spine switch, while servers and other endpoints attach to the leaf layer. This creates a predictable physical fabric in which routing and multipath forwarding determine how traffic reaches its destination.

Understanding the role of each layer

Leaf switches provide endpoint connectivity. They commonly connect to physical servers, virtualisation hosts, storage systems, firewalls and external network services. Depending on the design, leaf switches may also host Layer 3 gateway functions and VXLAN tunnel endpoints (VTEPs).

Spine switches provide the transit fabric between leaves. In a routed Layer 3 design, each leaf-to-spine connection is normally a point-to-point routed link. Spine switches forward traffic between the relevant leaf-facing interfaces without requiring the spine tier to act as a shared Layer 2 segment.

Tier 01

Leaf layer

Connects endpoints, advertises reachable routes and forwards traffic towards the destination leaf or an upstream service.

Tier 02

Spine layer

Interconnects the leaf switches and provides multiple transit paths across the fabric.

Routing

Underlay control plane

Protocols such as eBGP or OSPF establish Layer 3 reachability. The protocol and route design depend on the chosen fabric.

How a packet crosses the fabric

Consider Server A connected to Leaf 1 and Server B connected to Leaf 2. When Server A sends traffic to Server B, Leaf 1 performs its forwarding lookup and selects an appropriate next hop. In a conventional routed fabric, the packet travels across one of the available leaf-to-spine links. The selected spine then forwards it across its connection to Leaf 2, which delivers the packet to Server B.

Illustrative inter-leaf forwarding path
Server A
→
Leaf 1
→
Spine
→
Leaf 2
→
Server B
The diagram illustrates the forwarding sequence, not a complete physical topology. A full fabric normally has multiple spines and a connection from each leaf to every spine.

Endpoints attached to the same leaf may communicate directly through that switch when the destination is locally reachable. Traffic between different leaves normally traverses a spine. This regular structure provides a consistent inter-leaf hop count, although the actual latency still depends on link speeds, congestion, forwarding performance and workload behaviour.

Equal-Cost Multipath (ECMP)

ECMP allows a router to install multiple next hops for a destination when the routing protocol identifies paths with equal routing cost. In a spine–leaf fabric, a leaf can commonly reach a destination prefix through multiple spine switches. Traffic can therefore use several available paths instead of depending on a single uplink.

Many implementations use a hash based on packet or flow fields to select a next hop. This typically keeps packets from a flow on the same path, helping preserve packet ordering. Consequently, ECMP does not guarantee that every link receives exactly the same amount of traffic: hash distribution, flow sizes and traffic patterns can create uneven utilisation.

Engineering factor What it means
Equal routing cost Multiple next hops are eligible for forwarding to a destination according to the routing implementation.
Flow hashing Traffic is mapped to paths using selected header fields; one large flow may dominate an individual link.
Available path count The number of usable paths depends on topology, routing policy, installed routes and hardware limits.
Failure convergence Following a failure, routes and forwarding state must update before traffic can reliably use alternate paths.

Underlay and overlay: two different responsibilities

The underlay provides IP reachability across the physical fabric. In a VXLAN/EVPN design, leaf switches commonly advertise VTEP loopback reachability through the underlay. The overlay carries tenant or workload traffic using VXLAN encapsulation between VTEPs, while EVPN can distribute endpoint and reachability information.

Keeping these functions distinct helps engineers troubleshoot connectivity. A workload communication problem may arise from underlay routing, overlay control-plane information, endpoint learning, policy enforcement or the physical links themselves. Verifying each layer separately narrows the fault domain.

Engineering takeaway

Spine–leaf provides a repeatable physical topology; routing establishes reachability, and ECMP enables multipath forwarding. Predictable performance still requires careful capacity planning, balanced traffic distribution and validation of failure behaviour.

Interactive Fabric Lab · 02

Trace a Route Through the Spine–Leaf Fabric

Follow traffic from Server A to Server B. Compare two illustrative equal-cost paths, inspect the role of each device, and step through forwarding. The example assumes a routed underlay with ECMP-capable paths between the leaf switches.

Path A Path B Other links
Step 1 of 4 · Traffic enters Leaf 1
Forwarding stage
Leaf 1 receives traffic

Leaf 1 receives the packet from Server A and performs a forwarding lookup. The route and next-hop information determine how it proceeds.

Fabric principle
ECMP
Equal-cost multipath can provide more than one eligible next hop to the destination.

Important: ECMP makes eligible equal-cost next hops available; it does not guarantee that every flow or link carries exactly the same amount of traffic. The forwarding choice depends on the routing table, hashing algorithm, flow characteristics and current topology.

Section 03 · Capacity Engineering

Spine–Leaf Capacity Planning: Bandwidth, Oversubscription and Growth

A spine–leaf fabric can provide predictable paths and substantial aggregate bandwidth, but its real capacity depends on link speeds, the number of uplinks, traffic distribution and the amount of bandwidth required during failures. Capacity planning must account for both normal operation and degraded conditions.

What oversubscription actually means

Oversubscription compares the bandwidth offered by a group of downstream interfaces with the bandwidth available through its upstream links. It is a useful design indicator, not a prediction that every link will be congested. Actual utilisation depends on workload demand, traffic locality, flow sizes and how traffic is distributed across available paths.

Core design formula
Oversubscription ratio = Downstream bandwidth ÷ Upstream bandwidth
Calculate both sides using comparable bandwidth units and clearly define which interfaces and traffic direction are included.
1:1

Nominally non-oversubscribed

The defined downstream capacity equals the available upstream capacity. This does not guarantee zero contention in every traffic pattern or at every point in the network.

3:1

Oversubscribed fabric

The defined downstream capacity is three times the upstream capacity. The design relies on demand not requiring every downstream interface to transmit at full rate simultaneously.

Workload-led

Capacity matched to demand

The target ratio should reflect measured traffic, service objectives, growth expectations and the cost of additional links.

Worked example: calculating leaf uplink capacity

Consider a leaf switch with 48 server-facing ports operating at 25 Gbps and four uplinks to the spine layer, each operating at 100 Gbps. This simplified example assumes all stated ports can transmit at their nominal line rate and compares aggregate downstream port capacity with aggregate uplink capacity.

Example fabric capacity calculation
Server-facing capacity
48 × 25 Gbps = 1,200 Gbps
Aggregate spine uplinks
4 × 100 Gbps = 400 Gbps
Nominal oversubscription ratio
1,200 ÷ 400 = 3:1
Illustrative uplink capacity per leaf
400 Gbps

The resulting 3:1 ratio means the aggregate server-facing port capacity is three times the aggregate uplink capacity. It does not mean the leaf will always experience congestion. If most traffic remains local to the leaf, less bandwidth may need to cross the fabric. If many servers simultaneously send large flows to endpoints on other leaves, uplinks can become a bottleneck.

This example also excludes protocol overhead, port breakout constraints, oversubscription elsewhere in the network and implementation-specific forwarding limits. Production designs should use the actual hardware configuration and expected traffic patterns rather than relying on this ratio alone.

Plan for failures, not just normal operation

Aggregate capacity changes when a link or spine fails. If a leaf has four 100 Gbps uplinks, losing one leaves three uplinks, or 300 Gbps of nominal uplink bandwidth, assuming the remaining links and paths are operational and usable. The example's downstream-to-uplink ratio therefore rises from 3:1 to 4:1.

The actual impact depends on the failure location, routing convergence, ECMP next-hop changes and the distribution of traffic across the surviving links. A resilient design must consider whether the remaining fabric can support critical workloads while operating in this reduced-capacity state.

Design scenario Capacity question What to validate
Normal operation Can the fabric support expected peak demand? Utilisation, flow distribution, latency and congestion.
Single uplink failure Can remaining leaf uplinks carry priority traffic? Surviving bandwidth, routing convergence and ECMP rebalancing.
Spine failure Can the remaining spines handle redistributed traffic? Remaining path capacity, failure-domain impact and link utilisation.
Growth phase Will new endpoints exceed the planned fabric capacity? Port availability, uplink capacity, spine capacity and expansion limits.

Capacity planning is an ongoing engineering task

Design decisions should be revisited using interface counters, telemetry, flow records and application performance measurements. Monitor sustained utilisation as well as short-lived bursts, packet drops, queue behaviour and latency. A fabric can show moderate average utilisation while still experiencing congestion during brief high-demand periods.

Growth planning should also include the physical limits of the chosen platform: available ports, supported speeds, optics, cabling, power, cooling and the number of endpoints that can be added without redesigning the fabric.

Engineering takeaway

Calculate oversubscription explicitly, validate the ratio against real workload behaviour, and repeat the capacity calculation after relevant failures. A well-designed spine–leaf fabric is not simply one with many links; it is one whose available bandwidth meets service requirements under both normal and degraded conditions.

Interactive Capacity Planner · 03

Calculate Leaf Oversubscription

Change the number and speed of server-facing ports and the uplinks connecting a leaf to the spine layer. See the nominal bandwidth ratio, then simulate the loss of one uplink to understand how redundancy affects available capacity.

1. Configure the leaf switch

Start with a typical example, then adjust the values to explore different port-density and uplink designs.

48 ports
8 ports64 ports
25 Gb/s
10 Gb/s100 Gb/s
2. Configure the fabric uplinks

Uplink capacity is the sum of the configured uplink line rates. These controls assume all configured links are available before failure.

4 links
1 link8 links
100 Gb/s
25 Gb/s400 Gb/s
Worked example

48 × 25 Gb/s server ports provide 1,200 Gb/s of nominal server-facing line rate. Four × 100 Gb/s uplinks provide 400 Gb/s of nominal uplink line rate, giving a 3:1 ratio.

3. Review the capacity results

Values are nominal line-rate calculations per direction, not a prediction of real application throughput.

Server-facing capacity
1,200
Gb/s aggregate
Uplink capacity
400
Gb/s aggregate
Uplink capacity per server port
8.33
Gb/s average capacity share
Uplink links available
Before failure simulation
Downlink-to-uplink ratio
Server-facing line rate ÷ uplink line rate
3:1
Uplink capacity compared with downlink capacity 33.3%
Illustrative 3:1 oversubscription

The aggregate server-facing line rate is three times the nominal uplink line rate. Actual contention depends on the traffic pattern and active demand.

4. Simulate one uplink failure

This calculation removes one uplink's capacity. It assumes the remaining links can continue forwarding; real convergence and link distribution depend on the platform and routing design.

Remaining uplink capacity 300 Gb/s
Remaining uplinks 3 of 4
Ratio after failure 4:1
Uplink capacity reduction 25%

Engineering note: Ethernet is full-duplex, so line rate is normally stated per direction; do not double these values when calculating a one-direction oversubscription ratio. The ratio alone does not establish a safe or unsafe design. Validate expected traffic, burst behaviour, ECMP distribution, failure scenarios, buffer behaviour and application requirements.

Section 04 · Resilience Engineering

Failure Domains, Resilience and High Availability

A resilient spine–leaf fabric is designed to keep essential communication working when links or devices fail. Its regular topology provides multiple potential paths between leaves, but redundancy alone does not guarantee uninterrupted service. Routing convergence, remaining capacity, device dependencies and the location of the failure all influence the outcome.

Understand the main failure domains

A failure domain is the part of a network whose operation may be affected by a particular fault. A single link failure may have a limited impact, while a failed leaf can disconnect the servers attached to it. A spine failure may affect traffic across multiple leaves, even when the fabric has alternative spines available.

Link failure

One path is lost

If other usable paths remain, routing can select alternate next hops. Available bandwidth falls, and traffic may need to redistribute across the surviving links.

Spine failure

Fabric capacity is reduced

Leaves may continue communicating through the remaining spines. The remaining fabric must have sufficient capacity to carry the traffic that is redirected onto it.

Leaf failure

Attached endpoints are at risk

Servers connected only to the failed leaf can lose network connectivity. Dual-homing or redundant attachment may help, but only when the complete design supports it.

How ECMP helps the fabric recover

Equal-Cost Multipath (ECMP) allows a router to install multiple eligible next hops with the same routing cost. Traffic can then be distributed across those paths, commonly using a hash of packet or flow fields. If a next hop becomes unavailable and the routing system detects the change, the forwarding table can be updated to use the remaining eligible paths.

ECMP does not make every flow move instantly or guarantee perfectly even link utilisation. The result depends on the routing protocol, failure detection, convergence behaviour, hash inputs, flow sizes and the forwarding hardware. A small number of large flows can produce uneven utilisation even when several paths are available.

Illustrative failure sequence: one spine becomes unavailable
Normal
Multiple paths are available Leaves have routes through several spines. Eligible traffic is distributed across the installed equal-cost next hops.
Failure
A spine or its path fails Failure detection and routing updates determine when the affected next hop is removed or becomes unusable.
Recompute
Forwarding uses surviving paths The routing and forwarding systems update their usable next hops. Some packets may be lost or delayed during detection and convergence.
Validate
Service continues if the design permits Confirm that critical flows recover and that surviving links and spines can handle the redistributed traffic.

Redundancy must include enough surviving capacity

Consider a leaf with four 100 Gbps uplinks to separate spines. Before a failure, the nominal aggregate uplink capacity is 400 Gbps. If one uplink becomes unavailable, the remaining three links provide 300 Gbps of nominal aggregate capacity, assuming each remaining link is usable at its stated rate.

That reduction matters even if routing converges successfully. If traffic demand exceeds the capacity available after the failure, congestion or packet loss may occur. Capacity planning should therefore evaluate expected demand with a link or spine unavailable, not just the normal operating state.

Failure Potential consequence Design and test focus
Leaf-to-spine link Fewer uplinks and reduced capacity from the affected leaf. Confirm alternate routes, detection time and surviving uplink utilisation.
Entire spine Multiple leaves lose one set of paths through the fabric. Check remaining spine capacity and traffic redistribution across the fabric.
Leaf switch Endpoints attached only to that leaf may become unreachable. Validate server attachment redundancy, gateway placement and application recovery.
Power or shared dependency Several devices or links may fail together. Review power feeds, cabling paths, rack placement and common failure dependencies.

Design for independent failure domains

Two links do not necessarily provide independent protection if they share a physical path, power source or intermediate device. Likewise, connecting a server to two switches does not automatically create active-active resilience. The server NIC configuration, switching design, gateway behaviour and routing or multi-chassis technology must work together.

Depending on the architecture, server redundancy may use routed connectivity, Layer 2 link aggregation, a multi-chassis link aggregation mechanism or another supported host-attachment design. Choose the method according to platform capabilities and the required failure behaviour rather than assuming that one method fits every fabric.

Test recovery instead of assuming it

A practical resilience test should deliberately remove a link or device in a controlled environment, observe routing and forwarding changes, and measure the effect on representative application traffic. Check packet loss, recovery time, latency, route changes and the utilisation of surviving links. Repeat the test for the failures that matter to the service.

Engineering takeaway

A resilient spine–leaf fabric needs alternate paths, working failure detection, correct routing behaviour and sufficient surviving capacity. Validate the whole system—including server attachment and shared physical dependencies—under realistic failure conditions. Redundant topology is the starting point; tested recovery is the outcome that matters.

Interactive Resilience Lab · 04

What Happens When a Fabric Component Fails?

Select a failure scenario to see how a simplified routed spine–leaf fabric is affected. You can also select an individual spine or leaf to inspect its role. Green links represent available connections; red links indicate failed or affected connections.

Available connection Failed / affected Other connection
Available spine paths between Leaf 1 and Leaf 2
2
Illustrative paths through operational spines
Fabric connectivity
Available
For the selected source and destination in this model
Nominal transit capacity
100%
Simplified relative capacity, not measured throughput
Normal operation

Both spine paths are available in this simplified topology. Actual traffic distribution depends on routing state, ECMP hashing and link capacity.

Component inspection
Spine–leaf resilience

Select a device in the diagram to inspect its role. Use the failure controls to explore how losing a component changes the available paths.

This is a conceptual failure model, not a live network simulation. It assumes a two-spine, two-leaf routed fabric with independent links and enough remaining capacity to carry traffic after a single spine or uplink failure. Real outcomes depend on topology, routing convergence, link speeds, platform limits, endpoint attachment and traffic demand. A failed leaf can disconnect endpoints attached only to that leaf.

Section 05 · Fabric Architecture

Underlay, VXLAN/EVPN and Cisco ACI

Spine–leaf describes a physical and logical fabric topology, but it does not prescribe a single way to provide network services. A common design uses a routed Layer 3 underlay to connect the switches and an overlay to provide logical Layer 2 or Layer 3 connectivity across that fabric. Cisco ACI is another approach, combining a spine–leaf fabric with a policy-driven architecture and centralised controller-based management.

Separate transport from network services

The underlay and overlay solve different problems. The underlay provides IP reachability between the relevant fabric endpoints, while an overlay can create logical network segments that are independent of the physical location of a workload. Keeping these roles distinct makes the architecture easier to reason about, operate and troubleshoot.

01

Physical fabric

Leaf and spine switches, server-facing interfaces, fabric links, transceivers, cabling and physical capacity. This layer determines the available ports, speeds and physical paths.

02

Routed underlay

IP addressing, routing adjacencies and routes that provide reachability across the fabric. Common designs use an IGP or BGP, depending on the operational model and requirements.

03

Overlay and segmentation

VXLAN can encapsulate tenant traffic across the IP fabric. EVPN commonly distributes MAC and IP reachability information and supports control-plane functions for VXLAN overlays.

04

Policy and operations

Network policy, tenant segmentation, automation, telemetry and troubleshooting workflows define how the fabric is configured, monitored and managed.

What VXLAN and EVPN contribute

VXLAN provides an encapsulation mechanism that carries an inner Ethernet frame across an IP network. The outer IP packet travels through the underlay, allowing logical Layer 2 segments to span multiple switches without requiring the same physical Layer 2 segment to extend across the entire fabric.

EVPN is a control-plane mechanism commonly used with VXLAN to advertise endpoint reachability and support MAC learning and IP-related information. It can help the fabric make forwarding decisions without relying solely on data-plane flooding and learning. Exact behaviour depends on the EVPN design, device capabilities and configuration.

Illustrative packet journey between two logical segments
1 · Source workload
A server sends traffic into its attached leaf.
2 · Overlay processing
The leaf applies the configured forwarding and encapsulation behaviour.
3 · Underlay forwarding
The outer IP packet is routed across the leaf–spine fabric.
4 · Destination leaf
The destination tunnel endpoint processes the encapsulated traffic.
5 · Destination workload
The decapsulated frame is forwarded according to the destination network and policy.

This is an illustrative forwarding sequence, not a claim that every packet must cross a spine. Traffic between endpoints on the same leaf may be forwarded locally, depending on the network and forwarding configuration. Traffic between different leaves typically traverses the routed fabric.

Why the underlay still matters

An overlay does not remove the need for a reliable underlay. Tunnel endpoints must have the IP reachability required to communicate, and the physical fabric must provide sufficient bandwidth and predictable forwarding. If underlay routes, interfaces or MTU settings are incorrect, overlay services can fail even when their logical configuration appears valid.

Reachability

Routing and next hops

Verify interface addressing, routing adjacencies, route installation and reachability between relevant tunnel endpoints.

Encapsulation

MTU and packet handling

Account for encapsulation overhead and verify that the path supports the required packet sizes without unintended drops.

Forwarding

ECMP and capacity

Check usable next hops, traffic distribution, link utilisation and whether surviving paths can support the workload.

Where Cisco ACI fits

Cisco Application Centric Infrastructure (ACI) uses a spine–leaf fabric with a policy-driven operational model. In a typical ACI deployment, the Application Policy Infrastructure Controller (APIC) provides centralised policy and fabric management. The fabric switches enforce the configured policy and perform the forwarding functions supported by the platform.

ACI is not simply another name for VXLAN/EVPN. It is a broader architecture with its own policy model, management components and control mechanisms. By contrast, a conventional spine–leaf network can be assembled using routed switching and separately selected overlay and automation technologies.

Design area Routed spine–leaf with VXLAN/EVPN Cisco ACI
Architecture A routed fabric with an overlay and control-plane choices selected for the deployment. An integrated fabric architecture with a policy-driven model.
Configuration model Commonly uses switch configuration, automation and selected management or controller tools. Uses ACI constructs and APIC-based policy and fabric management.
Segmentation Implemented through the selected overlay, routing and policy design. Implemented through ACI policy constructs and supported fabric features.
Operational considerations Requires a consistent design and operational model across the selected protocols and tools. Requires understanding of ACI policy, fabric operation, controller health and platform-specific behaviour.

Neither approach is universally better. Selection depends on operational skills, policy requirements, interoperability, automation, platform constraints, lifecycle costs and the organisation's preferred way of managing change.

Engineering takeaway

Keep the roles clear: the physical fabric provides connectivity, the routed underlay provides IP reachability, and an overlay such as VXLAN/EVPN can provide logical network services. Cisco ACI packages fabric operation and policy into a broader architecture. Whichever model you choose, validate routing, encapsulation, MTU, segmentation and failure behaviour as one end-to-end system.

Interactive Overlay Lab · 05

Trace a Packet Through Underlay and Overlay

A modern data-centre fabric can separate IP transport from tenant connectivity. Explore the routed underlay, the VXLAN data plane and the EVPN control plane, then step through an illustrative packet journey between endpoints connected to different leaf switches.

TENANT ENDPOINTS ROUTED SPINE FABRIC Leaf 1 · VTEP VTEP 192.0.2.11 Leaf 2 · VTEP VTEP 192.0.2.12 Spine 1 IP transit Spine 2 IP transit Endpoint A 10.10.1.10 Endpoint B 10.10.1.20 TENANT SEGMENT · VNI 10010 Illustrative VXLAN overlay EVPN CONTROL PLANE Advertises endpoint reachability
Routed underlay VXLAN overlay EVPN control plane
Transport
Routed underlay

Provides IP reachability between VTEP addresses across the leaf–spine fabric. Routing and ECMP select available transport paths.

Data plane
VXLAN overlay

Encapsulates an inner Ethernet frame in an outer IP/UDP/VXLAN packet, carrying a VNI to identify the overlay segment.

Reachability
EVPN control plane

Uses BGP EVPN routes to distribute MAC and, where applicable, IP reachability information so VTEPs can learn remote endpoints.

Step 1 of 4 · Packet journey
VXLAN data plane
Encapsulate at the source VTEP

Leaf 1 receives Endpoint A's Ethernet frame, identifies the tenant segment and encapsulates the frame in VXLAN for the destination VTEP on Leaf 2.

Inner source: 10.10.1.10
Inner destination: 10.10.1.20
VNI: 10010
Outer destination: 192.0.2.12

Conceptual example only. The IP addresses and VNI are illustrative. Exact EVPN route types, gateway placement, ARP/ND handling, multicast or ingress-replication behaviour and policy depend on the implementation. Cisco ACI is a distinct policy-driven fabric architecture; it should not be treated as simply another name for a generic VXLAN/EVPN deployment.

Section 06 · Operations and Observability

Telemetry, Analytics and Troubleshooting a Spine–Leaf Fabric

A spine–leaf fabric can have many equal-cost paths, high aggregate bandwidth and redundant links, yet applications can still suffer from packet loss, latency or intermittent connectivity. Effective operations combine physical interface health, routing state, forwarding behaviour and application-level evidence to locate the actual fault rather than treating every symptom as a switch problem.

Build visibility across the fabric

No single monitoring source explains every network problem. Interface counters can reveal physical errors and congestion; routing information shows which paths are eligible; flow telemetry helps explain where traffic is going; and application measurements show whether the network is meeting service requirements. Correlating these sources provides a more reliable picture than examining isolated counters or alerts.

Physical layer

Interfaces and optics

Monitor link state, CRC errors, discards, interface resets, transceiver alarms and changes in error counters over time.

Control plane

Routing and neighbours

Check routing adjacencies, installed routes, next-hop changes, ECMP membership and evidence of repeated convergence.

Traffic behaviour

Flows and utilisation

Identify heavy flows, asymmetric traffic patterns, sustained utilisation, bursts, queue drops and uneven path loading.

Service layer

Latency and reachability

Correlate network events with application latency, packet loss, connection failures and the timing of user-visible incidents.

Know what each monitoring source can tell you

Source Useful evidence Important limitation
SNMP or interface polling Interface status, byte and packet counters, errors and discards. Polling intervals may miss short bursts; counter changes need context.
Streaming telemetry Frequent structured measurements of supported interface, queue, routing or device state. Available metrics and sampling behaviour vary by platform and configuration.
Flow records Traffic conversations, source and destination patterns, protocol usage and traffic-volume estimates. Sampling and export configuration affect what is visible; flow records do not necessarily explain every packet drop.
Routing and forwarding tables Selected routes, next hops, ECMP paths and forwarding entries. A valid route does not prove that the physical path is healthy or that application traffic is performing well.
Active probes and application monitoring Reachability, round-trip time, loss and application response behaviour. Results depend on probe placement, test traffic and the path taken by the measured flow.

A systematic troubleshooting workflow

Start with the observed symptom and narrow the scope. Determine which endpoints, applications, leaves and paths are affected. Establish when the issue began, compare current state with a known-good baseline, and look for changes that match the incident timeline.

01

Define the impact

Identify affected source and destination endpoints, the application or service, whether the issue is constant or intermittent, and whether it affects one leaf or multiple leaves.

02

Check physical health

Inspect interface state, error counters, discards, optics, cabling and queue statistics along the likely path. Compare counter changes over a consistent time interval.

03

Verify routing and ECMP

Confirm reachability and installed routes. Check whether the expected next hops are present, whether adjacencies are stable and whether a recent failure changed path selection.

04

Examine traffic and congestion

Compare utilisation across relevant uplinks, inspect available queue and drop metrics, and look for large flows or uneven ECMP distribution. High average utilisation is not the only possible cause of congestion.

05

Correlate with application evidence

Compare network events with application latency, retransmissions, connection errors and probe results. Check endpoint, host and service health before concluding that the fabric is responsible.

06

Verify the fix

Repeat the same tests, confirm counters stop increasing abnormally, validate the intended paths and check application performance. Record the cause and the evidence that demonstrated recovery.

Example: diagnosing intermittent application latency

Imagine that an application communicates between servers connected to different leaf switches. Users report occasional delays, but the links remain up and routing adjacencies appear stable. The correct response is to gather evidence across several layers rather than assuming that the fabric has sufficient capacity because no interface is continuously saturated.

Observation Possible interpretation Next check
Interface errors increase A physical link, optic, cable or interface issue may be present. Identify the affected interface and inspect physical diagnostics and error-counter changes.
Queue drops rise during bursts Short periods of congestion may be affecting latency or packet delivery. Correlate queue statistics with traffic bursts and the affected flows.
One uplink is much busier than others ECMP hashing or a small number of large flows may create uneven utilisation. Inspect available flow data, hash behaviour and per-link counters.
Routes change near the incident time A link event or routing instability may have altered the forwarding path. Review logs, adjacency events, route changes and convergence timing.
Fabric indicators appear normal The cause may lie at the host, virtual switch, application or another dependency. Compare endpoint metrics, service logs, packet captures and independent probes.

Build useful baselines and alerts

Alerting is more effective when it combines thresholds with trends and context. A brief utilisation spike may be expected, while a sustained rise in discards or recurring routing changes may deserve immediate investigation. Establish baselines for normal and peak periods, and tune alert thresholds to the platform and service requirements.

Useful operational dashboards bring together topology, interface health, link utilisation, routing state, device events and service performance. Time synchronisation across devices and monitoring systems is essential when correlating an incident. Retain enough historical data to compare the period before, during and after the fault.

Engineering takeaway

Troubleshoot from evidence, not assumptions. Correlate physical health, routing and ECMP state, traffic distribution, congestion indicators and application symptoms. The aim is to identify the fault domain, demonstrate the cause with observable data, and verify that the corrective action restores the required service.

Interactive Troubleshooting Lab · 06

Diagnose a Spine–Leaf Fabric Incident

Choose a symptom, inspect the simulated telemetry and work through the diagnostic sequence. The objective is to identify evidence that supports a hypothesis before changing the network.

Incident summary
Investigation required

Application response times rise during busy periods. Determine whether congestion, physical errors or another fault is supported by evidence.

Simulated telemetry snapshot
Utilisation
92%
Busy uplink
CRC errors
0
No increase observed
Path state
Up
Routes present
Spine 1 IP transit Spine 2 IP transit Leaf 1 Endpoint access Leaf 2 Endpoint access Server A Source Server B Destination
Normal Warning / investigate Suspected fault Verified / recovered
Diagnostic workflow · Select a step
Investigation focus
Establish the scope before changing anything

Identify which applications, source and destination endpoints, paths and time windows are affected. Compare the symptoms with a known-good baseline.

01Record the first observed failure and its duration.
02Check whether the issue affects one flow or many.

Training simulation: all metrics and fault indicators are illustrative, not live device telemetry. High utilisation alone does not prove congestion; correlate it with drops, queue behaviour, latency and the affected traffic. A route being present does not prove the complete data path is healthy.

Section 07 · Design and Implementation

Spine–Leaf Design Decisions and Implementation Checklist

A successful spine–leaf deployment starts with workload requirements, not a switch count or a preferred topology diagram. The design should establish the required connectivity, performance, resilience and operational model before hardware, routing protocols and overlays are selected. Each decision should be validated against the services the fabric must support.

Start with requirements, not assumptions

Document how many endpoints must connect, where workloads communicate, which applications are sensitive to latency, and how much traffic is expected to cross between leaves. Include planned growth, maintenance requirements, failure scenarios and operational constraints. These inputs determine the appropriate topology, link speeds, oversubscription target and expansion strategy.

Connectivity

Endpoint and port needs

Estimate server counts, port speeds, dual-homing requirements, network segments and the number of leaf switches needed.

Performance

Traffic and latency

Understand east–west traffic, peak demand, workload locality, latency targets and expected flow distribution.

Resilience

Failure requirements

Define which failures the fabric must tolerate and what performance is required while operating in a degraded state.

Operations

Management and skills

Plan configuration, automation, monitoring, troubleshooting, maintenance windows and team expertise.

Work through the design in a controlled sequence

01

Choose the physical topology

Determine the number of leaves and spines, required endpoint density, cabling paths and supported link speeds. Check platform port limits and expansion constraints before finalising the topology.

02

Define the routed underlay

Select the addressing plan, routing protocol, link addressing, route policy and failure-detection approach. Keep the design consistent and document how routes should behave during faults.

03

Set capacity and oversubscription targets

Calculate aggregate server-facing bandwidth and uplink capacity. Test expected peak traffic, account for ECMP behaviour, and verify remaining capacity after relevant link or spine failures.

04

Select segmentation and overlay services

Decide whether routed connectivity alone meets requirements or whether VXLAN/EVPN, another overlay or a policy-driven fabric architecture is needed. Document Layer 2 and Layer 3 service boundaries and security controls.

05

Plan endpoint and gateway redundancy

Define server attachment, gateway placement, link aggregation or other supported redundancy mechanisms. Validate the complete design rather than assuming two connections guarantee continuity.

06

Build observability into the deployment

Establish telemetry, interface and queue monitoring, routing event collection, flow visibility, time synchronisation and application-level performance baselines.

07

Validate before production rollout

Test connectivity, expected forwarding paths, policy enforcement, failure recovery, degraded capacity and operational procedures. Record the results and resolve gaps before expanding the deployment.

Implementation readiness checklist

Use the following checklist during design review and pre-production validation. Each item should have supporting evidence, such as a calculation, configuration review, test result or documented decision.

✓
Topology and physical capacity Leaf and spine counts, port density, link speeds, cabling, power and expansion limits have been reviewed.
✓
Routing and reachability Addressing, routing adjacencies, route selection, ECMP membership and intended forwarding behaviour are documented.
✓
Capacity and degraded operation Oversubscription calculations reflect expected workloads, and surviving capacity has been evaluated for relevant failures.
✓
Segmentation and security Network boundaries, routing policy, access controls and overlay behaviour meet the intended service requirements.
✓
Endpoint and gateway resilience Host connectivity, gateway availability and any link-aggregation or multi-chassis mechanisms have been tested for the intended failures.
✓
Monitoring and alerting Interface health, routing changes, traffic distribution, congestion and application symptoms can be correlated during an incident.
✓
Failure and recovery tests Link and device failures have been tested in a controlled environment, including convergence, packet loss and service recovery.
✓
Operational ownership Configuration standards, change control, escalation paths, maintenance procedures and recovery documentation are available.

Common design mistakes to avoid

Assumption Why it can be misleading Better approach
More spines always solve capacity problems Endpoint links, leaf uplinks, hardware limits or traffic distribution may remain the bottleneck. Identify the actual constraint and recalculate end-to-end capacity.
ECMP guarantees equal utilisation Hashing and flow-size differences can create uneven traffic distribution. Inspect per-link counters and available flow telemetry under realistic loads.
Redundancy guarantees uninterrupted service Convergence, shared dependencies, endpoint design and reduced capacity can still interrupt or degrade applications. Define failure requirements and measure recovery through controlled tests.
An overlay removes underlay complexity Tunnel endpoints still depend on routing, MTU, physical connectivity and correct forwarding state. Troubleshoot underlay and overlay as separate but connected layers.
Average utilisation tells the whole story Short bursts, queue congestion, packet drops or a few large flows can affect service even when averages look acceptable. Combine time-series metrics, queue data, flow evidence and application measurements.

Plan for the full lifecycle

The fabric should be designed for more than its initial deployment. Establish how new leaves will be added, how capacity will be reassessed, how software and hardware will be maintained, and how configuration changes will be tested. Define measurable service targets and periodically review whether the fabric still meets them as workload patterns and business requirements change.

A scalable architecture is one that can grow predictably without introducing unmanaged complexity. That requires consistent configuration, clear ownership, repeatable validation and operational evidence—not just a topology that looks symmetrical.

Engineering takeaway

Design from workload requirements, calculate capacity explicitly, separate underlay and overlay responsibilities, and test failure behaviour before production. A robust spine–leaf fabric balances performance, resilience, operational simplicity and the cost of future growth.

Interactive Design Workshop · 07

Build a Spine–Leaf Design Readiness Plan

Configure a sample fabric, review its nominal bandwidth and consider what happens when an uplink fails. Then complete the readiness checklist to assess whether the design has been specified, tested and documented.

1. Configure the fabric
48
25 Gb/s
4
100 Gb/s
2

The drawing shows up to five representative spines. The configured spine count is used in the design inputs, not as proof of available switch capacity.

2. Review the design
Aggregate downlink
1.20 Tb/s
Per leaf, nominal line rate
Aggregate uplink
400 Gb/s
Per leaf, nominal line rate
Oversubscription
3.00:1
Downlink capacity : uplink capacity
After one uplink fails
4.00:1
Remaining uplink line rate: 300 Gb/s
Uplink capacity relative to downlinks 33%
3. Implementation-readiness checklist
0 of 8 complete
Design review result
Design review not yet complete

Use the capacity calculation as an initial check, complete the readiness items and validate the design against workload and failure requirements.

Capacity model assumptions: nominal port line rates are compared in one direction and are not doubled for full duplex. The model does not account for protocol overhead, internal switch fabric limits, traffic locality or real flow distributions. After one uplink fails, one uplink's capacity is removed. The topology is illustrative and does not prove that the selected switches have sufficient ports, bandwidth or forwarding capacity. Validate the physical design and required failure scenarios before deployment.

```
☕
Support Network Insight
Help support independent engineering guides, interactive networking tools, and future learning labs.
Support Network Insight ```