Chaos Engineering

Chaos Engineering Kubernetes

Chaos Engineering Kuberentes

In Kubernetes environments, reliability cannot be measured simply by whether workloads are running. Distributed applications can remain technically available while experiencing increased latency, elevated error rates, resource exhaustion, or degraded dependencies. Chaos Engineering provides a controlled way to expose these weaknesses before they become production incidents.

Chaos Engineering involves deliberately introducing controlled failures or abnormal conditions into a system and observing how it responds. The objective is not to cause disruption for its own sake, but to validate resilience assumptions, identify unknown failure modes, and improve the system’s ability to recover. In Kubernetes, experiments can target workloads, nodes, networking, storage, dependencies, or resource availability.

A successful experiment begins with a hypothesis. Engineers define what they expect to happen if a particular component fails and establish the signals that will demonstrate whether the system remained within acceptable limits. A controlled fault is then introduced while telemetry is collected, allowing the resulting behaviour to be compared with the original reliability expectations.

This makes metrics and observability fundamental to Chaos Engineering. Key signals can include request latency, error rates, throughput, CPU and memory utilisation, pod restarts, resource saturation, queue depth, and application-specific service-level indicators. Looking at these signals together provides a much clearer picture of system health than relying on a single metric.

Latency metrics help reveal how a failure affects application response times. Introducing network delay, dependency latency, or resource contention can demonstrate whether timeouts, retries, load balancing, and application fallbacks behave as expected. A service may remain available while its latency increases enough to create a significant user-facing impact.

Error and availability metrics show whether the system continues to meet its reliability objectives when components fail. Controlled pod termination, dependency failures, or network disruption can reveal whether Kubernetes workloads restart correctly and whether applications have sufficient redundancy and graceful failure mechanisms.

Resource and saturation metrics provide another important perspective. CPU throttling, memory pressure, constrained capacity, or excessive workload demand can expose weak resource limits, inefficient scheduling, or scaling assumptions. These experiments can help validate whether Kubernetes workloads respond correctly when the underlying resources become constrained.

The real value of Chaos Engineering comes from connecting these experiments to observable outcomes. A useful experiment should establish a hypothesis, introduce a controlled fault, monitor the relevant telemetry, measure the impact, and capture what was learned. The results can then feed back into application design, Kubernetes configuration, alerting, capacity planning, and incident response.

Chaos Engineering therefore becomes more than deliberately creating failures. It is a practical method for testing whether a Kubernetes platform and the applications running on it can detect, tolerate, and recover from unexpected conditionsbefore those conditions become real-world incidents.

Interactive Chaos Engineering / Experiment 01

Chaos Engineering Experiment Loop

Chaos engineering is not simply breaking a system. The engineering process is to define normal behavior, form a hypothesis, introduce a realistic failure, observe the system, and use the evidence to improve resilience.

Experiment Objective
Prove that the application can tolerate failure
Start with measurable steady-state behavior. Then introduce one controlled fault and determine whether the application remains within its reliability objectives or successfully recovers.
p99 < 200ms
Errors < 1%
Availability > 99.9%
CPU < 70%
Engineering Principle
Test the hypothesis
A useful experiment attempts to disprove an assumption about system resilience rather than simply generate failure.
Experiment Lifecycle
01
Steady State
Establish measurable normal behavior.
02
Hypothesis
Predict how the system should respond.
03
Inject Failure
Introduce a controlled realistic fault.
04
Observe
Measure system behavior during failure.
05
Compare
Compare results against steady state.
06
Improve
Fix weaknesses and repeat the experiment.
Selected Stage
01 — Steady State
BASELINE
Before introducing chaos, define what healthy behavior looks like. The baseline should be measurable so that the experiment has something meaningful to compare against.
Question: What does “healthy” look like for this application?
Engineering principle: If you cannot measure steady state, you cannot reliably determine whether a chaos experiment caused meaningful degradation.
Experiment Telemetry
p99 Latency
142 ms
Error Rate
0.3%
Availability
99.98%
CPU Usage
54%
Experiment Result
HYPOTHESIS SUPPORTED
The simulated failure produced a measurable change, but the service recovered and returned toward its defined steady state.
Engineering Takeaway: Chaos engineering should be treated as a controlled scientific experiment. Define the steady state first, introduce a realistic failure with a known blast radius, observe the system, compare the result with the baseline, and feed the learning back into the design.
STEADY STATE → HYPOTHESIS → FAILURE → OBSERVE → COMPARE → IMPROVE → REPEAT

Highlights: Chaos Engineering Kuberentes

The Principles of Chaos Engineering

Chaos Engineering is grounded in several core principles. First, it is about embracing failure as a learning opportunity. By simulating failures, teams can understand how their systems react under stress. Another principle is to conduct experiments in a controlled environment, ensuring any disruptions do not affect end users. Lastly, Chaos Engineering emphasizes continuous learning and improvement, turning insights from experiments into actionable changes.

**Tools and Techniques**

Implementing chaos engineering requires a robust set of tools and techniques to simulate real-world disruptions effectively. Some popular tools in the chaos engineering toolkit include Chaos Monkey, Gremlin, and Litmus, each offering unique features to test system resilience. These tools enable engineers to automate experiments, analyze results, and derive actionable insights. By using these advanced tools, organizations can run experiments at scale and gain confidence in their systems’ ability to handle unpredictable events.

**Why Chaos Engineering Matters**

Modern systems are complex and often distributed across multiple platforms and services. This complexity makes it difficult to predict how systems will behave under unexpected conditions. Chaos Engineering allows teams to identify hidden vulnerabilities, improve system reliability, and enhance user experience. Companies like Netflix and Amazon have successfully used Chaos Engineering to maintain their competitive edge by ensuring their services remain robust and available.

**The Traditional Application**

When considering Chaos Engineering kubernetes, we must start from the beginning. Not too long ago, applications ran in single private data centers, potentially two data centers for high availability. These data centers were on-premises, and all components were housed internally. Life was easy, and troubleshooting and monitoring any issues could be done by a single team, if not a single person, with predefined dashboards. Failures were known, and there was a capacity planning strategy that did not change too much, and you could carry out standard dropped packet test

**A Static Infrastructure**

The network and infrastructure had fixed perimeters and were pretty static. There weren’t many changes to the stack, for example, daily. Agility was at an all-time low, but that did not matter for the environments in which the application and infrastructure were housed. However, nowadays, we are in a completely different environment with many more moving parts with an increasing need to support a reliable distributed system.

Complexity is at an all-time high, and business agility is critical. Now, we have distributed applications with components/services located in many different places and types of places, on-premises and in the cloud, with dependencies on both local and remote services. So, in this land of complexity, we must find system reliability. A reliable system is one that you can trust will be reliable.

Chaos Engineering in Kubernetes — Designing for Failure in Cloud‑Native Systems

Chaos engineering in Kubernetes is the discipline of intentionally injecting failure into clusters to validate resilience, uncover hidden weaknesses, and ensure workloads behave correctly under stress. Instead of waiting for outages, chaos engineering forces the system to experience them in a controlled, observable way. Kubernetes is a perfect environment for chaos experiments because it is inherently dynamic, distributed, and built around self‑healing primitives.

Why Chaos Engineering Matters in Kubernetes

Kubernetes abstracts infrastructure, but abstraction hides failure. Chaos engineering exposes how workloads behave when:

  • nodes crash
  • pods restart unexpectedly
  • network latency spikes
  • storage becomes slow or unavailable
  • API server becomes overloaded
  • autoscaling triggers aggressively
  • controllers misbehave

Chaos engineering ensures your cluster is resilient by design, not by assumption.

Core Principles of Kubernetes Chaos Engineering

Chaos engineering in Kubernetes follows four foundational principles:

1. Define Steady State

You must know what “normal” looks like.

Examples:

  • p99 latency under 200ms
  • error rate < 1%
  • CPU usage < 70%
  • pods healthy and ready

Steady state becomes the baseline for evaluating chaos impact.

2. Introduce Realistic Failure

Chaos experiments should mimic real‑world failures:

  • node shutdown
  • pod eviction
  • network partition
  • DNS failure
  • container crash loops
  • storage throttling

Chaos must be representative, not random.

3. Observe System Behavior

Use Kubernetes observability tools:

  • Prometheus metrics
  • Loki logs
  • Jaeger/Tempo traces
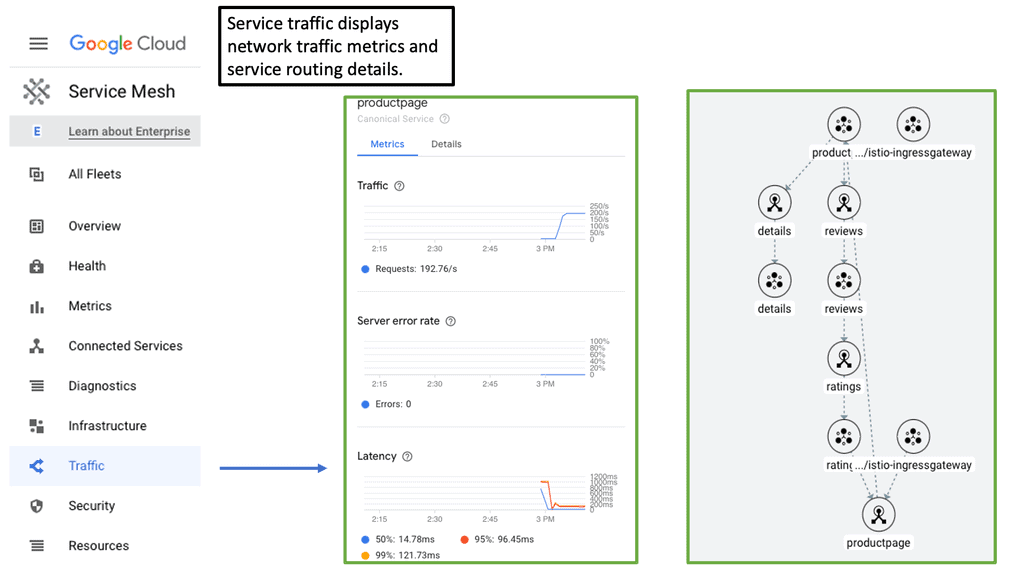
  • Kiali (service mesh)
  • OpenTelemetry pipelines

Chaos without observability is just destruction.

4. Improve and Repeat

Chaos engineering is iterative.

Each experiment reveals weaknesses that must be fixed, validated, and re‑tested.

Common Chaos Experiments in Kubernetes

Here are the most valuable chaos tests for real‑world clusters:

1. Pod Kill / Pod Restart

Simulates container crashes.

Validates:

  • readiness/liveness probes
  • retry logic
  • graceful shutdown
  • autoscaling behavior

2. Node Failure / Node Drain

Simulates hardware failure or maintenance.

Validates:

  • pod rescheduling
  • replica distribution
  • disruption budgets
  • cluster autoscaler behavior

3. Network Latency / Packet Loss

Simulates degraded network conditions.

Validates:

  • microservices resilience
  • timeout handling
  • circuit breakers
  • service mesh routing

4. API Server Stress

Simulates control‑plane overload.

Validates:

  • controller stability
  • admission webhook behavior
  • cluster responsiveness

5. Storage Throttling / Volume Detach

Simulates slow or failing storage.

Validates:

  • database failover
  • persistent volume resilience
  • application retry logic

6. Service Mesh Failure

Simulates sidecar or proxy issues.

Validates:

  • fallback routing
  • mesh control‑plane resilience
  • degraded mode behavior

Chaos Engineering + Kubernetes Operators

Operators automate application lifecycle management.

Chaos engineering validates operator logic:

  • reconciliation loops
  • state recovery
  • CRD consistency
  • failover automation

If an operator cannot recover state after chaos, it is not production‑ready.

Chaos Engineering for Security

Chaos engineering can also test security controls:

  • RBAC misconfigurations
  • network policy gaps
  • pod escape attempts
  • privilege escalation
  • secret rotation failures

Security chaos engineering ensures Zero Trust principles hold under stress.

Tools for Kubernetes Chaos Engineering

Popular tools include:

  • LitmusChaos — CNCF project for Kubernetes chaos workflows
  • Chaos Mesh — powerful, Kubernetes‑native chaos platform
  • Gremlin — enterprise chaos engineering suite
  • Kube‑Monkey — pod‑kill chaos inspired by Netflix’s Chaos Monkey

These tools integrate with CI/CD pipelines, allowing chaos tests to run automatically.

Outcome — A Resilient, Self‑Healing Kubernetes Platform

Chaos engineering ensures Kubernetes workloads:

  • survive node failures
  • recover from pod crashes
  • tolerate network degradation
  • handle storage instability
  • maintain service reliability
  • enforce security under stress

Chaos engineering transforms Kubernetes from “works in ideal conditions” to “works under real‑world failure.”

Implementing Chaos Engineering

Implementing Chaos Engineering involves several steps. First, start by defining a “steady state” of your system’s normal operations. Next, develop hypotheses about potential failure points and design experiments to test these. Use tools like Chaos Monkey or Gremlin to introduce controlled disruptions and observe the outcomes. Finally, analyze the results and apply any necessary changes to improve system resilience.

Challenges and Considerations

While Chaos Engineering offers many benefits, it also presents challenges. Resistance from stakeholders who are wary of intentional disruptions can be a hurdle. Additionally, ensuring that experiments are conducted safely and do not impact customers is crucial. To overcome these challenges, it’s important to foster a culture of transparency, continuous learning, and collaboration among teams.

Benefits of Chaos Engineering in Kubernetes:

1. Enhanced Reliability: By subjecting Kubernetes deployments to controlled failures, Chaos Engineering helps organizations identify weak points and vulnerabilities, enabling them to build more resilient systems that can withstand unforeseen events.

2. Improved Incident Response: Chaos Engineering allows organizations to test and refine their incident response processes by simulating real-world failures. This helps teams understand how to quickly detect and mitigate potential issues, reducing downtime and improving the overall incident response capabilities.

3. Cost Optimization: Chaos engineering can help optimize resource utilization within a Kubernetes cluster by identifying and addressing performance bottlenecks and inefficient resource allocation. This, in turn, leads to cost savings and improved efficiency.

Personal Note: Today’s standard explanation for Chaos Engineering is “The facilitation of experiments to uncover systemic weaknesses.” The following is true for Chaos Engineering.

  1. Begin by defining “steady state” as some measurable output of a system that indicates normal behavior.
  2. Hypothesize that this steady state will persist in both the control and experimental groups.
  3. Submit variables that mirror real-world events like servers that crash, hard drives that malfunction, severed network connections, etc.
  4. Then, as a final step, try to disprove the hypothesis by looking for a steady-state difference between the control and experimental groups.

Chaos Engineering Scenarios in Kubernetes:

Chaos Engineering in Kubernetes involves deliberately introducing failures into the system to observe how it behaves and recovers. This proactive approach enables teams to understand the system’s response to unexpected disruptions, whether it’s a pod failure, network latency, or a node shutdown.

**Implementing Chaos Experiments in Kubernetes**

To harness the full potential of Chaos Engineering, it’s essential to implement chaos experiments thoughtfully. Start by identifying critical components of your Kubernetes cluster that need testing. Tools like LitmusChaos and Chaos Mesh provide a framework for defining and executing chaos experiments. These experiments simulate disruptions such as pod deletions, CPU stress, and network partitioning, allowing teams to evaluate system behavior and improve fault tolerance.

**Chaos Engineering Kubernetes**

1. Pod Failures: Simulating failures of individual pods within a Kubernetes cluster allows organizations to evaluate how the system responds to such events. By randomly terminating pods, Chaos Engineering can help ensure that the system can handle pod failures gracefully, redistributing workload and maintaining high availability.

2. Network Partitioning: Introducing network partitioning scenarios can help assess the resilience of a Kubernetes cluster. By isolating specific nodes or network segments, Chaos Engineering enables organizations to test how the group reacts to network disruptions and evaluate the effectiveness of load balancing and failover mechanisms.

3. Resource Starvation: Chaos Engineering can simulate resource scarcity scenarios by intentionally consuming excessive resources, such as CPU or memory, within a Kubernetes cluster. This allows organizations to identify potential performance bottlenecks and optimize resource allocation strategies.

Understanding GKE-Native Monitoring

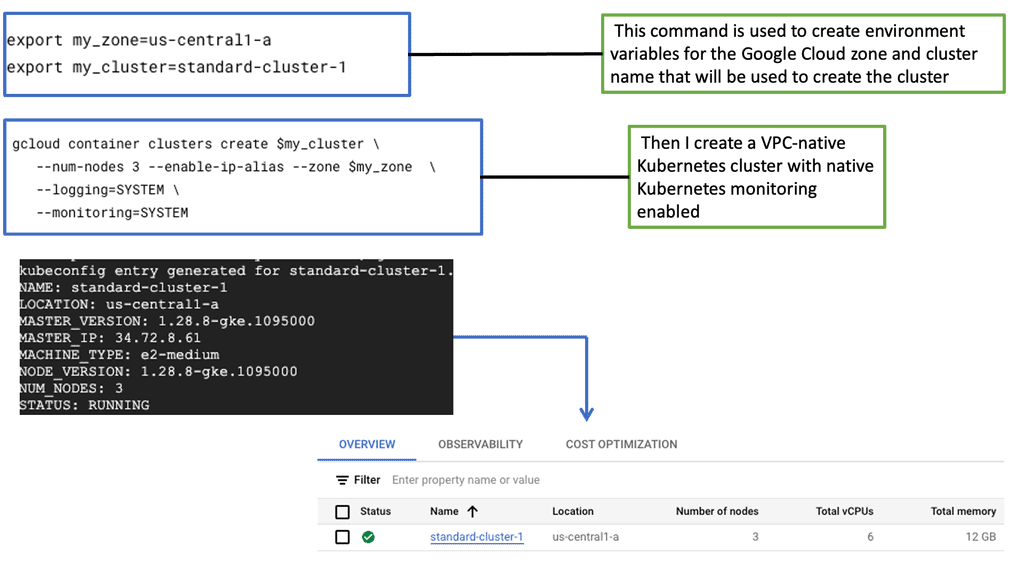
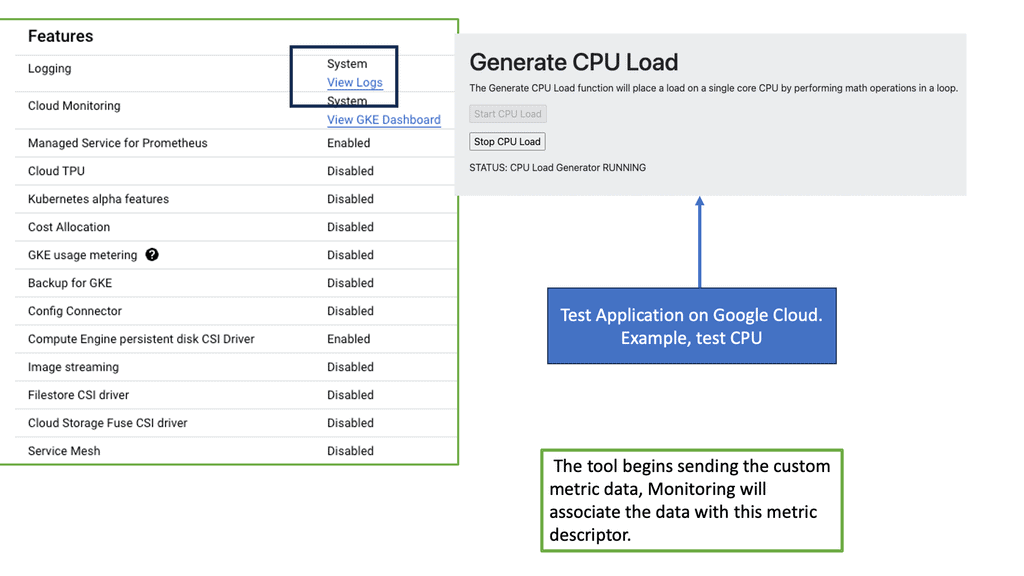
GKE-Native Monitoring is a comprehensive solution designed for Google Kubernetes Engine (GKE). It empowers developers and operators with real-time insights into the health and performance of their Kubernetes clusters, pods, and containers. Leveraging the power of Prometheus, GKE-Native Monitoring offers a wide range of monitoring metrics, such as CPU and memory utilization, network traffic, and custom application metrics.

GKE-Native Monitoring: Features

GKE-Native Monitoring boasts several key features that enhance observability and troubleshooting capabilities. One notable feature is the ability to create custom dashboards, enabling users to visualize and analyze critical metrics tailored to their needs. GKE-Native Monitoring integrates seamlessly with Stackdriver, Google Cloud’s unified monitoring and logging platform, allowing for centralized management and alerting across multiple GKE clusters.
The Rise of Chaos Engineering

Infrastructure is becoming increasingly complex, and let’s face it, a lot can go wrong. It’s imperative to have a global view of all the infrastructure components and a good understanding of the application’s performance and health. In a large-scale container-based application design, there are many moving pieces and parts, and trying to validate the health of each piece manually is hard. 

With these new environments, especially cloud-native at scale. Complexity is at its highest, and many more things can go wrong. For this reason, you must prepare as much as possible so the impact on users is minimal.

So, the dynamic deployment patterns you get with frameworks with Kubernetes allow you to build better applications. But you need to be able to examine the environment and see if it is working as expected. Most importantly, this course’s focus is that to prepare effectively, you need to implement a solid strategy for monitoring in production environments.

Chaos Engineering Kubernetes

For this, you need to understand practices and tools like Chaos Engineering and how they can improve the reliability of the overall system. Chaos Engineering is the ability to perform tests in a controlled way. Essentially, we intentionally break things to learn how to build more resilient systems.

So, we are injecting faults in a controlled way to make the overall application more resilient by injecting various issues and faults. It comes down to a trade-off and your willingness to accept it. There is a considerable trade-off with distributed computing. You have to monitor efficiently, have performance management, and, more importantly, accurately test the distributed system in a controlled manner. 

Service Mesh Chaos Engineering

 Service Mesh is an option to use to implement Chaos Engineering. You can also implement Chaos Engineering with Chaos Mesh, a cloud-native Chaos Engineering platform that orchestrates tests in the Kubernetes environment. The Chaos Mesh project offers a rich selection of experiment types. Here are the choices, such as the POD lifecycle test, network test, Linux kernel, I/O test, and many other stress tests.

Implementing practices like Chaos Engineering will help you understand and manage unexpected failures and performance degradation. The purpose of Chaos Engineering is to build more robust and resilient systems. 

Cloud Service Mesh:

### The Role of Cloud Service Mesh in Modern Architecture

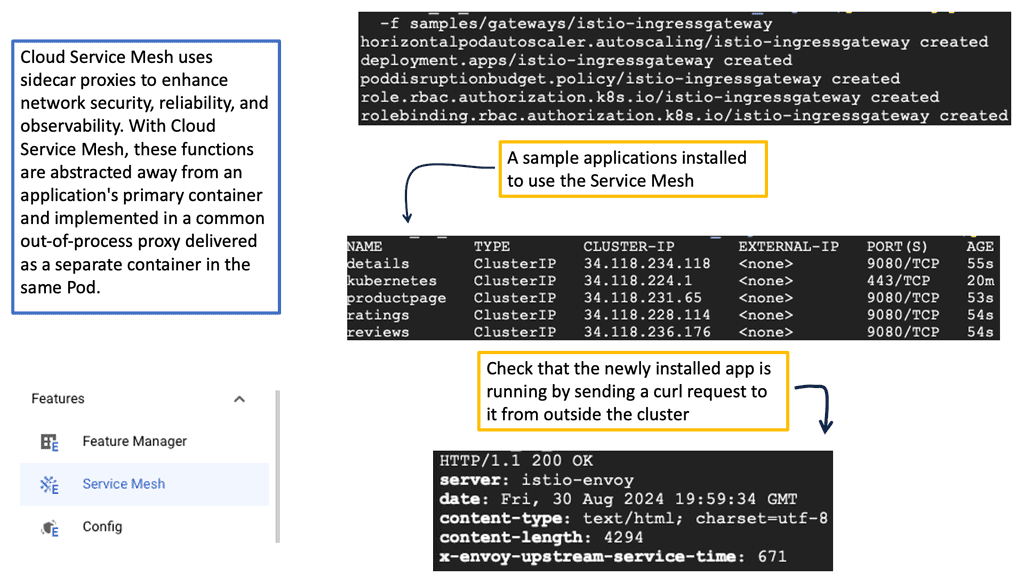
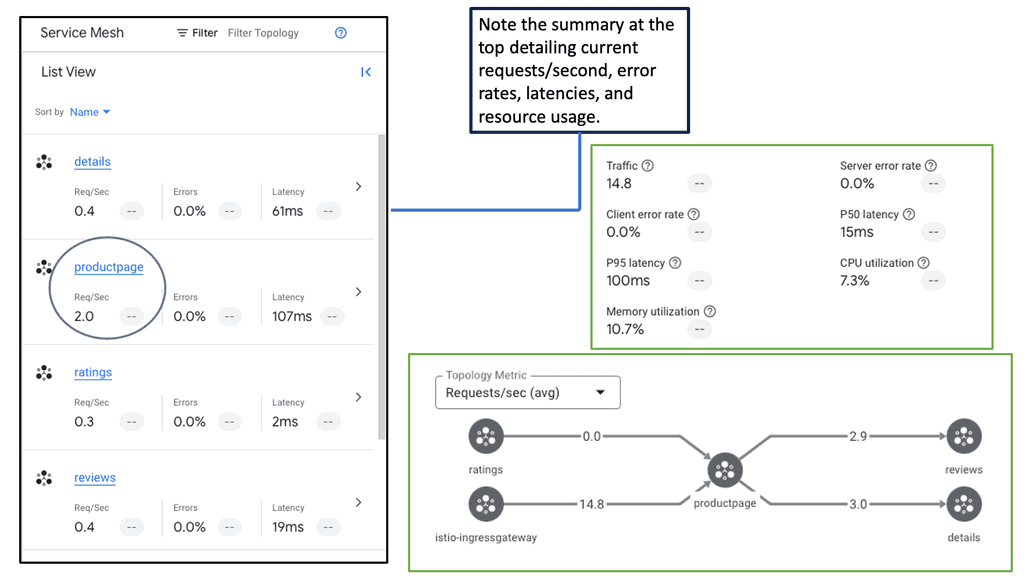
Traditional monolithic applications are being replaced by microservices architectures, which break down applications into smaller, independent services. While this shift offers numerous benefits such as scalability and flexibility, it also introduces complexities in managing the interactions between these services. This is where a Cloud Service Mesh comes into play. It provides a structured method to handle service discovery, load balancing, failure recovery, metrics, and monitoring without adding heavy burdens to the developers.

### Google’s Pioneering Efforts in Cloud Service Mesh

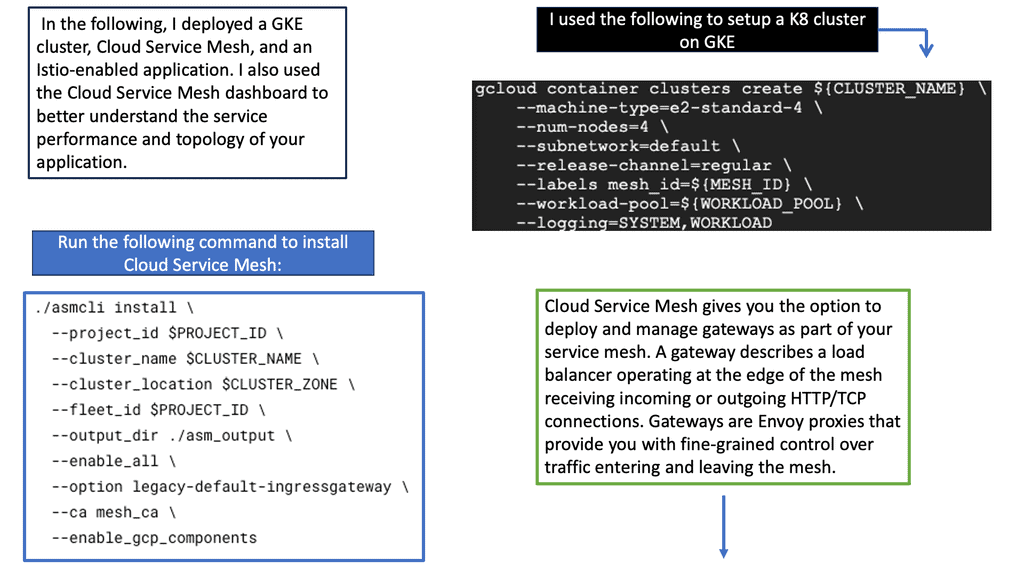
Google has been at the forefront of cloud innovation, and its contributions to the development of Cloud Service Mesh technologies are no exception. Through its open-source project Istio, Google has provided a robust framework for managing microservices.

Istio simplifies the observability, security, and management of microservices, making it easier for enterprises to adopt and scale their cloud-native applications. By integrating Istio with their Google Kubernetes Engine (GKE), Google has made it seamless for organizations to deploy and manage their service meshes.
### Enhancing Reliability with Chaos Engineering

One of the most intriguing aspects of utilizing a Cloud Service Mesh is its ability to enhance system reliability through Chaos Engineering. This practice involves intentionally injecting faults into the system to test its resilience and identify potential weaknesses.

By simulating real-world failures, organizations can better prepare for unexpected issues and ensure their services remain robust under pressure. The granular control provided by a Cloud Service Mesh makes it an ideal platform for implementing Chaos Engineering practices, helping to create more resilient and dependable cloud environments.
 

Interactive Chaos Engineering / Kubernetes Failure Lab

Kubernetes Failure Injection

Select a realistic failure scenario and trace what should happen next: failure injection, Kubernetes response, application impact and recovery. The goal is not to break Kubernetes randomly — it is to test a resilience hypothesis.

Selected Experiment
Pod Failure
Terminate one application pod and observe whether the Service continues directing traffic to healthy replicas while the Deployment recreates the failed workload.
◆
Application
→
×
Pod Fails
→
↻
Replica Recovery
→
✓
Service Restored
Failure Injected Application pod termination
Kubernetes Reaction Controller recreates the desired replica
What To Observe Endpoint health, pod readiness and request errors
Recovery Signal Healthy replica returns to service
Potential Impact: A correctly configured replicated application should experience little or no user-visible disruption.
Experiment Console
chaos-engineering / kubernetes
$ experiment --scenario pod-failure
[baseline] replicas=3 ready=3 error_rate=0.3%
[inject] terminating pod/frontend-7d8c9
[event] pod state=Terminating
[controller] desired replicas=3
[scheduler] replacement pod created
[recovery] replicas=3 ready=3
Experiment Complete
The simulated failure was introduced and the recovery path completed. Check whether the application remained inside its reliability objectives.
Engineering Takeaway: Each chaos experiment should connect a realistic failure to an expected Kubernetes response and a measurable recovery signal. The question is not simply “did something break?” — it is “did the platform and application recover the way we designed them to?”

Chaos Engineering Kuberentes

Monitoring & Troubleshooting 

Beyond the Complexity Horizon

Therefore, monitoring and troubleshooting are much more demanding, as everything is interconnected, making it difficult for a single person in one team to understand what is happening entirely. The edge of the network and application boundary surpasses one location and team. Enterprise systems have gone beyond the complexity horizon, and you can’t understand every bit of every single system.

Even if you are a developer closely related to the system and truly understand the nuts and bolts of the application and its code, no one can understand every bit of every single system.  So, finding the correct information is essential, but once you see it, you have to give it to those who can fix it. So monitoring is not just about finding out what is wrong; it needs to alert, and these alerts need to be actionable.

Troubleshooting: Chaos engineering kubernetes

– Chaos Engineering aims to improve a system’s reliability by ensuring it can withstand turbulent conditions. Chaos Engineering makes Kubernetes more secure. So, if you are adopting Kubernetes, you should adopt Chaos Engineering as an integral part of your monitoring and troubleshooting strategy.

– Firstly, we can pinpoint the application errors and understand, at best, how these errors arose. This could be anything from badly ordered scripts on a web page to a database query that has bad sequel calls or even unoptimized code-level issues.

– Or there could be something more fundamental going on. It is expected to have issues with how something is packaged into a container. You can pull in the incorrect libraries or even use a debug version of the container.

– Or there could be nothing wrong with the packaging and containerization of the container; it is all about where the container is being deployed. There could be something wrong with the infrastructure, either a physical or logical problem—incorrect configuration or a hardware fault somewhere in the application path.

**Non-ephemeral and ephemeral services**

With the introduction of containers and microservices observability, monitoring solutions need to manage non-ephemeral and ephemeral services. We are collecting data for applications that consist of many different benefits.

So when it comes to container monitoring and performing chaos engineering kubernetes tests, we need to understand the nature and the full application that lies upon it. Everything is dynamic by nature. It would be best if you had monitoring and troubleshooting in place that can handle the dynamic and transient nature. When monitoring a containerized infrastructure, you should consider the following.

A: Container Lifespan: Containers have a short lifespan; they are provisioned and commissioned based on demand. This is compared to VMs or bare-metal workloads, which generally have a longer lifespan. As a generic guideline, containers have an average lifespan of 2.5 days, while traditional and cloud-based VMs have an average lifespan of 23 days. Containers can move, and they do move frequently.

One day, we could have workload A on cluster host A, and the next day or even on the same day, the same cluster host could be hosting Application workload B. Therefore, different types of impacts could depend on the time of day.

B: Containers are Temporary: Containers are dynamically provisioned for specific use cases temporarily. For example, we could have a new container based on a specific image. New network connections, storage, and any integrations to other services that make the application work will be set up for that container. All of this is done dynamically and can be done temporarily.

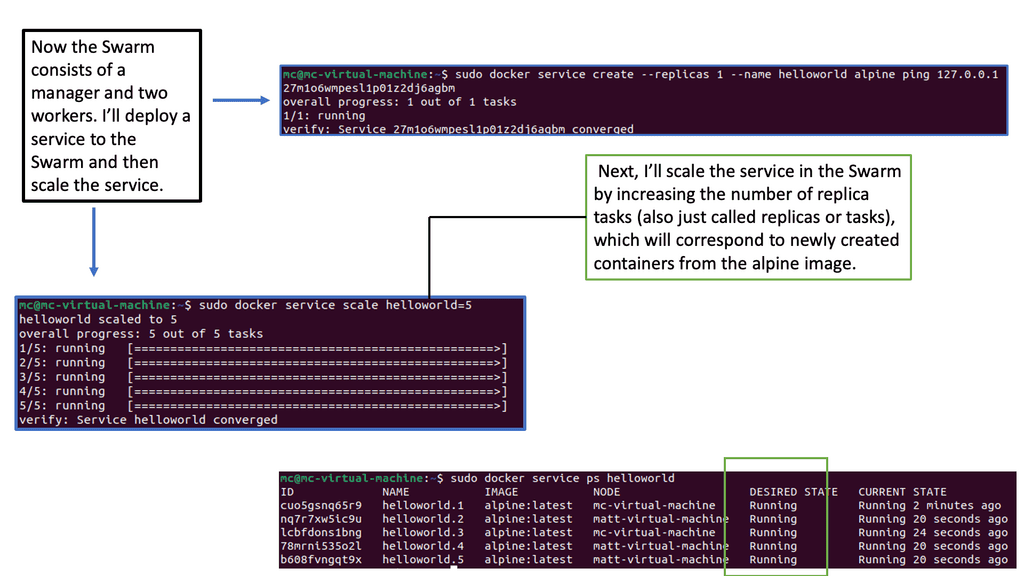
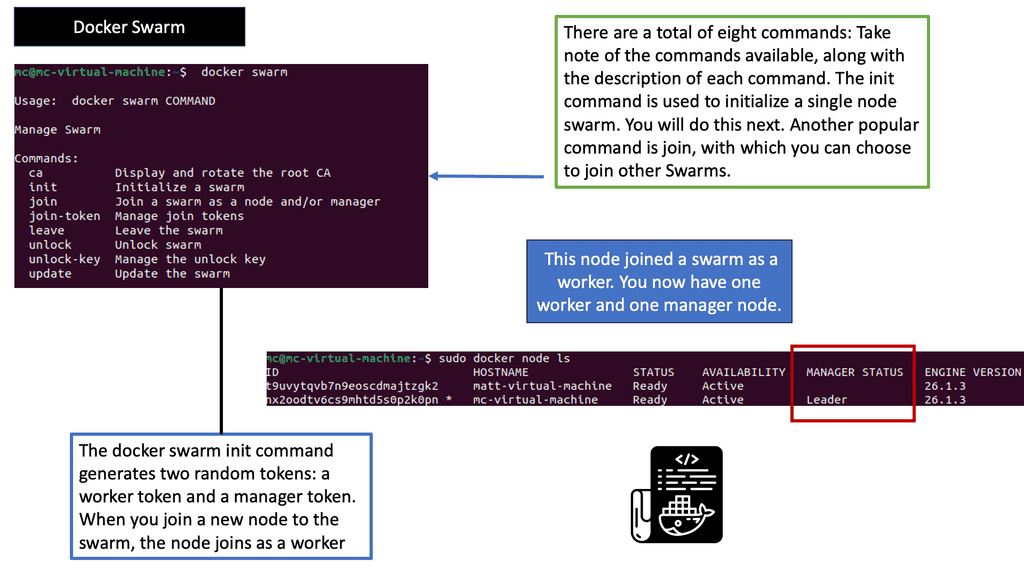
Example: Orchestration with Docker Swarm
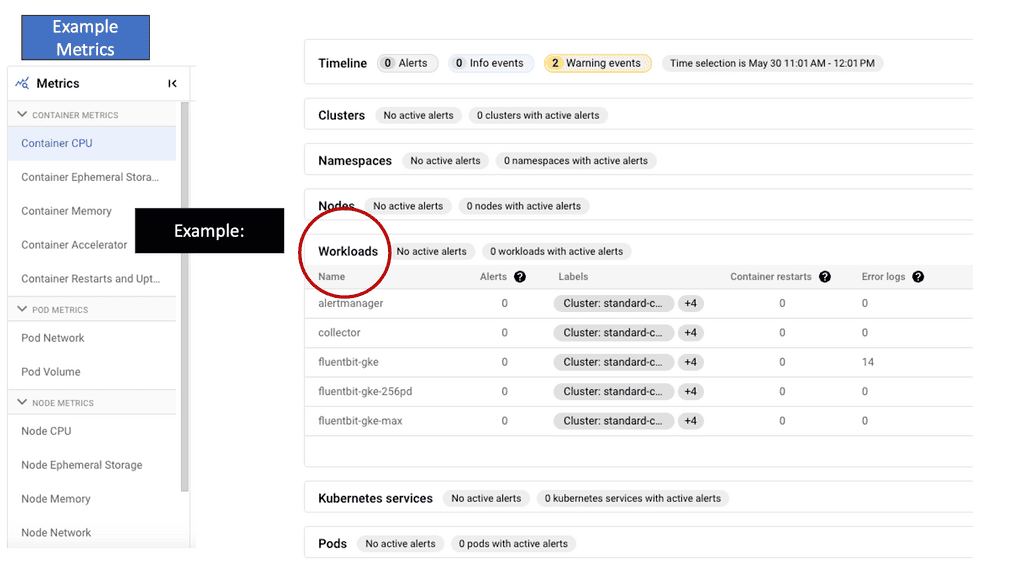
C: Different monitoring levels: In a Kubernetes environment, there are many monitoring levels. The components that make up the Kubernetes deployment will affect application performance. We have nodes, pods, and application containers. We also monitor at different levels, such as the VM, storage, and microservice levels.

D: Microservices change fast and often: Microservices consist of constantly evolving apps. New microservices are added, and existing ones are decommissioned quickly. So, what does this mean to usage patterns? This will result in different usage patterns on the infrastructure. If everything is often changing, it can be hard to derive the baseline and build a topology map unless you have something automatic in place. 

E: Metric overload: We now have loads of metrics, including additional metrics for the different containers and infrastructure levels. We must consider metrics for the nodes, cluster components, cluster add-on, application runtime, and custom application metrics. This is compared to a traditional application stack, where we use metrics for components such as the operating system and the application. 

Metric Explosion

Note: Prometheus Scrapping Metrics

In the traditional world, we didn’t have to be concerned with the additional components such as an orchestrator or the dynamic nature of many containers. With a container cluster, we must consider metrics from the operating system, application, orchestrator, and containers.  We refer to this as a metric explosion. So now we have loads of metrics that need to be gathered. There are also different ways to pull or scrape these metrics.

Prometheus is expected in the world of Kubernetes and uses a very scalable pull approach to getting those metrics from HTTP endpoints either through Prometheus client libraries or exports.
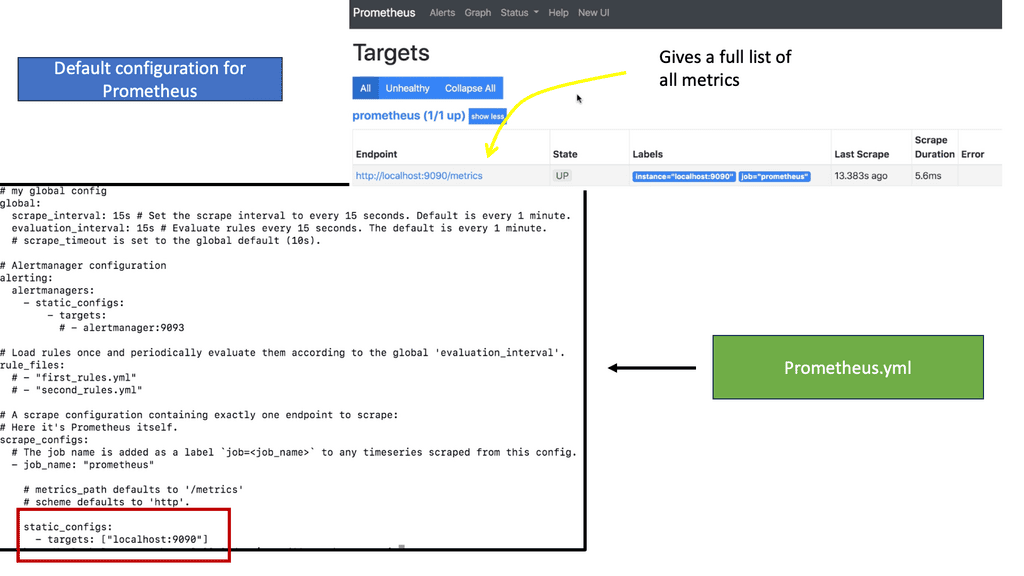
Prometheus YAML file
Diagram: Prometheus YAML file

**A key point: What happens to visibility**  

So, we need complete visibility now more than ever—not just for single components but visibility at a holistic level. Therefore, we need to monitor a lot more data points than we had to in the past. We need to monitor the application servers, Pods and containers, clusters running the containers, the network for service/pod/cluster communication, and the host OS.

All of the monitoring data needs to be in a central place so trends can be seen and different queries to the data can be acted on. Correlating local logs would be challenging in a sizeable multi-tier application with docker containers. We can use Log forwarders or Log shippers, such as FluentD or Logstash, to transform and ship logs to a backend such as Elasticsearch.

**A key point: New avenues for monitoring**

Containers are the norm for managing workloads and adapting quickly to new markets. Therefore, new avenues have opened up for monitoring these environments. So we have, for example, AppDynamics and Elastic search, which are part of the ELK stack, and the various log shippers that can be used to help you provide a welcome layer of unification. We also have Prometheus to get metrics. Keep in mind that Prometheus works only in the land of metrics. There will be different ways to visualize all this data, such as Grafana and Kibana. 

Distributed Systems Visbility

What happens to visibility? We need complete visibility now more than ever, not just for single components but at a holistic level. Therefore, we need to monitor a lot more data points than we had to in the past. We need to monitor the application servers, Pods and containers, clusters running the containers, the network for service/pod/cluster communication, and the host OS. 

All of the monitoring data needs to be in a central place so trends can be seen and different queries to the data can be acted on. Correlating local logs would be challenging in a sizeable multi-tier application with docker containers. We can use Logforwarders or Log shippers, such as FluentD or Logstash, to transform and ship logs to a backend such as Elasticsearch.

Containers are the norm for managing workloads and adapting quickly to new markets. Therefore, new avenues have opened up for monitoring these environments. So, I have mentioned AppDynamics, Elastic search, which is part of the ELK stack, and the various log shippers that can be used to help you provide a layer of unification. We also have Prometheus. There will be different ways to visualize all this data, such as Grafana and Kibana. 

A: – Microservices Complexity

With the wave towards microservices, we get the benefits of scalability and business continuity, but managing them is very complex. The monolith is much easier to manage and monitor. Also, as separate components, they don’t need to be written in the same language or toolkits, so you can mix and match different technologies.

This approach has a lot of flexibility, but we can increase latency and complexity. There are a lot more moving parts that will increase complexity.

We have, for example, reverse proxies, load balancers, firewalls, and other infrastructure support services. What used to be method calls or interprocess calls within the monolith host now go over the network and are susceptible to deviations in latency. 

B: – Debugging Microservices

With the monolith, the application is simply running in a single process, and it is relatively easy to debug. Many traditional tooling and code instrumentation technologies have been built, assuming you have the idea of a single process. However, with microservices, we have a completely different approach with a distributed application.

Now, your application has multiple processes running in other places. The core challenge is trying to debug microservices applications.

So much of the tooling we have today has been built for traditional monolithic applications. So, there are new monitoring tools for these new applications, but there is a steep learning curve and a high barrier to entry. New tools and technologies such as distributed tracing and chaos engineering kubernetes are not the simplest to pick up on day one.

C: – Automation and monitoring

Automation comes into play with the new environment. With automation, we can do periodic checks not just on the functionality of the underlying components but also implement health checks of how the application performs. All can be automated for specific intervals or in reaction to certain events.

With the rise of complex systems and microservices, it is more important to have real-time performance monitoring and metrics that tell you how the systems behave. For example, what is the usual RTT, and how long can transactions occur under normal conditions?
Interactive Chaos Engineering / Observability Lab

Observability & Resilience

A chaos experiment is only useful if you can prove what happened, where it happened, how the application responded, and whether the system recovered.

Select Incident
Kubernetes Service Path
User Request
→
Ingress Entry point
→
Service Discovery
→
Pods Failure target
→
Node Compute
→
Cluster Control plane
Observability Signal Matrix

Metrics

p99 142ms
errors 0.3%

Quantifies system behaviour and SLO impact.

Logs

request OK
pod Ready

Shows application and component-level evidence.

Traces

124ms total
service OK

Shows where request time or failure occurred.

Events

Normal
Ready

Provides Kubernetes lifecycle evidence.

SLO

99.98%
Healthy

Connects telemetry to user-facing reliability.

Incident Timeline BASELINE
00:00
Baseline established — application operating normally.
00:05
Observability signals are within expected thresholds.
Engineering Takeaway

Never treat a single dashboard metric as proof of recovery. Correlate metrics, logs, traces and Kubernetes events, then verify that the user-facing SLO has returned to its expected state.

kubernetes security best practice

Kubernetes Security Best Practice

Kubernetes Securtiy Best Practices

Kubernetes provides a powerful control plane for deploying and operating containerised workloads, but its flexibility also creates a broad security surface. A production cluster contains APIs, identities, workloads, container images, secrets, network paths, nodes, admission controls, and supporting infrastructure. Securing Kubernetes therefore requires controls across the entire application and platform lifecycle.

The objective is not simply to secure the Kubernetes API or restrict who can create pods. A mature Kubernetes security strategy should reduce unnecessary privileges, control what workloads can run, restrict communication, protect sensitive data, monitor activity, and provide mechanisms for detecting and responding to abnormal behaviour.

Identity and Least Privilege

The Kubernetes API is a critical security boundary. Access should be based on authenticated identities and carefully defined authorisation policies.

Role-Based Access Control (RBAC) should follow the principle of least privilege, giving users and service accounts only the permissions they require. Broad cluster-wide permissions should be avoided where namespace-level access is sufficient.

Service accounts also require careful management. Workloads should not automatically receive powerful credentials simply because they run inside the cluster.

Workload Security

Pods and containers should run with the minimum privileges required by the application. Security contexts can be used to control user and group IDs, privilege escalation, Linux capabilities, filesystem behaviour, and other runtime characteristics.

Privileged containers and unnecessary host access should be treated as high-risk configurations because they can significantly weaken workload isolation.

Where appropriate, organisations should use mechanisms such as Pod Security Standards and admission policies to prevent insecure workload configurations from being deployed in the first place.

Container Image and Supply Chain Security

Kubernetes security begins before a workload reaches the cluster.

Container images should originate from trusted registries and controlled build pipelines. Images should be scanned for known vulnerabilities, unnecessary packages should be removed, and image provenance should be established where possible.

Production deployments can use immutable image references or digests rather than relying solely on mutable tags. Image signing and verification can provide additional assurance that approved artifacts are being deployed.

Software supply-chain security should also consider dependencies, build systems, CI/CD credentials, source repositories, and the tools responsible for producing deployment artifacts.

Network Policies and Segmentation

Kubernetes networking can allow workloads to communicate broadly unless appropriate restrictions are implemented.

NetworkPolicy can be used to define which pods are permitted to communicate with other workloads and external destinations. A default-deny approach can provide a stronger starting point, with only required communication paths explicitly permitted.

Segmentation should be based on application architecture and trust relationships rather than simply treating the cluster as one trusted network.

Ingress and egress paths also require protection. Externally exposed services should use appropriate authentication, encryption, rate limiting, and application-layer security controls where required.

Secrets and Sensitive Data

Passwords, API keys, certificates, tokens, and other sensitive information should be handled carefully throughout the Kubernetes lifecycle.

Kubernetes Secrets provide a mechanism for distributing sensitive configuration, but they should not automatically be considered a complete secrets-management solution. Access permissions, encryption at rest, auditability, rotation, and integration with external secrets-management systems should be considered according to the sensitivity of the workload.

Credentials should also be prevented from appearing in container images, source repositories, configuration files, or application logs.

API and Control Plane Security

The Kubernetes API server is one of the most important security components in the platform. Authentication, authorisation, encryption, audit logging, network exposure, and secure configuration should all be carefully controlled.

The control plane should not be unnecessarily exposed to untrusted networks. Administrative access should use strong authentication and tightly controlled privileges.

Admission controls can provide another important enforcement layer by validating or rejecting workloads that violate organisational security policies before they are accepted by the cluster.

Node and Runtime Security

Kubernetes workloads ultimately execute on nodes, making node security an essential part of cluster security.

Nodes should be patched and hardened, unnecessary services should be removed, and access to the underlying operating system should be restricted. Container runtimes and supporting Kubernetes components should also be kept current.

A compromised node can potentially affect multiple workloads, so workload isolation, node segmentation, runtime protections, and rapid replacement mechanisms are important components of defence in depth.

Logging, Monitoring, and Auditing

Security controls need visibility to be effective.

Kubernetes audit logs can provide information about API activity, while application logs, container runtime events, node telemetry, network data, and security alerts can provide additional context.

Monitoring should look for behaviours such as unexpected privilege changes, unusual API activity, suspicious workload creation, abnormal network connections, failed authentication attempts, and unexpected changes to cluster configuration.

Centralised collection and correlation can help security teams distinguish isolated operational events from indicators of a broader compromise.

Patch and Vulnerability Management

Kubernetes environments contain multiple software layers, including the Kubernetes components themselves, operating systems, container runtimes, images, applications, libraries, and infrastructure integrations.

Security updates should therefore be treated as a continuous lifecycle process. Vulnerability management should identify affected components, prioritise risk, apply patches or rebuild images, and verify that remediation has been successful.

Security as a Continuous Process

Kubernetes security is not achieved through a single configuration setting. It is a layered operating model:

Secure Identity → Least Privilege → Trusted Images → Admission Controls → Isolated Networking → Protected Secrets → Hardened Nodes → Runtime Monitoring → Audit and Response

The strongest Kubernetes environments assume that credentials can be compromised, applications can contain vulnerabilities, and individual workloads can fail or become malicious.

The objective is therefore to limit what a compromised identity or workload can access, detect suspicious behaviour quickly, and provide reliable mechanisms for containment and recovery.

By treating Kubernetes security as a continuous combination of prevention, isolation, detection, and response, organisations can significantly reduce the potential impact of vulnerabilities while maintaining the flexibility that makes Kubernetes valuable for modern application platforms.

Interactive Kubernetes Security Lab

Kubernetes Security Posture Builder

Start with a weak Kubernetes security posture and progressively harden the cluster. Select controls across identity, workloads, network, supply chain and observability, then validate the resulting security posture.

Scenario

Harden a production Kubernetes cluster

The cluster is running workloads but several security controls are missing. Your objective is to reduce privilege, constrain workload behaviour, protect the supply chain and improve visibility.

12
Security Score / 100
CRITICAL POSTURE

Security controls

Select controls you would introduce as part of a layered Kubernetes security strategy.

Identity & Access
Workload & Runtime
Network Security
Supply Chain & Data
Observability

Posture analysis

The score is a teaching aid. Real Kubernetes risk depends on architecture, workload sensitivity, threat model and implementation.

Identity protection LOW
Workload isolation LOW
Network controls LOW
Supply chain LOW
Visibility LOW
# Hardened configuration summary
RBAC: not configured
networkPolicy: not configured
podSecurity: not configured
imageVerification: not configured
auditLogging: not configured
[READY] Kubernetes security posture assessment initialized
[INFO] Cluster contains multiple unprotected security boundaries
Engineering takeaway: Kubernetes security is layered. RBAC controls API permissions, Pod Security controls workload security requirements, NetworkPolicy controls permitted network communication, image controls address supply-chain risk, and audit logging provides visibility into activity. No single control provides complete protection.

Highlights: Kubernetes Securtiy Best Practices

The Move to the Cloud

– Cloud workloads are typically managed with Kubernetes as they move to the cloud. Kubernetes’ popularity can be attributed to its declarative nature: It abstracts infrastructure details and allows users to specify which workloads they want to run. App teams only need to set up configurations in Kubernetes to deploy their applications; they don’t need to worry about how workloads are deployed, where workloads run, or other details like networking.

– To achieve this abstraction, Kubernetes manages the creation, shutdown, and restart of workloads. As a typical implementation, workloads can be scheduled on any available network resource (physical host or virtual machine) based on their requirements. Kubernetes clusters consist of resources that run workloads.

– As needed, Kubernetes restarts unresponsive nodes based on the status of workloads (which are deployed as pods in Kubernetes). It also manages the network between pods and hosts and pod communication. Network plug-ins allow you to select the type of networking technology. Although the network plug-in has some configuration options, you cannot directly control networking behavior (either IP address assignment or scheduling).

An Orchestration Tool

Kubernetes has quickly become the de facto orchestration tool for deploying Kubernetes microservices and containers to the cloud. It offers a way of running groups of resources as a cluster and provides an entirely different abstraction level to single container deployments, allowing better management. From a developer’s perspective, it will enable the rolling out of new features that align with business demands while not worrying about the underlying infrastructure complexities.

Security Pitfalls: But there are pitfalls to consider when considering Kubernetes security best practices and Docker container security. Security teams must maintain the required visibility, compliance, and control, which is difficult because they do not control the underlying infrastructure. To help you on your security journey, you should introduce a chaos engineering project, specifically chaos engineering kubernetes.

This will help you find the breaking points and performance-related issues that may indirectly create security gaps in your Kubernetes cluster, making the cluster acceptable to Kubernetes attack vectors.

Kubernetes Security Best Practices

Kubernetes security is about protecting clusters, nodes, pods, containers, identities, and the control plane in a dynamic, distributed environment. Because Kubernetes is highly automated and highly scalable, misconfigurations can spread quickly — so security must be layered, enforced, and continuously verified.

Below is a clean, easy‑to‑copy, production‑grade breakdown you can drop directly into your notes, blog, or architecture docs.


1. Secure the Control Plane

  • API server hardening — restrict access, enforce RBAC, enable audit logs.

  • etcd encryption — encrypt secrets at rest.

  • TLS everywhere — secure all communication between components.

  • Network segmentation — isolate control plane from worker nodes.

The control plane is the brain — protect it first.


2. Identity & Access Security

  • RBAC — least‑privilege roles and role bindings.

  • Service Accounts — avoid using default service accounts.

  • OIDC integration — integrate with enterprise identity providers.

  • Pod Security Standards — enforce restricted policies.

Identity is the new perimeter.


3. Container & Runtime Security

  • Image scanning — scan images for CVEs before deployment.

  • Trusted registries — block untrusted sources.

  • Drop capabilities — remove unnecessary Linux capabilities.

  • Seccomp profiles — restrict dangerous syscalls.

  • AppArmor / SELinux — enforce mandatory access control.

  • Read‑only root filesystem — prevent tampering.

Containers must be locked down by default.


4. Network Security

  • NetworkPolicies — restrict pod‑to‑pod communication.

  • Service Mesh — mTLS, identity‑aware routing, policy enforcement.

  • Ingress security — TLS, WAF, rate limiting.

  • Egress control — restrict outbound traffic.

Kubernetes networking is open by default — close it.


5. Secrets & Config Security

  • Encrypt secrets at rest

  • Use external secret stores (Vault, AWS KMS, Azure Key Vault)

  • Avoid secrets in environment variables

  • Rotate secrets regularly

Secrets must never be treated as normal config.


6. Node & OS Security

  • Harden nodes — disable unused services, enforce firewall rules.

  • Use minimal OS images — reduce attack surface.

  • Keep nodes patched — automate updates.

  • Limit root access — protect kubelet and container runtime.

Nodes are the foundation — secure them aggressively.


7. Supply Chain Security

  • Image signing — verify trusted images (cosign, sigstore).

  • Admission controllers — block unsafe deployments.

  • Policy engines — enforce OPA Gatekeeper or Kyverno.

  • SBOMs — track dependencies and vulnerabilities.

Supply chain attacks are now the #1 cloud threat.


8. Observability & Runtime Monitoring

  • Audit logs — track API calls and changes.

  • Prometheus + Grafana — metrics and dashboards.

  • OpenTelemetry — traces and logs.

  • Falco — detect runtime anomalies.

  • Cluster health monitoring — detect drift and misconfigurations.

Visibility is mandatory for security.


Outcome

Kubernetes security best practices deliver:

  • hardened control plane

  • secure workloads and containers

  • strong identity enforcement

  • Zero Trust network segmentation

  • protected supply chain

  • continuous compliance

  • runtime threat detection

  • reliable, production‑grade cluster posture

Kubernetes becomes a secure, resilient, enterprise‑ready platform.

Before you proceed, you may find the following posts helpful:

  1. OpenShift SDN
  2. Hands On Kubernetes
  3. Kubernetes Network Namespace


Kubernetes Securtiy Best Practices

Incident Investigation

Kubernetes Attack Path Investigation Lab

A workload has been compromised. Investigate the evidence and reconstruct how an attacker could move from a compromised Pod toward Kubernetes API resources, secrets and other workloads.

Incident Scenario

Compromised workload detected

The application Pod is behaving suspiciously. Determine which security weaknesses contribute to the attack path. Select the evidence that should be investigated before drawing a conclusion.

Investigation evidence

Select the evidence you believe contributes to the attack path. Not every Kubernetes workload has every weakness.

Potential attack path

Your investigation should connect workload compromise with identity, authorization, API access and lateral movement.

Compromised Pod
↓
ServiceAccount Identity
↓
Kubernetes API Server
↓
Excessive RBAC Permissions
↓
Secrets / Workloads
↓
Lateral Movement
Workload UNDER INVESTIGATION
API Access UNKNOWN
Authorization UNKNOWN
Lateral Movement UNKNOWN
[READY] Incident investigation initialized
[INFO] Select evidence before running the investigation
Engineering takeaway: a Kubernetes ServiceAccount does not automatically have full API permissions. The security risk depends on the RBAC bindings assigned to that identity. Attackers often chain multiple weaknesses: workload compromise, excessive permissions, API access, secrets exposure and unrestricted network paths.

As workloads move to the cloud, Kubernetes is the most common orchestrator for managing them. Kubernetes’s popularity is due to its declarative nature: It abstracts infrastructure details and allows users to specify the workloads they want to run and the desired outcomes.

However, securing, observing, and troubleshooting containerized workloads on Kubernetes is challenging. It requires a range of considerations, from infrastructure choices and cluster configuration to deployment controls, runtime, and network security. Keep in mind that Kubernetes is not secure by default.

Kubernetes Architecture

Before we delve into some of Kubernetes’ security best practices and attack vectors, let’s recap Kubernetes Networking 101. Within Kubernetes, four common constructs will always be: pods, services, labels, and replication controllers. All constructs combine to create an entire application stack.

Pods

Pods are the smallest scheduling unit within a Kubernetes environment. They hold a set of closely related containers. Containers within a Pod share the same network namespace and must be installed on the same physical host. This enables processing locally without latency traversing from one physical host to another.

Labels

As I said, containers within a pod share the same network namespaces. As a result, the containers within a pod can reach each other’s ports on localhost. Therefore, we need to introduce a tagging mechanism known as labels. Labels offer another level of abstraction by tagging items as a group. They are essentially key-value pairs categorizing constructs. For example, labels distinguish containers as part of an application stack’s web or database tier.

Replication Controllers (RC)

Then, we have replication controllers. Their primary purpose is to manage the pods’ lifecycle and state by ensuring the desired state always matches the actual state. The replication controllers ensure the correct numbers are running by creating or removing pods at any time.

Services

Other standard Kubernetes components are services. Services represent groups of pods acting as one, allowing pods to access services in other pods without directing service-destined traffic to the pod IP. Pods are targeted by accessing a service that represents a group of pods. A service can be analogous to a load balancer in front of a pod accepting front-end service-destined traffic.

Kubernetes API server

Finally, the Kubernetes API server validates and configures data for the API objects, which include the constructs mentioned above—pods, services, and replication controllers, to name a few. Also, consider the practice of chaos engineering to understand your Kubernetes environment better and test for resilience and breaking points. Chaos engineering Kubernetes breaks your system to help you better understand it.

Listing Kubernetes Security Controls

  • Regularly Update Kubernetes:

Keeping your Kubernetes environment up to date is one of the fundamental aspects of maintaining a secure cluster. Regularly updating Kubernetes ensures you have the latest security patches and bug fixes, reducing the risk of potential vulnerabilities.

  • Enable RBAC (Role-Based Access Control):

Implementing Role-Based Access Control (RBAC) is crucial for controlling and restricting user access within your Kubernetes cluster. By assigning appropriate roles and permissions to users, you can ensure that only authorized personnel can perform specific operations, minimizing the chances of unauthorized access and potential security breaches.

  • Use Network Policies:

Kubernetes Network Policies allow you to define and enforce rules for network traffic within your cluster. Effectively utilizing network policies can isolate workloads, control ingress and egress traffic, and prevent unauthorized communication between pods. This helps reduce the attack surface and enhance the overall security posture of your Kubernetes environment.

  • Employ Pod Security Policies:

Pod Security Policies (PSPs) enable you to define security configurations and restrictions for pods running in your Kubernetes cluster. By defining PSPs, you can enforce policies like running pods with non-root users, disallowing privileged containers, and restricting host namespace sharing. These policies help prevent malicious activities and reduce the impact of potential security breaches.

  • Implement Image Security:

Ensuring the security of container images is crucial to protect your Kubernetes environment. Employing image scanning tools and registries that provide vulnerability assessments allows you to identify and address potential security issues within your images. Additionally, only using trusted and verified images from reputable sources reduces the risk of running compromised or malicious containers.

  • Monitor and Audit Cluster Activity:

Implementing robust monitoring and auditing mechanisms is essential for promptly detecting and responding to security incidents. By leveraging Kubernetes-native monitoring solutions, you can gain visibility into cluster activity, detect anomalies, and generate alerts for suspicious behavior. Furthermore, regularly reviewing audit logs helps identify potential security breaches and provides valuable insights for enhancing the security posture of your Kubernetes environment.

**Understanding GKE-Native Monitoring**

GKE-native monitoring provides a seamless and integrated way to collect, analyze, and visualize metrics and logs from your GKE clusters. By leveraging Google Cloud’s robust monitoring services like Stackdriver, GKE offers a comprehensive solution for monitoring the health and performance of your applications. With GKE-native monitoring, you gain valuable insights into resource utilization, latency, error rates, and more, enabling you to make data-driven decisions and ensure optimal performance.

Logging plays a crucial role in understanding your applications’ behavior and diagnosing issues. GKE-native logging allows you to capture and analyze logs from your GKE clusters effortlessly. With Stackdriver Logging, you can collect logs from various sources, including application logs, system logs, and even logs from managed services running on GKE. This unified logging platform provides powerful filtering, searching, and alerting capabilities, making troubleshooting issues easier and gaining deeper insights into your system.

Kubernetes Attack Vectors

The hot topic for security teams is improving Kubernetes security, implementing Kubernetes security best practices within the cluster, and making container networking deployments more secure. Kubernetes is a framework that provides infrastructure and features. However, thinking outside the box regarding Kubernetes’ best security practices would be best.

We are not saying that Kubernetes doesn’t have built-in security features to protect your application architecture! These include logging and monitoring, debugging and introspection, identity, and authorization. But ask yourself: Do these defaults cover all aspects of your security requirements? Remember that much of the complexity with Kubernetes can be abstract with OpenShift networking.

Traditional Security Constructs  

A: -) Traditional security constructs don’t work with containers, as we have seen with the introduction of Zero Trust Networking. Containers have a different security model as they are short-lived and immutable. For example, securing containers differs from securing a virtual machine (VM).

B: -) For one, the attack surface is smaller, as containers usually only live for about a week, as opposed to a VM that may stay online forever. As a result, we need to manage vulnerabilities and compliance throughout the container scheduler lifecycle—from build tools to image registries to production.

C: -) How do you measure security within a Kubernetes environment? No one can ever be 100% secure, but one should follow certain best practices to harden the gates against bad actors. You can have different levels of security within other parts of the Kubernetes domain. However, a general Kubernetes security best practice would be introducing as many layers of protection as possible between your Kubernetes environment and the bad actors to secure valuable company assets.

Hacker sophistication

Hackers are growing in sophistication. We started with script kiddies in the 1980s and are now entering a world of artificial intelligence ( AI ) and machine learning (ML) in the hands of bad actors. They have the tools to throw everything and anything at your Kubernetes environment, dynamically changing attack vectors on the fly. If you haven’t adequately secured the domain, once a bad actor gains access to your environment, they can move laterally throughout the application stack, silently accessing valuable assets.

Kubernetes Security Best Practice: Security 101

Now that you understand the most commonly used Kubernetes constructs let’s explore some of the best practices for central Kubernetes security and attack vectors.

**Kubernetes API**

Firstly, a bad actor can attack the Kubernetes API server to attack the cluster further. By design, each pod has a service account associated with it. The service account has full permissions and sufficient privileges to access the Kubernetes API server. A bad actor can get the token mounted in the pod and then use that token to gain access to the API server.

Unfortunately, once they can access the Kubernetes API server, they can get information, such as secrets, to compromise the cluster further. For example, a bad actor could access the database server where sensitive and regulatory data is held.

**Kubernetes API – Mitigate**

Another way to mitigate a Kubernetes API attack is to introduce role-based access control (RBAC). Essentially, RBAC gives rules to service accounts that can be assigned to the entire cluster. RBAC allows you to set permission on individual constructs such as pods and containers and then define rules based on personal use cases.

Another Kubernetes best practice would be to introduce an API server firewall. This firewall would work similarly to a standard firewall, where you can allow and block ranges of addresses. Essentially, this narrows the attack surface, hardening Kubernetes security.

**Secure pods with network policy**

Introducing ingress and egress network policies would allow you to block network access to certain pods. Only then can certain pods communicate with each other. For example, network policies can be set up to restrict the web front end from communicating directly to the database tier.

There is also a risk of a user implementing unsecured pods. In this case, you can have network policies in place so that if an unsecured pod does appear in the Kubernetes environment, the Kubernetes API will reject it.

Remember, left to its defaults, intra-cluster pod-to-pod communication is open. You may think a bad actor could sniff this traffic, but that’s harder to do than in everyday environments. A better strategy to harden Kubernetes security would be to use a network policy that only allows certain pods to communicate with each other.

**Container escape**

In the past, an unpatched kernel or a bug in the web front-end allowed a bad actor to exit a container and gain access to other containers or even to the Kubelet process itself. Once the bad actor gets access to the Kubelet client, it can access the API server, gaining a further foothold in the Kubernetes environment.

**Sandboxed Pods**

One way to mitigate a container escape would be to introduce sandboxed pods inside a lightweight VM. A sandboxed pod provides additional barriers to security as it lies above the kernel itself. Providing layers of protection above the kernel brings many Kubernetes security advantages. As the sandboxed pod runs inside a VM, an additional bug is required to break out of the container if there is a kernel exploit.

**Scanning containers**

For adequate Kubernetes security, you should know if your container image is vulnerable. Running containers with vulnerabilities exposes the entire system to attacks. Scanning all container images to discover and remove known vulnerabilities would be best. The scanning function should integrate runtime enforcement and remediation capabilities, enabling a secure and compliant SDLC (Software Development Life Cycle).

**Restrict access to Kubectl**

Kubectl is a powerful command-line interface for running commands against Kubernetes clusters. It allows you to create and update resources in a Kubernetes environment. Due to its potential, one should restrict access to this tool with firewall rules.

Disabling the Kubernetes dashboard is a must, as it has been part of some high-profile compromises. Previously, bad actors accessed a publicly unrestricted Kubernetes dashboard and privileged account credentials to access resources and mine cryptocurrency.

As Kubernetes adoption continues to grow, ensuring the security of your cluster becomes increasingly essential. By following these Kubernetes security best practices, you can establish a robust security foundation for your infrastructure and applications.

Regularly updating Kubernetes, enabling RBAC, utilizing network policies, employing pod security policies, implementing image security measures, and monitoring cluster activity will significantly enhance your security posture. Embracing these best practices will protect your organization’s sensitive data and provide peace of mind in today’s ever-evolving threat landscape.

Containment & Segmentation

Kubernetes Network & Runtime Segmentation Lab

A frontend Pod has been compromised. Build a least-privilege security boundary around the application so that the compromised workload cannot freely reach the API or database.

Application topology

Protect the application dependency chain

The intended application flow is Internet → Ingress → Frontend → API → Database. The objective is to permit required traffic while preventing unnecessary lateral movement.

Internet external
→
Ingress entry point
→
Frontend workload
→
API service
→
Database data tier

Required traffic policy

These are the intended application dependencies. Everything else should be treated as unnecessary unless explicitly required.

Internet → Ingress Public application entry
ALLOW
Ingress → Frontend Application frontend
ALLOW
Frontend → API Required application call
ALLOW
API → Database Required data access
ALLOW
Frontend → Database Bypass of API tier
DENY
Database → Internet Unnecessary egress
DENY
API → Internet Restrict unless required
DENY

Containment controls

Apply multiple layers. Network segmentation alone does not replace workload or identity security.

⚠ COMPROMISED FRONTEND

The attacker attempts to bypass the API tier and connect directly to the Database.

[READY] Segmentation lab initialized
[INFO] Frontend compromise is simulated
[INFO] Apply controls before running the attack test
Engineering takeaway: Kubernetes NetworkPolicy can restrict which Pods may communicate, but effective enforcement depends on the cluster's network plugin and policy configuration. Combine network controls with least-privilege RBAC, workload security, runtime restrictions and controlled egress to reduce lateral movement and blast radius.