Network Overlays: Building Virtual Networks Above the Physical Infrastructure
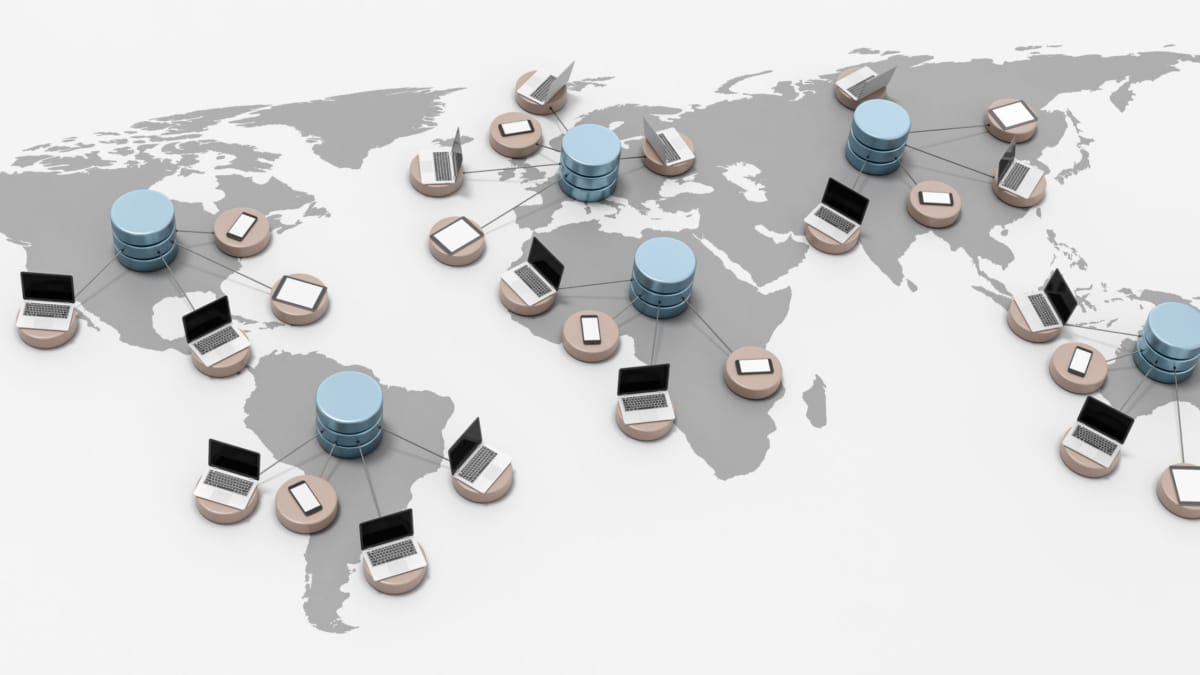
Modern networks are no longer defined exclusively by physical switches, routers, cables and geographical boundaries. Through network overlays, engineers can construct logical networks that operate across an existing physical infrastructure, enabling scalable connectivity, workload mobility, tenant isolation and programmable network services.
A network overlay is a logical network built on top of another network, commonly referred to as the underlay. Rather than requiring every virtual network to mirror the physical topology, overlay technologies use encapsulation, tunnel endpoints and forwarding information to create connectivity independently of the physical arrangement of devices.
Technologies such as VXLAN, GRE, Geneve, MPLS VPNs and IPsec-based tunnels demonstrate different approaches to network abstraction. Some extend Layer 2 connectivity across routed infrastructure. Others connect remote sites, provide virtual routing environments or protect traffic across untrusted networks.
Three Layers of Overlay Networking
Understanding how physical transport supports logical connectivity.
Physical Underlay
Routers, switches, physical links and IP routing provide reachability between overlay tunnel endpoints.
Overlay Transport
Tunnel mechanisms encapsulate original traffic inside transport packets that traverse the underlay network.
Logical Network
Virtual segments, tenant networks, routing domains and policies define application connectivity.
Why Network Overlays Became Essential
Traditional network architectures frequently connected applications to fixed physical locations and VLAN boundaries. As virtualisation, cloud computing and distributed applications expanded, these designs became increasingly difficult to scale.
Modern data centres require large numbers of isolated network segments, dynamic workload placement and efficient east-west communication. Overlay networking addresses these requirements by separating the logical connectivity model from the physical transport network.
Network Abstraction
Virtual networks can be created and modified without rebuilding the physical network topology.
Scalable Segmentation
Technologies such as VXLAN support large numbers of logical segments through 24-bit network identifiers.
Workload Mobility
Logical connectivity can follow workloads across compatible hosts, racks and network domains.
The Engineering Challenge: Two Connected Worlds
Although overlays simplify logical network provisioning, they introduce additional operational dependencies. Engineers must understand both the physical forwarding infrastructure and the logical forwarding information maintained by overlay endpoints.
For example, a VXLAN fabric may use an IP-routed Leaf-Spine underlay while BGP EVPN distributes endpoint reachability information across the overlay. The underlay determines how packets reach remote VTEPs, while EVPN provides the information needed to locate tenant endpoints and establish logical connectivity.
Network Engineering Insight
An overlay cannot operate independently of its transport network. A failure in underlay routing, an MTU mismatch, an incorrect VNI mapping or stale EVPN reachability information can disrupt application connectivity even when individual physical interfaces remain operational.
From Encapsulation to Intelligent Network Fabrics
The evolution of overlays extends beyond basic tunneling. Modern architectures combine encapsulation with distributed control planes, tenant-aware routing, policy enforcement and operational telemetry.
BGP EVPN, for example, can distribute MAC and IP reachability information between VTEPs, reducing dependence on traditional flood-and-learn behaviour. Meanwhile, network analytics can correlate tunnel performance, underlay path changes and endpoint mobility to help engineers identify faults that are difficult to observe from a single network layer.
The result is a programmable network fabric in which connectivity, segmentation and forwarding behaviour can be managed at a logical level while continuing to rely on a resilient physical transport foundation.
What You Will Explore in This Guide
This engineering guide moves from fundamental overlay concepts to practical architecture, troubleshooting and resilient network design.
Navigate the Network Overlay
Follow nine connected engineering stages, from understanding overlay fundamentals to designing a resilient EVPN fabric. Select any node to jump directly into its technical section.
Progress is recorded locally in this browser. Sections are marked as explored when selected or reached while reading.
Understanding Network Overlays
A network overlay creates a logical connectivity model above an existing physical network. Rather than requiring virtual network boundaries to follow the location of switches, routers and physical links, overlay networking allows engineers to construct virtual segments and routing domains across a shared transport infrastructure.
This separation between the logical network and the physical network is one of the foundations of modern data centre, cloud and enterprise network design. It allows multiple isolated environments to share the same infrastructure while maintaining independent forwarding information and network policies.
The essential concept is abstraction. A workload may appear to be directly connected to another workload within the same logical network even though its packets travel through several intermediate Layer 3 routers before reaching the destination.
Physical Underlay vs Logical Overlay
An overlay architecture contains two related forwarding environments. The underlay transports packets between network endpoints, while the overlay defines logical connectivity between workloads, sites or tenant networks.
Physical Underlay Network
The underlay provides the transport infrastructure required for tunnel endpoint reachability.
- Physical switches and routers
- IP addressing and routing
- OSPF, IS-IS, BGP or static routes
- ECMP and redundant transport paths
- Physical interface and link health
- MTU and transport performance
Logical Overlay Network
The overlay defines virtual connectivity and forwarding behaviour above the physical transport network.
- Virtual Layer 2 segments
- Virtual routing and forwarding domains
- VXLAN VNIs and tunnel endpoints
- Tenant-specific forwarding tables
- EVPN endpoint reachability
- Logical segmentation and policy
The two environments perform different tasks, but they are not operationally independent. Overlay packets still require a functioning underlay path between their tunnel endpoints. If the underlay loses reachability to a remote endpoint, the logical network using that endpoint can lose connectivity.
Visualising the Two Network Topologies
Consider two servers connected to different leaf switches in a routed data centre fabric. Each server belongs to the same logical VXLAN segment, identified by VNI 10010. The physical network transports encapsulated traffic between the two VXLAN Tunnel Endpoints (VTEPs).
Underlay and Overlay Architecture
One physical routed fabric supporting one logical tenant segment.
The dashed VXLAN connection is a logical relationship between VTEPs, not an additional physical cable. The actual encapsulated packets traverse whichever valid IP paths the underlay routing and forwarding mechanisms select.
Multiple overlay tunnels can share the same physical links, and multiple tenant networks can use the same VTEP infrastructure while remaining logically separated through their forwarding contexts and VNI mappings.
How an Overlay Packet Reaches Its Destination
The forwarding process illustrates why understanding both network layers is essential. When Host 1 sends traffic to Host 2, the ingress VTEP identifies the appropriate logical segment and remote destination VTEP.
Classify Traffic
The ingress VTEP identifies the tenant segment and forwarding context associated with the incoming frame.
Resolve Endpoint
The forwarding table identifies the remote VTEP responsible for the destination endpoint.
Encapsulate
The VTEP adds VXLAN, UDP and outer IP headers so the packet can cross the routed underlay.
Decapsulate
The destination VTEP removes the transport headers and forwards the original frame within the tenant segment.
In an EVPN-based design, BGP EVPN can distribute endpoint reachability information, including MAC addresses, IP addresses and associated VTEP information. In other overlay designs, endpoint discovery may rely on different mechanisms, including flood-and-learn, static configuration or controller-based distribution.
Layer 2 and Layer 3 Virtual Networks
Network overlays can provide different types of logical connectivity. Some emulate a shared Layer 2 broadcast domain, while others create independent Layer 3 routing environments. A modern fabric may support both models simultaneously.
Layer 2 Overlay
Extends an Ethernet segment across an IP network. VXLAN can transport Ethernet frames between remote VTEPs using a common Layer 2 VNI.
Layer 3 Overlay
Provides virtual routing domains with independent routing tables. VRFs and EVPN IP-VRF services support tenant-aware Layer 3 connectivity.
Integrated Fabric
Combines virtual Layer 2 segments with distributed Layer 3 routing, allowing local bridging and inter-subnet forwarding within a common fabric architecture.
These logical services should not be confused with physical isolation. Multiple tenants may share the same switching hardware, routing infrastructure and physical interfaces. Their separation depends on correctly implemented forwarding contexts, VNI mappings, routing policies and security controls.
Why Overlay Abstraction Does Not Mean Independence
The logical topology can remain stable even when the physical forwarding path changes. For example, an ECMP-enabled underlay may select an alternative spine path after a link failure without requiring the tenant network to change its addressing or logical segment configuration.
However, this flexibility introduces dependencies between the underlay routing system and the overlay forwarding system. A healthy BGP EVPN session does not necessarily guarantee that encapsulated packets can reach a remote VTEP. Similarly, successful IP reachability between VTEPs does not prove that the correct tenant VNI or endpoint mapping exists.
Engineering Insight: Two Views of Reachability
When troubleshooting an overlay, distinguish between transport reachability and tenant reachability. The underlay must deliver packets to the remote tunnel endpoint, while the overlay must correctly identify the tenant segment and destination endpoint. Both conditions are required for successful end-to-end forwarding.
Engineering Checks Before Deploying an Overlay
Before introducing overlay services, engineers should verify that the physical infrastructure can support the additional transport requirements and that the logical forwarding model is clearly defined.
Overlay Architecture Validation
Section 1 — Key Engineering Takeaway
A network overlay separates logical connectivity from physical topology, but it does not eliminate the underlying network dependencies. Reliable overlay design requires engineers to understand how tunnel encapsulation, endpoint reachability, virtual forwarding tables and physical routing work together. The overlay provides abstraction; the underlay provides transport.
Underlay vs Overlay Topology Explorer
Explore the difference between physical transport and logical network connectivity. Switch views, inspect network devices, trace a packet and simulate an underlay link failure.
Packet Journey
Ready to traceSource Host
Host A sends an Ethernet frame.
Ingress VTEP
VTEP A maps the frame to VNI 10100.
Underlay
The encapsulated packet crosses R1 or R2.
Egress VTEP
VTEP B removes the VXLAN encapsulation.
Destination
Host B receives the original frame.
Engineering Concept
Underlay: the routed IP network provides reachability between VTEP addresses. Overlay: VXLAN provides logical Layer 2 connectivity between the two hosts, independently of the physical transit topology. The overlay still relies on a functioning underlay.
Tunneling and Encapsulation
Tunneling is the mechanism that allows one network protocol or logical network to traverse another network infrastructure. By wrapping an original packet or frame inside additional transport headers, an overlay can carry traffic between endpoints without requiring the intermediate network to understand the original payload.
This process is known as encapsulation. At the source tunnel endpoint, the original traffic is packaged inside a new transport format. The intermediate network forwards the resulting outer packet according to its own routing and forwarding information. At the destination tunnel endpoint, the additional headers are removed through decapsulation.
Encapsulation is fundamental to technologies such as GRE, VXLAN, Geneve, IP-in-IP and IPsec tunnel mode. Although these technologies use different packet formats and provide different capabilities, they share the general principle of transporting one communication context through another.
Three Essential Encapsulation Concepts
Original Payload
The packet or Ethernet frame generated by the source endpoint. It contains the original addressing and protocol information required by the communicating systems.
Outer Transport Header
Additional protocol headers identify the tunnel endpoints and allow the encapsulated traffic to traverse the physical underlay network.
Decapsulation
The receiving tunnel endpoint removes the outer encapsulation, validates the relevant tunnel context and forwards the original traffic toward its intended destination.
Inside a VXLAN-Encapsulated Packet
VXLAN provides a useful example because it transports an original Ethernet frame across an IP-routed underlay. The ingress VTEP adds a VXLAN header, a UDP header and an outer IP header. An outer Ethernet header is also present when the encapsulated packet is transmitted over an Ethernet link.
The VXLAN header includes a 24-bit VXLAN Network Identifier (VNI), allowing the receiving VTEP to associate the packet with the correct logical network segment.
VXLAN Packet Encapsulation
Conceptual header structure from original Ethernet frame to outer transport.
Simplified illustration of an Ethernet frame carrying an IP packet. VXLAN can also transport other Ethernet payload types.
What Happens at the Tunnel Endpoints?
The intermediate routers in a typical IP underlay do not need to inspect the inner tenant Ethernet frame. They forward the encapsulated packet using the destination address in the outer IP header. This allows tenant traffic to traverse an infrastructure that has no direct knowledge of the tenant's Layer 2 topology.
Ingress Classification
The source tunnel endpoint determines the correct logical segment, tunnel context and remote destination.
Header Construction
The original traffic is encapsulated with the required tunnel and outer transport protocol headers.
Underlay Forwarding
Intermediate routers forward using the outer destination IP address and their normal routing tables.
Egress Processing
The destination tunnel endpoint removes the encapsulation and forwards traffic within the appropriate logical network.
GRE, VXLAN and Geneve: Different Encapsulation Models
Not every tunnel carries the same type of payload or serves the same architectural purpose. GRE is a general-purpose tunneling mechanism, VXLAN is commonly used for Ethernet network virtualisation, and Geneve provides an extensible encapsulation format for network virtualisation.
| Technology | Encapsulation | Typical Application | Important Consideration |
|---|---|---|---|
| GRE | GRE over IP | Point-to-point tunnels, routing overlays and multiprotocol transport | No native encryption or authentication |
| VXLAN | Ethernet over VXLAN, UDP and IP | Data centre Layer 2 overlays and EVPN fabrics | VNI mapping, MTU and VTEP reachability |
| Geneve | Geneve over UDP/IP | Extensible virtual networking and software-defined fabrics | Variable-length options and implementation support |
| IP-in-IP | IP packet inside another IP packet | IP network tunneling and protocol transition | Additional IP header and tunnel endpoint configuration |
| IPsec Tunnel Mode | Protected inner IP packet with outer transport addressing | Site-to-site VPNs and secure transport | Security associations, cryptographic processing and MTU overhead |
These technologies should not be treated as interchangeable. For example, GRE can carry multicast routing traffic across a unicast IP network, while VXLAN carries Ethernet frames associated with virtual network segments.
VXLAN commonly uses UDP destination port 4789. The UDP source port may be derived from packet information to provide entropy for ECMP load distribution across the underlay fabric.
Encapsulation Overhead and MTU
Every additional transport header increases the size of the packet transmitted across the underlay. Engineers must account for this overhead when designing tunnel interfaces, physical links and network paths.
For a typical VXLAN packet using IPv4 transport over Ethernet, the encapsulation adds 50 bytes relative to the original Ethernet frame, excluding the outer Ethernet header from that overhead calculation.
VXLAN MTU Engineering Example
A 1500-byte inner IP packet, carried inside an Ethernet frame, requires additional transport capacity when encapsulated with VXLAN.
Result: approximately 1550 bytes at the outer IP layer when carrying a full-sized 1500-byte inner IP packet over IPv4 VXLAN, assuming an untagged inner Ethernet frame. Outer Ethernet framing is additional.
Engineering Warning: MTU Mismatch
If the underlay cannot carry the encapsulated packet, traffic may be fragmented where permitted or dropped. Fragmentation behaviour depends on the outer IP version, DF settings and device implementation. A tunnel may appear operational while larger application packets fail. Validate the effective path MTU rather than assuming tunnel reachability proves data-plane health.
GRE Encapsulation and Multiprotocol Transport
Generic Routing Encapsulation provides a flexible way to carry different network-layer payloads through an IP transport network. A basic GRE tunnel adds a GRE header and an outer IP header around the original packet.
GRE is frequently associated with routed overlays because tunnel interfaces can behave like logical point-to-point links. Routing protocols such as OSPF or EIGRP can operate across appropriately configured GRE tunnels, enabling logical routing adjacencies between geographically separated devices.
Multipoint GRE extends this concept by allowing one tunnel interface to communicate with multiple remote endpoints. Technologies such as DMVPN combine multipoint GRE with NHRP and dynamic routing to support scalable hub-and-spoke and spoke-to-spoke communication.
Security Distinction: Tunneling Is Not Encryption
Encapsulation alone does not guarantee confidentiality or integrity. GRE and VXLAN do not provide encryption by default. IPsec can be used alongside appropriate tunneling technologies to protect traffic across untrusted networks. Tunnel reachability, tenant isolation and cryptographic protection are separate design considerations.
Decapsulation and Forwarding Context
Decapsulation is more than simply removing headers. The receiving endpoint must associate the incoming traffic with the correct logical forwarding environment.
In a VXLAN fabric, the receiving VTEP uses the VNI and its local configuration to determine the appropriate Layer 2 segment or forwarding context. In a routed overlay, the receiving tunnel endpoint may forward the decapsulated IP packet according to a routing table associated with the tunnel or virtual network.
Incorrect tunnel mappings, unexpected encapsulation formats or inconsistent endpoint configuration can therefore create traffic loss even when the underlay successfully delivers the outer packet.
Engineering Checks for Tunnel Troubleshooting
Encapsulation and Tunnel Validation
Packet captures taken at both the ingress and egress tunnel endpoints can be particularly valuable. Comparing the original packet with its encapsulated representation helps identify incorrect outer addressing, tunnel identifiers, unexpected fragmentation and forwarding-context mismatches.
Section 2 — Key Engineering Takeaway
Encapsulation enables logical connectivity across a physical network, but every tunnel introduces transport overhead and forwarding dependencies. Successful overlay communication requires correct encapsulation, underlay reachability, appropriate MTU capacity and accurate decapsulation at the destination. Engineers must validate both the outer transport packet and the original inner traffic.
Packet Encapsulation and Tunnel Explorer
Construct an encapsulated packet, inspect its headers, calculate transport overhead and investigate how MTU and Path MTU Discovery affect overlay forwarding.
Inside the Encapsulated Packet
Select a protocol, then press Encapsulate Packet. Click any header to inspect its purpose and size.
Tenant traffic enters the tunnel endpoint.
New transport headers are added.
The underlay routes the outer packet.
The destination recovers the original frame.
MTU and Encapsulation Overhead Calculator
Change the tenant IP packet size, underlay IP MTU and outer IP version. The calculator determines whether the encapsulated packet fits the transport.
From Tenant Host to Remote VTEP
Engineering Concept
Encapsulation allows the underlay to forward packets using outer IP addresses while preserving the original tenant traffic inside the tunnel. The additional headers increase packet size and must be accounted for in MTU design.
Overlay Technologies Compared
Network overlays are not implemented through a single protocol or architectural model. Different technologies provide different combinations of tunneling, virtualisation, routing, segmentation and security. Selecting the correct approach requires understanding what each technology encapsulates, how forwarding information is distributed and which network requirements it is designed to satisfy.
Technologies such as GRE, VXLAN, NVGRE, Geneve, MPLS VPNs and IPsec all support forms of logical connectivity across a transport infrastructure. However, their operational characteristics differ significantly. Some provide simple point-to-point tunneling, while others support large-scale multi-tenant fabrics or encrypted communication across untrusted networks.
The key engineering distinction is that encapsulation, endpoint discovery, routing control and encryption are separate architectural functions. A protocol may provide one of these capabilities without providing the others.
Six Important Overlay Technology Families
Generic Routing Encapsulation
GRE creates logical tunnels across IP networks and supports the transport of multiple protocol types. It is commonly used for routed overlays, point-to-point connectivity and multipoint GRE architectures.
General-purpose tunnelingVXLAN
Virtual Extensible LAN encapsulates Ethernet frames inside UDP/IP packets. Its 24-bit VNI supports large-scale logical segmentation across routed data centre fabrics.
Data centre virtualisationNVGRE
Network Virtualization using GRE extends Ethernet connectivity over IP transport using a GRE-based encapsulation and a virtual subnet identifier for tenant separation.
GRE-based virtual networksGeneve
Generic Network Virtualization Encapsulation provides a flexible UDP-based tunneling format with extensible metadata options for software-defined networking.
Extensible network virtualisationMPLS VPNs
MPLS-based VPN architectures use labels and service-specific forwarding information to deliver Layer 2 and Layer 3 virtual network services across a provider transport network.
Service provider VPN servicesIPsec
IPsec provides cryptographic protection for IP traffic. Tunnel mode can carry protected IP packets between security gateways or other endpoints across untrusted networks.
Secure IP transportThree Different Overlay Architecture Models
Overlay technologies can be understood by examining the forwarding model they create. The following examples illustrate general-purpose tunneling, Ethernet virtualisation and provider VPN services.
Comparing Overlay Forwarding Models
Similar abstraction principle, different forwarding mechanisms.
GRE Routed Tunnel
A logical tunnel interface connects two routers across an intermediate IP network.
VXLAN Fabric
Two VTEPs transport tenant Ethernet frames across a routed IP fabric using VNIs.
MPLS VPN Service
Provider edge routers maintain VPN service state while the transport core forwards labelled packets.
In a GRE design, tunnel interfaces often participate directly in the routing topology. In a VXLAN fabric, VTEPs map Ethernet segments to VNIs and transport frames between remote endpoints. In MPLS VPN services, provider edge routers maintain customer-specific forwarding state while the core transports traffic using label-based forwarding.
Detailed Overlay Technology Comparison
A technology comparison must consider more than packet encapsulation. Engineers should examine the service model, control-plane architecture, security properties and operational dependencies before choosing a deployment approach.
| Technology | Transport Format | Logical Service | Control Plane | Native Encryption |
|---|---|---|---|---|
| GRE | GRE over IP | Multiprotocol tunneling and logical routed links | Static configuration or separate routing protocols | No |
| VXLAN | Ethernet over VXLAN/UDP/IP | Virtual Layer 2 segments and fabric services | Flood-and-learn, BGP EVPN or controller | No |
| NVGRE | Ethernet over GRE/IP | Virtual Ethernet tenant networks | Controller or implementation-specific endpoint distribution | No |
| Geneve | Geneve over UDP/IP | Extensible virtual networking | External controller or other control plane | No |
| MPLS VPN | MPLS label stack | Layer 2 VPN and Layer 3 VPN services | BGP VPN signaling with an MPLS transport control plane | No |
| IPsec | ESP over IP, optionally UDP-encapsulated | Protected IP communication | IKE or configured security associations | Yes, when encryption is negotiated/configured |
The control-plane column describes common deployment models rather than mandatory requirements for every implementation. For example, VXLAN defines an encapsulation format but does not itself require BGP EVPN. EVPN is a control-plane solution that can distribute endpoint reachability and service information for VXLAN fabrics.
VXLAN and NVGRE: Two Virtualisation Approaches
VXLAN and NVGRE were developed to address the limitations of traditional VLAN-based segmentation in large virtualised environments. Both support a significantly larger logical network identifier space than the 12-bit VLAN identifier.
VXLAN uses a 24-bit VNI inside a UDP-based encapsulation. NVGRE uses a 24-bit Virtual Subnet ID carried in a GRE key field. Both approaches can represent approximately 16 million identifier values, although actual supported tenant scale depends on hardware, software and control-plane limits.
VXLAN's UDP encapsulation is particularly useful in routed fabrics because a varying UDP source port can provide entropy for ECMP hashing. NVGRE uses a different encapsulation structure, so forwarding and load-distribution behaviour depend on the network devices and their ability to inspect or hash GRE traffic.
Geneve: Extensible Overlay Encapsulation
Geneve was designed to provide a flexible network virtualisation encapsulation format. Like VXLAN, it uses UDP/IP transport, but it includes an extensible options mechanism that can carry additional metadata.
This flexibility is useful in software-defined networking environments where virtual switching systems, hypervisors and network services may need to exchange contextual information.
However, extensibility introduces implementation considerations. Devices must correctly process supported options, and variable header lengths affect packet overhead and MTU planning. Hardware offload capabilities should also be validated.
MPLS VPNs: Virtual Networks in Provider Fabrics
MPLS VPNs use a different transport approach from UDP/IP overlay encapsulations. Instead of identifying a virtual segment through a VXLAN header, MPLS forwarding relies on labels associated with transport paths and service forwarding contexts.
In a typical MPLS Layer 3 VPN, provider edge routers maintain customer-specific VRFs and exchange VPN reachability using multiprotocol BGP. The provider core can forward labelled traffic without maintaining every customer route in its global routing table.
MPLS also supports Layer 2 services, including pseudowires and EVPN-based services. Importantly, EVPN is not exclusive to VXLAN: it can provide service signaling for different data-plane encapsulations, including MPLS and VXLAN.
Engineering Insight: EVPN Is a Control Plane
VXLAN and EVPN are not the same technology. VXLAN defines a data-plane encapsulation mechanism. BGP EVPN distributes reachability and service information between participating network devices. Understanding this separation is essential when diagnosing a fabric where BGP sessions are established but tenant traffic is not forwarding.
IPsec: Adding Cryptographic Protection
IPsec addresses a different requirement from most basic overlay encapsulations: protecting IP traffic against unauthorised observation and modification.
IPsec ESP can provide confidentiality, integrity and data-origin authentication, depending on the negotiated algorithms and security association configuration. IPsec tunnel mode protects an inner IP packet while providing outer addressing for transport.
GRE and IPsec can be combined when an architecture requires GRE's tunneling capabilities alongside cryptographic protection. This is particularly relevant to routed WAN overlays and traditional enterprise VPN designs.
Security Warning: Isolation Is Not Encryption
A tenant VNI, VRF or MPLS VPN forwarding context provides logical separation, but it does not automatically encrypt traffic. Security requirements must separately address endpoint authentication, encryption, policy enforcement and protection against misconfiguration or unauthorised tunnel endpoints.
Choosing the Right Overlay Technology
Technology selection should begin with the network service requirement rather than the encapsulation protocol. A distributed data centre, a service provider VPN and a branch-office WAN have different operational requirements.
Multi-Tenant Data Centre
Typical choice: VXLAN with BGP EVPN. This supports scalable Layer 2 segmentation, distributed endpoint learning and integrated Layer 3 tenant services across a routed fabric.
Enterprise Routed Overlay
Typical choice: GRE or multipoint GRE, potentially protected by IPsec. These designs support logical routed connectivity across intermediate transport networks.
Service Provider VPN
Typical choice: MPLS L3VPN, L2VPN or EVPN-based services. These architectures support customer-specific forwarding contexts across provider networks.
Cloud and Virtual Switching
Possible choice: Geneve or VXLAN, depending on platform support. The selected technology must integrate with the virtual switching environment, orchestration and network policy model.
Four Questions Before Selecting an Overlay
Engineering Decision Framework
A structured selection process helps avoid choosing a technology based solely on popularity or familiarity.
What Is the Service?
Layer 2 extension, Layer 3 VPN, routed tunneling or encrypted transport?
How Is State Learned?
Static configuration, BGP EVPN, routing protocols or an external controller?
What Must Scale?
Tenants, endpoints, routes, tunnel relationships or forwarding entries?
What Must Be Protected?
Tenant isolation, traffic confidentiality, endpoint trust or service availability?
Operational Trade-Offs and Design Constraints
Overlay networking introduces additional state and packet processing. Each technology must be evaluated against the capabilities of the physical and virtual forwarding platforms.
Important considerations include tunnel scale, encapsulation overhead, hardware acceleration, ECMP hashing, control-plane convergence, operational visibility and failure isolation.
A design that works correctly in a small laboratory may behave differently when deployed across thousands of endpoints or hundreds of virtual routing domains. Scale testing and failure validation are therefore essential parts of overlay architecture.
Overlay Technology Selection Checklist
Section 3 — Key Engineering Takeaway
Overlay technologies solve different networking problems, even when they share the general principle of logical connectivity over physical transport. GRE provides flexible tunneling, VXLAN and Geneve support network virtualisation, MPLS VPNs provide labelled virtual network services, and IPsec protects IP traffic. Successful design requires matching the technology's forwarding model, control plane and security properties to the actual service requirements.
Overlay Technology Architecture Explorer
Compare five overlay and tunneling technologies, inspect how their forwarding models differ, follow a packet journey and evaluate which architecture fits a real network design requirement.
GRE Tunnel Architecture
GRE — Generic Routing Encapsulation
GRE provides a point-to-point tunnel across an IP network. The outer IP header carries the encapsulated traffic between tunnel endpoints, while intermediate routers forward according to the outer destination.
Follow the Packet Journey
Press Trace Packet to follow the selected technology's forwarding model.
Host sends traffic.
Tunnel endpoint encapsulates.
Core forwards the outer packet.
Remote endpoint decapsulates.
Host receives original traffic.
Technology Capability Matrix
Selecting a technology highlights its row. Compare encapsulation, segmentation, control-plane requirements and encryption.
| Technology | Primary role | Transport | Segmentation | Encryption |
|---|---|---|---|---|
| GRE | General-purpose tunnel | IP protocol 47 | Separate design | Not native |
| VXLAN | Layer 2 overlay | UDP 4789 | 24-bit VNI | Not native |
| NVGRE | Layer 2 virtualization | GRE / IP 47 | 24-bit VSID | Not native |
| MPLS L3VPN | Provider Layer 3 VPN | MPLS labels | VRF / route targets | Not native |
| IPsec | Secure IP transport | ESP / UDP 4500 | Policy / tunnel design | Yes, with ESP encryption |
Choose the Right Overlay Technology
Select a network requirement and evaluate the technology that best matches its forwarding, security and operational needs.
The recommendation will explain the technology choice and its limitations.
VXLAN and EVPN Fabric Architecture
VXLAN and BGP EVPN form one of the most widely adopted architectural combinations for modern data centre network virtualisation. VXLAN transports Ethernet traffic across an IP-routed infrastructure, while BGP EVPN distributes endpoint reachability and service information between participating network devices.
Together, these technologies allow a routed Leaf-Spine fabric to support logical Layer 2 segments, tenant-specific routing domains and distributed forwarding services without requiring the physical network to operate as one large Layer 2 topology.
The architecture separates three important functions: underlay transport, overlay control-plane distribution and VXLAN data-plane forwarding. Understanding how these functions interact is essential for both fabric design and troubleshooting.
The Three Architectural Layers
IP Underlay
A routed Leaf-Spine topology provides IP connectivity between VTEP addresses. Routing protocols such as OSPF, IS-IS or BGP can establish reachability across redundant physical paths.
BGP EVPN Control Plane
BGP EVPN distributes MAC, IP, inclusive multicast and IP-prefix reachability information. Route targets and service configuration determine which EVPN information belongs to each virtual network.
VXLAN Data Plane
VTEPs encapsulate tenant Ethernet frames using VXLAN over UDP/IP. The VNI identifies the logical forwarding segment, while outer IP addressing transports packets between VTEPs.
Visualising a VXLAN EVPN Leaf-Spine Fabric
In a typical design, leaf switches provide server attachment and VXLAN tunnel termination. Spine switches provide redundant IP forwarding paths and may also participate in the EVPN control plane as BGP route reflectors.
The example below uses three spines and two leaf VTEPs. Both attached hosts belong to the same Layer 2 virtual network, identified by VNI 10010.
VXLAN EVPN Fabric — Reference Architecture
IP underlay, BGP EVPN reachability and logical VXLAN connectivity.
The VXLAN tunnel is a logical relationship between VTEP A and VTEP B. Encapsulated packets travel through the IP underlay, potentially using different ECMP paths across the spine layer.
Spine 2 is shown as an EVPN route reflector. Its control-plane function is to distribute EVPN reachability information between BGP clients. It does not need to terminate the tenant VXLAN tunnel merely because it participates in EVPN route reflection.
Engineering Insight: Route Reflection vs Forwarding
A BGP EVPN route reflector distributes control-plane information but does not automatically become a data-plane forwarding hop for VXLAN traffic. The underlay independently determines how encapsulated packets reach the remote VTEP. Separating these roles helps prevent confusion when troubleshooting EVPN route propagation and VXLAN forwarding.
Understanding VTEPs, L2 VNIs and L3 VNIs
A VXLAN Tunnel Endpoint (VTEP) performs encapsulation and decapsulation. It maps local network attachments to virtual network identifiers and maintains forwarding information for remote endpoints.
In an EVPN VXLAN fabric, a Layer 2 VNI commonly identifies a bridge domain, while a Layer 3 VNI can identify the VXLAN context associated with an IP-VRF for routed tenant traffic. Exact forwarding behaviour depends on the chosen symmetric or asymmetric integrated routing and bridging model.
| Component | Purpose | Example | Engineering Dependency |
|---|---|---|---|
| VTEP | Encapsulates and decapsulates VXLAN traffic | 10.0.0.11 | Underlay IP reachability |
| L2 VNI | Identifies a logical Layer 2 segment | 10010 | VLAN/bridge-domain mapping |
| L3 VNI | Identifies a routed tenant VRF context | 50001 | VRF and routing configuration |
| Route Target | Controls EVPN route import and export | 65000:10010 | Consistent tenant policy |
| EVPN Next Hop | Identifies the BGP next-hop endpoint for reachability | 10.0.0.12 | Resolvable VTEP next hop |
These identifiers perform different functions. A VNI is carried in the VXLAN data-plane header, while a route target is a BGP extended community used for VPN route distribution and import policy. They should not be confused.
BGP EVPN Route Types: RT2, RT3 and RT5
BGP EVPN uses different route types to distribute service and endpoint information. Three particularly important types in VXLAN fabrics are MAC/IP Advertisement routes, Inclusive Multicast Ethernet Tag routes and IP Prefix routes.
MAC/IP Advertisement
EVPN Route Type 2 advertises MAC reachability and can associate an IP address with the advertised MAC. It allows remote VTEPs to learn where endpoints are located.
IP: 192.168.10.11
Next Hop: 10.0.0.11
Inclusive Multicast Ethernet Tag
EVPN Route Type 3 is used to discover participating provider endpoints for broadcast, unknown-unicast and multicast handling within an EVPN service.
Originating VTEP: 10.0.0.12
BUM replication membership
IP Prefix Advertisement
EVPN Route Type 5 advertises IP prefix reachability associated with an EVPN routing service, supporting routed tenant connectivity beyond individual MAC/IP endpoint advertisements.
Tenant: VRF-A
Next Hop: 10.0.0.12
RT2, RT3 and RT5 are not interchangeable. RT2 provides endpoint MAC/IP reachability, RT3 supports discovery for BUM forwarding, and RT5 provides IP-prefix reachability for routed EVPN services.
EVPN also defines other route types, including Ethernet Auto-Discovery and Ethernet Segment routes, which are important in multihoming architectures.
How EVPN Learns and Advertises Endpoints
Consider Host 1 attached to VTEP A. When the local VTEP learns the host's MAC address, it can originate an EVPN MAC/IP Advertisement route containing the relevant endpoint information.
Local Learning
VTEP A learns the locally attached host's MAC address and associated segment.
EVPN Advertisement
VTEP A originates a Type 2 route with the endpoint reachability information.
Route Distribution
BGP EVPN distributes the route to eligible peers, potentially through a route reflector.
Remote Installation
VTEP B imports the eligible route and programs the relevant forwarding state.
This process allows remote endpoint reachability to be learned through the control plane rather than relying exclusively on traditional data-plane flooding.
However, successful BGP route reception is only one part of the forwarding process. The receiving VTEP must accept the route according to route-target policy, resolve its next hop and install usable forwarding information.
Distributed Anycast Gateway and Inter-Subnet Routing
A distributed anycast gateway allows multiple leaf switches to provide the same logical default gateway address for a tenant subnet. This enables hosts to use a consistent gateway identity even when they are attached to different leaf switches.
Rather than sending all inter-subnet traffic to a centralised router, the ingress leaf can perform the routing operation locally and forward the traffic toward the appropriate remote destination.
In symmetric IRB designs, routing is associated with the tenant IP-VRF and an L3 VNI is commonly used for inter-VTEP routed traffic. In asymmetric IRB designs, the forwarding and VNI requirements differ.
Engineering Insight: Local Gateway, Distributed Routing
A distributed anycast gateway reduces unnecessary traffic tromboning through a centralised routing point. However, gateway addresses, virtual MAC configuration, tenant VRF membership and EVPN routing policies must remain consistent across participating leaves.
Endpoint Mobility and EVPN MAC Mobility
One of the advantages of overlay networking is the ability to move workloads between physical attachment points while maintaining logical network connectivity.
When a workload moves from one VTEP to another, the fabric must update its endpoint reachability information so that remote devices forward traffic toward the new location.
EVPN Endpoint Mobility Sequence
A host moves from Leaf A to Leaf B while remaining in the same logical segment.
Original Location
Host MAC is advertised through VTEP A. Remote VTEPs forward traffic to the original tunnel endpoint.
Host Migration
The host becomes reachable through VTEP B. Updated EVPN reachability is advertised, with mobility sequence information where applicable.
Forwarding Update
Remote VTEPs update endpoint forwarding information and direct subsequent traffic toward the new VTEP.
EVPN MAC Mobility extended community information helps distinguish newer endpoint advertisements from older information in supported mobility scenarios.
Excessive endpoint movement can create control-plane churn and unstable forwarding. Engineers should monitor repeated MAC moves, route withdrawals, forwarding-table updates and endpoint learning events.
Engineering Warning: EVPN Control Plane vs Data Plane
An established BGP EVPN session does not prove that VXLAN forwarding is operational. A route may be received but rejected by import policy, have an unresolved next hop or fail to program into hardware. Troubleshooting must validate both EVPN route state and the actual data-plane forwarding result.
Engineering Validation for VXLAN EVPN Fabrics
A reliable troubleshooting process begins with the physical underlay, moves into BGP EVPN reachability and finishes by validating tenant forwarding.
Fabric Architecture Validation Checklist
This layered validation approach helps distinguish an underlay transport failure from an EVPN control-plane issue or a VXLAN forwarding problem.
Section 4 — Key Engineering Takeaway
VXLAN provides the overlay transport, while BGP EVPN provides distributed reachability information for the virtual fabric. VTEPs map tenant traffic into VNIs, EVPN route types distribute endpoint and prefix information, and the routed underlay transports encapsulated packets between VTEPs. Reliable fabric operation depends on the correct interaction of all three architectural layers.
VXLAN and BGP EVPN Fabric Explorer
Investigate how an EVPN/VXLAN fabric separates IP underlay routing from overlay reachability. Explore MAC/IP routes, VNI mappings, distributed gateway forwarding and MAC mobility.
Dual-Spine EVPN/VXLAN Architecture
Select any leaf or spine to inspect its role. Switch forwarding modes to change the logical packet path.
Explore BGP EVPN Route Types
Select a route type to inspect its function, example attributes and forwarding implications.
Type 2 · MAC/IP Advertisement
Example Route Attributes
Layer 2 VXLAN Packet Journey
Trace a frame from Host A to Host C through L2 VNI 10100.
MAC Mobility and Endpoint Relearning
Simulate Host C moving from Leaf 3 to Leaf 2. Observe how the advertised VTEP next hop and MAC mobility sequence change.
Endpoint State
Control-Plane Event Timeline
This deterministic experiment represents a single-homed endpoint move. The receiving VTEPs update their forwarding state after accepting the newer EVPN advertisement.
Overlay Control Plane vs Underlay Routing
A network overlay depends on two related but distinct reachability systems. The underlay routing system determines how encapsulated packets travel between tunnel endpoints, while the overlay control plane determines how logical networks, tenant endpoints and virtual routing services are discovered.
This separation creates flexibility, scalability and operational abstraction. However, it also introduces an important engineering dependency: a route may exist in the overlay control plane even when the physical network cannot successfully deliver packets to its associated tunnel endpoint.
Understanding the interaction between underlay routing, EVPN reachability, recursive next-hop resolution and forwarding-table installation is essential when investigating connectivity failures in modern virtual network fabrics.
Two Control Planes, Two Responsibilities
In a VXLAN EVPN fabric, the underlay and overlay can use different routing protocols, different BGP sessions and different forwarding information. Even when both layers use BGP, their address families and operational purposes remain distinct.
Underlay Routing
The underlay provides transport reachability between network infrastructure addresses, including VTEP loopbacks.
- Physical interface connectivity
- OSPF, IS-IS, BGP or static routing
- VTEP loopback reachability
- ECMP and transport path selection
- Link failure detection
- Routing and FIB convergence
Overlay Control Plane
The overlay distributes tenant-specific reachability and logical service information between tunnel endpoints.
- BGP EVPN route distribution
- MAC/IP endpoint advertisements
- VNI and VRF service association
- Route-target import and export
- Remote VTEP identification
- Tenant forwarding installation
The underlay does not normally need to maintain individual tenant MAC addresses or tenant IP prefixes. Instead, it must know how to reach the outer IP destination of each encapsulated packet.
The overlay maintains the logical information required to determine which remote VTEP should receive traffic for a particular tenant endpoint or routed destination.
The Forwarding Dependency Chain
Consider a remote EVPN MAC/IP advertisement received by Leaf A. The route identifies a destination endpoint reachable through Leaf B's VTEP address.
Before traffic can be forwarded, the local device must associate the route with the correct tenant context, resolve the remote VTEP address through the underlay and program usable forwarding state.
From EVPN Advertisement to Packet Forwarding
Four dependent operations must work together before an overlay route becomes usable.
EVPN Route
BGP distributes endpoint or prefix reachability associated with a remote VTEP.
Route Import
Route-target policy and service configuration determine whether the route is accepted.
Next-Hop Resolution
The underlay routing table resolves the remote VTEP address to a valid transport path.
Forwarding State
The device installs the required tunnel and tenant forwarding information.
This process is often described as recursive next-hop resolution. The overlay identifies a remote destination VTEP, while the underlay resolves that VTEP address into an actual forwarding adjacency and physical egress interface.
For example, an EVPN route may identify VTEP 10.0.0.12 as the next hop. The local underlay RIB must provide a usable route to 10.0.0.12, and the forwarding plane must resolve that route into a valid outgoing path.
Engineering Insight: BGP Established Is Not Enough
An established EVPN BGP session confirms that the control-plane adjacency is operational. It does not guarantee that every imported EVPN route has a resolvable next hop or that VXLAN forwarding entries have been programmed correctly. Always validate the installed data plane.
Underlay Failure and Overlay Continuity
A major advantage of routed Leaf-Spine architectures is the availability of multiple equal-cost paths between leaf switches.
When one physical path fails, the underlay can select an alternative route to the destination VTEP. If the remote endpoint remains reachable and the overlay forwarding state remains valid, the tenant overlay may continue operating without requiring its EVPN routes to change.
Underlay Link Failure — Alternate Transport Path
A failed spine connection does not necessarily require an overlay route withdrawal.
In this example, the Leaf A to Spine 1 connection fails. The remaining routed fabric still provides reachability to VTEP B through Spine 2 or Spine 3.
The underlay can remove the failed next hop from its forwarding table and continue forwarding through the remaining valid paths. The overlay endpoint location has not changed, so the EVPN MAC/IP route may remain valid.
The precise recovery behaviour depends on the underlay routing protocol, failure detection, ECMP implementation and forwarding-plane update speed. A surviving path does not automatically imply zero packet loss.
Understanding Convergence Across Two Layers
Network convergence is the process through which devices detect a change, update their control-plane information and install new forwarding state.
In overlay networks, the convergence process may involve only the underlay, only the overlay, or both. The distinction depends on what actually failed.
Illustrative Underlay Failure Timeline
The following stages describe the logical sequence of recovery. Actual timing depends on platform and protocol configuration.
Healthy Forwarding
Multiple valid underlay paths provide reachability to the remote VTEP. VXLAN traffic is forwarded using the installed transport next hops.
Physical Failure Detection
A link or adjacency failure is detected through interface state, routing protocol timers or a mechanism such as BFD.
Underlay Route Recalculation
The routing system removes the failed path and selects surviving next hops for the remote VTEP address.
Forwarding-Plane Update
The device updates its forwarding entries to use the valid underlay path. Hardware programming and recovery behaviour depend on the platform.
Overlay Traffic Recovery
Encapsulated traffic resumes through the surviving path. Existing EVPN endpoint advertisements may remain unchanged.
Engineering Insight: Convergence Is Not Always an EVPN Event
If a single physical link fails but the remote VTEP remains reachable, the underlay may reconverge without requiring EVPN MAC/IP route withdrawal. If the remote VTEP itself becomes unreachable, additional overlay route invalidation or withdrawal may be required.
When Overlay and Underlay State Disagree
One of the most difficult overlay troubleshooting scenarios occurs when the control plane and forwarding plane no longer represent the same operational reality.
For example, an EVPN route may remain visible in a BGP table even though the corresponding VTEP next hop has become unreachable.
Depending on the implementation, that route may be retained in the BGP control-plane database while being excluded from usable forwarding state. In other situations, stale or incorrectly programmed data-plane entries can produce traffic blackholing.
Unresolved VTEP
An EVPN route identifies a remote tunnel endpoint, but the underlay lacks a usable forwarding path to that endpoint.
Stale Endpoint Location
A host moves to another VTEP, but some devices retain outdated MAC/IP reachability information.
Forwarding Mismatch
EVPN control-plane information is correct, but the installed tunnel, adjacency or hardware forwarding entry is incorrect.
Blackholing, Routing Loops and Recursive Dependencies
A traffic blackhole occurs when packets are forwarded toward a destination that cannot successfully deliver them, or when forwarding state causes packets to be dropped before reaching the intended endpoint.
Overlay blackholing can result from unresolved VTEP addresses, incorrect tunnel mappings, stale endpoint information, failed ECMP paths or inconsistent forwarding entries.
Routing loops are a separate but related risk. Incorrect route redistribution, recursive route dependencies or misconfigured tunnel routing can cause traffic to circulate between devices instead of reaching its destination.
A particularly important design principle is that the route used to reach a tunnel endpoint should not depend on forwarding through that same tunnel. Such circular dependencies can create recursive routing failures.
Engineering Warning: Recursive Tunnel Routing
If the route to a tunnel's remote endpoint resolves through the tunnel itself, the forwarding dependency becomes circular. Depending on the platform and protocol, this may cause tunnel instability, recursive resolution errors or packet loss. Keep tunnel transport reachability logically separate from routes carried inside the tunnel.
Comparing Common Failure Scenarios
| Failure | Underlay Impact | Overlay Impact | Primary Check |
|---|---|---|---|
| Single Spine Link Failure | One transport path becomes unavailable | EVPN endpoint routes may remain unchanged | ECMP next hops and underlay FIB |
| VTEP Loopback Unreachable | Remote endpoint loses transport reachability | Overlay routes may become unusable | Next-hop resolution and route installation |
| EVPN Session Failure | IP transport may remain operational | EVPN routes may be withdrawn or become stale | BGP neighbor state, timers and route changes |
| Incorrect Route Target | No direct impact on transport routing | Expected tenant routes may not be imported | EVPN import/export policy |
| Incorrect VNI Mapping | Transport may remain healthy | Tenant forwarding may fail | VLAN/VNI mapping and bridge-domain state |
| MTU Mismatch | Large encapsulated packets may fail | Partial application connectivity | Effective path MTU and packet captures |
Engineering Investigation: EVPN Route Present, Traffic Failing
Consider a network where Host A cannot reach Host B across a VXLAN fabric. Both leaf switches report established EVPN BGP sessions, and Leaf A displays a Type 2 route for Host B.
The presence of the Type 2 route narrows the investigation, but it does not prove successful forwarding. The next step is to validate whether the route has been imported, whether its next hop resolves and whether the expected VXLAN forwarding entry exists.
Structured Investigation Sequence
Inspect EVPN
Confirm the route type, destination, next hop and route-target attributes.
Resolve VTEP
Verify underlay routing and forwarding to the remote VTEP address.
Inspect FIB
Confirm remote MAC/VNI entries and tunnel forwarding programming.
Trace Packet
Validate encapsulation, transport path, decapsulation and delivery.
This approach prevents engineers from treating a BGP route-table entry as proof that the entire forwarding path is healthy.
Designing for Predictable Convergence
Resilient overlay architectures should minimise unnecessary dependencies and make failures observable.
A well-designed underlay provides redundant paths, stable tunnel endpoint addressing, predictable routing policy and sufficient transport MTU. The overlay control plane should distribute reachability information consistently and support timely removal of invalid endpoint state.
Fast failure detection can reduce recovery time, but aggressive timers must be balanced against control-plane stability, CPU utilisation and the risk of unnecessary adjacency flaps.
Control-Plane and Underlay Validation Checklist
Section 5 — Key Engineering Takeaway
Overlay reachability and underlay routing are separate control-plane functions, but successful forwarding depends on both operating correctly. EVPN routes identify logical destinations and remote VTEPs, while the underlay resolves those VTEPs into physical forwarding paths. Reliable convergence requires correct next-hop resolution, consistent route installation, resilient transport and accurate forwarding state.
Underlay and Overlay Failure Investigation
An EVPN route can be present without guaranteeing successful packet delivery. Inject a fault, inspect underlay reachability, examine the EVPN control plane and trace the actual forwarding outcome.
EVPN/VXLAN Forwarding Architecture
Solid links represent physical underlay connectivity. The animated logical path represents the VXLAN service between VTEPs.
Healthy EVPN/VXLAN Fabric
The underlay provides reachable VTEP loopbacks, the EVPN control plane advertises Host B's MAC, and the forwarding plane can encapsulate traffic across VXLAN VNI 10100.
Healthy Baseline vs Incident State
Compare the expected operational state against the selected incident.
A Healthy Baseline
B Current Network
Trace the VXLAN Forwarding Decision
Run the trace after injecting a fault. The journey stops at the stage where forwarding becomes impossible.
Host A sends an Ethernet frame.
Leaf 1 resolves Host B's MAC.
Underlay resolves 10.0.0.12.
Outer packet crosses the fabric.
Leaf 2 decapsulates and forwards.
Investigate with CLI Commands
Run simulated show commands to inspect the underlay, EVPN control plane, VTEP resolution and interface state.
Diagnose the Incident
Use the network-state comparison, packet trace and CLI evidence before revealing the explanation.
What is preventing successful forwarding?
Select the suspected root cause. The lab will check your diagnosis.
Select a scenario, inspect the evidence and submit your diagnosis.
Overlay Security and Tenant Isolation
Overlay networking allows multiple logical networks to share the same physical infrastructure while maintaining separate forwarding contexts. In multi-tenant environments, this separation is fundamental to preventing unintended communication between customers, applications and security domains.
However, network isolation and network security are not identical. A VXLAN VNI or tenant VRF can provide logical separation, but it does not automatically provide encryption, workload authentication, firewall inspection or protection against every form of lateral movement.
A secure overlay architecture combines forwarding isolation, controlled route distribution, explicit security policy, encrypted transport where required, and continuous operational validation.
Three Foundations of Overlay Security
Routing Isolation
Virtual Routing and Forwarding creates independent routing contexts. Different tenants can use overlapping IP addresses without sharing the same routing table.
Logical Segmentation
VXLAN Network Identifiers distinguish virtual network segments transported across the same IP underlay. Correct VNI mappings preserve logical forwarding boundaries.
Route Distribution Control
EVPN route targets determine which VPN routes are eligible for import into configured tenant services. They help control the distribution of logical reachability.
These mechanisms operate at different levels. A VRF separates Layer 3 routing information, a Layer 2 VNI identifies a virtual bridge domain, and an EVPN route target controls route import and export.
None of these mechanisms alone should be treated as a complete security policy. Effective isolation also depends on correct endpoint attachment, route filtering, forwarding configuration and enforcement at relevant trust boundaries.
Multi-Tenant Isolation Across a Shared Fabric
Consider a Leaf-Spine fabric hosting two tenants: Tenant Blue and Tenant Green. Both use the same physical spine switches and IP underlay, but each tenant has independent logical network services.
Tenant Blue uses L2 VNI 10010, while Tenant Green uses L2 VNI 20020. Their routing contexts are also separated into different VRFs.
Shared Underlay — Separate Tenant Overlays
Two isolated logical services use the same physical transport fabric.
The diagram illustrates logical tenant separation, not separate physical infrastructures. Both tenants can use the same switches and transport links while maintaining different forwarding contexts.
In this example, no inter-tenant route leaking or permitted forwarding path is configured. Traffic cannot cross between the two tenant routing domains through the illustrated fabric. If shared services or cross-tenant connectivity are introduced, explicit routing and security controls are required.
Engineering Insight: A VNI Is Not a Firewall
A VNI identifies a logical VXLAN segment. It does not inspect application traffic or enforce user identity. Likewise, a VRF provides routing separation, but controlled route leaking can create connectivity between VRFs. The resulting traffic must be evaluated against explicit security requirements and policies.
Four Layers of Tenant Isolation
Effective tenant isolation is established through multiple cooperating mechanisms. Each layer addresses a different part of the forwarding and security architecture.
Attachment
Assign workloads and interfaces to the correct VLAN, bridge domain, VNI and VRF.
Route Control
Import only authorised EVPN reachability into the intended tenant forwarding contexts.
Traffic Policy
Apply ACLs, firewalls or distributed policies where traffic crosses security boundaries.
Verification
Test allowed and denied traffic, inspect routes, and validate actual forwarding behaviour.
EVPN Route Targets and Controlled Route Leaking
EVPN route targets are BGP extended communities used to control VPN route import and export. In a multi-tenant design, separate route-target policies help ensure that routes are installed only in the intended services.
For example, Tenant Blue might use route target 65000:10010, while Tenant Green uses 65000:20020. Import and export configuration determines which EVPN routes each service receives.
Route leaking deliberately introduces selected reachability between routing domains. It can be useful for shared DNS, authentication, monitoring or application services. However, route leaking creates reachability; it does not independently guarantee that only authorised application traffic will pass.
Security enforcement may require firewall policies, ACLs, service insertion or distributed microsegmentation, depending on the architecture.
East-West Traffic and Lateral Movement
East-west traffic refers to communication between workloads or services inside a data centre or cloud environment. It can remain within a single subnet, cross routed tenant segments or traverse multiple physical hosts.
Overlay networking makes workload mobility and distributed connectivity easier, but this can also expand the reach available to a compromised workload if security boundaries are too broad.
For example, two application servers may belong to the same Layer 2 VNI and communicate directly without passing through a centralised firewall. If application-level restrictions are required, they must be enforced through an appropriate security control.
East-West Security Investigation
Consider a workload attempting to connect to a protected database service in another security segment.
Source Workload
An application server initiates a connection toward a protected database.
Route Evaluation
The fabric determines whether the destination is reachable through the relevant VRF.
Security Inspection
An enforced firewall or distributed policy evaluates source, destination, protocol and permitted service.
Allow or Deny
Authorised traffic is forwarded. Traffic that violates the enforced policy is denied.
This investigation demonstrates why routing and security policy must be evaluated separately. A destination can be reachable in the routing table but still be intentionally blocked by a security control.
Conversely, a permissive firewall rule does not create connectivity when the destination route is absent or the overlay forwarding state is invalid.
GRE, VXLAN and IPsec: Isolation vs Encryption
Overlay encapsulation is sometimes incorrectly described as encryption. The two functions must be distinguished.
GRE encapsulates packets for transport through an IP network, but does not provide confidentiality. VXLAN transports tenant Ethernet frames inside UDP/IP packets, but does not encrypt them.
IPsec provides cryptographic protection for IP traffic when appropriately configured. It can protect traffic across untrusted networks and may be combined with tunneling technologies where the architecture requires both functions.
| Technology | Primary Function | Logical Isolation | Encryption | Security Consideration |
|---|---|---|---|---|
| VXLAN | Ethernet overlay encapsulation | VNI-based logical segmentation | No | Validate VNI mappings, trusted VTEPs and forwarding policy |
| VRF | Independent Layer 3 forwarding contexts | Separate routing tables | No | Control route leaking and inter-VRF traffic |
| GRE | Multiprotocol packet tunneling | Tunnel-based logical separation | No | Add cryptographic protection where confidentiality is required |
| IPsec ESP | Protected IP communication | Policy and security association based | Yes, when encryption is negotiated | Validate keys, algorithms, peers and security policy |
| EVPN Route Targets | VPN route import/export control | Route distribution separation | No | Audit route-target membership and import policy |
| Firewall / ACL | Traffic policy enforcement | Policy-dependent segmentation | Not inherently | Verify enforcement location, rule order and permitted flows |
Security Warning: Shared Transport Is a Trust Boundary
VXLAN and GRE traffic should not be assumed confidential simply because it is encapsulated. When an overlay traverses infrastructure outside the trusted administrative boundary, evaluate encryption, tunnel endpoint authentication, filtering and transport security requirements.
Zero Trust and Overlay Network Design
Zero Trust architectures do not assume that a workload is trustworthy merely because it is attached to an internal network or a particular VNI.
Instead, access decisions should be based on the identity and context of the communicating entities, the requested resource and the applicable security policy.
Overlay segmentation can support this architecture by creating smaller network boundaries, separating applications and directing sensitive traffic through appropriate enforcement points.
However, Zero Trust requires more than network segmentation. Identity verification, device posture, least-privilege access, application controls, telemetry and continuous policy evaluation may also be required.
Common Overlay Security Failure Modes
Incorrect VNI Mapping
A workload is attached to an unintended bridge domain or VNI, potentially exposing it to the wrong logical segment.
Route-Target Misconfiguration
Incorrect EVPN import or export policy can distribute reachability into an unintended tenant service.
Uncontrolled Route Leaking
Inter-VRF routing introduces broader connectivity than intended, without adequate policy enforcement.
Untrusted Tunnel Endpoints
Inadequate control of encapsulated traffic sources can expose the fabric to unauthorised or spoofed tunnel traffic.
Security Validation and Operational Controls
Overlay security should be tested using both positive and negative connectivity scenarios.
Positive testing confirms that authorised workloads can communicate. Negative testing confirms that unauthorised communication is blocked at the intended enforcement point.
Engineers should also inspect forwarding tables, route-target membership, security policy counters, tunnel endpoint configuration and traffic logs.
Overlay Security Validation Checklist
Section 6 — Key Engineering Takeaway
Secure overlay networking requires more than logical segmentation. VRFs, VNIs and EVPN route targets establish separate forwarding and reachability contexts, while firewalls, ACLs, identity-based controls and encryption provide additional security functions. A resilient multi-tenant architecture must validate both permitted connectivity and denied traffic across every relevant trust boundary.
VXLAN Tenant Isolation and Route Leak Investigation
Explore how VRFs, VNIs, EVPN route targets and security policy work together to isolate tenants. Introduce a route leak, test packet forwarding and determine whether a firewall policy prevents unauthorized cross-tenant communication.
EVPN/VXLAN Security Architecture
Tenant Blue and Tenant Green share the same physical underlay while retaining independent overlay forwarding domains.
Tenant Blue → Tenant Blue
Host A and Host C belong to the same tenant and broadcast domain. EVPN Type 2 reachability enables VXLAN forwarding over L2 VNI 10100.
Modify EVPN Route Import and Firewall Policy
Introduce a route-target import error, then test whether an independent security policy still blocks unauthorized communication.
01 · EVPN Route-Target Policy
The route target determines which VPN routes are eligible for import into a VRF.
02 · Inter-Tenant Firewall Policy
A separate policy enforcement point can deny or permit traffic even when routing reachability exists.
Trace the Isolation Decision
Follow the packet through tenant classification, route import, security policy and VXLAN transport.
Host A generates traffic.
Source tenant identified.
Reachability policy checked.
Inter-tenant rule evaluated.
Packet forwarded or denied.
Inspect VRFs, EVPN Routes and Security Policy
Run simulated commands to investigate route-target imports, VNI mappings and firewall decisions.
Identify the Isolation Failure
Inspect the configuration and trace the packet before evaluating the security state.
What is the current cross-tenant security state?
Configure the route import and firewall policy, then assess the resulting security state.
Overlay Performance and Troubleshooting
Overlay networks introduce an additional forwarding layer between applications and the physical transport infrastructure. While technologies such as VXLAN provide scalable logical connectivity, they also introduce encapsulation overhead, forwarding dependencies and new troubleshooting considerations.
A VXLAN EVPN control plane can appear healthy while application traffic experiences packet loss, unexpected latency, reduced throughput or intermittent connectivity. These symptoms often originate from the interaction between encapsulation, transport MTU, ECMP forwarding, endpoint mobility, hardware forwarding state and network congestion.
Effective troubleshooting requires engineers to follow the packet through the complete forwarding journey rather than relying exclusively on routing protocol status or tunnel configuration.
Four Dimensions of Overlay Performance
Packet Size
Encapsulation increases the packet size carried across the underlay.
Path Selection
Hashing determines how flows are distributed across available paths.
Endpoint State
MAC learning and mobility influence remote endpoint forwarding decisions.
Congestion
Queue utilisation, microbursts and drops affect application performance.
Following a Packet Through the Overlay
Consider Host A sending an Ethernet frame to Host B across a VXLAN fabric. Leaf A receives the original frame, identifies the destination VNI and determines the remote VTEP responsible for Host B.
Leaf A then adds VXLAN, UDP and outer IP encapsulation. The underlay forwards the encapsulated packet toward Leaf B using its normal IP forwarding mechanisms.
Leaf B removes the outer encapsulation and forwards the recovered Ethernet frame toward Host B.
VXLAN Packet Journey Across the Underlay
The outer IP header determines transport forwarding between VTEPs.
The forwarding path should be examined at several points: the original source frame, the encapsulated packet at the ingress VTEP, the underlay transport path, the decapsulated frame at the egress VTEP and the final host delivery.
Each stage can fail independently. An EVPN route may be correct, for example, while the physical transport drops encapsulated packets because of an MTU limitation or congestion.
VXLAN Encapsulation Overhead and MTU
VXLAN encapsulates an original Ethernet frame inside UDP/IP transport. This increases the amount of data carried over the physical underlay.
For a conventional VXLAN packet using an IPv4 underlay, the added outer headers are:
VXLAN Over IPv4 — Header Structure
The following shows the encapsulated frame as it appears on an Ethernet transport link.
Example assumes a 1,500-byte inner IP packet, a 14-byte inner Ethernet header, IPv4 without options, and no VLAN tags. The encapsulated inner Ethernet frame is therefore 1,514 bytes. Adding 36 bytes of outer IPv4, UDP and VXLAN headers produces a 1,550-byte outer IP packet. Adding 14 bytes of outer Ethernet produces 1,564 bytes excluding FCS.
This distinction matters because interface MTU settings commonly refer to the maximum Layer 3 packet size, rather than the complete Ethernet frame length.
If the underlay cannot accommodate the outer packet size, the encapsulated packet may be dropped or, where permitted and supported, fragmented. IPv4 fragmentation behaviour depends on the outer DF setting and the implementation. IPv6 routers do not fragment packets in transit.
A robust design normally provisions sufficient underlay MTU for the intended tenant packet sizes, including encapsulation overhead.
Engineering Warning: Small Pings Can Pass While Applications Fail
Small ICMP probes may succeed across an overlay even when larger application packets exceed the effective transport MTU. Test realistic packet sizes, inspect fragmentation-related errors, and verify path MTU discovery behaviour rather than treating a successful default ping as proof of complete connectivity.
ECMP Hashing and Uneven Traffic Distribution
Leaf-Spine fabrics commonly use Equal-Cost Multipath routing to distribute traffic across multiple available transport paths.
ECMP generally selects a path using a hash derived from packet header fields. In VXLAN networks, the outer UDP source port is commonly used to provide entropy so that different inner flows can be distributed across multiple paths.
However, ECMP does not guarantee that every physical link receives an equal amount of traffic. A small number of high-bandwidth flows may hash onto the same path, creating congestion while other links remain underutilised.
Hash Polarisation
Multiple flows select the same forwarding path because of their hash results, potentially creating uneven link utilisation.
Elephant Flows
A small number of large flows consume substantial bandwidth and may dominate particular ECMP paths.
Microbursts
Short traffic bursts can temporarily exceed output queue capacity, producing drops that are not obvious in averaged interface statistics.
QoS Mapping
Incorrect classification or outer-header marking can cause encapsulated traffic to receive unexpected queue treatment.
MAC Mobility and Stale Endpoint Information
In EVPN fabrics, endpoint MAC addresses can be advertised using EVPN Type 2 routes. When a workload moves from one VTEP to another, the control plane must update the location associated with that endpoint.
EVPN MAC mobility procedures use mobility information, including sequence numbers where applicable, to help remote devices select the newer endpoint advertisement.
During a mobility event, stale forwarding state can temporarily direct traffic toward the previous VTEP. Repeated moves or conflicting advertisements can also indicate MAC flapping or incorrect endpoint attachment.
Troubleshooting should examine the EVPN MAC/IP route, its advertised next hop, mobility information and the installed remote MAC entry.
Engineering Insight: Route Visibility Is Not Forwarding Proof
A correct EVPN Type 2 advertisement is only one part of successful endpoint forwarding. Engineers must also verify route import, remote VTEP resolution, bridge-domain/VNI mapping and the installed forwarding entry. Inconsistent state between these components can produce blackholing even when the BGP session remains established.
Structured Overlay Troubleshooting
The most reliable troubleshooting approach follows the packet from source to destination while validating each forwarding dependency.
Six-Stage Overlay Investigation
Use this sequence to distinguish endpoint, overlay control-plane, underlay and forwarding problems.
Validate the Source Endpoint
Confirm the source VLAN, VNI, VRF, IP address, gateway and local MAC learning state.
Inspect Overlay Reachability
Check EVPN route type, route targets, imported routes, remote MAC/IP information and the destination VTEP.
Resolve the Underlay Path
Verify reachability to the remote VTEP loopback and inspect underlay routing, ECMP paths and adjacency state.
Inspect Encapsulation and MTU
Confirm the expected VNI, outer source and destination IP, UDP encapsulation and supported transport packet size.
Check Congestion and Forwarding
Review interface drops, output queues, hardware counters, forwarding entries and potential ECMP imbalance.
Validate Egress Delivery
Confirm decapsulation, destination bridge-domain membership, local MAC forwarding and successful delivery to the destination host.
Overlay Failure Symptoms and Likely Causes
| Observed Symptom | Potential Cause | Primary Investigation | Relevant Layer |
|---|---|---|---|
| Small packets work, large packets fail | Insufficient underlay MTU or broken PMTUD | Packet-size testing, DF behaviour, ICMP errors | Encapsulation / Transport |
| Intermittent throughput degradation | ECMP imbalance, congestion or queue drops | Per-link utilisation, flow hashing, queue telemetry | Underlay / QoS |
| EVPN route present, traffic fails | Unresolved VTEP, incorrect VNI mapping or FIB mismatch | Next-hop resolution, tunnel state, forwarding entries | Overlay / Data Plane |
| Connectivity fails after VM migration | Stale MAC/IP route or mobility convergence issue | EVPN Type 2 routes, mobility sequence, remote MAC table | EVPN Control Plane |
| One tenant fails, others work | VNI, VRF, route-target or policy mismatch | Tenant route import, service mappings, security policy | Tenant Overlay |
| Loss during underlay failure | Failure detection, routing convergence or hardware update delay | Link events, RIB/FIB changes, ECMP recovery | Underlay Convergence |
Telemetry: Observing What the Fabric Actually Does
Traditional monitoring based only on interface status and averaged bandwidth utilisation is insufficient for complex overlay fabrics.
Engineers need visibility into both the overlay and the underlay, including EVPN route changes, endpoint movement, tunnel statistics, forwarding counters, queue occupancy and packet drops.
Streaming telemetry can provide more frequent operational measurements than periodic polling. However, telemetry collection intervals, counter granularity and platform support determine whether short-lived microbursts and transient forwarding problems are visible.
Useful evidence includes timestamped route events, interface error counters, queue drops, ECMP path utilisation and packet captures at ingress and egress VTEPs.
Engineering Insight: Correlate Control-Plane and Data-Plane Events
A BGP EVPN route change and a packet-loss event occurring at the same time may be related, but correlation alone does not establish the root cause. Compare route updates, next-hop resolution, forwarding changes and interface counters on a consistent timeline to identify the actual failure mechanism.
Performance Validation Before Production
Overlay performance should be validated under realistic traffic conditions rather than relying only on control-plane health checks.
Testing should include different packet sizes, multiple concurrent flows, high-throughput traffic, endpoint mobility and physical link failure scenarios.
Overlay Performance Engineering Checklist
Section 7 — Key Engineering Takeaway
Overlay troubleshooting requires visibility across the complete forwarding path. Encapsulation overhead, MTU limitations, ECMP hashing, MAC mobility, congestion and forwarding-table inconsistencies can all affect application performance even when EVPN routing sessions remain healthy. Reliable diagnosis combines control-plane inspection, underlay validation, packet tracing and detailed data-plane telemetry.
VXLAN Performance and Incident Investigation
Investigate the difference between a healthy EVPN control plane and an unhealthy forwarding path. Inject network faults, inspect telemetry, test packet sizes, compare ECMP paths and diagnose the root cause using simulated engineering commands.
Underlay Path and Overlay Forwarding
The selected ECMP path determines which spine forwards the encapsulated packet. Incidents alter the modeled forwarding and telemetry state.
Healthy EVPN/VXLAN Fabric
Both ECMP paths are available. The underlay resolves the remote VTEP, EVPN advertises Host B's MAC and the VXLAN packet is forwarded successfully.
Performance and Forwarding Indicators
These are modeled telemetry snapshots for the selected incident, not live measurements. Observe how the symptoms change as faults are introduced.
Telemetry Interpretation
Balanced path utilization and low packet loss indicate healthy transport behavior for this modeled traffic sample.
Change the Packet and ECMP Path
Test different packet sizes and force a representative ECMP hash result. This lets you distinguish a path-dependent failure from a packet-size-dependent failure.
01 · Inner IP Packet Size
Change the inner IP packet size. The model assumes Ethernet-over-VXLAN with IPv4 transport, no VLAN tags and a 1500-byte underlay IP MTU.
02 · ECMP Path Selection
Select which spine carries this representative packet flow. Real ECMP selection normally uses a hash rather than a manual choice.
Trace the VXLAN Forwarding Decision
Follow the packet through EVPN lookup, VTEP resolution, encapsulation and underlay forwarding.
Host A sends a frame.
Remote MAC resolved.
VXLAN headers added.
Selected spine forwards.
Leaf 2 decapsulates.
Investigate the Incident Using CLI
Run simulated operational commands to inspect EVPN routes, VTEP reachability, interfaces, ECMP paths, MTU and MAC mobility.
Diagnose the Network Incident
Compare the telemetry, packet trace and CLI evidence before selecting a diagnosis.
What is the primary engineering condition?
Select an incident, inspect the evidence and submit your diagnosis.
Overlay Networks Across WAN and Cloud
Network overlays are not limited to data centre fabrics. The same architectural principle of separating logical connectivity from physical transport is widely used across enterprise WANs, hybrid-cloud environments and distributed application platforms.
Traditional WAN designs often depend on fixed transport connections and routing relationships. Modern overlay architectures introduce additional flexibility by establishing logical tunnels across MPLS, broadband Internet, private interconnects and cellular networks.
Technologies such as DMVPN, SD-WAN, IPsec VPNs and cloud connectivity overlays enable organisations to connect geographically distributed environments while applying routing, security and transport policies independently of the underlying physical infrastructure.
Four Building Blocks of Distributed Overlays
Transport Independence
Logical tunnels can operate across multiple transport services, including MPLS, Internet and LTE/5G.
Secure Connectivity
IPsec can provide confidentiality, integrity and peer authentication for traffic crossing untrusted networks.
Application Awareness
SD-WAN policies can select paths using application identity, link quality and business requirements.
Cloud Integration
Overlay connectivity can extend enterprise routing and security domains into cloud networks and hosted services.
Multi-Site Overlay Architecture
Consider an enterprise with two branch offices, a central data centre and workloads hosted in a public cloud.
Each site connects to one or more transport networks. Overlay tunnels establish logical connectivity between participating edge devices.
The physical WAN determines how packets reach remote tunnel endpoints, while the overlay determines how enterprise traffic is routed, segmented and protected.
Enterprise WAN and Hybrid-Cloud Overlay
Encrypted logical connectivity across multiple transport networks.
The diagram is conceptual. Actual tunnel establishment, encryption, routing and path availability depend on the selected platform and network design.
A cloud gateway, for example, may terminate IPsec tunnels but not participate directly in the same SD-WAN control plane as the enterprise edge devices.
Engineering Insight: Underlay Independence Is Not Underlay Irrelevance
An overlay can abstract multiple transport services into a common logical network, but it still depends on underlay reachability, available bandwidth, packet loss, latency and MTU. A tunnel cannot compensate for a completely unavailable physical path without another functioning transport option.
DMVPN, SD-WAN and Cloud Overlays Compared
Different overlay technologies solve different operational problems. Some focus on scalable tunnel formation, while others provide centralised policy, transport abstraction or integration with cloud routing.
| Architecture | Overlay Mechanism | Control / Routing | Primary Benefit | Design Consideration |
|---|---|---|---|---|
| DMVPN | mGRE with NHRP; commonly protected using IPsec | NHRP resolution plus routing protocols | Dynamic spoke-to-spoke tunnel connectivity | NHRP registration, routing design, IPsec and hub resilience |
| SD-WAN | Vendor-specific secure overlay tunnels | Centralised or distributed policy and route distribution | Application-aware transport selection and operational automation | Controller resilience, tunnel health, policy and interoperability |
| Site-to-Site IPsec | IPsec ESP, commonly tunnel mode | Static or dynamic routing across protected connectivity | Secure connectivity across untrusted IP transport | Security associations, IKE negotiation, MTU and routing |
| Hybrid-Cloud VPN | Encrypted tunnels between enterprise and cloud gateways | Often BGP or static routing | Private network reachability over public transport | Prefix overlap, route propagation, throughput and redundancy |
| Cloud Transit | Cloud-native virtual routing and attachment constructs | Cloud route tables, policies and sometimes BGP | Scalable connectivity among VPCs/VNets, on-premises sites and shared services | Route domains, attachment policy, asymmetric paths and inspection |
DMVPN: Dynamic Multipoint Connectivity
Dynamic Multipoint VPN uses multipoint GRE tunnels, the Next Hop Resolution Protocol and a routing protocol to support dynamic connectivity between participating sites.
In a traditional hub-and-spoke VPN, traffic between two spokes may need to traverse the hub. DMVPN can allow direct spoke-to-spoke communication when the design and implementation support it.
NHRP provides a mechanism for resolving tunnel destinations to transport addresses. IPsec is commonly used to secure the GRE traffic.
Engineers must consider routing next-hop behaviour, NHRP registration and resolution, tunnel protection, hub availability and the chosen DMVPN deployment model.
SD-WAN: Application-Aware Overlay Routing
SD-WAN extends the overlay concept by combining secure connectivity with centralised policy and ongoing transport monitoring.
Instead of selecting a WAN path solely through traditional destination-based routing metrics, an SD-WAN solution can evaluate application requirements and transport health.
Common measurements include latency, packet loss and jitter. Policies can define acceptable service levels for different application classes.
For example, a real-time voice application may prefer a path with low jitter, while a bulk data transfer may prioritise throughput and cost.
Application Packet Journey Across SD-WAN
Classify
Identify the application or traffic class using configured policy criteria.
Evaluate
Compare available WAN paths against application policy and measured transport health.
Encapsulate
Apply the platform's overlay encapsulation and encryption where configured.
Transport
Forward traffic over the selected underlay connection toward the remote edge.
Deliver
Validate and decapsulate the traffic before forwarding it to the destination.
The precise classification, policy evaluation and packet encapsulation mechanisms vary between SD-WAN implementations.
WAN Failover and Path Steering
A major benefit of multi-transport overlays is the ability to redirect traffic when a WAN path becomes unavailable or fails to meet application performance requirements.
However, failover is not instantaneous by definition. Recovery depends on failure detection, policy evaluation, tunnel availability, routing convergence and the behaviour of existing application sessions.
Example: MPLS to Internet Failover
A branch application initially uses a preferred MPLS overlay path. An alternate encrypted Internet path is available.
Normal Operation
The MPLS path meets application policy requirements. Traffic uses the preferred overlay tunnel.
Transport Degradation
Loss, latency or jitter exceeds the configured threshold, or the transport becomes unreachable.
Path Health Detection
Tunnel monitoring and path measurements identify the degraded service. The controller or edge device evaluates policy.
Policy-Based Steering
Traffic is moved to the alternate Internet overlay when that path is eligible and healthy.
Application Recovery
Forwarding continues over the alternate path. Application continuity depends on convergence time, session handling and the characteristics of the traffic.
Engineering Warning: Failover Does Not Guarantee Session Preservation
A new overlay path may be available while existing sessions still experience disruption. Changes in source addressing, NAT state, security associations, asymmetric routing or packet ordering can affect application continuity. Validate actual session behaviour, not only tunnel recovery.
Hybrid-Cloud Overlay Connectivity
Hybrid-cloud environments introduce additional routing and security domains. Enterprise networks must exchange reachability with cloud gateways, virtual networks and hosted applications.
IPsec VPNs are commonly used to establish encrypted connectivity over the Internet. Dedicated private connectivity services provide another transport option, although private connectivity does not necessarily imply encryption.
BGP is frequently used to exchange routes between enterprise routers and cloud gateways. Cloud-native transit services can then distribute reachability among multiple virtual networks and connected sites.
Key design challenges include overlapping IP address ranges, route advertisement policy, asymmetric forwarding, security inspection, MTU limitations and multi-region resilience.
Service Mesh: An Overlay at a Different Layer
The overlay principle also appears in application networking, particularly within microservices architectures.
A service mesh introduces a logical communication and policy layer between services, commonly using proxies or other data-plane enforcement mechanisms.
Unlike VXLAN or GRE, which encapsulate network traffic, a service mesh typically operates at higher layers to provide service identity, mutual TLS, traffic management and application-level observability.
These technologies are complementary rather than interchangeable. A service mesh may run on workloads whose packets are transported across a VXLAN data centre fabric and an SD-WAN enterprise network.
Engineering Insight: Multiple Overlays Can Coexist
A single application request may traverse a service mesh, a container networking overlay, a data centre VXLAN fabric and an encrypted WAN tunnel. Each layer introduces separate forwarding, security and observability considerations. Troubleshooting must identify which layer owns the failing function.
Designing Resilient Multi-Site Overlays
Transport Diversity
Use genuinely diverse transport paths where resilience is required. Two logical tunnels sharing the same physical access circuit do not eliminate that single point of failure.
Control-Plane Resilience
Evaluate controller, hub, gateway and route-distribution dependencies. Ensure that existing forwarding behaviour during controller loss is understood and tested.
Security Boundaries
Validate tunnel authentication, encryption, segmentation, route filtering and cloud security policies at every administrative boundary.
Application Validation
Measure end-to-end application performance during normal operation, path degradation and failover. Test real traffic rather than relying exclusively on tunnel status.
Operational Validation Checklist
Distributed overlays should be validated across both their logical control systems and the underlying transport services.
WAN and Cloud Overlay Engineering Checklist
Section 8 — Key Engineering Takeaway
WAN and cloud overlays extend logical networking beyond the physical boundaries of a single data centre. DMVPN, SD-WAN, IPsec and cloud networking services provide different approaches to scalable connectivity, security and transport abstraction. Resilient designs must coordinate overlay policy, underlay health, routing, encryption and application behaviour across multiple administrative and geographic domains.
SD-WAN Path Selection and Hybrid Cloud Connectivity
Operate a simulated SD-WAN overlay across MPLS, Internet and LTE/5G transports. Compare application SLA requirements, observe encrypted tunnel selection, introduce failures and investigate how traffic is rerouted.
Branch-to-Cloud Transport Selection
Each path represents an encrypted overlay tunnel across a different transport. The selected application determines which available path best satisfies its policy.
Application-Aware Routing
Voice traffic prefers a low-latency, low-jitter transport. The SD-WAN policy evaluates tunnel health and selects an eligible path.
Live Path Health and SLA Measurements
Compare the transport measurements against the selected application's SLA thresholds. The values are deterministic incident snapshots.
Eligible for selected application
Eligible for selected application
Backup transport
How the SD-WAN Selects a Path
The policy first removes unavailable tunnels, then evaluates latency, jitter and loss. Eligible paths are ranked by application preference. If none passes the SLA, the model uses a configurable best-effort fallback.
Application SLA Requirements
| Application | Latency | Jitter | Loss |
|---|---|---|---|
| Voice | ≤ 80 ms | ≤ 20 ms | ≤ 1% |
| Business | ≤ 150 ms | ≤ 50 ms | ≤ 2% |
| Cloud SaaS | ≤ 120 ms | ≤ 35 ms | ≤ 2% |
Application Transport Preference
The best-effort mode minimizes normalized SLA violations, then applies the application's transport preference as a tie-breaker.
Trace Application Traffic Across the WAN
Follow application classification, policy evaluation, IPsec encapsulation, transport forwarding and cloud delivery.
Identify application.
Check path health.
IPsec ESP tunnel.
Selected WAN path.
Hub-to-cloud service.
Inspect Tunnels, SLA and Routing Policy
Use simulated SD-WAN operational commands to investigate the selected incident.
Identify the Transport Condition
Review the tunnel state, SLA measurements, path selection and CLI output before submitting your assessment.
What is the primary WAN condition?
Inspect the transport state and application policy before submitting your diagnosis.
Designing a Resilient Overlay Fabric
A successful overlay network is more than a collection of tunnels or routing protocol sessions. It is an integrated architecture in which the physical underlay, overlay control plane, forwarding infrastructure, security policies and operational systems work together.
Technologies such as VXLAN, EVPN, GRE, IPsec and SD-WAN provide different mechanisms for extending connectivity beyond physical network boundaries.
However, the long-term success of an overlay architecture depends on how well it handles failure, scale, segmentation, convergence, observability and operational change.
The final design objective is not simply to establish connectivity. It is to create a network whose behaviour remains predictable during normal operation, maintenance and unexpected failures.
Six Principles of Resilient Overlay Design
Underlay Resilience
Provide redundant physical paths, stable routing, adequate capacity and predictable convergence between tunnel endpoints.
Control-Plane Scale
Design EVPN route distribution, route reflection, filtering and next-hop resolution for expected network growth.
Tenant Isolation
Maintain clear separation between tenant routing, bridge domains, VNIs, VRFs and security policies.
Forwarding Integrity
Validate encapsulation, MTU, ECMP, hardware forwarding entries and endpoint reachability.
Operational Visibility
Correlate underlay routing, EVPN state, tunnel health, packet drops and endpoint movement.
Failure Validation
Test link failures, VTEP loss, route withdrawal, MAC mobility and security policy changes.
Reference Architecture: Resilient VXLAN EVPN Fabric
A common data centre overlay architecture uses a Layer 3 leaf-spine underlay with VXLAN tunnels between participating VTEPs.
The underlay provides IP reachability between VTEP addresses, while BGP EVPN distributes endpoint and tenant reachability information.
In a typical design, leaf switches act as VTEPs and may provide distributed anycast gateway functionality. Spine switches provide redundant IP transport paths. Route reflectors may be deployed on spine devices or dedicated control-plane nodes.
Leaf-Spine EVPN Fabric — Logical and Physical Layers
Redundant IP transport with an EVPN-controlled VXLAN overlay.
In this architecture, every leaf has connectivity to both spine switches. ECMP can distribute underlay traffic across eligible equal-cost paths.
If one spine or uplink fails, underlay routing can converge onto the remaining available paths. The VXLAN overlay may continue operating without changing the logical tenant topology, provided that remote VTEPs remain reachable.
The diagram shows two example tenant services. Actual tenant isolation depends on bridge-domain, VNI, VRF, route-target and policy configuration. A VNI alone should not be treated as a complete security boundary.
Engineering Insight: Underlay Redundancy and Overlay Redundancy Are Different
Multiple ECMP paths can protect transport connectivity between VTEPs, but they do not automatically protect against VTEP failure, incorrect EVPN advertisements, tenant configuration errors or gateway loss. Resilience must be evaluated at each architectural layer independently.
Four Layers of Overlay Architecture
A useful design method separates the network into distinct operational layers. This makes dependencies easier to understand and simplifies failure investigation.
Physical and Underlay Transport
Links, interfaces, IP addressing, routing adjacencies, ECMP, transport MTU and next-hop reachability.
Overlay Control Plane
BGP EVPN sessions, route reflection, route types, route targets, endpoint advertisements and remote VTEP resolution.
Overlay Data Plane
VXLAN encapsulation, VNI mapping, MAC forwarding, distributed gateways, decapsulation and hardware forwarding state.
Security and Operations
Tenant isolation, access policies, telemetry, monitoring, configuration management and incident response.
These are architectural categories rather than OSI layer numbers. A fault in one category may affect services implemented by several others.
Overlay Architecture Decision Matrix
There is no single overlay technology suitable for every environment. Technology selection should begin with service requirements rather than a preferred encapsulation protocol.
| Design Requirement | Typical Approach | Key Dependency | Validation Question |
|---|---|---|---|
| Scalable data centre L2/L3 services | VXLAN with BGP EVPN | VTEP reachability, EVPN route distribution | Are remote MAC/IP and IP-prefix routes correctly imported and installed? |
| Simple routed tunnelling | GRE or an appropriate routed tunnel | Underlay reachability, tunnel endpoint configuration | Is the tunnel needed for encapsulation, routing or another service? |
| Secure site-to-site connectivity | IPsec VPN | IKE negotiation, security associations, route reachability | Are encryption, authentication and failover validated? |
| Application-aware WAN | SD-WAN | Path monitoring, policy, controller/edge operation | Does traffic use the correct path under normal and degraded conditions? |
| Multi-tenant segmentation | VRFs, VNIs, EVPN policies and security controls | Route targets, forwarding separation, enforcement | Can one tenant access another without an explicitly permitted path? |
| High availability | Redundant links, VTEPs, gateways and control-plane infrastructure | Failure detection, routing convergence, state consistency | What happens when each component fails independently? |
Five-Stage Overlay Engineering Workflow
Overlay design should follow a repeatable engineering process, beginning with requirements and ending with measured operational behaviour.
From Requirements to Production Validation
Define the Service Requirements
Identify tenant boundaries, L2 extension requirements, L3 routing domains, application dependencies, scale targets and acceptable recovery times.
Design the Underlay
Select the physical topology, IP addressing, routing protocol, ECMP strategy, MTU and failure detection mechanisms. Verify redundant reachability between VTEPs.
Design the Overlay Services
Define VNIs, VRFs, route targets, EVPN route distribution, gateway placement, endpoint mobility handling and tenant policies.
Validate Forwarding and Failure Behaviour
Test encapsulation, MTU, MAC/IP learning, ECMP, route withdrawal, link failures, VTEP loss and security isolation.
Establish Operational Assurance
Implement telemetry, configuration validation, route monitoring, incident runbooks and continuous checks against known healthy network behaviour.
Failure Testing: Proving the Architecture
A resilient design should be evaluated against realistic failure scenarios. The objective is to measure both the recovery mechanism and the resulting application impact.
| Failure Scenario | Expected Behaviour | Evidence to Collect | Potential Risk |
|---|---|---|---|
| Single underlay link failure | Routing converges onto surviving eligible paths | Adjacency events, RIB/FIB updates, packet loss | Slow convergence or insufficient remaining capacity |
| Spine switch failure | Remaining spines continue providing transport connectivity | ECMP changes, VTEP reachability, forwarding recovery | Hidden control-plane dependency or oversubscription |
| VTEP failure | Reachability is withdrawn or recovered through an available redundant attachment | EVPN withdrawals, endpoint location, traffic restoration | Blackholing or orphaned endpoints |
| Route reflector failure | Redundant control-plane connectivity maintains or restores route exchange | BGP sessions, route retention, convergence | Loss of route propagation or stale state |
| Endpoint migration | Remote forwarding updates to the new endpoint location | Type 2 routes, mobility sequence, MAC tables | MAC flapping or stale forwarding |
| Incorrect route target | Routes are imported only into intended routing domains | EVPN import/export state, VRF route tables | Tenant isolation failure or missing connectivity |
| MTU mismatch | Oversized traffic is detected and the design is corrected | Large-packet tests, drop counters, PMTUD evidence | Intermittent application failure |
Engineering Warning: Redundancy Must Be Tested, Not Assumed
Two physical links, two spine switches or two route reflectors do not automatically guarantee high availability. Shared power, common configuration errors, control-plane dependencies and insufficient spare capacity can create hidden failure domains. Test component failures individually and evaluate correlated failure scenarios.
Observability and Network State Comparison
Overlay operations become significantly easier when engineers can compare a known healthy network state with the state observed during an incident.
A useful baseline includes underlay routing tables, BGP EVPN sessions, advertised and imported routes, MAC/IP forwarding entries, VNI/VRF mappings and relevant interface counters.
During a failure, the engineer can compare the expected state with the actual state to identify which dependency changed.
For example, if a remote endpoint becomes unreachable, the investigation can determine whether its EVPN advertisement disappeared, its next hop became unresolved, the VXLAN tunnel became unavailable or the forwarding entry was incorrectly installed.
This method turns troubleshooting into a structured comparison of network behaviour rather than a sequence of unrelated command outputs.
Engineering Insight: Healthy Control Plane Does Not Guarantee Healthy Forwarding
EVPN routes may be present in the control plane while packets fail in the data plane. Production monitoring should correlate routing state, VTEP resolution, hardware forwarding, tunnel encapsulation and actual packet delivery.
Production Readiness Checklist
Before deploying an overlay fabric into production, validate the architecture against the following engineering requirements.
Final Overlay Fabric Validation
Bringing the Overlay Architecture Together
Throughout this Network Overlays guide, we have examined how encapsulation separates logical services from physical transport, how technologies such as GRE and VXLAN carry traffic, and how EVPN provides scalable control-plane distribution.
We have also explored tenant isolation, security, forwarding performance, troubleshooting, WAN overlays and hybrid-cloud connectivity.
These subjects are connected by a single engineering principle: the overlay can abstract the underlying network, but it cannot eliminate the dependencies on which forwarding relies.
Final Engineering Takeaway
A resilient overlay fabric requires coordinated design across physical transport, routing, control-plane distribution, encapsulation, tenant segmentation, security and operational monitoring.
The strongest overlay designs are not those with the most features, but those whose forwarding behaviour can be explained, tested and recovered under failure conditions.
Engineers should be able to trace a packet from source to destination, identify every forwarding dependency, predict the impact of a component failure and validate recovery using observable network state.
Resilient EVPN/VXLAN Fabric Design Lab
Design, validate and troubleshoot a multi-tenant EVPN/VXLAN fabric. Configure the underlay and overlay, test tenant isolation, inject network failures, inspect packet forwarding and compare the healthy baseline against the incident state. Your objective is to achieve a production-ready design and preserve service during recoverable faults.
Dual-Spine EVPN/VXLAN Network
The fabric contains two leaf VTEPs, two redundant spines and two tenant networks. The selected packet travels from Tenant A on Leaf 1 to Tenant A on Leaf 2.
Healthy Fabric Baseline
Both spines provide underlay connectivity. EVPN advertises Tenant A's MAC reachability, the remote VTEP resolves and VXLAN forwarding operates across VNI 10100.
Configure the Production Overlay
Adjust six engineering controls. Each setting affects the modeled fabric state and validation results. The baseline begins with a compliant configuration; deliberately misconfigure it to investigate failure dependencies.
01 · Underlay Routing
Provide IP reachability between VTEP loopbacks.
Configured correctly02 · EVPN Control Plane
Distribute remote endpoint reachability.
Configured correctly03 · VXLAN MTU
Allow a 1500-byte inner IP packet with VXLAN overhead.
Encapsulation supported04 · Spine Redundancy
Enable two independent forwarding paths.
Redundancy enabled05 · Tenant Isolation
Keep Tenant A and Tenant B in separate forwarding domains.
Isolation enforced06 · Failure Recovery
Allow a usable alternate path after a spine failure.
Recovery configuredHealthy Baseline vs Current Incident
Compare the reference healthy design with the current configuration and injected fault. The current state is recalculated whenever you change the design or incident.
Trace Tenant A Across the VXLAN Fabric
Observe MAC lookup, VTEP resolution, VXLAN encapsulation, ECMP forwarding and remote delivery.
Tenant A frame.
Remote MAC route.
Encapsulation / MTU.
ECMP forwarding.
Remote Tenant A.
Inspect the Fabric Using CLI
Use simulated operational commands to inspect underlay routing, EVPN reachability, VTEP state, ECMP, MTU and tenant isolation.
Validate the Fabric Design
The assessment checks six configuration requirements and the current forwarding outcome. A configuration can score highly while still failing an injected incident; review both results before declaring success.
Run the engineering checks and inspect the results.
From Network Overlays to Intelligent SD-WAN
You've explored the architecture, encapsulation, control planes and resilience of overlay networks. Now discover how these concepts extend across enterprise WANs. Explore SD-WAN architectures, encrypted tunnels, transport selection and application-aware routing in a dedicated interactive learning workspace.