Chaos Engineering

Chaos Engineering Kubernetes

Chaos Engineering Kuberentes

In Kubernetes environments, reliability cannot be measured simply by whether workloads are running. Distributed applications can remain technically available while experiencing increased latency, elevated error rates, resource exhaustion, or degraded dependencies. Chaos Engineering provides a controlled way to expose these weaknesses before they become production incidents.

Chaos Engineering involves deliberately introducing controlled failures or abnormal conditions into a system and observing how it responds. The objective is not to cause disruption for its own sake, but to validate resilience assumptions, identify unknown failure modes, and improve the system’s ability to recover. In Kubernetes, experiments can target workloads, nodes, networking, storage, dependencies, or resource availability.

A successful experiment begins with a hypothesis. Engineers define what they expect to happen if a particular component fails and establish the signals that will demonstrate whether the system remained within acceptable limits. A controlled fault is then introduced while telemetry is collected, allowing the resulting behaviour to be compared with the original reliability expectations.

This makes metrics and observability fundamental to Chaos Engineering. Key signals can include request latency, error rates, throughput, CPU and memory utilisation, pod restarts, resource saturation, queue depth, and application-specific service-level indicators. Looking at these signals together provides a much clearer picture of system health than relying on a single metric.

Latency metrics help reveal how a failure affects application response times. Introducing network delay, dependency latency, or resource contention can demonstrate whether timeouts, retries, load balancing, and application fallbacks behave as expected. A service may remain available while its latency increases enough to create a significant user-facing impact.

Error and availability metrics show whether the system continues to meet its reliability objectives when components fail. Controlled pod termination, dependency failures, or network disruption can reveal whether Kubernetes workloads restart correctly and whether applications have sufficient redundancy and graceful failure mechanisms.

Resource and saturation metrics provide another important perspective. CPU throttling, memory pressure, constrained capacity, or excessive workload demand can expose weak resource limits, inefficient scheduling, or scaling assumptions. These experiments can help validate whether Kubernetes workloads respond correctly when the underlying resources become constrained.

The real value of Chaos Engineering comes from connecting these experiments to observable outcomes. A useful experiment should establish a hypothesis, introduce a controlled fault, monitor the relevant telemetry, measure the impact, and capture what was learned. The results can then feed back into application design, Kubernetes configuration, alerting, capacity planning, and incident response.

Chaos Engineering therefore becomes more than deliberately creating failures. It is a practical method for testing whether a Kubernetes platform and the applications running on it can detect, tolerate, and recover from unexpected conditionsbefore those conditions become real-world incidents.

Interactive Chaos Engineering / Experiment 01

Chaos Engineering Experiment Loop

Chaos engineering is not simply breaking a system. The engineering process is to define normal behavior, form a hypothesis, introduce a realistic failure, observe the system, and use the evidence to improve resilience.

Experiment Objective
Prove that the application can tolerate failure
Start with measurable steady-state behavior. Then introduce one controlled fault and determine whether the application remains within its reliability objectives or successfully recovers.
p99 < 200ms
Errors < 1%
Availability > 99.9%
CPU < 70%
Engineering Principle
Test the hypothesis
A useful experiment attempts to disprove an assumption about system resilience rather than simply generate failure.
Experiment Lifecycle
01
Steady State
Establish measurable normal behavior.
02
Hypothesis
Predict how the system should respond.
03
Inject Failure
Introduce a controlled realistic fault.
04
Observe
Measure system behavior during failure.
05
Compare
Compare results against steady state.
06
Improve
Fix weaknesses and repeat the experiment.
Selected Stage
01 — Steady State
BASELINE
Before introducing chaos, define what healthy behavior looks like. The baseline should be measurable so that the experiment has something meaningful to compare against.
Question: What does “healthy” look like for this application?
Engineering principle: If you cannot measure steady state, you cannot reliably determine whether a chaos experiment caused meaningful degradation.
Experiment Telemetry
p99 Latency
142 ms
Error Rate
0.3%
Availability
99.98%
CPU Usage
54%
Experiment Result
HYPOTHESIS SUPPORTED
The simulated failure produced a measurable change, but the service recovered and returned toward its defined steady state.
Engineering Takeaway: Chaos engineering should be treated as a controlled scientific experiment. Define the steady state first, introduce a realistic failure with a known blast radius, observe the system, compare the result with the baseline, and feed the learning back into the design.
STEADY STATE → HYPOTHESIS → FAILURE → OBSERVE → COMPARE → IMPROVE → REPEAT

Highlights: Chaos Engineering Kuberentes

The Principles of Chaos Engineering

Chaos Engineering is grounded in several core principles. First, it is about embracing failure as a learning opportunity. By simulating failures, teams can understand how their systems react under stress. Another principle is to conduct experiments in a controlled environment, ensuring any disruptions do not affect end users. Lastly, Chaos Engineering emphasizes continuous learning and improvement, turning insights from experiments into actionable changes.

**Tools and Techniques**

Implementing chaos engineering requires a robust set of tools and techniques to simulate real-world disruptions effectively. Some popular tools in the chaos engineering toolkit include Chaos Monkey, Gremlin, and Litmus, each offering unique features to test system resilience. These tools enable engineers to automate experiments, analyze results, and derive actionable insights. By using these advanced tools, organizations can run experiments at scale and gain confidence in their systems’ ability to handle unpredictable events.

**Why Chaos Engineering Matters**

Modern systems are complex and often distributed across multiple platforms and services. This complexity makes it difficult to predict how systems will behave under unexpected conditions. Chaos Engineering allows teams to identify hidden vulnerabilities, improve system reliability, and enhance user experience. Companies like Netflix and Amazon have successfully used Chaos Engineering to maintain their competitive edge by ensuring their services remain robust and available.

**The Traditional Application**

When considering Chaos Engineering kubernetes, we must start from the beginning. Not too long ago, applications ran in single private data centers, potentially two data centers for high availability. These data centers were on-premises, and all components were housed internally. Life was easy, and troubleshooting and monitoring any issues could be done by a single team, if not a single person, with predefined dashboards. Failures were known, and there was a capacity planning strategy that did not change too much, and you could carry out standard dropped packet test

**A Static Infrastructure**

The network and infrastructure had fixed perimeters and were pretty static. There weren’t many changes to the stack, for example, daily. Agility was at an all-time low, but that did not matter for the environments in which the application and infrastructure were housed. However, nowadays, we are in a completely different environment with many more moving parts with an increasing need to support a reliable distributed system.

Complexity is at an all-time high, and business agility is critical. Now, we have distributed applications with components/services located in many different places and types of places, on-premises and in the cloud, with dependencies on both local and remote services. So, in this land of complexity, we must find system reliability. A reliable system is one that you can trust will be reliable.

Chaos Engineering in Kubernetes — Designing for Failure in Cloud‑Native Systems

Chaos engineering in Kubernetes is the discipline of intentionally injecting failure into clusters to validate resilience, uncover hidden weaknesses, and ensure workloads behave correctly under stress. Instead of waiting for outages, chaos engineering forces the system to experience them in a controlled, observable way. Kubernetes is a perfect environment for chaos experiments because it is inherently dynamic, distributed, and built around self‑healing primitives.

Why Chaos Engineering Matters in Kubernetes

Kubernetes abstracts infrastructure, but abstraction hides failure. Chaos engineering exposes how workloads behave when:

  • nodes crash
  • pods restart unexpectedly
  • network latency spikes
  • storage becomes slow or unavailable
  • API server becomes overloaded
  • autoscaling triggers aggressively
  • controllers misbehave

Chaos engineering ensures your cluster is resilient by design, not by assumption.

Core Principles of Kubernetes Chaos Engineering

Chaos engineering in Kubernetes follows four foundational principles:

1. Define Steady State

You must know what “normal” looks like.

Examples:

  • p99 latency under 200ms
  • error rate < 1%
  • CPU usage < 70%
  • pods healthy and ready

Steady state becomes the baseline for evaluating chaos impact.

2. Introduce Realistic Failure

Chaos experiments should mimic real‑world failures:

  • node shutdown
  • pod eviction
  • network partition
  • DNS failure
  • container crash loops
  • storage throttling

Chaos must be representative, not random.

3. Observe System Behavior

Use Kubernetes observability tools:

  • Prometheus metrics
  • Loki logs
  • Jaeger/Tempo traces
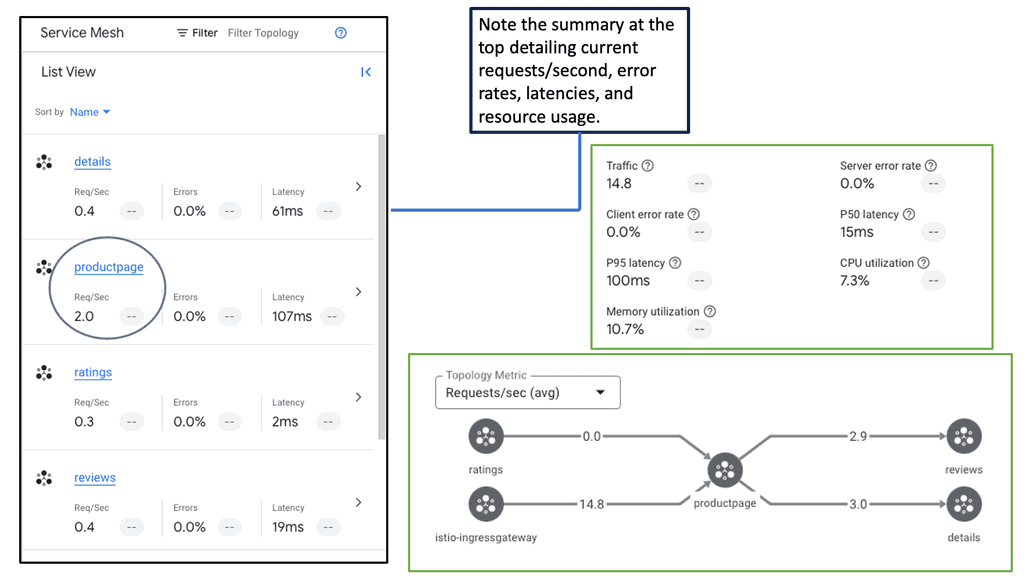
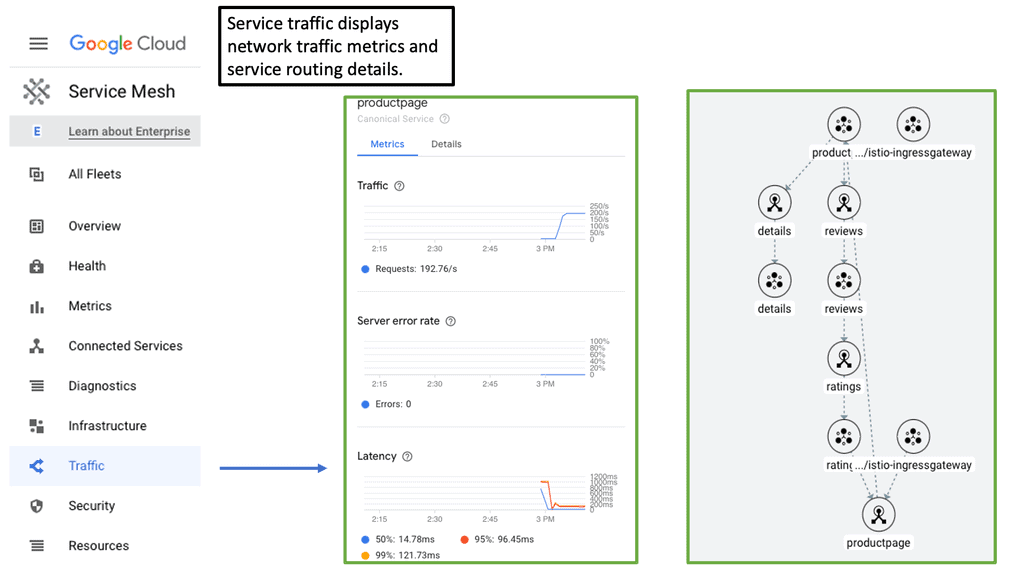
  • Kiali (service mesh)
  • OpenTelemetry pipelines

Chaos without observability is just destruction.

4. Improve and Repeat

Chaos engineering is iterative.

Each experiment reveals weaknesses that must be fixed, validated, and re‑tested.

Common Chaos Experiments in Kubernetes

Here are the most valuable chaos tests for real‑world clusters:

1. Pod Kill / Pod Restart

Simulates container crashes.

Validates:

  • readiness/liveness probes
  • retry logic
  • graceful shutdown
  • autoscaling behavior

2. Node Failure / Node Drain

Simulates hardware failure or maintenance.

Validates:

  • pod rescheduling
  • replica distribution
  • disruption budgets
  • cluster autoscaler behavior

3. Network Latency / Packet Loss

Simulates degraded network conditions.

Validates:

  • microservices resilience
  • timeout handling
  • circuit breakers
  • service mesh routing

4. API Server Stress

Simulates control‑plane overload.

Validates:

  • controller stability
  • admission webhook behavior
  • cluster responsiveness

5. Storage Throttling / Volume Detach

Simulates slow or failing storage.

Validates:

  • database failover
  • persistent volume resilience
  • application retry logic

6. Service Mesh Failure

Simulates sidecar or proxy issues.

Validates:

  • fallback routing
  • mesh control‑plane resilience
  • degraded mode behavior

Chaos Engineering + Kubernetes Operators

Operators automate application lifecycle management.

Chaos engineering validates operator logic:

  • reconciliation loops
  • state recovery
  • CRD consistency
  • failover automation

If an operator cannot recover state after chaos, it is not production‑ready.

Chaos Engineering for Security

Chaos engineering can also test security controls:

  • RBAC misconfigurations
  • network policy gaps
  • pod escape attempts
  • privilege escalation
  • secret rotation failures

Security chaos engineering ensures Zero Trust principles hold under stress.

Tools for Kubernetes Chaos Engineering

Popular tools include:

  • LitmusChaos — CNCF project for Kubernetes chaos workflows
  • Chaos Mesh — powerful, Kubernetes‑native chaos platform
  • Gremlin — enterprise chaos engineering suite
  • Kube‑Monkey — pod‑kill chaos inspired by Netflix’s Chaos Monkey

These tools integrate with CI/CD pipelines, allowing chaos tests to run automatically.

Outcome — A Resilient, Self‑Healing Kubernetes Platform

Chaos engineering ensures Kubernetes workloads:

  • survive node failures
  • recover from pod crashes
  • tolerate network degradation
  • handle storage instability
  • maintain service reliability
  • enforce security under stress

Chaos engineering transforms Kubernetes from “works in ideal conditions” to “works under real‑world failure.”

Implementing Chaos Engineering

Implementing Chaos Engineering involves several steps. First, start by defining a “steady state” of your system’s normal operations. Next, develop hypotheses about potential failure points and design experiments to test these. Use tools like Chaos Monkey or Gremlin to introduce controlled disruptions and observe the outcomes. Finally, analyze the results and apply any necessary changes to improve system resilience.

Challenges and Considerations

While Chaos Engineering offers many benefits, it also presents challenges. Resistance from stakeholders who are wary of intentional disruptions can be a hurdle. Additionally, ensuring that experiments are conducted safely and do not impact customers is crucial. To overcome these challenges, it’s important to foster a culture of transparency, continuous learning, and collaboration among teams.

Benefits of Chaos Engineering in Kubernetes:

1. Enhanced Reliability: By subjecting Kubernetes deployments to controlled failures, Chaos Engineering helps organizations identify weak points and vulnerabilities, enabling them to build more resilient systems that can withstand unforeseen events.

2. Improved Incident Response: Chaos Engineering allows organizations to test and refine their incident response processes by simulating real-world failures. This helps teams understand how to quickly detect and mitigate potential issues, reducing downtime and improving the overall incident response capabilities.

3. Cost Optimization: Chaos engineering can help optimize resource utilization within a Kubernetes cluster by identifying and addressing performance bottlenecks and inefficient resource allocation. This, in turn, leads to cost savings and improved efficiency.

Personal Note: Today’s standard explanation for Chaos Engineering is “The facilitation of experiments to uncover systemic weaknesses.” The following is true for Chaos Engineering.

  1. Begin by defining “steady state” as some measurable output of a system that indicates normal behavior.
  2. Hypothesize that this steady state will persist in both the control and experimental groups.
  3. Submit variables that mirror real-world events like servers that crash, hard drives that malfunction, severed network connections, etc.
  4. Then, as a final step, try to disprove the hypothesis by looking for a steady-state difference between the control and experimental groups.

Chaos Engineering Scenarios in Kubernetes:

Chaos Engineering in Kubernetes involves deliberately introducing failures into the system to observe how it behaves and recovers. This proactive approach enables teams to understand the system’s response to unexpected disruptions, whether it’s a pod failure, network latency, or a node shutdown.

**Implementing Chaos Experiments in Kubernetes**

To harness the full potential of Chaos Engineering, it’s essential to implement chaos experiments thoughtfully. Start by identifying critical components of your Kubernetes cluster that need testing. Tools like LitmusChaos and Chaos Mesh provide a framework for defining and executing chaos experiments. These experiments simulate disruptions such as pod deletions, CPU stress, and network partitioning, allowing teams to evaluate system behavior and improve fault tolerance.

**Chaos Engineering Kubernetes**

1. Pod Failures: Simulating failures of individual pods within a Kubernetes cluster allows organizations to evaluate how the system responds to such events. By randomly terminating pods, Chaos Engineering can help ensure that the system can handle pod failures gracefully, redistributing workload and maintaining high availability.

2. Network Partitioning: Introducing network partitioning scenarios can help assess the resilience of a Kubernetes cluster. By isolating specific nodes or network segments, Chaos Engineering enables organizations to test how the group reacts to network disruptions and evaluate the effectiveness of load balancing and failover mechanisms.

3. Resource Starvation: Chaos Engineering can simulate resource scarcity scenarios by intentionally consuming excessive resources, such as CPU or memory, within a Kubernetes cluster. This allows organizations to identify potential performance bottlenecks and optimize resource allocation strategies.

Understanding GKE-Native Monitoring

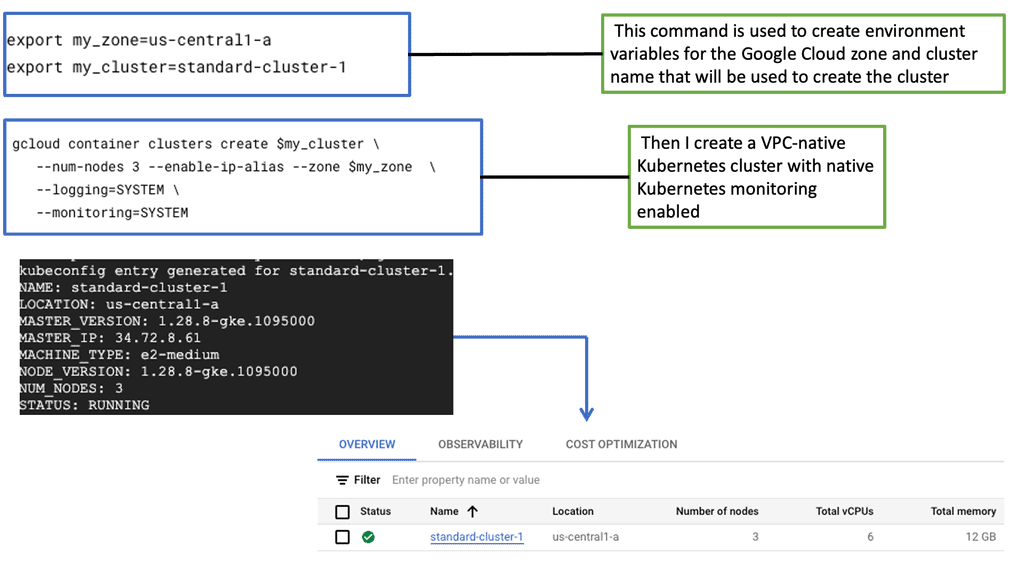
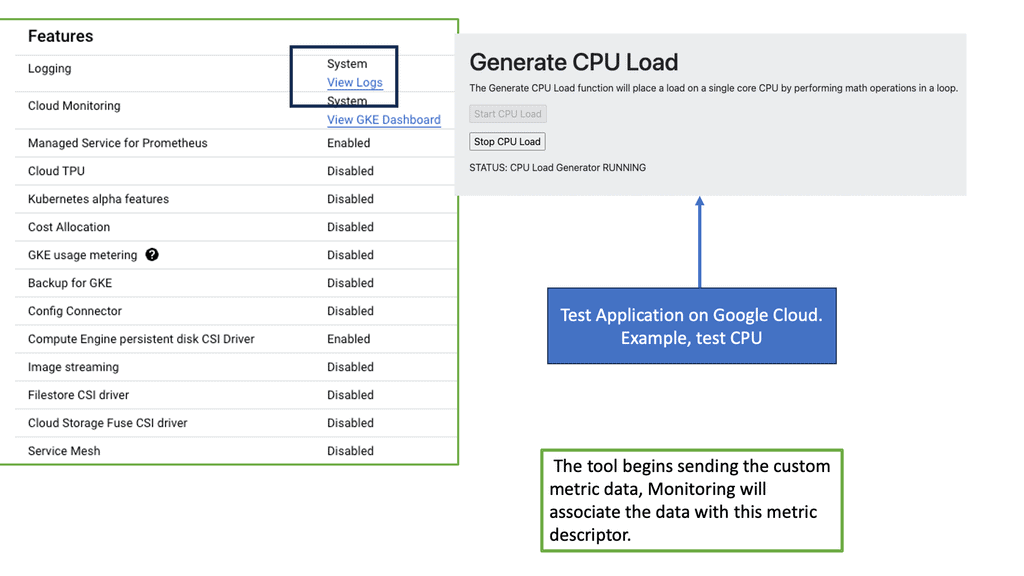
GKE-Native Monitoring is a comprehensive solution designed for Google Kubernetes Engine (GKE). It empowers developers and operators with real-time insights into the health and performance of their Kubernetes clusters, pods, and containers. Leveraging the power of Prometheus, GKE-Native Monitoring offers a wide range of monitoring metrics, such as CPU and memory utilization, network traffic, and custom application metrics.

GKE-Native Monitoring: Features

GKE-Native Monitoring boasts several key features that enhance observability and troubleshooting capabilities. One notable feature is the ability to create custom dashboards, enabling users to visualize and analyze critical metrics tailored to their needs. GKE-Native Monitoring integrates seamlessly with Stackdriver, Google Cloud’s unified monitoring and logging platform, allowing for centralized management and alerting across multiple GKE clusters.
The Rise of Chaos Engineering

Infrastructure is becoming increasingly complex, and let’s face it, a lot can go wrong. It’s imperative to have a global view of all the infrastructure components and a good understanding of the application’s performance and health. In a large-scale container-based application design, there are many moving pieces and parts, and trying to validate the health of each piece manually is hard. 

With these new environments, especially cloud-native at scale. Complexity is at its highest, and many more things can go wrong. For this reason, you must prepare as much as possible so the impact on users is minimal.

So, the dynamic deployment patterns you get with frameworks with Kubernetes allow you to build better applications. But you need to be able to examine the environment and see if it is working as expected. Most importantly, this course’s focus is that to prepare effectively, you need to implement a solid strategy for monitoring in production environments.

Chaos Engineering Kubernetes

For this, you need to understand practices and tools like Chaos Engineering and how they can improve the reliability of the overall system. Chaos Engineering is the ability to perform tests in a controlled way. Essentially, we intentionally break things to learn how to build more resilient systems.

So, we are injecting faults in a controlled way to make the overall application more resilient by injecting various issues and faults. It comes down to a trade-off and your willingness to accept it. There is a considerable trade-off with distributed computing. You have to monitor efficiently, have performance management, and, more importantly, accurately test the distributed system in a controlled manner. 

Service Mesh Chaos Engineering

 Service Mesh is an option to use to implement Chaos Engineering. You can also implement Chaos Engineering with Chaos Mesh, a cloud-native Chaos Engineering platform that orchestrates tests in the Kubernetes environment. The Chaos Mesh project offers a rich selection of experiment types. Here are the choices, such as the POD lifecycle test, network test, Linux kernel, I/O test, and many other stress tests.

Implementing practices like Chaos Engineering will help you understand and manage unexpected failures and performance degradation. The purpose of Chaos Engineering is to build more robust and resilient systems. 

Cloud Service Mesh:

### The Role of Cloud Service Mesh in Modern Architecture

Traditional monolithic applications are being replaced by microservices architectures, which break down applications into smaller, independent services. While this shift offers numerous benefits such as scalability and flexibility, it also introduces complexities in managing the interactions between these services. This is where a Cloud Service Mesh comes into play. It provides a structured method to handle service discovery, load balancing, failure recovery, metrics, and monitoring without adding heavy burdens to the developers.

### Google’s Pioneering Efforts in Cloud Service Mesh

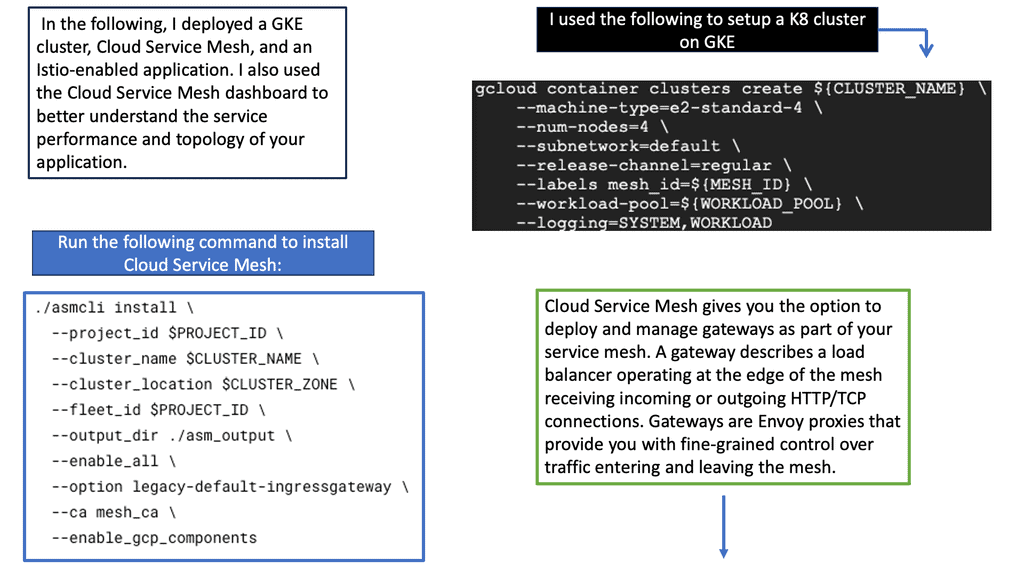
Google has been at the forefront of cloud innovation, and its contributions to the development of Cloud Service Mesh technologies are no exception. Through its open-source project Istio, Google has provided a robust framework for managing microservices.

Istio simplifies the observability, security, and management of microservices, making it easier for enterprises to adopt and scale their cloud-native applications. By integrating Istio with their Google Kubernetes Engine (GKE), Google has made it seamless for organizations to deploy and manage their service meshes.
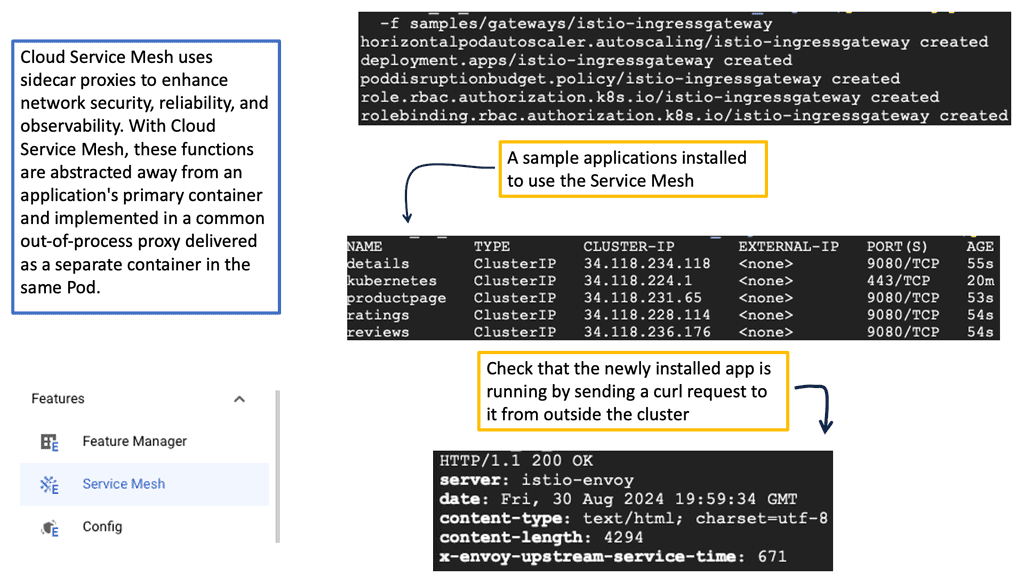
### Enhancing Reliability with Chaos Engineering

One of the most intriguing aspects of utilizing a Cloud Service Mesh is its ability to enhance system reliability through Chaos Engineering. This practice involves intentionally injecting faults into the system to test its resilience and identify potential weaknesses.

By simulating real-world failures, organizations can better prepare for unexpected issues and ensure their services remain robust under pressure. The granular control provided by a Cloud Service Mesh makes it an ideal platform for implementing Chaos Engineering practices, helping to create more resilient and dependable cloud environments.
 

Interactive Chaos Engineering / Kubernetes Failure Lab

Kubernetes Failure Injection

Select a realistic failure scenario and trace what should happen next: failure injection, Kubernetes response, application impact and recovery. The goal is not to break Kubernetes randomly — it is to test a resilience hypothesis.

Selected Experiment
Pod Failure
Terminate one application pod and observe whether the Service continues directing traffic to healthy replicas while the Deployment recreates the failed workload.
◆
Application
→
×
Pod Fails
→
↻
Replica Recovery
→
✓
Service Restored
Failure Injected Application pod termination
Kubernetes Reaction Controller recreates the desired replica
What To Observe Endpoint health, pod readiness and request errors
Recovery Signal Healthy replica returns to service
Potential Impact: A correctly configured replicated application should experience little or no user-visible disruption.
Experiment Console
chaos-engineering / kubernetes
$ experiment --scenario pod-failure
[baseline] replicas=3 ready=3 error_rate=0.3%
[inject] terminating pod/frontend-7d8c9
[event] pod state=Terminating
[controller] desired replicas=3
[scheduler] replacement pod created
[recovery] replicas=3 ready=3
Experiment Complete
The simulated failure was introduced and the recovery path completed. Check whether the application remained inside its reliability objectives.
Engineering Takeaway: Each chaos experiment should connect a realistic failure to an expected Kubernetes response and a measurable recovery signal. The question is not simply “did something break?” — it is “did the platform and application recover the way we designed them to?”

Chaos Engineering Kuberentes

Monitoring & Troubleshooting 

Beyond the Complexity Horizon

Therefore, monitoring and troubleshooting are much more demanding, as everything is interconnected, making it difficult for a single person in one team to understand what is happening entirely. The edge of the network and application boundary surpasses one location and team. Enterprise systems have gone beyond the complexity horizon, and you can’t understand every bit of every single system.

Even if you are a developer closely related to the system and truly understand the nuts and bolts of the application and its code, no one can understand every bit of every single system.  So, finding the correct information is essential, but once you see it, you have to give it to those who can fix it. So monitoring is not just about finding out what is wrong; it needs to alert, and these alerts need to be actionable.

Troubleshooting: Chaos engineering kubernetes

– Chaos Engineering aims to improve a system’s reliability by ensuring it can withstand turbulent conditions. Chaos Engineering makes Kubernetes more secure. So, if you are adopting Kubernetes, you should adopt Chaos Engineering as an integral part of your monitoring and troubleshooting strategy.

– Firstly, we can pinpoint the application errors and understand, at best, how these errors arose. This could be anything from badly ordered scripts on a web page to a database query that has bad sequel calls or even unoptimized code-level issues.

– Or there could be something more fundamental going on. It is expected to have issues with how something is packaged into a container. You can pull in the incorrect libraries or even use a debug version of the container.

– Or there could be nothing wrong with the packaging and containerization of the container; it is all about where the container is being deployed. There could be something wrong with the infrastructure, either a physical or logical problem—incorrect configuration or a hardware fault somewhere in the application path.

**Non-ephemeral and ephemeral services**

With the introduction of containers and microservices observability, monitoring solutions need to manage non-ephemeral and ephemeral services. We are collecting data for applications that consist of many different benefits.

So when it comes to container monitoring and performing chaos engineering kubernetes tests, we need to understand the nature and the full application that lies upon it. Everything is dynamic by nature. It would be best if you had monitoring and troubleshooting in place that can handle the dynamic and transient nature. When monitoring a containerized infrastructure, you should consider the following.

A: Container Lifespan: Containers have a short lifespan; they are provisioned and commissioned based on demand. This is compared to VMs or bare-metal workloads, which generally have a longer lifespan. As a generic guideline, containers have an average lifespan of 2.5 days, while traditional and cloud-based VMs have an average lifespan of 23 days. Containers can move, and they do move frequently.

One day, we could have workload A on cluster host A, and the next day or even on the same day, the same cluster host could be hosting Application workload B. Therefore, different types of impacts could depend on the time of day.

B: Containers are Temporary: Containers are dynamically provisioned for specific use cases temporarily. For example, we could have a new container based on a specific image. New network connections, storage, and any integrations to other services that make the application work will be set up for that container. All of this is done dynamically and can be done temporarily.

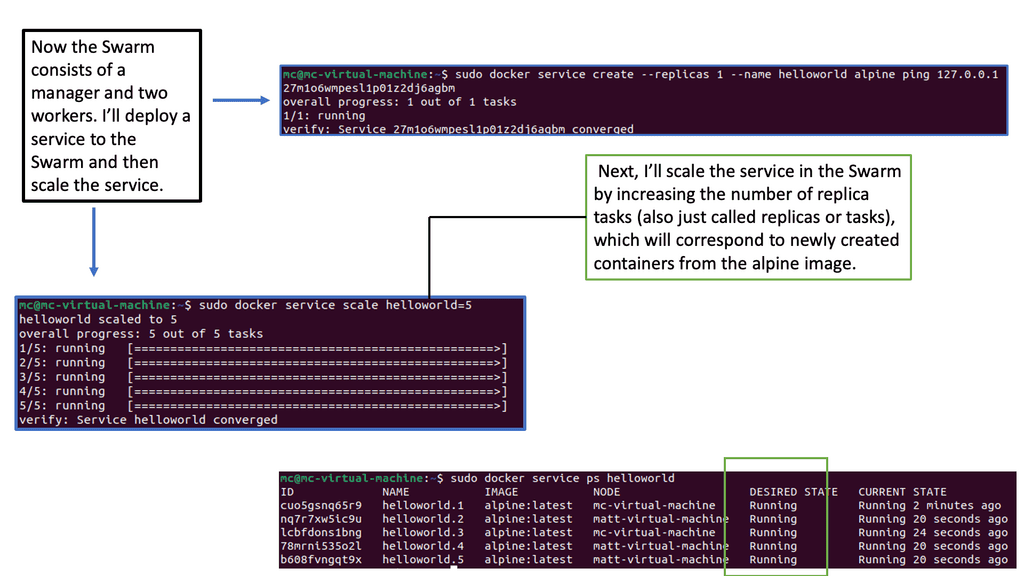
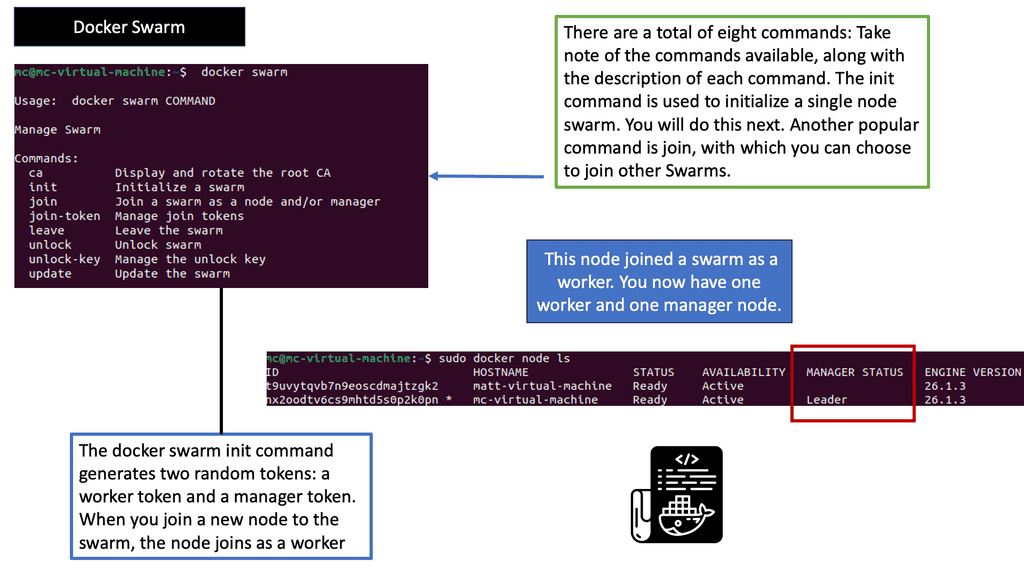
Example: Orchestration with Docker Swarm
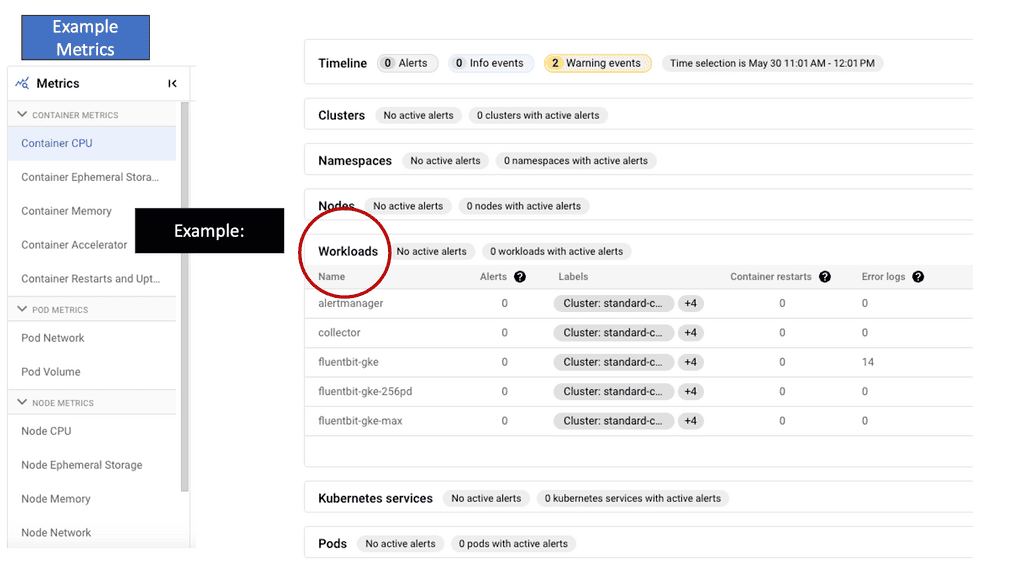
C: Different monitoring levels: In a Kubernetes environment, there are many monitoring levels. The components that make up the Kubernetes deployment will affect application performance. We have nodes, pods, and application containers. We also monitor at different levels, such as the VM, storage, and microservice levels.

D: Microservices change fast and often: Microservices consist of constantly evolving apps. New microservices are added, and existing ones are decommissioned quickly. So, what does this mean to usage patterns? This will result in different usage patterns on the infrastructure. If everything is often changing, it can be hard to derive the baseline and build a topology map unless you have something automatic in place. 

E: Metric overload: We now have loads of metrics, including additional metrics for the different containers and infrastructure levels. We must consider metrics for the nodes, cluster components, cluster add-on, application runtime, and custom application metrics. This is compared to a traditional application stack, where we use metrics for components such as the operating system and the application. 

Metric Explosion

Note: Prometheus Scrapping Metrics

In the traditional world, we didn’t have to be concerned with the additional components such as an orchestrator or the dynamic nature of many containers. With a container cluster, we must consider metrics from the operating system, application, orchestrator, and containers.  We refer to this as a metric explosion. So now we have loads of metrics that need to be gathered. There are also different ways to pull or scrape these metrics.

Prometheus is expected in the world of Kubernetes and uses a very scalable pull approach to getting those metrics from HTTP endpoints either through Prometheus client libraries or exports.
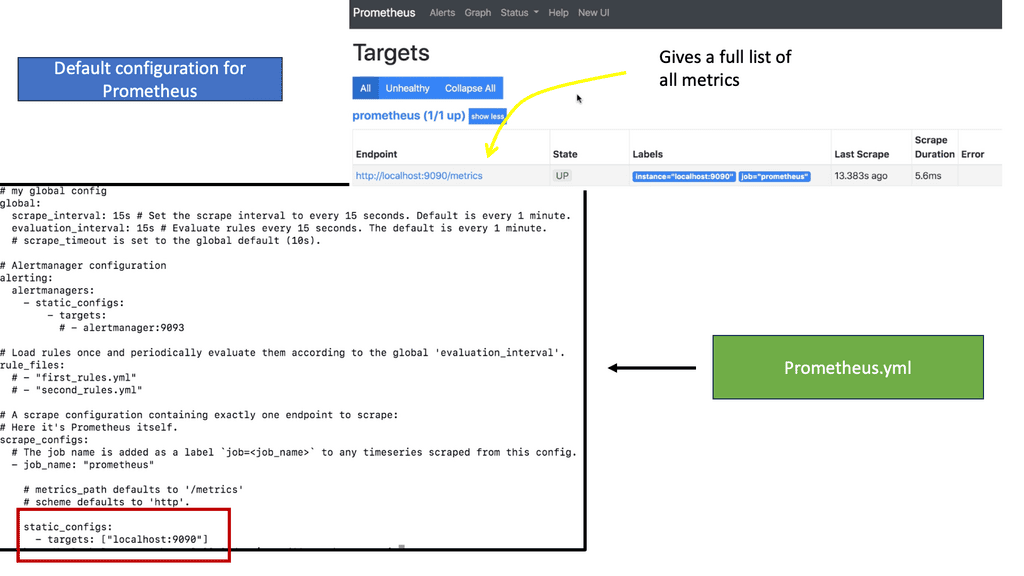
Prometheus YAML file
Diagram: Prometheus YAML file

**A key point: What happens to visibility**  

So, we need complete visibility now more than ever—not just for single components but visibility at a holistic level. Therefore, we need to monitor a lot more data points than we had to in the past. We need to monitor the application servers, Pods and containers, clusters running the containers, the network for service/pod/cluster communication, and the host OS.

All of the monitoring data needs to be in a central place so trends can be seen and different queries to the data can be acted on. Correlating local logs would be challenging in a sizeable multi-tier application with docker containers. We can use Log forwarders or Log shippers, such as FluentD or Logstash, to transform and ship logs to a backend such as Elasticsearch.

**A key point: New avenues for monitoring**

Containers are the norm for managing workloads and adapting quickly to new markets. Therefore, new avenues have opened up for monitoring these environments. So we have, for example, AppDynamics and Elastic search, which are part of the ELK stack, and the various log shippers that can be used to help you provide a welcome layer of unification. We also have Prometheus to get metrics. Keep in mind that Prometheus works only in the land of metrics. There will be different ways to visualize all this data, such as Grafana and Kibana. 

Distributed Systems Visbility

What happens to visibility? We need complete visibility now more than ever, not just for single components but at a holistic level. Therefore, we need to monitor a lot more data points than we had to in the past. We need to monitor the application servers, Pods and containers, clusters running the containers, the network for service/pod/cluster communication, and the host OS. 

All of the monitoring data needs to be in a central place so trends can be seen and different queries to the data can be acted on. Correlating local logs would be challenging in a sizeable multi-tier application with docker containers. We can use Logforwarders or Log shippers, such as FluentD or Logstash, to transform and ship logs to a backend such as Elasticsearch.

Containers are the norm for managing workloads and adapting quickly to new markets. Therefore, new avenues have opened up for monitoring these environments. So, I have mentioned AppDynamics, Elastic search, which is part of the ELK stack, and the various log shippers that can be used to help you provide a layer of unification. We also have Prometheus. There will be different ways to visualize all this data, such as Grafana and Kibana. 

A: – Microservices Complexity

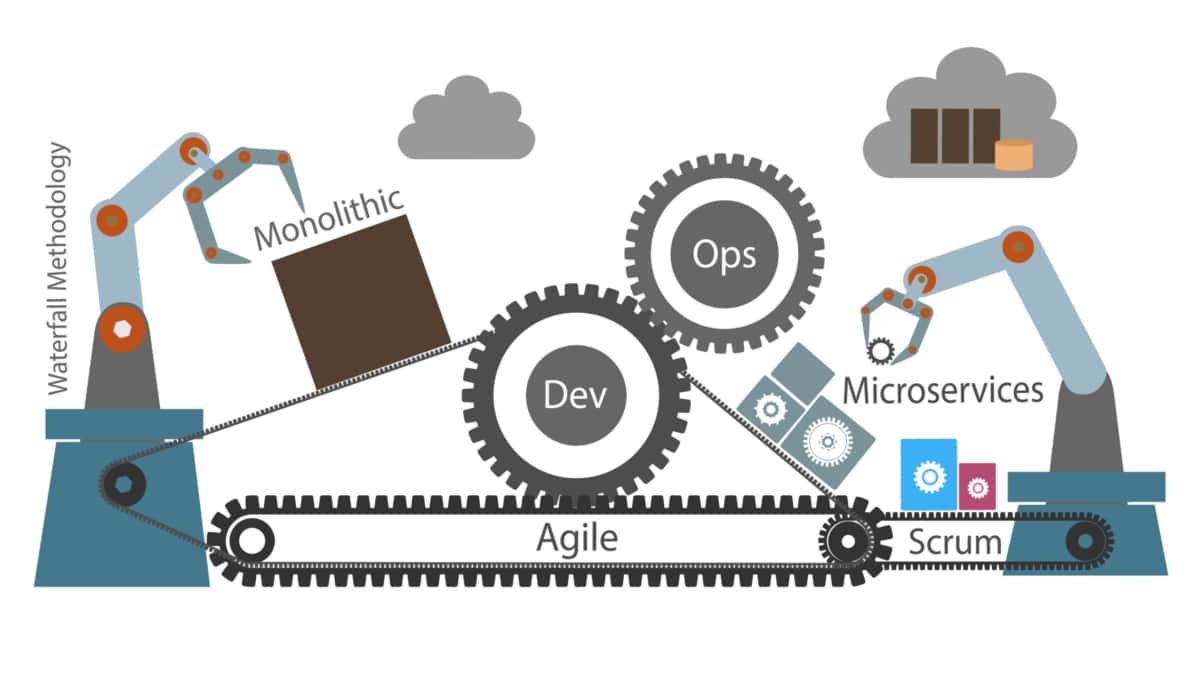
With the wave towards microservices, we get the benefits of scalability and business continuity, but managing them is very complex. The monolith is much easier to manage and monitor. Also, as separate components, they don’t need to be written in the same language or toolkits, so you can mix and match different technologies.

This approach has a lot of flexibility, but we can increase latency and complexity. There are a lot more moving parts that will increase complexity.

We have, for example, reverse proxies, load balancers, firewalls, and other infrastructure support services. What used to be method calls or interprocess calls within the monolith host now go over the network and are susceptible to deviations in latency. 

B: – Debugging Microservices

With the monolith, the application is simply running in a single process, and it is relatively easy to debug. Many traditional tooling and code instrumentation technologies have been built, assuming you have the idea of a single process. However, with microservices, we have a completely different approach with a distributed application.

Now, your application has multiple processes running in other places. The core challenge is trying to debug microservices applications.

So much of the tooling we have today has been built for traditional monolithic applications. So, there are new monitoring tools for these new applications, but there is a steep learning curve and a high barrier to entry. New tools and technologies such as distributed tracing and chaos engineering kubernetes are not the simplest to pick up on day one.

C: – Automation and monitoring

Automation comes into play with the new environment. With automation, we can do periodic checks not just on the functionality of the underlying components but also implement health checks of how the application performs. All can be automated for specific intervals or in reaction to certain events.

With the rise of complex systems and microservices, it is more important to have real-time performance monitoring and metrics that tell you how the systems behave. For example, what is the usual RTT, and how long can transactions occur under normal conditions?
Interactive Chaos Engineering / Observability Lab

Observability & Resilience

A chaos experiment is only useful if you can prove what happened, where it happened, how the application responded, and whether the system recovered.

Select Incident
Kubernetes Service Path
User Request
→
Ingress Entry point
→
Service Discovery
→
Pods Failure target
→
Node Compute
→
Cluster Control plane
Observability Signal Matrix

Metrics

p99 142ms
errors 0.3%

Quantifies system behaviour and SLO impact.

Logs

request OK
pod Ready

Shows application and component-level evidence.

Traces

124ms total
service OK

Shows where request time or failure occurred.

Events

Normal
Ready

Provides Kubernetes lifecycle evidence.

SLO

99.98%
Healthy

Connects telemetry to user-facing reliability.

Incident Timeline BASELINE
00:00
Baseline established — application operating normally.
00:05
Observability signals are within expected thresholds.
Engineering Takeaway

Never treat a single dashboard metric as proof of recovery. Correlate metrics, logs, traces and Kubernetes events, then verify that the user-facing SLO has returned to its expected state.

Reliability in Distributed Systems

Reliability In Distributed System

Reliability In Distributed System

Distributed systems are now fundamental to modern computing. Cloud platforms, payment systems, e-commerce applications, content delivery networks, databases, telecommunications services, and AI platforms all depend on multiple machines and services working together across networks. This architecture provides scalability, flexibility, and resilience, but it also introduces a fundamental engineering problem: components can fail independently while the overall system is expected to continue operating.

Reliability in a distributed system is therefore not simply a question of whether individual servers are available. It is the ability of the overall system to continue providing correct and useful behaviour despite failures, delays, network problems, overloaded components, software defects, and unexpected operating conditions. A reliable architecture assumes that failures will occur and is designed to contain their impact rather than assuming that every component will always behave correctly.

Failure Models:

Distributed systems must account for different types of failure. A node may crash completely, a network connection may be interrupted, packets may be delayed or dropped, a dependency may become unavailable, or a service may respond much more slowly than expected. More complex failure models can also include partial failures, where one component remains operational while its communication with another component has failed. Designing around these failure modes is one of the central challenges of distributed-systems engineering.

Redundancy and Replication:

Redundancy reduces dependence on individual components. Data and services can be replicated across multiple nodes, availability zones, regions, or infrastructure domains. If one instance fails, another replica can potentially continue serving requests. However, replication introduces additional challenges around consistency, synchronisation, failover, and data correctness. Simply creating multiple copies does not automatically create a reliable system.

Quorum and Distributed Consensus:

When multiple replicas maintain shared state, the system needs rules for deciding which operations or versions of data should be accepted. Quorum-based approaches require a sufficient number of replicas to participate in an operation before it is considered successful. Distributed consensus algorithms such as Raft and Paxos provide mechanisms for multiple nodes to agree on a sequence of state changes despite certain failures. These mechanisms are particularly important for distributed databases, coordination services, and control planes.

Consistency and Availability:

Distributed systems often have to make explicit trade-offs between consistency, latency, availability, and partition tolerance. Network partitions are especially important because two parts of a distributed system may temporarily be unable to communicate while both remain operational. The system must define how it behaves during this period—for example, whether it prioritises serving requests, preserving strong consistency, or temporarily rejecting operations to protect data integrity.

Timeouts and Failure Detection:

A distributed system cannot normally distinguish perfectly between a failed component and a slow component. A request that has not produced a response may be delayed, dropped, or processed by a service that is temporarily overloaded. Timeouts therefore become an important reliability mechanism. Appropriate timeout policies prevent resources from being consumed indefinitely while allowing the system to detect unhealthy dependencies and initiate recovery actions.

Retries and Backoff:

Retries can improve resilience when failures are temporary, such as transient network errors or overloaded dependencies. However, uncontrolled retries can make an outage significantly worse by generating additional traffic against an already struggling service. Reliable systems therefore commonly use bounded retries, exponential backoff, jitter, and carefully selected retry policies. Applications should also understand whether an operation is safe to repeat.

Idempotency:

Idempotency is particularly important for distributed applications that perform operations such as payments, provisioning, or database updates. If a client sends a request and does not receive a response, it may not know whether the operation succeeded. Retrying the operation could therefore create a duplicate action unless the system provides an idempotency mechanism or otherwise guarantees safe repetition.

Circuit Breakers and Load Shedding:

A service should not continue sending requests to a dependency that is consistently failing or timing out. Circuit-breaker patterns can temporarily stop calls to an unhealthy dependency and allow the system to recover without continuously generating additional load. Load shedding provides another protection mechanism by deliberately rejecting lower-priority work when resources become constrained, preserving capacity for critical operations.

Graceful Degradation:

Reliability does not always mean providing every feature under every condition. A well-designed distributed application can degrade gracefully when dependencies fail. For example, a recommendation service might become unavailable while the core shopping experience continues operating. Cached data, reduced functionality, asynchronous processing, and prioritised workloads can allow critical user journeys to remain available during partial failures.

Data Durability and Recovery:

Availability is only one dimension of reliability. A system can remain online while still losing or corrupting data. Reliable architectures therefore require durable storage, backups, replication, recovery procedures, and clearly defined recovery objectives. Recovery Point Objectives determine how much data loss can be tolerated, while Recovery Time Objectives define how quickly a service should be restored after a major failure.

Observability and Reliability Engineering:

Reliability depends on knowing what the system is actually doing. Metrics, logs, traces, events, health checks, and distributed tracing provide the telemetry required to detect failures and understand their propagation across service dependencies. Service Level Indicators and Service Level Objectives can then turn reliability into measurable engineering targets. This connects distributed-systems design with modern SRE practices and error-budget management.

Failure Isolation:

One of the most important reliability principles is preventing a local failure from becoming a system-wide failure. Resource limits, bulkheads, independent failure domains, workload isolation, queue boundaries, and carefully designed service dependencies can limit the blast radius of an incident. The objective is not to eliminate every failure, but to ensure that an individual failure does not unnecessarily cascade through the entire platform.

Testing Distributed Failure:

Reliability cannot be demonstrated simply by testing normal operation. Systems should also be tested under realistic failure conditions. Controlled experiments can introduce network latency, packet loss, service failures, node termination, resource exhaustion, dependency failures, and other faults. Techniques such as chaos engineering can help determine whether the architecture actually behaves as expected when components fail.

Designing for Recovery:

Recovery should be treated as part of the architecture rather than as an emergency procedure added later. Services should have clearly defined health checks, restart behaviour, failover mechanisms, backup strategies, recovery procedures, and operational runbooks. Automated recovery can reduce the duration of incidents, but automation must also be designed carefully so that recovery mechanisms do not amplify an existing failure.

The key principle behind reliable distributed systems is simple: assume that components will fail, communication will sometimes be unreliable, and unexpected states will occur. Reliability comes from designing the system so that these failures are detected, isolated, contained, and recovered from without unnecessarily affecting users or compromising data.

Modern distributed systems therefore combine multiple reliability mechanisms rather than relying on a single technology. Replication provides redundancy, consensus coordinates shared state, timeouts and retries manage unreliable communication, circuit breakers and load shedding contain failures, observability provides operational visibility, and recovery mechanisms restore service after serious incidents.

Ultimately, reliability is an architectural property as much as an operational one. A distributed system becomes resilient when failure is treated as a normal condition that the design is explicitly prepared to handle. By combining fault isolation, replication, consistency strategies, graceful degradation, observability, and tested recovery procedures, organisations can build platforms that continue delivering critical services even when individual components—and sometimes entire infrastructure domains—fail.

Interactive Distributed Systems Lab 01

Distributed Reliability Decision Lab

Reliability engineering is about choosing the right mechanism for the failure mode. Diagnose the scenario, identify the dominant risk, and select the reliability pattern that best addresses it.

ENGINEERING CHALLENGE

A distributed application is experiencing intermittent failures. The system contains multiple services, replicated workloads and external dependencies. Your job is to choose the reliability mechanism that addresses each failure without simply adding more capacity.

Failure scenario
Scenario 1

Choose the reliability mechanism
Reliability assessment complete.
You have worked through five different failure modes. The key lesson is that reliability is not one feature or one product. Redundancy, replication, retries, circuit breaking, bulkheads and graceful degradation solve different classes of failure.
Engineering takeaway: Do not treat every distributed-system failure as a capacity problem. First identify the failure mode, then apply the reliability mechanism that limits its blast radius, preserves correctness, or enables recovery.

Highlights: Reliability In Distributed System

Understanding Distributed Systems

At their core, distributed systems consist of multiple interconnected nodes working together to achieve a common goal. These nodes can be geographically dispersed and communicate through various protocols. Understanding the structure and behavior of distributed systems is crucial before exploring reliability measures.

To grasp the inner workings of distributed systems, it’s essential to familiarize ourselves with their key components. These include communication protocols, consensus algorithms, fault tolerance mechanisms, and distributed data storage. Each component plays a crucial role in ensuring the reliability and efficiency of distributed systems.

– Challenges and Risks: Reliability in distributed systems faces several challenges and risks due to their inherent nature. Network failures, node crashes, message delays, and data inconsistency are common issues compromising system reliability. Furthermore, the complexity of these systems amplifies the difficulty of diagnosing and resolving failures promptly.

– Replication and Redundancy: To mitigate the risks associated with distributed systems, replication and redundancy techniques are employed. Replicating data and functionalities across multiple nodes ensures fault tolerance and enhances reliability. The system can continue to operate with redundant components even if specific nodes fail.

– Consistency and Coordination: Maintaining data consistency is crucial in distributed systems. Distributed consensus protocols, such as the Paxos or Raft consensus algorithms, ensure that all nodes agree on the same state despite failures or network partitions. Coordinating actions among distributed nodes is essential to prevent conflicts and ensure reliable system behavior.

– Monitoring and Failure Detection: Continuous monitoring and failure detection mechanisms are essential for identifying and resolving issues promptly. Various monitoring tools and techniques, such as heartbeat protocols and health checks, can help detect failures and initiate recovery processes. Proactive monitoring and regular maintenance significantly contribute to the overall reliability of distributed systems.

**Shift in Landscape**

When considering reliability in a distributed system, considerable shifts in our environmental landscape have caused us to examine how we operate and run our systems and networks. We have had a mega change with the introduction of various cloud platforms and their services and containers.

In addition, with the complexity of managing distributed systems observability and microservices observability that unveil significant gaps in current practices in our technologies. Not to mention the flaws with the operational practices around these technologies.

Reliability in Distributed Systems

Reliability in distributed systems means ensuring that a system continues to operate correctly even when individual components fail, networks partition, nodes crash, messages arrive late, or workloads spike unexpectedly. Distributed systems are inherently unreliable — so reliability must be engineered deliberately through redundancy, consistency models, fault‑tolerance, and observability.

Below is a structured, high‑clarity section you can drop directly into your distributed systems or SRE content.

Core Goal of Reliability

A reliable distributed system continues to deliver correct results despite failures, despite scale, and despite complexity.

Reliability is achieved through:

  • fault tolerance

  • redundancy

  • consistency guarantees

  • replication

  • observability

  • SLOs

  • graceful degradation

Why Reliability Is Hard in Distributed Systems

Distributed systems fail in non‑linear ways:

  • partial failures

  • network partitions

  • retry storms

  • cascading latency

  • inconsistent replicas

  • clock drift

  • leader election failures

  • multi‑region divergence

Reliability must be engineered at every layer.


Key Reliability Techniques

1. Replication

Replicate data and services across nodes or regions:

  • active‑active

  • active‑standby

  • quorum‑based replication

  • multi‑region replication

Ensures availability even if nodes fail.

2. Fault Tolerance

Systems must continue operating during failures:

  • retry logic

  • circuit breakers

  • backpressure

  • failover routing

  • leader election (Raft, Paxos)

Fault tolerance prevents cascading failures.

3. Consistency Models

Choose the right consistency level:

  • strong consistency

  • eventual consistency

  • causal consistency

  • read‑your‑writes

Consistency affects correctness and user experience.

4. Redundancy

Redundant:

  • nodes

  • services

  • network paths

  • storage

  • load balancers

Redundancy eliminates single points of failure.

5. Graceful Degradation

If parts fail, the system still works:

  • disable non‑critical features

  • reduce load

  • serve cached data

  • fallback logic

Users experience reduced functionality, not outages.

6. Observability

Reliability requires visibility:

  • metrics

  • logs

  • traces

  • dependency maps

  • SLO burn rate

Observability reveals why failures occur.

Reliability Patterns in Distributed Systems

Circuit Breaker Pattern

Stops calling failing services to prevent cascading failures.

Bulkhead Pattern

Isolates components so one failure doesn’t sink the entire system.

Retry + Backoff

Retries failed operations with exponential backoff to avoid overload.

Leader Election

Ensures a single authoritative node manages coordination.

Idempotency

Allows safe retries without duplicating operations.

Event Sourcing

Stores state as events for replay and recovery.

Chaos Engineering

Proactively tests reliability by injecting controlled failures.


Reliability in Cloud & Kubernetes

Distributed systems today run on:

  • Kubernetes

  • microservices

  • serverless

  • multi‑region cloud

Reliability requires:

  • HPA/VPA auto‑scaling

  • pod disruption budgets

  • node health checks

  • multi‑AZ deployments

  • service mesh retries + mTLS

  • distributed tracing

Outcome

Reliable distributed systems deliver:

  • predictable performance

  • resilience to node and network failures

  • consistent data across replicas

  • fast recovery from outages

  • strong SLO compliance

  • reduced downtime

  • improved user experience

Reliability transforms distributed systems from fragile, complex architectures into robust, fault‑tolerant, self‑healing platforms.

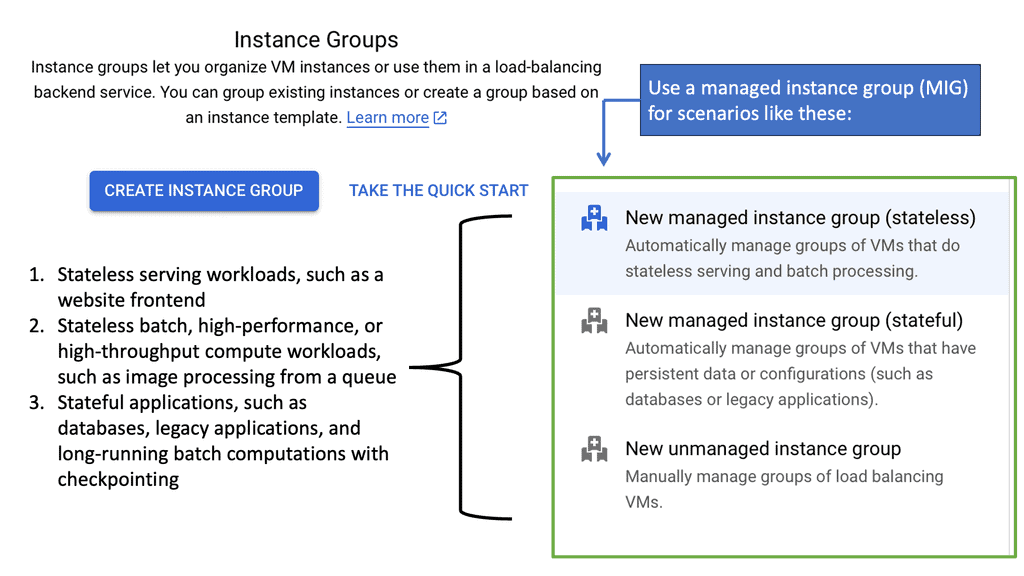
Managed Instance Groups (MIGs)

**Understanding the Basics of Managed Instance Groups**

Managed Instance Groups are collections of virtual machine (VM) instances that are treated as a single entity. They are designed to simplify the management of multiple instances by automating tasks like scaling, updating, and load balancing. With MIGs, you can ensure that your application has the right number of instances running at any given time, responding dynamically to changes in demand.

Google Cloud’s MIGs make it easy to deploy applications with high availability and reliability. By using templates, you can define the configuration for all instances in the group, ensuring consistency and reducing the potential for human error.

—

**Ensuring Reliability in Distributed Systems**

Reliability is a critical component of any distributed system, and Managed Instance Groups play a significant role in achieving it. By distributing workloads across multiple instances and regions, MIGs help prevent single points of failure. If an instance fails, the group automatically replaces it with a new one, minimizing downtime and ensuring continuous service availability.

Moreover, Google Cloud’s infrastructure ensures that your instances are backed by a robust network, providing low-latency access and high-speed connectivity. This further enhances the reliability of your applications and services, giving you peace of mind as you scale.

—

**Scaling with Ease and Flexibility**

One of the standout features of Managed Instance Groups is their ability to scale quickly and efficiently. Whether you’re dealing with sudden spikes in traffic or planning for steady growth, MIGs offer flexible scaling policies to meet your needs. You can scale based on CPU utilization, load balancing capacity, or even custom metrics, allowing for precise control over your application’s performance.

Google Cloud’s autoscaling capabilities mean you only pay for the resources you use, optimizing cost-efficiency while maintaining high performance. This flexibility makes MIGs an ideal choice for businesses looking to grow their cloud infrastructure without unnecessary expenditure.

—

**Integrating with Google Cloud Ecosystem**

Managed Instance Groups seamlessly integrate with other Google Cloud services, providing a cohesive ecosystem for your applications. They work in harmony with Cloud Load Balancing to distribute traffic efficiently and with Stackdriver for monitoring and logging, giving you comprehensive insights into your application’s performance.

By leveraging Google Cloud’s extensive suite of tools, you can build, deploy, and manage applications with greater agility and confidence. This integration streamlines operations and simplifies the complexities of managing a distributed system.

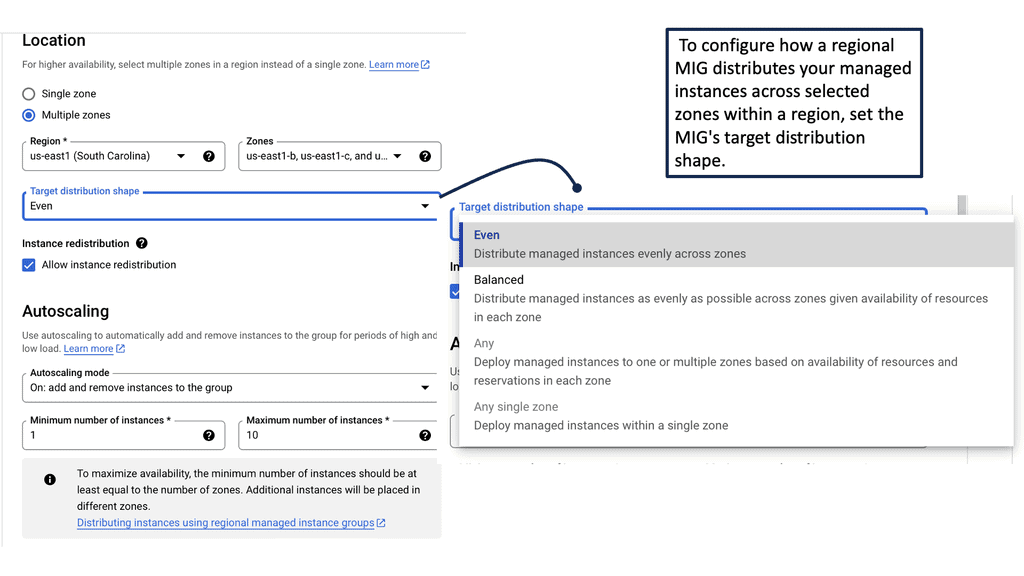
Managed Instance Group

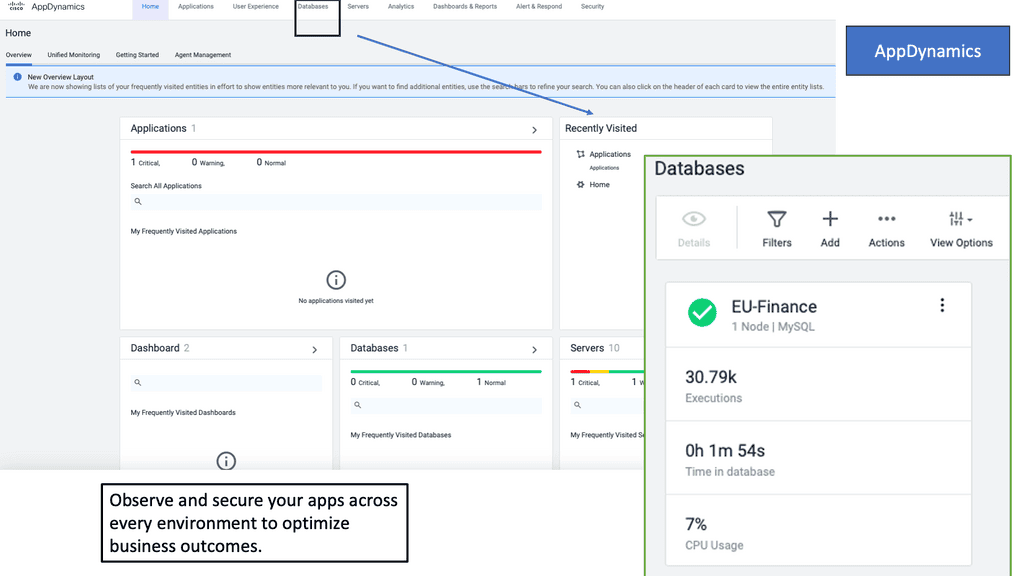
Example Product: Cisco AppDynamics

### What is Cisco AppDynamics?

Cisco AppDynamics is an application performance management (APM) solution that offers deep insights into your application’s performance, user experience, and business impact. It helps IT teams detect, diagnose, and resolve issues quickly, ensuring a seamless digital experience for end-users. By leveraging machine learning and artificial intelligence, AppDynamics provides actionable insights to optimize your applications.

### Key Features of Cisco AppDynamics

#### Real-Time Performance Monitoring

With Cisco AppDynamics, you can monitor the performance of your applications in real-time. This feature allows you to detect anomalies and performance issues as they happen, ensuring that you can address them before they impact your users.

#### End-User Monitoring

Understanding how your users interact with your applications is crucial. AppDynamics offers end-user monitoring, which provides visibility into the user journey, from the front-end user interface to the back-end services. This helps you identify and resolve issues that directly affect user experience.

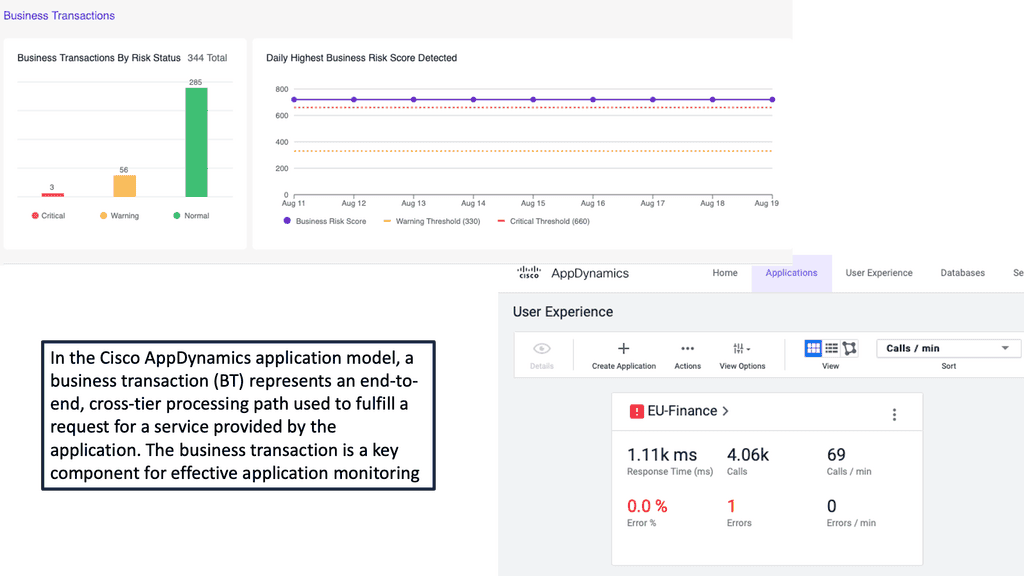
#### Business Transaction Monitoring

AppDynamics breaks down your application into business transactions, which are critical user interactions within your application. By monitoring these transactions, you can gain insights into how your application supports key business processes and identify areas for improvement.

#### AI-Powered Analytics

The platform’s AI-powered analytics enable you to predict and prevent performance issues before they occur. By analyzing historical data and identifying patterns, AppDynamics helps you proactively manage your application’s performance.

### Benefits of Using Cisco AppDynamics

#### Improved Application Performance

By continuously monitoring your application’s performance, AppDynamics helps you identify and resolve issues quickly, ensuring that your application runs smoothly and efficiently.

#### Enhanced User Experience

With end-user monitoring, you can gain insights into how users interact with your application and address any issues that may affect their experience. This leads to increased user satisfaction and retention.

#### Better Business Insights

Business transaction monitoring provides a clear understanding of how your application supports critical business processes. This helps you make data-driven decisions to optimize your application and drive business growth.

Monitoring GKE Environment

The Significance of Monitoring in GKE

Monitoring in GKE goes beyond simply monitoring resource utilization. It provides valuable insights into the health and performance of your Kubernetes clusters, nodes, and applications running within them. You gain a comprehensive understanding of your system’s behavior by closely monitoring key metrics such as CPU usage, memory utilization, and network traffic. You can proactively address issues before they escalate.

GKE-Native Monitoring has many powerful features that simplify the monitoring process. One notable feature is integrating with Stackdriver, Google Cloud’s monitoring and observability platform.

With this integration, you can access a rich set of monitoring tools, including customizable dashboards, alerts, and logging capabilities, all designed explicitly for GKE deployments. Additionally, GKE-Native Monitoring seamlessly integrates with other Google Cloud services, enabling you to leverage advanced analytics and machine learning capabilities.

Challenges to Gaining Reliability

**Existing Static Tools**

This has caused a knee-jerk reaction to a welcomed drive-in innovation to system reliability. Yet, some technologies and tools used to manage these innovations do not align with the innovative events. Many of these tools have stayed relatively static in our dynamic environment. So, we have static tools used in a dynamic environment, which causes friction to reliability in distributed systems and the rise for more efficient network visibility.

**Understanding the Complexity**

Distributed systems are inherently complex, with multiple components across different machines or networks. This complexity introduces challenges like network latency, hardware failures, and communication bottlenecks. Understanding the intricate nature of distributed systems is crucial to devising reliable solutions.

Gaining Reliability

**Redundancy and Replication**

One critical approach to enhancing reliability in distributed systems is redundancy and replication. By duplicating critical components or data across multiple nodes, the system becomes more fault-tolerant. This ensures the system can function seamlessly even if one component fails, minimizing the risk of complete failure.

**Consistency and Consensus Algorithms**

Maintaining consistency in distributed systems is a significant challenge due to the possibility of concurrent updates and network delays. Consensus algorithms, such as the Paxos or Raft algorithms, are vital in achieving consistency by ensuring agreement among distributed nodes. These algorithms enable reliable decision-making and guarantee that all nodes reach a consensus state.

**Monitoring and Failure Detection**

To ensure reliability, robust monitoring mechanisms are essential. Monitoring tools can track system performance, resource utilization, and network health. Additionally, implementing efficient failure detection mechanisms allows for prompt identification of faulty components, enabling proactive measures to mitigate their impact on the overall system.

**Load Balancing and Scalability**

Load balancing is crucial in distributing the workload evenly across nodes in a distributed system. It ensures that no single node is overwhelmed, reducing the risk of system instability. Furthermore, designing systems with scalability in mind allows for seamless expansion as the workload grows, ensuring that reliability is maintained even during periods of high demand.

Required: Distributed Tracing

Using distributed tracing, you can profile or monitor the results of requests across a distributed system. Distributed systems can be challenging to monitor since each node generates its logs and metrics. To get a complete view of a distributed system, it is necessary to aggregate these separate node metrics holistically. 

A distributed system generally doesn’t access its entire set of nodes but rather a path through those nodes. With distributed tracing, teams can analyze and monitor commonly accessed paths through a distributed system. The distributed tracing is installed on each system node, allowing teams to query the system for information on node health and performance.

Benefits: Distributed Tracing

Despite the challenges, distributed systems offer a wide array of benefits. One notable advantage is enhanced fault tolerance. Distributing tasks and data across multiple nodes improves system reliability, as a single point of failure does not bring down the entire system.

Additionally, distributed systems enable improved scalability, accommodating growing demands by adding more nodes to the network. The applications of distributed systems are vast, ranging from cloud computing and large-scale data processing to peer-to-peer networks and distributed databases.

Google Cloud Trace

Understanding Cloud Trace

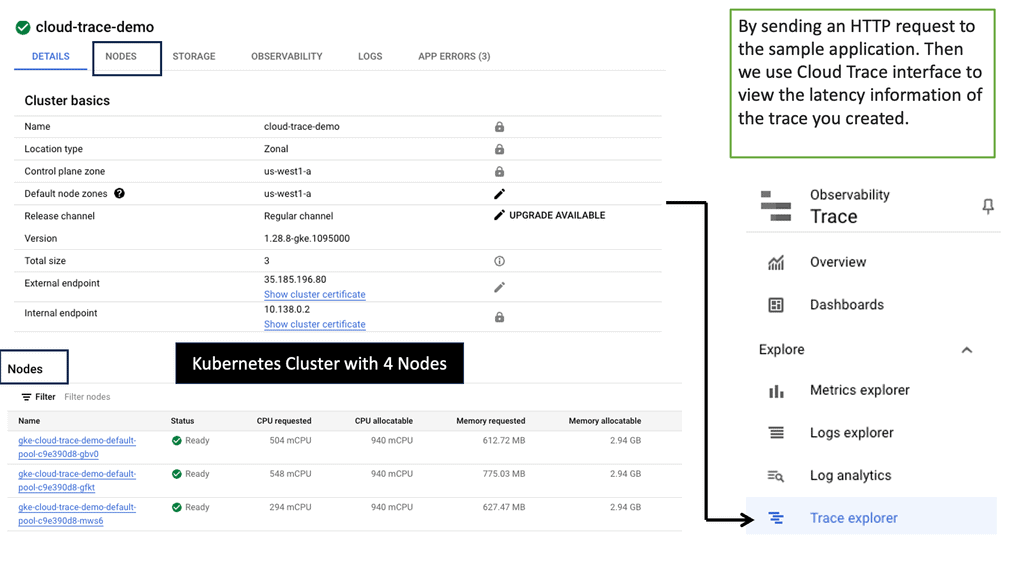
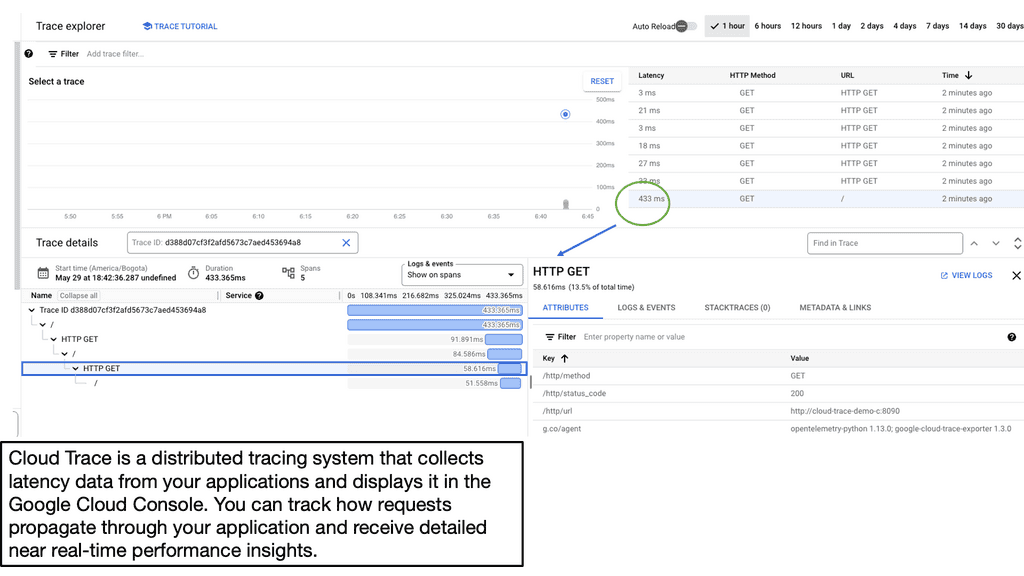
Cloud Trace, an integral part of Google Cloud’s observability offerings, provides developers with a detailed view of their application’s performance. It enables tracing and analysis of requests as they flow through different components of a distributed system. By visualizing the latency, bottlenecks, and dependencies, Cloud Trace empowers developers to optimize their applications for better performance and user experience.

Cloud Trace offers a range of features to simplify the monitoring and troubleshooting process. With its distributed tracing capabilities, developers can gain insights into how requests traverse various services, identify latency issues, and pinpoint the root causes of performance bottlenecks. The integration with Google Cloud’s ecosystem allows seamless correlation between traces and other monitoring data, enabling a comprehensive view of application health.

Improve Performance & Reliability 

By leveraging Cloud Trace, developers can significantly improve the performance and reliability of their applications. The ability to pinpoint and resolve performance issues quickly translates into enhanced user satisfaction and higher productivity. Moreover, Cloud Trace enables proactive monitoring, ensuring that potential bottlenecks and inefficiencies are identified before they impact end-users. For organizations, this translates into cost savings, improved scalability, and better resource utilization.

Adopting Cloud Trace

Cloud Trace has been adopted by numerous organizations across various industries, with remarkable outcomes. From optimizing the response time of e-commerce platforms to enhancing the efficiency of complex microservices architectures, Cloud Trace has proven its worth in diagnosing performance issues and driving continuous improvement. The real-time visibility provided by Cloud Trace empowers organizations to make data-driven decisions and deliver exceptional user experiences.


Interactive Distributed Systems Lab 02

Failure & Recovery Simulator

Distributed systems rarely fail cleanly. Inject a fault, observe how the failure propagates, detect the problem, and then recover the affected component.

SIMULATION OBJECTIVE

Select a failure mode and follow the recovery lifecycle: Healthy → Failure → Detection → Recovery. Notice how a local fault can create a wider degraded state when the architecture does not isolate the failure.

Live service topology
⇄
Load Balancer
Healthy
▣
Service A
Healthy
◈
Service B
Healthy
▤
Database
Healthy
Inject a failure
System state
Overall service HEALTHY
Failure detection READY
Recovery STANDBY
Event console

Reliability In Distributed System

Adopting Distributed Systems

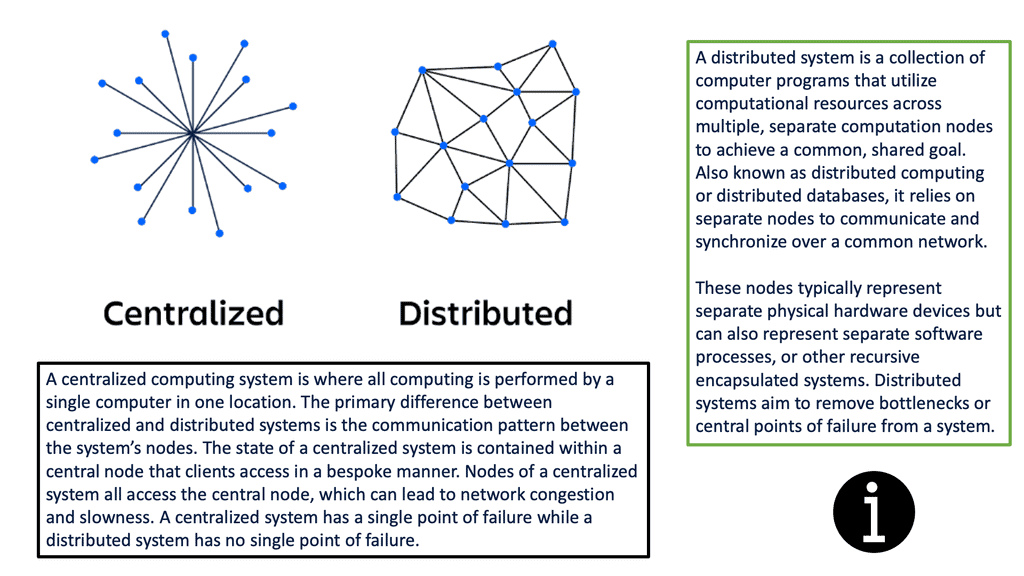
Distributed systems refer to a network of interconnected computers that communicate and coordinate their actions to achieve a common goal. Unlike traditional centralized systems, where a single entity controls all components, distributed systems distribute tasks and data across multiple nodes. This decentralized approach enables enhanced scalability, fault tolerance, and resource utilization.

**Key Components of Distributed Systems**

To comprehend the inner workings of distributed systems, we must familiarize ourselves with their key components. These components include nodes, communication channels, protocols, and distributed file systems. Nodes represent individual machines or devices within the network; communication channels facilitate data transmission, protocols ensure reliable communication and distributed file systems enable data storage across multiple nodes.

Distribued vs centralized

**Distributed Systems Use Cases**

Many modern applications use distributed systems, including mobile and web applications with high traffic. Web browsers or mobile applications serve as clients in a client-server environment, and the server becomes its own distributed system. The modern web server follows a multi-tier system pattern. Requests are delegated to several server logic nodes via a load balancer.

Kubernetes is popular among distributed systems since it enables containers to be combined into a distributed system. Kubernetes orchestrates network communication between the distributed system nodes and handles dynamic horizontal and vertical scaling of the nodes. 

Cryptocurrencies like Bitcoin and Ethereum are also peer-to-peer distributed systems. The currency ledger is replicated at every node in a cryptocurrency network. To bootstrap, a currency node connects to other nodes and downloads its full ledger copy. Additionally, cryptocurrency wallets use JSON RPC to communicate with the ledger nodes.

Challenges in Distributed Systems

While distributed systems offer numerous advantages, they also pose various challenges. One significant challenge is achieving consensus among distributed nodes. Ensuring that all nodes agree on a particular value or decision can be complex, especially in the presence of failures or network partitions. Additionally, maintaining data consistency across distributed nodes and mitigating issues related to concurrency control requires careful design and implementation.

**Example: Distributed System of Microservices**

Microservices are one type of distributed system since they decompose an application into individual components. A microservice architecture, for example, may have services corresponding to business features (payments, users, products, etc.), with each element handling the corresponding business logic. Multiple redundant copies of the services will then be available, so there is no single point of failure.

**Distributed Systems: The Challenge**

Distributed systems are required to implement the reliability, agility, and scale expected of modern computer programs. Distributed systems are applications of many different components running on many other machines. Containers are the foundational building block, and groups of containers co-located on a single device comprise the atomic elements of distributed system patterns.

The significant shift we see with software platforms is that they evolve much quicker than the products and paradigms we use to monitor them. We need to consider new practices and technologies with dedicated platform teams to enable a new era of system reliability in a distributed system. Along with the practices of Observability that are a step up to the traditional monitoring of static infrastructure: Observability vs monitoring.

Knowledge Check: Distributed Systems Architecture

  • Client-Server Architecture

A client-server architecture has two primary responsibilities. The client presents user interfaces and is connected to the server via a network. The server handles business logic and state management. Unless the server is redundant, a client-server architecture can quickly degrade into a centralized architecture. A truly distributed client-server setup will consist of multiple server nodes that distribute client connections. In modern client-server architectures, clients connect to encapsulated distributed systems on the server.

  • Multi-tier Architecture

Multi-tier architectures are extensions of client-server architectures. Multi-tier architectures decompose servers into further granular nodes, decoupling additional backend server responsibilities like data processing and management. By processing long-running jobs asynchronously, these additional nodes free up the remaining backend nodes to focus on responding to client requests and interacting with the data store.

  • Peer-to-Peer Architecture

Peer-to-peer distributed systems contain complete instances of applications on each node. There is no separation between presentation and data processing at the node level. A node consists of a presentation layer and a data handling layer. Peer nodes may contain the entire system’s state data. 

Peer-to-peer systems have a great deal of redundancy. When initiated and brought online, peer-to-peer nodes discover and connect to other peers, thereby synchronizing their local state with the system’s. As a result of this feature, nodes on a peer-to-peer network won’t be disrupted by the failure of one. Additionally, peer-to-peer systems will persist. 

  • Service-orientated Architecture

A service-oriented architecture (SOA) is a precursor to microservices. Microservices differ from SOA primarily in their node scope, which is at the feature level. Each microservice node encapsulates a specific set of business logic, such as payment processing—multiple nodes of business logic interface with independent databases in a microservice architecture. In contrast, SOA nodes encapsulate an entire application or enterprise division. Database systems are typically included within the service boundary of SOA nodes.

Because of their benefits, microservices have become more popular than SOA. The small service nodes provide functionality that teams can reuse through microservices. The advantages of microservices include greater robustness and a more extraordinary ability for vertical and horizontal scaling to be dynamic.

Reliability in Distributed Systems: Components

A- Redundancy and Replication:

Redundancy and replication are two fundamental concepts distributed systems use to enhance reliability. Redundancy involves duplicating critical system components, such as servers, storage devices, or network links, so the redundant component can seamlessly take over if one fails. Replication, on the other hand, involves creating multiple copies of data across different nodes in a system, enabling efficient data access and fault tolerance. By incorporating redundancy and replication, distributed systems can continue to operate even when individual components fail.

B – Fault Tolerance:

Fault tolerance is a crucial aspect of achieving reliability in distributed systems. It involves designing systems to operate correctly even when one or more components encounter failures. Several techniques, such as error detection, recovery, and prevention mechanisms, are employed to achieve fault tolerance.

C – Error Detection:

Error detection techniques, such as checksums, hashing, and cyclic redundancy checks (CRC), identify errors or data corruption during transmission or storage. By verifying data integrity, these techniques help identify and mitigate potential failures in distributed systems.

D – Error Recovery:

Error recovery mechanisms, such as checkpointing and rollback recovery, aim to restore the system to a consistent state after a failure. Checkpointing involves periodically saving the system’s state and data, allowing recovery to a previously known good state in case of failures. On the other hand, rollback recovery involves undoing the effects of failed operations and returning the system to a consistent state.

E – Error Prevention:

Distributed systems employ error prevention techniques, such as redundancy elimination, consensus algorithms, and load balancing to enhance reliability. Redundancy elimination reduces unnecessary duplication of data or computation, thereby reducing the chances of errors. Consensus algorithms ensure that all nodes in a distributed system agree on a shared state despite failures or message delays. Load balancing techniques distribute computational tasks evenly across multiple nodes to prevent overloading and potential shortcomings.

Challenges: Traditional Monitoring

**Lack of Connective Event**

If you examine traditional monitoring systems, they look to capture and investigate signals in isolation. They work in a siloed environment, similar to that of developers and operators before the rise of DevOps. Existing monitoring systems cannot detect the “Unknowns Unknowns” that are familiar with modern distributed systems. This often leads to service disruptions. So, you may be asking what an “Unknown Unknown” is.

I’ll put it to you this way: the distributed systems we see today lack predictability—certainly not enough predictability to rely on static thresholds, alerts, and old monitoring tools. If something is fixed, it can be automated, and we have static events, such as in Kubernetes, a POD reaching a limit.

Then, a replica set introduces another pod on a different node if specific parameters are met, such as Kubernetes Labels and Node Selectors. However, this is only a tiny piece of the failure puzzle in a distributed environment.  Today, we have what’s known as partial failures and systems that fail in very creative ways.

Reliability In Distributed System: Creative ways to fail

So, we know that some of these failures are quickly predicted, and actions are taken. For example, if this Kubernetes POD node reaches a specific utilization, we can automatically reschedule PODs on a different node to stay within our known scale limits.

Predictable failures can be automated in Kubernetes and with any infrastructure. An Ansible script is useful when these events occur. However, we have much more to deal with than POD scaling; we have many partial and complicated failures known as black holes.

**In today’s world of partial failures**

Microservices applications are distributed and susceptible to many external factors. On the other hand, if you examine the traditional monolithic application style, all the functions reside in the same process. It was either switched ON or OFF!! Not much happened in between. So, if there is a failure in the procedure, the application as a whole will fail. The results are binary, usually either a UP or Down.

This was easy to detect with some essential monitoring, and failures were predictable. There was no such thing as a partial failure. In a monolith application, all application functions are within the same process. A significant benefit of these monoliths is that you don’t have partial failures.

However, in a cloud-native world, where we have broken the old monolith into a microservices-based application, a client request can go through multiple hops of microservices, and we can have several problems to deal with.

There is a lack of connectivity between the different domains. Many monitoring tools and knowledge will be tied to each domain, and alerts are often tied to thresholds or rate-of-change violations that have nothing to do with user satisfaction, which is a critical metric to care about.

**System reliability: Today, you have no way to predict**

So, the new, modern, and complex distributed systems place very different demands on your infrastructure—considerably different from the simple three-tier application, where everything is generally housed in one location.  We can’t predict anything anymore, which breaks traditional monitoring approaches.

When you can no longer predict what will happen, you can no longer rely on a reactive approach to monitoring and management. The move towards a proactive approach to system reliability is a welcomed strategy.

**Blackholes: Strange failure modes**

When considering a distributed system, many things can happen. A service or region can disappear or disappear for a few seconds or ms and reappear. We believe this is going into a black hole when we have strange failure modes. So when anything goes into it will disappear. Peculiar failure modes are unexpected and surprising.

Strange failure modes are undoubtedly unpredictable. So, what happens when your banking transactions are in a black hole? What if your banking balance is displayed incorrectly or if you make a transfer to an external account and it does not show up? 

Site Reliability Engineering (SRE) and Observability

Site reliability engineering (SRE) and observational practices are needed to manage these types of unpredictability and unknown failures. SRE is about making systems more reliable. And everyone has a different way of implementing SRE practices. Usually, about 20% of your issues cause 80% of your problems.

You need to be proactive and fix these issues upfront. You need to be able to get ahead of the curve and do these things to prevent incidents from occurring. This usually happens in the wake of a massive incident. This usually acts as a teachable moment. It gives the power to be the reason to listen to a Chaos Engineering project. 

New tools and technologies:

1 – Distributed tracing

We have new tools, such as distributed tracing. So, what is the best way to find the bottleneck if the system becomes slow? Here, you can use Distributed Tracing and Open Telemetry. The tracing helps us instrument our system, figuring out where the time has been spent and where it can be used across distributed microservice architecture to troubleshoot problems. Open Telemetry provides a standardized way of instrumenting our system and providing those traces.

2 – SLA, SLI, SLO, and Error Budgets

So we don’t just want to know when something has happened and then react to an event that is not looking from the customer’s perspective. We need to understand if we are meeting SLA by gathering the number and frequency of the outages and any performance issues.

Service Level Objectives (SLO) and Service Level Indicators (SLI) can assist you with measurements. Service Level Objectives (SLOs) and Service Level Indicators (SLI) not only help you with measurements but also offer a tool for having better reliability and forming the base for the reliability stack.

Interactive Distributed Systems Lab 03

Consistency & Consensus Lab

Replication improves availability and durability, but multiple copies create coordination problems. Explore replica lag, leader failure, network partitions and quorum decisions while keeping consistency and consensus concepts separate.

LAB OBJECTIVE

Use the controls to create distributed-system events. Observe what happens to replica state, then determine whether the system can safely continue accepting writes or needs a new leader and quorum.

Replicated data service
◆
Replica 1
Leader
v104
◇
Replica 2
Follower
v104
◇
Replica 3
Follower
v104
Inject an event
Quorum: In this three-replica example, a majority is two replicas. A consensus protocol can use quorum rules to prevent conflicting leaders or committed decisions.
Distributed-system analysis
System ready.
All three replicas contain the same committed version. Select an event to explore what changes.
Property
Current
Meaning
Leader
R1
Active
Quorum
3 / 3
Available
Versions
104 / 104 / 104
Aligned