Data Center Fabric: Building the Modern Network Foundation
Modern data centres are no longer built around a single network core. They are engineered as scalable, resilient fabrics that connect workloads through multiple paths, predictable forwarding behaviour and programmable network services.
The data centre fabric is the connectivity foundation that allows servers, storage systems, virtual machines and distributed applications to communicate efficiently. Its architecture determines how traffic moves, how the network scales, and how failures are absorbed without unnecessarily disrupting applications.
From traditional hierarchical Ethernet and Cisco FabricPath to routed Clos architectures, BGP underlays and EVPN-VXLAN overlays, fabric design has evolved to support increasingly distributed and virtualised workloads. The objective is not simply faster switching: it is a network that can be operated, measured and expanded with confidence.
Conceptual three-spine fabric. Each leaf has connectivity to every spine, enabling multiple routed paths between workloads.
Predictable Connectivity
A structured fabric replaces complex hierarchical forwarding with consistent leaf-to-spine connectivity.
Horizontal Expansion
Additional leaf and spine capacity can be introduced as workload and bandwidth requirements grow.
Underlay & Overlay
A routed IP foundation supports virtual networks, tenant isolation and workload mobility.
Observable Resilience
Routing state, telemetry and failure analysis help engineers validate fabric behaviour.
From Physical Topology to Network Behaviour
Understanding a data centre fabric requires looking beyond the topology diagram. Engineers must examine the physical interconnect, the routing control plane, the forwarding data plane, and the virtual networks carried across the infrastructure.
This guide follows that engineering journey: beginning with traditional network limitations, moving through Clos and FabricPath designs, examining BGP and EVPN-VXLAN, and finally investigating performance, segmentation, resilience and troubleshooting.
Throughout the guide, interactive visualisations and engineering exercises connect architectural principles to observable network behaviour. The objective is to understand not only how a fabric is built, but why it forwards traffic the way it does.
Explore the Data Centre Fabric
Follow the nine engineering stages, from fabric fundamentals and Clos architecture through EVPN-VXLAN, security, performance and troubleshooting. Select any numbered circle to jump directly to that section.
FABRIC ENGINEERING GUIDE
Fundamentals 02 Clos &
Spine-Leaf 03 Ethernet &
FabricPath 04 IP Fabric &
Underlay 05 VXLAN &
EVPN 06 Virtualization
& Cloud 07 Performance
& Analytics 08 Security &
Resilience 09 Design &
Troubleshooting
9 sections · Architecture to engineering diagnosis
Start Learning →Understanding Data Center Fabric Fundamentals
A data centre fabric is more than a collection of interconnected switches. It is an architectural system that defines how workloads communicate, how forwarding paths are selected, how network capacity is expanded, and how the infrastructure responds when individual components fail.
Modern fabric designs aim to provide predictable connectivity across a large population of servers, virtual machines, storage systems and distributed applications. Rather than concentrating forwarding capacity in a small number of central devices, a fabric distributes connectivity across a structured network of interconnected switching and routing nodes.
What Makes a Network a Fabric?
The term network fabric describes an interconnected forwarding infrastructure designed to provide consistent communication between endpoints. In a data centre, the fabric commonly connects top-of-rack switches, compute clusters, storage networks, virtualised workloads and network service appliances.
The physical topology provides connectivity, but the operational behaviour of the fabric depends on additional mechanisms: routing protocols, forwarding tables, multipath selection, failure detection, network segmentation and management systems.
Physical Connectivity
Switches, interfaces, optical links and cabling establish the available paths between workloads and network service endpoints.
Control Plane
Routing and discovery protocols establish reachability, exchange topology information and determine which forwarding paths are valid.
Data Plane
Hardware forwarding tables and packet-processing pipelines move traffic according to established routing and switching decisions.
Operational Intelligence
Monitoring, telemetry, automation and configuration validation expose network behaviour and help maintain consistent operational state.
Engineering Perspective
A fabric should not be judged solely by its physical topology. Two networks with identical cabling can exhibit very different behaviour depending on their control-plane design, forwarding model, failure handling and operational policies.
From Three-Tier Hierarchies to Fabric Networks
Traditional enterprise data centres commonly used a three-tier architecture consisting of access, aggregation and core layers. Each layer performed a relatively distinct function, and traffic between servers frequently traversed shared aggregation or core infrastructure.
This approach provided clear administrative boundaries and supported established redundancy mechanisms. However, large Layer 2 domains, spanning-tree constraints, oversubscribed uplinks and centralised forwarding bottlenecks could limit how efficiently additional network capacity was utilised.
Modern fabric architectures increasingly favour structured, multipath connectivity. In a typical two-tier Clos design, every leaf connects to every spine. Servers attach to leaves, while spines provide transit connectivity between leaves. Additional capacity can be introduced by expanding the leaf or spine population within the topology's design limits.
| Design Characteristic | Traditional Hierarchy | Modern Clos Fabric |
|---|---|---|
| Topology | Core, aggregation and access | Leaf and spine tiers |
| Forwarding | May rely on STP and hierarchical paths | Typically routed multipath forwarding |
| Expansion | Often involves aggregation capacity upgrades | Add leaves or spines within design limits |
| East-West Traffic | May traverse shared aggregation or core devices | Usually leaf-spine-leaf |
| Resilience | Redundant devices and links | Multiple paths with routing convergence |
| Operational Model | Often device and hierarchy focused | Fabric-wide routing and automation |
Important Design Distinction
A Clos topology does not automatically eliminate every network bottleneck. Oversubscription ratios, uplink speeds, ECMP hashing, traffic concentration and application placement still determine the actual performance experienced by workloads.
Why East-West Traffic Changed Data Centre Design
Traditional client-server environments frequently emphasised north-south traffic: communication between users outside the data centre and applications hosted within it.
Virtualisation, distributed databases, microservices, container platforms and storage replication have increased the importance of east-west communication between workloads inside the data centre.
North-South Traffic
Traffic entering or leaving the data centre, such as internet clients accessing applications, API requests, and communication with external networks.
East-West Traffic
Communication between internal services, virtual machines, databases, compute clusters and distributed application components.
A fabric is particularly useful when applications require frequent communication between different server racks. The design seeks to provide consistent path characteristics regardless of which leaf switches host the communicating workloads.
Application-Aware Engineering
The network architecture should reflect application communication patterns. An environment dominated by distributed storage or service-to-service calls may require different oversubscription, latency and congestion-management targets from a primarily north-south application environment.
Following a Packet Across the Fabric
Consider two application servers connected to different leaf switches in a routed Clos fabric. A packet travelling between these endpoints typically follows a leaf-spine-leaf forwarding path.
The source leaf determines the next hop using its forwarding table. When several equal-cost routes exist, ECMP can distribute flows across available spine paths. The spine forwards the packet toward the destination leaf, which delivers the traffic to the attached endpoint.
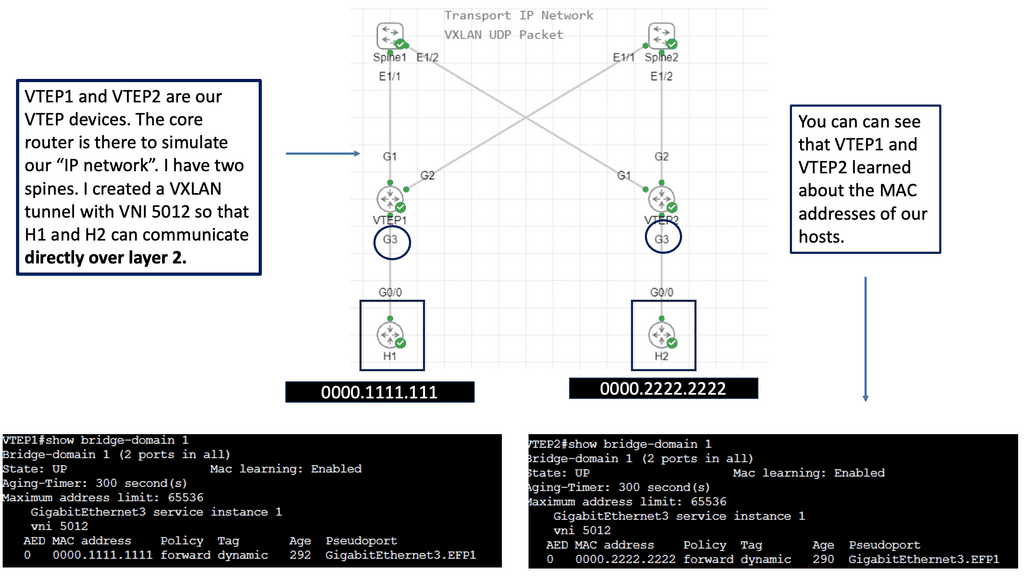
This is the basic forwarding model for a routed fabric. In an EVPN-VXLAN design, the source leaf may first encapsulate the original Ethernet frame into a VXLAN packet. The spine then forwards the outer IP packet without needing to understand the tenant's inner Ethernet frame.
ECMP Does Not Guarantee Equal Utilisation
ECMP commonly uses flow-based hashing rather than distributing every packet independently. Consequently, several large flows can hash onto the same path while other equal-cost paths remain lightly utilised. Traffic telemetry is required to identify these imbalances.
Separating Physical Reachability from Virtual Services
A central architectural principle in modern data centre networking is the separation of the physical forwarding infrastructure from the virtual networking services delivered to workloads.
The Underlay
The physical or routed IP fabric that establishes reachability between network devices and tunnel endpoints. It commonly uses eBGP or OSPF, depending on the selected design.
The Overlay
Virtual network services carried across the underlay. VXLAN encapsulation and EVPN control-plane signalling can support tenant segmentation, virtual Layer 2 domains and routed connectivity.
The underlay provides the transport foundation. The overlay determines how tenant traffic is logically connected and isolated. Separating these responsibilities allows the physical fabric to remain comparatively simple while virtual services evolve independently.
However, this separation introduces operational dependencies. A VXLAN tunnel can only function when the underlying IP network can reach the remote VTEP. Engineers must therefore validate both underlay routing and overlay state when investigating connectivity failures.
Key Troubleshooting Principle
When tenant connectivity fails, establish whether the problem exists in the physical fabric, underlay routing, tunnel endpoint reachability, EVPN control-plane information, or the tenant's forwarding policy. Each layer requires different evidence and diagnostic commands.
Five Requirements of a Well-Engineered Fabric
| Requirement | Engineering Objective | Validation Method |
|---|---|---|
| Scalability | Expand endpoint and bandwidth capacity without redesigning the entire network | Port capacity, addressing, route scale and topology limits |
| Resilience | Maintain connectivity during expected link or device failures | Failure injection, convergence and packet-loss measurement |
| Performance | Deliver predictable latency, throughput and congestion behaviour | Flow telemetry, queue monitoring and load testing |
| Segmentation | Keep tenants and application security domains appropriately isolated | VRF/VNI mapping, ACL and policy verification |
| Operability | Make network state observable, repeatable and diagnosable | Telemetry, configuration validation and troubleshooting workflows |
These requirements must be considered together. For example, a design may provide abundant physical bandwidth but still experience application performance problems because of poor ECMP distribution, excessive oversubscription or inconsistent congestion management.
Similarly, adding redundant links does not guarantee rapid recovery. Routing convergence, hardware forwarding updates, failure-detection timers and application timeout behaviour all influence the actual recovery experienced by users.
Fabric Architecture Is About Predictable Behaviour
The defining advantage of a modern data centre fabric is not simply the removal of traditional network layers. It is the ability to engineer a consistent forwarding foundation that supports scalable workloads, multiple network paths, virtual services and operational visibility.
- Traditional hierarchical designs can concentrate forwarding capacity and introduce spanning-tree constraints.
- Clos fabrics provide structured multipath connectivity between leaves.
- East-west application traffic is a major driver of fabric architecture.
- Underlay routing and overlay virtualization serve different but interdependent purposes.
- Fabric quality must be validated through performance, resilience, segmentation and operational testing.
Fabric Architecture Explorer
Compare a traditional three-tier network with a modern spine-leaf fabric. Select a traffic pattern, trace a packet, then inject a network failure to investigate how the forwarding path changes.
Engineering Controls
Packet Journey & Forwarding Analysis
Clos and Spine-Leaf Fabric Architecture
The Clos architecture provides the structural foundation for many modern data centre networks. By connecting leaf switches to a shared set of spine switches, the fabric creates multiple parallel forwarding paths and supports predictable horizontal expansion.
Unlike a conventional hierarchical network, where traffic may concentrate around aggregation or core devices, a Clos fabric distributes connectivity across a regular topology. Each leaf can reach other leaves through the spine layer, and routed forwarding protocols can use multiple equal-cost paths.
Understanding the Clos Network
The Clos network originated as a multistage switching architecture designed to provide scalable connectivity without requiring a single enormous switching device. Its central idea is to construct a larger switching system from multiple interconnected switching stages.
In contemporary data centre networking, the term Clos fabric commonly describes a leaf-spine topology in which leaf switches connect to every spine within their fabric plane.
The spine switches act as transit devices, while the leaf switches provide workload connectivity. The resulting structure offers a regular path model: traffic between different leaves typically crosses one spine.
Leaf Switches
Connect servers, storage devices, virtualisation hosts and network services. Leaf switches can also act as VXLAN tunnel endpoints, enforce policies and provide distributed default gateways.
Spine Switches
Provide high-speed transit connectivity between leaves. In a conventional routed Clos, spines primarily forward IP traffic and do not directly connect ordinary workloads.
Equal-Cost Paths
Multiple spine switches can provide alternative routes to the same destination. ECMP allows the forwarding plane to use these paths concurrently.
Failure Domains
Redundant spine paths reduce dependence on individual links or transit devices. However, the impact of failures depends on topology, routing convergence and available spare capacity.
Engineering Principle
In a standard two-tier routed Clos, each leaf should connect to every spine in its fabric plane. This creates a consistent path structure and avoids introducing topology-dependent reachability differences between leaves.
Building a Fully Connected Leaf-Spine Fabric
A two-tier Clos fabric consists of a spine layer and a leaf layer. Every leaf connects to every spine, while leaf-to-leaf and spine-to-spine links are generally unnecessary for the basic forwarding topology.
This arrangement provides a regular set of possible forwarding paths. A packet travelling between servers attached to different leaves normally traverses the source leaf, one spine and the destination leaf.
Why the Topology Is Predictable
For any pair of distinct leaves in this example, three spine paths are available when all links and routing adjacencies are healthy. A failed spine removes one candidate path, but the remaining spines can continue providing connectivity if capacity and routing state permit.
Scaling Beyond a Single Spine Layer
A two-tier Clos fabric is limited by the port density, bandwidth and platform scale of its spine switches. As the number of leaves increases, the number of required spine-facing ports also increases.
Larger fabrics may introduce a superspine layer to interconnect multiple leaf-spine pods. This creates a multistage architecture that can support larger numbers of workloads and more extensive physical deployments.
| Characteristic | Two-Tier Clos | Multistage Clos |
|---|---|---|
| Primary Layers | Leaf and spine | Leaf, spine and superspine |
| Typical Scope | Single fabric or moderate-scale deployment | Large deployments with multiple pods |
| Inter-Leaf Path | Leaf-spine-leaf | Depends on whether traffic crosses pods |
| Scaling Constraint | Spine port count and platform capacity | Additional stages, cabling and routing scale |
| Operational Complexity | Relatively simple topology | More devices, adjacencies and failure domains |
Design Trade-Off
Introducing superspines increases the potential size of the fabric, but it also introduces additional network hops, cabling requirements and operational complexity. The decision should be driven by measurable port, bandwidth, scale and resiliency requirements.
Calculating Fabric Oversubscription
Oversubscription describes the relationship between the total potential bandwidth offered to connected workloads and the available uplink bandwidth toward the rest of the fabric.
A fabric does not need to be non-oversubscribed for every workload. The appropriate ratio depends on application traffic patterns, peak concurrency, storage behaviour and acceptable congestion levels.
The result is commonly expressed as an N:1 ratio. A 2:1 design offers half as much aggregate fabric uplink bandwidth as the sum of server-facing port rates.
Example: 48-Port Leaf Switch
Consider a leaf switch with 48 server-facing interfaces operating at 25 Gbps, and six uplinks operating at 100 Gbps each.
Server-facing capacity
Fabric uplink capacity
Oversubscription ratio
This is a nominal port-capacity calculation. Real throughput depends on protocol overhead, platform limitations, traffic distribution and congestion.
| Design | Downlink Capacity | Uplink Capacity | Ratio |
|---|---|---|---|
| Non-Oversubscribed | 800 Gbps | 800 Gbps | 1:1 |
| Moderate | 1.2 Tbps | 600 Gbps | 2:1 |
| Higher | 1.2 Tbps | 300 Gbps | 4:1 |
| Heavy | 1.2 Tbps | 150 Gbps | 8:1 |
Capacity Planning Insight
Oversubscription should be assessed at multiple boundaries, not only at individual leaf switches. A fabric can have a favourable leaf uplink ratio but still experience congestion at a superspine tier, border leaf or shared network service.
Understanding Fabric Bisection Capacity
Bisection bandwidth describes the aggregate capacity crossing a division of the network into two groups. It is an important theoretical measure of how much traffic a topology can carry between different portions of the fabric.
In a Clos topology, the available cross-fabric bandwidth depends on link rates, connectivity, the number of spine devices and how the fabric is partitioned. A balanced topology can provide high aggregate bandwidth, but not every traffic matrix will achieve the theoretical maximum.
Engineering Example
Consider four leaves split into two groups of two. If each leaf has three 100 Gbps spine uplinks, the aggregate uplink capacity from either two-leaf group is 600 Gbps. In an ideal non-blocking spine design, this can support up to 600 Gbps of one-direction traffic across the partition, subject to available capacity on both sides and the forwarding distribution.
Bisection bandwidth must not be confused with the sum of every physical interface rate. It measures connectivity across a specific network partition and is constrained by the capacity of the links and switching stages carrying that traffic.
How ECMP Distributes Traffic Across Spines
Equal-Cost Multipath allows a router or Layer 3 switch to install multiple next hops for the same destination when the routing process determines that those paths are equally eligible.
In a leaf-spine fabric, the source leaf may have several equal-cost next hops toward a remote leaf or VTEP. The forwarding hardware typically selects one of these next hops using a hash calculated from packet-header fields.
Flow-based hashing helps preserve packet ordering within a flow, but it does not guarantee equal utilisation across links. A small number of large flows can create uneven distribution, sometimes described as ECMP polarization.
Parallel Path Utilisation
Multiple independent flows can use different spine paths, increasing aggregate fabric throughput and reducing dependence on one uplink.
Elephant Flow Concentration
Large flows may collide on the same hashed path, creating congestion while other equal-cost paths remain underutilised.
VXLAN Hashing Consideration
In VXLAN fabrics, underlay devices generally hash using fields from the outer packet headers. VXLAN source UDP ports can provide additional entropy derived from inner flows, helping distribute encapsulated traffic across ECMP paths. Exact hashing behaviour is platform-dependent.
Designing for Link and Spine Failures
A principal advantage of a multipath fabric is the ability to maintain alternate forwarding paths when a link or transit device becomes unavailable.
However, resilience depends on more than physical redundancy. The control plane must detect failures, withdraw or update routes, and install the appropriate forwarding state.
| Failure Scenario | Expected Behaviour | Engineering Check |
|---|---|---|
| Single Spine Link | Remove failed next hop; use remaining paths | Interface state, routing adjacency and ECMP group |
| Entire Spine | Withdraw affected paths and converge via surviving spines | Convergence time and remaining capacity |
| Leaf Failure | Workloads on the failed leaf may lose connectivity | Dual-homing and workload recovery design |
| Oversubscribed Uplink | Congestion, queuing or packet drops may occur | Interface utilisation, buffers and flow telemetry |
| Routing Misconfiguration | Missing or inconsistent reachability | Adjacency state, route tables and policy validation |
Resilience Is a Measured Outcome
The presence of redundant spine paths does not guarantee zero packet loss during failure. Detection timers, routing convergence, forwarding-table programming and application tolerance all influence the observed recovery.
Engineering Decisions Before Building a Clos Fabric
A successful fabric design begins with measurable workload requirements rather than simply selecting a particular number of leaf or spine switches.
Endpoint Scale
Estimate server-facing ports, virtual endpoints, route scale, MAC entries and expected growth over the design lifetime.
Bandwidth Demand
Calculate peak traffic demand, oversubscription ratios, uplink requirements and spare capacity after failures.
Routing Architecture
Choose an underlay protocol, addressing scheme, ECMP design, adjacency model and convergence strategy.
Operational Visibility
Define telemetry, logging, configuration validation, troubleshooting commands and failure-testing procedures.
Physical constraints must also be considered. Optics, cable distance, rack placement, power consumption, switch port density and maintenance boundaries can materially affect the topology.
The design should be validated against both normal operating conditions and expected failure scenarios. A fabric that performs well when every link is healthy may become heavily oversubscribed when a spine fails.
Clos Fabrics Turn Connectivity into Scalable Capacity
A Clos fabric provides a structured network foundation where multiple forwarding paths can be used concurrently. Its value comes from combining regular topology, routed multipath forwarding, modular expansion and measurable operational behaviour.
- Leaf switches connect workloads; spine switches provide transit connectivity.
- A two-tier Clos provides predictable leaf-spine-leaf forwarding between racks.
- Superspine architectures extend the fabric across multiple pods.
- Oversubscription and bisection bandwidth determine important capacity boundaries.
- ECMP enables multipath forwarding but can produce uneven flow distribution.
- Resilience requires both alternate physical paths and correct control-plane convergence.
Clos & Spine-Leaf Design Lab
Design a two-tier Clos fabric, inspect ECMP forwarding, calculate nominal oversubscription and inject a spine failure. Select individual paths to investigate how traffic travels between leaf switches.
Design Controls
Engineering Analysis
Available Leaf-to-Leaf Paths
Model assumptions: four leaf switches, one equal-speed uplink per leaf per spine, full leaf-to-spine connectivity, equal routing costs, and no other bottlenecks. Nominal interface capacity is not equivalent to measured application throughput. ECMP selects paths using flow hashing rather than distributing every flow evenly.
Traditional Ethernet and Cisco FabricPath
Traditional Ethernet was designed around distributed MAC address learning, broadcast forwarding and loop-free Layer 2 topologies. These mechanisms work well in many environments, but large, highly interconnected data centres exposed important limitations in scalability, path utilisation and convergence.
Cisco FabricPath emerged as an alternative approach to building multipath Layer 2 data centre networks. It combined Ethernet service delivery at the edge with a link-state control plane and multipath forwarding inside the fabric.
Understanding FabricPath is useful not only for maintaining legacy environments but also for understanding the architectural transition toward modern routed IP fabrics.
The Scaling Limitations of Traditional Ethernet
Classical Ethernet switches learn source MAC addresses from received frames and associate those addresses with ingress interfaces. When a destination MAC address is unknown, the switch normally floods the frame within the relevant VLAN.
Broadcast traffic is also flooded within the broadcast domain, while multicast forwarding depends on the available snooping and replication mechanisms.
In a large Layer 2 network, these behaviours can create significant operational challenges. Switches may need to maintain extensive MAC forwarding tables, flooded traffic can consume bandwidth, and accidental forwarding loops can destabilise the network.
Unknown Unicast Flooding
When the destination MAC address is not known, Ethernet switches flood the frame across eligible forwarding ports in the VLAN.
MAC Table Scale
Large broadcast domains can increase the number of endpoint MAC addresses that switches must learn, maintain and age.
Loop Sensitivity
Ordinary Ethernet frames do not contain a hop-count field. Persistent loops can cause repeated forwarding and severe network instability.
Restricted Path Utilisation
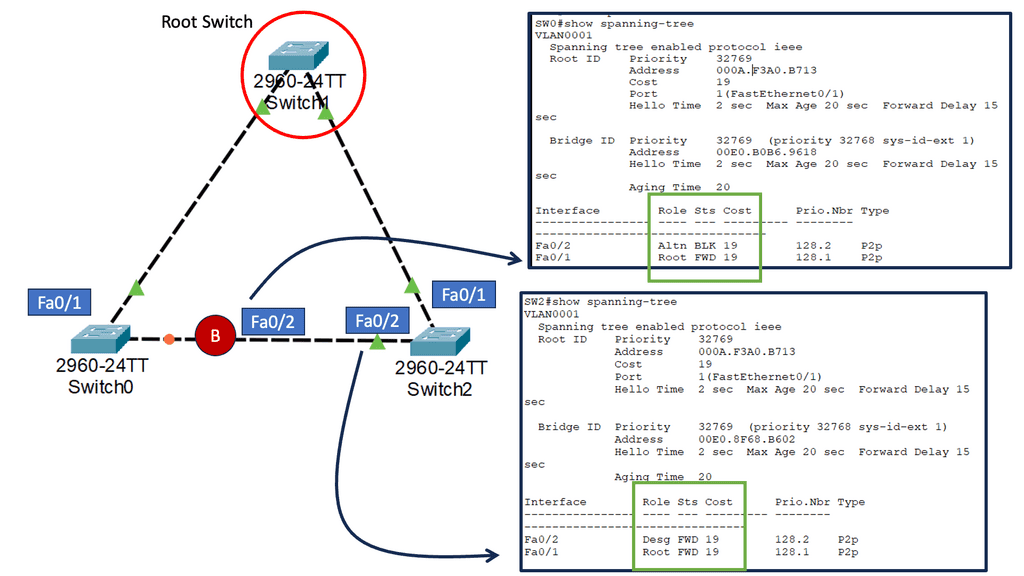
Traditional spanning-tree forwarding blocks selected redundant paths, limiting simultaneous use of the available physical topology.
Engineering Perspective
Ethernet flooding and MAC learning are not inherently defective. The challenge arises when large broadcast domains, extensive multipath connectivity and demanding convergence requirements are combined without sufficient segmentation or control-plane mechanisms.
Why Spanning Tree Became a Fabric Bottleneck
Spanning Tree Protocol prevents persistent Layer 2 forwarding loops by creating a logical loop-free topology. Redundant physical links may remain connected, but selected ports are placed into non-forwarding states to prevent cycles.
This provides essential protection for bridged Ethernet networks. However, it can also prevent otherwise usable links from carrying traffic for a particular spanning-tree instance.
Rapid Spanning Tree Protocol improves convergence compared with original 802.1D STP. Multiple Spanning Tree can also use different logical trees for different VLAN groups. Nevertheless, these approaches do not provide the same multipath forwarding model as a routed Clos fabric.
Important Distinction
MST can distribute different VLAN groups across different spanning-tree topologies, but an individual MST instance still operates as a logical loop-free tree. It does not provide general-purpose ECMP across all redundant Layer 2 paths for the same traffic.
Introducing a Multipath Layer 2 Fabric
Cisco FabricPath was developed to overcome several limitations associated with large classical Ethernet networks. Rather than extending spanning-tree forwarding across the entire fabric, FabricPath uses a link-state control plane to establish reachability between fabric switches.
Ethernet frames entering a FabricPath domain are encapsulated for transport across the fabric. The outer FabricPath header identifies fabric switches and includes a time-to-live mechanism that helps prevent indefinite circulation.
This allows the FabricPath core to forward traffic using fabric-level reachability rather than relying exclusively on conventional destination MAC learning at every transit switch.
IS-IS Control Plane
FabricPath uses IS-IS to distribute fabric topology information and calculate paths between FabricPath switches.
Switch Identifiers
Fabric switches use identifiers that allow the forwarding system to distinguish fabric destinations from ordinary endpoint MACs.
Layer 2 Multipath
Multiple eligible paths can be installed between fabric switches, allowing concurrent use of redundant transit links.
Hop-Count Protection
A FabricPath TTL field limits how long an encapsulated frame can remain in the fabric during abnormal forwarding.
Why FabricPath Was Significant
FabricPath demonstrated how a Layer 2 service could operate over a topology-aware, multipath forwarding core. This represented a major departure from traditional spanning-tree-dependent forwarding across large bridged domains.
Following an Ethernet Frame Across FabricPath
Consider two servers attached to different FabricPath edge switches. The servers exchange ordinary Ethernet frames, but the FabricPath domain uses an additional encapsulation and fabric forwarding mechanism between the edge switches.
FabricPath transport forwarding separates the fabric-level destination from the original Ethernet endpoint destination. This reduces the need for every transit device to maintain the same endpoint MAC forwarding information as a classical bridged network.
Forwarding Detail
FabricPath's forwarding model depends on the distinction between classical Ethernet edge interfaces and FabricPath core interfaces. The edge provides Ethernet services, while the fabric core transports encapsulated traffic between fabric switches.
Reducing Unnecessary MAC Learning
Traditional Ethernet learning associates source MAC addresses with the ports on which frames arrive. In a large Layer 2 domain, this can result in widespread learning of endpoint addresses.
FabricPath introduced conversational learning to reduce the number of remote endpoint MAC addresses that edge switches need to maintain.
Rather than requiring every edge switch to retain all remote MAC addresses, FabricPath can learn remote endpoint information based on observed communication. The precise learning process depends on the frame type, forwarding state and FabricPath learning rules.
Broad Source-MAC Learning
Switches learn source MAC addresses from frames they receive. Flooding can expose endpoint traffic to many switches within a VLAN.
Conversation-Oriented Learning
Edge switches can reduce remote MAC state by retaining information for endpoints involved in relevant traffic conversations.
Do Not Confuse Learning with Routing
Conversational MAC learning is distinct from the FabricPath IS-IS topology database. IS-IS establishes fabric switch reachability; endpoint MAC learning determines how Ethernet traffic reaches the appropriate fabric edge.
Using Multiple Paths Without a Spanning Tree Core
FabricPath uses a link-state view of the fabric to calculate forwarding paths between switches. Where multiple equal-cost paths exist, traffic can be distributed across eligible alternatives.
This differs fundamentally from a single spanning-tree forwarding topology, where redundant links may be blocked for a given spanning-tree instance.
| Characteristic | Traditional STP Ethernet | Cisco FabricPath |
|---|---|---|
| Topology Control | Spanning-tree calculation | IS-IS link-state control plane |
| Loop Prevention | Blocking redundant forwarding paths | Fabric forwarding rules and TTL |
| Path Utilisation | One logical tree per instance | Multiple equal-cost fabric paths |
| Core Forwarding | Conventional Ethernet bridging | FabricPath encapsulated forwarding |
| MAC Learning | Source-MAC learning | Edge learning including conversational mechanisms |
| Failure Recovery | STP/RSTP topology changes | IS-IS reconvergence and forwarding updates |
Multipath Engineering
The practical benefit of FabricPath multipath forwarding depends on the number of supported equal-cost next hops, the available link bandwidth and the platform's traffic distribution behaviour. Additional paths do not automatically guarantee balanced utilisation.
What Engineers Should Inspect in a FabricPath Network
Troubleshooting a FabricPath deployment requires separating fabric control-plane health from endpoint reachability and forwarding behaviour.
A fabric may have healthy physical links but still experience connectivity failures because of inconsistent switch IDs, missing IS-IS adjacencies, incorrect VLAN mappings or incomplete MAC learning.
show fabricpath switch-id
show fabricpath isis adjacency
show fabricpath route
show fabricpath topology
show fabricpath mac address-table
show interface brief
| Investigation | Expected Evidence | Possible Fault |
|---|---|---|
| Fabric Adjacency | Expected IS-IS neighbours present | Link, interface or control-plane failure |
| Switch ID Reachability | Remote fabric destinations installed | Missing or inconsistent topology information |
| MAC Reachability | Expected endpoint forwarding state | Learning or VLAN forwarding issue |
| Multipath State | Eligible next hops available | Reduced redundancy or asymmetric reachability |
| Physical Links | Correct interfaces and operational state | Optical, cabling or interface failure |
Practical Troubleshooting Sequence
Start with interface and adjacency health. Next, validate fabric switch reachability and route installation. Finally, inspect endpoint MAC learning and forwarding. This sequence helps distinguish fabric transport problems from edge Ethernet service problems.
From FabricPath to Routed Clos and EVPN-VXLAN
FabricPath was an important development in the evolution of data centre networking, but it is now best understood as a legacy architecture rather than the default choice for a new fabric.
Contemporary data centre designs commonly use routed IP connectivity between leaf and spine switches. Standard IP routing protocols establish underlay reachability, while VXLAN can carry virtual Layer 2 and Layer 3 services across that routed infrastructure.
BGP EVPN provides a control-plane mechanism for distributing endpoint and virtual network reachability information. This reduces reliance on traditional flood-and-learn behaviour and supports scalable tenant segmentation.
| Design Element | FabricPath | Routed EVPN-VXLAN Fabric |
|---|---|---|
| Transport | FabricPath Layer 2 encapsulation | IP underlay with VXLAN encapsulation |
| Topology Protocol | FabricPath IS-IS | Typically BGP, OSPF or IS-IS |
| Virtual Networks | Ethernet VLAN services | VNIs, bridge domains and VRFs |
| Endpoint Control Plane | FabricPath learning mechanisms | BGP EVPN route advertisements |
| Multipath | FabricPath equal-cost forwarding | IP ECMP forwarding |
| Design Position | Legacy Cisco-specific fabric technology | Widely adopted standards-based architecture |
Architectural Continuity
Although the transport and control-plane technologies differ, FabricPath and routed EVPN-VXLAN fabrics address several related engineering goals: multipath connectivity, reduced dependence on spanning tree, scalable endpoint reachability and predictable failure recovery.
FabricPath Changed How Layer 2 Networks Could Scale
Traditional Ethernet depends on distributed MAC learning and loop-free bridging. FabricPath introduced topology-aware multipath forwarding to overcome important limitations associated with large spanning-tree-based networks.
- Classical Ethernet relies on MAC learning and flooding within broadcast domains.
- Spanning tree prevents loops but can leave redundant forwarding capacity unused.
- FabricPath uses IS-IS to establish fabric topology and reachability.
- FabricPath encapsulation supports multipath transport and hop-count protection.
- Conversational learning helps reduce unnecessary remote endpoint MAC state.
- Modern routed IP fabrics with EVPN-VXLAN extend these architectural goals using different transport and control-plane mechanisms.
Traditional Ethernet & FabricPath Explorer
Investigate how a looped Layer 2 topology behaves with Spanning Tree Protocol compared with a FabricPath-style multipath fabric. Trace traffic, inspect forwarding links and introduce a failure to see how available paths change.
Engineering Controls
Forwarding Journey
MAC Learning & Forwarding State
Inspect a simplified example of the information used to reach the destination. Traditional Ethernet learns MAC addresses against bridge ports. FabricPath combines edge MAC learning with fabric switch reachability.
| Destination | Forwarding State | Engineering Meaning |
|---|
Educational abstraction: the STP example uses a deterministic tree and a simplified topology change after failure. Actual STP behavior depends on bridge priorities, port roles, costs, timers and protocol variant. FabricPath forwarding uses IS-IS-derived reachability and encapsulation; its actual multipath selection, MAC distribution and convergence depend on platform and design.
IP Fabric and the Routing Underlay
A modern IP fabric uses Layer 3 routing between leaf and spine switches to create a resilient, multipath forwarding infrastructure. Rather than extending a large bridged Ethernet domain across the physical network, each fabric link can operate as an independent routed connection.
The underlay provides IP reachability between fabric devices and, when an overlay is deployed, between VXLAN tunnel endpoints. Its design directly influences convergence, ECMP path availability, scalability and the reliability of virtual networking services.
Why Modern Fabrics Use Routed Links
In a conventional Layer 3 Clos fabric, leaf-to-spine interfaces operate as routed links. Each connection has its own Layer 3 adjacency, allowing routing protocols to calculate reachability across the fabric.
This reduces the dependence on spanning tree in the physical fabric and permits multiple equal-cost paths to remain active simultaneously.
Routed Point-to-Point Links
Leaf-spine connections use Layer 3 addressing and routing adjacencies instead of participating in one large bridged Ethernet domain.
Loopback Reachability
Stable loopback addresses identify fabric nodes and commonly serve as VXLAN VTEP or routing endpoint addresses.
Equal-Cost Multipath
Routing protocols can establish several eligible paths toward remote destinations, enabling ECMP forwarding.
Failure Convergence
Routing and forwarding state can be updated when links or network devices fail, allowing surviving paths to carry traffic.
Architectural Principle
The underlay should provide simple, predictable IP reachability. Tenant segmentation and virtual Layer 2 services can be implemented separately in an overlay, avoiding unnecessary complexity in the physical forwarding layer.
Using eBGP as the Underlay Routing Protocol
External BGP is a common routing protocol choice for modern data centre Clos fabrics. RFC 7938 describes the use of BGP in large-scale data centre network environments, including considerations for topology, autonomous system allocation and operational scalability.
One common design assigns an autonomous system to each leaf and a separate autonomous system to the spine tier. Other designs allocate AS numbers differently to meet specific scaling and policy requirements.
AS-Path Loop Prevention
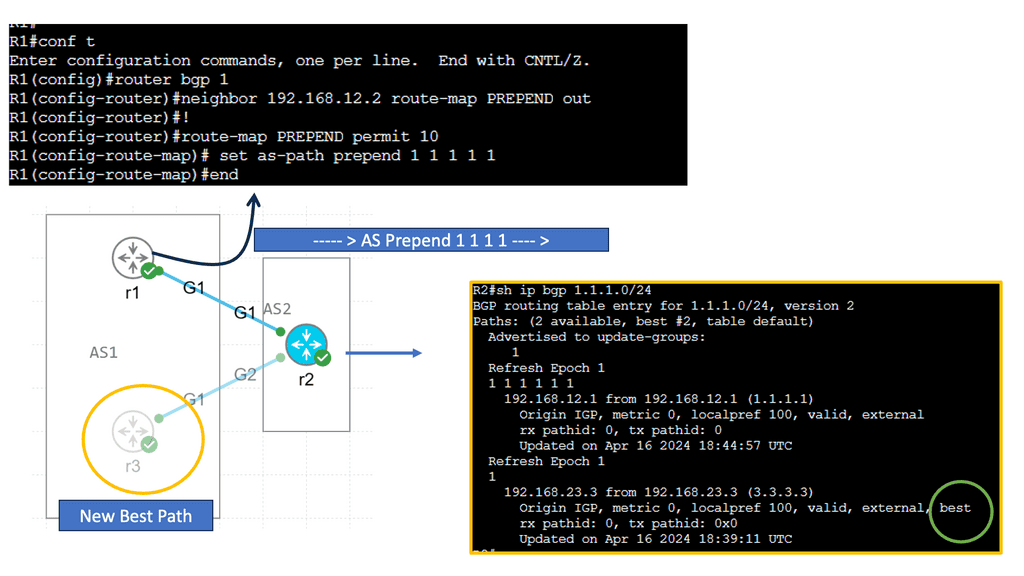
Sharing an AS number across multiple spines can introduce AS-path loop-prevention considerations when routes are exchanged between leaves. Some designs use separate spine AS numbers, while others use mechanisms such as AS-path rewriting or allow-as-in under carefully controlled conditions. The AS allocation model must be validated against the intended route propagation.
In an eBGP underlay, BGP neighbours commonly peer using directly connected interface addresses. The sessions exchange infrastructure reachability, including loopback routes needed by overlay endpoints.
BGP's path-selection process and multipath configuration determine which routes are eligible for installation into the routing and forwarding tables.
Designing Point-to-Point Links and Loopbacks
An IP fabric needs an addressing plan that is simple to automate, easy to troubleshoot and scalable as new switches are introduced.
Point-to-point routed links commonly use IPv4 /31 prefixes, as described by RFC 3021, when supported by the devices. This allows two usable interface addresses without requiring a larger subnet.
Loopback interfaces normally use /32 addresses. These addresses provide stable identities for routing and overlay endpoints independent of individual physical interfaces.
| Device / Link | Address | Purpose |
|---|---|---|
| Spine 1 Loopback | 10.255.0.1/32 | Infrastructure identity |
| Spine 2 Loopback | 10.255.0.2/32 | Infrastructure identity |
| Leaf A Loopback | 10.255.1.1/32 | Routing / possible VTEP endpoint |
| Leaf B Loopback | 10.255.1.2/32 | Routing / possible VTEP endpoint |
| Leaf A–Spine 1 | 10.0.0.0/31 | Leaf .0 / Spine .1 |
| Leaf A–Spine 2 | 10.0.0.2/31 | Leaf .2 / Spine .3 |
| Leaf B–Spine 1 | 10.0.0.4/31 | Leaf .4 / Spine .5 |
| Leaf B–Spine 2 | 10.0.0.6/31 | Leaf .6 / Spine .7 |
Addressing Design Principle
Keep infrastructure addressing separate from tenant addressing. Loopback and point-to-point prefixes should follow predictable allocation conventions so that configuration generation, troubleshooting and route filtering remain manageable.
Establishing a Leaf-to-Spine eBGP Session
The following example illustrates a directly connected eBGP adjacency between Leaf A and Spine 1. The leaf belongs to AS 65001 and the spine belongs to AS 65000.
This example uses Cisco NX-OS-style syntax and focuses on the fundamental relationship between interface addressing, BGP neighbour configuration and loopback advertisement.
feature bgp

interface loopback0
  ip address 10.255.1.1/32

interface Ethernet1/1
  no switchport
  ip address 10.0.0.0/31
  no shutdown

router bgp 65001
  router-id 10.255.1.1

  address-family ipv4 unicast
    network 10.255.1.1/32
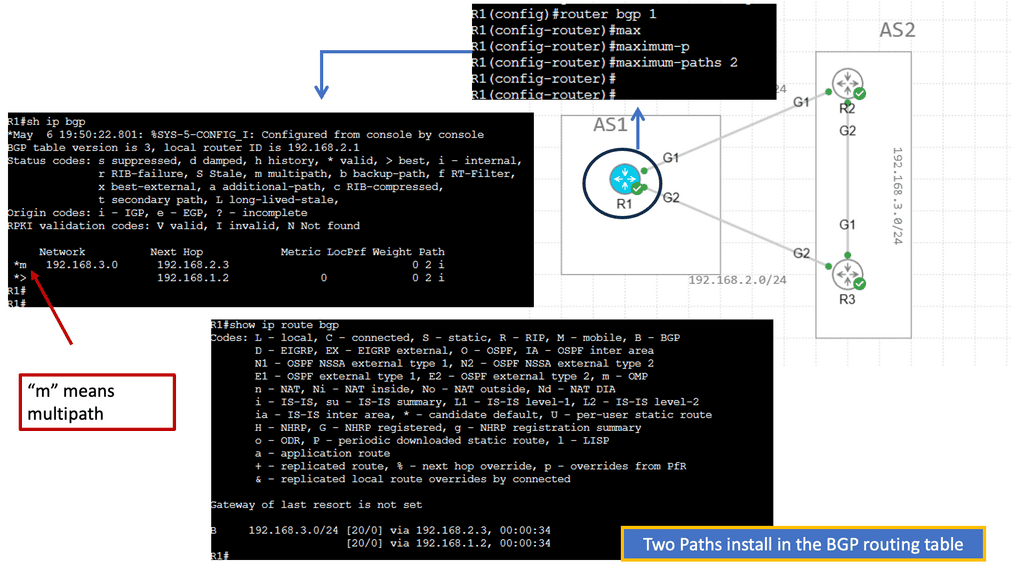
    maximum-paths 2

  neighbor 10.0.0.1
    remote-as 65000
    address-family ipv4 unicast
feature bgp

interface loopback0
  ip address 10.255.0.1/32

interface Ethernet1/1
  no switchport
  ip address 10.0.0.1/31
  no shutdown

router bgp 65000
  router-id 10.255.0.1

  address-family ipv4 unicast
    network 10.255.0.1/32

  neighbor 10.0.0.0
    remote-as 65001
    address-family ipv4 unicast
Configuration Scope
These are educational configuration fragments, not a complete production template. Production designs must also address route policy, peer authentication where applicable, maximum prefix controls, failure detection, telemetry and the chosen autonomous system allocation model.
How a Leaf Learns Remote Loopback Reachability
In an IP fabric, each leaf needs reachability to relevant remote infrastructure endpoints. When VXLAN is used, this includes remote VTEP loopback addresses.
Consider Leaf B advertising its loopback prefix 10.255.1.2/32 to both spine switches. The spines can propagate this reachability toward Leaf A according to the configured BGP topology and route policy.
The BGP control plane maintains route attributes and next-hop information. The routing table represents selected routes, while the forwarding table contains the next-hop entries used to move packets through the fabric.
BGP Best Path vs ECMP
BGP does not automatically install every received path into the forwarding table. Multipath eligibility depends on the BGP implementation, route attributes and configured multipath rules. Routes must satisfy those rules before they can contribute to an ECMP group.
Multiple Next Hops Toward a Remote VTEP
If Leaf A learns two eligible equal-cost routes toward Leaf B's loopback, it may install both next hops into its forwarding table.
The forwarding hardware then selects an eligible next hop for each flow according to the configured ECMP hashing behaviour.
| Destination | Next Hop | Interface | Forwarding State |
|---|---|---|---|
| 10.255.1.2/32 | 10.0.0.1 | Ethernet1/1 | ECMP path 1 |
| 10.255.1.2/32 | 10.0.0.3 | Ethernet1/2 | ECMP path 2 |
next hops
per uplink
uplink capacity
Aggregate Capacity Is Not Single-Flow Speed
Two 100 Gbps ECMP uplinks provide 200 Gbps of nominal aggregate capacity, but a single conventional flow typically hashes onto one next hop. Its throughput is therefore constrained by the selected path and other network factors.
What Happens When a Spine Link Fails?
A routed fabric must respond to physical link failures and control-plane failures without leaving invalid next hops in the forwarding table.
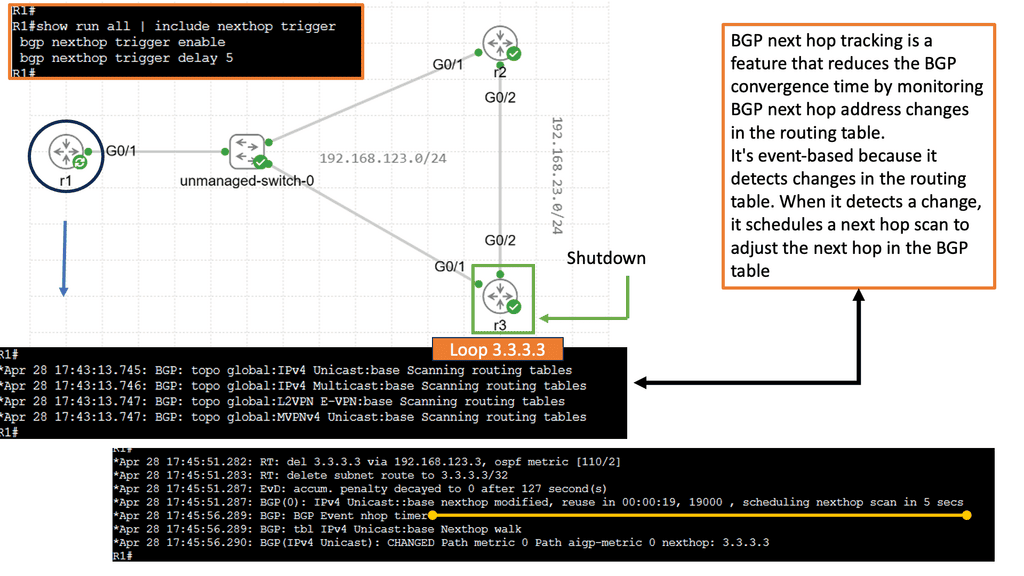
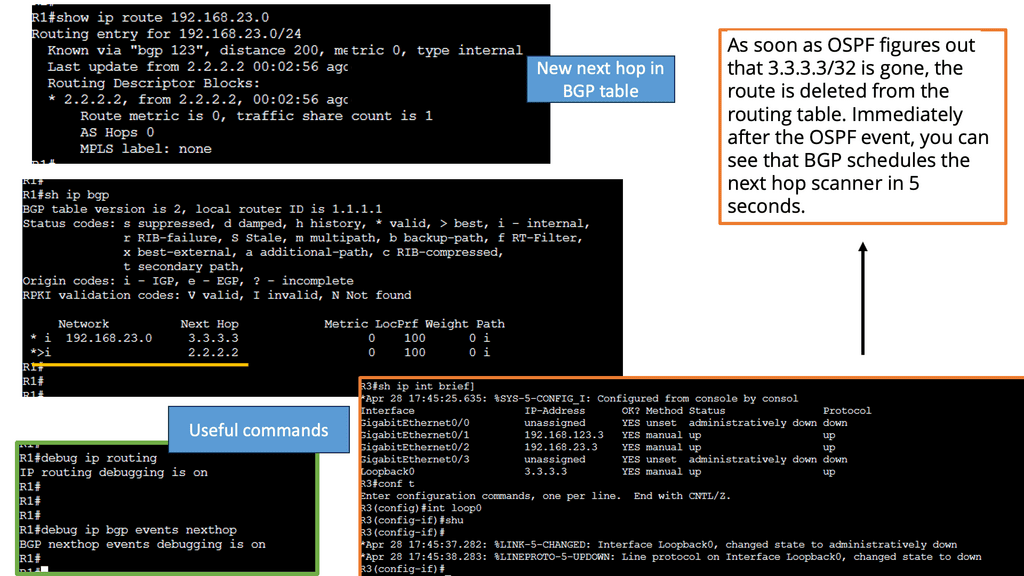
When a directly connected interface fails, the device can detect the loss of link state and invalidate affected reachability. Routing processes update their state, and the forwarding plane removes or replaces unusable next hops.
| Stage | Network Event | Operational Evidence |
|---|---|---|
| 1 · Detection | Link failure or loss of BGP/BFD liveness | Interface and neighbour state |
| 2 · Control Plane | Affected routes are withdrawn or invalidated | BGP table changes |
| 3 · Route Selection | Surviving routes become eligible | Routing table entries |
| 4 · FIB Update | Failed next hop removed from forwarding group | Hardware forwarding state |
| 5 · Recovery | Traffic continues through available paths | Packet loss, latency and application behaviour |
Where BFD Fits
Bidirectional Forwarding Detection can provide rapid path-failure detection for routing protocols, including BGP, when supported and correctly configured.
BFD is especially useful when a forwarding-path failure does not immediately cause a local physical interface to transition down.
Convergence Is Not a Single Timer
End-to-end recovery includes failure detection, control-plane processing, route selection, forwarding programming and application recovery. BFD can reduce detection time, but it does not eliminate every other convergence component.
Investigating a Missing Remote Loopback Route
Consider a fault where Leaf A cannot reach Leaf B's loopback address 10.255.1.2.
This is significant because a VXLAN overlay using that loopback as a tunnel endpoint depends on underlay IP reachability.
show interface brief
show ip interface brief
show bgp ipv4 unicast summary
show bgp ipv4 unicast 10.255.1.2/32
show ip route 10.255.1.2
show forwarding ipv4 route 10.255.1.2/32
ping 10.255.1.2 source 10.255.1.1
traceroute 10.255.1.2 source 10.255.1.1
Interface Health
Verify routed interfaces, IP addressing and operational status. Confirm that the physical underlay links are available.
BGP Adjacency
Confirm expected neighbours are established and that received prefix counts are consistent with the design.
Route Installation
Inspect BGP reachability, route attributes, next-hop resolution and routing-table installation.
Forwarding Validation
Verify the installed next hops, forwarding interfaces and actual reachability through the fabric.
Incident Scenario: BGP Established, Traffic Failing
An Established BGP session does not prove that all expected routes are present or installed. Route filtering, AS-path rejection, next-hop resolution failures and forwarding inconsistencies can still prevent remote VTEP reachability.
Engineering a Reliable IP Fabric
| Design Area | Recommended Consideration | Validation |
|---|---|---|
| Topology | Consistent leaf-to-spine connectivity | Physical topology and link inventory |
| Addressing | Predictable /31 links and /32 loopbacks where supported | IP allocation and route verification |
| Routing | Explicit AS allocation and route propagation policy | BGP neighbour and route tables |
| Multipath | Eligible ECMP routes and appropriate hardware limits | FIB next-hop groups |
| Failure Detection | Appropriate link, BGP and BFD mechanisms | Controlled failure tests |
| Visibility | Telemetry, route monitoring and event correlation | Operational dashboards and CLI diagnostics |
The objective is not to create the most complex routing design. It is to provide stable, predictable reachability across a fabric that can expand and recover without requiring extensive manual intervention.
When the underlay is correctly designed, the overlay can rely on a consistent transport foundation. This separation is central to modern EVPN-VXLAN architectures.
The Underlay Is the Foundation of Fabric Reliability
A routed IP fabric provides the connectivity required for modern data centre services. eBGP, predictable addressing, ECMP and rapid failure detection work together to establish resilient transport between fabric endpoints.
- Routed leaf-spine links eliminate the need for a spanning-tree-based physical fabric.
- eBGP provides a scalable underlay routing option, as discussed in RFC 7938.
- Point-to-point interfaces and loopbacks support predictable addressing.
- ECMP enables multiple eligible forwarding paths toward remote destinations.
- BFD can accelerate failure detection, while routing convergence and FIB updates complete recovery.
- Underlay reachability must be verified before investigating overlay services.
IP Fabric & Routing Underlay Lab
Explore a routed leaf-spine fabric using eBGP, OSPF or IS-IS. Inspect protocol adjacencies, loopback reachability and ECMP forwarding. Inject link failures to investigate how the underlay adapts.
Underlay Engineering Controls
Underlay Forwarding Investigation
Routing Table & ECMP Next Hops
| Destination | Protocol | Next Hop | Status |
|---|
Engineering CLI Console
Inspect simplified operational output based on the selected protocol and failure scenario.
This is a teaching model, not an actual router command interpreter. CLI output is illustrative. Actual commands and neighbor states depend on the network operating system and configuration. Convergence is shown as the resulting stable state rather than protocol timer-by-timer events.
VXLAN and EVPN Overlay Architecture
The IP underlay provides resilient connectivity between fabric switches. The overlay uses that connectivity to create virtual Layer 2 and Layer 3 networks across the physical fabric. VXLAN supplies the encapsulation, while BGP EVPN can distribute endpoint and virtual-network reachability information.
This separation allows multiple tenants, applications and network segments to share the same routed infrastructure without requiring every virtual network to exist as a traditional end-to-end Ethernet VLAN.
Understanding VXLAN and EVPN requires distinguishing three elements: the IP transport network, the VXLAN data plane, and the EVPN control plane.
Separating the Physical Fabric from Virtual Networks
A network overlay creates logical connectivity over an existing transport network. In a VXLAN fabric, the physical infrastructure forwards IP packets between tunnel endpoints, while the overlay carries tenant Ethernet frames and virtual-network traffic.
The underlay does not normally need to learn every tenant MAC address. Instead, it forwards encapsulated packets toward the destination VTEP IP address.
IP Underlay
Leaf and spine switches exchange infrastructure reachability using routing protocols. The underlay provides paths between VTEP addresses.
VXLAN Overlay
VTEPs encapsulate Ethernet frames inside UDP/IP packets, allowing virtual networks to span routed infrastructure.
BGP EVPN
EVPN distributes MAC, IP and virtual-network reachability information between participating devices.
VNIs and VRFs
VXLAN Network Identifiers distinguish virtual segments, while VRFs maintain separate Layer 3 routing domains.
Architectural Principle
Underlay routing answers the question: "How do I reach the remote VTEP?" The overlay answers: "Which tenant or virtual network should this traffic belong to?"
How VTEPs Connect Virtual Networks
A VXLAN Tunnel Endpoint, or VTEP, performs encapsulation and decapsulation at the boundary between the local Ethernet segment and the IP transport network.
In a typical leaf-spine design, leaf switches operate as VTEPs. Servers connect to local VLANs, while the leaf maps those VLANs to VXLAN VNIs.
Important Distinction
A VXLAN tunnel is not necessarily a dedicated physical path or a persistent point-to-point circuit. It is an encapsulation relationship between tunnel endpoints carried across the existing IP network.
Inside a VXLAN Packet
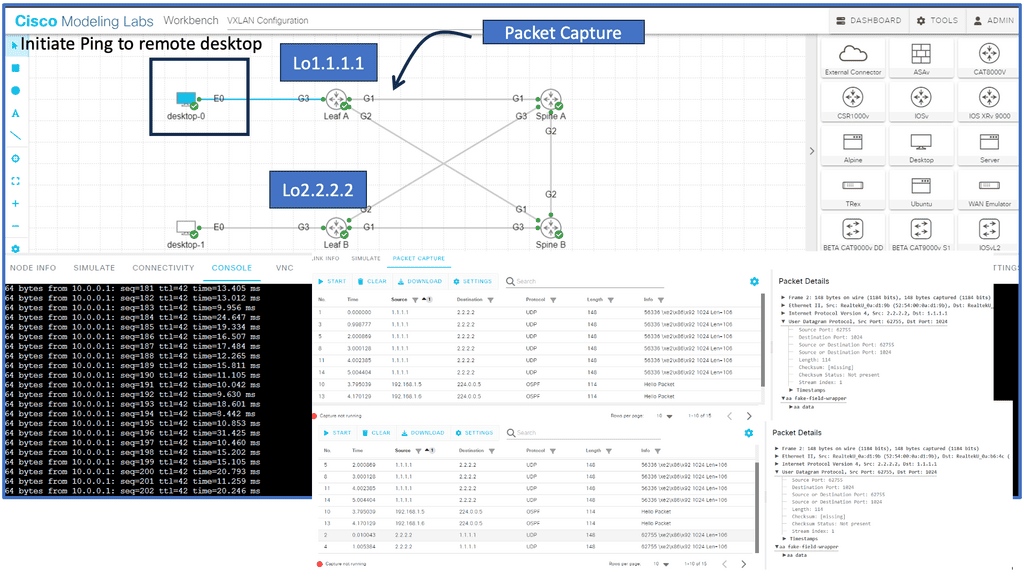
VXLAN encapsulates an original Ethernet frame within an outer UDP/IP packet. The outer destination IP identifies the remote VTEP, while the VXLAN header identifies the virtual network.
The VXLAN header contains a 24-bit VNI field, providing approximately 16.7 million possible identifier values. This greatly expands the logical segment identifier space compared with the 12-bit VLAN ID field.
| Field | Example | Purpose |
|---|---|---|
| Outer Source IP | 10.255.1.1 | Ingress VTEP address |
| Outer Destination IP | 10.255.1.2 | Egress VTEP address |
| UDP Destination | 4789 | Standard VXLAN UDP destination port |
| VNI | 10100 | Identifies the overlay segment |
| Inner Destination MAC | 00:11:22:33:44:55 | Original Ethernet destination |
MTU Engineering
VXLAN adds encapsulation overhead to the original Ethernet frame. For standard IPv4 VXLAN, the additional outer IP, UDP and VXLAN headers total 36 bytes, plus an outer Ethernet header of 14 bytes without an outer VLAN tag. The fabric MTU must accommodate the resulting packet size. Outer IPv6 and optional headers change the overhead.
Building Logical Network Segments
VXLAN VNIs identify logical overlay forwarding domains. In a common deployment, a local VLAN is associated with a Layer 2 VNI on a leaf switch.
Layer 3 VNIs are commonly associated with tenant VRFs in symmetric inter-subnet routing designs.
| Tenant | VLAN | Layer 2 VNI | VRF |
|---|---|---|---|
| Application | 100 | 10100 | APP-VRF |
| Database | 200 | 10200 | APP-VRF |
| Development | 300 | 10300 | DEV-VRF |
Bridge Domain
Represents a virtual Layer 2 segment. Endpoints in the same segment can exchange bridged Ethernet traffic.
Tenant Routing
Used in common symmetric IRB designs to carry routed tenant traffic between VTEPs.
Tenant Isolation
Different VRFs maintain separate routing tables. Traffic between VRFs requires an explicit interconnection or route-leaking design. A VNI identifies a virtual network; it does not by itself constitute a complete security policy.
Replacing Data-Plane Discovery with Control-Plane Reachability
VXLAN can operate using flood-and-learn mechanisms, but BGP EVPN introduces a control plane that distributes endpoint reachability information between participating devices.
EVPN uses BGP address families and route types to advertise MAC addresses, IP bindings, Ethernet segment information and overlay reachability.
| EVPN Route | Name | Primary Purpose |
|---|---|---|
| Type 1 | Ethernet Auto-Discovery | Ethernet segment discovery, aliasing and mass withdrawal |
| Type 2 | MAC/IP Advertisement | Endpoint MAC reachability and optional IP bindings |
| Type 3 | Inclusive Multicast Ethernet Tag | Discovery of remote participants for BUM replication |
| Type 4 | Ethernet Segment | Ethernet segment membership and designated-forwarder election support |
| Type 5 | IP Prefix Advertisement | IP prefix reachability in EVPN routing designs |
Why Route Type 2 Matters
A Type 2 route allows a remote VTEP to learn endpoint MAC reachability through BGP EVPN instead of relying entirely on flooded data-plane traffic. When an IP address is included, the advertisement can also support MAC/IP binding and neighbour discovery optimisation.
EVPN route distinguishers allow otherwise identical routes to be represented uniquely in BGP. Route targets determine which EVPN routes are imported into the appropriate virtual networking contexts.
EVPN Does Not Eliminate All Flooding
Broadcast, unknown unicast and multicast traffic may still require replication, depending on the design and forwarding state. EVPN provides control-plane information that can reduce unnecessary flooding, but it does not make every form of BUM traffic disappear.
Routing Close to the Workload
In a distributed anycast gateway design, multiple leaf switches provide the same logical default-gateway address for a tenant subnet.
A workload can therefore send traffic to its locally attached leaf rather than traversing the fabric to reach a centralised gateway.
Remote First-Hop Routing
Workloads may need to traverse the network to reach a gateway located elsewhere in the topology.
Local First-Hop Routing
Each participating leaf can provide a consistent gateway IP and virtual MAC identity for the subnet.
Engineering Benefit
Distributed anycast gateways support localised first-hop routing and can simplify workload mobility across participating leaves. Correct configuration of gateway addresses, virtual MACs and tenant forwarding contexts is essential.
Routing Between Subnets Across the Fabric
Integrated Routing and Bridging, or IRB, combines Layer 2 bridging and Layer 3 routing functions.
In a common symmetric IRB EVPN-VXLAN design, inter-subnet traffic is routed at the ingress leaf into a tenant routing context, transported across the fabric using the Layer 3 VNI, and processed by the egress leaf before delivery.
Why Symmetric IRB Scales
Symmetric IRB can reduce the need for every VTEP to maintain all remote Layer 2 segments involved in inter-subnet routing. The design relies on appropriate tenant VRFs, L3 VNIs, EVPN route distribution and platform support.
Investigating Overlay Connectivity Failures
VXLAN troubleshooting should distinguish between transport reachability, EVPN control-plane state and tenant forwarding.
A healthy underlay does not automatically prove that an overlay is functioning. Incorrect VNI mappings, missing EVPN routes, route-target mismatches and gateway configuration errors can all prevent endpoint connectivity.
show nve peers
show nve vni
show bgp l2vpn evpn summary
show bgp l2vpn evpn
show mac address-table
show ip arp
show ip route vrf APP-VRF
show interface nve1
show ip route 10.255.1.2
| Investigation | Expected Evidence | Possible Fault |
|---|---|---|
| Underlay | Remote VTEP IP reachable | Missing route or forwarding failure |
| VTEP State | Expected NVE peers and VNIs | Incorrect tunnel or VNI configuration |
| EVPN Control Plane | Expected EVPN routes received and imported | BGP, route-target or policy issue |
| Endpoint Learning | Correct MAC/IP reachability | Missing or stale endpoint state |
| Tenant Routing | Correct VRF routes and gateway state | IRB or inter-VRF configuration fault |
| Data Plane | Encapsulated traffic reaches destination | MTU, ACL, UDP or forwarding issue |
Incident Scenario: BGP EVPN Established, Hosts Cannot Communicate
An Established EVPN BGP session only confirms control-plane adjacency. It does not prove that the correct routes have been imported, that the VNI is operational or that encapsulated traffic can traverse the fabric. Troubleshooting must validate all three layers independently.
Engineering a Scalable EVPN-VXLAN Fabric
| Design Area | Key Consideration | Validation |
|---|---|---|
| Underlay | Reliable IP reachability between VTEPs | Routing and forwarding tests |
| VNI Allocation | Consistent segment and tenant mapping | VNI inventory and NVE state |
| EVPN Policy | Correct route-target import/export | EVPN route verification |
| Gateway Design | Consistent distributed anycast configuration | ARP, gateway and IRB tests |
| MTU | Support for VXLAN encapsulation overhead | Path MTU validation |
| Security | VRF isolation and explicit traffic policy | Tenant isolation testing |
| Operations | Visibility across underlay, EVPN and data plane | Telemetry and fault injection |
The most reliable EVPN-VXLAN deployments maintain clear separation between transport routing, virtual-network control-plane state and tenant services.
This separation supports repeatable automation, structured troubleshooting and controlled expansion as workloads and tenants grow.
EVPN-VXLAN Connects Virtual Networks Across an IP Fabric
VXLAN provides encapsulated transport for virtual networks, while BGP EVPN distributes the reachability information required to operate those networks at scale.
- The IP underlay transports packets between VTEP addresses.
- VXLAN encapsulates Ethernet frames using UDP/IP and a 24-bit VNI.
- Layer 2 VNIs represent virtual bridge domains, while Layer 3 VNIs support common symmetric IRB designs.
- BGP EVPN distributes MAC/IP, Ethernet segment and IP prefix reachability information.
- Distributed anycast gateways allow routing close to workloads.
- Symmetric IRB provides scalable inter-subnet routing across participating VTEPs.
- Troubleshooting must validate the underlay, EVPN control plane and overlay forwarding separately.
VXLAN & EVPN Overlay Explorer
Follow a packet from one VTEP to another. Inspect EVPN control-plane advertisements, VXLAN encapsulation, VNI mapping and inter-subnet routing. Introduce faults to investigate the relationship between underlay reachability and overlay forwarding.
Overlay Engineering Controls
Packet Journey & Overlay Analysis
VXLAN Encapsulation Inspector
Examine the packet layers used to carry tenant traffic across the routed underlay. The transport VNI and inner frame depend on the selected forwarding scenario.
EVPN Control-Plane Route Table
| Route | Destination | Next Hop | State |
|---|
Engineering CLI Console
Inspect illustrative operational output generated from the current overlay scenario.
Educational model: EVPN Type 2 provides MAC/IP reachability, while Type 5 advertises IP prefixes. Symmetric IRB uses an L3 VNI and distributed gateway routing. Actual route import, route targets, router MACs, ARP suppression and encapsulation depend on the implementation and configuration.
Fabric Virtualization and Cloud Networking
Modern data centre fabrics do more than connect physical switches. They provide a foundation for virtual networks, isolated tenants, distributed workloads and policy-driven application connectivity.
Network virtualization separates logical connectivity from the underlying physical topology. This allows infrastructure teams to create virtual routing domains, application segments and security boundaries without redesigning the physical fabric for every new workload.
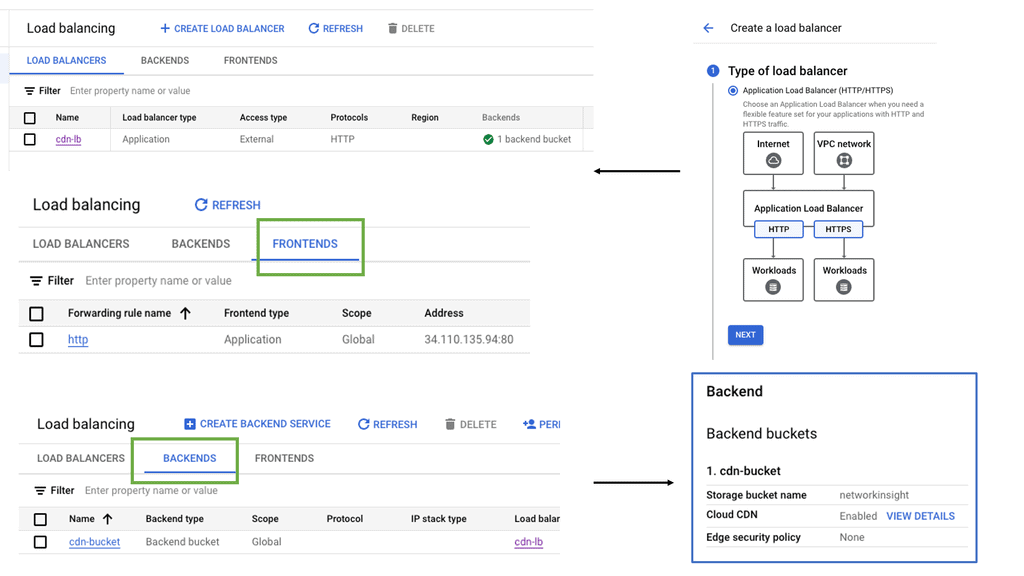
The same architectural principles extend into cloud environments, where virtual private clouds, software-defined routing, cloud firewalls and hybrid connectivity services provide logical networking over provider-managed infrastructure.
Decoupling Logical Networks from Physical Infrastructure
Traditional network designs often associated logical network boundaries with physical interfaces, switches and VLAN trunks. Network virtualization allows multiple isolated logical networks to operate across shared physical infrastructure.
The physical fabric provides transport connectivity, while virtual routing and bridging instances maintain separate forwarding contexts.
Logical Segmentation
VLANs, VXLAN VNIs and bridge domains separate Layer 2 connectivity into logical forwarding environments.
Routing Isolation
VRFs maintain independent routing tables, allowing different tenants to use overlapping IP address ranges when appropriately isolated.
Policy Abstraction
Connectivity rules can be expressed through application groups, contracts and logical security policies.
Infrastructure Automation
APIs, templates and controllers can provision network services consistently across multiple devices and environments.
Engineering Principle
Virtualization does not eliminate the physical network. It creates logical services that depend on a reliable transport foundation. Underlay routing, MTU, capacity and failure recovery remain critical.
Policy-Driven Data Centre Fabric Networking
Cisco Application Centric Infrastructure, or ACI, combines a leaf-spine fabric with a policy model for application connectivity and network services.
Cisco APIC provides centralised policy management and orchestration for the ACI fabric. The leaf and spine switches perform distributed forwarding according to their programmed policies and fabric state.
Control and Forwarding Separation
APIC is not the per-packet forwarding engine. ACI switches forward traffic using locally programmed hardware state. An APIC management outage does not inherently stop established data-plane forwarding, although management and policy operations may be affected.
Tenants, VRFs, Bridge Domains and Endpoint Groups
Cisco ACI uses a hierarchical policy model to represent application connectivity. Network engineers define logical objects and relationships instead of configuring every forwarding device independently.
| ACI Object | Role | Example |
|---|---|---|
| Tenant | Administrative policy container | PRODUCTION |
| VRF / Context | Independent Layer 3 routing domain | PROD-VRF |
| Bridge Domain | Layer 2 forwarding and subnet policy context | APP-BD |
| Application Profile | Logical grouping of application EPGs | ECOMMERCE |
| Endpoint Group | Endpoints sharing common policy | WEB-EPG |
| Contract | Policy defining permitted communication | WEB-TO-APP |
Policy Does Not Equal Automatic Trust
An endpoint's membership in a tenant, VRF or bridge domain does not automatically permit communication with every other endpoint. ACI policy enforcement depends on contracts, filters and other configured policy mechanisms.
Supporting Multiple Applications on Shared Infrastructure
Multi-tenancy allows independent applications, customers or environments to share a physical network while maintaining appropriate logical separation.
Tenant isolation may use separate VRFs, bridge domains, VXLAN VNIs and security policies. The exact mechanisms depend on the fabric platform and operational model.
| Environment | Routing Domain | Overlay Segments | Connectivity Policy |
|---|---|---|---|
| Production | PROD-VRF | Web / App / DB VNIs | Restricted application flows |
| Development | DEV-VRF | Development VNIs | Isolated from production |
| Management | MGMT-VRF | Management segments | Administrative access only |
| Shared Services | SHARED-VRF | DNS / monitoring segments | Controlled inter-VRF access |
Shared Services Engineering
Services such as DNS, authentication and monitoring may need to be reachable from several tenants. Inter-VRF connectivity must be designed explicitly, including route exchange, firewall policy, return-path routing and overlapping address considerations.
Extending Virtual Network Principles into Public Cloud
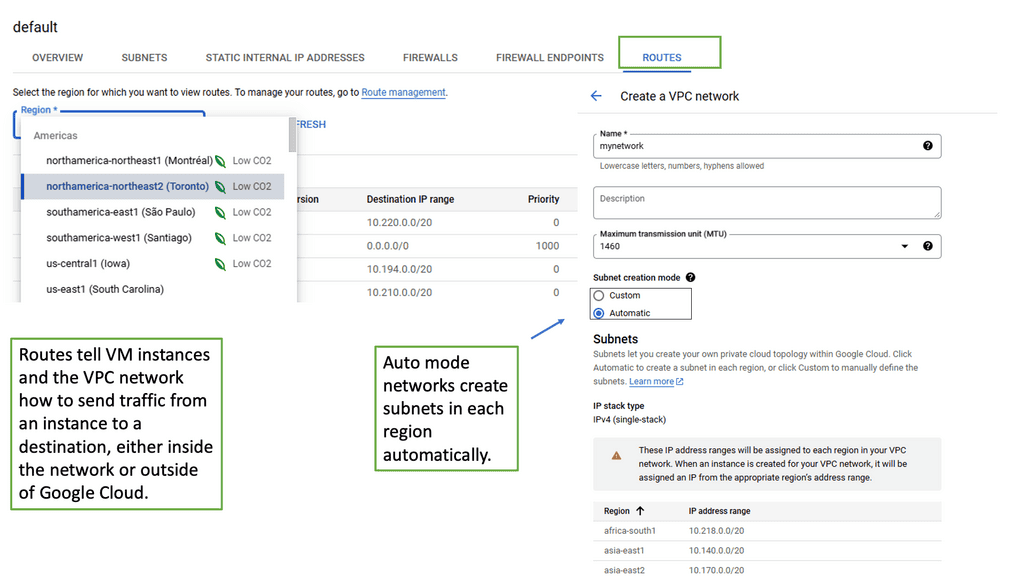
Public cloud platforms expose logical networking services over infrastructure operated by the cloud provider. Customers define address spaces, routes, security policies and connectivity relationships without managing the underlying physical switching fabric.
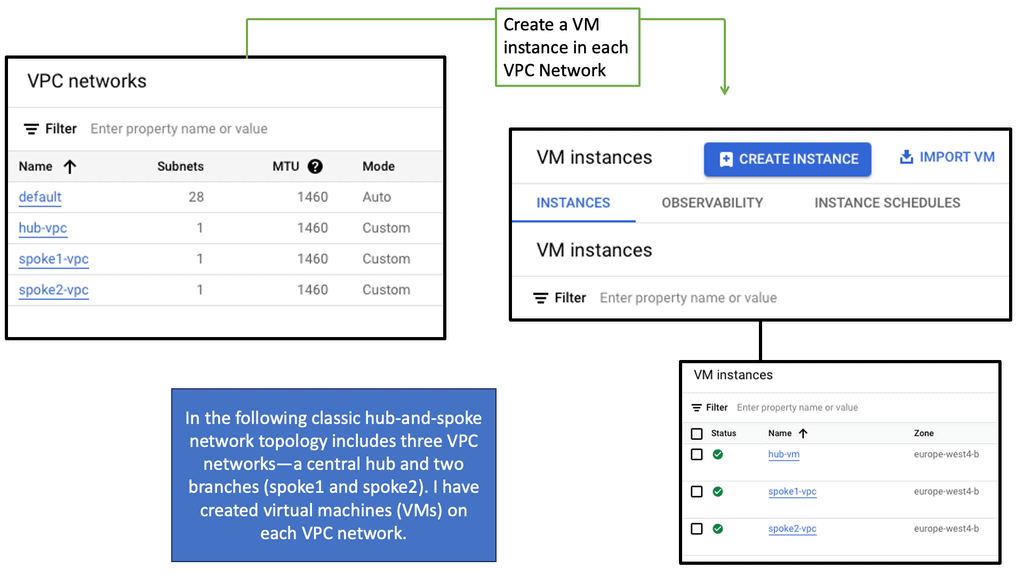
In Google Cloud, a Virtual Private Cloud network provides a logical networking environment for supported cloud resources. Google Cloud VPC networks are global resources, while their subnets are regional.
Virtual Private Cloud
Defines a logical network environment with subnets, routing behaviour and associated firewall controls.
Cloud Routing
Cloud routing services provide route exchange and connectivity between supported cloud and hybrid networking components.
Cloud Firewall Policies
Security rules control permitted traffic according to the provider's firewall model and policy hierarchy.
Private Connectivity
VPN and dedicated connectivity services can connect enterprise networks to cloud environments.
Cloud Networking Is Not Simply VXLAN Exposed to Customers
A cloud VPC and an on-premises VXLAN VNI both provide logical networking abstractions, but they are not interchangeable technologies. Public cloud providers manage their own underlying infrastructure and expose service-specific networking behaviour.
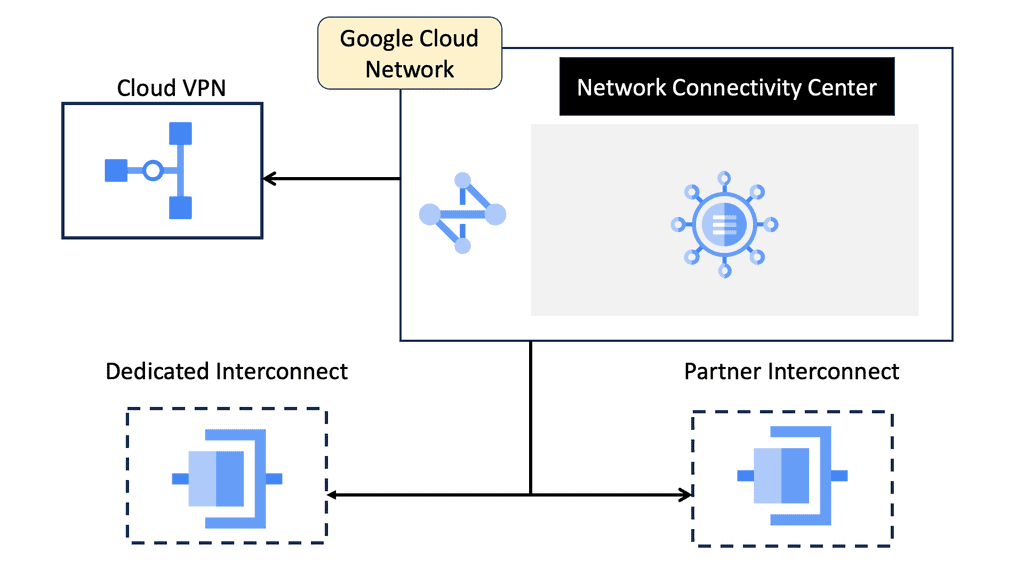
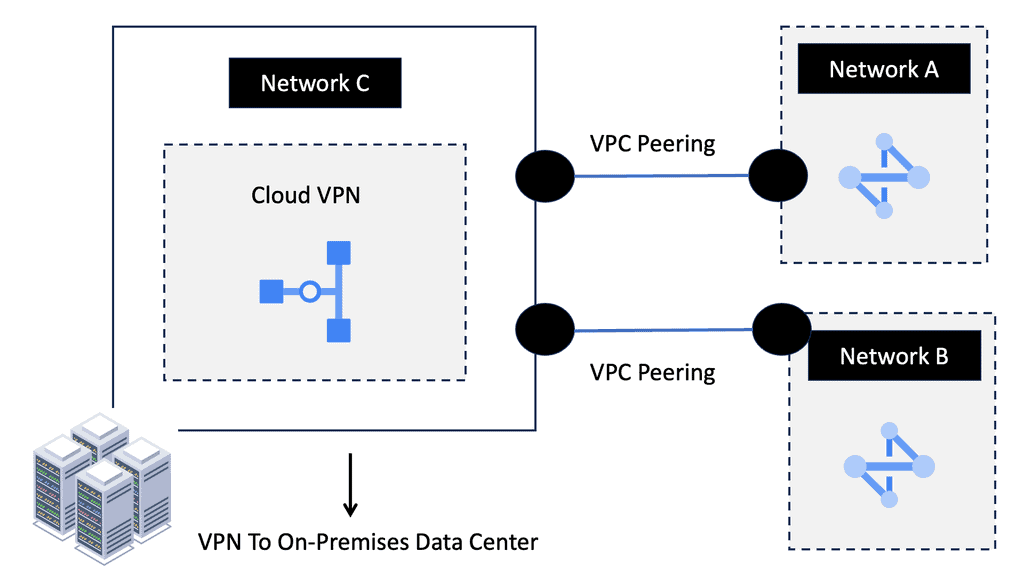
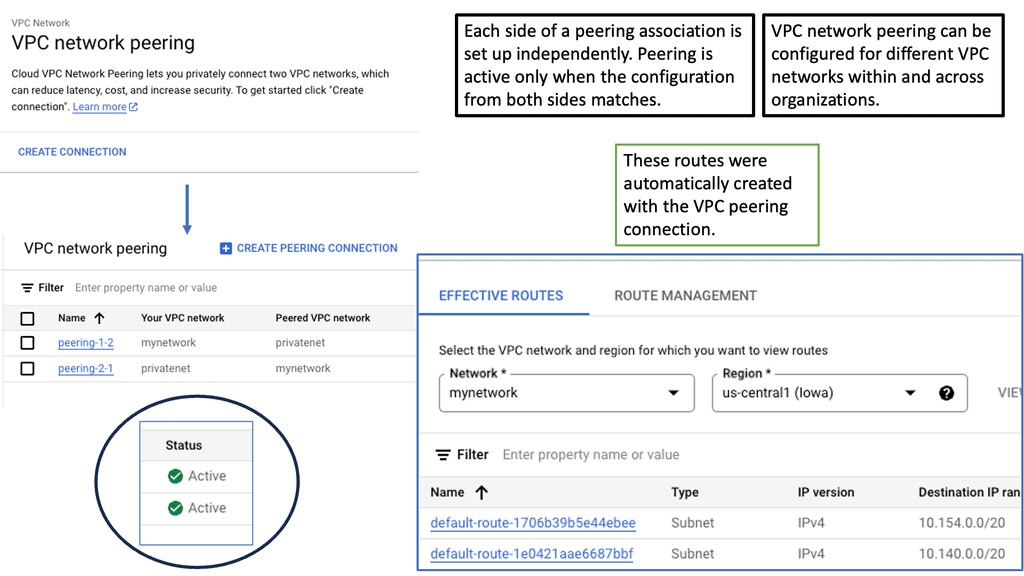
VPC Peering, Network Connectivity Center and Hybrid Routing
Google Cloud offers several mechanisms for connecting networking environments. The appropriate service depends on topology, routing requirements, operational ownership and connectivity scale.
| Service | Primary Function | Engineering Consideration |
|---|---|---|
| VPC Network Peering | Private IP connectivity between supported VPC networks | Non-transitive peering and route exchange constraints |
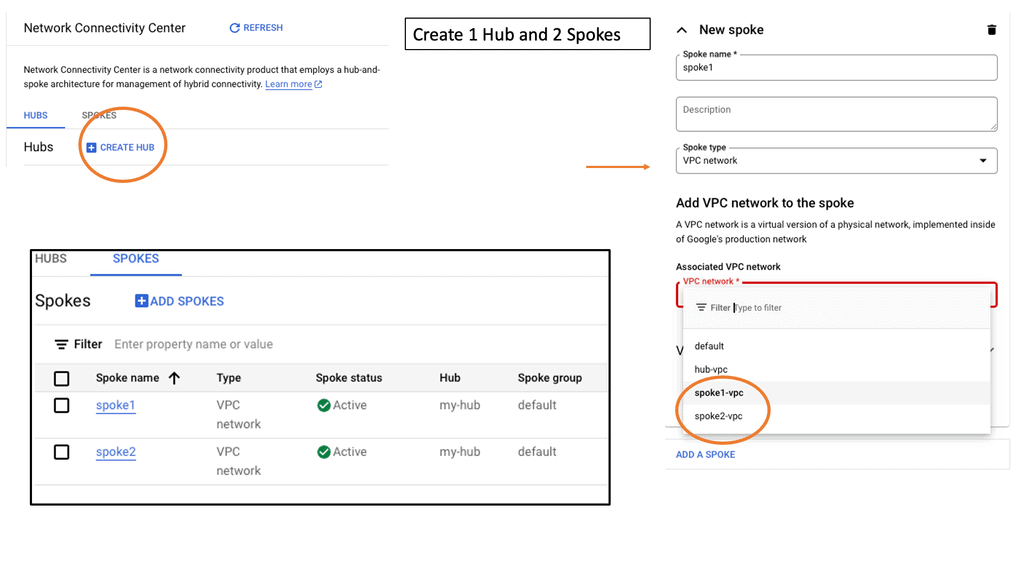
| Network Connectivity Center | Hub-and-spoke connectivity orchestration | Supported spoke types, route exchange and topology behaviour |
| Cloud VPN | IPsec connectivity between networks | Tunnel availability, routing and throughput |
| Cloud Interconnect | Dedicated or partner connectivity into Google Cloud | Capacity, redundancy and Cloud Router/BGP design |
| Cloud Router | Dynamic BGP route exchange for supported connectivity services | Advertisement policy, learned routes and failover |
VPC Peering Is Not Transitive Routing
If VPC A is peered with VPC B, and VPC B is peered with VPC C, that does not automatically provide connectivity between A and C. Architectures requiring hub-and-spoke or transit connectivity should use services and topologies designed for those requirements.
Network Connectivity Center can simplify connectivity management across supported network environments. However, route propagation and transit behaviour depend on the selected spoke types and connectivity configuration.
Connecting On-Premises Data Centres to Cloud Workloads
Hybrid cloud networking combines on-premises infrastructure with cloud-hosted workloads. The objective is to provide controlled reachability between environments while maintaining consistent routing and security boundaries.
Hybrid Routing Principle
Both directions of a communication flow must have valid reachability. Engineers should validate route advertisements, return paths, address overlap, firewall policy and the effect of failover on traffic symmetry.
Enforcing Consistent Security Across Virtual Environments
Virtualization enables logical isolation, but isolation must be combined with explicit security controls to protect applications and sensitive workloads.
On-premises fabrics may enforce security through ACI contracts, ACLs, firewalls and segmentation policies. Cloud environments expose their own firewall, identity and connectivity controls.
Network Segmentation
Separate application tiers and tenants into appropriate forwarding and routing domains.
Least-Privilege Access
Permit only the protocols, ports and communication relationships required by the application.
Identity and Automation
Use consistent policy definitions and controlled automation to reduce configuration drift.
Visibility and Audit
Monitor traffic, policy changes and denied flows across physical, virtual and cloud boundaries.
Security Boundary Warning
VRFs and VPCs provide logical separation, but secure application architecture also requires appropriate access controls, identity policy, encryption where needed and continuous validation.
Investigating Connectivity Across Fabric and Cloud Boundaries
A hybrid connectivity problem can originate in the on-premises fabric, the external connectivity service, cloud routing or a security policy.
Troubleshooting should follow the forwarding path rather than assuming that a healthy physical interface proves end-to-end connectivity.
show ip route vrf PROD-VRF
show bgp ipv4 unicast summary
show bgp l2vpn evpn summary
show nve peers
show nve vni
show mac address-table
show ip arp
show interface brief
gcloud compute networks list
gcloud compute routes list
gcloud compute firewall-rules list
gcloud compute routers list
gcloud compute vpn-tunnels list
gcloud compute interconnects list
| Investigation | Expected Evidence | Possible Fault |
|---|---|---|
| Tenant Routing | Correct VRF route to destination | Missing route or incorrect route leaking |
| Fabric Transport | Healthy underlay and overlay reachability | VTEP, BGP or forwarding issue |
| Hybrid Edge | Expected VPN or Interconnect connectivity | Link, tunnel or BGP failure |
| Cloud Routing | Correct cloud route and return path | Route propagation or priority issue |
| Security | Required flows explicitly permitted | Contract, ACL or cloud firewall denial |
| Application | Service reachable on expected port | DNS, host firewall or application fault |
Incident Scenario: Cloud Routes Present, Application Unreachable
A route in the cloud routing table does not guarantee that application traffic is permitted. Firewall rules, network tags, service accounts, return-path routing, host configuration and application listeners must also be checked.
Traditional Fabric, Cisco ACI and Cloud Networking
| Design Element | EVPN-VXLAN Fabric | Cisco ACI | Cloud VPC |
|---|---|---|---|
| Physical Infrastructure | Customer-managed switches | Customer-managed ACI fabric | Provider-managed |
| Logical Segmentation | VNIs and VRFs | Tenants, VRFs, BDs and EPGs | VPCs, subnets and associated controls |
| Policy Management | Platform-specific configuration and automation | APIC policy model | Cloud APIs and management services |
| Routing | Underlay BGP/IGP and EVPN | ACI fabric control plane and external routing | Cloud-managed routing and supported BGP services |
| Security | ACLs, firewalls and segmentation | Contracts, filters and security controls | Cloud firewall and identity controls |
| Operations | CLI, APIs and telemetry | APIC, APIs and fabric diagnostics | Cloud console, APIs and observability |
These architectures share several objectives, including segmentation, automation and scalable connectivity, but they expose different operational abstractions and management models.
Successful engineering depends on understanding where the forwarding decisions are made, where policy is enforced and which infrastructure components are responsible for failure recovery.
Virtualization Extends the Fabric Beyond Physical Switches
Modern data centre fabrics support logical networks, policy-driven applications and connectivity into cloud environments. The underlying infrastructure remains essential, but virtual services provide flexibility and operational abstraction.
- Network virtualization separates logical connectivity from physical transport.
- VRFs, VNIs and policy objects provide tenant and application segmentation.
- Cisco ACI uses APIC and a policy-driven operational model.
- ACI endpoint groups and contracts define application communication policy.
- Cloud VPCs provide logical networking over provider-managed infrastructure.
- Google Cloud connectivity services support VPC and hybrid networking designs.
- Hybrid networks require correct routing, return paths and security controls.
- Troubleshooting must correlate physical, virtual, cloud and application state.
Fabric Virtualization & Cloud Networking Lab
Investigate how Cisco ACI tenants, VRFs, endpoint groups and contracts control traffic. Explore permitted and denied application flows, then extend the investigation into hybrid connectivity between the data centre and a cloud VPC.
Fabric Policy Controls
Application Flow Investigation
Tenant, VRF & Contract Decision
| Source | Destination | Service | Decision |
|---|
Engineering CLI Console
Inspect simulated policy, routing and endpoint state for the current scenario.
This is a conceptual model of Cisco ACI policy and hybrid networking. ACI contracts operate between endpoint groups and are associated with tenant and VRF contexts. Actual forwarding depends on bridge domains, EPG relationships, contract filters, routing, external EPGs and other configured policy. Cloud VPC connectivity additionally requires working routing, gateway and cloud-side security controls.
Fabric Performance, Telemetry and Analytics
A data centre fabric must deliver more than connectivity. It must provide predictable performance under changing workloads, traffic bursts, failures and increasing application demand.
Modern leaf-spine fabrics use high-speed links, Equal-Cost Multipath forwarding and distributed switching to provide multiple available paths. However, physical capacity alone does not guarantee low latency or consistent application performance.
Effective performance engineering requires understanding traffic distribution, oversubscription, congestion, buffering, queue behaviour and network telemetry.
What Determines Fabric Performance?
Data centre performance is influenced by forwarding capacity, available bandwidth, traffic patterns, packet processing and queueing behaviour.
A fabric may have substantial aggregate capacity while still experiencing congestion on individual interfaces or queues.
Bandwidth
The maximum data transmission capacity available across links and forwarding paths.
Latency
The time required for traffic to travel between endpoints, including forwarding and queueing delays.
Packet Loss
Packets may be discarded because of congestion, buffer exhaustion, policy or physical errors.
Jitter
Variation in packet delay caused by changing forwarding and queueing conditions.
Engineering Principle
A low average interface utilisation does not prove that a link is free from congestion. Short traffic bursts may exceed available capacity even when long-term averages appear healthy.
How ECMP Distributes Traffic Across the Fabric
Equal-Cost Multipath, or ECMP, allows a forwarding device to install multiple eligible next hops for the same destination prefix.
In a leaf-spine topology, a leaf switch may have several equal-cost paths through different spine switches toward a remote leaf.
Many platforms use a hash derived from packet header fields, such as source and destination addresses, protocol and transport ports.
This flow-based selection helps avoid packet reordering within a flow, but it does not guarantee perfectly equal bandwidth utilisation.
ECMP Limitation: Elephant Flows
A small number of large flows can create uneven link utilisation. A single high-bandwidth flow may remain assigned to one ECMP next hop, even when other paths have spare capacity. Adaptive load balancing is platform-dependent.
Calculating Fabric Capacity and Oversubscription
Oversubscription describes the relationship between available downstream capacity and upstream connectivity capacity.
For example, a leaf switch may connect 48 servers at 25 Gbps while providing six 100 Gbps uplinks to the spine layer.
| Ratio | Meaning | Design Implication |
|---|---|---|
| 1:1 | Equal aggregate downlink and uplink capacity | Low nominal oversubscription at the measured boundary |
| 2:1 | Twice as much downstream as upstream capacity | Requires consideration of simultaneous traffic demand |
| 4:1 | Four times as much downstream as upstream capacity | Higher potential contention under heavy load |
| 8:1 | Eight times as much downstream as upstream capacity | Suitable only when workload demand supports the tradeoff |
Capacity Planning
Oversubscription should be evaluated alongside real traffic profiles, application placement, failure scenarios and peak demand. A 1:1 ratio at one leaf does not guarantee that the entire network is non-blocking.
Why Short Traffic Bursts Cause Unexpected Packet Loss
A microburst is a short-lived increase in traffic arrival rate that can exceed the capacity of an egress interface or queue.
Microbursts may last microseconds or milliseconds, making them difficult to identify through coarse interface polling intervals.
Consider several servers simultaneously transmitting toward one destination. The aggregate ingress traffic may temporarily exceed the destination-facing interface capacity.
The switch attempts to absorb the excess traffic using buffers. If the queue exceeds available buffering capacity, packets may be dropped.
Microburst Investigation
A 100 Gbps interface can show low average utilisation while experiencing brief congestion and packet drops. High-resolution queue telemetry, drop counters and packet capture evidence may be needed to identify the event.
How Switch Buffers Influence Latency and Packet Loss
Network switches use packet buffers to handle temporary differences between traffic arrival and departure rates.
Buffering can absorb short bursts, but excessive queue occupancy increases packet delay. When available buffer space is exhausted, packets may be discarded.
Low Occupancy
Traffic is forwarded with limited queueing delay when the egress path has sufficient capacity.
Growing Queue
The arrival rate temporarily exceeds the service rate, increasing buffer occupancy and packet latency.
Congestion Marking
Supported devices may use ECN or congestion management mechanisms to signal congestion before buffer exhaustion.
Recovery
As arrival rates fall below departure capacity, queued packets drain and latency can return toward baseline.
Buffer Size Is Not the Only Design Variable
Larger buffers may absorb more burst traffic but can also increase latency under persistent congestion. Queue scheduling, traffic classification, congestion avoidance and workload behaviour must be considered together.
How Fabric Congestion Affects Application Throughput
Packet loss and increasing round-trip time can affect application throughput, particularly for transport protocols that adapt their sending behaviour in response to congestion signals.
TCP congestion control algorithms adjust sending rates based on acknowledgements, packet loss, timing information or ECN feedback, depending on the implementation.
| Condition | Network Effect | Application Impact |
|---|---|---|
| Queue Build-up | Increased packet waiting time | Higher latency and possible response-time variation |
| Packet Drops | Lost packets and retransmissions | Reduced effective throughput or delayed completion |
| ECMP Imbalance | Some paths more heavily utilised | Uneven flow performance |
| MTU Mismatch | Dropped oversized packets or fragmentation where applicable | Connectivity or throughput problems |
| ECN Marking | Congestion signalled without necessarily dropping packets | Compatible senders may reduce their transmission rate |
VXLAN Performance Consideration
EVPN-VXLAN fabrics introduce encapsulation overhead. The transport MTU must accommodate the outer headers and original payload. Incorrect MTU configuration can cause packet loss or forwarding failures, particularly for larger packets.
Observing Fabric Behaviour in Near Real Time
Traditional monitoring often relies on periodic polling of interface counters and device state. While useful for capacity planning and fault detection, coarse polling may miss short-duration congestion events.
Streaming telemetry enables supported devices to publish operational measurements to external collectors. Depending on the platform, these measurements may include interface statistics, queue occupancy, drops, routing state and hardware telemetry.
| Telemetry Metric | What It Reveals | Engineering Use |
|---|---|---|
| Interface Utilisation | Traffic load over a measurement interval | Capacity planning and imbalance detection |
| Queue Occupancy | Buffer usage over time | Microburst and congestion investigation |
| Packet Drops | Discarded traffic by interface or queue | Congestion and error diagnosis |
| ECMP Path Counters | Traffic distribution across available paths | Load-balancing validation |
| Routing Events | Neighbour changes and route updates | Convergence and stability analysis |
| Latency Measurements | Delay observed through supported measurement mechanisms | Application performance investigation |
Telemetry Resolution Matters
Streaming telemetry does not automatically guarantee visibility into every microburst. Measurement accuracy depends on hardware counters, collection intervals, supported sensors and the monitoring pipeline.
Understanding Who Is Using Fabric Capacity
Interface counters show how much traffic passes through a link, but they do not necessarily identify the applications or endpoints responsible for that traffic.
Flow telemetry, packet sampling and application-aware monitoring can provide additional context about traffic sources, destinations and communication patterns.
Top Talkers
Identify endpoints or applications generating substantial traffic volumes.
East-West Traffic
Observe communication patterns between workloads inside the data centre.
Traffic Distribution
Correlate flow demand with forwarding paths and link utilisation.
Anomaly Detection
Investigate unexpected traffic changes, unusual communication patterns and emerging congestion.
Telemetry Correlation
A useful investigation correlates flow information with interface utilisation, queue counters, routing state and application performance measurements. No single metric provides a complete explanation of fabric behaviour.
Investigating Latency, Congestion and Packet Loss
Performance incidents should be approached systematically. The investigation begins by defining the affected application flows, identifying the relevant forwarding paths and examining available performance evidence.
show interface ethernet 1/1
show interface counters errors
show interface counters discards
show queuing interface ethernet 1/1
show policy-map interface ethernet 1/1
show ip route 10.10.10.0/24
show forwarding distribution
show logging last 50
| Symptom | Evidence to Collect | Potential Cause |
|---|---|---|
| High Latency | Queue depth, RTT and traffic timing | Queueing or application processing |
| Packet Drops | Interface and queue discard counters | Congestion, errors or policy |
| Uneven Links | ECMP member counters and flow distribution | Hash imbalance or elephant flows |
| Intermittent Loss | High-resolution telemetry and event timestamps | Microbursts or transient faults |
| Low Throughput | TCP behaviour, RTT, drops and MTU | Congestion, host or path constraints |
Incident: A Healthy Fabric with Poor Application Performance
Consider a production leaf-spine fabric with multiple 100 Gbps uplinks and stable BGP routing sessions.
Network monitoring reports average interface utilisation below 35%. However, an application team reports intermittent latency spikes and TCP retransmissions during database synchronisation.
Initial Symptoms
Routing sessions remain established. No physical links are down. Average bandwidth utilisation appears normal, yet application performance degrades during specific workload events.
| Evidence | Observation | Interpretation |
|---|---|---|
| Routing State | Stable BGP and ECMP routes | No obvious control-plane failure |
| Average Utilisation | Below 35% | Long-term average does not explain short bursts |
| Queue Telemetry | Short occupancy spikes | Possible transient egress congestion |
| Drop Counters | Increases during synchronisation | Packets discarded during workload events |
| Flow Analysis | Several large flows share one uplink | Potential ECMP hash concentration |
Engineering Diagnosis
In this illustrative scenario, the evidence suggests transient egress congestion caused by synchronised traffic bursts and uneven flow distribution. The next step is to validate queue behaviour and forwarding decisions before selecting a corrective action.
Possible improvements include adjusting workload scheduling, reviewing traffic placement, evaluating supported load-balancing mechanisms or increasing capacity where measurements justify it.
Changes to buffer allocation, QoS or congestion management should be tested carefully because they can shift contention rather than eliminate it.
Building a Performance-Aware Fabric
| Design Area | Engineering Requirement | Validation Method |
|---|---|---|
| Capacity | Appropriate bandwidth and oversubscription | Peak-load and failure-capacity testing |
| ECMP | Correct path installation and traffic distribution | Next-hop and flow-counter analysis |
| Congestion | Predictable queue and drop behaviour | Queue telemetry and controlled traffic tests |
| MTU | Support for overlay encapsulation | End-to-end packet-size validation |
| Telemetry | Relevant metrics at useful resolution | Monitoring pipeline and event validation |
| Resilience | Acceptable performance after path failure | Fault injection and convergence testing |
| Applications | Network performance aligned with workload needs | Application-level latency and throughput tests |
A performance-aware fabric combines sound topology design with realistic traffic modelling and operational observability.
Engineers should measure both normal operation and degraded conditions, including link failures, path changes and simultaneous workload peaks.
Fabric Performance Depends on Traffic Behaviour, Not Just Link Speed
High-bandwidth leaf-spine fabrics provide substantial forwarding capacity, but application performance depends on how traffic is distributed, queued and delivered under changing conditions.
- ECMP provides multiple eligible forwarding paths, but flow hashing can produce uneven utilisation.
- Oversubscription ratios describe nominal capacity relationships, not guaranteed application throughput.
- Microbursts can cause congestion and drops despite low average interface utilisation.
- Switch buffers absorb temporary traffic bursts but can introduce queueing delay.
- TCP performance is affected by packet loss, delay and congestion behaviour.
- Streaming telemetry and flow analytics improve visibility into operational fabric behaviour.
- Troubleshooting should correlate forwarding paths, queue counters, traffic patterns and application measurements.
- Performance validation must include peak-load conditions and failure scenarios.
Fabric Performance & Analytics Lab
Investigate ECMP traffic distribution, uplink utilization, oversubscription and microburst congestion. Change traffic patterns and link capacity, then inspect queue depth, packet loss and engineering telemetry in a simulated leaf-spine fabric.
Performance Experiment Controls
ECMP Link Utilization
Each spine represents one equal-cost forwarding path between the source and destination leaf switches.
Utilization bars are capped visually at 100%. The labels show offered load, which can exceed the physical link rate. Excess traffic must queue or be dropped.
Microburst & Queue Depth Timeline
The chart shows modeled queue occupancy over the configured burst duration. The dashed line represents the selected buffer limit.
Engineering Telemetry Table
| Interface | Offered Load | Capacity | Utilization | Queue / Drop |
|---|
Engineering CLI Console
Inspect simulated interface counters, queue behavior and ECMP distribution.
Model assumptions: two independent spine uplinks, fixed traffic distribution, constant offered load during a burst, initially empty buffers and a work-conserving output queue per link. Queue growth is calculated from the excess offered rate. Actual ASIC behavior, ECMP hashing, scheduling, shared buffers, pause frames and congestion control are more complex. The values are illustrative engineering calculations, not live device telemetry.
Fabric Security, Segmentation and Resilience
Modern data centre fabrics must provide secure, predictable connectivity while remaining resilient to device failures, link outages, configuration errors and changing application requirements.
Security and resilience are closely related engineering disciplines. Segmentation restricts unwanted communication, while redundancy and failure recovery maintain application availability when infrastructure components fail.
A well-designed fabric combines logical isolation, distributed forwarding, explicit security policy and multiple independent paths.
Security Boundaries Inside the Data Centre Fabric
Data centre security is no longer limited to traffic entering or leaving the network. Applications frequently communicate with other workloads inside the same data centre.
This east-west traffic may include communication between web servers, application services, databases, management systems and shared infrastructure.
Segmentation
Separate workloads into appropriate Layer 2, Layer 3 and security domains.
Policy Enforcement
Control which applications, protocols and services are permitted to communicate.
Traffic Inspection
Use appropriate firewall and inspection services where traffic requires deeper security controls.
Operational Visibility
Monitor permitted and denied communication, policy changes and security events.
Engineering Principle
A shared physical fabric does not require a shared security domain. VRFs, VLANs, VXLAN VNIs, ACLs and security services can establish logical boundaries between workloads.
Separating Application Tiers and Trust Domains
Segmentation limits the reachability between applications and infrastructure services. A common architecture separates frontend, application, database and management environments.
Security policy should define required communication relationships rather than permitting unrestricted connectivity between every application tier.
| Source | Destination | Example Policy |
|---|---|---|
| Web | Application | Permit required application service ports |
| Application | Database | Permit required database connections |
| Web | Database | Deny direct access unless explicitly required |
| Management | Infrastructure | Permit controlled administrative access |
Segmentation Is Not Always Stateful Inspection
VRFs and VXLAN segments establish logical separation. ACLs can filter traffic, but conventional ACL enforcement is not equivalent to stateful firewall inspection. The required security function must be selected deliberately.
Enforcing Security Close to the Workload
Traditional designs often centralised security inspection at network aggregation points. Modern fabrics can enforce selected policies closer to connected workloads.
Depending on the platform, security controls may include interface ACLs, VLAN-based policies, ACI contracts, distributed firewalling or external inspection services.
Interface ACLs
Apply filtering to traffic entering or leaving selected interfaces.
Fabric Policy
Use logical groups and contracts where supported by the fabric architecture.
Distributed Firewall
Apply supported stateful controls near virtual workloads or network endpoints.
Central Inspection
Redirect selected traffic through dedicated security appliances or service chains.
Policy Placement Matters
Security enforcement should account for traffic direction, routing symmetry, encapsulation, endpoint mobility and application requirements. An incorrectly positioned policy may permit unwanted traffic or disrupt legitimate flows.
Service Insertion and East-West Traffic Inspection
Some application flows require security functions beyond basic routing and packet filtering. These may include stateful inspection, intrusion prevention, application controls or threat detection.
A fabric can integrate dedicated security services through routed service insertion, policy-based steering or supported service-chaining mechanisms.
Asymmetric Routing Risk
Stateful firewalls generally need sufficient visibility into the relevant connection state. If forward and return traffic traverse different firewall instances without appropriate state sharing, valid traffic may be dropped.
Maintaining Local First-Hop Routing Across the Fabric
EVPN-VXLAN fabrics commonly use distributed anycast gateway functionality. Multiple leaf switches present a consistent default gateway IP and virtual MAC address for a given subnet.
This allows connected endpoints to use a local leaf for first-hop routing, rather than forwarding all gateway traffic toward a central aggregation device.
Anycast Gateway Versus HSRP or VRRP
Traditional HSRP and VRRP provide first-hop redundancy using active gateway election or priority mechanisms. Distributed anycast gateways instead allow multiple participating leaf switches to provide the same logical gateway concurrently.
Maintaining Connectivity During Individual Link Failures
Link aggregation combines multiple physical interfaces into a logical connection. Port channels can provide increased aggregate bandwidth and redundancy when correctly configured.
Link Aggregation Control Protocol, or LACP, supports negotiation and operational management of aggregated links.
Port Channels
Multiple physical members operate as one logical interface.
LACP
Negotiates aggregation membership and helps detect incompatible link states.
vPC / MLAG
Supported architectures allow a downstream device to aggregate links toward two physical switches.
Failure Recovery
Traffic may continue over surviving members when a link fails, subject to remaining capacity.
Port Channels Do Not Multiply Single-Flow Bandwidth Automatically
Most port-channel implementations use flow-based hashing to distribute traffic. Aggregate capacity increases across multiple flows, but a single flow is commonly limited by the selected physical member.
Detecting Unidirectional Link Failures
A physical Ethernet link may experience asymmetric failure conditions where communication works in one direction but not the other.
Cisco Unidirectional Link Detection, or UDLD, can help detect certain unidirectional connectivity failures between supported directly connected devices.
| Mechanism | Purpose | Engineering Consideration |
|---|---|---|
| UDLD | Detect supported unidirectional link conditions | Mode and platform behaviour matter |
| LACP | Manage link aggregation state | Requires compatible configuration |
| Interface Monitoring | Detect errors and physical faults | Inspect optics, CRC and link counters |
| BFD | Provide rapid forwarding-path failure detection where supported | Timer and platform capabilities matter |
| Routing Convergence | Recalculate forwarding after topology changes | Depends on detection and protocol behaviour |
UDLD Is a Complementary Mechanism
UDLD does not replace routing protocols, LACP or physical monitoring. It addresses a particular category of link failure and should be deployed according to platform and operational requirements.
Designing for Device, Link and Control-Plane Failures
Resilience depends on limiting the impact of individual component failures. A well-designed leaf-spine fabric provides multiple available paths between network endpoints.
However, resilience requires more than adding redundant links. Routing convergence, device placement, power diversity, control-plane stability and operational procedures must also be considered.
| Failure | Expected Response | Validation |
|---|---|---|
| Single Spine Failure | Remove failed next hops and use surviving paths | Routing and ECMP state |
| Uplink Failure | Use remaining uplinks where available | Interface and next-hop counters |
| Leaf Failure | Dual-attached endpoints may retain connectivity | Host attachment and failover tests |
| BGP Neighbour Failure | Withdraw or replace affected routes | BGP session and route state |
| Firewall Failure | Recover through designed security redundancy | Session continuity and policy tests |
Redundancy Must Be Tested Under Load
Surviving paths may remain operational after a failure, but they must have sufficient capacity for the redirected traffic. A resilient design must account for degraded-state performance.
Protecting Routing Stability and Fabric Convergence
Modern IP fabrics depend on routing protocols to discover available paths and respond to topology changes.
BGP-based underlays commonly rely on multiple neighbour sessions and ECMP next hops to provide resilient forwarding.
BGP Session Health
Monitor neighbour state, route advertisements and session stability.
BFD
Use supported fast failure detection where operationally appropriate.
Route Policy
Validate prefix filtering, route acceptance and advertised reachability.
Control-Plane Protection
Protect device control planes from unwanted traffic and excessive protocol load.
Fast Detection Is Only Part of Convergence
Failure recovery includes fault detection, route recalculation, forwarding-table updates and application recovery. Reducing detection time alone does not guarantee uninterrupted application traffic.
Operational Commands for Fabric Verification
Security and resilience troubleshooting should correlate interface state, routing state, policy configuration and forwarding behaviour.
show interface brief
show port-channel summary
show lacp neighbor
show vpc brief
show udld neighbors
show bgp ipv4 unicast summary
show ip route
show nve peers
show logging last 50
show access-lists
show running-config interface ethernet 1/1
show ip interface brief
show ip route vrf all
show forwarding route
show logging last 50
| Check | Expected Evidence | Potential Fault |
|---|---|---|
| Physical Links | Interfaces operational with acceptable errors | Optics, cabling or physical failure |
| Port Channel | Expected members bundled and forwarding | LACP or configuration mismatch |
| Routing | Healthy sessions and correct next hops | Neighbour or route-policy failure |
| Overlay | Expected VTEP and VNI state | EVPN or NVE issue |
| Security Policy | Required flows permitted, unwanted flows denied | ACL, contract or firewall mismatch |
| Failure Recovery | Traffic uses surviving paths | Convergence or redundancy problem |
Incident: A Spine Failure Exposes a Security Policy Problem
Consider a production fabric with three spine switches and multiple leaf switches. Application traffic normally uses several equal-cost forwarding paths.
During maintenance, one spine becomes unavailable. Routing converges and the surviving spine switches continue forwarding traffic.
However, a subset of application flows begins failing even though the routing table contains valid alternate paths.
Initial Symptoms
BGP sessions to surviving spines remain established. ECMP routes are updated. Most applications remain available, but selected database connections fail after the topology change.
| Evidence | Observation | Interpretation |
|---|---|---|
| Routing | Valid alternate next hops | Basic fabric reachability remains |
| ECMP | Traffic redistributed across surviving paths | Expected failure response |
| Firewall Logs | Connection-state drops increase | Possible asymmetric service path |
| Application | Selected database sessions fail | Impact isolated to inspected flows |
Engineering Diagnosis
In this illustrative incident, the topology change causes affected traffic to traverse different stateful firewall instances without the necessary session synchronisation. The resulting asymmetric inspection path causes valid traffic to be dropped.
Corrective actions depend on the firewall and service insertion design. They may include restoring symmetric steering, validating high-availability state synchronisation or correcting routing and policy relationships.
The incident demonstrates why resilience testing must include security services, not just routing convergence.
Testing Security and Resilience Before Production
| Test | Success Criteria |
|---|---|
| Spine Failure | Traffic recovers through surviving paths within the required service objective |
| Leaf Uplink Failure | Expected alternate paths remain available |
| Firewall Failover | Required security policy remains enforced and permitted services recover |
| Segmentation Test | Unauthorised communication remains blocked before and after failures |
| Gateway Test | First-hop routing remains available where redundant attachment exists |
| Capacity Test | Surviving paths support required degraded-state traffic demand |
Controlled Failure Testing
Failure injection should be performed in a lab or approved maintenance environment with defined rollback procedures. Production changes must follow operational change controls.
Secure Fabrics Must Remain Secure During Failure
Fabric security and resilience should be designed together. Redundant links and routing paths maintain reachability, while segmentation, policy enforcement and inspection services protect application communication.
- Segmentation establishes logical boundaries between workloads and tenants.
- ACLs, contracts and firewalls provide different levels of traffic enforcement.
- Distributed anycast gateways provide local first-hop routing across participating leaf switches.
- Port channels, LACP and multi-chassis aggregation can improve link resilience.
- UDLD and BFD address specific failure detection requirements.
- ECMP and routing convergence provide alternate paths when fabric components fail.
- Stateful firewall integration requires careful consideration of routing symmetry and session state.
- Security controls must remain effective during degraded network conditions.
- Resilience testing should validate application behaviour, not just device and routing state.
Fabric Security & Resilience Lab
Investigate segmentation, firewall inspection and network resilience in a modern data centre. Trace authorized and unauthorized traffic, introduce failures, and compare the healthy fabric against an incident state.
Security Investigation Controls
Packet Journey & Security Decision
Security Policy Decision Table
| Source | Destination | Service | Policy |
|---|
Healthy Baseline vs Incident State
Engineering CLI Console
Inspect simulated security and forwarding state to determine whether a traffic failure originates from policy or network reachability.
Educational model: the lab simplifies segmentation, ACLs, firewall insertion, BGP reachability and ECMP. A real deployment requires explicit service-chain design, symmetric firewall traversal where applicable, correct route advertisement and convergence, plus validation of firewall high availability. An ALLOW policy does not guarantee delivery, and an available ECMP path does not guarantee the security service is reachable.
Fabric Design, Validation and Troubleshooting
Designing a production data centre fabric requires more than selecting a topology and configuring routing protocols. The architecture must support application demand, operational visibility, security requirements, scalability and predictable failure recovery.
Modern fabrics combine Clos connectivity, Layer 3 routing, ECMP, EVPN-VXLAN overlays and distributed network services.
Successful engineering depends on validating how these components interact during normal operation, traffic congestion, maintenance events and unexpected failures.
Start with Workload and Operational Requirements
Fabric design should begin with application requirements rather than hardware selection. Engineers need to understand traffic patterns, growth expectations, security boundaries and availability objectives.
Application Connectivity
Identify required Layer 2 adjacency, Layer 3 routing and communication between services.
Performance
Define bandwidth, latency, oversubscription and peak traffic requirements.
Security
Determine tenant boundaries, segmentation, inspection and management access policies.
Resilience
Establish failure tolerance, convergence expectations and acceptable service impact.
Design Principle
A fabric should be evaluated against measurable application and operational requirements. A technically functional topology is not necessarily an appropriate production design.
Selecting the Appropriate Fabric Architecture
A two-tier Clos architecture is commonly used for modern data centre fabrics. Leaf switches provide endpoint connectivity, while spine switches provide inter-leaf transport.
Larger environments may introduce additional fabric tiers or interconnected pods when scaling beyond a single leaf-spine domain.
| Architecture | Characteristics | Design Consideration |
|---|---|---|
| Traditional Three-Tier | Access, aggregation and core layers | May introduce Layer 2 blocking or aggregation bottlenecks |
| Two-Tier Clos | Leaf-spine connectivity with multiple paths | Suitable for many scalable data centre deployments |
| Multi-Stage Clos | Additional switching tiers | Supports larger scale with additional design complexity |
| EVPN-VXLAN Fabric | Routed transport with logical overlay networks | Requires coordinated underlay, overlay and gateway design |
Calculating Port Capacity and Growth Requirements
Capacity planning should consider server-facing connectivity, uplink bandwidth, oversubscription, traffic distribution and future workload growth.
Consider a leaf switch with 48 server-facing ports operating at 25 Gbps, and six uplinks operating at 100 Gbps.
Engineers should also evaluate the remaining bandwidth after losing one or more uplinks.
Design for Failure, Not Only Normal Operation
A fabric may meet bandwidth requirements under normal conditions but become congested after losing a spine or uplink. Capacity planning should include expected failure scenarios and traffic peaks.
Separating Physical Reachability from Virtual Networks
Modern EVPN-VXLAN fabrics separate the physical transport network from logical tenant networks.
The underlay provides IP reachability between VTEPs, while the overlay provides virtual Layer 2 and Layer 3 connectivity.
IP Fabric
Physical links, routed interfaces, addressing, BGP or another routing protocol, and ECMP.
EVPN-VXLAN
VTEPs, VNIs, EVPN route exchange, tenant VRFs and distributed gateway services.
| Design Element | Validation Question |
|---|---|
| Underlay Routing | Can every required VTEP reach the remote VTEP addresses? |
| ECMP | Are the expected equal-cost next hops installed? |
| EVPN | Are the expected MAC/IP and IP prefix routes exchanged? |
| VNI Mapping | Are VLANs, VNIs and tenant VRFs mapped correctly? |
| Anycast Gateway | Are gateway parameters consistent on participating leaf switches? |
| MTU | Can the transport path carry the encapsulated packets? |
Layered Troubleshooting
When overlay connectivity fails, first verify the underlying IP transport. A VTEP reachability problem can disrupt VXLAN traffic even when EVPN configuration appears correct.
Recording the Healthy State Before Investigating Failures
Troubleshooting becomes more effective when engineers have a verified baseline of normal network behaviour.
A baseline should capture topology, routing neighbours, forwarding tables, overlay state, interface counters and expected application connectivity.
| Component | Healthy Baseline | Failure Indicator |
|---|---|---|
| Physical Interfaces | Expected links operational | Down links or rising errors |
| BGP Underlay | Expected neighbours established | Missing sessions or routes |
| ECMP | Expected next-hop members installed | Reduced or incorrect path set |
| EVPN Control Plane | Expected EVPN routes present | Missing MAC/IP or prefix advertisements |
| VXLAN | Expected VNI and peer state | VNI mismatch or unreachable VTEP |
| Security | Required flows permitted and unwanted flows blocked | Policy mismatch or unexpected drops |
| Performance | Normal latency, loss and queue behaviour | Congestion or abnormal counters |
Network State Comparison
Comparing healthy and incident states helps isolate the changes responsible for a failure. This includes differences in BGP routes, EVPN advertisements, forwarding next hops, interface state and security policy.
Investigating the Fabric Layer by Layer
A structured troubleshooting process reduces the risk of making unnecessary configuration changes.
Engineers should establish the affected scope, confirm the physical topology, validate underlay routing, inspect overlay state and trace the forwarding path.
show interface brief
show interface counters errors
show lldp neighbors
show bgp ipv4 unicast summary
show ip route
show ip route 10.255.0.12/32
show logging last 50
show bgp l2vpn evpn summary
show bgp l2vpn evpn
show nve peers
show nve vni
show mac address-table
show ip route vrf all
show running-config interface nve1
Control Plane Versus Data Plane
A route appearing in the control plane does not always prove that the forwarding hardware is correctly programmed. Where supported, verify the actual hardware forwarding state and use traffic testing to confirm delivery.
Tracing a Packet Through an EVPN-VXLAN Fabric
Understanding packet forwarding requires following the traffic from the source workload through the ingress VTEP, routed underlay and destination VTEP.
| Stage | Forwarding Operation | Validation |
|---|---|---|
| Host A | Creates the original Ethernet/IP traffic | Source addressing and gateway |
| Ingress Leaf | Performs endpoint lookup and VXLAN encapsulation when required | MAC/IP routes and VNI mapping |
| Underlay | Routes the outer IP packet toward the remote VTEP | Routing and ECMP next hops |
| Egress Leaf | Decapsulates and forwards toward the destination | Local endpoint and forwarding state |
| Host B | Receives the original traffic | Application and packet delivery |
Comparing Healthy and Failed Fabric States
Network failures should be analysed by identifying what changed between the healthy state and the incident state.
The most useful comparison includes routing, forwarding, overlay state, security policy and packet delivery results.
| Component | Healthy State | Incident State |
|---|---|---|
| Physical Link | Operational | One uplink unavailable |
| BGP Session | Established | One neighbour down |
| ECMP | Three next hops | Two next hops |
| VTEP Reachability | Reachable | Reachable through alternate paths |
| EVPN Routes | Expected routes present | Expected routes remain present |
| Application | Normal latency | Increased latency under load |
Interpreting the Evidence
In this illustrative case, the fabric retains logical reachability after the uplink failure. However, the reduced path capacity may cause congestion under peak application demand. The problem is degraded performance rather than complete routing failure.
Incident: The Fabric Is Up, but Applications Are Failing
A production data centre operates a three-spine EVPN-VXLAN fabric. All leaf switches maintain BGP underlay sessions and exchange EVPN routes.
Following a planned maintenance event, application teams report intermittent packet loss between two workload segments.
Basic connectivity tests succeed, but large application transfers experience timeouts and degraded throughput.
Incident Symptoms
BGP underlay sessions are established. EVPN routes remain present. VTEP addresses are reachable. Small test packets succeed, while larger transfers fail intermittently.
| Investigation | Finding | Significance |
|---|---|---|
| Physical Interfaces | All expected links operational | No obvious link failure |
| BGP Underlay | Expected routing sessions established | Control plane appears healthy |
| EVPN | Expected endpoint routes present | Overlay advertisements are available |
| VTEP Reachability | Small probes succeed | Basic transport connectivity exists |
| MTU Validation | One transport link has a smaller MTU | Encapsulated packets may exceed path MTU |
| Traffic Testing | Larger packets fail on affected path | Confirms packet-size-related forwarding issue |
Root Cause
In this illustrative incident, a transport interface was configured with an MTU that could not accommodate the required VXLAN encapsulation overhead. Certain ECMP flows used the affected path, resulting in intermittent application failures.
The corrective action is to align transport MTU configuration with the supported encapsulated packet size and verify forwarding across all relevant ECMP paths.
The engineer should then repeat the original application tests, validate packet-size handling and confirm that no unexpected packet drops remain.
Engineering Lesson
Healthy BGP sessions and valid EVPN routes do not guarantee successful application delivery. The complete forwarding path, including transport MTU and hardware behaviour, must be validated.
Balancing Scalability, Complexity and Operational Risk
Every fabric architecture introduces tradeoffs. Increasing redundancy, segmentation and automation can improve operational capabilities, but may also increase the number of components that must be designed, monitored and maintained.
| Decision | Benefit | Tradeoff |
|---|---|---|
| More Spines | Additional aggregate path capacity | Cost, ports and operational complexity |
| EVPN-VXLAN | Scalable logical networks and distributed gateways | Overlay control-plane and troubleshooting complexity |
| Higher Uplink Capacity | Reduced nominal oversubscription | Optics and hardware cost |
| Distributed Security | Policy enforcement closer to workloads | Policy consistency and visibility requirements |
| Automation | Repeatable provisioning and validation | Requires reliable testing and change control |
| Streaming Telemetry | Improved operational visibility | Collection, storage and analysis overhead |
Production Readiness Checklist
Before production deployment, the fabric should be validated against the original design requirements.
Production Acceptance
A fabric should not be considered production-ready solely because routing neighbours are established. Acceptance should include forwarding, security, resilience and application-level validation.
From Network Architecture to Operational Confidence
Data centre fabric engineering combines several disciplines: topology design, routing, encapsulation, security, capacity planning, telemetry and troubleshooting.
Each discipline contributes to the overall reliability of the infrastructure. However, the greatest engineering challenge is understanding how these components interact.
A fabric can have healthy routing sessions while experiencing forwarding problems. It can have redundant paths while suffering congestion. It can have logical segmentation while permitting unintended communication through incorrect policy.
The objective is therefore not simply to build a connected fabric, but to build one whose behaviour can be predicted, observed and verified.
A Reliable Fabric Is Designed, Measured and Tested
Production data centre fabrics require coordinated architecture, routing, overlay networking, security, performance engineering and operational validation.
- Begin with application, capacity and resilience requirements.
- Use appropriate Clos topology designs for scalable connectivity.
- Validate underlay routing and ECMP forwarding.
- Ensure EVPN-VXLAN overlays have correct VTEP, VNI and VRF relationships.
- Design transport MTU for encapsulated traffic.
- Establish verified healthy-state operational baselines.
- Investigate failures by comparing control-plane, forwarding and application behaviour.
- Test performance and security under degraded network conditions.
- Use telemetry, CLI diagnostics and packet analysis to confirm actual forwarding behaviour.
- Treat operational validation as a continuous engineering discipline.
Fabric Design & Troubleshooting Capstone
You are the on-call data centre network engineer. A production application has reported connectivity problems. Investigate the fabric, inspect CLI evidence, identify the fault, apply a corrective action and validate recovery. Use the design capacity model to understand the impact of failures.
Engineering Mission
Investigate the production fabric incident. Use routing, overlay and interface evidence before selecting a corrective action.
Incident Investigation Controls
Packet Trace & Investigation Result
Healthy Baseline vs Incident State
Fabric Capacity Design Calculator
Reference leaf design: 48 server-facing ports at 25 Gbps and six uplinks at 100 Gbps each.
| Capacity Component | Healthy | Current |
|---|
This is a separate six-uplink capacity reference design. The two-spine diagram above is a simplified forwarding model; each illustrated spine connection represents a logical path rather than all six physical uplinks. A single failed 100 Gbps uplink changes the oversubscription ratio from 2:1 to 2.4:1.
Engineering CLI Console
Engineering Challenge Score
Current incident investigation score
Scoring: CLI investigation (20 points), correct diagnosis (30 points), correct repair (30 points), and successful post-repair validation (20 points). Scores reset when changing incidents. The model uses simplified, deterministic operational states rather than a full BGP, EVPN or packet-forwarding engine.
Take Your Fabric Knowledge Further
You have explored the architecture, routing, virtualization, performance and security of modern data centre fabrics. Now move from technical concepts to interactive engineering. Choose a workspace to investigate real-world networking and security scenarios.
Networking Explore Workspace →
Data Centre Network Workspace
Explore spine-leaf architecture, fabric forwarding, traffic paths, routing behaviour and practical network troubleshooting through interactive labs.
Launch Networking Workspace →Security Explore Workspace →
Data Centre Security Workspace
Investigate trust boundaries, segmentation, traffic policies, Zero Trust principles, security telemetry and incident recovery through interactive security scenarios.
Launch Security Workspace →