
AI Inference Infrastructure Architecture Explained
Model Serving, Inference Gateways, GPU Scheduling, KV Caching, Latency, Throughput, and Scaling. Explore the infrastructure that transforms an AI request into a generated response, from application gateways and model-serving runtimes to GPU execution, memory management, distributed inference, and production performance engineering.
Why AI Inference Infrastructure Matters
Artificial intelligence applications depend on more than trained models. Every production inference request requires an infrastructure system capable of accepting traffic, selecting an appropriate model deployment, scheduling execution, managing accelerator memory, and delivering generated tokens within acceptable performance limits.
A language model may contain billions of parameters, but model size alone does not determine the quality of the user experience. Infrastructure design influences how quickly the first token appears, how efficiently subsequent tokens are generated, how many requests can be processed concurrently, and how much compute capacity is required.
As enterprise AI applications grow, inference becomes a distributed systems engineering challenge. Engineers must coordinate request admission, routing, GPU scheduling, memory allocation, batching, networking, observability, and failure recovery.
Inside an AI Inference Request
Consider an enterprise application sending a prompt to a deployed large language model. The request passes through multiple logical infrastructure responsibilities before the application receives its generated response.
Client request
Request routing
Batch scheduling
Decode
Client delivery
The inference gateway can enforce admission controls and direct requests to suitable model-serving instances. The serving runtime manages execution queues, batching, and model-specific scheduling. GPU resources perform the computation required for prompt processing and autoregressive token generation.
During generation, the runtime maintains attention state in a key-value cache, commonly called the KV cache. This avoids recomputing previously generated attention keys and values at every decoding step, but introduces important GPU memory capacity and scheduling constraints.
Performance, Capacity, and Reliability
Production inference architectures must balance three connected engineering objectives. Optimizing one objective without considering the others can create unexpected performance or operational problems.
Latency Engineering
Reduce request queueing, time to first token, and inter-token delays. Understand how prompt length, batching, network paths, and GPU execution influence user-visible response time.
Throughput and Capacity
Improve aggregate token generation and request processing capacity through scheduling, batching, efficient memory use, and appropriately sized model-serving deployments.
Resilience and Scaling
Design healthy replicas, controlled admission, overload protection, autoscaling, observability, and recovery mechanisms for production inference services.
When Powerful GPUs Still Deliver Slow AI Responses
Imagine an enterprise deploying an AI assistant on a cluster of high-performance GPUs. Initial testing demonstrates acceptable response times, but performance deteriorates when hundreds of users begin submitting concurrent requests.
GPU utilization increases, request queues grow, time to first token becomes unpredictable, and users experience inconsistent token streaming. The organization considers purchasing additional accelerators, but the root cause has not yet been established.
Why Is the Inference Service Slowing Down?
Investigate the complete request path before assuming that additional GPU hardware is the correct solution.
This investigation demonstrates an important distinction: high GPU utilization does not automatically indicate efficient inference. A saturated accelerator may be processing useful work efficiently, or it may be operating within a poorly balanced serving architecture.
What You Will Learn
This guide progresses through nine connected engineering disciplines, beginning with the inference request architecture and finishing with production troubleshooting and optimization.
Inference Architecture
Trace requests across gateways, serving runtimes, GPU execution, and response delivery.
Model Serving Engines
Understand serving runtimes, execution scheduling, batching, and model deployments.
Inference Gateways
Explore request routing, admission control, load balancing, and backend selection.
GPU Scheduling
Investigate accelerator placement, GPU allocation, and resource contention.
Prefill and Decode
Understand prompt processing, token generation, and inference execution phases.
KV Cache Architecture
Examine attention-state caching, GPU memory pressure, and cache reuse.
Latency and Throughput
Analyze TTFT, TPOT, batching, concurrency, and system capacity trade-offs.
Distributed Scaling
Explore multi-GPU execution, model parallelism, networking, and scaling.
Production Troubleshooting
Diagnose inference failures and performance bottlenecks using operational telemetry.
AI inference infrastructure connects modern model-serving technology with traditional disciplines in networking, distributed systems, resource scheduling, performance engineering, and production operations. Understanding these relationships enables engineers to design AI platforms that are efficient, observable, scalable, and resilient.
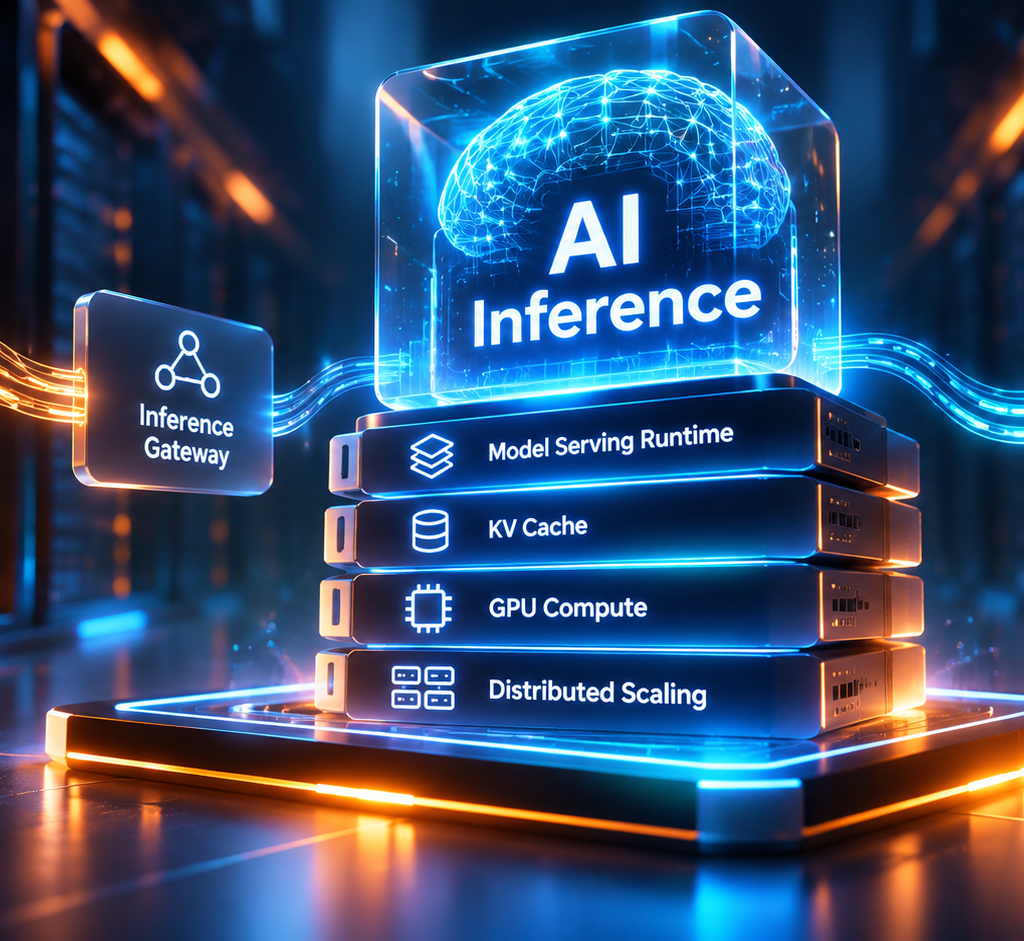
Explore the AI Inference Stack
Follow an inference request from its first arrival at the platform through model serving, GPU scheduling, token generation, distributed scaling and production troubleshooting. Select any architecture layer to explore it.
Understanding AI Inference Infrastructure Architecture
AI inference infrastructure is the collection of software services, computing resources, networking components, and operational controls required to execute trained AI models and deliver their outputs to applications and users.
A production inference platform must coordinate application requests, model selection, request routing, execution scheduling, GPU memory, model computation, response streaming, and infrastructure monitoring. Understanding these responsibilities is essential for designing reliable and scalable AI systems.
What Is AI Inference Infrastructure?
AI inference is the process of using a trained model to generate predictions, classifications, embeddings, or other outputs from new input data. For large language models, inference commonly involves processing an input prompt and generating a sequence of output tokens.
In a development environment, a model may execute directly on a workstation or a single accelerator. Production deployments introduce additional requirements: many concurrent users, predictable response times, controlled access, efficient accelerator utilization, high availability, and operational visibility.
These requirements transform inference from an isolated computation into a distributed application architecture. The platform must coordinate multiple components with different performance characteristics and operational responsibilities.
The Five Layers of AI Inference Infrastructure
A useful engineering model divides inference infrastructure into five logical layers. These layers describe responsibilities rather than five mandatory physical deployment tiers.
Each layer introduces different engineering considerations. Application engineers focus on API behavior and user requirements. Platform engineers design gateway and serving services. Infrastructure engineers manage accelerator placement, network connectivity, and capacity. Operations teams correlate telemetry across the complete system.
Inference Control Plane vs Data Plane
Production inference infrastructure contains management and configuration activities alongside the runtime processing of user requests. Separating these responsibilities helps engineers understand deployment, scaling, and troubleshooting.
Control Plane
Manages model deployment definitions, serving replica configuration, GPU resource allocation, scheduling policies, autoscaling decisions, and service discovery.
Data Plane
Processes live inference requests through gateways, serving runtimes, accelerator execution, and response delivery.
This distinction is useful but not absolute. A model-serving runtime may perform local scheduling decisions during live request execution, while Kubernetes and other orchestration systems manage infrastructure-level workload placement.
Following an Inference Request End to End
Consider an enterprise AI assistant receiving a user question. The application sends a request to a model endpoint, and the serving platform performs several coordinated operations.
During prefill, the model processes input tokens and produces attention state used during generation. During autoregressive decoding, the model repeatedly computes the next token using the available context and previously generated tokens.
Serving runtimes commonly maintain KV cache allocations to avoid recomputing previous attention keys and values during subsequent decoding steps. The amount of cache memory required grows with factors such as active sequence count, context length, model architecture, and cache precision.
In streaming deployments, the client can receive output tokens while the decode phase continues. Consequently, time to first token and the rate of subsequent token delivery are distinct performance measurements.
Key Components in a Production Inference Platform
A complete inference environment may combine dedicated serving software, container orchestration, GPU infrastructure, networking, storage, and operational services.
| Component | Primary Responsibility | Engineering Consideration |
|---|---|---|
| Inference Gateway | API admission, authentication and request routing | Queueing, backend selection and availability |
| Model Serving Runtime | Model execution and sequence scheduling | Batching efficiency and runtime overhead |
| GPU Accelerators | Parallel computation for model execution | Compute utilization and memory bandwidth |
| GPU Memory | Stores model weights, KV cache and execution buffers | Capacity limits and memory pressure |
| Kubernetes | Container placement and workload lifecycle | GPU scheduling, health and scaling |
| Network Fabric | Connects clients, services and distributed accelerators | Latency, bandwidth and communication overhead |
| Model Storage | Provides model artifacts and deployment assets | Startup time and model loading |
| Observability | Collects performance and operational telemetry | End-to-end bottleneck identification |
Not every deployment requires every component as a separate service. A small inference system may combine gateway and serving responsibilities, while a large platform may distribute these functions across multiple clusters and regions.
Single-GPU, Multi-GPU, and Distributed Inference
The appropriate inference deployment depends on model size, memory requirements, request concurrency, latency objectives, and operational constraints.
Single-GPU Inference
A model-serving runtime executes on one accelerator when model weights, KV cache, and execution memory fit within available capacity. This reduces inter-GPU communication requirements and deployment complexity.
Multi-GPU Model Execution
Large models may distribute computation across multiple GPUs using techniques such as tensor or pipeline parallelism. Communication and synchronization overhead become important performance factors.
Replicated Model Serving
Multiple model replicas can process separate requests concurrently. Gateways and load balancers distribute traffic according to health, capacity, and routing policies.
Distributed Inference Platform
Large deployments combine distributed model execution, replicated serving, specialized scheduling, and potentially separate prefill and decode resources.
Why Network Engineering Matters for AI Inference
Network performance influences inference at multiple boundaries. Client-to-gateway communication affects request delivery, gateway-to-backend connections affect service routing, and distributed model execution may depend on high-bandwidth accelerator communication.
For a single-GPU deployment, external API connectivity and response streaming may be the primary networking concerns. In distributed inference, communication between accelerators can become part of the model execution critical path.
Depending on the architecture, engineers may need to evaluate Ethernet or InfiniBand interconnects, RDMA capabilities, congestion management, GPU communication libraries, and the network topology connecting compute nodes.
Diagnosing an Inference Request Bottleneck
An enterprise deploys a model-serving platform with multiple GPU-backed replicas. During low traffic periods, requests complete within expected performance targets. Under heavier concurrency, users report long delays before the first generated token appears.
High Time to First Token Under Load
The investigation must determine whether the delay originates before the request reaches the serving runtime, while it waits for execution, or during prompt processing.
If requests spend most of their time waiting for runtime admission, queueing and effective concurrency deserve attention. If queueing remains low but prefill duration increases, engineers should investigate prompt characteristics, batching, compute behavior, and resource contention.
The investigation should use measurements rather than assume that the GPU or network is responsible. Distributed traces and serving metrics can help identify the actual source of latency.
Building a Production-Ready Inference Architecture
Strong inference infrastructure begins with explicit workload requirements. Engineers should establish expected prompt and output lengths, request rates, concurrency, model characteristics, latency objectives, and availability targets.
These requirements guide model placement, accelerator selection, serving runtime configuration, gateway policies, memory allocation, and scaling strategies. Capacity testing should reflect realistic workload distributions rather than relying exclusively on synthetic single-request benchmarks.
Production observability should expose gateway behavior, request queues, runtime scheduling, GPU utilization, KV cache pressure, prefill performance, decode performance, and client-visible response times.
AI inference infrastructure is a coordinated architecture spanning applications, gateways, model-serving runtimes, accelerators, memory systems, networking, and operations. Reliable production inference requires engineers to understand the complete request lifecycle and optimize the system as a whole rather than treating GPU performance as an isolated concern.
Inside a Production AI Inference Request
Follow a request across the inference gateway, serving runtime, GPU execution and memory system. Inspect each stage to understand how infrastructure decisions affect latency and response delivery.
Engineering Investigation
Illustrative Request Latency Breakdown
Infrastructure Event Trace
Follow the simulated request lifecycle and infrastructure decisions.
Model Serving Engines and Runtime Architecture
Model-serving engines provide the execution infrastructure that transforms incoming inference requests into model outputs. They coordinate model loading, request admission, batching, scheduling, accelerator execution, memory management, and response delivery.
Modern serving engines are designed to support large models, variable prompt lengths, concurrent users, and demanding latency requirements. Understanding their internal architecture is essential for optimizing GPU efficiency and building scalable AI inference platforms.
What Is a Model Serving Engine?
A model serving engine is software responsible for executing a trained model in response to application requests. For large language models, it commonly manages tokenization, request queues, sequence scheduling, model computation, attention-state caching, and generated output.
A basic inference implementation may load model weights into GPU memory and execute one request at a time. This can be useful for experimentation, but production systems frequently require many concurrent requests with different prompt lengths and generation requirements.
Serving engines improve operational efficiency by coordinating how requests share available compute and memory resources. Their scheduling strategies influence how much useful work accelerators perform and how long individual users wait for responses.
Inside a Production Model Serving Runtime
A serving runtime contains several cooperating components. Some operate before GPU execution, while others manage the execution and memory requirements of active sequences.
The scheduler determines which requests can execute within available resource limits. The memory manager tracks allocations required for model execution, particularly the KV cache used by transformer-based autoregressive models.
The model executor coordinates computation on available accelerators. Depending on the deployment, execution may occur on one GPU or across multiple devices using model parallelism and communication mechanisms.
vLLM, NVIDIA Triton, TGI, and SGLang
Several technologies are used to serve AI models in production. They differ in their supported model types, runtime architecture, scheduling capabilities, deployment integrations, and operational tooling.
| Technology | Primary Focus | Engineering Relevance |
|---|---|---|
| vLLM | High-throughput LLM inference and efficient KV cache management | Continuous batching, PagedAttention, serving APIs and distributed execution |
| NVIDIA Triton Inference Server | General-purpose inference serving across supported frameworks and backends | Model repositories, scheduling, dynamic batching and production deployment |
| Hugging Face TGI | Text generation model serving | Request batching, token streaming and operational deployment |
| SGLang | Efficient LLM and structured generation serving | Scheduling, prefix reuse, KV cache management and optimized execution |
These technologies are not always mutually exclusive. A serving platform may expose multiple model backends, and NVIDIA Triton can integrate with supported specialized execution backends.
Engineers should evaluate the actual model, hardware, software version, deployment pattern, and workload characteristics rather than assuming that one serving engine is optimal for every inference application.
Continuous Batching and Concurrent Inference
Traditional static batching groups requests into a batch and executes the batch according to a predefined processing boundary. For autoregressive language models, requests may generate different numbers of tokens and finish at different times.
Continuous batching allows a serving runtime to reconsider the active set of sequences at execution scheduling boundaries. Completed sequences can release resources, while waiting requests may be admitted as capacity becomes available.
Continuous batching can improve accelerator utilization and aggregate throughput, especially when requests have variable generation lengths. However, larger active batches also consume more memory and can influence latency.
Scheduling policies must balance throughput, fairness, waiting time, KV cache capacity, and the execution requirements of active requests.
From Model Deployment to GPU Execution
Before a serving runtime can process requests, the model must be made available, loaded, initialized, and prepared for execution. Startup behavior is especially important when deploying large models or scaling inference replicas.
Model loading can involve transferring large weight files from storage, preparing runtime structures, initializing accelerator memory, and establishing distributed execution relationships where required.
A newly created container is not necessarily ready to accept inference traffic. Readiness checks should reflect whether the serving runtime can successfully handle requests, not simply whether the process has started.
Model Weights, KV Cache, and Runtime Memory
GPU memory is a central constraint in large language model serving. A deployment must accommodate model weights, attention state, temporary computation buffers, and other runtime allocations.
Model weights consume memory according to model architecture, parameter count, numerical precision, and any quantization strategy. KV cache memory depends on active sequences, retained token context, model attention architecture, and cache precision.
Serving engines may use specialized allocation techniques to reduce fragmentation and improve the efficiency of KV cache management. For example, vLLM's PagedAttention approach organizes KV cache storage into blocks rather than requiring each sequence to occupy one contiguous allocation.
Understanding Serving Efficiency
Model serving performance should be measured using multiple metrics rather than a single GPU utilization percentage.
Time to First Token
Measures the delay before the client receives its first generated token. It can include network, queueing, prefill, and output delivery overhead.
Inter-Token Latency
Measures the time between generated output tokens. It helps characterize the responsiveness of streamed output.
Token Throughput
Measures token processing or generation capacity over time. Engineers should distinguish input-token throughput from output-token throughput.
Effective Concurrency
Describes how many requests or sequences the system can process while satisfying relevant latency and resource constraints.
These measurements should be correlated with request queue depth, prompt length, output length, GPU utilization, memory consumption, cache allocation, and scheduling behavior.
Why Does Model Serving Slow Down Under Concurrency?
A model-serving deployment performs well with individual test requests but experiences increasing latency when many users submit prompts simultaneously.
Inference Queue Growth and GPU Memory Pressure
Investigate whether the serving engine is limited by request admission, scheduling efficiency, available KV cache memory, or accelerator execution capacity.
If requests are waiting because KV cache capacity is exhausted, increasing admission limits may worsen performance rather than improve it. If memory capacity is available but GPU computation is saturated, a different batching or scaling strategy may be required.
Engineers should compare runtime metrics under representative workloads before changing scheduling policies or purchasing additional accelerator capacity.
Design Principles for Reliable Model Serving
Production serving platforms should begin with explicit model and workload requirements. These include model architecture, parameter size, supported precision, expected context lengths, output lengths, request concurrency, latency objectives, and availability needs.
Runtime selection should consider model compatibility, GPU hardware, scheduling features, deployment integration, monitoring support, and operational complexity.
Capacity testing should use realistic prompt and generation distributions. A benchmark using short prompts and uniform output lengths may not represent an enterprise workload containing long documents, agent requests, and variable generation patterns.
Model-serving engines are the execution foundation of production AI inference. Their scheduling, batching, memory management, and GPU execution strategies determine how efficiently models serve concurrent workloads. Understanding runtime architecture allows engineers to identify bottlenecks, plan capacity, and improve inference performance without treating additional hardware as the only scaling solution.
Model Serving Runtime & GPU Execution Scheduler
Investigate how inference requests enter a model-serving runtime, compete for execution capacity and progress through prefill and autoregressive decoding. Compare continuous batching with static batch execution.
Request Execution State
Requests change state as the scheduler admits and executes work.
GPU Scheduling Timeline
Each block represents one simulated GPU execution step.
Scheduler Event Log
Engineering Investigation
Inference Gateways and Request Routing
Inference gateways provide a controlled entry point between AI applications and model-serving infrastructure. They receive requests, enforce access and admission policies, select suitable model deployments, and direct traffic toward available inference backends.
As AI platforms scale, gateway architecture becomes increasingly important. Different models, accelerator pools, latency requirements, tenant policies, and backend capacities require more sophisticated routing than a simple round-robin load balancer.
What Is an AI Inference Gateway?
An AI inference gateway is a service or logical architectural layer that manages access to one or more inference endpoints. It can expose a consistent API while forwarding authorized requests to different model-serving backends.
In a small deployment, an application may connect directly to a model-serving endpoint. In a larger enterprise platform, multiple applications may share inference infrastructure containing different models, model versions, GPU pools, regions, and serving engines.
A gateway can centralize authentication, request validation, tenant policy enforcement, routing, rate limiting, and operational telemetry. Depending on the product and deployment design, it may also support token-aware quotas, model fallback, request transformation, and streaming response handling.
Inside a Production Inference Gateway
A production gateway connects incoming AI application traffic with available model-serving deployments. Its routing decisions may depend on model identity, request requirements, backend health, tenant permissions, and observed serving capacity.
Backend pools may contain multiple replicas of the same model or separate deployments optimized for different workloads. A gateway should distinguish these cases when applying routing policies.
The gateway must also maintain an accurate view of backend availability. A network connection being established does not necessarily mean that a model is loaded, ready, or capable of accepting more work.
How an Inference Gateway Processes Requests
Each incoming inference request passes through a sequence of logical checks before execution. The precise order and implementation depend on the gateway architecture.
An authenticated request may still be rejected if the tenant exceeds its quota, the requested model is unavailable, or no suitable backend has sufficient admission capacity.
Successful forwarding does not mean that GPU execution begins immediately. The serving runtime may place the request into its own scheduling queue.
Choosing the Correct Inference Backend
Traditional load balancers often distribute traffic based on transport connections, backend availability, or application-level routing rules. AI inference introduces additional requirements because backends may differ in model identity, context capacity, accelerator resources, and current serving workload.
| Routing Policy | Decision Basis | Engineering Consideration |
|---|---|---|
| Round Robin | Rotate among eligible replicas | Simple distribution but not inherently workload-aware |
| Least Connections | Choose a backend with fewer active connections | Connections may not reflect inference execution cost |
| Least Outstanding Requests | Consider active or pending requests | Request sizes and generation lengths may differ |
| Model-Aware Routing | Match model identity, version and capabilities | Prevents requests reaching incompatible deployments |
| Capacity-Aware Routing | Use supported load or capacity signals | Requires sufficiently fresh and meaningful telemetry |
| Region-Aware Routing | Consider location, policy and regional health | Latency, residency and failover constraints matter |
For example, two replicas may each have ten active requests, but one replica may be processing long-context prompts while the other handles short requests. Equal request counts do not imply equal computational load.
More sophisticated routing can consider model-specific performance metrics, waiting queues, estimated token demand, and available serving capacity where the platform exposes reliable signals.
Balancing Latency, Throughput, and GPU Capacity
Load balancing distributes inference requests across suitable serving replicas. The objective is not simply to equalize request counts, but to use available capacity while meeting latency, reliability, and policy requirements.
Availability First
Route only to eligible, healthy deployments. Exclude unavailable or unready backends before considering performance optimization.
Capacity Awareness
Use suitable runtime or gateway telemetry to avoid sending excessive work to overloaded model-serving replicas.
Policy Compliance
Respect model permissions, regional restrictions, tenant isolation, and workload-specific routing requirements.
GPU utilization can contribute to capacity analysis, but it is not sufficient by itself. A highly utilized GPU may be efficiently processing a batch, while another backend with lower utilization may still lack enough KV cache memory for new requests.
The gateway should avoid unstable routing decisions caused by rapidly changing metrics. Capacity-aware routing may require smoothing, admission limits, and mechanisms that prevent traffic oscillation between backend pools.
Protecting Shared Inference Infrastructure
AI inference workloads can consume very different amounts of compute and memory. A short classification request may require substantially fewer resources than a long-context document analysis request.
Production gateways can enforce policies that limit how much traffic applications or tenants submit to shared inference infrastructure.
Requests per Minute
Restrict request arrival rates for individual users, applications, or tenants. This protects against excessive API traffic but does not fully represent model workload.
Token-Based Quotas
Account for input or output token consumption where supported. Estimates may be needed before execution because final output length is not always known.
Concurrent Request Limits
Bound the number of in-flight requests to prevent unmanageable queues and protect shared serving capacity.
Priority and Tenant Policy
Differentiate workloads according to approved service levels while preventing starvation and uncontrolled resource competition.
Health Checks, Retries, Failover, and Token Streaming
Inference gateways must account for backend failures, unavailable models, connection errors, and overloaded serving instances.
A backend health check should reflect the readiness requirements of the serving deployment. A reachable process may still be loading model weights, initializing GPU execution, or unable to accept new requests.
Retry behavior requires particular care. Retrying a failed request may repeat expensive model computation. If a response has already started streaming, automatically switching to another backend may duplicate or alter generated output and break response continuity.
Safe retry policies should distinguish failures before request execution, failures after execution begins, and failures after output has been delivered to the client.
Why Is One Inference Backend Overloaded?
An enterprise operates three replicas of the same language model. The gateway reports that all replicas are healthy, yet users experience inconsistent response times during peak demand.
Operational telemetry reveals that one backend has a growing request queue while the other two have available serving capacity.
Uneven Request Distribution Across GPU Replicas
Determine whether the bottleneck originates in gateway routing, backend readiness, workload characteristics, or serving runtime capacity.
The investigation may reveal that connection-based load balancing does not reflect actual inference workload, or that a capacity signal is stale. Alternatively, the overloaded backend may be processing unusually long prompts despite receiving a similar number of requests.
Corrective action should be based on correlated gateway and runtime telemetry, not request counts alone.
Designing a Reliable Inference Gateway
A production gateway should establish clear requirements for identity, model access, request admission, backend selection, failure recovery, and observability.
Engineers should identify the models and versions that each application can access, define the eligible serving pools, and determine which capacity and health signals can safely influence routing.
Gateway metrics should include request arrival rates, routing decisions, admission rejections, backend errors, gateway latency, and the duration of active streaming responses.
Inference gateways are a critical component of production AI infrastructure. They connect applications to model-serving capacity while enforcing access, admission, routing, and reliability policies. Effective gateway architecture requires awareness of model compatibility, backend readiness, workload variability, and serving capacity. Gateway routing and runtime scheduling must be designed together to deliver predictable inference performance at scale.
Inference Gateway & Request Routing Lab
Route AI inference requests across GPU-serving backends. Compare routing strategies, investigate capacity constraints, inject infrastructure failures and observe HTTP responses.
Model inference API
Health · Capacity
GPU Serving Backend Pool
Inspect active requests, backend capacity and estimated service latency.
Gateway Routing Event Trace
Routing decisions and failures are recorded for each request.
Engineering Investigation
GPU Scheduling and Resource Allocation
GPU scheduling determines how accelerator resources are assigned to AI inference workloads. In production environments, this involves identifying suitable GPU nodes, allocating accelerator devices, managing workload placement, and coordinating resource availability across shared infrastructure.
GPU capacity is expensive and finite. Effective scheduling must balance model memory requirements, workload isolation, accelerator utilization, hardware compatibility, and service availability without introducing uncontrolled resource contention.
What Is GPU Scheduling?
GPU scheduling is the process of assigning accelerator resources to workloads that require GPU computation. For AI inference, these workloads commonly include model-serving containers, runtime processes, and distributed model execution services.
Unlike general-purpose CPU workloads, accelerator-based applications may require specific GPU architectures, memory capacities, driver versions, communication capabilities, and supported runtime environments.
A model-serving workload that requires substantial accelerator memory cannot necessarily run on any available GPU. Similarly, distributed inference workloads may need coordinated placement across multiple accelerators or nodes.
How Kubernetes Schedules GPU Workloads
Kubernetes provides a framework for scheduling containerized workloads across a cluster. GPU-capable nodes expose accelerator resources through supported device plugins or resource management integrations.
A GPU device plugin advertises available accelerator resources to Kubernetes. Workloads request supported GPU resource types, and the scheduler selects eligible nodes based on resource availability and scheduling constraints.
Kubernetes normally schedules a pod onto a node rather than selecting an individual physical GPU directly. The device plugin and node-level allocation process determine which eligible device resources are made available to the container.
The default scheduler does not inherently understand model weights, KV cache demand, or GPU memory fragmentation inside a model-serving runtime. These requirements may need additional scheduling policies, specialized orchestration, or application readiness checks.
GPU Discovery, Drivers, and Device Management
The NVIDIA GPU Operator helps automate the management of NVIDIA GPU software components in Kubernetes environments. Depending on configuration, it can manage GPU drivers, container toolkit integration, device plugins, monitoring components, and related operational services.
These components enable GPU-capable Kubernetes nodes to expose accelerator resources to compatible workloads. The device plugin reports supported GPU resource types, while monitoring integrations can provide accelerator telemetry for operations and capacity analysis.
GPU Drivers
Provide the software interface required for supported accelerator operation. Driver compatibility must align with hardware and runtime requirements.
Device Plugin
Advertises supported accelerator resources to Kubernetes and participates in allocation of devices to containers.
Container Toolkit
Enables compatible containers to access allocated GPU devices and the required accelerator software interfaces.
GPU Monitoring
Exposes accelerator telemetry such as utilization, memory usage, and hardware health where supported by the deployment.
The GPU Workload Scheduling Journey
When a new inference deployment is created, Kubernetes evaluates whether suitable nodes can satisfy the workload's resource requests and placement constraints.
Scheduling may fail when no node has sufficient advertised GPU resources, when node affinity requirements cannot be satisfied, or when other placement constraints eliminate eligible nodes.
A successfully scheduled pod may still fail during initialization if the model cannot allocate sufficient GPU memory, the runtime is incompatible with the device, or required model artifacts are unavailable.
Dedicated GPUs, MIG, and Time-Slicing
Different GPU allocation strategies support different combinations of isolation, utilization, and workload flexibility. The appropriate model depends on hardware capabilities, application requirements, and the platform's resource-sharing configuration.
Dedicated GPU Allocation
A workload receives access to an allocated GPU device without sharing it through an additional configured partitioning or time-slicing mechanism. This provides a straightforward allocation model for demanding workloads.
Multi-Instance GPU
On supported NVIDIA GPUs, MIG partitions an accelerator into hardware-isolated instances with defined compute and memory resources. Available profiles depend on the GPU generation.
GPU Time-Slicing
Multiple workloads can share execution time on a GPU through supported software configuration. Unlike MIG, time-slicing does not inherently provide dedicated GPU memory isolation.
| Allocation Model | Isolation | Typical Consideration |
|---|---|---|
| Dedicated GPU | Device allocation without configured partition sharing | Predictable allocation and straightforward capacity management |
| MIG | Hardware partitioning on supported GPUs | Instance profiles, partition capacity and workload fit |
| Time-Slicing | Shared execution and memory resources | Contention, fairness and limited isolation |
MIG is not available on every NVIDIA accelerator, and partition sizes are not arbitrary. Engineers must verify supported hardware, MIG profiles, device plugin configuration, and workload compatibility.
Why GPU Allocation Is Not the Same as Memory Capacity
GPU memory is consumed by several categories of data during model serving. A deployment must reserve sufficient capacity for model weights, attention state, execution buffers, and runtime overhead.
A model may fit into accelerator memory during startup but fail to sustain expected concurrency because KV cache allocations increase as active requests process longer contexts.
Kubernetes resource accounting generally tracks advertised GPU devices or configured GPU resource types rather than the exact amount of free model-serving memory inside each runtime.
Kubernetes Scheduling vs Inference Runtime Scheduling
GPU infrastructure involves at least two important scheduling responsibilities. Kubernetes determines where containerized workloads execute, while the model-serving runtime manages how incoming inference requests use the allocated accelerator resources.
Infrastructure Scheduling
Selects nodes for model-serving pods according to advertised resources, affinity, topology, taints, tolerations, and other scheduling constraints.
Runtime Scheduling
Manages admitted inference sequences, batching, prefill and decode work, KV cache availability, and execution priorities within allocated resources.
A pod can be correctly placed on a GPU node while the serving runtime experiences request queueing, memory pressure, or inefficient batching.
Conversely, a serving engine may be capable of efficient request execution but remain unavailable because Kubernetes cannot find an eligible node for its GPU resource request.
Why Is an Inference Pod Pending?
An enterprise deploys a new model-serving replica to handle increased inference traffic. Kubernetes creates the pod, but it remains in the Pending state.
The operations team initially assumes that the cluster has insufficient GPU capacity. However, several different scheduling constraints could explain the failure.
Model Serving Pod Cannot Be Scheduled
Diagnose GPU resource availability, node eligibility, and device plugin health before modifying the deployment.
Kubernetes pod events and scheduler diagnostics can identify unsatisfied resource requests or placement rules. If the pod subsequently starts but fails to load the model, the investigation should shift toward runtime compatibility, accelerator memory, and model initialization.
This separation prevents engineers from confusing a Kubernetes placement failure with an inference runtime capacity problem.
Designing Efficient GPU Resource Allocation
Production GPU scheduling begins with understanding the model's hardware requirements and the expected inference workload. Engineers should establish model memory demand, accelerator compatibility, deployment topology, concurrency objectives, and isolation requirements.
Dedicated allocation may be appropriate for large or latency-sensitive workloads, while supported GPU sharing approaches can improve utilization for smaller workloads when their isolation and contention trade-offs are acceptable.
GPU telemetry should be correlated with Kubernetes placement information and serving runtime metrics. Monitoring device utilization alone cannot reveal whether the cluster is efficiently placing workloads or whether individual serving engines are meeting their latency objectives.
GPU scheduling connects Kubernetes infrastructure management with the execution requirements of AI model-serving workloads. Successful production inference requires compatible hardware, accurate resource advertisement, suitable placement constraints, appropriate isolation, and sufficient GPU memory. Infrastructure-level scheduling and inference runtime scheduling must be understood separately, then monitored together to achieve efficient accelerator utilization and predictable service performance.
GPU Cluster Scheduling & Workload Placement
Allocate AI inference workloads across physical GPUs. Investigate memory requirements, multi-GPU placement, fragmentation, scheduling policies and infrastructure failures.
Inference Workload Queue
Workloads request one or two GPUs and reserve the specified amount of memory on each allocated GPU.
GPU Placement Decision Trace
Observe admission, placement failures and node health events.
Engineering Investigation
Prefill, Decode, and Token Generation Architecture
Large language model inference consists of two fundamental execution phases: prefill and decode. Prefill processes the input prompt and establishes attention state, while autoregressive decoding generates subsequent output tokens using the available context.
These phases place different demands on GPU computation, memory bandwidth, and serving infrastructure. Understanding their behavior is essential for diagnosing latency, optimizing token throughput, and designing efficient production inference systems.
How a Language Model Generates Tokens
A large language model processes text as tokens. Tokens are numerical identifiers representing units of text according to a tokenizer's vocabulary and encoding rules. They are not necessarily complete words.
During inference, a transformer model applies learned parameters to token representations through layers containing attention mechanisms and other neural network operations. The model produces scores for possible next tokens, which are converted into a probability distribution or otherwise processed by the configured decoding strategy.
A token is selected according to the generation configuration. The newly generated token becomes part of the context for the next decoding step. This process continues until a stopping condition is reached, such as an end-of-sequence token, a configured generation limit, or another supported termination rule.
The Prefill and Decode Pipeline
The inference pipeline begins when the serving runtime receives tokenized input and schedules model execution. The initial prompt-processing phase differs from subsequent token-generation operations.
During prefill, the model can process multiple prompt-token positions in parallel within supported attention and execution constraints. The model also creates key-value attention state for later generation.
During decoding, the model typically processes one new token position per active sequence at each generation step. Previously computed attention state is reused through the KV cache, avoiding repeated computation of historical keys and values.
Understanding the Prompt Processing Phase
Prefill processes the input context supplied to the model. This may include system instructions, conversation history, retrieved documents, user prompts, and other supported input representations.
Longer prompts generally require more computation and attention-state storage. The precise scaling behavior depends on model architecture, attention implementation, sequence length, and execution optimizations.
Prefill often exhibits substantial compute demand because multiple token positions can be processed together, enabling large matrix operations on accelerator hardware.
Prompt Length
Larger contexts increase the amount of input work and KV cache state that must be processed or retained.
Compute Utilization
Prompt processing can exploit parallel GPU computation, although efficiency depends on sequence shape, batching, and model design.
Attention Operations
Attention computation and memory access contribute to prefill cost. Optimized attention kernels can improve execution efficiency.
Prefix Reuse
Supported prefix caching techniques can avoid recomputing reusable prompt prefixes when cache entries remain valid and available.
Autoregressive Decoding and Token-by-Token Execution
After the initial prompt has been processed, the model continues generation through iterative decoding. Each step uses the current context and cached attention state to compute the next token.
For a single sequence, decode steps commonly involve relatively small amounts of new token computation compared with repeatedly accessing model weights and existing attention state. This can make decoding sensitive to memory bandwidth, especially at low batch sizes.
Continuous batching allows multiple active sequences to participate in execution scheduling, potentially improving the amount of useful computation performed per model weight access.
Visualizing Prefill, Decode, and Token Streaming
The following conceptual timeline illustrates the relationship between request waiting, prompt processing, output generation, and client-visible token delivery.
The time before the first output token reaches the client can include request routing, admission, queueing, prefill, and output transport overhead.
Once generation begins, token delivery speed depends on decode execution, runtime scheduling, and any additional transport or application overhead.
TTFT, TPOT, and End-to-End Response Time
Engineers use several complementary measurements to characterize inference responsiveness.
Time to First Token
TTFT measures the interval between the chosen request start point and the first generated token becoming available or reaching the client.
Specify whether measurement occurs at the client, gateway, or runtime.
Time per Output Token
TPOT commonly represents average generation time per subsequent output token after the first.
For N greater than one, using consistently defined token timestamps.
End-to-End Latency
Measures total time from request initiation until the response completes according to the measurement boundary.
Includes processing and delivery overhead within the chosen boundary.
TTFT is particularly important for interactive applications because it influences how quickly users perceive that the model has begun responding. TPOT helps characterize the subsequent pace of generated output.
Metrics must be interpreted alongside prompt lengths, output lengths, concurrency, request queues, and accelerator utilization.
Compute-Bound vs Memory-Bandwidth-Bound Inference
Different inference operations stress accelerator resources in different ways. Some workloads are constrained primarily by computational throughput, while others are limited by memory movement or communication overhead.
| Characteristic | Prefill | Decode |
|---|---|---|
| Primary Operation | Process prompt-token positions | Generate successive output tokens |
| Parallelism | Substantial parallel work across prompt positions | Sequential token dependency per sequence; parallelism across sequences |
| Typical Constraint | Often compute-intensive | Often memory-bandwidth-sensitive at low batch sizes |
| Memory Behavior | Builds attention KV state | Reads and extends existing KV state |
| Important Metric | Prefill duration and contribution to TTFT | TPOT, inter-token latency and output throughput |
| Optimization Focus | Efficient kernels, prompt management and prefix reuse | Batching, memory access and scheduling efficiency |
The distinction is useful for initial performance analysis, but actual bottlenecks depend on batch size, context length, model architecture, quantization, hardware, and execution implementation.
For distributed inference, accelerator communication can introduce additional latency and bandwidth constraints. The execution bottleneck may therefore shift between computation, memory access, and network communication.
Why Is the First Token Slow but Streaming Fast?
An enterprise AI assistant processes long document-analysis prompts. Users report that responses take several seconds to begin, but once the first token appears, subsequent output arrives at a consistent rate.
The investigation must distinguish request queueing from prefill execution and network delivery.
High TTFT with Acceptable Decode Performance
Diagnose where the delay occurs before changing GPU capacity or model-serving configuration.
If runtime queueing is low but prefill duration grows with prompt length, prompt processing is a likely contributor. If prefill completes quickly but the client receives its first token much later, gateway buffering or transport behavior deserves investigation.
Engineers should avoid assuming that slow first-token delivery necessarily indicates inefficient decoding. TTFT and TPOT measure different parts of the user experience.
Optimizing the Token Generation Pipeline
Production optimization begins with understanding the workload. Prompt length distributions, expected output lengths, concurrency, model architecture, and latency objectives determine which execution optimizations are most valuable.
Prefill optimization may involve reducing unnecessary context, using optimized attention kernels, improving batching, and reusing valid prompt prefixes.
Decode optimization may involve adjusting active batch sizes, improving KV cache management, selecting suitable precision, and balancing accelerator computation with memory bandwidth.
End-to-end measurements should distinguish gateway queueing, runtime waiting, prefill execution, decode execution, and response transport wherever instrumentation permits.
Prefill and decode are distinct phases of autoregressive language model inference. Prefill processes input context and establishes attention state, while decoding generates subsequent tokens through repeated model execution. Their different compute and memory characteristics explain why time to first token and token streaming performance can behave differently. Effective inference engineering requires measuring and optimizing both phases within the complete serving architecture.
Prefill, Decode & Autoregressive Token Generation
Explore how GPU inference transforms input context into generated tokens. Investigate the relationship between prompt length, prefill computation, decoding speed and user-visible latency.
Attention state creation
One token per sequence per step
Execution Progress
Ready to begin inference.
Generated Token Stream
Each block represents one synthetic output token emitted after the prefill phase.
GPU Execution Timeline
Blue represents prefill; teal represents decode iterations.
Inference Execution Trace
Inspect model execution events and simulated timing.
Engineering Investigation
KV Caching and GPU Memory Architecture
The key-value cache, commonly called the KV cache, stores attention state generated during transformer inference. By reusing previously computed attention keys and values, it reduces repeated computation during autoregressive token generation.
KV caching is fundamental to efficient large language model serving, but it also introduces significant GPU memory requirements. Cache allocation, block management, prefix reuse, and memory pressure directly influence the number of concurrent requests an inference platform can support.
What Is the KV Cache?
Transformer attention mechanisms operate on representations commonly described as queries, keys, and values. During autoregressive generation, a model repeatedly processes new token positions while attending to relevant previous context.
Without caching, previously computed attention keys and values would need to be regenerated during subsequent decoding steps. KV caching preserves this historical attention state, allowing the model to reuse it as new tokens are generated.
For a typical decoder-only transformer, cached keys and values are maintained across relevant attention layers. Each newly processed token adds attention state that may be needed by later decoding operations.
Where the KV Cache Fits in GPU Memory
A model-serving runtime uses accelerator memory for several purposes. Model weights occupy a substantial allocation, while active inference requests require KV cache storage and temporary execution buffers.
The balance between these memory categories depends on model size, numerical precision, architecture, runtime configuration, context length, and concurrency.
A model may successfully load into GPU memory but still have insufficient remaining capacity to support the intended number of concurrent inference sequences.
How KV Cache Memory Requirements Grow
For a conventional transformer attention cache, memory demand grows with the number of retained token positions, the number of cached attention layers, the number of key-value heads, the head dimension, and the precision used to store cached values.
For example, consider a hypothetical model with 32 attention layers, eight KV heads, a head dimension of 128, and two bytes per cached element.
Under these assumptions, the conventional KV cache requires approximately 128 KiB per retained token position. A sequence containing 4,096 cached token positions would therefore require approximately 512 MiB of KV storage before allocator overhead.
This calculation is illustrative rather than a universal model specification. Architectures using different attention mechanisms, cache compression, sliding windows, or other optimizations may have different memory requirements.
How Attention State Expands During Generation
During prefill, the runtime establishes attention state for the prompt. During decoding, each newly processed token position can extend the retained KV cache.
As multiple requests execute concurrently, the serving runtime must track cache allocations for many active sequences. Longer generation lengths increase the amount of state retained until completion or an applicable cache management operation.
Some architectures limit the retained attention window or use specialized cache structures. Consequently, cache growth is not identical across every model or serving implementation.
Block-Based KV Cache Allocation
A major challenge in KV cache management is allocating memory efficiently for sequences with different and unpredictable lengths.
PagedAttention, introduced with vLLM, uses a block-based approach to KV cache storage. Logical token blocks can map to physical memory blocks without requiring each sequence to occupy one continuous region of GPU memory.
Block allocation reduces the need for large contiguous KV cache regions and can reduce memory waste associated with conventional allocation strategies. It also supports efficient management of cache blocks across sequences.
However, block-based allocation does not eliminate all overhead. Partially filled blocks, allocation metadata, cache retention policies, and runtime implementation details still influence effective memory utilization.
Reusing Attention State Across Requests
Many inference applications repeatedly submit prompts containing the same initial context. Examples include shared system instructions, common document prefixes, and repeated application templates.
Prefix caching allows a compatible serving runtime to reuse previously computed KV cache state for an eligible matching prompt prefix. This can reduce repeated prefill computation.
Cache reuse requires correctness. Model identity, tokenized prefix, cache configuration, and other relevant execution conditions must be compatible.
Prefix caching also introduces operational considerations involving cache retention, memory pressure, tenant isolation, and potential information leakage through shared caching behavior.
Cache Eviction, Preemption, and Fragmentation
A serving runtime has finite KV cache capacity. When active requests require more cache storage than available, the runtime must apply its configured resource management and scheduling policies.
| Mechanism | Purpose | Engineering Trade-Off |
|---|---|---|
| Cache Eviction | Release eligible retained cache entries | May reduce future prefix-cache hit rates |
| Request Preemption | Free capacity by interrupting or suspending scheduled work | Can introduce recomputation or additional latency |
| Block Allocation | Manage KV storage in smaller allocation units | Requires metadata and may leave partially used blocks |
| Admission Limits | Restrict active sequences to available capacity | Protects memory but can increase waiting queues |
| Cache Quantization | Reduce bytes used per cached element where supported | Requires compatibility and accuracy validation |
| Prefix Reuse | Avoid recomputing valid cached prompt prefixes | Consumes retained cache capacity and needs correct matching |
Different serving runtimes implement memory management differently. Some may recompute preempted sequences, while others support additional mechanisms such as offloading or alternative cache placement.
Engineers should examine the actual runtime's cache allocation metrics, preemption counters, request waiting times, and memory configuration rather than assuming every engine uses the same recovery strategy.
Why Does Inference Concurrency Collapse?
An enterprise deploys a language model that performs well with short prompts and a small number of users. As more users submit long-context requests, the serving platform experiences increasing queueing and unpredictable response times.
GPU utilization remains high, but the number of active inference sequences stops increasing. The investigation focuses on KV cache capacity and runtime memory behavior.
GPU Memory Pressure Limits Active Inference Requests
Determine whether KV cache exhaustion, cache allocation overhead, or preemption is restricting effective concurrency.
If long contexts consume most available KV cache blocks, additional requests may remain queued even when the GPU could otherwise perform more computation.
Corrective actions might include reducing unnecessary context, adjusting concurrency limits, enabling compatible cache optimizations, or increasing available memory capacity.
Changes should be validated against representative workloads because increasing concurrency can also worsen per-request latency or introduce new resource contention.
Designing Efficient KV Cache Management
Production KV cache engineering begins with understanding model architecture and workload characteristics. Relevant factors include attention configuration, context length, generation length, concurrency, cache precision, and runtime allocation strategy.
Engineers should measure cache utilization alongside active sequences, waiting requests, preemption activity, TTFT, TPOT, and aggregate token throughput.
Prefix caching and block-based allocation can improve efficiency when supported and configured appropriately. However, these techniques do not eliminate the underlying physical memory capacity constraint.
KV caching is essential for efficient autoregressive transformer inference. It allows serving runtimes to reuse attention state during token generation, but introduces memory requirements that grow with retained context and active workloads. Block-based allocation, prefix reuse, admission control, and memory-aware scheduling help manage this capacity. Effective inference engineering requires treating GPU memory as a first-class resource alongside compute throughput and network performance.
KV Cache Allocation & GPU Memory Pressure
Investigate how an inference engine allocates attention memory, shares cached prompt prefixes and evicts reusable blocks when GPU memory becomes constrained.
GPU Memory Allocation Map
0 / 48 GiBLogical KV Block Pool
Each square represents a sample of the logical KV block pool. Blue blocks are referenced by active requests; teal blocks are retained for potential prefix reuse.
Active Inference Sequences
Inspect each request's token allocation, shared-prefix references and cache ownership.
GPU Memory Event Trace
Follow KV allocations, cache reuse, eviction and allocation failures.
Engineering Investigation
Inference Latency and Throughput Engineering
Production AI inference performance is governed by the relationship between request arrival rates, available serving capacity, batching efficiency, concurrency, and response latency.
Increasing throughput can improve accelerator utilization, but it may also increase queueing, memory pressure, and tail latency. Engineering an effective inference platform requires balancing aggregate capacity with predictable performance for individual requests.
Latency and Throughput Are Different Objectives
Latency measures how long an inference request takes to produce a response or reach a specified processing milestone. Throughput measures the amount of useful work completed per unit of time.
An inference platform may deliver low latency for a single request but relatively low aggregate throughput. Another configuration may achieve higher token throughput by processing many requests concurrently, while individual requests experience longer waiting or generation times.
The appropriate balance depends on the application. Interactive AI assistants prioritize responsiveness, while asynchronous batch-processing systems may prioritize aggregate completion capacity and cost efficiency.
Request Latency
Time required to complete an inference request, measured at a defined boundary such as the client or serving runtime.
Token Throughput
Number of input or output tokens processed per second. These should be reported separately when possible.
Concurrency
Number of requests or sequences active within the inference system at a given time.
Tail Latency
High-percentile response times, such as p95 and p99, that reveal delays affecting slower requests.
Where Inference Latency Accumulates
End-to-end inference latency is influenced by multiple components. Network transport, gateway admission, runtime queueing, model execution, and response delivery can each contribute to observed delay.
An engineering investigation should identify which component dominates the measured latency rather than treating the entire response time as a GPU execution problem.
For example, a request may experience high time to first token because it waits in a runtime queue, even when the actual prefill execution is fast.
Breaking Down a Response Time Budget
Latency budgets allocate an expected amount of time to individual processing stages. They help engineers identify whether performance problems originate in request transport, queueing, computation, or delivery.
In this example, queueing and prefill account for most of the first-token latency. Reducing a small gateway processing delay would have limited impact compared with addressing the dominant stages.
Concurrency, Arrival Rates, and Little's Law
Queueing theory provides a useful framework for understanding how requests move through inference infrastructure.
Little's Law relates average concurrency, average throughput, and average time spent in a system under stable, appropriately defined conditions.
λ = average completed requests per second
W = average time spent in the system
For example, if an inference service completes 20 requests per second and each request spends an average of two seconds in the system, average in-system concurrency is approximately 40 requests.
Little's Law does not itself predict the maximum throughput of a GPU. It describes the relationship between work in progress, completion rate, and response time.
When arrival rates approach sustainable serving capacity, queueing delay can grow rapidly. If incoming work persistently exceeds completion capacity, queues cannot remain stable without admission control, load shedding, or additional capacity.
Why More Concurrency Eventually Stops Helping
Increasing concurrency may initially improve GPU utilization because the serving runtime can form more efficient execution batches.
However, additional active sequences also consume KV cache memory, scheduling capacity, and accelerator execution resources.
Beyond an efficient operating region, additional concurrency may increase request waiting time without producing proportional throughput gains.
The appropriate concurrency limit should be established through load testing against latency objectives, not by maximizing GPU utilization alone.
Understanding p95 and p99 Response Times
Average latency can conceal poor performance affecting a subset of requests. Percentile metrics provide additional visibility into the distribution of response times.
p50 Latency
The median response time. Approximately half of measured requests complete at or below this value.
p95 Latency
Approximately 95% of measured requests complete at or below this value, using the chosen percentile calculation.
p99 Latency
Highlights the slowest portion of the workload and helps expose queueing, contention, and unusual execution delays.
Inference latency distributions are strongly influenced by prompt length, output length, workload concurrency, and runtime behavior.
Engineers should avoid comparing percentiles across workloads with substantially different request characteristics without accounting for those differences.
Defining Service-Level Objectives for Inference
Service-level objectives establish measurable performance and reliability expectations for an inference service. They should reflect the actual application experience and business requirements.
| Metric | What It Measures | Engineering Application |
|---|---|---|
| TTFT | Delay before first output token | Interactive responsiveness |
| TPOT | Average time per subsequent output token | Streaming generation performance |
| End-to-End Latency | Time until request completion | Full response experience |
| Output Tokens/sec | Aggregate generated token throughput | Serving capacity and efficiency |
| Successful Request Rate | Fraction of eligible requests completing successfully | Service reliability |
| Queue Waiting Time | Time awaiting runtime admission or execution | Capacity and scheduling analysis |
| p95 / p99 Latency | High-percentile response times | Tail latency and overload detection |
An example interactive-service SLO might specify that 95% of eligible requests receive their first token within a defined threshold. The actual threshold should be established from application needs, not assumed to be universal.
SLO definitions should specify request eligibility, measurement boundaries, observation windows, and treatment of errors and timeouts.
Why Does Throughput Increase While Latency Gets Worse?
An inference platform increases the maximum number of concurrent requests to improve accelerator utilization. Aggregate output throughput initially rises, but users begin reporting slower response times.
Monitoring shows that request queues are growing and p99 latency has increased sharply.
High GPU Utilization with Degrading Tail Latency
Investigate whether the platform has exceeded its efficient operating region or encountered additional memory and scheduling contention.
If throughput has approached saturation while queues continue to grow, increasing concurrency further is unlikely to resolve the underlying capacity problem.
Corrective action may involve reducing admission limits, improving workload distribution, optimizing batching, or adding suitable serving capacity. The chosen response should be validated against the relevant latency and throughput objectives.
Finding the Efficient Inference Operating Point
Production performance optimization should use representative workloads rather than relying exclusively on synthetic peak-throughput benchmarks.
Load tests should include realistic distributions of prompt lengths, output lengths, request arrival patterns, and concurrent users. Engineers should measure both steady-state performance and behavior during bursts.
The optimal operating point is often a region where the platform provides strong throughput while maintaining acceptable tail latency, memory headroom, and reliability.
Runtime configuration, batching limits, admission control, model placement, and replica capacity should be tuned together rather than optimized independently.
Inference latency and throughput are closely related but competing performance objectives. Increasing concurrency can improve accelerator efficiency until execution, memory, or scheduling capacity becomes constrained. Beyond that point, queueing and tail latency can increase sharply. Effective inference engineering requires workload-aware testing, meaningful SLOs, careful admission control, and a balanced approach to GPU utilization and user experience.
Inference Latency, Throughput & Capacity Engineering
Run synthetic inference load tests to investigate queueing delay, GPU worker capacity, concurrency, throughput saturation and production latency SLOs.
Request Throughput
Completed requests per second versus incoming traffic.
Time to First Token
Average observed TTFT compared with the configured SLO.
Active and Waiting Request Pool
Blue blocks represent active inference requests. Amber blocks represent queued requests. The display samples up to 100 requests.
Performance Investigation
Run a load test to observe system performance.
Capacity Planning Principle
Throughput increases with load until available compute capacity becomes saturated. Beyond saturation, queueing delay can grow even when completed throughput remains nearly constant.Load Test Event Trace
Distributed Inference and Infrastructure Scaling
Distributed inference uses multiple accelerators, model replicas, or serving nodes to execute AI workloads that exceed the capacity or performance limits of a single GPU.
Scaling inference infrastructure introduces new architectural decisions involving model partitioning, workload distribution, accelerator communication, replica placement, and fault tolerance. The correct approach depends on model size, latency requirements, throughput objectives, and the available compute and network infrastructure.
Why Inference Requires Multiple GPUs
A single GPU has finite memory capacity, computational throughput, and memory bandwidth. Large models may exceed the memory available on one accelerator, while heavily used services may require more aggregate throughput than one device can provide.
Distributed inference addresses these constraints through several approaches. A model can be partitioned across accelerators, independent replicas can serve separate requests, or specialized execution stages can operate on different GPU groups.
These approaches solve different problems. Partitioning helps execute models that require multiple devices, while replication increases the number of requests that can be served independently.
Model Capacity
Distribute model parameters and execution state when a model cannot fit within one accelerator.
Aggregate Throughput
Add serving replicas to process more independent requests when demand exceeds existing capacity.
Execution Efficiency
Use compatible parallel execution techniques to distribute computation across multiple accelerators.
Service Availability
Deploy independent replicas and suitable failure-domain placement to reduce the impact of individual serving failures.
From Inference Gateway to Distributed GPU Execution
A distributed inference deployment typically includes request-routing infrastructure, model-serving processes, accelerator resources, and communication mechanisms connecting participating devices.
In a partitioned model deployment, participating GPUs may exchange intermediate tensors or activations during execution.
In a replicated deployment, each replica can process its own requests without requiring cross-replica communication for every token.
Tensor, Pipeline, Data, and Expert Parallelism
Distributed model-serving systems use different parallelism techniques to divide work across accelerators. Each technique introduces distinct communication patterns and performance trade-offs.
| Strategy | How It Works | Primary Consideration |
|---|---|---|
| Tensor Parallelism | Partitions supported tensor operations or model weights across GPUs | Frequent synchronization and collective communication |
| Pipeline Parallelism | Places different groups of model layers on different devices | Stage balance, activation transfer and pipeline utilization |
| Data Parallelism / Replication | Runs independent model replicas serving different requests | Aggregate capacity, memory duplication and request distribution |
| Expert Parallelism | Distributes experts in compatible mixture-of-experts models | Token dispatch, all-to-all traffic and expert load balance |
Tensor parallelism is commonly used when a model or execution configuration benefits from dividing operations across GPUs. Collective communication can become important because participating devices must exchange intermediate results.
Pipeline parallelism distributes model layers across stages. Its effectiveness depends on workload scheduling, pipeline depth, and the balance of computation across stages.
Data parallelism in inference commonly means serving independent requests through separate model replicas. Unlike data-parallel training, these replicas generally do not require gradient synchronization.
Expert parallelism applies to compatible mixture-of-experts architectures, where tokens may be routed to different expert networks during execution.
NVLink, NVSwitch, InfiniBand, and RoCEv2
Distributed inference performance depends not only on accelerator computation but also on how efficiently participating devices exchange data.
Within supported GPU systems, NVLink provides high-bandwidth accelerator interconnect capabilities. NVSwitch can provide switching connectivity between supported GPUs within compatible system architectures.
Across nodes, distributed inference may use high-performance network fabrics such as InfiniBand or Ethernet deployments supporting RDMA over Converged Ethernet (RoCEv2).
Intra-Node Communication
GPU-to-GPU transfers within a server may use supported accelerator interconnects or PCIe paths.
Inter-Node Communication
Network fabrics carry distributed execution traffic between servers. Latency and effective bandwidth affect performance.
Collective Operations
Operations such as all-reduce and all-gather exchange or combine data among participating workers.
Topology Awareness
Placement decisions should consider communication locality and the available hardware topology.
Following a Request Through Multiple GPUs
The following sequence illustrates a model-serving deployment in which a request is executed by a coordinated multi-GPU model instance.
In tensor-parallel execution, participating devices may exchange partial computation results repeatedly during model execution.
In pipeline-parallel execution, intermediate activations move between model stages according to the runtime's scheduling and execution design.
These patterns differ from independent replicas, where each request is normally assigned to one replica without requiring all replicas to participate.
Vertical Scaling, Horizontal Scaling, and Model Partitioning
Inference capacity can be expanded through several infrastructure approaches. The most suitable method depends on whether the dominant limitation is memory capacity, request throughput, or communication.
Vertical Scaling
Use more capable accelerator resources or a larger GPU configuration for an individual serving instance. This may improve memory capacity or execution performance.
Horizontal Scaling
Add independent model-serving replicas and distribute incoming requests among them. This is useful for increasing aggregate serving capacity.
Model Partitioning
Split a model across multiple accelerators when memory or execution requirements justify coordinated distributed processing.
Adding replicas can increase aggregate throughput when sufficient infrastructure and request demand exist. However, each replica typically requires its own model weight allocation and serving resources.
Model partitioning can enable larger models or different execution characteristics, but it introduces communication and synchronization overhead.
Why Adding GPUs Does Not Guarantee Linear Performance
Ideal scaling would increase useful throughput proportionally to the number of added accelerators. Real systems experience overhead from communication, synchronization, scheduling, and resource imbalance.
This measure must be interpreted carefully. A model that cannot execute on fewer GPUs may not have a meaningful single-GPU performance baseline.
For independent replicas, scaling is often evaluated through aggregate request or token throughput at a specified latency target.
For model-parallel execution, engineers may evaluate per-request latency, output throughput, communication overhead, and accelerator utilization.
Why Does an Eight-GPU Model Perform Worse Than Expected?
An enterprise deploys a large model across eight GPUs on two servers. The model loads successfully, but output token generation is slower than anticipated.
GPU utilization is uneven, and distributed execution traces reveal periods when some workers wait for communication or slower participants.
Multi-GPU Inference Limited by Communication Overhead
Investigate whether the chosen parallelism configuration, worker placement, or network communication is restricting effective model execution.
If collective communication consumes a large fraction of decode execution time, increasing GPU count may provide limited improvement.
Engineers may investigate alternative tensor-parallel group sizes, more local placement, different partitioning strategies, or infrastructure changes.
Corrective actions should be supported by profiling and benchmark comparisons. Not every slow distributed deployment is caused by the network; model kernels, memory behavior, and runtime scheduling can also dominate.
Designing Scalable Distributed Inference Infrastructure
Production distributed inference architecture should begin with a clear understanding of model requirements, expected traffic, and service-level objectives.
Models that fit comfortably on a single GPU may benefit from independent replication rather than unnecessary cross-device partitioning. Larger models may require coordinated multi-GPU execution.
Infrastructure design should account for accelerator memory capacity, interconnect topology, network performance, runtime compatibility, placement policies, and failure-domain isolation.
Monitoring should correlate GPU utilization, runtime queueing, token throughput, communication overhead, and end-to-end latency. This provides a more complete picture than accelerator utilization alone.
Distributed inference enables AI platforms to serve larger models and greater request volumes by using multiple accelerators and serving instances. Tensor, pipeline, data, and expert parallelism introduce different execution and communication requirements. Efficient scaling depends on selecting the appropriate strategy, understanding accelerator interconnects, minimizing unnecessary communication, and measuring performance against realistic latency and throughput goals.
Distributed Inference & Multi-GPU Scaling
Explore tensor parallelism, pipeline parallelism, GPU communication overhead and scaling efficiency across different accelerator interconnect architectures.
Distributed Model Execution Topology
GPU partitions and communication relationships.
Execution Cost Breakdown
Illustrative computation and distributed communication contributions.
Scaling Comparison
Distributed Execution Trace
Inspect model partitioning and communication decisions.
Engineering Investigation
Production Inference Troubleshooting and Optimization
Production AI inference troubleshooting requires visibility across the complete request path: client applications, inference gateways, model-serving runtimes, GPU execution, memory allocation, and distributed communication infrastructure.
A slow or failed inference request may originate from queueing, GPU memory pressure, inefficient model execution, network congestion, overloaded gateways, or several interacting conditions. Reliable diagnosis depends on correlating telemetry across these layers rather than treating each component independently.
Building End-to-End Visibility into Inference
Observability provides the information engineers need to understand the internal behavior of a production inference platform.
A useful architecture combines application metrics, request traces, structured logs, model-serving telemetry, GPU metrics, and infrastructure monitoring.
Correlation identifiers allow engineers to follow a request across application, gateway, and serving components. Distributed traces can expose timing boundaries between instrumented operations.
GPU telemetry provides complementary resource-level information but does not automatically identify which individual request caused a particular device condition.
What Engineers Should Monitor
A production inference platform should expose measurements that distinguish request demand, serving execution, memory pressure, and infrastructure health.
| Layer | Important Metrics | Diagnostic Purpose |
|---|---|---|
| Application | Success rate, end-to-end latency, client TTFT | Understand user-visible reliability and responsiveness |
| Gateway | Request rate, 429/5xx responses, routing, retries | Identify admission, routing and upstream failures |
| Runtime | Queue waiting time, running requests, prefill and decode timing | Analyze scheduling and execution bottlenecks |
| KV Cache | Cache utilization, available blocks, preemptions, prefix-cache hits | Detect attention-state memory pressure |
| GPU | Memory use, compute activity, power, temperature, device errors | Identify accelerator constraints or faults |
| Network | Throughput, errors, drops, latency and collective-operation timing | Investigate transport and distributed execution delays |
Metrics should be segmented where practical by model, deployment, request type, prompt length, and output length.
This prevents workloads with different execution characteristics from being combined into misleading aggregate measurements.
Following a Request Across the Inference Stack
Distributed tracing helps engineers understand how an individual inference request progresses through instrumented services.
A trace may contain spans for request reception, authentication, gateway routing, runtime admission, queue waiting, model execution, and response delivery.
Trace data becomes especially valuable when combined with timestamps from runtime metrics and GPU telemetry.
Engineers should account for clock synchronization, sampling decisions, and instrumentation overhead. Not every GPU kernel or distributed collective will appear as a span in an application trace.
Separating Queueing, Prefill, Decode, and Delivery Delays
A slow inference response does not identify its own bottleneck. Engineers must separate the time spent waiting for resources from time spent executing model operations.
High TTFT
Investigate gateway routing, admission delay, runtime queueing, prompt length, prefill duration, and first-token buffering.
High TPOT
Investigate decode scheduling, batch size, KV cache behavior, memory bandwidth, and distributed communication.
High Tail Latency
Examine burst traffic, long-running requests, queue growth, uneven replica load, retries, and resource contention.
The diagnostic process should begin with the metric that violates the relevant service-level objective.
Comparing healthy and degraded request traces can reveal which processing stage changed during an incident.
Common Production Inference Failure Patterns
Inference incidents can originate in different parts of the platform. Symptoms may overlap, so engineers should confirm suspected causes using correlated evidence.
| Symptom | Possible Cause | Initial Investigation |
|---|---|---|
| High TTFT | Runtime queueing, long prefill, gateway delay | Compare queue time, prefill duration and client timing |
| Slow Token Streaming | Decode contention, memory bandwidth, communication | Inspect TPOT, active batches and GPU execution |
| Out-of-Memory Errors | Insufficient memory for weights, KV cache or runtime buffers | Review allocation failures, memory use and workload shape |
| HTTP 429 | Rate limits, quotas or admission policies | Inspect gateway policy and request demand |
| HTTP 503 | Unavailable backend, overload or service failure | Check backend health, capacity and upstream logs |
| Uneven Replica Performance | Load imbalance, model differences or unhealthy workers | Compare routing decisions and per-replica telemetry |
| Multi-GPU Slowdown | Collective overhead, placement or worker imbalance | Profile distributed execution and communication |
Diagnosing Accelerator Resource Constraints
GPU resource monitoring should include more than overall utilization. Memory capacity, memory bandwidth, compute activity, device health, and execution timelines provide different forms of evidence.
GPU Memory Capacity
Determine whether model weights, KV cache, and execution buffers fit within available memory.
Memory Bandwidth
Investigate memory-sensitive decode operations and inefficient data movement.
Execution Efficiency
Compare active batches, GPU execution time, kernel behavior, and scheduling gaps.
Distributed Communication
Identify communication overhead, worker imbalance, and synchronization delays in multi-GPU deployments.
A GPU can report high utilization while still delivering poor inference performance. The workload may be constrained by memory access, inefficient batching, or communication rather than a lack of arithmetic activity.
Likewise, low GPU utilization may indicate insufficient request demand, excessive queueing outside the runtime, CPU-side bottlenecks, or stalled distributed workers.
Connecting Symptoms Across Infrastructure Layers
Production incidents frequently involve multiple interacting conditions. An increase in request demand can affect queueing, KV cache utilization, scheduling, and gateway behavior simultaneously.
Engineers should construct an incident timeline using deployment changes, traffic patterns, service metrics, and infrastructure events.
This sequence is illustrative. Actual incidents may follow different paths, and the presence of correlated events does not by itself prove causation.
The investigation should test hypotheses using available telemetry and controlled comparisons.
Investigating a Degraded Enterprise Inference Service
An enterprise AI platform serves interactive assistants and document-analysis workloads through a shared model-serving environment.
Following an increase in long-context requests, users report slower first-token delivery, intermittent timeouts, and inconsistent response performance.
Inference Latency Degradation Across Multiple Layers
Initial evidence shows growing runtime queues, high KV cache occupancy, and increasing gateway timeout responses. The engineering objective is to identify the primary constraint and restore stable service.
The evidence may indicate that long-context requests consume a larger share of available KV cache capacity, reducing the number of requests that can execute concurrently.
Queueing then increases first-token latency. Gateway timeouts may follow when requests exceed configured response deadlines.
Potential mitigations include workload isolation, admission control, context management, improved replica placement, or additional serving capacity. The appropriate action depends on confirmed root cause and operational constraints.
A Structured Production Inference Investigation
Reliable troubleshooting follows a repeatable methodology that moves from user-visible symptoms to component-level evidence and validated corrective action.
Recovery should be verified across the affected workload, not only through a small number of successful test requests.
Following restoration, engineers should document the root cause, contributing conditions, mitigation effectiveness, and opportunities to improve monitoring or capacity planning.
Production inference reliability depends on end-to-end visibility across gateways, serving runtimes, GPU execution, KV cache management, and distributed infrastructure. Effective troubleshooting combines request tracing, performance metrics, infrastructure telemetry, and disciplined incident analysis. By identifying the actual bottleneck before applying changes, engineers can improve latency, throughput, availability, and operational efficiency without introducing unnecessary complexity.
Production AI Inference Incident Investigation
Investigate production inference failures using telemetry, diagnostic commands, root-cause analysis and remediation verification.
Infrastructure Telemetry
Compare observed measurements with the healthy baseline.
Diagnostic CLI Console
Run read-only diagnostic commands against the simulated inference infrastructure.
Root-Cause Diagnosis & Remediation
Select the suspected root cause and a remediation. Apply the change, then verify whether service health improves.
Incident Timeline
Investigation Scorecard
Inspect telemetry, identify the root cause and verify remediation.

- Azure Machine Learning Architecture Explained - November 15, 2026
- Azure GPU Infrastructure and AI Compute Explained - November 15, 2026
- Azure AI RAG Architecture Explained - November 15, 2026