Network Insight · Routing & Forwarding
Optimal Layer 3 Forwarding
How does a router decide where a packet should go next? Optimal Layer 3 forwarding brings together routing information, next-hop selection and hardware-assisted packet forwarding to move traffic efficiently across an IP network.
Every packet travelling beyond its local IP subnet depends on a sequence of forwarding decisions. A router examines the destination IP address, consults its forwarding information and identifies the appropriate next hop and outgoing interface. Repeating this process across the network allows packets to reach remote destinations.
The challenge is not simply finding a route. Networks must select suitable paths, resolve next-hop addresses, use available link capacity and respond to failures without creating unnecessary complexity. Routing protocols such as OSPF, EIGRP and BGP contribute routing information, while the router's forwarding plane applies the installed forwarding state to individual packets.
These decisions become especially important in data centres, enterprise networks and cloud environments, where multiple paths, redundant links, traffic policies and large routing tables influence how traffic moves. Technologies such as Cisco Express Forwarding (CEF), Equal-Cost Multipath (ECMP), policy-based routing and BGP multipath address different parts of this challenge.
The engineering principle
The best routing choice and the actual packet-forwarding action are related but distinct. Routing protocols determine eligible routes and best paths; the forwarding plane uses the installed forwarding table to send packets. Effective optimisation must consider reachability, policy, path cost, resilience and the capabilities of the network platform.
Your learning roadmap
Explore the Article
Navigate through the fundamentals, routing decisions, forwarding technologies and engineering practices behind optimal Layer 3 forwarding.
Section 01 · Forwarding Fundamentals
How Layer 3 Forwarding Works
Layer 3 forwarding is the process of moving IP packets towards their destination across one or more networks. Each router makes a local forwarding decision using the packet's destination IP address and the forwarding information installed on that device.
When a packet arrives at a router, the router processes its Layer 2 frame, examines the IP header and identifies the destination address. It then looks up that address in its forwarding information base (FIB). The result identifies the applicable next hop, outgoing interface or other forwarding action.
The packet's destination IP address normally remains unchanged as it travels through ordinary routed networks. The Layer 2 header, however, is rewritten for the next link. At each routed hop, the router constructs an appropriate outgoing frame and forwards the packet, subject to the relevant forwarding and security rules.
The packet-forwarding sequence
Routing table versus forwarding table
A router's routing information base (RIB) contains routes learned from connected networks, static configuration and routing protocols. Route selection determines which routes are eligible for installation. The selected results are used to program the FIB, which is optimised for packet forwarding. The precise implementation varies by platform.
Control plane · RIB
Learns and evaluates routes, applies routing policy, and determines which routes should be installed for forwarding.
Forwarding plane · FIB
Performs packet lookups using installed forwarding entries and directs traffic towards the appropriate next hop and interface.
Longest-prefix match: choosing the destination route
A router may have several routes that match a destination address. For ordinary IP forwarding, it selects the matching route with the longest prefix—the most specific network match. This is different from comparing routing protocols by administrative distance or comparing candidate BGP paths.
Consider a router with the following IPv4 routes and a packet destined for 10.20.30.45.
| Route | Prefix specificity | Match? |
|---|---|---|
| 10.0.0.0/8 | Broad network | Yes |
| 10.20.0.0/16 | More specific | Yes |
| 10.20.30.0/24 | Most specific match | Selected |
In this example, 10.20.30.0/24 wins because it matches more leading bits of the destination address than the broader routes. If no more-specific route exists, the router may use a less-specific matching route or a default route, provided one is installed and usable.
Routing protocols and the router's route-installation process determine which routes become available for forwarding. Longest-prefix match then selects the most specific installed prefix for the packet's destination. These are separate stages of the forwarding process.
Next-hop resolution and Layer 2 rewriting
The selected route may identify a directly connected destination, a specific next-hop IP address, or a route through a tunnel or other logical interface. When forwarding over Ethernet, the router must also determine the destination MAC address for the next hop. IPv4 commonly uses ARP, while IPv6 uses Neighbor Discovery.
If the required adjacency is not yet available, the router may need to resolve it before forwarding can proceed. If the destination has no usable route, or a required next hop cannot be resolved, the packet may be dropped or handled according to the platform's configured behaviour.
Efficient forwarding depends on more than selecting a route. The installed FIB entry, next-hop reachability, interface state, adjacency information, hardware capacity and applicable policies all influence whether the packet can be forwarded successfully.
Key takeaway: Routing determines the available paths and installs forwarding state. Longest-prefix match identifies the applicable destination route, while next-hop resolution and the forwarding plane enable the packet to move onto the next link. These fundamentals provide the basis for understanding OSPF, EIGRP, BGP, ECMP and advanced data-centre forwarding.
Interactive Lab 01 · Forwarding Fundamentals
Follow a Packet Through a Router
Enter a destination IP address and see how a router compares routing entries, selects the most specific matching prefix, resolves the next hop and prepares the packet for forwarding.
Forwarding decision
Route selected: 10.20.30.0/24
The destination matches several routes. The /24 prefix is the most specific matching route in this example.
1. Compare the routing entries
The router considers only prefixes that contain the destination. The matching route with the longest prefix length wins.
| Routing entry | Next hop | Match? | Decision |
|---|---|---|---|
| 10.0.0.0/8 | 192.0.2.8 | Yes | Less specific |
| 10.20.0.0/16 | 192.0.2.16 | Yes | Less specific |
| 10.20.30.0/24 | 192.0.2.1 | Yes | Selected |
| 0.0.0.0/0 | 192.0.2.254 | Yes | Fallback |
2. Follow the forwarding process
The router reads the destination address in the IP header.
The forwarding table is checked for matching destination prefixes.
The most specific installed matching route determines the forwarding entry.
The router identifies the outgoing interface and the required Layer 2 rewrite.
The router applies the relevant forwarding operations and transmits the packet, if the path is usable.
Section 02 · Route Learning and Selection
Routing Protocols and Next-Hop Selection
Optimal Layer 3 forwarding starts with the routes available to a router. Connected networks, static configuration and dynamic routing protocols contribute routing information, but each source serves a different purpose. Understanding how routes are learned, selected and installed is essential to understanding the forwarding decision.
A router does not automatically use every route it learns. It evaluates route information, applies the platform's route-selection rules and routing policies, and installs eligible routes into its routing table. The resulting forwarding information is then used to move packets towards their destinations.
Where routes come from
Connected routes
Created when a Layer 3 interface is operational and has an appropriate IP address configured. These routes provide reachability to the associated connected subnet.
Static routes
Configured by an administrator to specify a destination and forwarding path. They can provide predictable routing, explicit traffic steering or a default route.
OSPF and EIGRP
Interior routing protocols exchange reachability information within an organisation or routing domain. Their algorithms and metrics help determine preferred internal paths.
BGP
The Border Gateway Protocol exchanges reachability between autonomous systems and can also distribute routes within an autonomous system. Policy and path attributes play a central role.
Administrative distance and route preference
On platforms that use administrative distance, it expresses the relative trust assigned to routes from different sources when otherwise competing routes to the same destination are considered. A lower value is generally preferred. Administrative distance is vendor-specific and is not a universal metric shared between all routing implementations.
For example, a Cisco IOS-style configuration commonly uses the following default administrative-distance values. These values illustrate one vendor's convention; other vendors and configurations may differ.
| Route source | Example distance | What it represents |
|---|---|---|
| Connected | 0 | Directly attached network |
| Static | 1 | Manually configured route |
| EIGRP internal | 90 | Internal EIGRP route |
| OSPF | 110 | Route learned through OSPF |
| RIP | 120 | Route learned through RIP |
| eBGP | 20 | Route learned from an external BGP peer |
| iBGP | 200 | Route learned from an internal BGP peer |
Administrative distance is used by platforms that implement it to compare route sources. BGP first evaluates candidate paths using its own path-selection rules. Attributes such as local preference, AS_PATH, origin and MED can influence that decision, subject to the implementation and configuration. Administrative distance should not be confused with BGP path attributes.
How BGP selects a path
BGP can learn multiple paths to the same IP prefix from different peers. A router evaluates those paths using a sequence of decision rules. The exact order and available tie-breakers can vary by vendor, software version and configuration, so the following attributes should be understood as key factors rather than a universal complete decision sequence.
| Attribute or factor | Role in path selection |
|---|---|
| Local Preference | Expresses the preferred exit path within an autonomous system; higher is generally preferred. |
| AS_PATH | Lists autonomous systems traversed; a shorter path is generally preferred when earlier decision criteria do not decide the outcome. |
| Origin | Indicates how the route was originated in BGP; IGP origin is generally preferred over EGP, then incomplete. |
| MED | Can signal a preferred entry point into an autonomous system; comparison behaviour depends on policy and implementation. |
| Next-hop reachability | The next hop must be resolvable for the path to be usable for forwarding. |
BGP also uses other decision criteria, including locally configured policy, weight on some platforms, eBGP versus iBGP preference and tie-breakers. The path that wins is not necessarily the path with the lowest latency or the fewest physical hops. If the network needs to optimise for those properties, it may require explicit policy, measurement or traffic-engineering mechanisms.
Next-hop reachability: a selected route must be usable
Routing information can identify a next-hop address without that address being directly connected to the router. The router must resolve the next hop through another usable route or forwarding mechanism. In BGP, for example, an advertised prefix may carry a next-hop address that must be reachable through the local routing table.
If the next hop cannot be resolved, the route may be ineligible for installation or forwarding, depending on the protocol and platform. This is one reason why a routing protocol can appear operational while traffic to a particular destination still fails.
A route in a protocol's database is not automatically proof that packets can use it. Check the selected route, its next-hop resolution, the installed FIB entry and the outgoing interface. These checks help distinguish a route-selection problem from a forwarding or adjacency problem.
Key takeaway: Connected routes, static routes, OSPF, EIGRP and BGP provide different ways to learn or define reachability. Route-selection rules determine which information is installed, and next-hop reachability determines whether the chosen path can actually support forwarding. The next section explores ECMP, hardware-assisted forwarding and data-centre designs that use these routes to distribute traffic efficiently.
Interactive Lab 02 · Routing Decisions
Who Wins the Route?
Explore two separate decisions: which route source is installed in the routing table, and which path BGP prefers within its own process. Change the inputs to see how each decision works.
Part A — Compare route sources
This example uses typical Cisco IOS administrative-distance defaults. Lower administrative distance is preferred when competing routes to the same prefix are otherwise eligible for installation.
Route installation result
Static route preferred
The static route has an administrative distance of 1 in this example, lower than the competing route sources.
Route-source comparison
| Route source | Example AD | Available? | Result |
|---|
Part B — Explore BGP best-path selection
Three illustrative BGP paths advertise the same prefix. Select a scenario to see how local preference, AS-path length and next-hop reachability can affect the outcome.
Illustrative BGP decision
Path A selected
Path A has the highest local preference among the currently eligible paths in this simplified example.
Understand the decision sequence
A route generally needs a valid, resolvable next hop to be usable.
Depending on the implementation and policy, attributes such as local preference and AS-path length influence selection.
The BGP decision process selects a best path; the routing system then determines what is installed for forwarding.
Section 03 · Multipath and High-Performance Networks
ECMP, CEF and Data-Centre Forwarding
Selecting a usable route is only part of optimal forwarding. Networks must also distribute traffic across available paths, forward packets efficiently at scale, and maintain connectivity when links or devices fail. ECMP, hardware-assisted forwarding and resilient Layer 3 designs help address these requirements.
In modern enterprise and data-centre networks, multiple paths may connect the same source and destination. Using more than one eligible path can increase aggregate capacity and reduce dependence on a single link. The forwarding design must balance traffic distribution, predictable packet delivery and fast recovery from failures.
Equal-Cost Multipath (ECMP)
ECMP allows a router to install and use multiple eligible next hops for the same destination prefix when those paths satisfy the platform's equal-cost and multipath rules. Instead of forwarding every packet over one next hop, the router can distribute traffic across the available forwarding paths.
Conceptual illustration: multiple forwarding paths can serve traffic towards the same destination.
Many implementations use a hash based on packet or flow fields to select a next hop. This often keeps packets from the same flow on the same path, helping avoid packet reordering. The exact hash inputs, distribution method and available balancing options vary by platform.
Use parallel paths
Eligible paths can contribute to aggregate forwarding capacity, rather than leaving all traffic dependent on a single route.
Recover from path loss
If a path becomes unavailable and the network converges correctly, traffic can use remaining eligible next hops.
Hash-based distribution generally balances flows or packets according to the implementation. A small number of large flows can create uneven utilisation even when several equal-cost paths are available. Unequal-cost load sharing is a separate capability and is not automatically provided by ECMP.
Cisco Express Forwarding (CEF)
Cisco Express Forwarding is a Cisco forwarding architecture designed to accelerate packet forwarding. It uses a Forwarding Information Base (FIB) for destination lookups and an adjacency structure for information needed to transmit packets to the next hop. This separates fast packet forwarding from the routing calculations that populate the forwarding structures.
| Component | Purpose | Operational value |
|---|---|---|
| RIB | Maintains selected routing information. | Provides routes used to construct forwarding state. |
| FIB | Maps destination prefixes to forwarding actions and next hops. | Enables efficient destination lookups. |
| Adjacency information | Stores information required to transmit packets over the next link. | Helps avoid repeating neighbour-resolution work for every packet. |
On supported platforms, forwarding structures may be programmed into specialised hardware such as ASICs. This allows packets to be forwarded at high rates without requiring the main CPU to process every packet individually. Exact hardware pipelines and exception handling depend on the device architecture.
Layer 3 EtherChannel and link aggregation
A Layer 3 EtherChannel combines multiple physical Ethernet links into a single logical routed interface on platforms that support it. Routing operates over the logical interface, while the device distributes traffic across member links according to its hashing and forwarding implementation.
Logical routed interface
The bundle presents one Layer 3 interface to the routing configuration, simplifying addressing and route management.
Multiple physical members
Several links can provide combined capacity and link-level resilience, provided the remaining bundle has sufficient capacity.
Link aggregation and ECMP are related but different mechanisms. An EtherChannel distributes traffic across member links inside a logical bundle. ECMP distributes traffic across multiple eligible next hops or routed paths. A network can use both mechanisms at different points in the forwarding topology.
Data-centre forwarding: leaf-spine and routed fabrics
Many data-centre networks use a leaf-spine topology. Servers connect to leaf switches, and each leaf connects to multiple spine switches. A routed fabric can provide multiple equal-cost paths between leaves, allowing ECMP to distribute traffic across the fabric.
This design supports predictable scaling: adding capacity can involve adding links or fabric devices, subject to the topology, oversubscription goals and platform limits. Routing protocols such as eBGP or OSPF can provide reachability between fabric devices, depending on the design.
Redundant paths only help when failures are detected, routing and forwarding state are updated correctly, and the surviving network has enough capacity. Convergence behaviour, failure domains, configuration consistency and traffic symmetry should all be considered during design and testing.
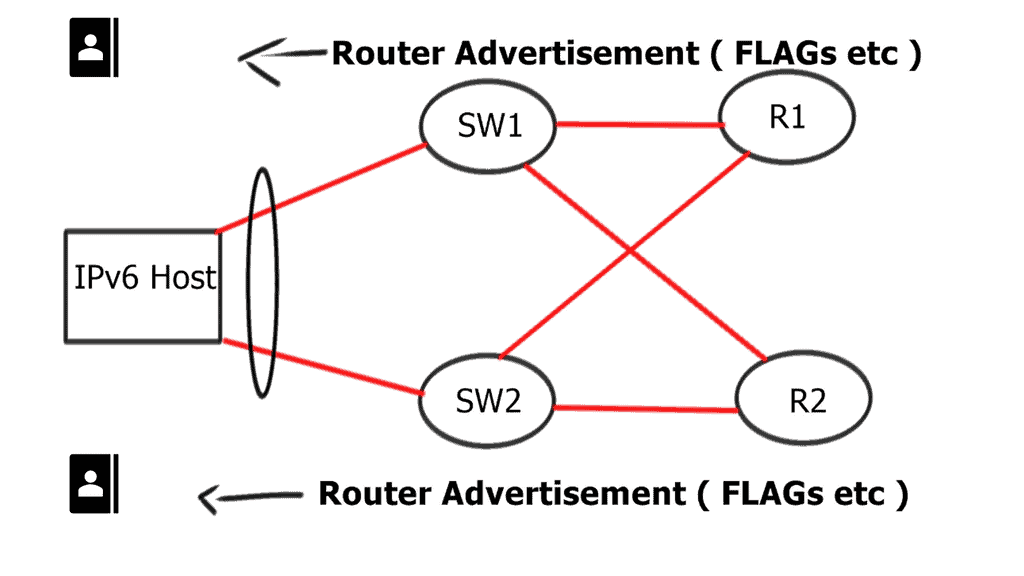
Other forwarding designs: VARP and vPC
Data-centre platforms may also provide features for gateway availability and multi-device link aggregation. Their purpose and implementation should be understood separately from ECMP.
Arista VARP
Virtual ARP provides a shared virtual gateway address and MAC behaviour across participating Arista switches. It can allow hosts to use a resilient default gateway in supported designs.
Cisco vPC
Virtual PortChannel allows a downstream device to form a port channel across two supported Cisco Nexus peers. It provides multi-device Layer 2 attachment; it is not itself an ECMP routing algorithm.
These features address different parts of network availability. VARP concerns gateway behaviour, vPC concerns multi-device port-channel connectivity, and ECMP concerns forwarding across multiple eligible routed next hops. They may coexist in a larger architecture, but they should not be treated as interchangeable technologies.
Key takeaway: ECMP distributes traffic across eligible routed paths, CEF provides an efficient forwarding architecture on supported Cisco platforms, and Layer 3 EtherChannel aggregates physical links into a logical routed interface. Leaf-spine fabrics, gateway redundancy and multi-device link aggregation build on related principles to support scalable, resilient networks. The next section examines troubleshooting, fast failure detection, policy-based routing and traffic control.
Interactive Lab 03 · Multipath Forwarding
How Does ECMP Distribute Traffic?
Simulate traffic from one router to a destination through multiple equal-cost paths. Change the number of paths and the distribution method to see why flow-based hashing behaves differently from packet-by-packet round-robin scheduling.
1. Configure the forwarding scenario
Simulation result
Traffic distributed across 3 paths
Flow-based hashing assigns each flow to one path in this illustrative simulation. Different flows can be distributed unevenly.
2. Inspect the traffic distribution
3. What happens inside the forwarding plane?
| Component | Role in forwarding | What to validate |
|---|---|---|
| RIB | Holds routing information and route-selection results. | Expected prefix and selected route source. |
| FIB | Provides the destination-prefix lookup used for packet forwarding. | Installed forwarding entry and next-hop set. |
| Adjacency | Provides next-hop forwarding details, including Layer 2 rewrite information where applicable. | Neighbour resolution and usable egress interface. |
| ECMP hash | Can map packet-flow fields to one of several eligible equal-cost paths. | Path eligibility, hash inputs and actual traffic distribution. |
Section 04 · Resilience and Operational Control
Resilience, Troubleshooting and Traffic Engineering
Optimal forwarding is not simply about choosing the fastest path. A production network must detect failures, recover from changing topology, apply traffic policies and provide enough visibility to identify forwarding problems. Resilience depends on how these mechanisms work together.
A route can be correct when it is installed but become unusable after an interface failure, a neighbour becomes unreachable, or an intermediate network stops forwarding traffic. Effective network operations therefore examine both the routing control plane and the actual forwarding path.
Failure detection and routing convergence
When a link or neighbour fails, the network needs to detect the event, update relevant routing and forwarding state, and direct traffic over a surviving path where one exists. The time required for the network to settle on a usable path is part of its convergence behaviour.
Bidirectional Forwarding Detection (BFD)
BFD provides rapid detection of forwarding-path failures between participating endpoints. Routing protocols can use BFD events to react more quickly than relying solely on longer protocol hello or dead timers, where integration is supported.
Routing convergence
After a failure is detected, the routing system recalculates or selects alternatives and updates forwarding entries. Actual recovery time depends on protocol behaviour, timers, topology, hardware and configuration.
BFD can help identify a failed forwarding path quickly, but it does not independently calculate a new route or guarantee that traffic will be restored immediately. Routing convergence, forwarding programming and the availability of an alternative path also affect recovery.
Diagnosing the forwarding path with traceroute
Traceroute helps identify the sequence of Layer 3 hops that respond to probes on the way towards a destination. Traditional implementations use probes with progressively increasing IP TTL or IPv6 Hop Limit values. Routers that reduce the value to zero may return an ICMP time-exceeded response, revealing an intermediate hop.
The output must be interpreted carefully. Some routers filter or rate-limit probe responses, so an asterisk does not necessarily indicate a forwarding failure. Return paths may differ from outbound paths, and load balancing can cause probes to reveal different paths depending on the probing method and network configuration.
| Observed symptom | Possible explanation | Useful next check |
|---|---|---|
| Destination is unreachable | Missing route, invalid next hop or explicit rejection. | Inspect the route table, FIB and relevant interface state. |
| Traceroute shows asterisks | Probe responses may be filtered, rate-limited or unsupported. | Test end-to-end reachability and inspect the responding hops. |
| High latency begins at a hop | Congestion, queueing, control-plane response limits or a real path issue. | Compare end-to-end measurements and interface counters. |
| Traffic fails after a link event | Convergence delay, stale state or no usable alternate path. | Check routing neighbours, logs, FIB entries and adjacency state. |
Policy-Based Routing (PBR)
Conventional routing primarily selects a forwarding path using the destination address and the installed routing information. Policy-Based Routing can apply additional rules to selected traffic, using supported packet attributes such as source address, protocol or transport ports to choose a different next hop or forwarding action.
PBR is useful when specific applications, source networks or traffic classes must follow a path that differs from the ordinary destination-based route. For example, a network might steer selected traffic through a security appliance or a dedicated WAN connection.
Potential benefits
Enables traffic steering, service chaining and application-specific forwarding policies when supported by the platform.
Operational considerations
Policy rules can create asymmetric paths, bypass expected controls or send traffic towards an unreachable next hop if they are not designed and monitored carefully.
Quality of Service (QoS) and congestion
QoS mechanisms classify traffic and apply actions such as marking, policing, shaping and queue scheduling. They influence how traffic is handled when resources are constrained, particularly on busy links. QoS does not replace route selection, but it can strongly influence the performance experienced by traffic using a chosen path.
For example, a real-time voice flow may be assigned to a low-latency queue, while bulk transfers use another queue. The benefit depends on consistent classification and configuration along the path, and on the available bandwidth and congestion conditions.
Routing determines where packets should go. QoS determines how packets are treated when they compete for network resources. A preferred route can still perform poorly if the outgoing interface is congested or its queueing policy is inappropriate.
Next-hop tracking and route validity
Forwarding depends on the continued availability of the next hop. A route may need to be withdrawn, marked unusable or replaced when its next-hop reachability changes. Some routing implementations support next-hop tracking to associate route validity with changes in the reachability of a specified next-hop address.
In BGP environments, next-hop reachability is especially important: a BGP path can be present in the BGP table but not be usable for forwarding if its next hop cannot be resolved. Troubleshooting should therefore check both the BGP path and the underlying route that provides next-hop reachability.
A practical Layer 3 troubleshooting workflow
- Confirm the symptom. Identify the source, destination, affected protocol and whether the problem is intermittent or persistent.
- Check interfaces and links. Inspect operational state, errors, drops, utilisation and recent link events.
- Inspect the route. Verify the destination prefix, selected route, route source and any applicable policy.
- Validate next-hop reachability. Confirm that the next hop resolves and the expected adjacency is present.
- Inspect forwarding state. Where platform tools permit, compare the RIB with the FIB and check for unresolved or missing forwarding entries.
- Trace and test. Use ping, traceroute and application-level tests while accounting for filtering, asymmetric routing and load balancing.
- Review resilience mechanisms. Check routing neighbours, BFD state, failover events and convergence after a failure.
- Check traffic treatment. Review PBR, access controls, QoS policies and any intermediate services that may affect the flow.
A disciplined workflow avoids changing routing configuration before establishing where the failure occurs. The objective is to distinguish a control-plane problem from a forwarding problem, an adjacency issue, congestion or an intentional policy decision.
Key takeaway: Resilient Layer 3 forwarding requires timely failure detection, correct convergence, usable next hops and clear operational visibility. BFD, traceroute, PBR and QoS serve different roles in detecting, diagnosing and controlling network behaviour. The next section explores cloud networking, overlays, IPv6 and advanced forwarding architectures.
Interactive Lab 04 · Resilience
Investigate a Layer 3 Forwarding Failure
A destination suddenly becomes unreachable. Simulate a path failure, inspect the remaining forwarding options, and work through the checks an engineer would use to distinguish physical failure, routing convergence and next-hop resolution problems.
1. Select a failure scenario
Network operating normally
Both illustrative paths are available. Inject a failure to see how the forwarding state and investigation sequence change.
2. Follow the investigation timeline
Confirm the destination route and both available paths.
Identify the failed link, adjacency or next-hop condition.
Check route selection, the FIB and usable next hops.
Test reachability and confirm the actual forwarding path.
3. Complete the troubleshooting checklist
0 of 5 checks completed
Section 05 · Cloud and Advanced Architectures
Cloud Networking, VXLAN, IPv6 and Advanced Forwarding
Modern Layer 3 forwarding extends beyond traditional enterprise routers. Cloud networks, virtualised data centres and software-defined environments combine routing, overlays, policy and distributed infrastructure to connect workloads across increasingly complex network boundaries.
The core forwarding principles remain familiar: identify the destination, select an applicable route, resolve the next hop and transmit the packet. What changes is the environment in which these decisions occur. Virtual networks, encapsulation, cloud route tables and centralised policy systems can introduce additional forwarding stages that must be understood during design and troubleshooting.
Cloud networking and virtual routing
Public cloud platforms provide virtual networks with configurable subnets, routes, gateways and traffic controls. These constructs allow cloud workloads to communicate with one another, with on-premises networks and with external destinations. The exact routing model, supported route types and forwarding behaviour depend on the cloud provider and service.
Cloud route tables
Define how traffic from a subnet or virtual network is directed towards local destinations, gateways, peering connections or other supported next hops.
Cloud and on-premises routing
VPNs and dedicated connectivity services can exchange or provide routes between private networks, subject to provider features, route propagation and security policy.
Cloud troubleshooting should examine more than the guest operating system's route table. Virtual network routes, subnet associations, security rules, network interfaces, gateway configuration and provider-specific forwarding behaviour can all affect connectivity.
A valid route inside a virtual machine does not guarantee that the cloud network will permit the traffic. Confirm the workload's local route, the cloud-side forwarding path and the applicable security controls before concluding that the problem is a routing failure.
VXLAN: extending Layer 2 over a Layer 3 underlay
Virtual Extensible LAN (VXLAN) is an overlay encapsulation technology used to carry Layer 2 Ethernet frames across a Layer 3 IP network. It allows logical Layer 2 segments to span a routed underlay without requiring the underlay itself to operate as one large Layer 2 domain.
VXLAN tunnel endpoints (VTEPs) encapsulate and decapsulate traffic. The outer IP header is routed through the underlay, while the encapsulated Ethernet frame represents the overlay traffic. VXLAN uses a 24-bit VXLAN Network Identifier (VNI), allowing a large number of logical segments.
The overlay determines how tenant or segment traffic is represented and delivered between VTEPs. The underlay provides IP reachability between those endpoints. An overlay can fail even when the underlay is reachable, for example because of incorrect VNI mapping, missing endpoint information, filtering or encapsulation issues.
IPv6 forwarding and neighbour discovery
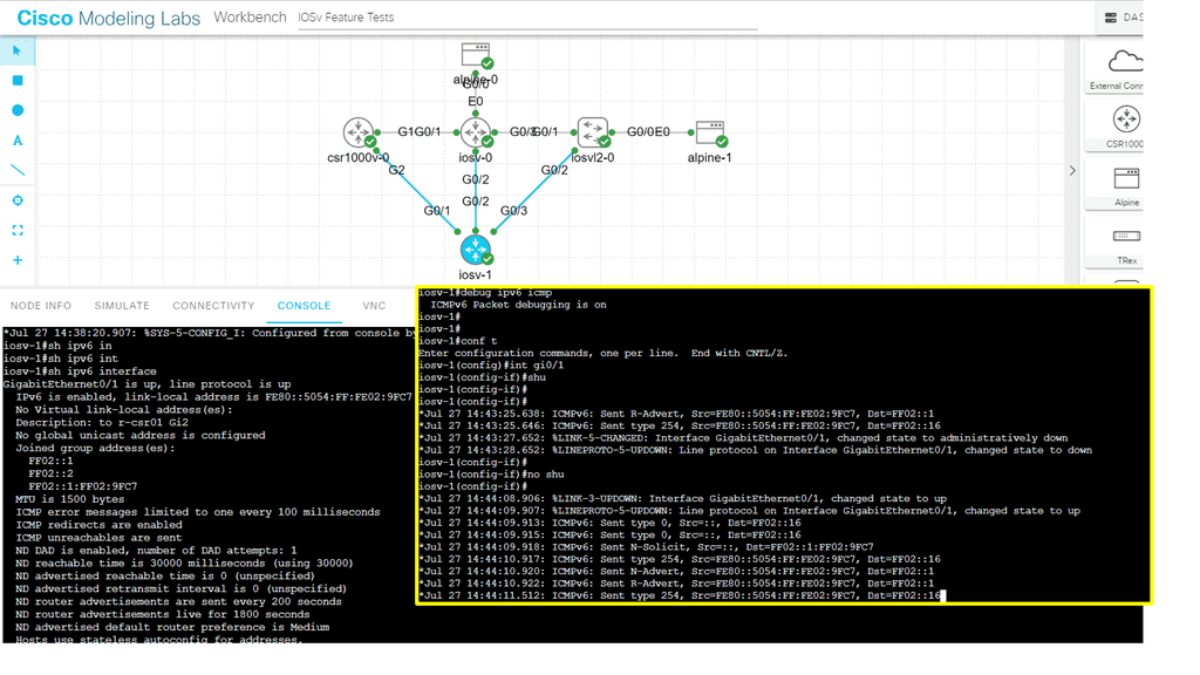
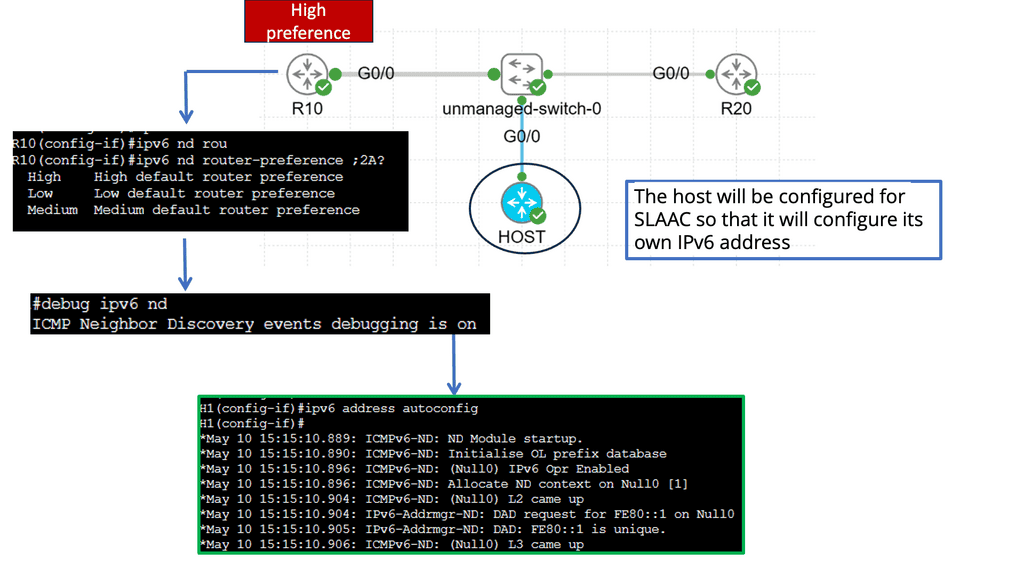
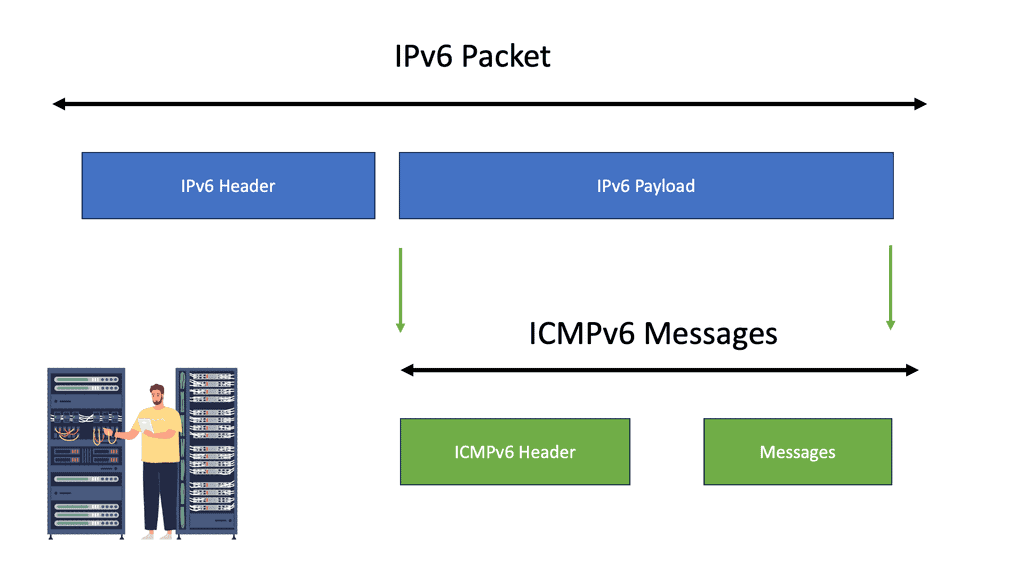
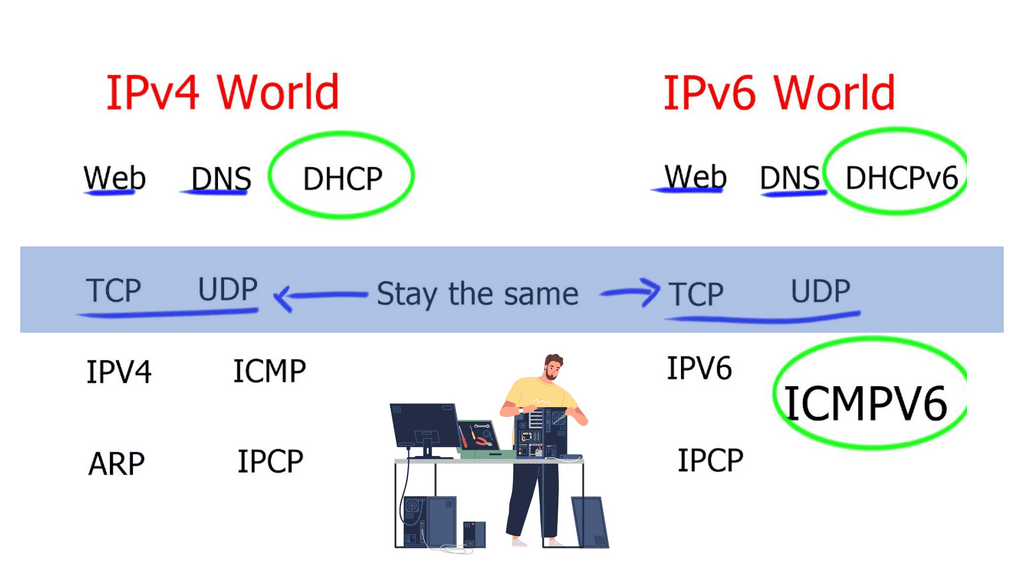
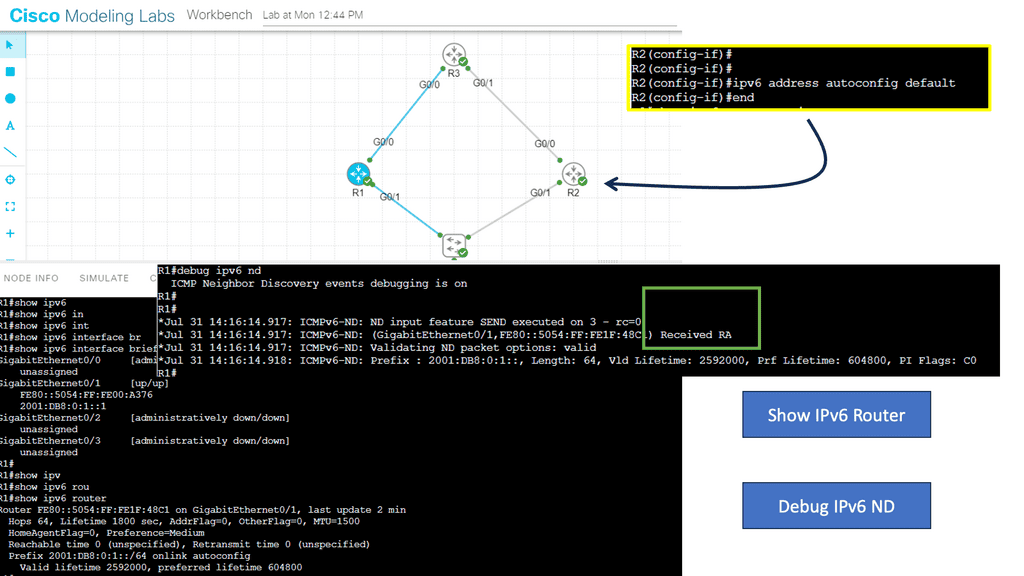
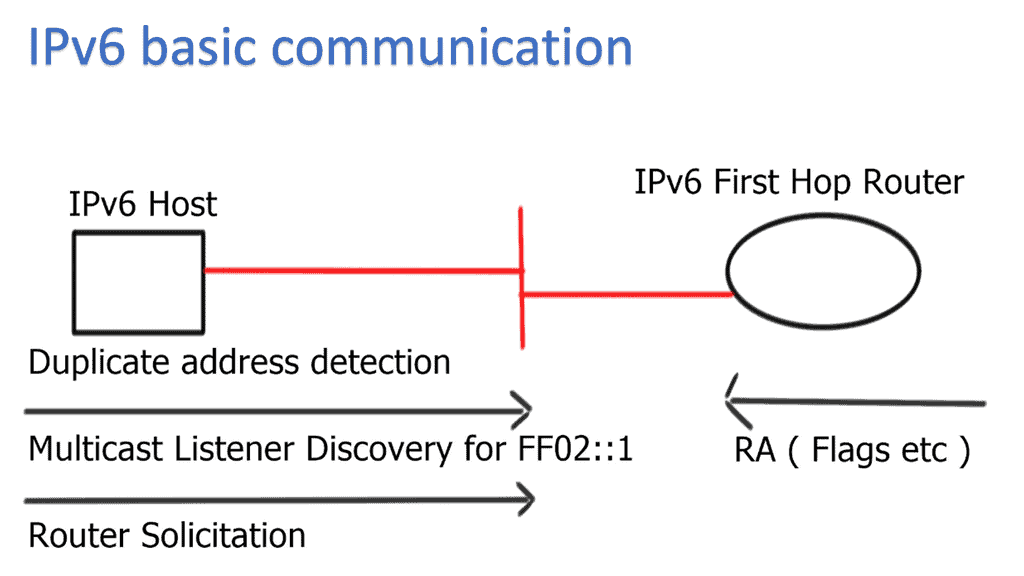
IPv6 follows the same broad forwarding model as IPv4: routers examine the destination address and use the most specific applicable route. However, IPv6 has a different address format, header structure and neighbour-resolution mechanism. IPv6 uses Neighbor Discovery Protocol (NDP), carried in ICMPv6, rather than ARP.
| Concept | IPv4 | IPv6 |
|---|---|---|
| Address size | 32 bits | 128 bits |
| Neighbour resolution | ARP on Ethernet | Neighbor Discovery using ICMPv6 |
| Address configuration | Manual configuration or DHCPv4, among other methods | Manual configuration, SLAAC and/or DHCPv6, depending on the design |
| Default route notation | 0.0.0.0/0 | ::/0 |
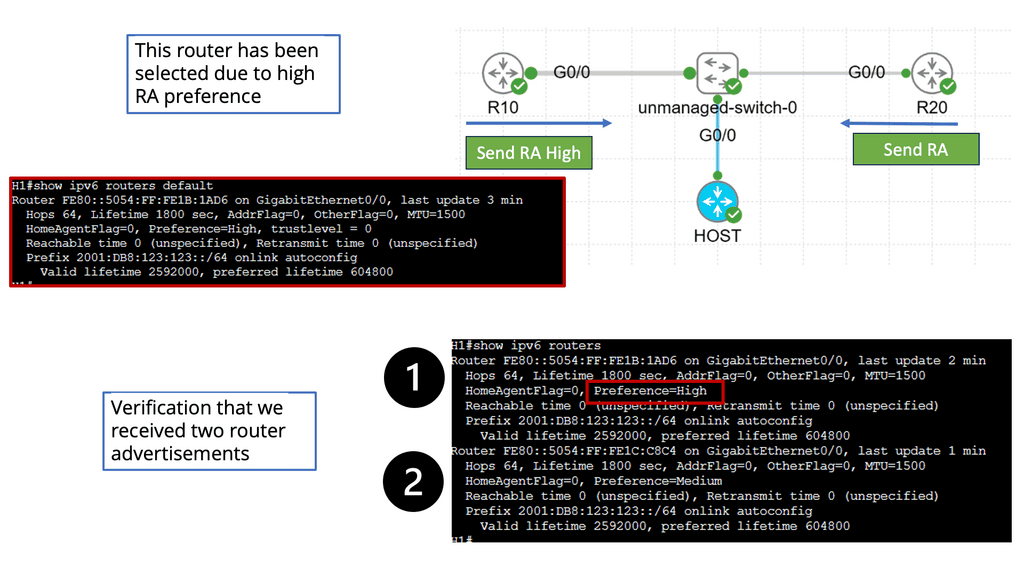
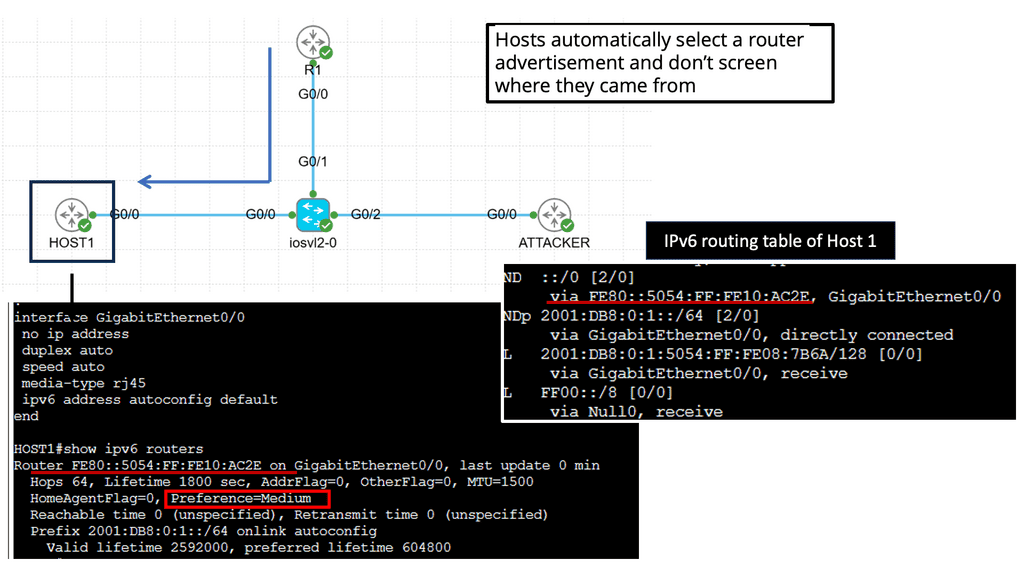
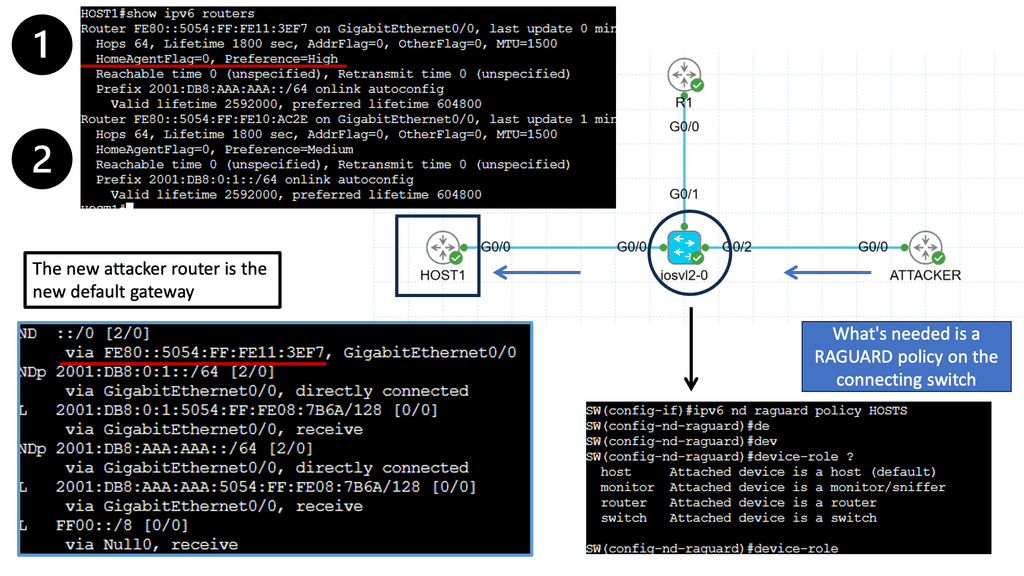
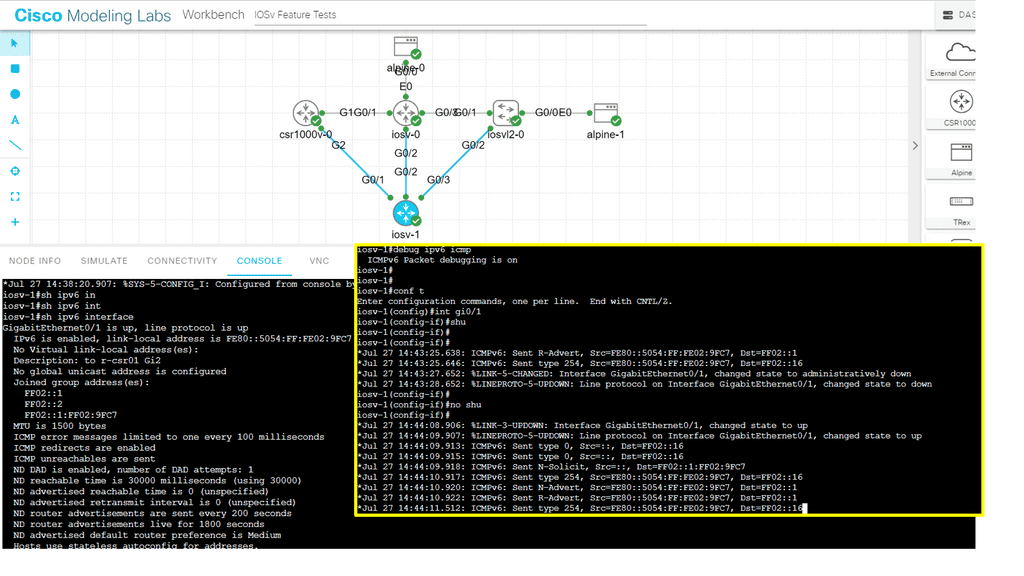
IPv6 deployments must also account for Router Advertisements, prefix configuration, link-local addresses and ICMPv6 behaviour. Filtering essential ICMPv6 messages indiscriminately can disrupt functions required for normal operation, including neighbour discovery and Path MTU Discovery.
Software-defined networking and programmable forwarding
Software-defined networking (SDN) separates aspects of network control and policy from the individual forwarding devices. Depending on the architecture, a controller or orchestration system can coordinate configuration and distribute forwarding policy across switches, routers and virtual network components.
Centralised policy
Network-wide intent and configuration can be managed through common systems, helping maintain consistent connectivity and segmentation rules.
Programmable forwarding
Supported platforms can expose programmable data-plane functions or APIs that allow specialised packet-processing behaviour beyond conventional destination-based forwarding.
SDN does not mean that every packet must pass through a central controller. In many designs, the controller distributes policy or forwarding state while switches and routers continue to forward packets locally. The precise control model depends on the technology.
Network functions virtualisation and service chaining
Network Functions Virtualisation (NFV) allows network functions such as firewalls, routers and load balancers to run as software on virtualised or cloud infrastructure. Service chaining directs selected traffic through a sequence of services, such as inspection, filtering and application delivery.
These designs introduce additional forwarding decisions and operational dependencies. Engineers need to verify route symmetry where required, service reachability, encapsulation, capacity and the behaviour of each service in the chain.
Load balancing, direct server return and edge delivery
Load balancers distribute client traffic across available back-end servers using configured algorithms and health checks. In some architectures, Direct Server Return (DSR) allows the server to send response traffic directly back towards the client rather than returning it through the load balancer. The appropriate design depends on address handling, routing symmetry, platform support and operational requirements.
Content delivery networks and edge architectures move content or processing closer to users. DNS responses, anycast announcements, application-layer decisions and regional routing can all influence which service endpoint a client reaches. These mechanisms complement IP forwarding but are not the same as a router's per-packet longest-prefix match.
A CDN or load balancer may decide which server or service endpoint should receive a request. The network then forwards packets towards that endpoint. Application-layer selection and Layer 3 forwarding interact, but they solve different parts of the delivery problem.
Advanced forwarding: matching the tool to the problem
| Requirement | Relevant mechanism | Key consideration |
|---|---|---|
| Multiple routed paths | ECMP | Path eligibility, hashing and capacity |
| Logical Layer 2 segments across a routed fabric | VXLAN | VTEP reachability, VNI configuration and MTU |
| Cloud workload connectivity | Virtual network routes and gateways | Provider routing, security controls and route propagation |
| Traffic-specific path steering | PBR or supported policy-based mechanisms | Policy order, symmetry and next-hop validity |
| Centralised network configuration | SDN and orchestration | Controller availability, policy consistency and operational visibility |
| IPv6 network reachability | IPv6 routing and Neighbor Discovery | Prefix design, ICMPv6 and address configuration |
Key takeaway: Cloud networking, VXLAN, IPv6, SDN and virtualised network functions extend the environments in which Layer 3 forwarding operates. They do not remove the need for correct routing, next-hop reachability, MTU planning, policy control and systematic troubleshooting. The final stage is to bring these concepts together into a practical forwarding design and engineering checklist.
Interactive Lab 05 · Modern Forwarding
Explore Cloud, VXLAN and IPv6 Forwarding
Choose a networking environment and follow a packet through its forwarding stages. Compare a cloud route-table decision, a VXLAN overlay carried by an IP underlay, and native IPv6 forwarding.
1. Select a forwarding environment
Packet trace
The route table selects a local destination path
A forwarding device checks the destination against its installed routes and forwards the packet using the selected entry.
2. Inspect the forwarding stages
The packet's destination address determines which route is relevant.
The forwarding plane uses its installed forwarding information.
Determine the egress interface and required link-layer forwarding details.
Forward when a usable path exists; otherwise investigate the missing route or unusable next hop.
Section 06 · Engineering Framework
Optimal Layer 3 Forwarding: Design Checklist and Conclusion
Effective Layer 3 forwarding combines correct route selection, efficient packet processing, resilient paths and clear operational visibility. This final section brings the key concepts together into a practical framework for designing, validating and maintaining routed networks.
No single protocol or feature guarantees optimal forwarding. A network may use OSPF or BGP to learn routes, ECMP to distribute traffic, hardware-assisted forwarding to process packets, and BFD or other mechanisms to detect failures. The right combination depends on the topology, application requirements, scale and operational constraints.
Six principles of optimal Layer 3 forwarding
Build accurate routing information
Ensure that connected, static and dynamically learned routes reflect the intended topology and that routing policy produces the required reachability.
Validate next hops
Confirm that selected next hops resolve correctly, interfaces are operational and the necessary forwarding adjacencies exist.
Use forwarding resources effectively
Consider FIB capacity, hardware forwarding capabilities, ECMP distribution, interface utilisation and packet-processing requirements.
Design for failures
Provide appropriate path diversity, failure detection, convergence behaviour and enough remaining capacity to handle expected failure scenarios.
Control traffic intentionally
Apply routing policy, PBR, segmentation and QoS where required. Verify that these mechanisms support the intended traffic flows.
Make forwarding observable
Monitor routes, neighbours, interface health, traffic counters, drops, latency and failure events so problems can be isolated and measured.
Practical engineering validation checklist
Use this checklist when reviewing a new routed design, investigating a connectivity issue or validating a network change.
Match the requirement to the forwarding mechanism
| Engineering requirement | Mechanisms to evaluate |
|---|---|
| Learn and select routes | Static routing, OSPF, EIGRP, BGP and routing policy |
| Forward packets efficiently | FIB, adjacency resolution and platform forwarding hardware |
| Use multiple routed paths | ECMP and supported multipath routing features |
| Aggregate physical links | Layer 3 EtherChannel or equivalent link aggregation |
| Detect failures quickly | BFD, interface monitoring and routing-protocol failure detection |
| Steer selected traffic | PBR and supported traffic-engineering mechanisms |
| Connect overlay segments | VXLAN, VTEP reachability and a routed underlay |
| Operate in cloud environments | Virtual route tables, gateways, network policy and provider controls |
A design should be validated against measurable requirements: reachability, throughput, latency, packet loss, convergence time, capacity under failure and policy compliance. A configuration that looks correct on paper is not sufficient without testing the resulting forwarding behaviour.
Conclusion: making Layer 3 forwarding optimal
Optimal Layer 3 forwarding is the result of several cooperating systems. Routing protocols and static configuration provide reachability; route-selection rules determine which information is installed; longest-prefix match identifies the applicable destination route; and the forwarding plane moves packets through usable next hops.
Technologies such as ECMP, CEF, link aggregation, BFD, QoS, PBR, VXLAN and cloud routing extend these fundamentals to support higher capacity, resilience, traffic control and modern virtualised environments.
The strongest designs are not necessarily the most complicated. They are designs with clear routing intent, verified forwarding state, appropriate redundancy, predictable failure behaviour and sufficient visibility to diagnose problems quickly.
Final takeaway: Design the route, validate the next hop, inspect the forwarding state, test failure scenarios and measure real traffic behaviour. These practices turn Layer 3 forwarding from a collection of routing commands into an engineered, observable and resilient network service.